mirror of
https://github.com/infiniflow/ragflow.git
synced 2026-10-12 02:16:39 +00:00
 YanZhang
@@ -3,7 +3,7 @@
|
||||
"position": 2,
|
||||
"link": {
|
||||
"type": "generated-index",
|
||||
"description": "Chat-specific guides."
|
||||
"description": "Learn how to create, use, configure, and test Chat applications."
|
||||
},
|
||||
"customProps": {
|
||||
"categoryIcon": "LucideMessagesSquare"
|
||||
|
||||
@@ -1,11 +0,0 @@
|
||||
{
|
||||
"label": "Best Practices",
|
||||
"position": 7,
|
||||
"link": {
|
||||
"type": "generated-index",
|
||||
"description": "Best practices on chat assistant configuration."
|
||||
},
|
||||
"customProps": {
|
||||
"categoryIcon": "LucideStar"
|
||||
}
|
||||
}
|
||||
@@ -1,49 +0,0 @@
|
||||
---
|
||||
sidebar_position: 1
|
||||
title: Accelerate Answering
|
||||
sidebar_label: Accelerate Answering
|
||||
slug: /accelerate_question_answering
|
||||
---
|
||||
|
||||
# Accelerate Answering
|
||||
import APITable from '@site/src/components/APITable';
|
||||
|
||||
A checklist to speed up question answering for your chat assistant.
|
||||
|
||||
---
|
||||
|
||||
Please note that some of your settings may consume a significant amount of time. If you often find that your question answering is time-consuming, here is a checklist to consider:
|
||||
|
||||
- Disabling **Multi-turn optimization** will reduce the time required to get an answer from the LLM.
|
||||
- Leaving the **Rerank model** field empty will significantly decrease retrieval time.
|
||||
- Disabling the **Reasoning** toggle will reduce the LLM's thinking time. For a model like Qwen3, you also need to add `/no_think` to the system prompt to disable reasoning.
|
||||
- When using a rerank model, ensure you have a GPU for acceleration; otherwise, the reranking process will be *prohibitively* slow.
|
||||
|
||||
:::tip NOTE
|
||||
Please note that rerank models are essential in certain scenarios. There is always a trade-off between speed and performance; you must weigh the pros against cons for your specific case.
|
||||
:::
|
||||
|
||||
- Disabling **Keyword analysis** will reduce the time to receive an answer from the LLM.
|
||||
- When chatting with your chat assistant, click the light bulb icon above the *current* dialogue and scroll down the popup window to view the time taken for each task:
|
||||
|
||||
|
||||
```mdx-code-block
|
||||
<APITable>
|
||||
```
|
||||
|
||||
| Item name | Description |
|
||||
| ----------------- | --------------------------------------------------------------------------------------------- |
|
||||
| Total | Total time spent on this conversation round, including chunk retrieval and answer generation. |
|
||||
| Check LLM | Time to validate the specified LLM. |
|
||||
| Create retriever | Time to create a chunk retriever. |
|
||||
| Bind embedding | Time to initialize an embedding model instance. |
|
||||
| Bind LLM | Time to initialize an LLM instance. |
|
||||
| Tune question | Time to optimize the user query using the context of the multi-turn conversation. |
|
||||
| Bind reranker | Time to initialize an reranker model instance for chunk retrieval. |
|
||||
| Generate keywords | Time to extract keywords from the user query. |
|
||||
| Retrieval | Time to retrieve the chunks. |
|
||||
| Generate answer | Time to generate the answer. |
|
||||
|
||||
```mdx-code-block
|
||||
</APITable>
|
||||
```
|
||||
@@ -0,0 +1,125 @@
|
||||
---
|
||||
sidebar_position: 3
|
||||
title: Chat Configuration
|
||||
sidebar_label: Chat Configuration
|
||||
slug: /chat_configuration
|
||||
sidebar_custom_props:
|
||||
categoryIcon: LucideSettings
|
||||
---
|
||||
|
||||
# Chat Configuration
|
||||
|
||||
## Dataset Configuration
|
||||
|
||||
dataset determine the data scope that Chat can retrieve and cite. Only dataset that contain successfully parsed, available chunks can serve as valid knowledge sources.
|
||||
|
||||
- **Select dataset**: Associate one or more dataset in the **dataset** field. New or empty dataset generally do not appear in the selection list.
|
||||
- **Unavailable dataset**: If a dataset has been deleted or contains no available chunks, Chat indicates that the selected dataset is unavailable. Select another dataset.
|
||||
|
||||
:::tip NOTE
|
||||
For answers grounded in retrieved knowledge, consider retaining the `{knowledge}` placeholder in the system prompt.
|
||||
:::
|
||||
|
||||
## Model
|
||||
|
||||
Select the large language model that understands questions and generates answers. Models differ in context length, reasoning capability, response speed, tool-calling capability, and cost.
|
||||
|
||||
Choose a model based on the use case. For routine dataset Q&A, prioritize response speed. For complex analysis or multi-document synthesis, select a model with stronger reasoning capabilities.
|
||||
|
||||
The available models depend on the models that have been added and configured in the current system.
|
||||
|
||||
## Opening Greeting
|
||||
|
||||
The opening greeting is the initial content shown when a user enters the Chat. Use it to briefly introduce the Chat's purpose, capability scope, usage, or example questions and help users begin a conversation.
|
||||
|
||||
An opening greeting can explain:
|
||||
|
||||
- The types of questions the Chat can answer.
|
||||
- The knowledge or business content on which its answers are based.
|
||||
- How users should phrase their questions.
|
||||
- Recommended examples or frequently asked questions.
|
||||
|
||||
The opening greeting primarily provides an introduction and guidance; it does not control subsequent answer behavior.
|
||||
|
||||
## System Prompt
|
||||
|
||||
The system prompt defines the Chat's role, tasks, and answer rules, and affects model behavior throughout the conversation.
|
||||
|
||||
Use it to specify the role, answer scope, language and tone, dataset usage, answer format, and how the Chat should handle missing information. For knowledge-base Q&A, explicitly instruct the model to prioritize dataset content and avoid filling in gaps or guessing when reliable evidence is unavailable.
|
||||
|
||||
You can also require the Chat to:
|
||||
|
||||
- Answer in English, Chinese, or another specified language.
|
||||
- Keep answers concise and professional, or use a specified format.
|
||||
- State clearly when an answer cannot be confirmed from the available information.
|
||||
- Decline questions outside the scope of the current Chat.
|
||||
|
||||
Clearer prompts produce more stable behavior. Refine the prompt continuously based on testing, and avoid conflicting settings or overly complex rules.
|
||||
|
||||
## Retrieval Configuration
|
||||
|
||||
Retrieval configuration controls how Chat recalls, filters, and ranks chunks from dataset. Tune these settings to balance retrieval scope, relevance, and response efficiency.
|
||||
|
||||
- **Similarity threshold**: The minimum similarity score for retrieved content. A higher threshold is stricter and usually returns more relevant content, but may miss useful information. A lower threshold broadens recall but may introduce less relevant content.
|
||||
- **Vector similarity weight**: Controls the relative weight of vector semantic similarity and full-text matching in hybrid search. A higher vector weight favors semantic similarity; a higher full-text weight favors keyword and text matching. Tune it according to the dataset content and question style.
|
||||
- **Top N**: The number of candidate chunks returned by each retrieval. A larger value provides more context but increases context length, response time, and cost. Tune it according to document scale and retrieval results.
|
||||
- **Rerank model**: Reranks retrieval results, calculates the relevance between candidate chunks and the question, and moves more relevant content forward for answer generation. Configure an available rerank model before using this option.
|
||||
- **Metadata**: Uses document or chunk metadata to limit the retrieval scope, such as by document type, date, or source.
|
||||
|
||||
## Empty Response
|
||||
|
||||
An empty response is preset content returned when the system cannot obtain enough information from a dataset, for example:
|
||||
|
||||
> No relevant content was found in the dataset. Add more information and try again.
|
||||
|
||||
When retrieval returns no usable dataset content, Chat returns the preset response instead of continuing to generate an answer. This is useful when answers must be strictly grounded in a dataset and helps reduce unreliable output.
|
||||
|
||||
If no empty response is configured, the model may continue answering from its own knowledge when the dataset contains no relevant content.
|
||||
|
||||
Choose a configuration according to the scenario:
|
||||
|
||||
- **Strictly use the dataset**: Configure an empty response for internal policies, customer service, compliance, product documentation, and other scenarios that depend heavily on dataset content.
|
||||
- **Allow the model to answer freely**: Leave it blank if answering from the model's own knowledge is acceptable.
|
||||
- **Guide the user's next action**: Include a clear instruction, such as adding information, trying again, or contacting an administrator.
|
||||
|
||||
An empty response is triggered only when retrieval finds no usable content. If any usable result exists, the system normally continues model generation; it does not decide based on whether the final answer is complete.
|
||||
|
||||
The Thinking mode also affects this process. Higher Thinking modes perform more retrieval and reasoning before returning an empty response. **Low** makes a quick determination, **Medium** performs standard processing, and **High** or **Ultra** conducts multiple rounds of deeper retrieval. An empty response is returned only when the system ultimately determines that it cannot answer.
|
||||
|
||||
## Select a Thinking Mode
|
||||
|
||||
Thinking mode determines how deeply Chat investigates available data before answering.
|
||||
|
||||
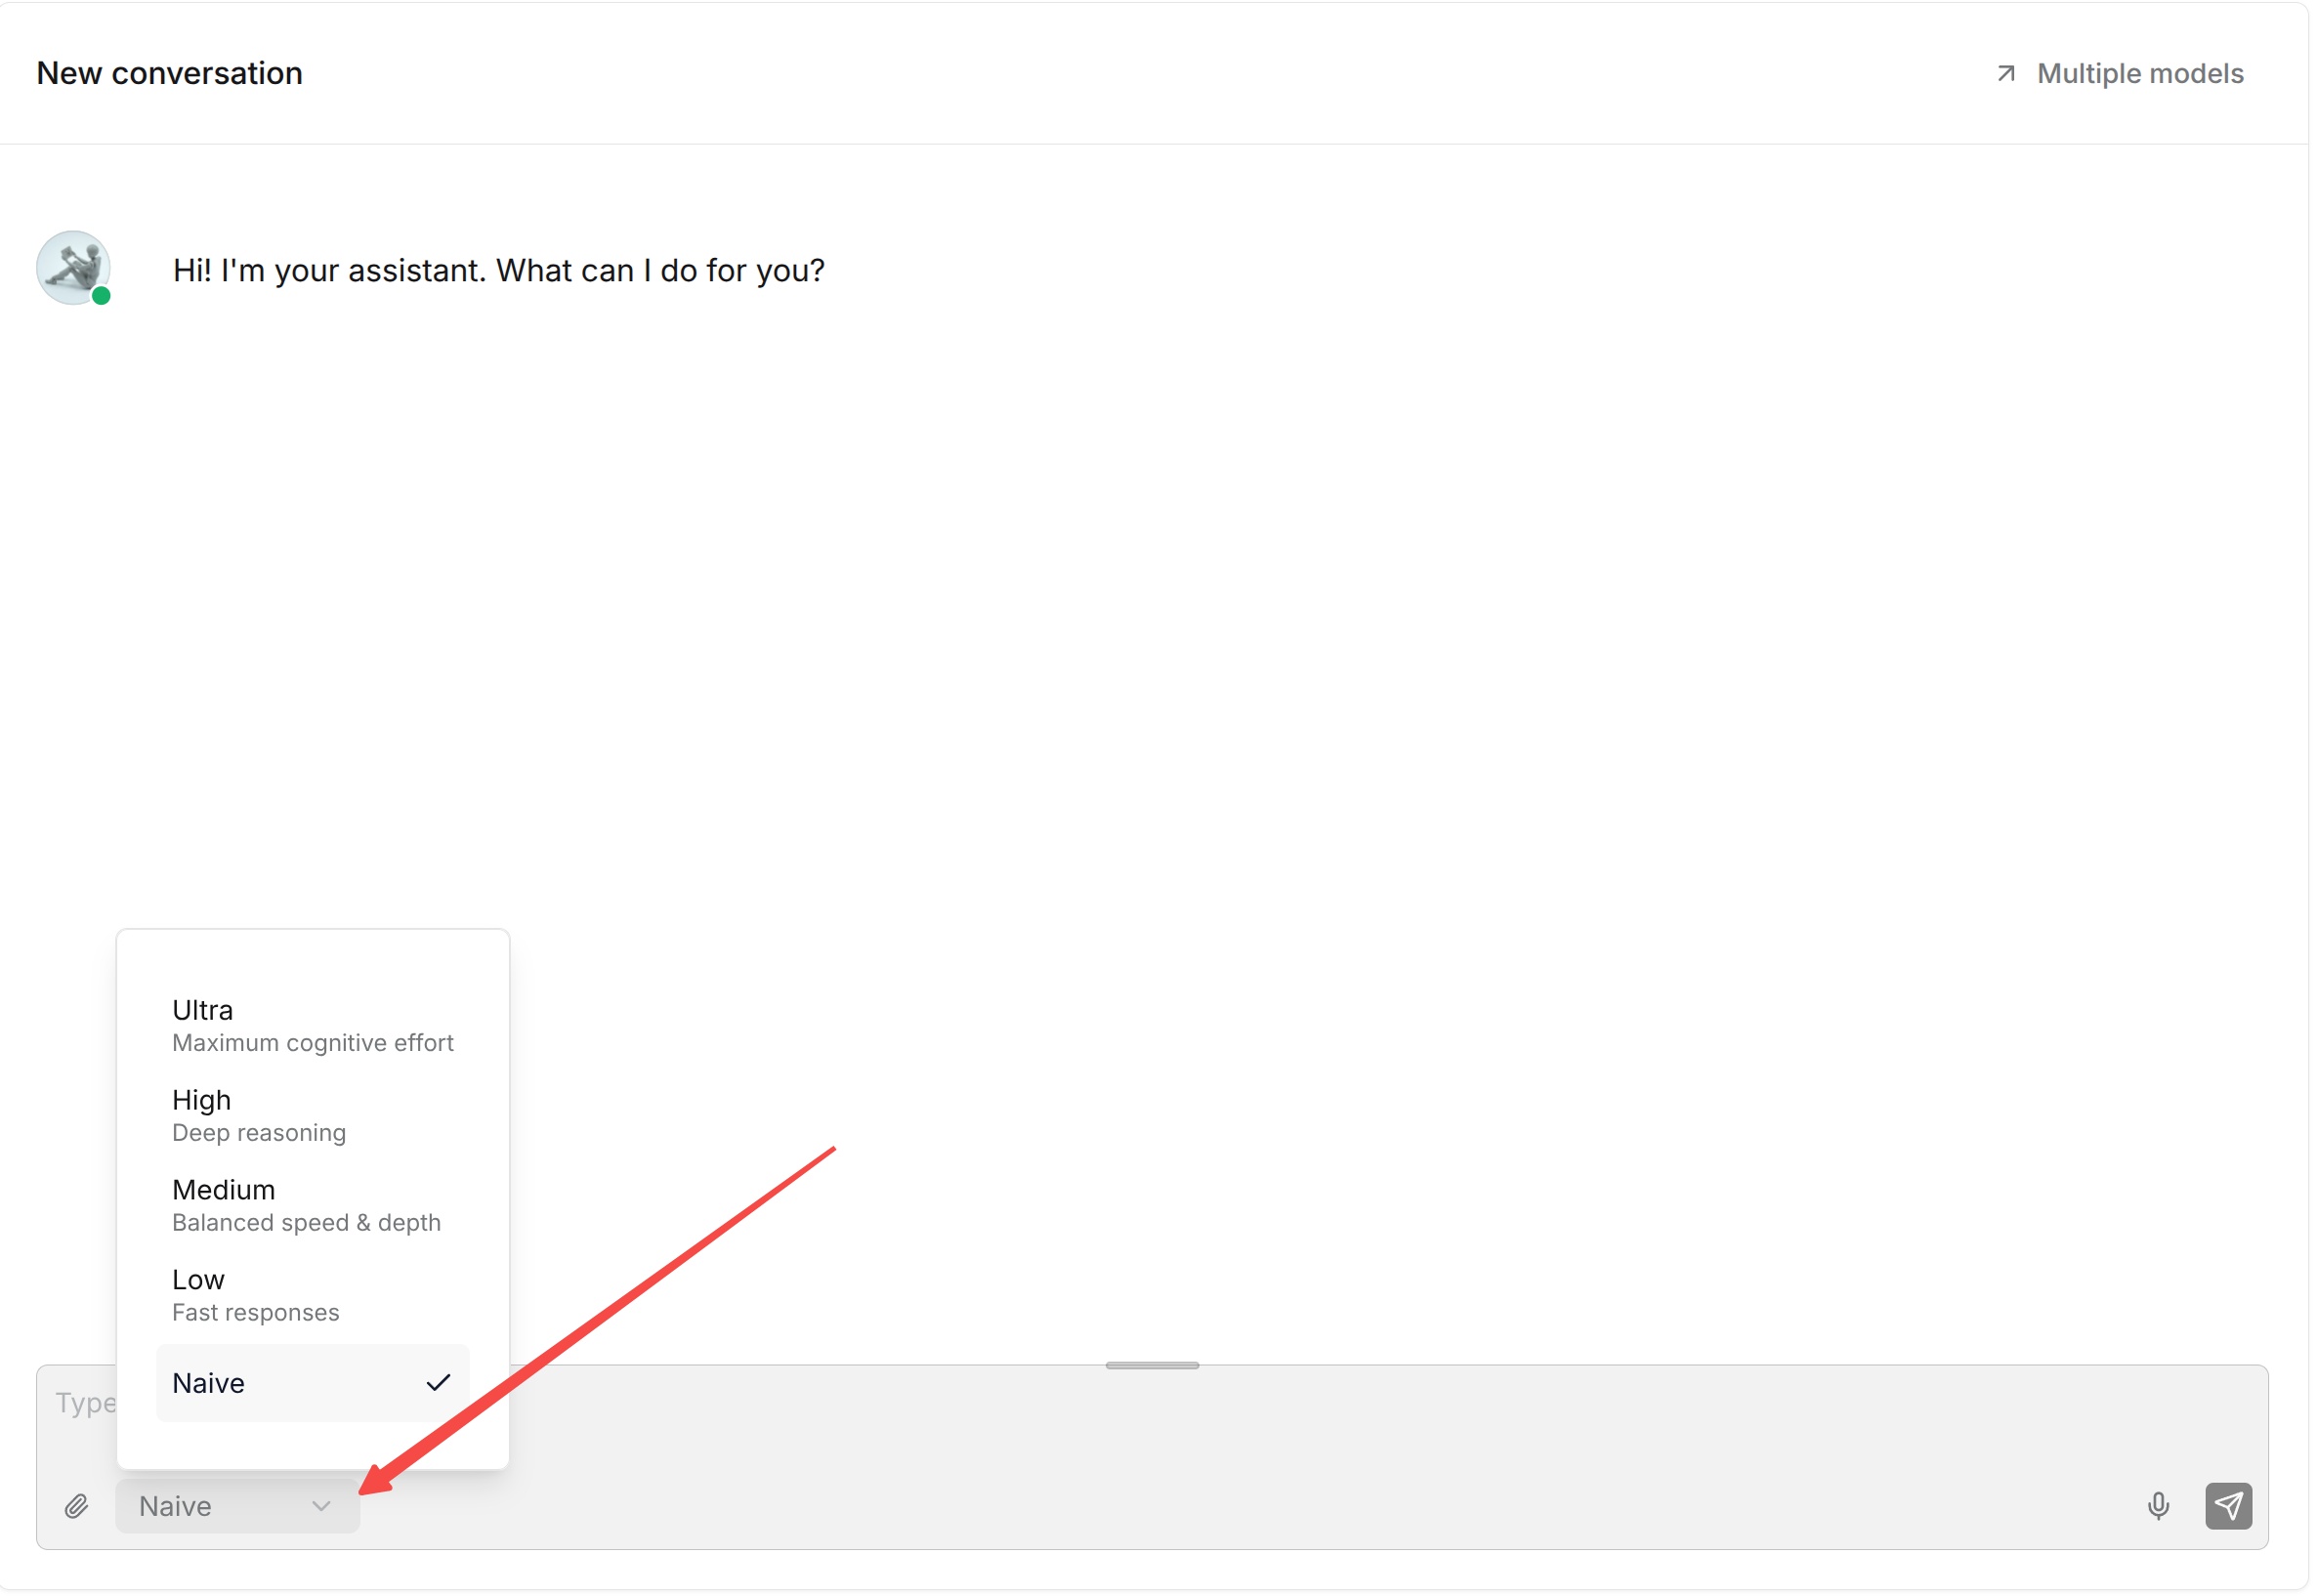
Before asking a question, select **Naive**, **Low**, **Medium**, **High**, or **Ultra** from the Thinking menu near the message box.
|
||||
|
||||
Retrieval means searching for evidence before answering. If a dataset is associated with the Chat, the system retrieves relevant chunks. If web search is enabled, or the current version provides PageIndex or Graph capabilities, those sources can also be used as supplemental evidence. The final answer should be based on the retrieved content.
|
||||
|
||||
- **None**: Performs retrieval without complex analysis. Use it for straightforward factual questions when identifiers, terms, or locations are clearly present in a document. It generally uses one query and responds fastest. It can be used together with empty responses and citations.
|
||||
- **Low**: Performs slightly more retrieval than **None** while remaining fast. It is suitable for enhanced basic retrieval, but not for multi-step comparisons or complex judgments.
|
||||
- **Medium** (recommended starting point): Suitable for most formal dataset Q&A, questions with multiple conditions or context, and summaries of multiple paragraphs. It first clarifies or rewrites the question, then retrieves and integrates evidence.
|
||||
- **High**: Suitable for complex Q&A, cross-chapter or cross-document questions, process and policy explanations, comparisons, and multi-condition judgments. It splits the problem more actively and checks whether the evidence is sufficient, so it may take longer and invoke the model more often.
|
||||
- **Ultra**: Suitable for version-difference analysis, multi-document research, complex attribution, multi-hop relationships, and questions whose answers are distributed across several documents. It performs the most retrieval and analysis, generally takes the longest, and is not recommended as the default configuration for everyday Q&A.
|
||||
|
||||
If you are unsure which mode to choose, start with **Medium** for formal business Q&A. For simple questions or when speed is critical, use **None** or **Low**. If the answer is incomplete or requires cross-document comparison, move up to **High** or **Ultra**.
|
||||
|
||||
|
||||
|
||||
## Retrieval Augmentation Options
|
||||
|
||||
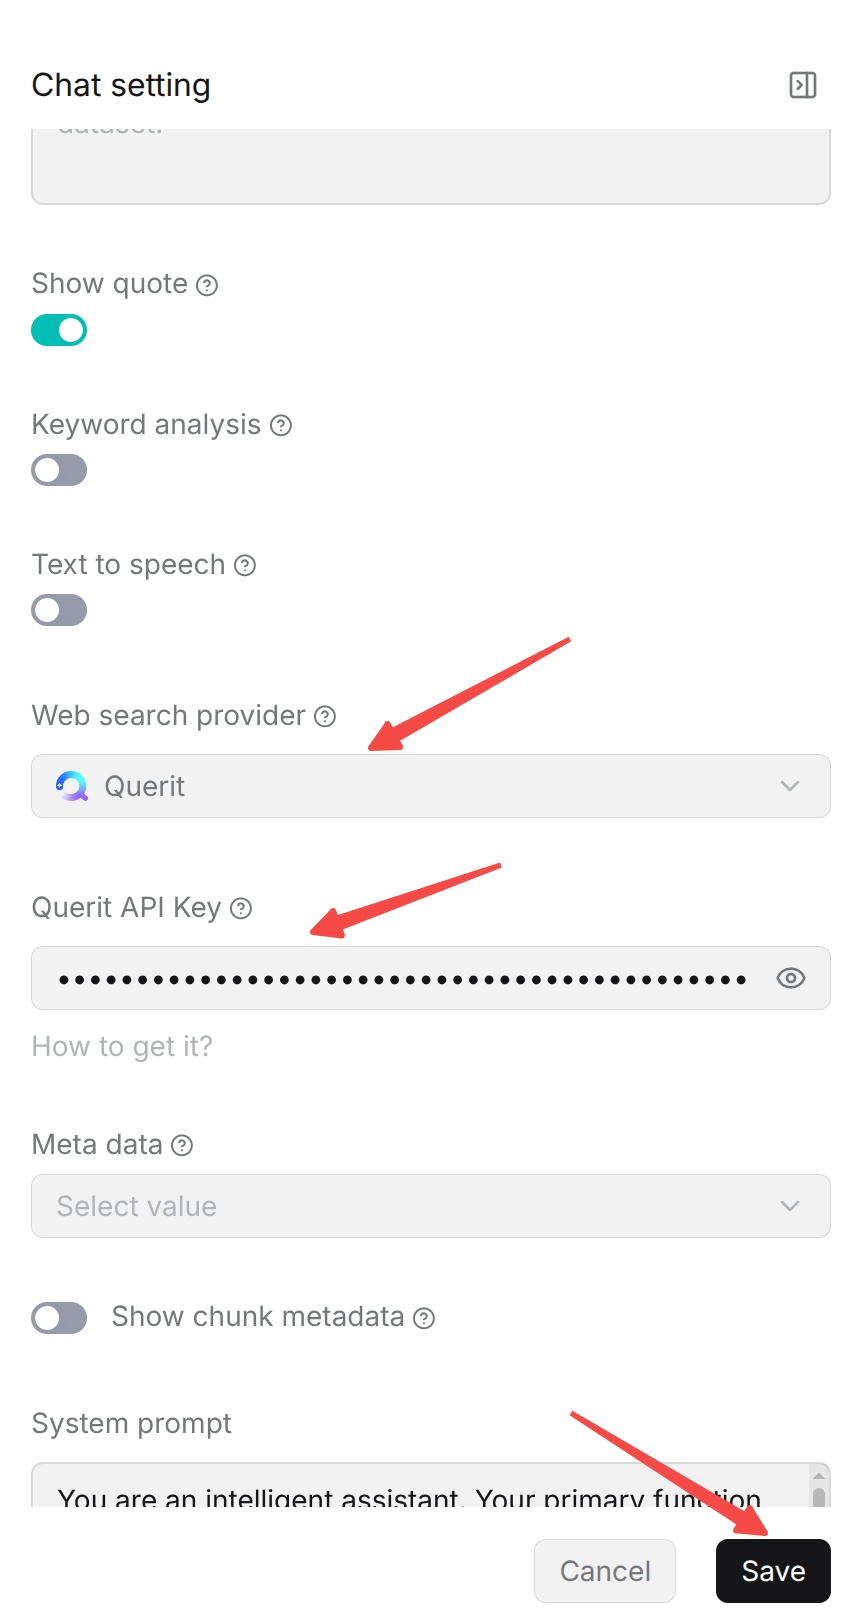
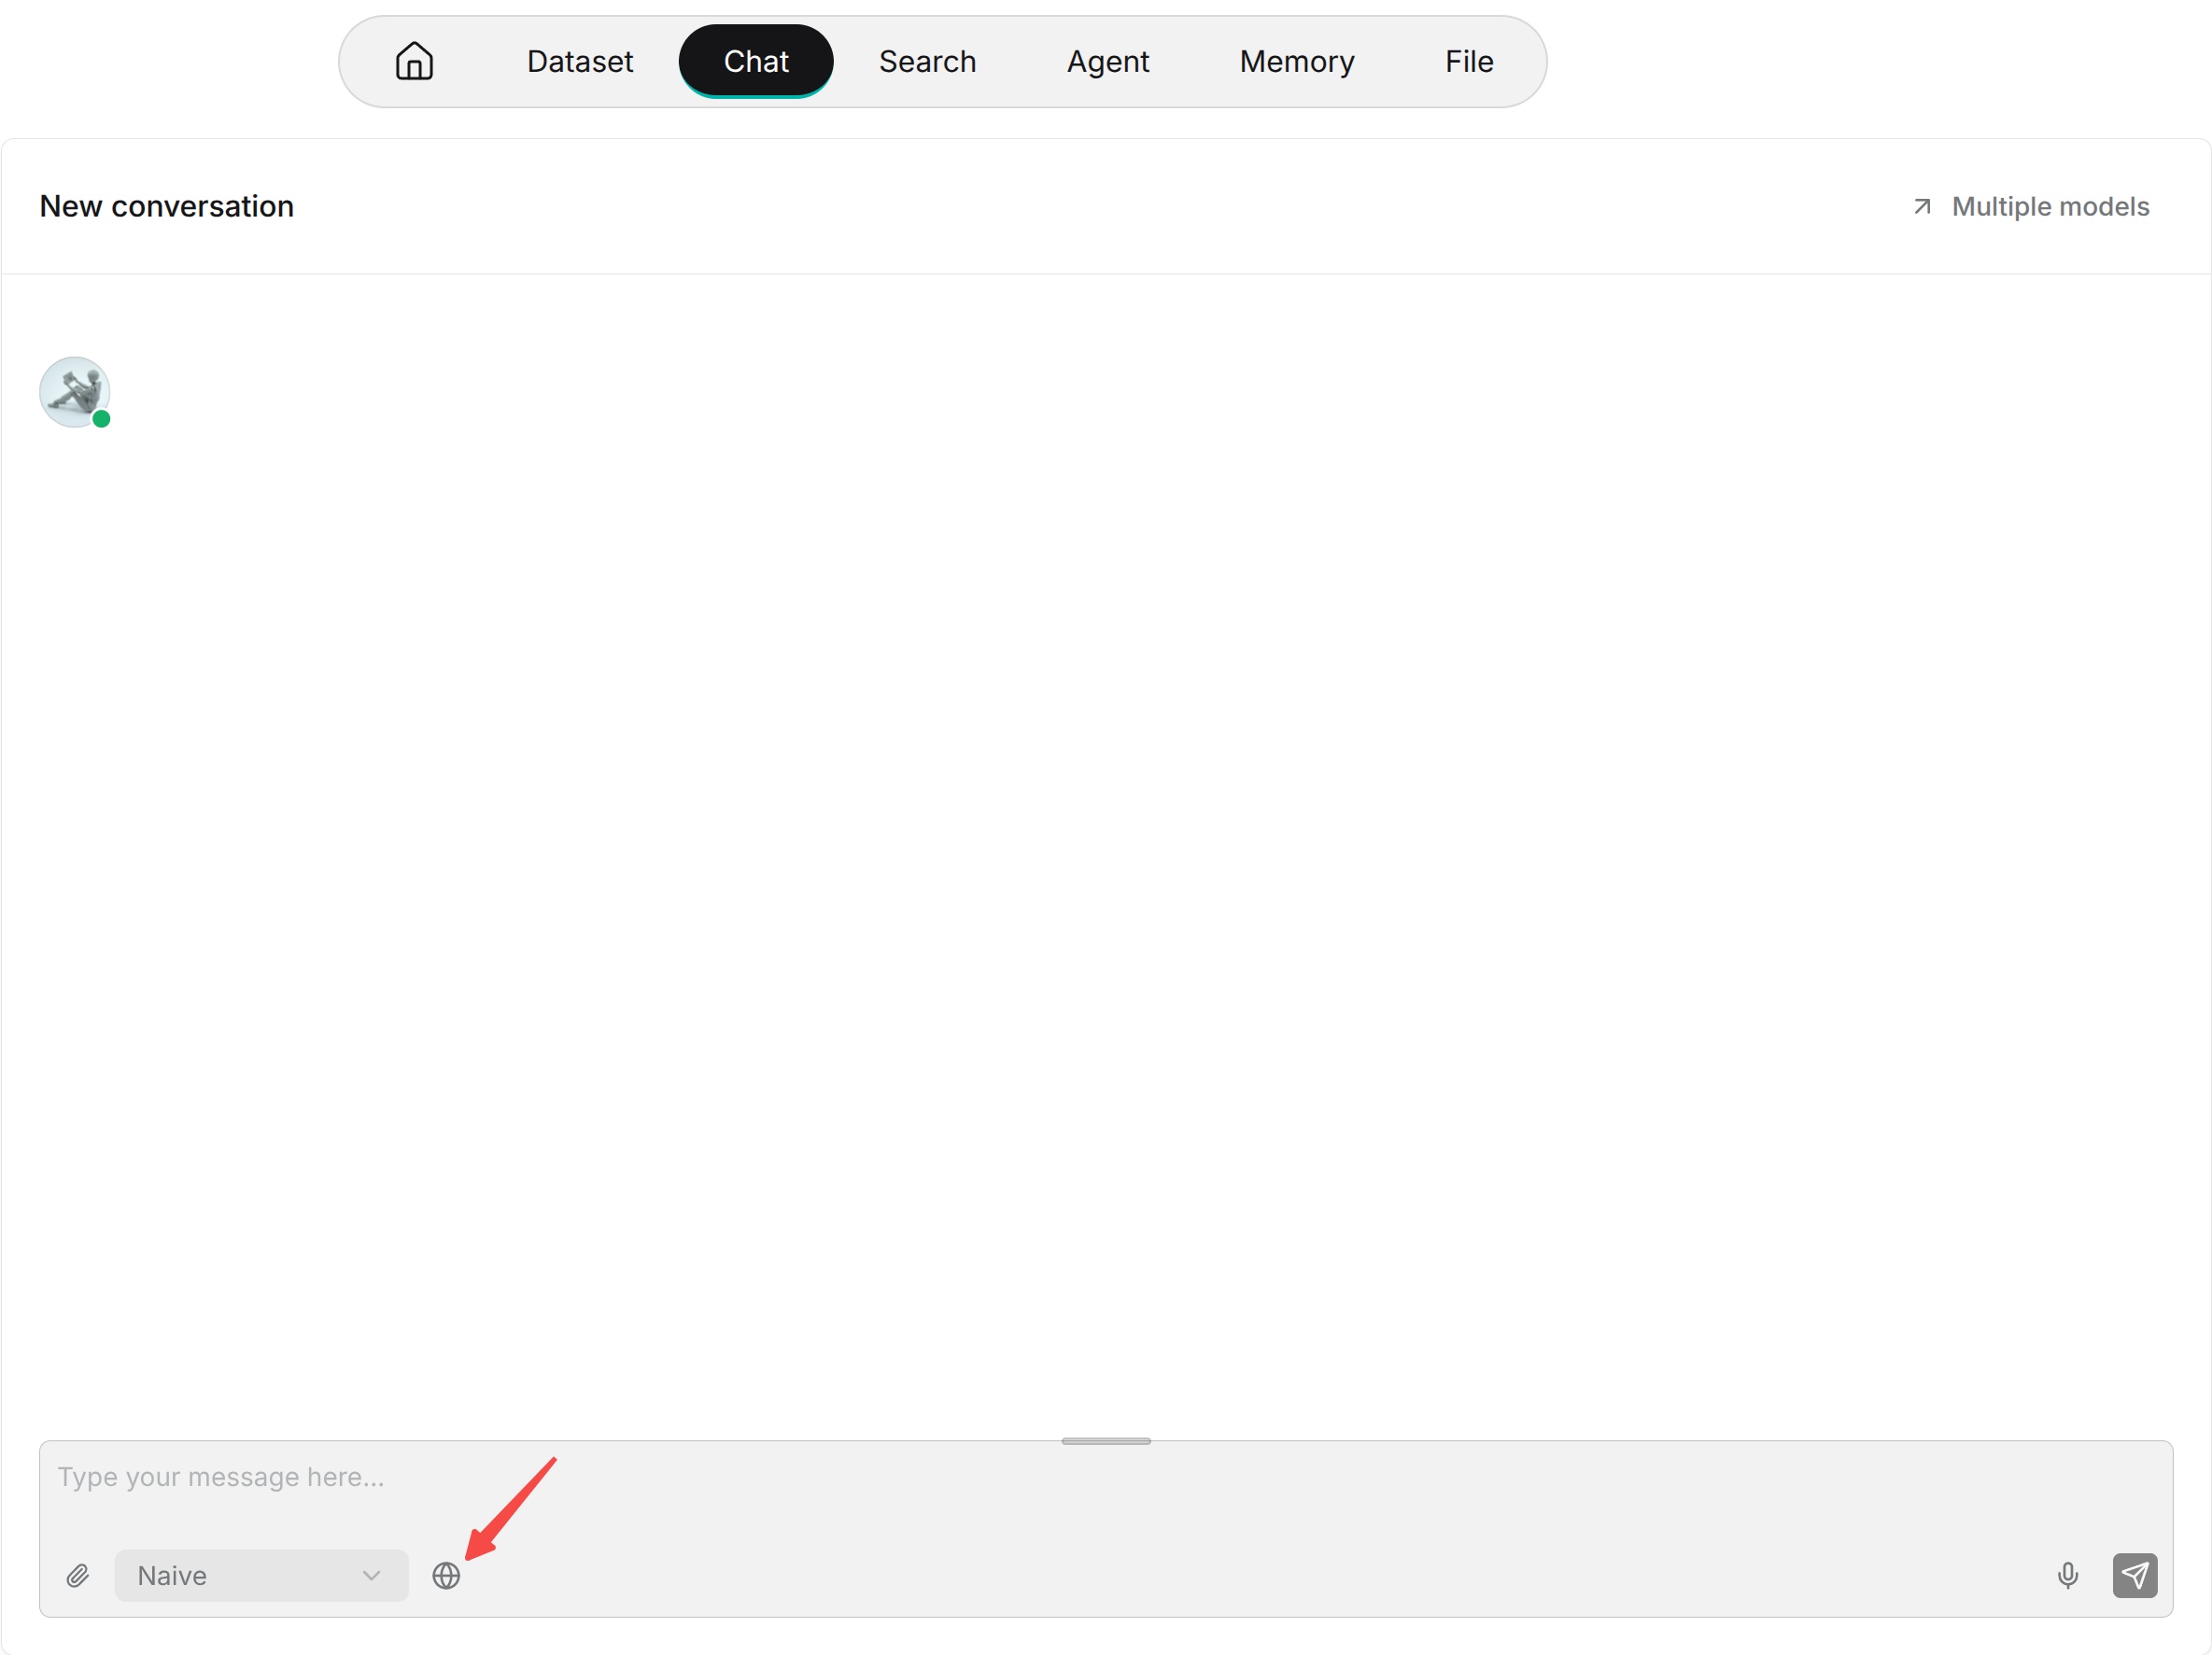
Retrieval augmentation options further optimize queries or expand information retrieval beyond basic dataset retrieval. Enable them according to the actual question-answering scenario; you do not need to enable every option.
|
||||
|
||||
- **Keyword analysis**: Analyzes the user's question and uses the extracted keywords to assist retrieval. It is suitable for questions with distinctive keywords, such as product names, technical terms, and reference numbers.
|
||||
- **Multi-turn conversation optimization**: Uses the conversation history to optimize the current retrieval query, helping the system understand context, references, and omitted information in a continuous conversation. It is suitable for multi-turn conversations about the same topic.
|
||||
- **Cross-language search**: Improves retrieval across languages. When the question language differs from the language of the dataset documents, this option can improve the recall of cross-language content.
|
||||
|
||||
|
||||
|
||||
|
||||
|
||||
## Answer and Display Settings
|
||||
|
||||
Answer and display settings control how generated content is presented and output. They generally do not change the dataset retrieval scope, but affect how citations, metadata, and voice content are presented to users.
|
||||
|
||||
- **Show citations**: When enabled, Chat displays the dataset content cited in the answer and its source, allowing users to inspect the evidence and trace it to the original document. When disabled, citation information is not shown.
|
||||
- **Show chunk metadata**: When enabled, citations display metadata for the corresponding chunk, such as the source, author, and date fields configured for the document. This supplements citation context and helps users understand the source and attributes of the cited content.
|
||||
- **Text-to-speech**: Select the model used to convert text answers to speech. Once configured, Chat can output generated text as speech. Leave it disabled if voice output is not needed. Before using this feature, configure an available text-to-speech (TTS) model.
|
||||
@@ -0,0 +1,66 @@
|
||||
---
|
||||
sidebar_position: 1
|
||||
title: Feature Overview and Creation
|
||||
sidebar_label: Feature Overview and Creation
|
||||
slug: /chat_feature_overview_and_creation
|
||||
sidebar_custom_props:
|
||||
categoryIcon: LucideBot
|
||||
---
|
||||
|
||||
# Feature Overview and Creation
|
||||
|
||||
Chat is used to create dataset-based question-answering applications. After configuring the datasets, large language model, system prompt, and retrieval parameters for a Chat, users can ask questions based on dataset content in the chat interface.
|
||||
|
||||
Chat supports dataset retrieval, citation display, keyword analysis, multi-turn conversation optimization, cross-language search, web search, and other capabilities.
|
||||
|
||||
After creating a Chat, configure its datasets, model, system prompt, and retrieval parameters for the actual business scenario before using it to answer questions. You can modify these settings later.
|
||||
|
||||
## Create a Chat
|
||||
|
||||
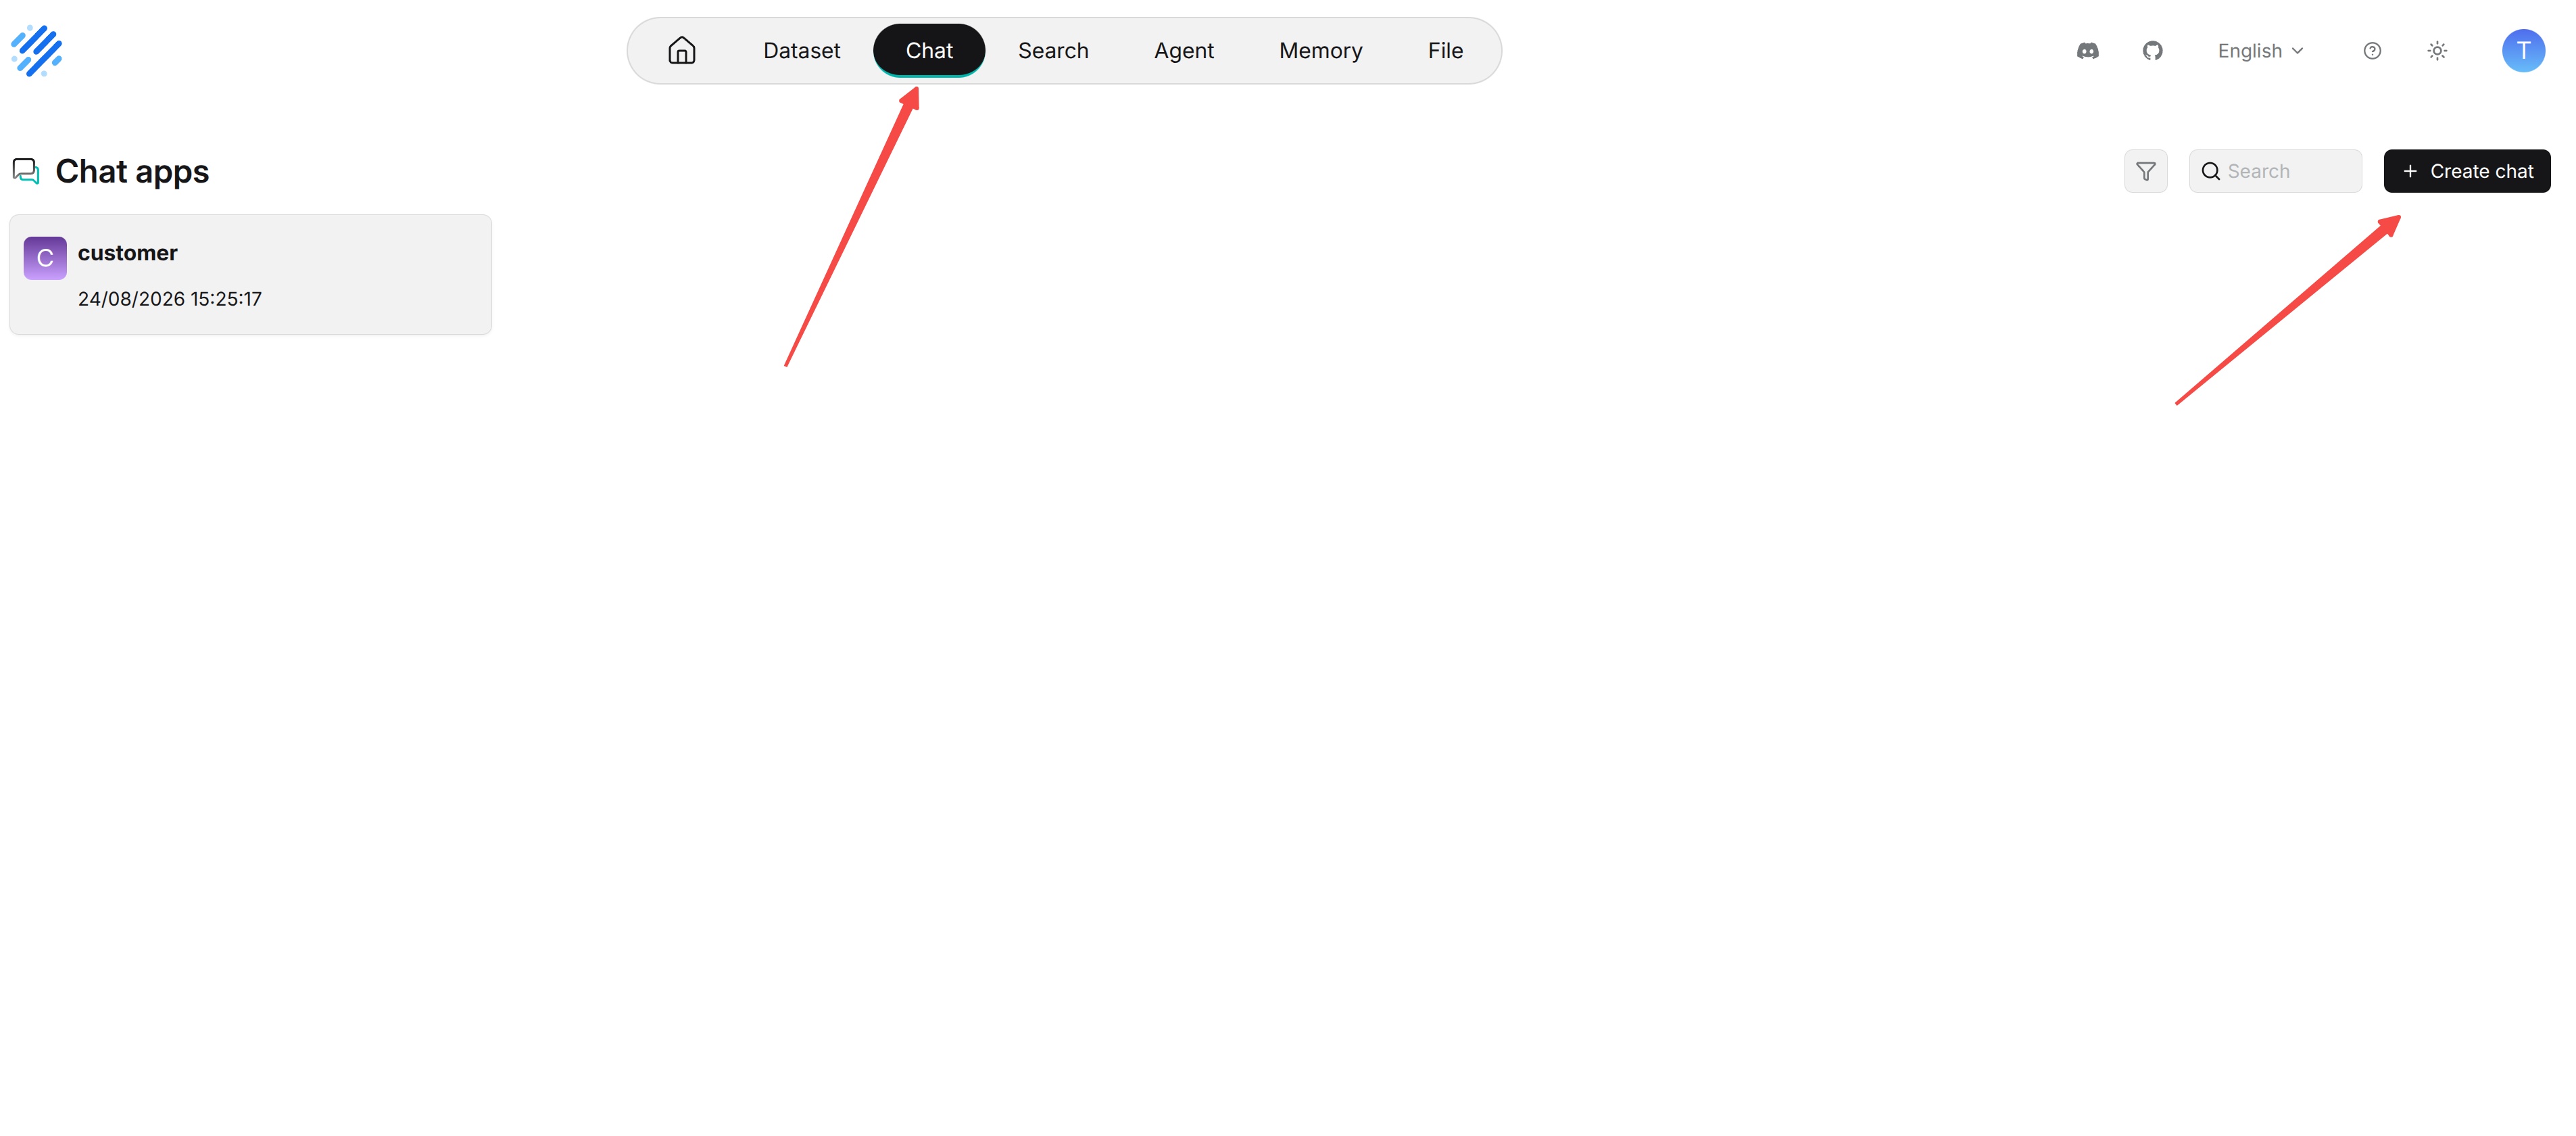
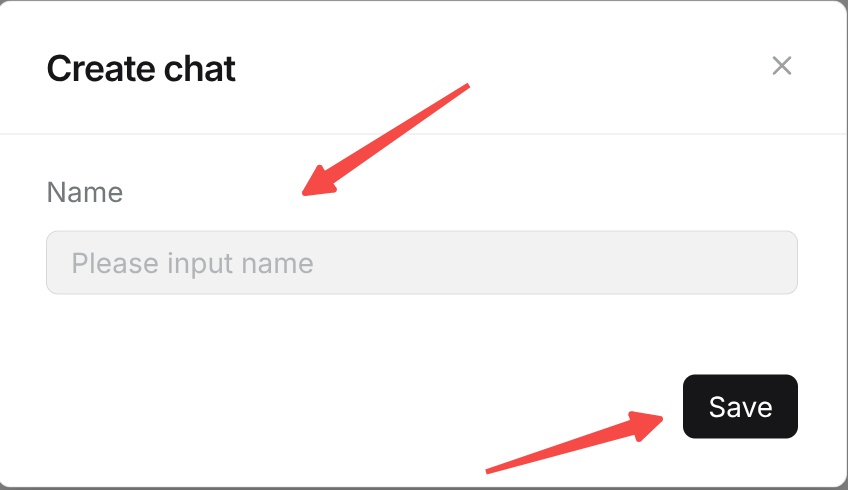
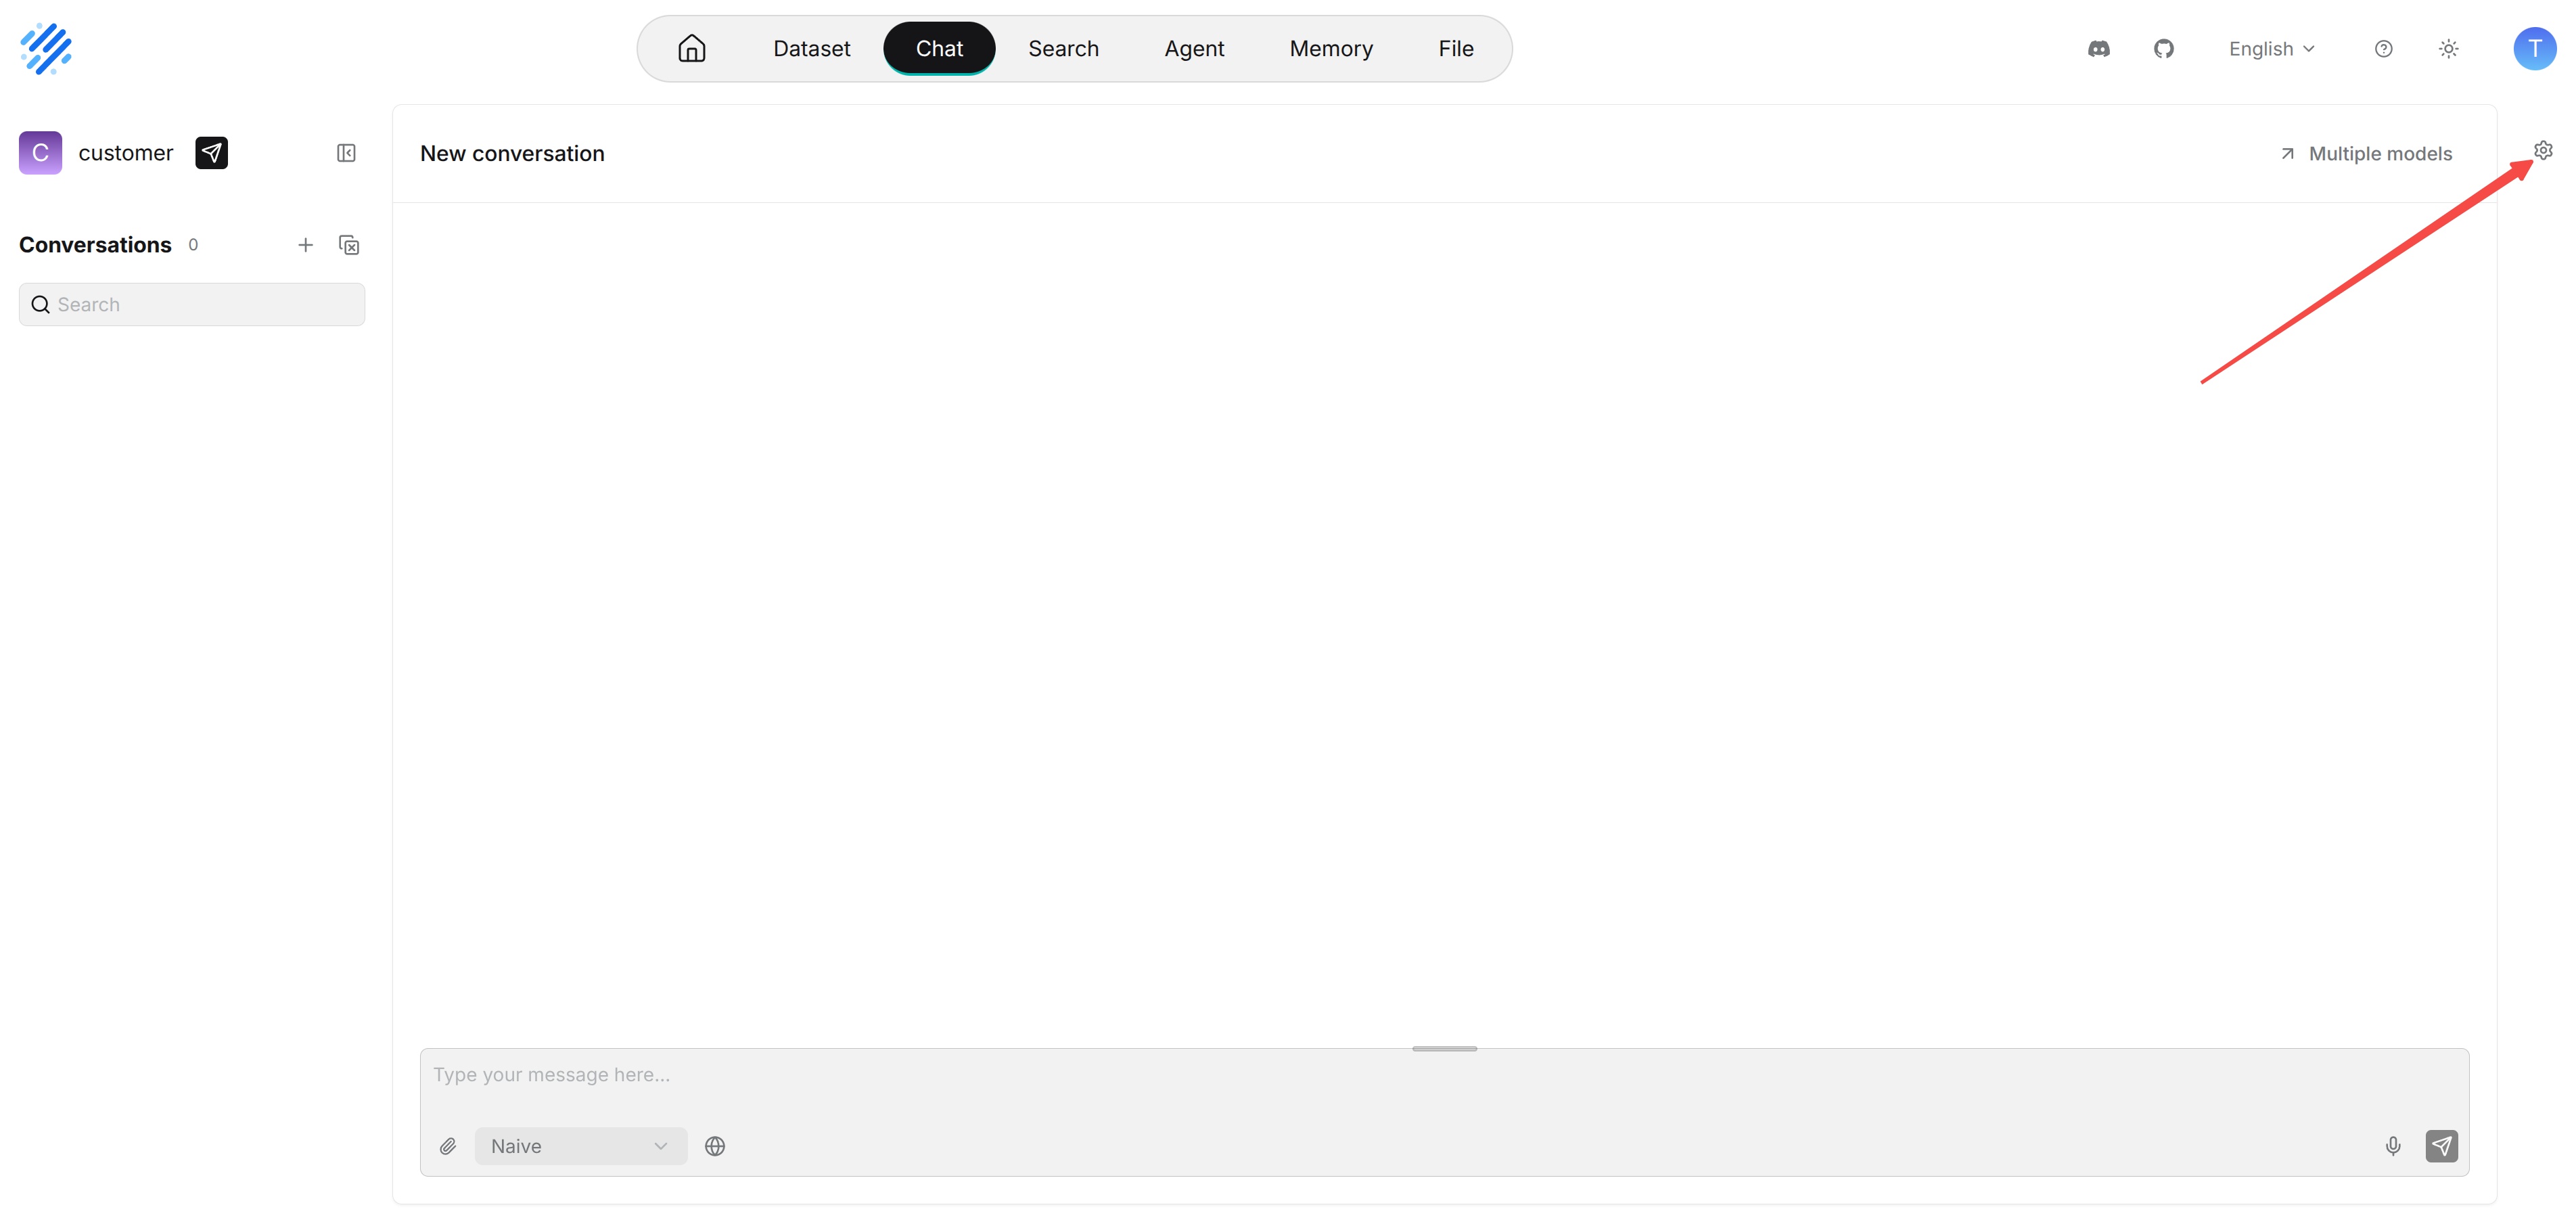
1. Select **Chat** in the left navigation bar.
|
||||
2. Click **Create chat**.
|
||||
3. Enter a name for the Chat.
|
||||
4. Confirm the creation.
|
||||
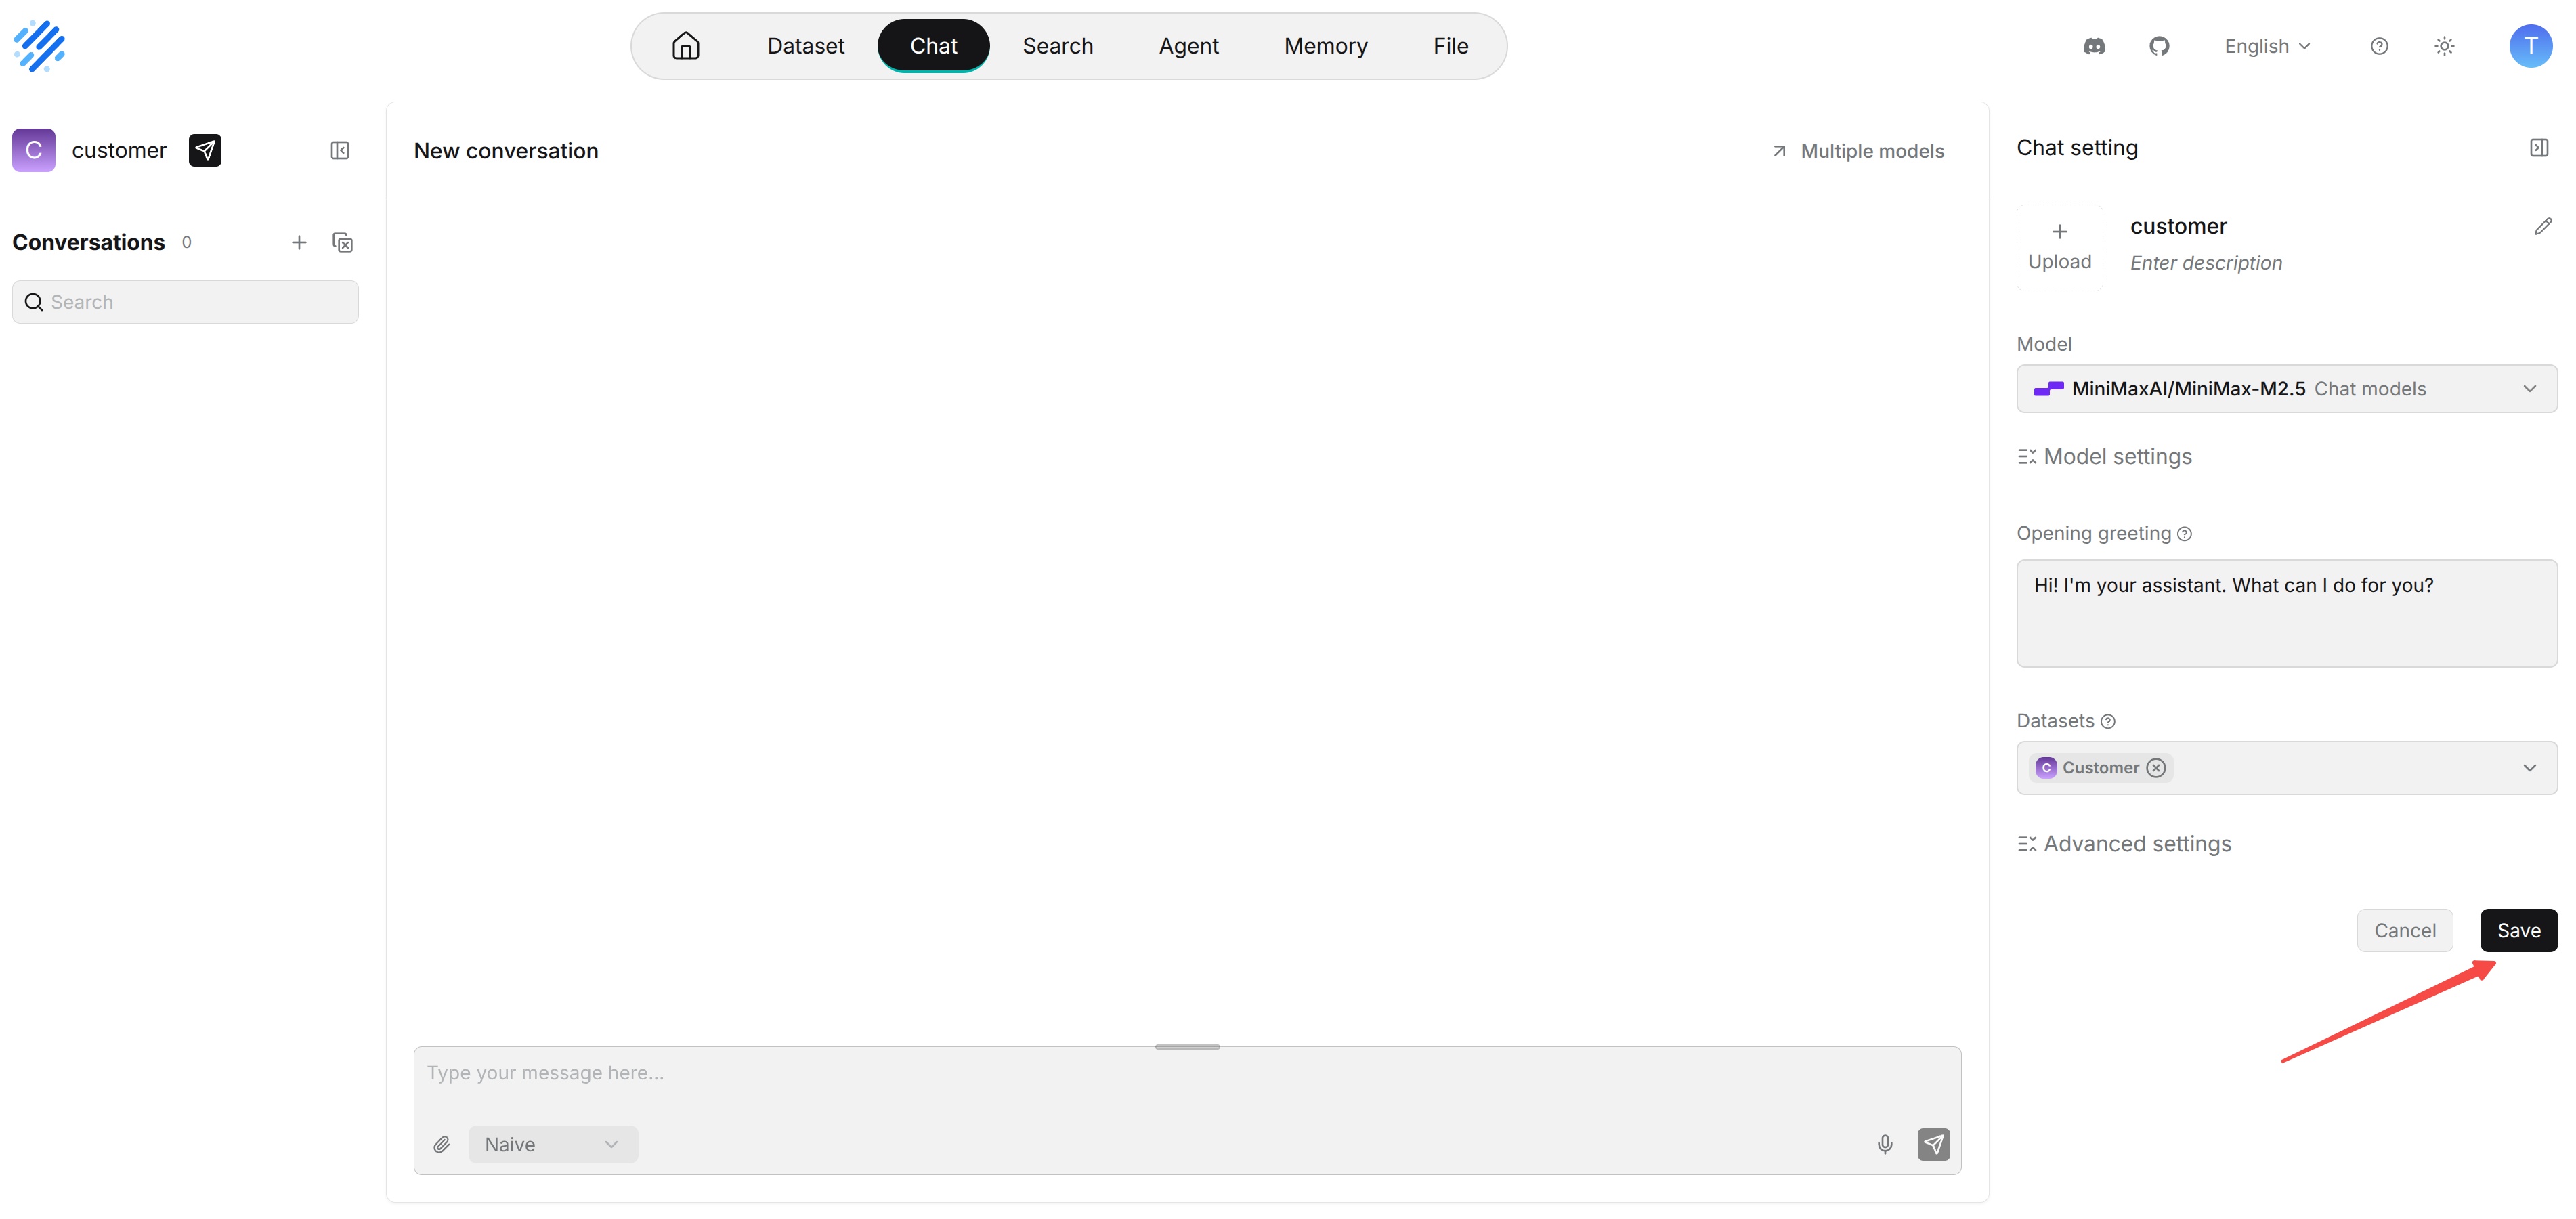
5. Open **Chat setting**, then configure the datasets, model, system prompt, and retrieval parameters.
|
||||
6. Save the setting, then open the chat window to test and use the Chat.
|
||||
|
||||
|
||||
|
||||
|
||||
|
||||
|
||||
|
||||
|
||||
|
||||
You do not need to complete every setting when creating a Chat. You can return to the corresponding Chat from the Chat list and update its configuration later.
|
||||
|
||||
## Basic Information
|
||||
|
||||
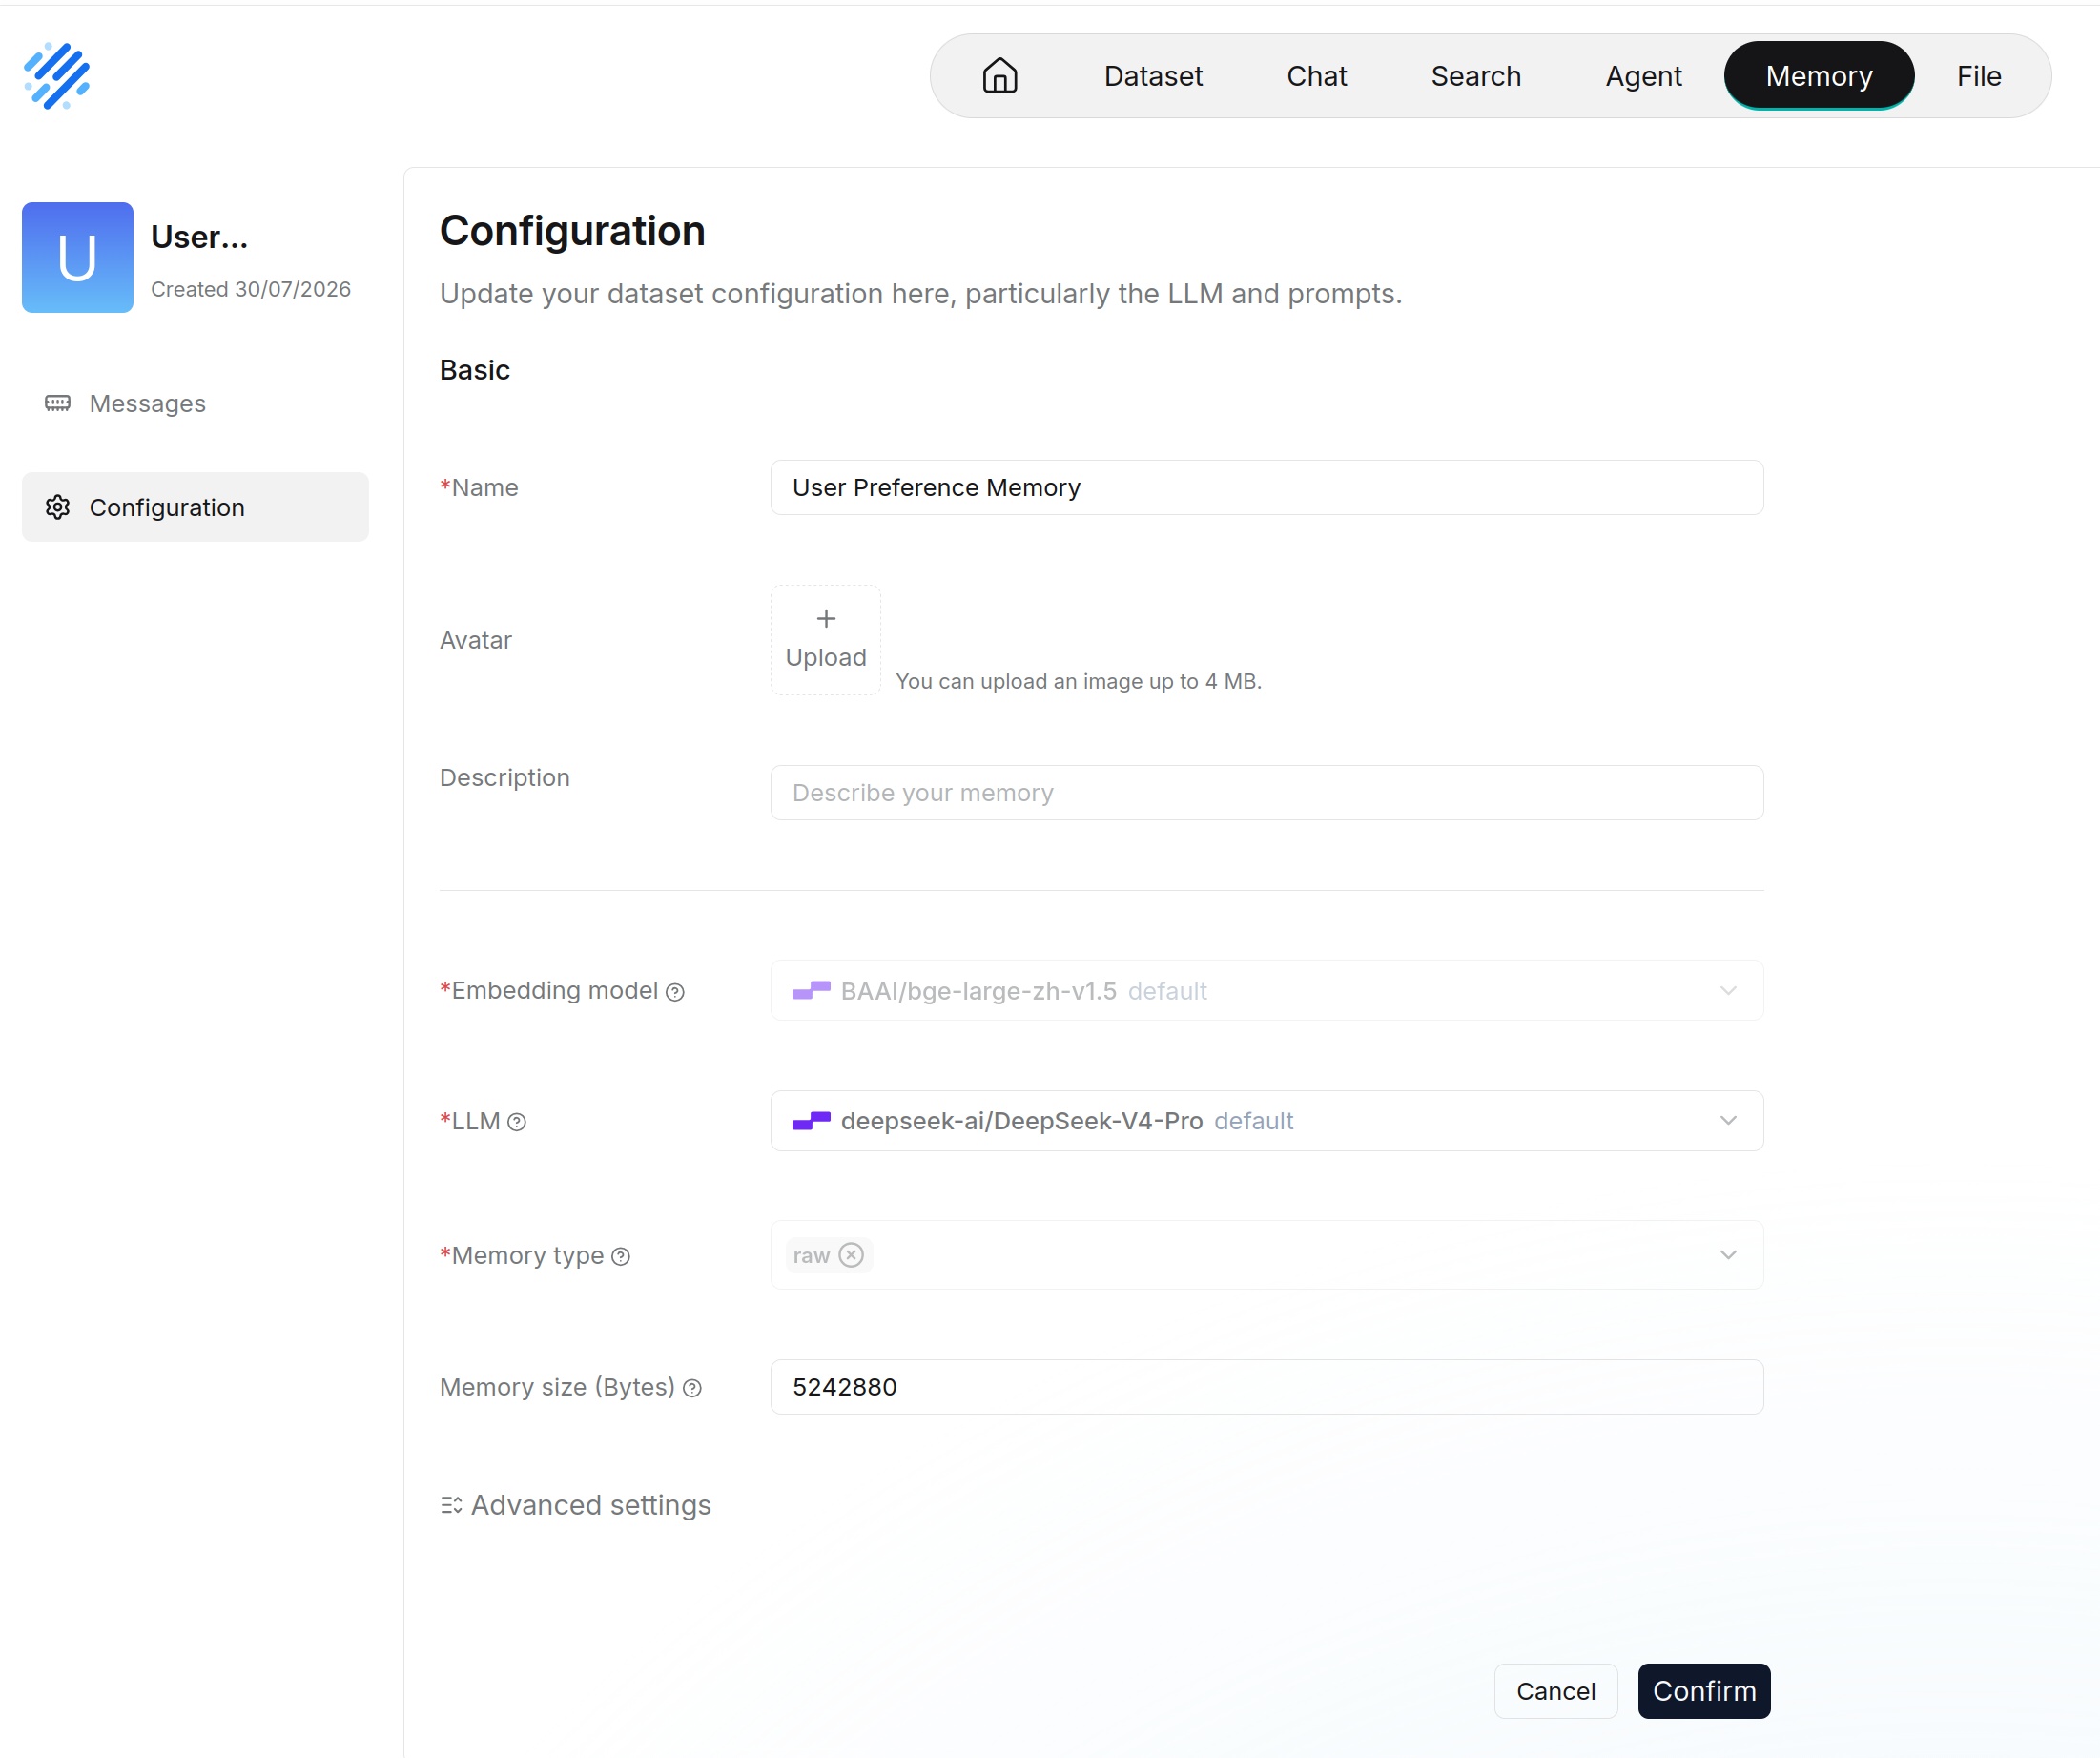
You can set the following basic information for a Chat:
|
||||
|
||||
- **Name**: The display name used to identify the Chat in the Chat list, published pages, or embedded scenarios. Use a clear name that reflects its business scope or purpose.
|
||||
- **Avatar**: The image displayed for the Chat. Select a brand, product, or general-purpose icon according to the scenario.
|
||||
- **Description**: A brief description of the Chat's purpose, service scope, intended audience, or dataset coverage.
|
||||
|
||||
|
||||
|
||||
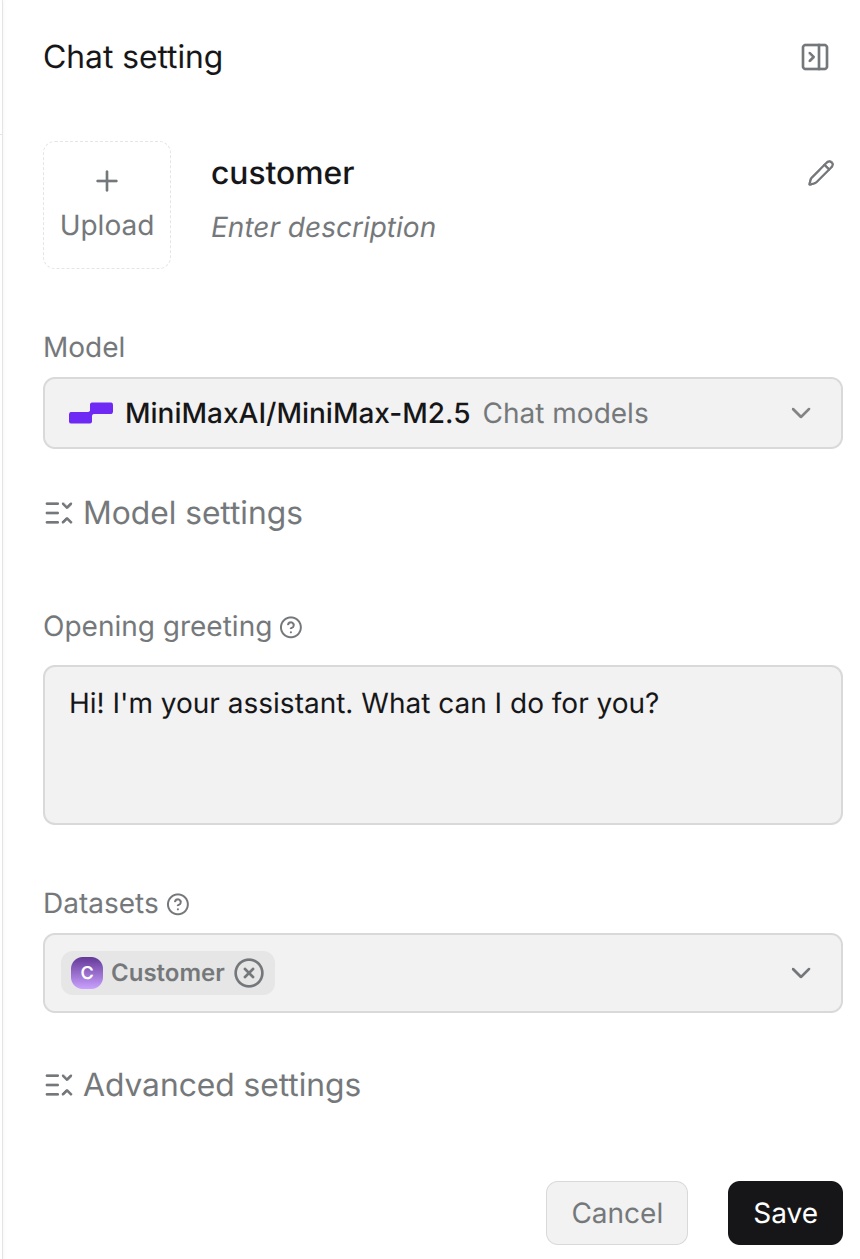
## Configure a Chat
|
||||
|
||||
Complete the main Chat settings according to the actual scenario:
|
||||
|
||||
- **Dataset**: Select the dataset the Chat can retrieve from. When answering a question, the system searches for relevant content in the associated dataset.
|
||||
- **Model**: Select the large language model used to generate answers.
|
||||
- **Retrieval configuration**: Configure the similarity threshold, vector similarity weight, Top N, and other settings to control the retrieval scope and results.
|
||||
- **Advanced settings**: Use the options available in the current version to further tune answer generation and retrieval behavior.
|
||||
|
||||
Save the setting and test it in the chat window.
|
||||
|
||||
|
||||
|
||||
Start with the default parameters for a basic test. Then gradually adjust the retrieval parameters and system prompt based on the quality of the actual answers.
|
||||
|
||||
## Modify an Existing Chat
|
||||
|
||||
You can modify an existing Chat at any time. Find the Chat in the Chat list, open **Chat setting**, update its datasets, model, system prompt, or retrieval parameters, and save the changes.
|
||||
|
||||
After changing the configuration, rerun tests with representative questions to confirm that the new settings meet expectations.
|
||||
@@ -1,27 +0,0 @@
|
||||
---
|
||||
sidebar_position: 3
|
||||
title: Implement Deep Research
|
||||
sidebar_label: Implement Deep Research
|
||||
slug: /implement_deep_research
|
||||
sidebar_custom_props: {
|
||||
categoryIcon: LucideScanSearch
|
||||
}
|
||||
---
|
||||
# Implement Deep Research
|
||||
|
||||
Implements deep research for agentic reasoning.
|
||||
|
||||
---
|
||||
|
||||
From v0.17.0 onward, RAGFlow supports integrating agentic reasoning in an AI chat.
|
||||
|
||||
|
||||
To activate this feature:
|
||||
|
||||
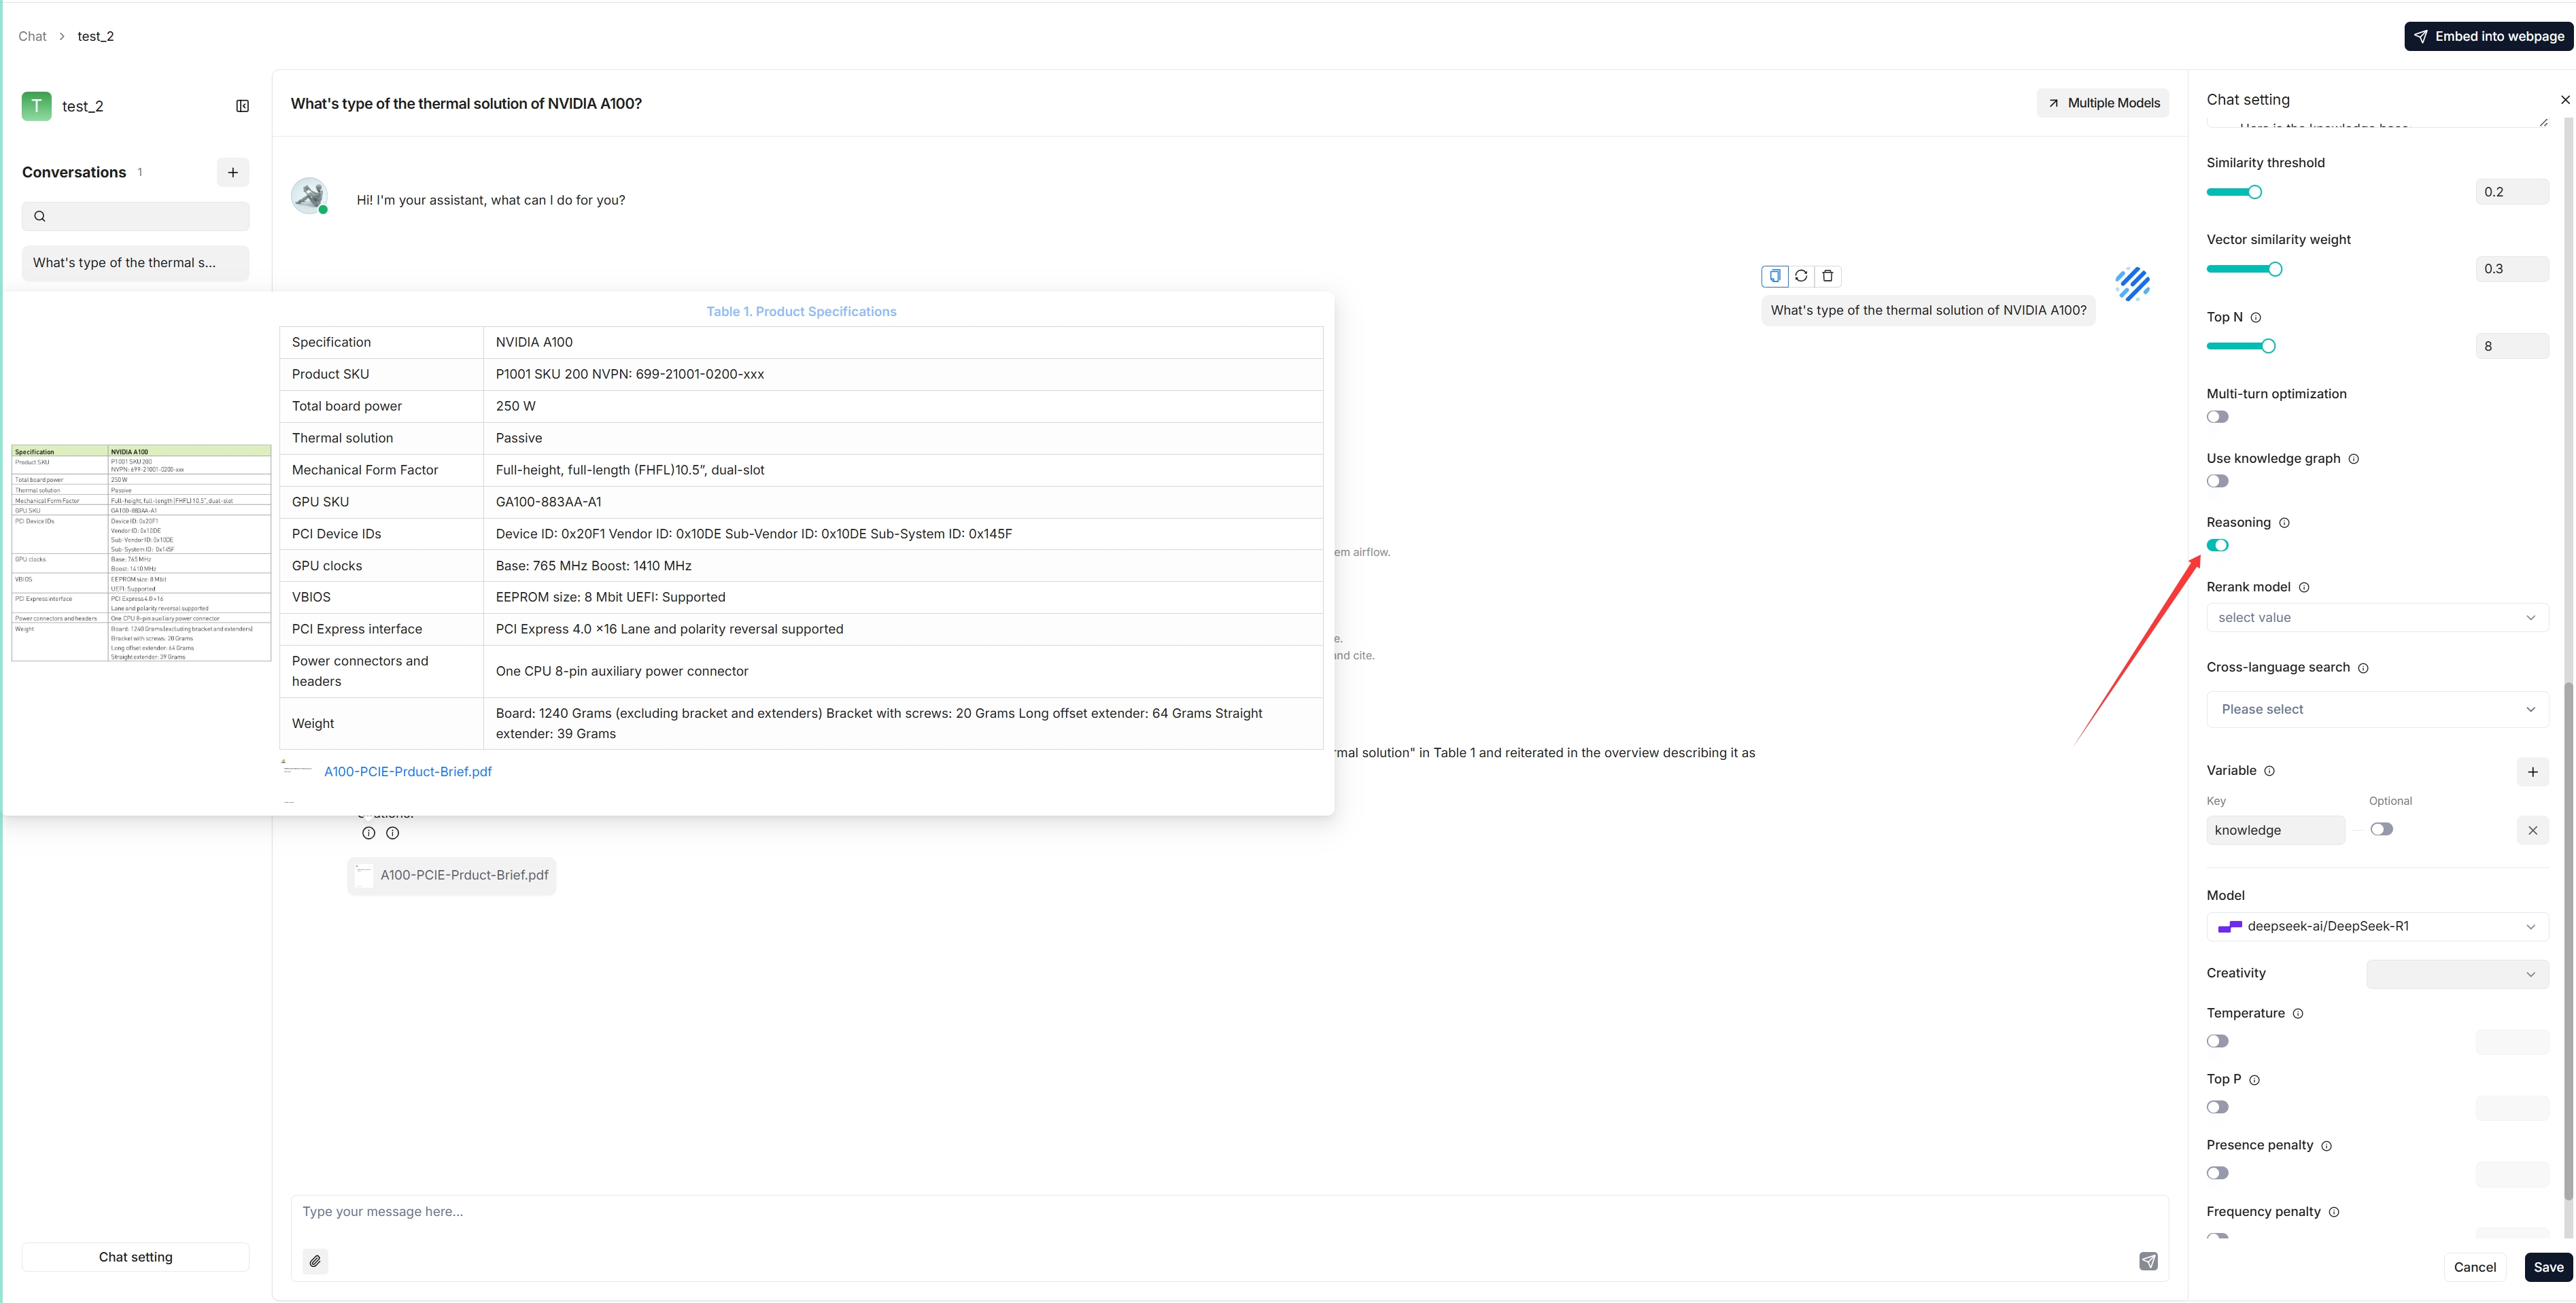
1. Enable the **Reasoning** toggle in **Chat setting**.
|
||||
|
||||
|
||||
|
||||
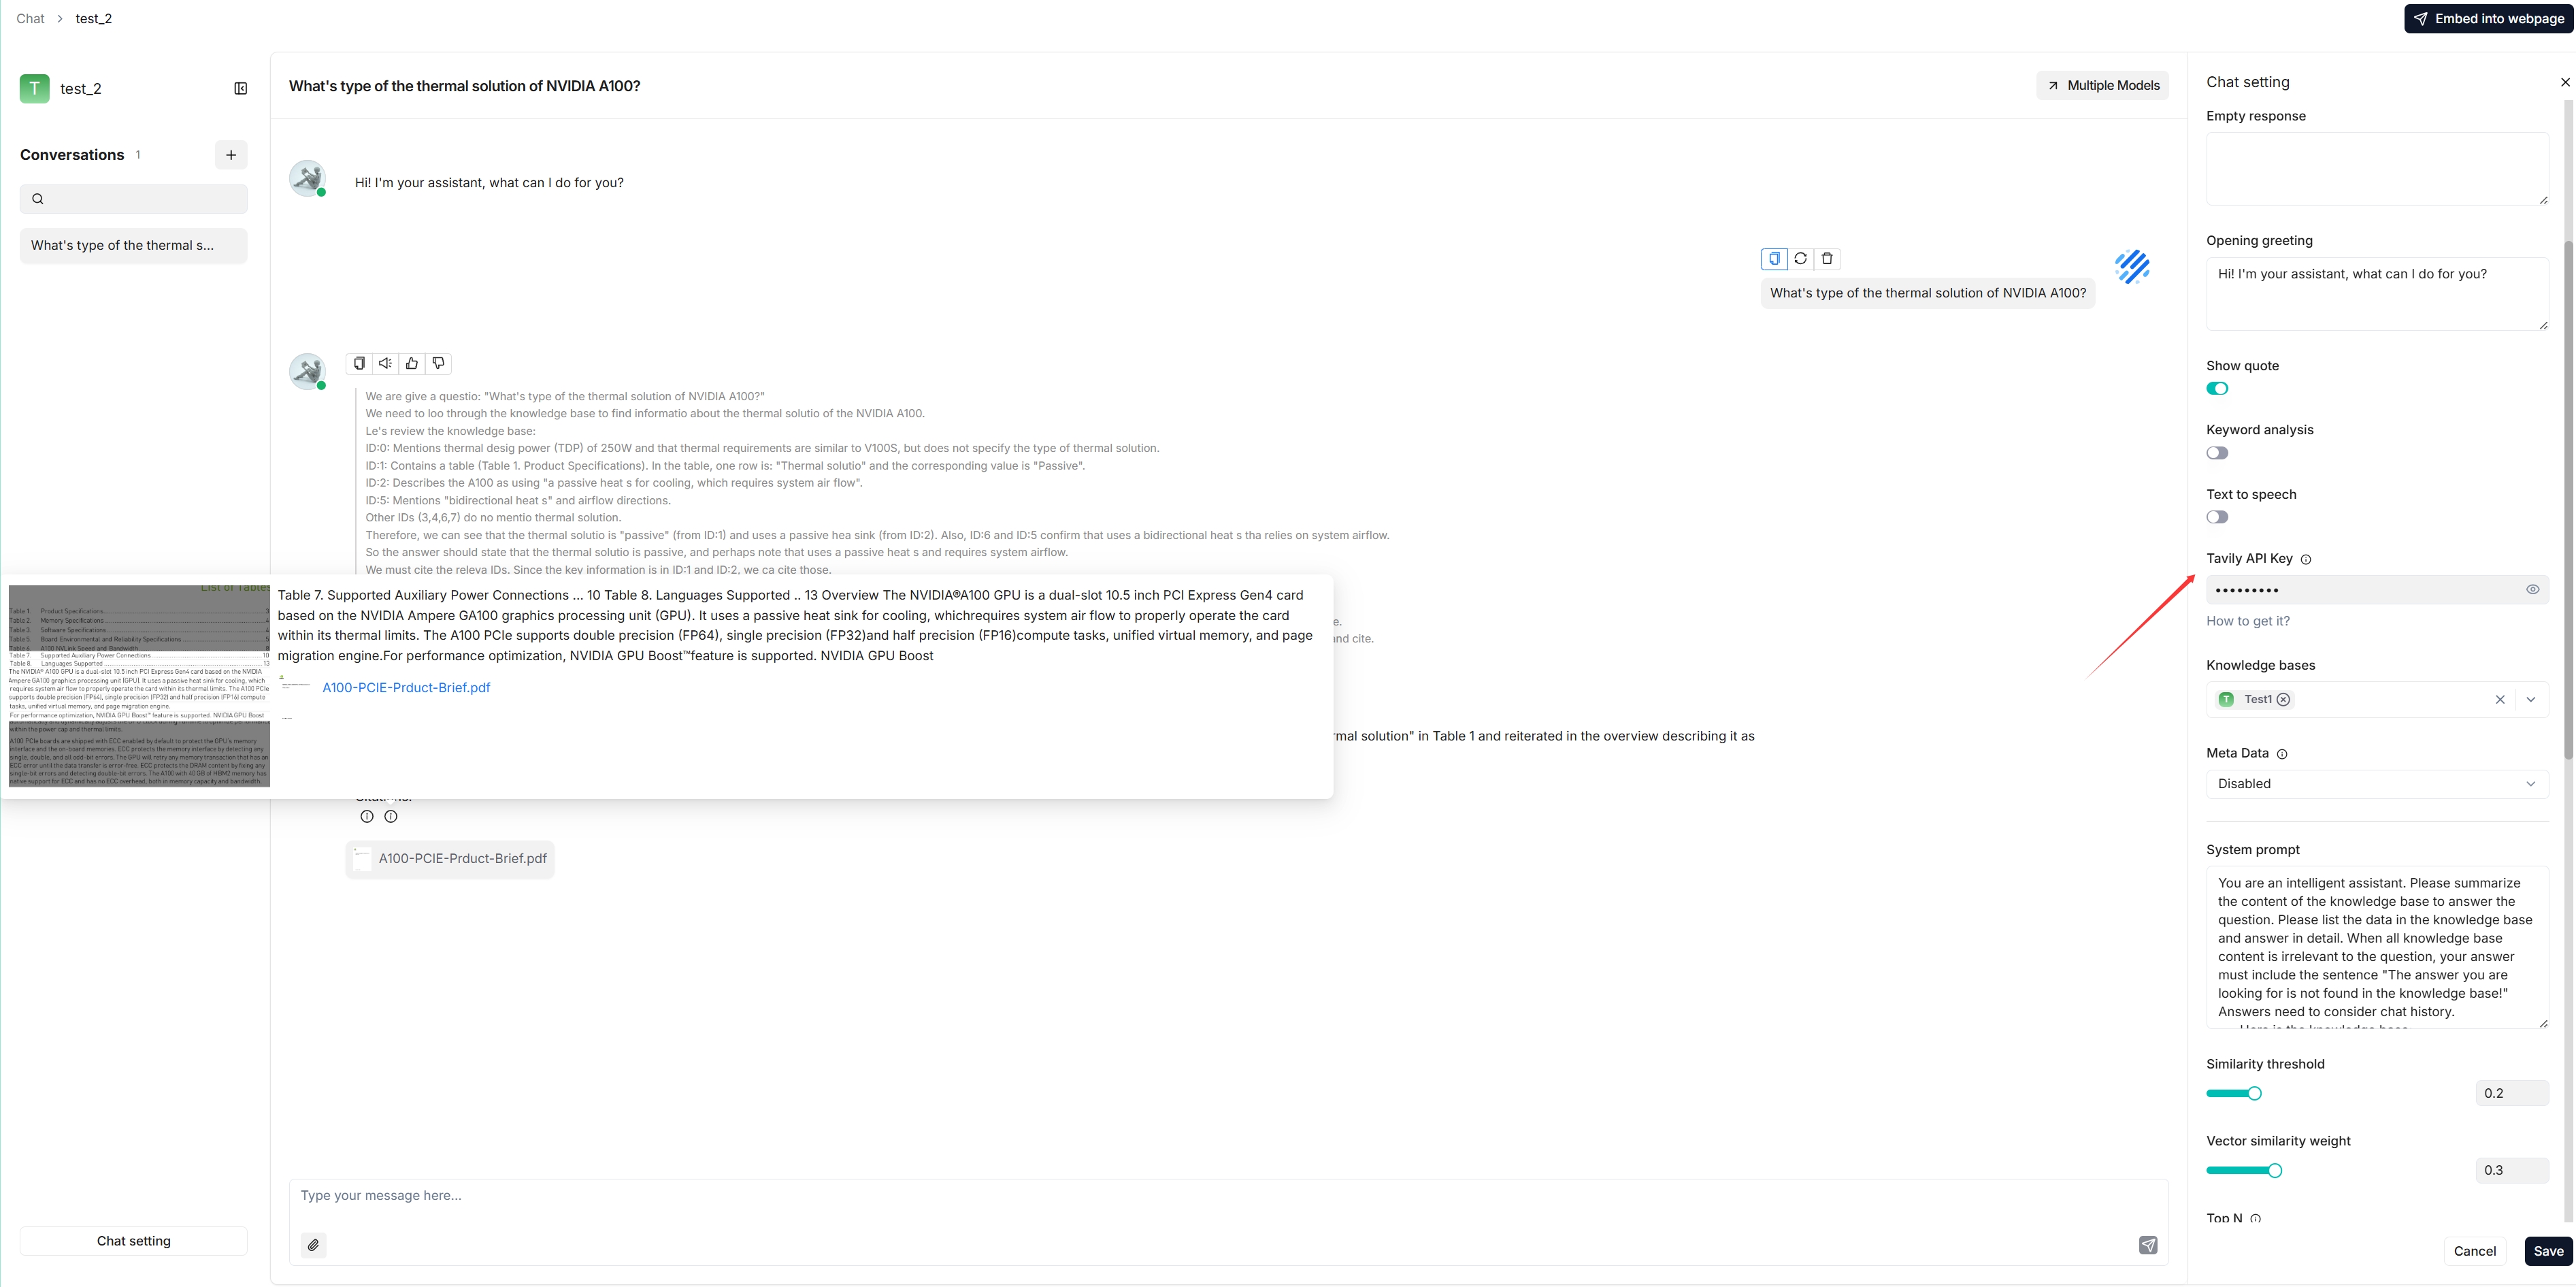
2. Enter the correct Tavily API key to leverage Tavily-based web search:
|
||||
|
||||
|
||||
@@ -1,119 +0,0 @@
|
||||
---
|
||||
sidebar_position: 4
|
||||
title: Set Variables
|
||||
sidebar_label: Set Variables
|
||||
slug: /set_chat_variables
|
||||
sidebar_custom_props: {
|
||||
categoryIcon: LucideVariable
|
||||
}
|
||||
---
|
||||
# Set Variables
|
||||
|
||||
Set variables to be used together with the system prompt for your LLM.
|
||||
|
||||
---
|
||||
|
||||
When configuring the system prompt for a chat model, variables play an important role in enhancing flexibility and reusability. With variables, you can dynamically adjust the system prompt to be sent to your model. In the context of RAGFlow, if you have defined variables in **Chat setting**, except for the system's reserved variable `{knowledge}`, you are required to pass in values for them from RAGFlow's [HTTP API](../../references/http_api_reference.md#converse-with-chat-assistant) or through its [Python SDK](../../references/python_api_reference.md#converse-with-chat-assistant).
|
||||
|
||||
:::danger IMPORTANT
|
||||
In RAGFlow, variables are closely linked with the system prompt. When you add a variable in the **Variable** section, include it in the system prompt. Conversely, when deleting a variable, ensure it is removed from the system prompt; otherwise, an error would occur.
|
||||
:::
|
||||
|
||||
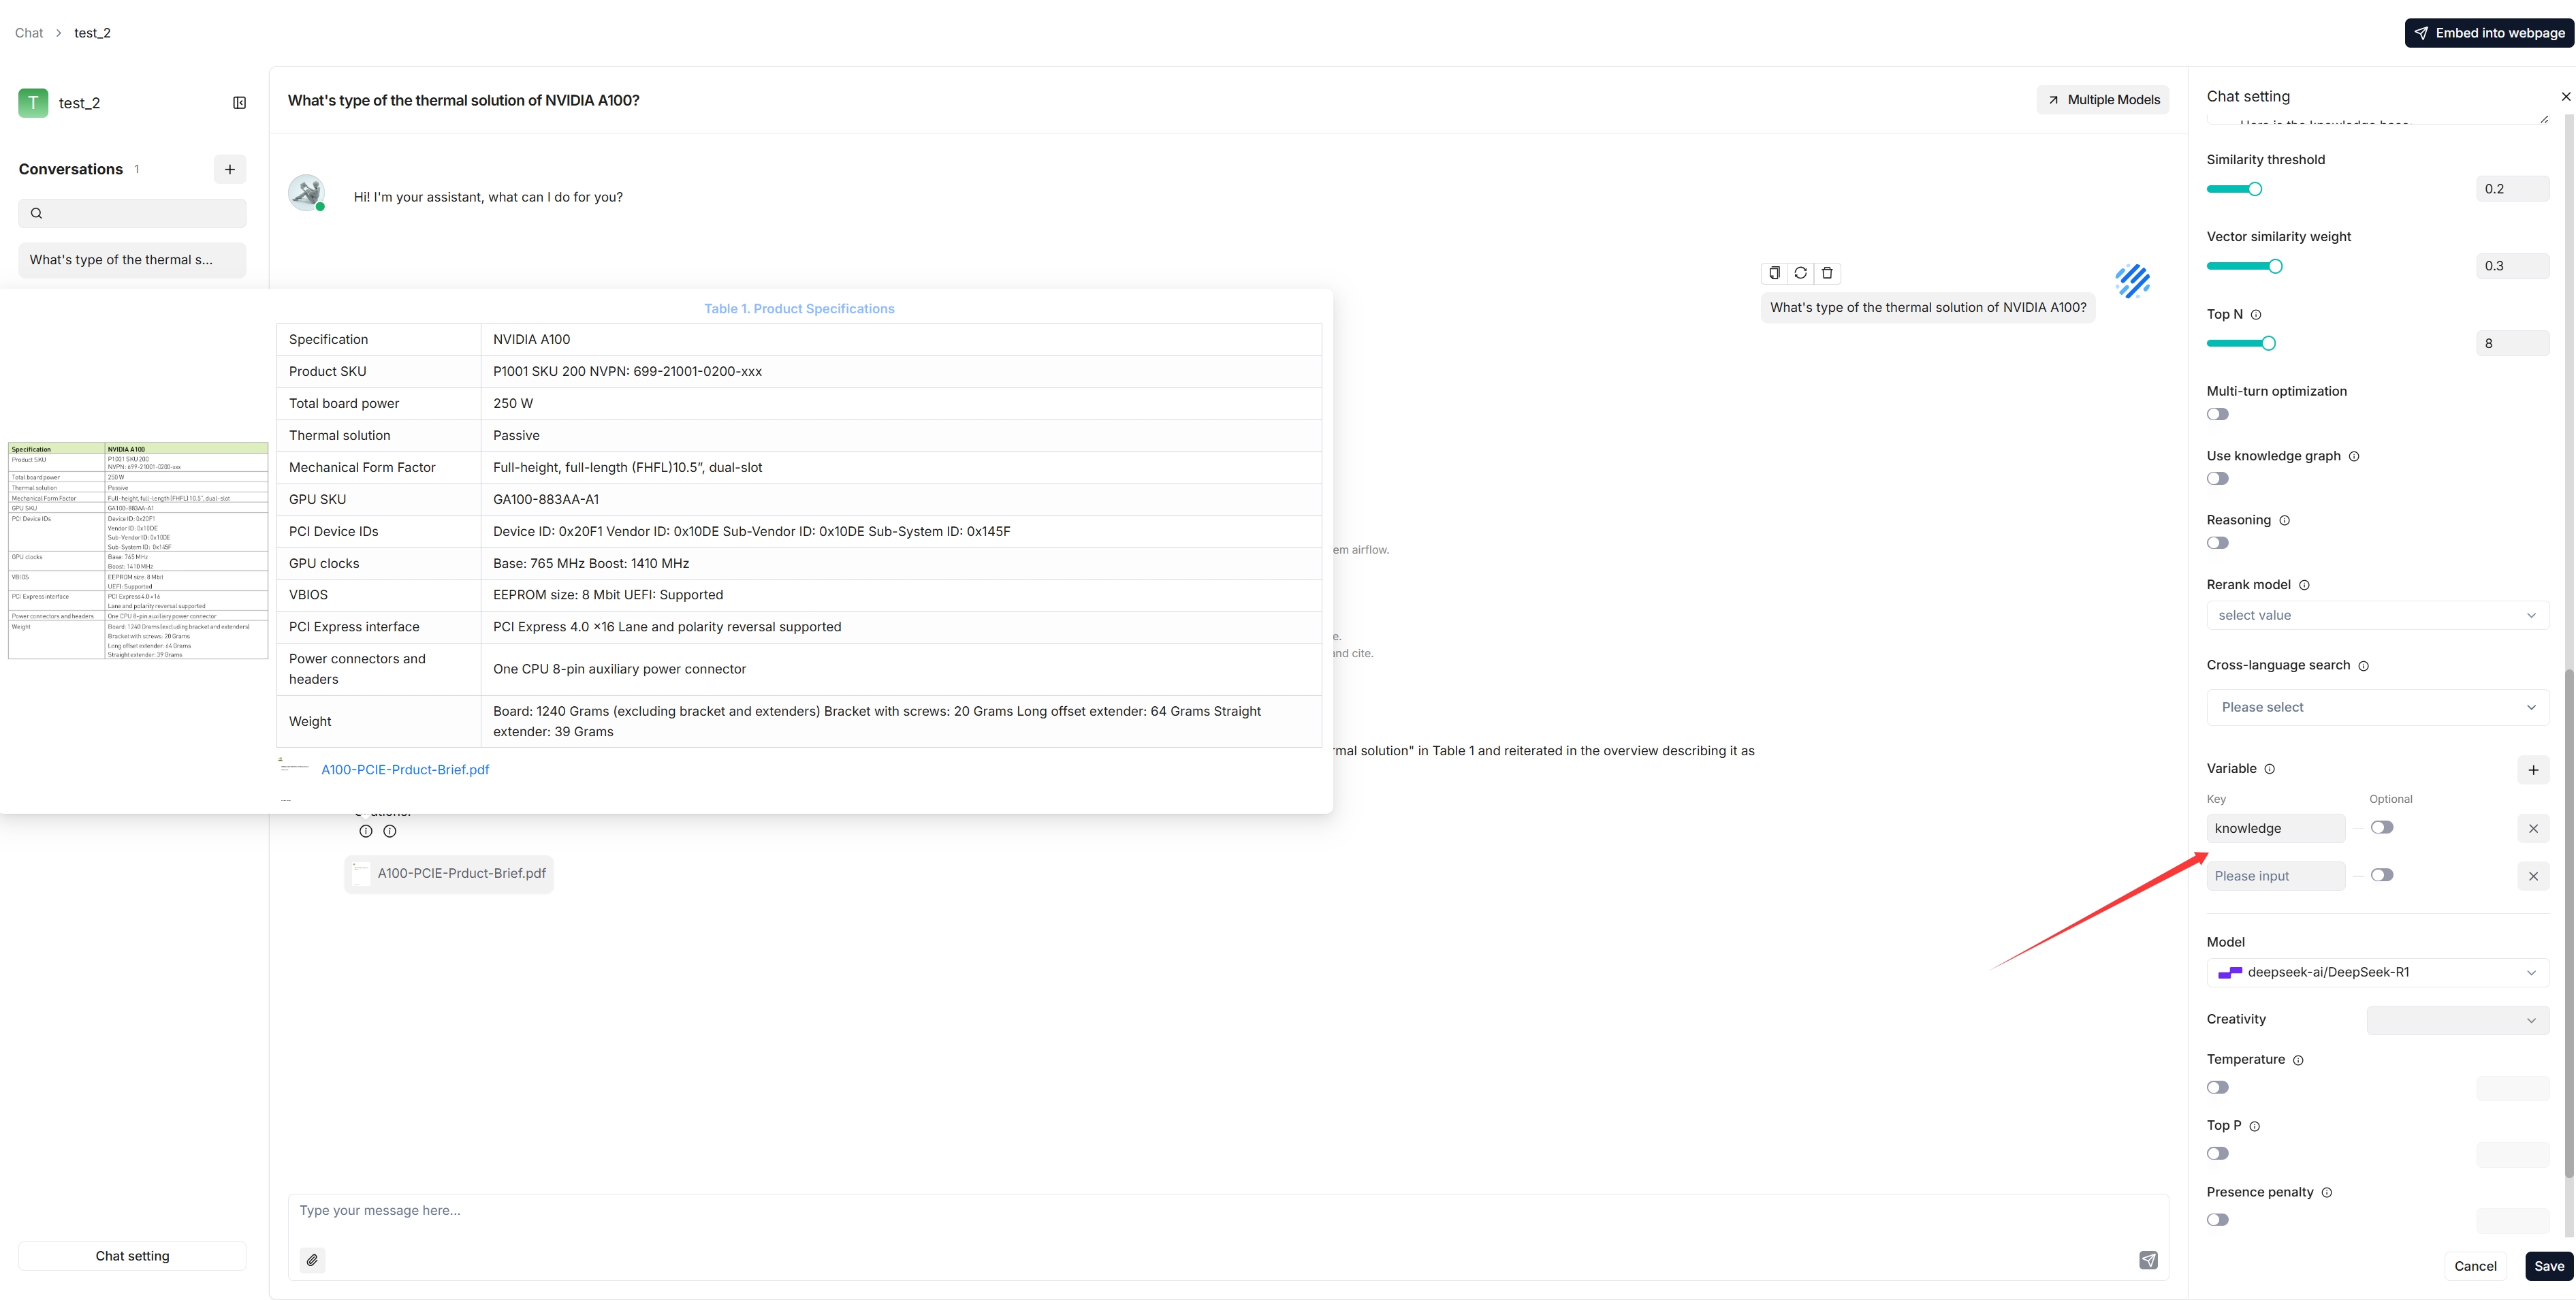
## Where to Set Variables
|
||||
|
||||
|
||||
|
||||
## 1. Manage Variables
|
||||
|
||||
In the **Variable** section, you add, remove, or update variables.
|
||||
|
||||
### `{knowledge}` - A Reserved Variable
|
||||
|
||||
`{knowledge}` is the system's reserved variable, representing the chunks retrieved from the dataset(s) specified by **Knowledge bases** under the **Assistant settings** tab. If your chat assistant is associated with certain datasets, you can keep it as is.
|
||||
|
||||
:::info NOTE
|
||||
It currently makes no difference whether `{knowledge}` is set as optional or mandatory, but please note this design will be updated in due course.
|
||||
:::
|
||||
|
||||
From v0.17.0 onward, you can start an AI chat without specifying datasets. In this case, we recommend removing the `{knowledge}` variable to prevent unnecessary reference and keeping the **Empty response** field empty to avoid errors.
|
||||
|
||||
### Custom Variables
|
||||
|
||||
Besides `{knowledge}`, you can also define your own variables to pair with the system prompt. To use these custom variables, you must pass in their values through RAGFlow's official APIs. The **Optional** toggle determines whether these variables are required in the corresponding APIs:
|
||||
|
||||
- **Disabled** (Default): The variable is mandatory and must be provided.
|
||||
- **Enabled**: The variable is optional and can be omitted if not needed.
|
||||
|
||||
## 2. Update System Prompt
|
||||
|
||||
After you add or remove variables in the **Variable** section, ensure your changes are reflected in the system prompt to avoid inconsistencies or errors. Here's an example:
|
||||
|
||||
```
|
||||
You are an intelligent assistant. Please answer the question by summarizing chunks from the specified dataset(s)...
|
||||
|
||||
Your answers should follow a professional and {style} style.
|
||||
|
||||
...
|
||||
|
||||
Here is the knowledge base:
|
||||
{knowledge}
|
||||
The above is the knowledge base.
|
||||
```
|
||||
|
||||
:::tip NOTE
|
||||
If you have removed `{knowledge}`, ensure that you thoroughly review and update the entire system prompt to achieve optimal results.
|
||||
:::
|
||||
|
||||
## APIs
|
||||
|
||||
The *only* way to pass in values for the custom variables defined in the **Chat Configuration** dialogue is to call RAGFlow's [HTTP API](../../references/http_api_reference.md#converse-with-chat-assistant) or through its [Python SDK](../../references/python_api_reference.md#converse-with-chat-assistant).
|
||||
|
||||
### HTTP API
|
||||
|
||||
See [Converse with chat assistant](../../references/http_api_reference.md#converse-with-chat-assistant). Here's an example:
|
||||
|
||||
```json {9}
|
||||
curl --request POST \
|
||||
--url http://{address}/api/v1/chat/completions \
|
||||
--header 'Content-Type: application/json' \
|
||||
--header 'Authorization: Bearer <YOUR_API_KEY>' \
|
||||
--data-binary '
|
||||
{
|
||||
"chat_id": "{chat_id}",
|
||||
"stream": true,
|
||||
"messages": [
|
||||
{
|
||||
"role": "user",
|
||||
"content": "xxxxxxxxx"
|
||||
}
|
||||
],
|
||||
"style":"hilarious"
|
||||
}'
|
||||
```
|
||||
|
||||
### Python API
|
||||
|
||||
See [Converse with chat assistant](../../references/python_api_reference.md#converse-with-chat-assistant). Here's an example:
|
||||
|
||||
```python {18}
|
||||
from ragflow_sdk import RAGFlow
|
||||
|
||||
rag_object = RAGFlow(api_key="<YOUR_API_KEY>", base_url="http://<YOUR_BASE_URL>:9380")
|
||||
assistant = rag_object.list_chats(name="Miss R")
|
||||
assistant = assistant[0]
|
||||
session = assistant.create_session()
|
||||
|
||||
print("\n==================== Miss R =====================\n")
|
||||
print("Hello. What can I do for you?")
|
||||
|
||||
while True:
|
||||
question = input("\n==================== User =====================\n> ")
|
||||
style = input("Please enter your preferred style (e.g., formal, informal, hilarious): ")
|
||||
|
||||
print("\n==================== Miss R =====================\n")
|
||||
|
||||
cont = ""
|
||||
for ans in session.ask(question, stream=True, style=style):
|
||||
print(ans.content[len(cont):], end='', flush=True)
|
||||
cont = ans.content
|
||||
```
|
||||
@@ -1,120 +0,0 @@
|
||||
---
|
||||
sidebar_position: 1
|
||||
title: Start AI Chat
|
||||
sidebar_label: Start AI Chat
|
||||
slug: /start_chat
|
||||
sidebar_custom_props: {
|
||||
categoryIcon: LucideBot
|
||||
}
|
||||
---
|
||||
# Start AI Chat
|
||||
|
||||
Initiate an AI-powered chat with a configured chat assistant.
|
||||
|
||||
---
|
||||
|
||||
Chats in RAGFlow are based on a particular dataset or multiple datasets. Once you have created your dataset, finished file parsing, and [run a retrieval test](../dataset/retrieval_testing.md), you can go ahead and start an AI conversation.
|
||||
|
||||
## Start an AI Chat
|
||||
|
||||
You start an AI conversation by creating an assistant.
|
||||
|
||||
1. Click the **Chat** tab in the middle top of the page **>** **Create an assistant** to show the **Chat Configuration** dialogue *of your next dialogue*.
|
||||
|
||||
> RAGFlow offers you the flexibility of choosing a different chat model for each dialogue, while allowing you to set the default models in **System Model Settings**.
|
||||
|
||||
2. Update Assistant-specific settings:
|
||||
|
||||
- **Assistant name** is the name of your chat assistant. Each assistant corresponds to a dialogue with a unique combination of datasets, prompts, hybrid search configurations, and large model settings.
|
||||
- **Empty response**:
|
||||
- If you wish to *confine* RAGFlow's answers to your datasets, leave a response here. Then, when it doesn't retrieve an answer, it *uniformly* responds with what you set here.
|
||||
- If you wish RAGFlow to *improvise* when it doesn't retrieve an answer from your datasets, leave it blank, which may give rise to hallucinations.
|
||||
- **Show quote**: This is a key feature of RAGFlow and enabled by default. RAGFlow does not work like a black box. Instead, it clearly shows the sources of information that its responses are based on.
|
||||
- Select the corresponding datasets. You can select one or multiple datasets, but ensure that they use the same embedding model, otherwise an error would occur.
|
||||
|
||||
3. Update Prompt-specific settings:
|
||||
|
||||
- In **System**, you fill in the prompts for your LLM, you can also leave the default prompt as-is for the beginning.
|
||||
- **Similarity threshold** sets the similarity "bar" for each chunk of text. The default is 0.2. Text chunks with lower similarity scores are filtered out of the final response.
|
||||
- **Vector similarity weight** is set to 0.3 by default. RAGFlow uses a hybrid score system to evaluate the relevance of different text chunks. This value sets the weight assigned to the vector similarity component in the hybrid score.
|
||||
- If **Rerank model** is left empty, the hybrid score system uses keyword similarity and vector similarity, and the default weight assigned to the keyword similarity component is 1-0.3=0.7.
|
||||
- If **Rerank model** is selected, the hybrid score system uses keyword similarity and reranker score, and the default weight assigned to the reranker score is 1-0.7=0.3.
|
||||
- **Top N** determines the *maximum* number of chunks to feed to the LLM. In other words, even if more chunks are retrieved, only the top N chunks are provided as input.
|
||||
- **Multi-turn optimization** enhances user queries using existing context in a multi-round conversation. It is enabled by default. When enabled, it will consume additional LLM tokens and significantly increase the time to generate answers.
|
||||
- **Use knowledge graph** indicates whether to use knowledge graph(s) in the specified dataset(s) during retrieval for multi-hop question answering. When enabled, this would involve iterative searches across entity, relationship, and community report chunks, greatly increasing retrieval time.
|
||||
- **Reasoning** indicates whether to generate answers through reasoning processes like Deepseek-R1/OpenAI o1. Once enabled, the chat model autonomously integrates Deep research during question answering when encountering an unknown topic. This involves the chat model dynamically searching external knowledge and generating final answers through reasoning.
|
||||
- **Rerank model** sets the reranker model to use. It is left empty by default.
|
||||
- If **Rerank model** is left empty, the hybrid score system uses keyword similarity and vector similarity, and the default weight assigned to the vector similarity component is 1-0.7=0.3.
|
||||
- If **Rerank model** is selected, the hybrid score system uses keyword similarity and reranker score, and the default weight assigned to the reranker score is 1-0.7=0.3.
|
||||
- [Cross-language search](../../references/glossary.mdx#cross-language-search): Optional
|
||||
Select one or more target languages from the dropdown menu. The system’s default chat model will then translate your query into the selected target language(s). This translation ensures accurate semantic matching across languages, allowing you to retrieve relevant results regardless of language differences.
|
||||
- When selecting target languages, please ensure that these languages are present in the dataset to guarantee an effective search.
|
||||
- If no target language is selected, the system will search only in the language of your query, which may cause relevant information in other languages to be missed.
|
||||
- **Variable** refers to the variables (keys) to be used in the system prompt. `{knowledge}` is a reserved variable. Click **Add** to add more variables for the system prompt.
|
||||
- If you are uncertain about the logic behind **Variable**, leave it *as-is*.
|
||||
- As of v0.17.2, if you add custom variables here, the only way you can pass in their values is to call:
|
||||
- HTTP method [Converse with chat assistant](../../references/http_api_reference.md#converse-with-chat-assistant), or
|
||||
- Python method [Converse with chat assistant](../../references/python_api_reference.md#converse-with-chat-assistant).
|
||||
|
||||
4. Update Model-specific Settings:
|
||||
|
||||
- In **Model**: you select the chat model. Though you have selected the default chat model in **System Model Settings**, RAGFlow allows you to choose an alternative chat model for your dialogue.
|
||||
- **Creativity**: A shortcut to **Temperature**, **Top P**, **Presence penalty**, and **Frequency penalty** settings, indicating the freedom level of the model. From **Improvise**, **Precise**, to **Balance**, each preset configuration corresponds to a unique combination of **Temperature**, **Top P**, **Presence penalty**, and **Frequency penalty**.
|
||||
This parameter has three options:
|
||||
- **Improvise**: Produces more creative responses.
|
||||
- **Precise**: (Default) Produces more conservative responses.
|
||||
- **Balance**: A middle ground between **Improvise** and **Precise**.
|
||||
- **Temperature**: The randomness level of the model's output.
|
||||
Defaults to 0.1.
|
||||
- Lower values lead to more deterministic and predictable outputs.
|
||||
- Higher values lead to more creative and varied outputs.
|
||||
- A temperature of zero results in the same output for the same prompt.
|
||||
- **Top P**: Nucleus sampling.
|
||||
- Reduces the likelihood of generating repetitive or unnatural text by setting a threshold *P* and restricting the sampling to tokens with a cumulative probability exceeding *P*.
|
||||
- Defaults to 0.3.
|
||||
- **Presence penalty**: Encourages the model to include a more diverse range of tokens in the response.
|
||||
- A higher **presence penalty** value results in the model being more likely to generate tokens not yet been included in the generated text.
|
||||
- Defaults to 0.4.
|
||||
- **Frequency penalty**: Discourages the model from repeating the same words or phrases too frequently in the generated text.
|
||||
- A higher **frequency penalty** value results in the model being more conservative in its use of repeated tokens.
|
||||
- Defaults to 0.7.
|
||||
|
||||
5. Now, let's start the show:
|
||||
|
||||
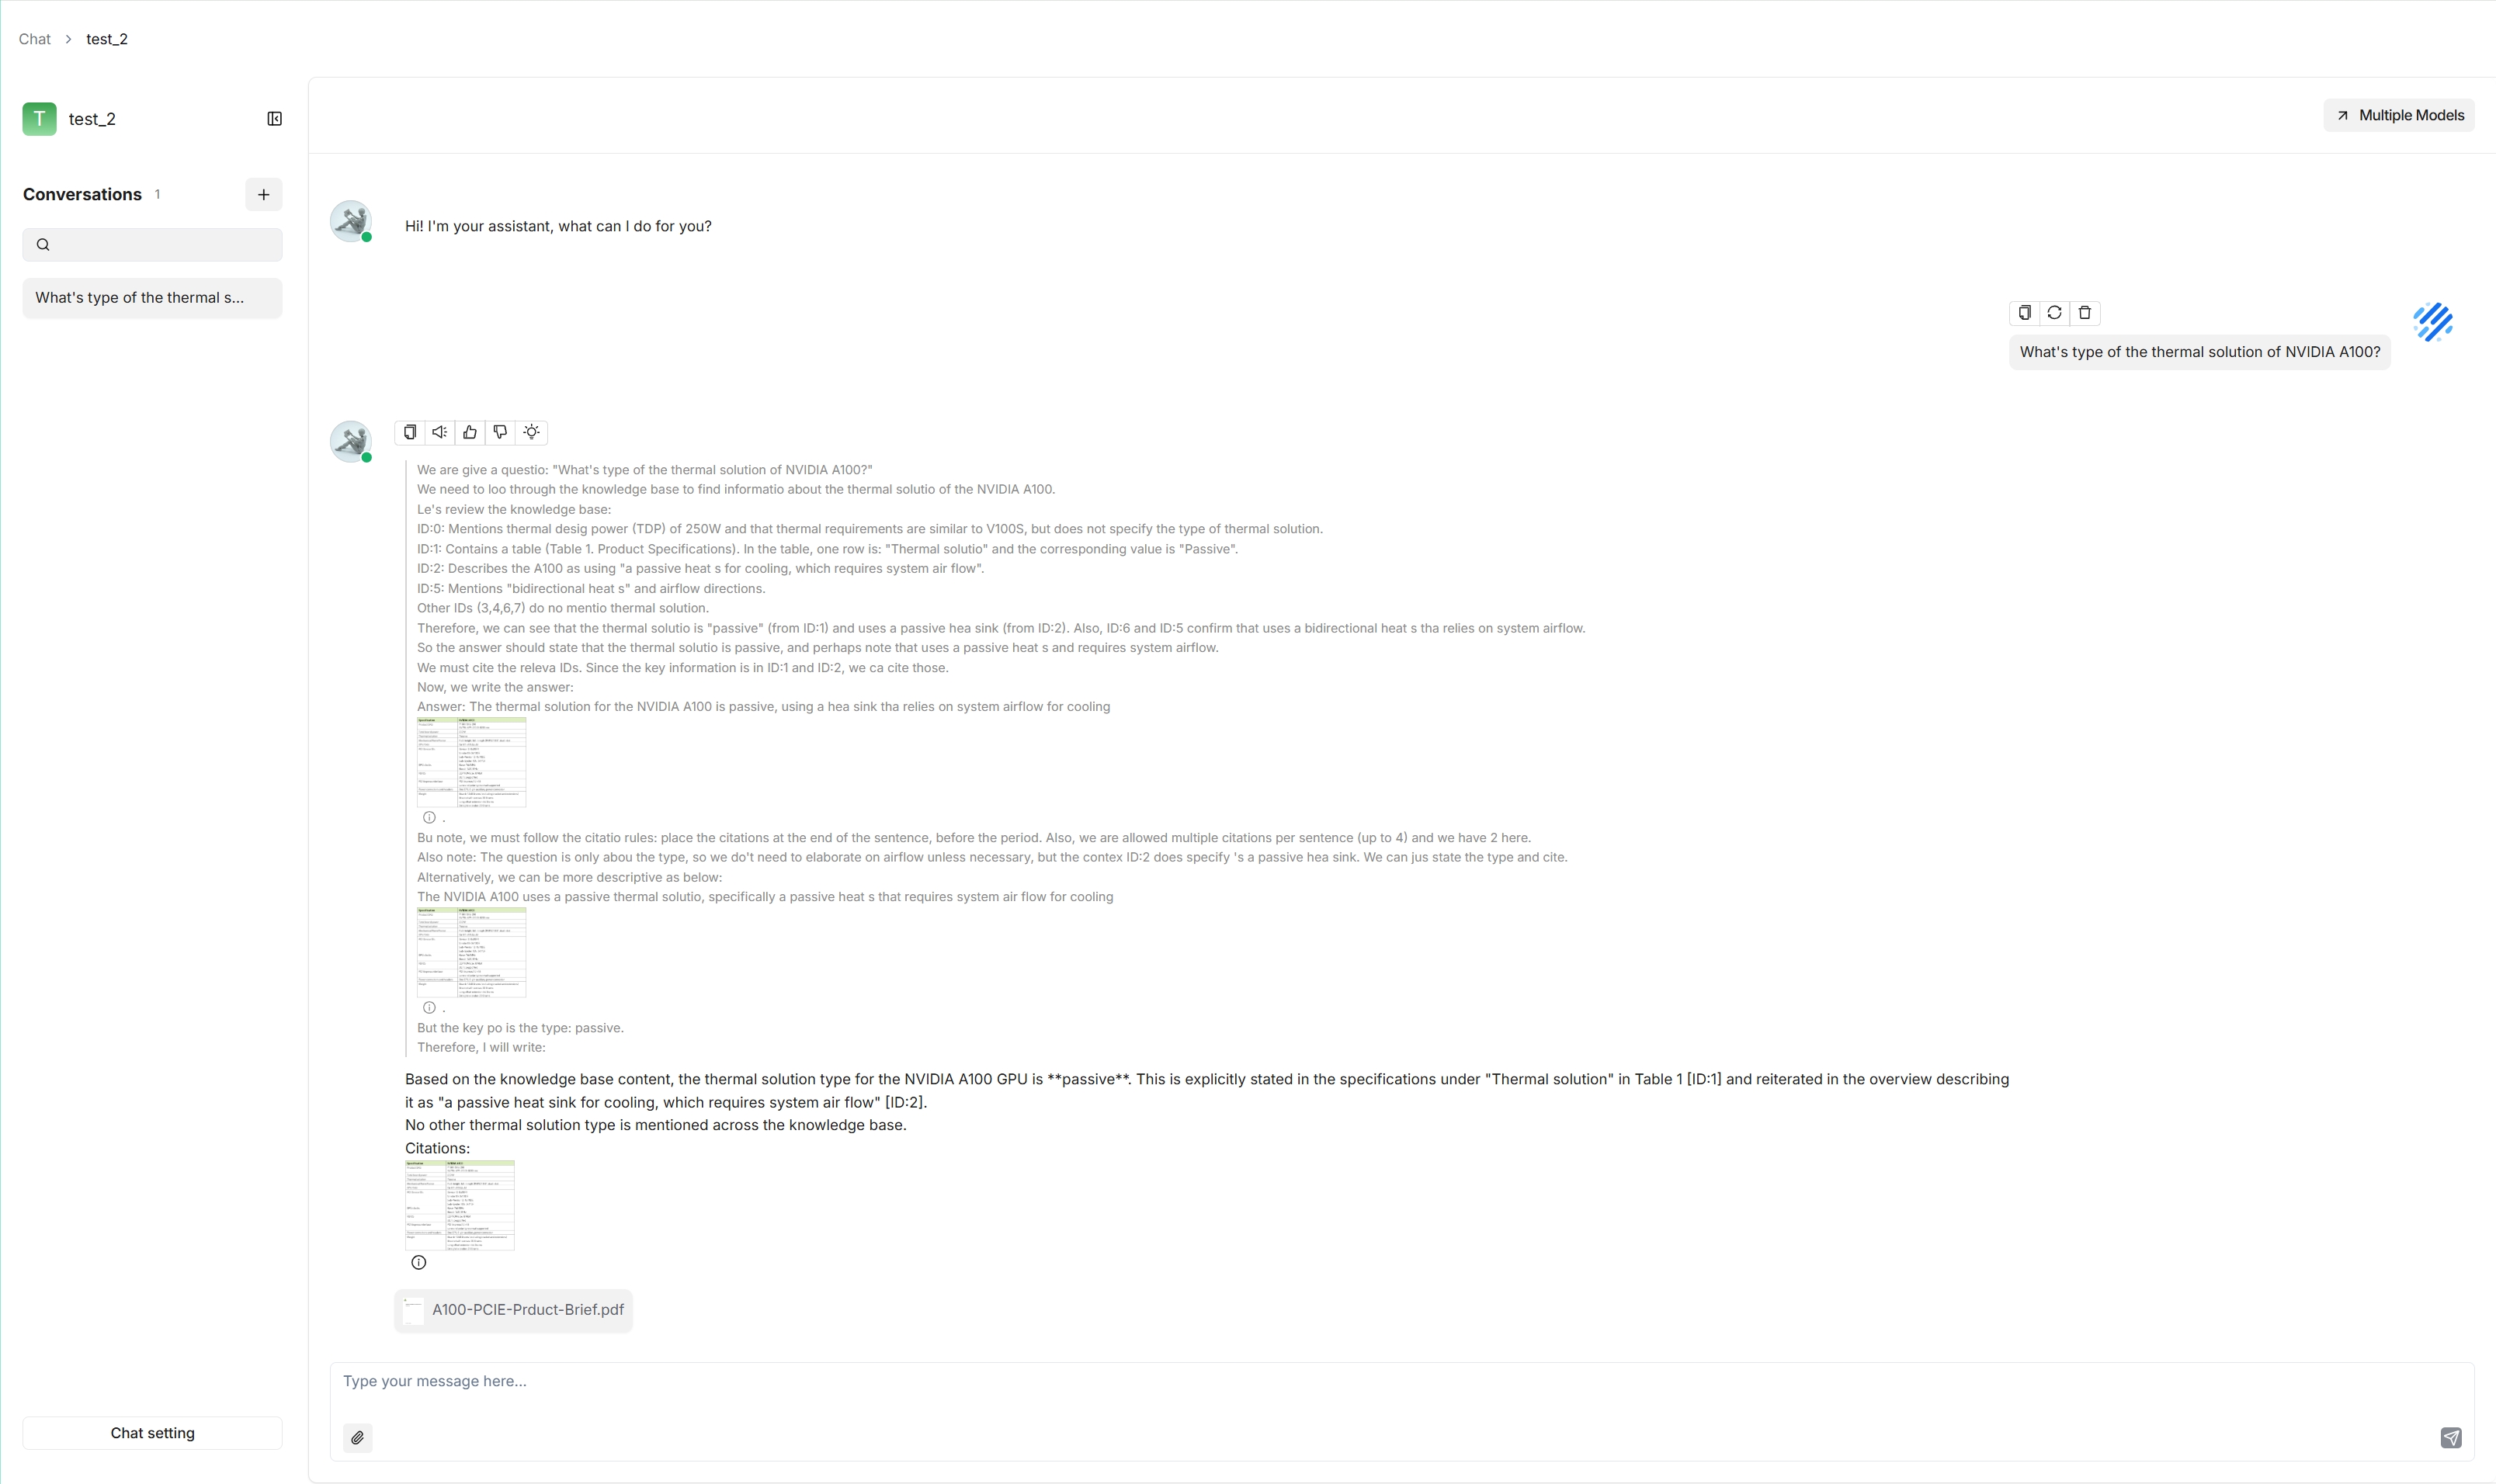
|
||||
|
||||
:::tip NOTE
|
||||
|
||||
1. Click the light bulb icon above the answer to view the expanded system prompt:
|
||||
|
||||
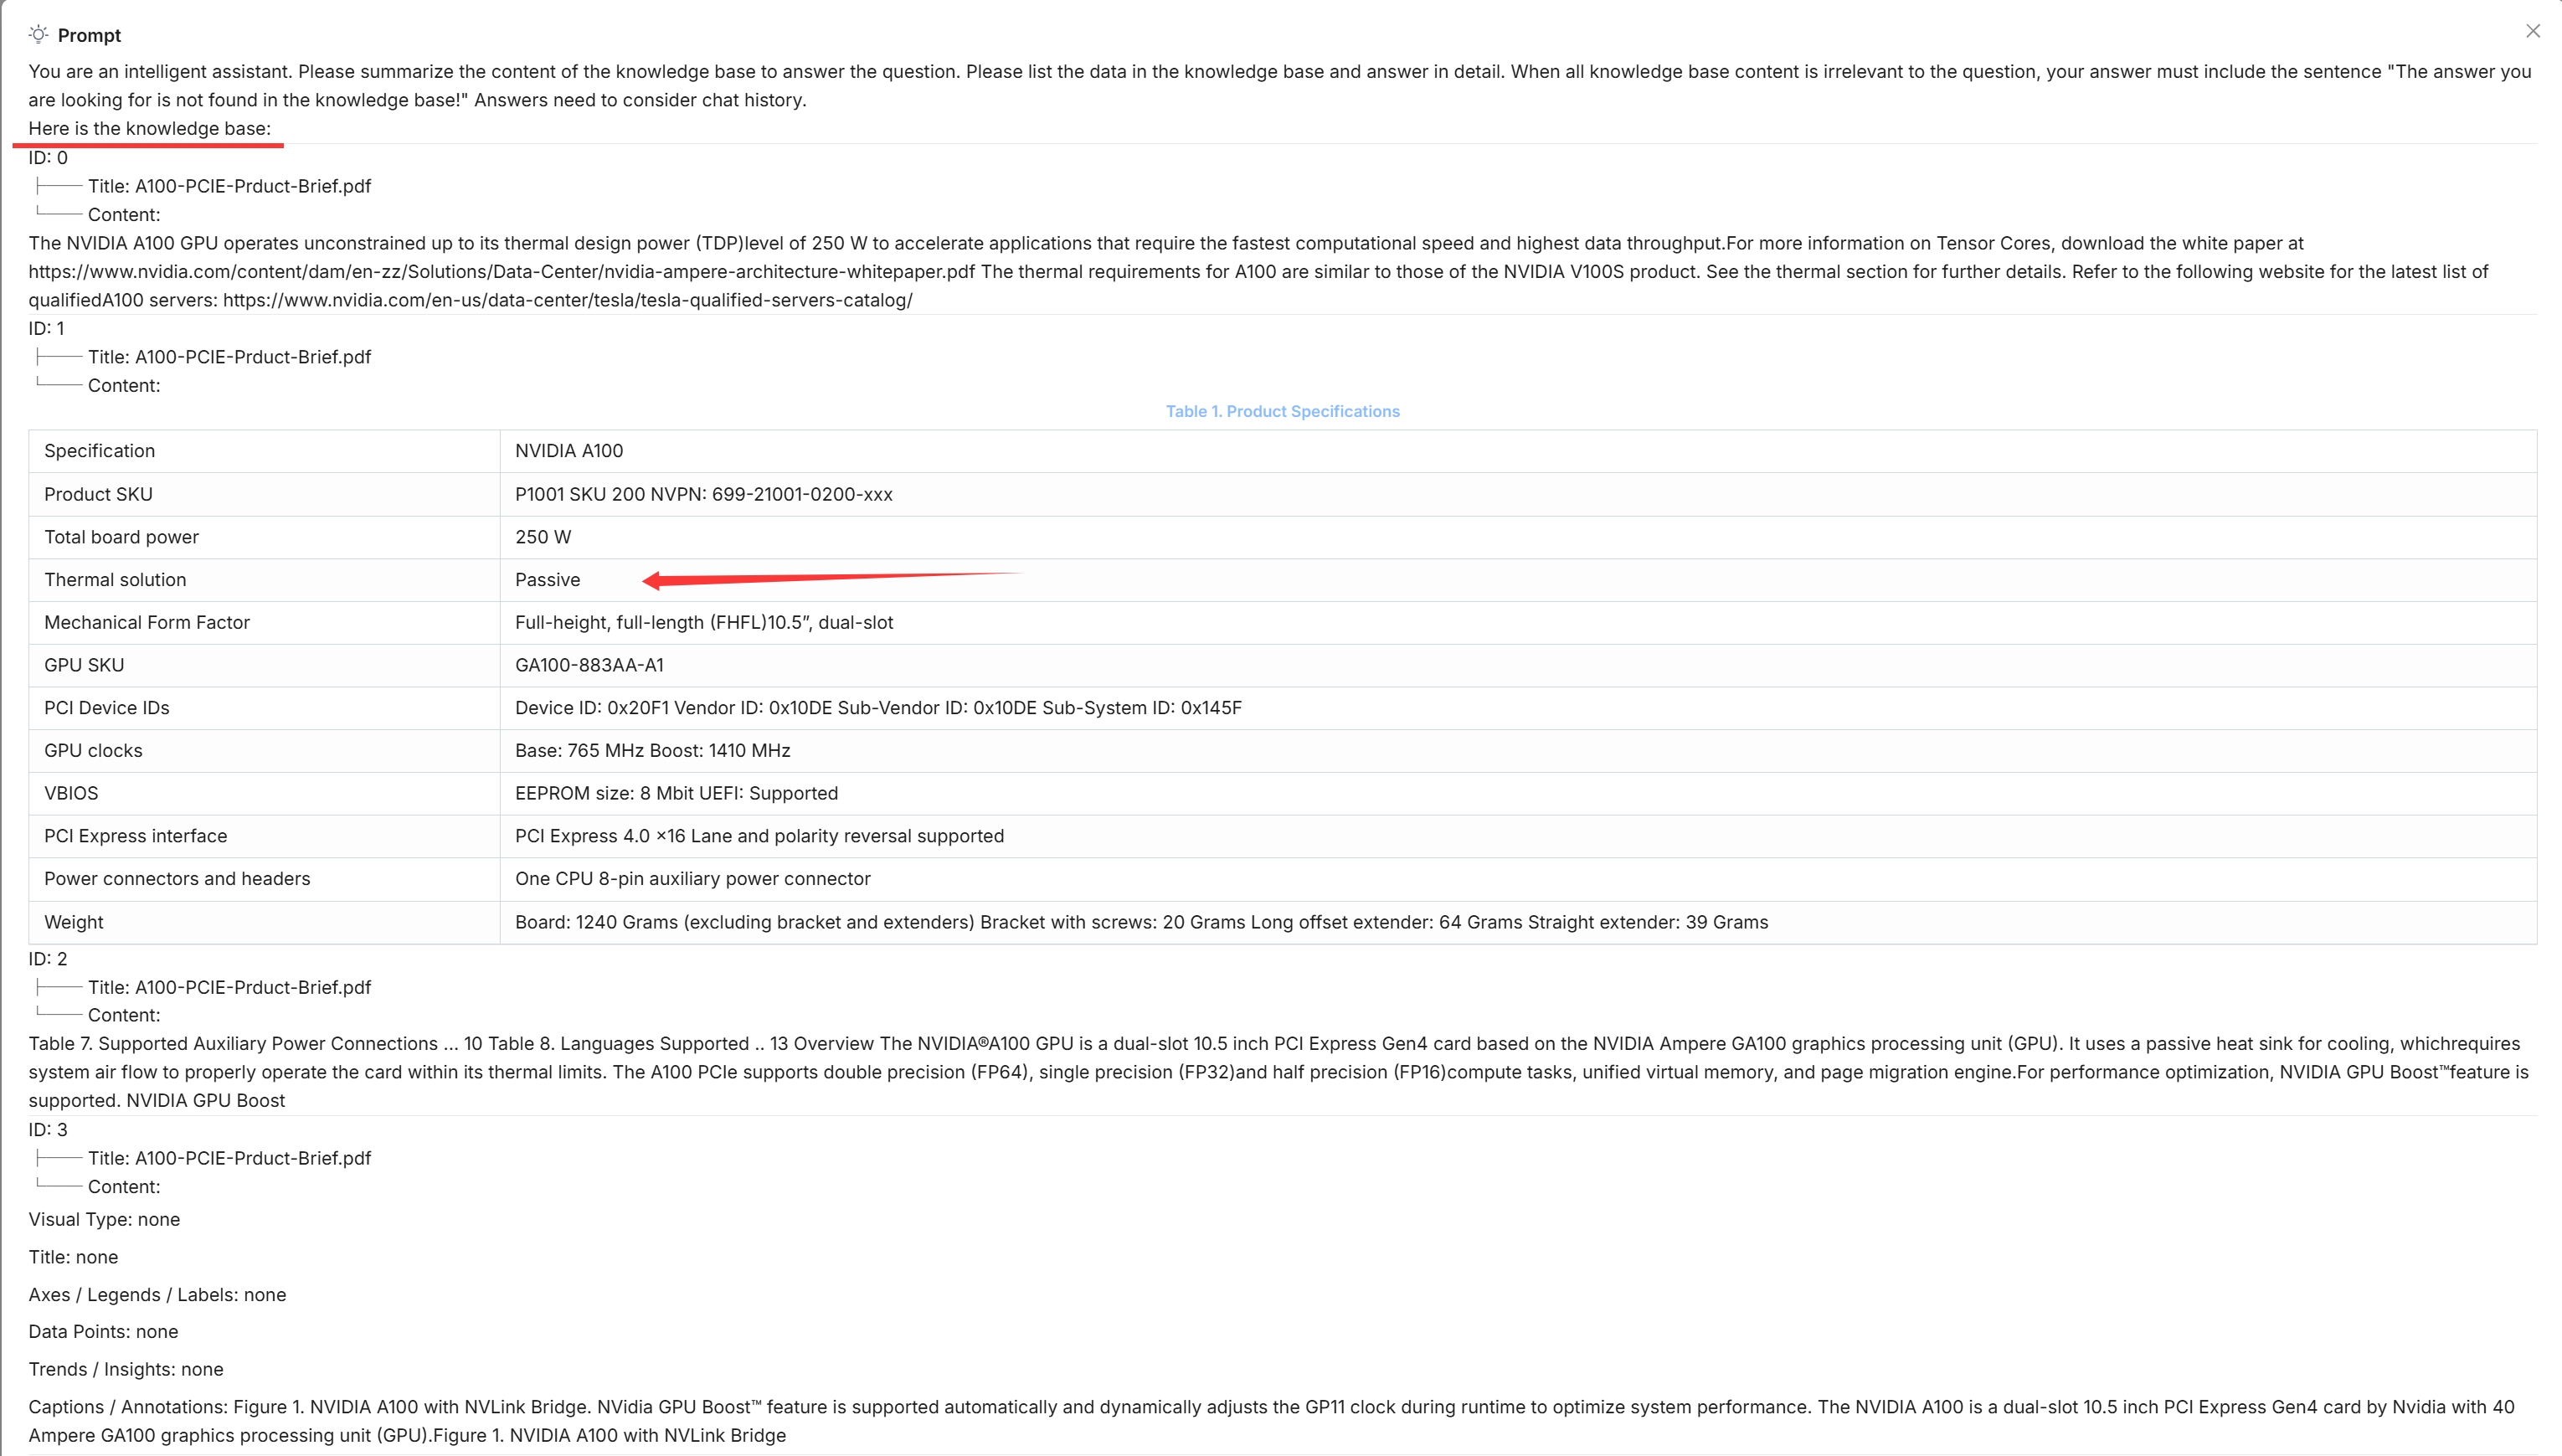
|
||||
|
||||
*The light bulb icon is available only for the current dialogue.*
|
||||
|
||||
2. Scroll down the expanded prompt to view the time consumed for each task:
|
||||
|
||||
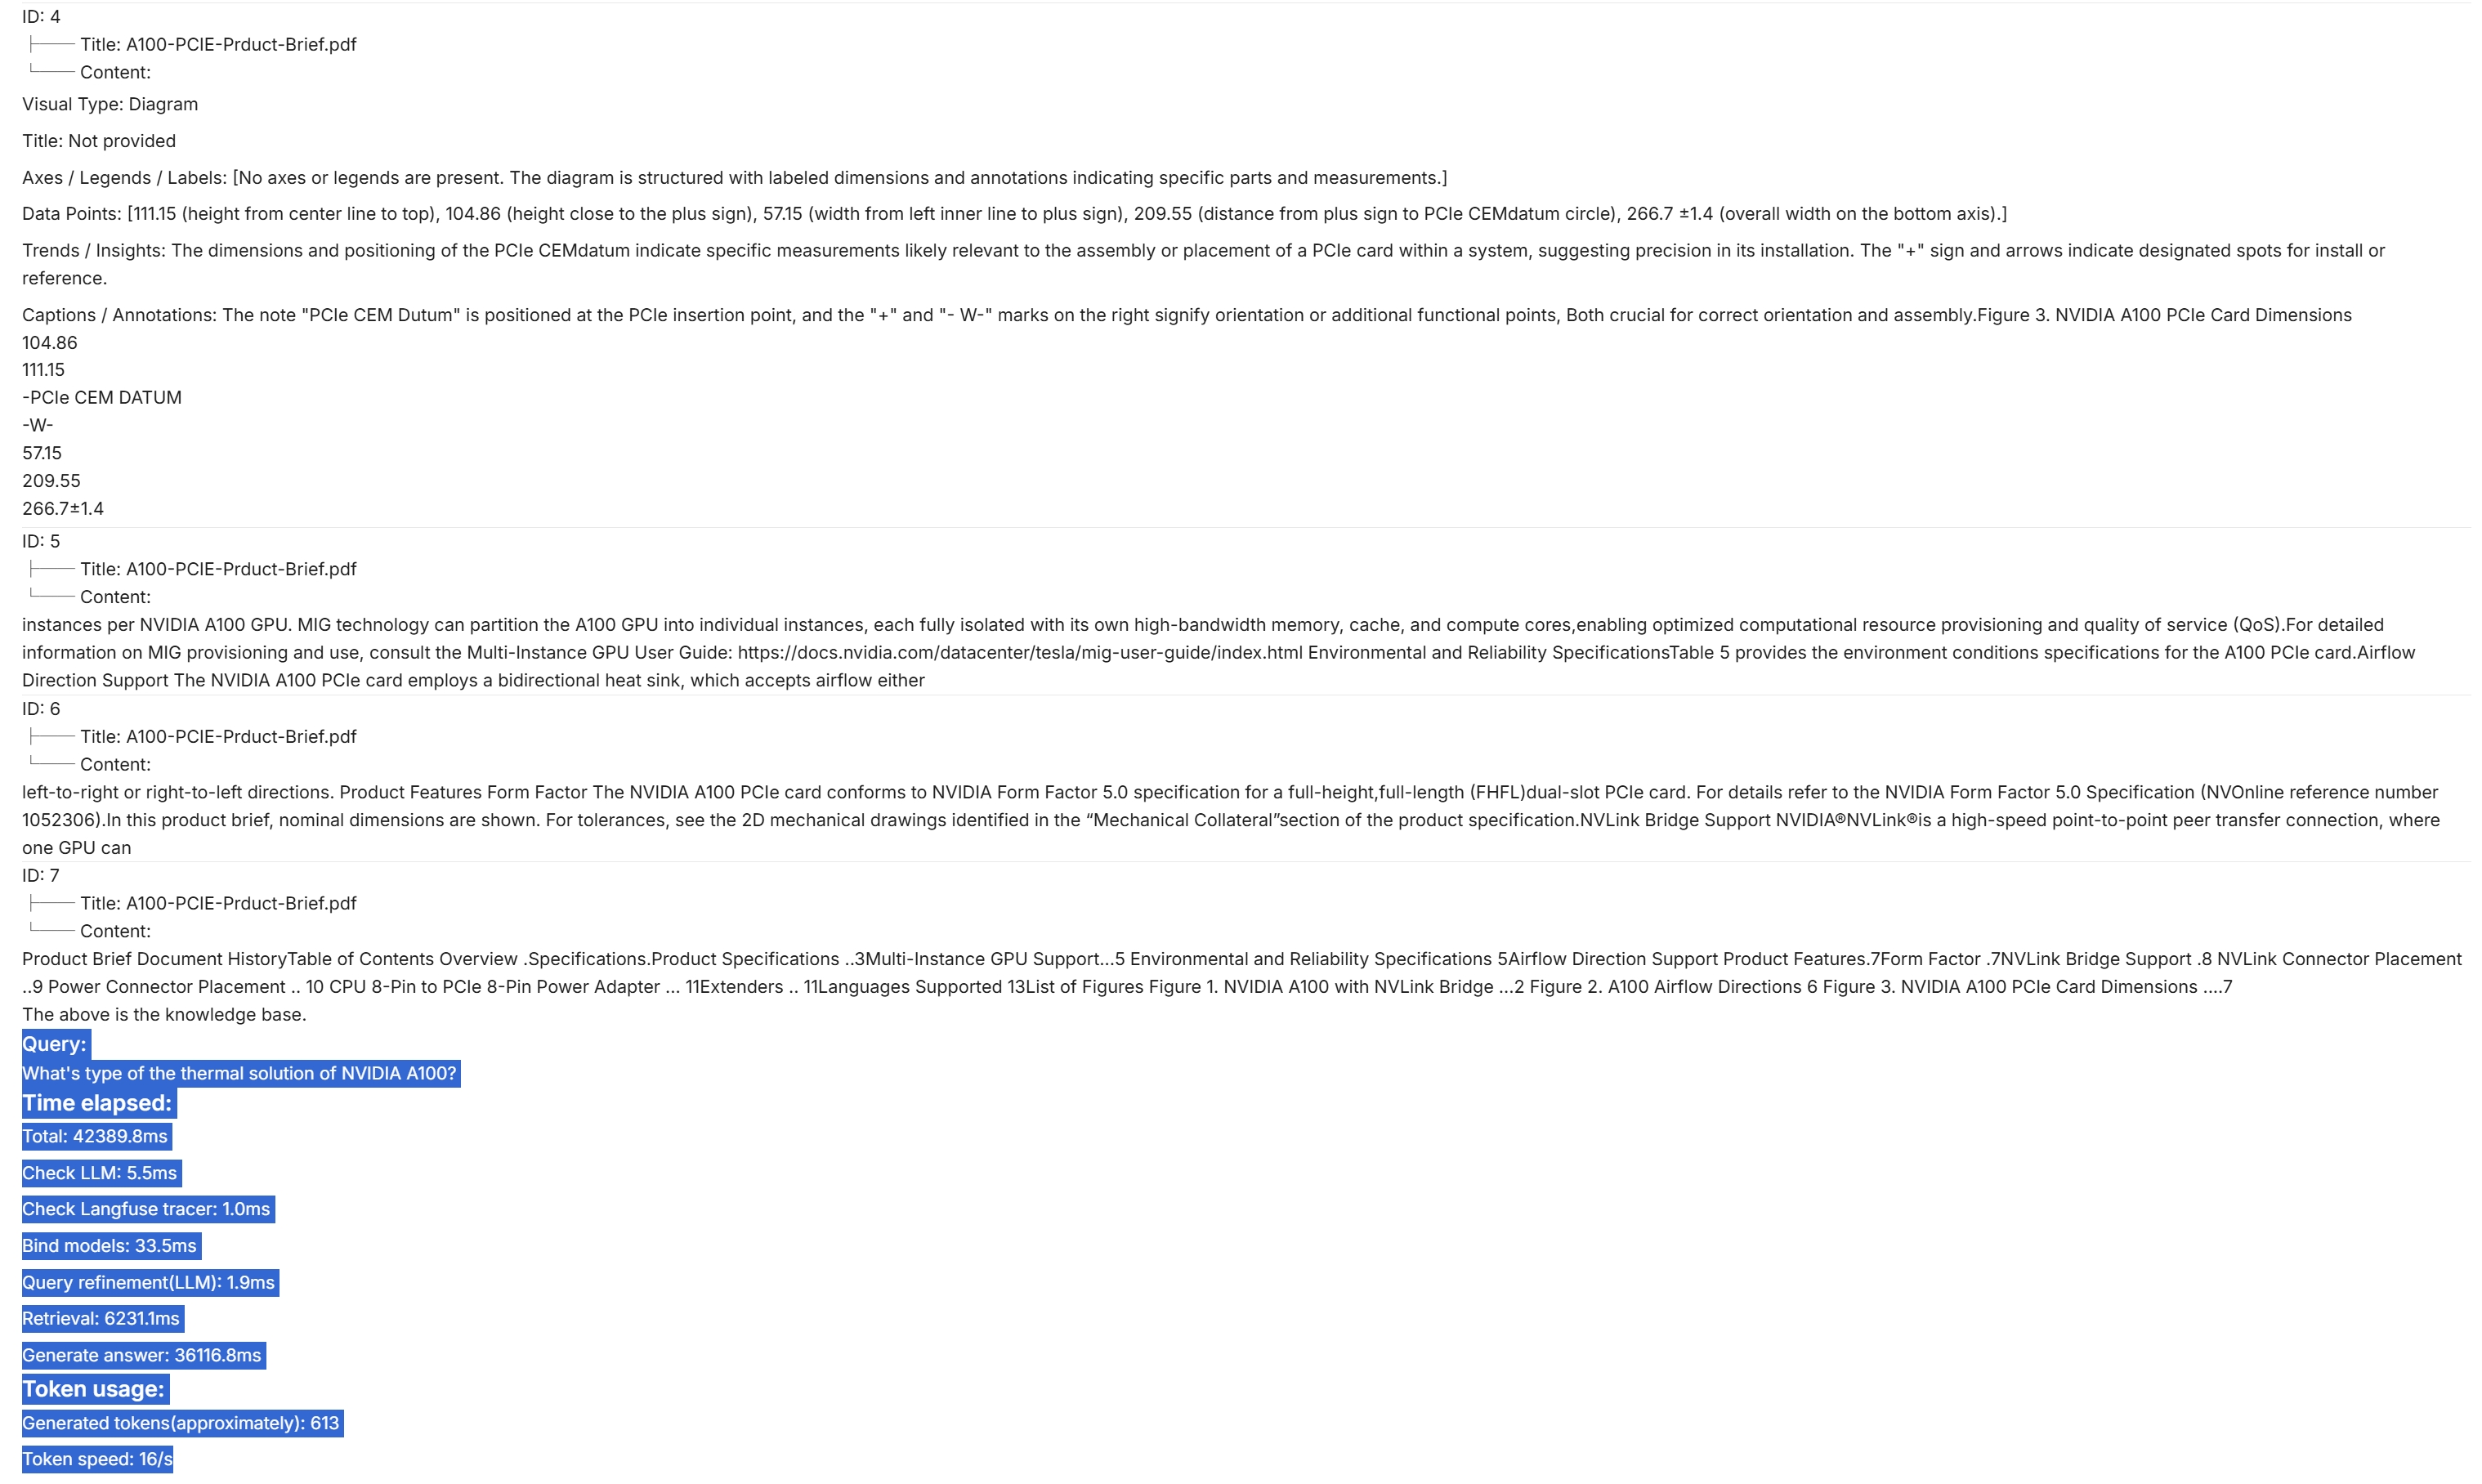
|
||||
:::
|
||||
|
||||
## Update Settings of an Existing Chat Assistant
|
||||
|
||||
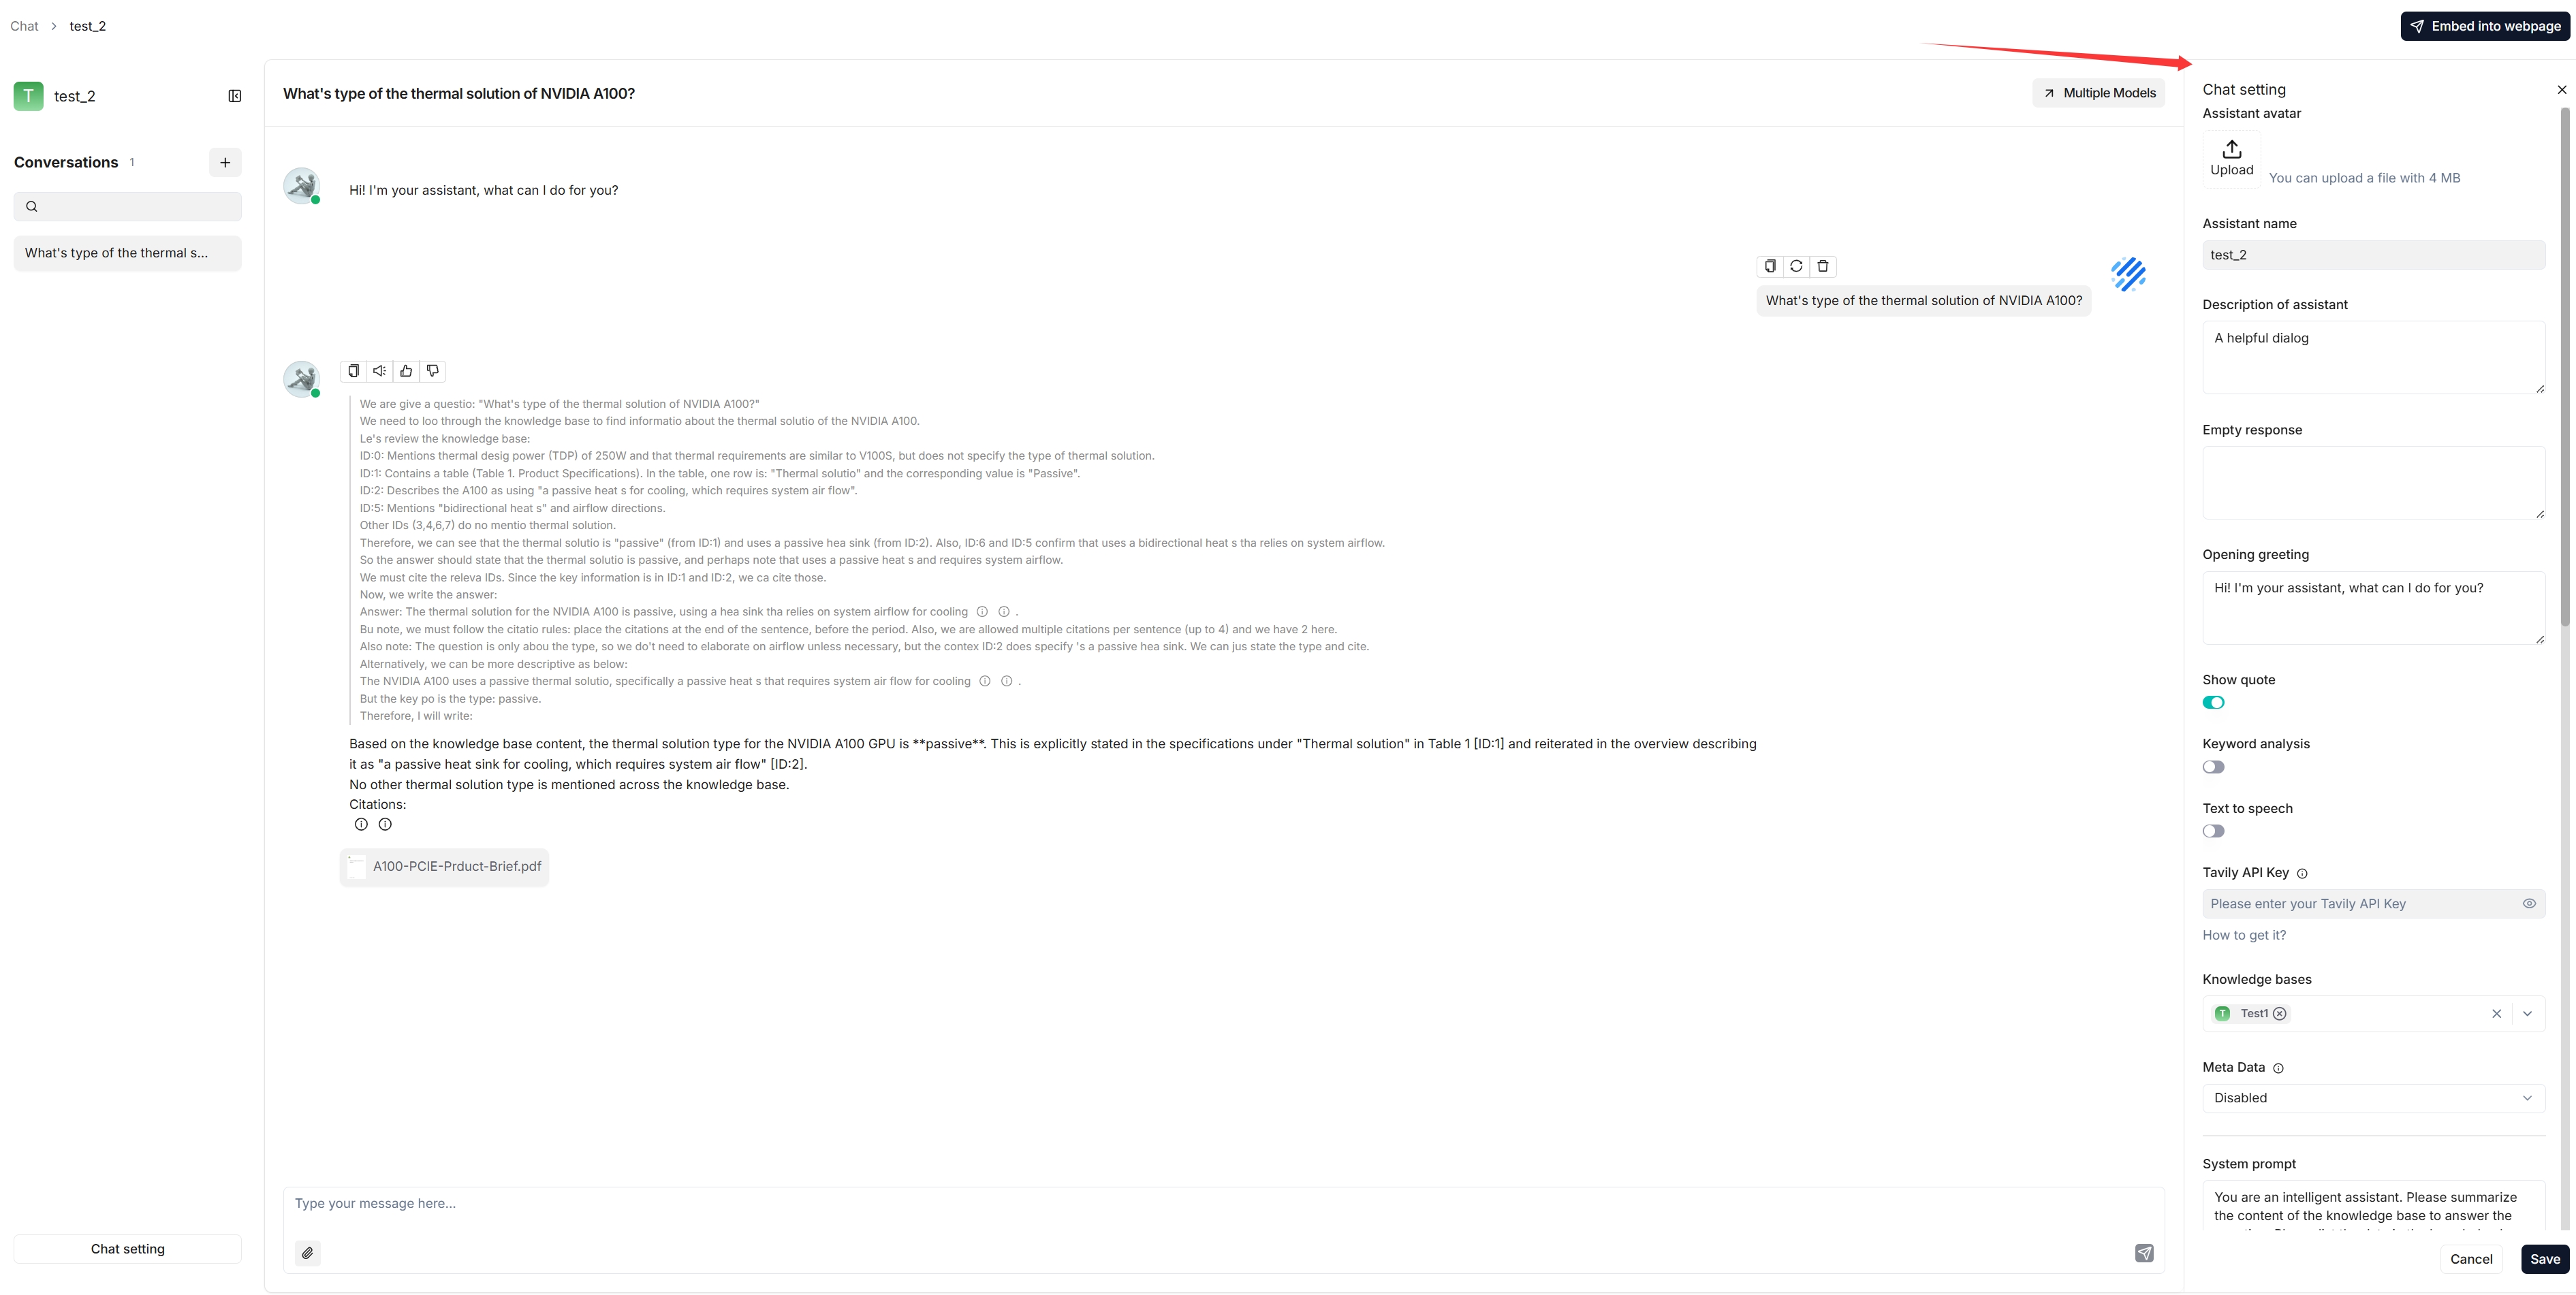
|
||||
|
||||
## Integrate Chat Capabilities into Your Application or Webpage
|
||||
|
||||
RAGFlow offers HTTP and Python APIs for you to integrate RAGFlow's capabilities into your applications. Read the following documents for more information:
|
||||
|
||||
- [Acquire a RAGFlow API key](../../develop/acquire_ragflow_api_key.md)
|
||||
- [HTTP API reference](../../references/http_api_reference.md)
|
||||
- [Python API reference](../../references/python_api_reference.md)
|
||||
|
||||
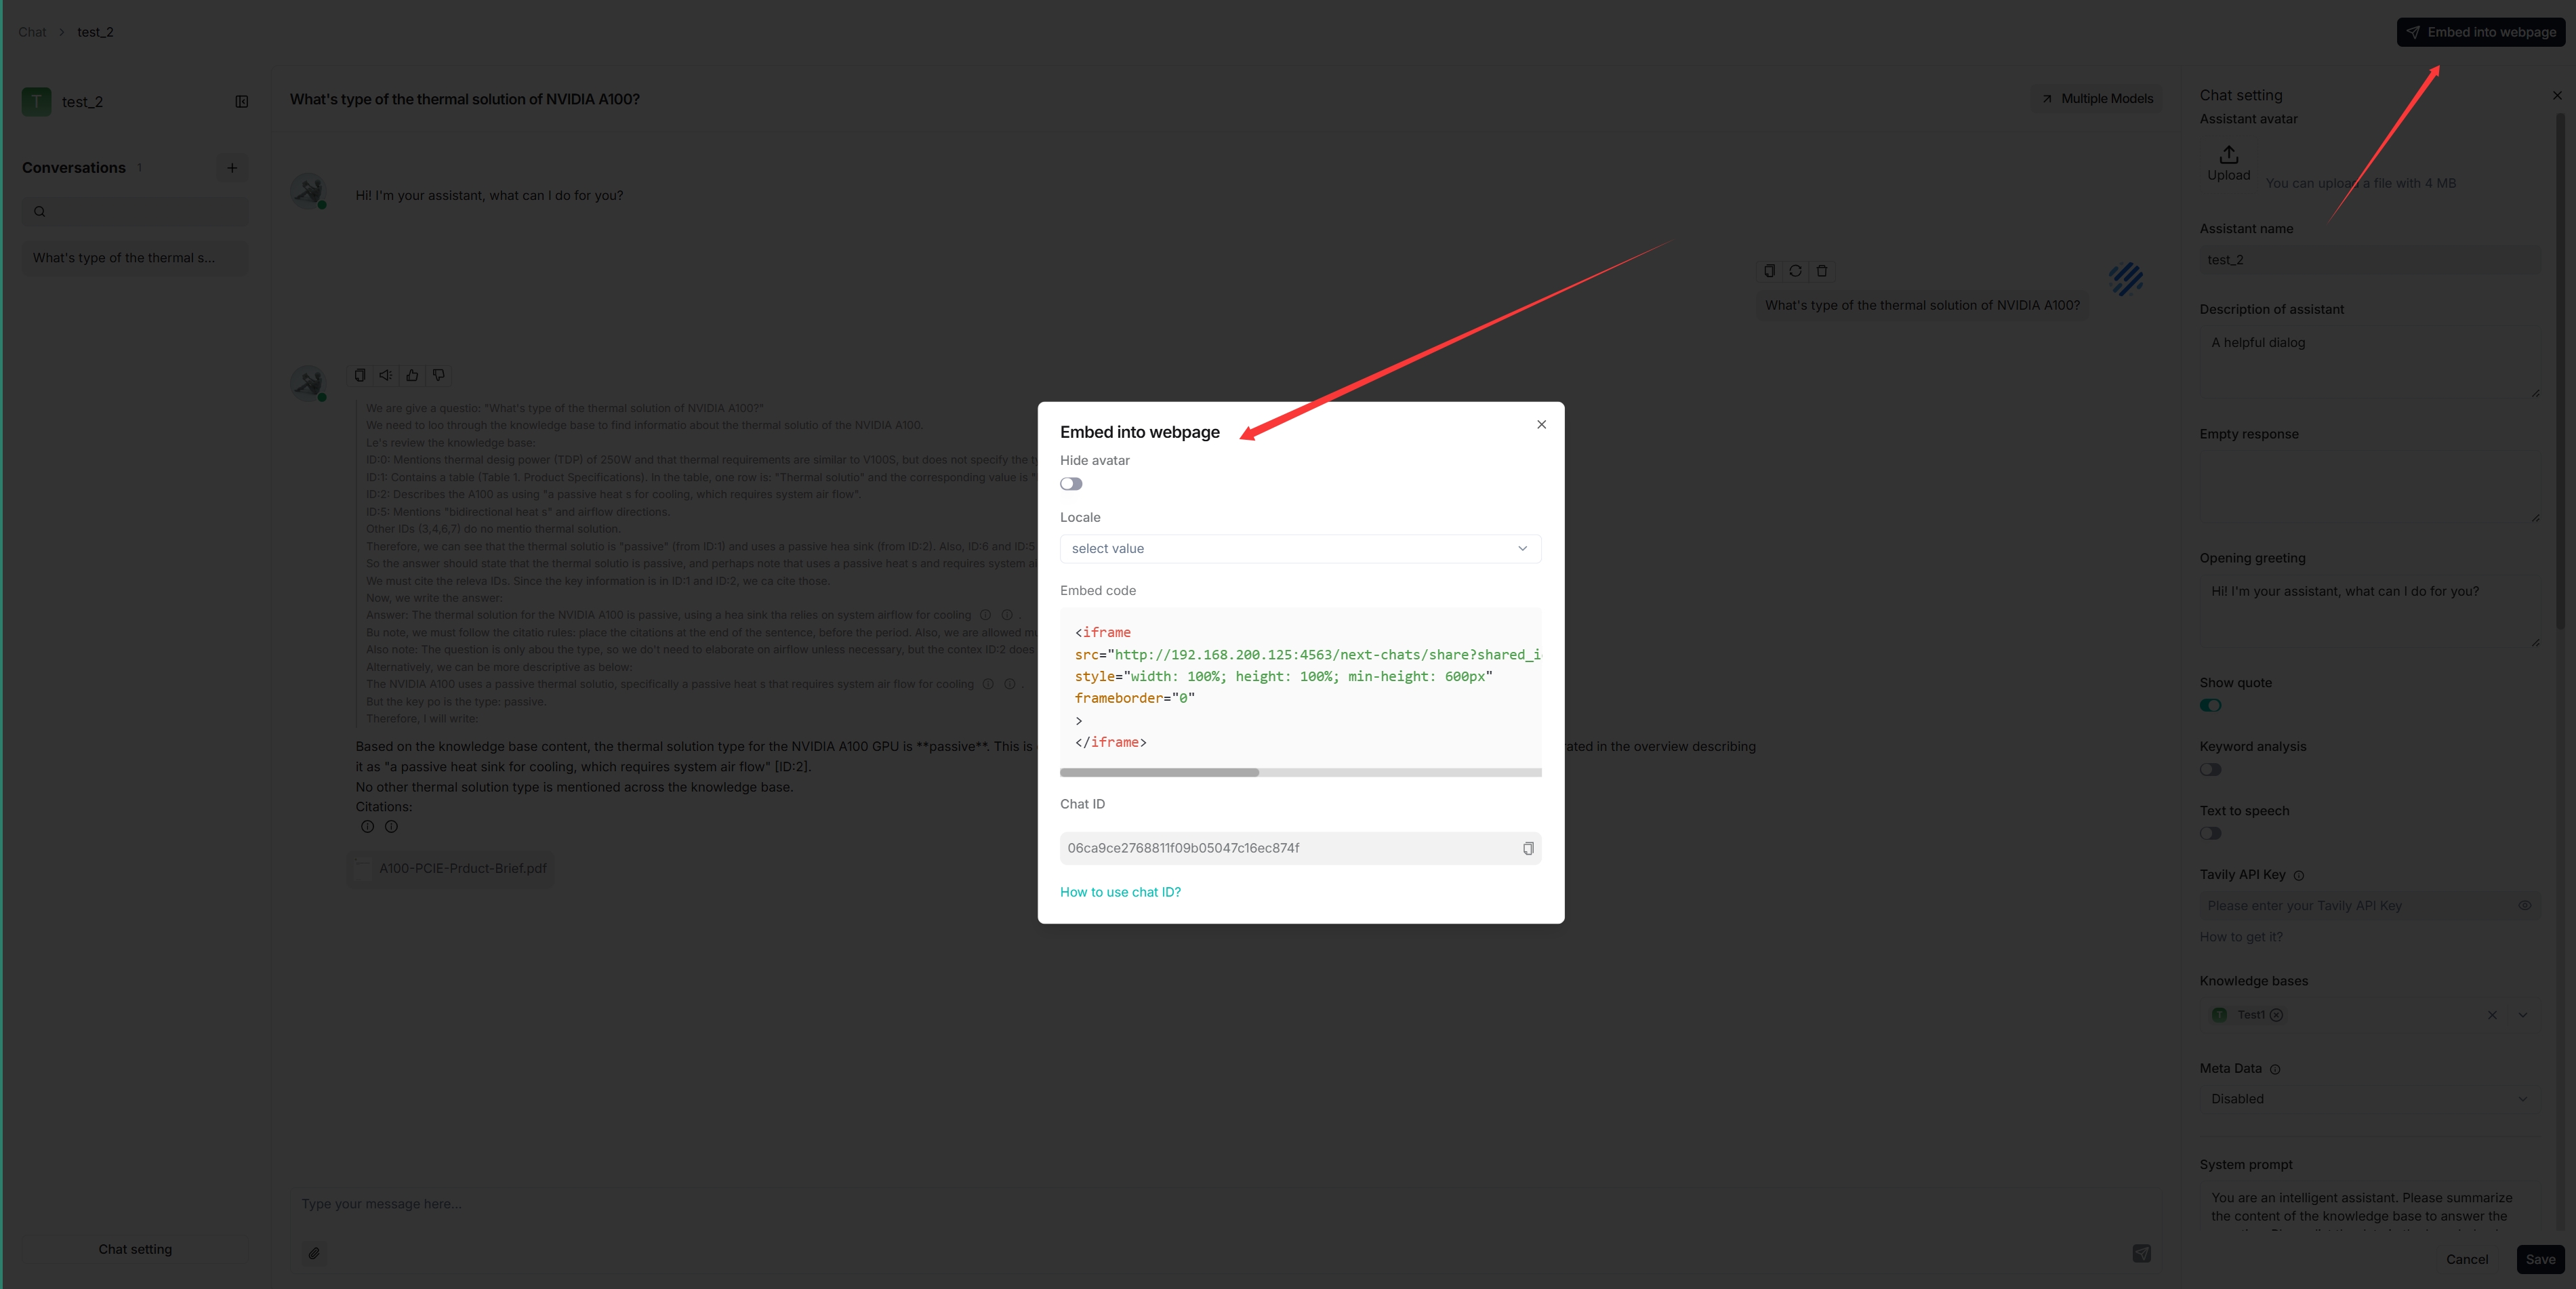
You can use iframe to embed the created chat assistant into a third-party webpage:
|
||||
|
||||
1. Before proceeding, you must [acquire an API key](../../develop/acquire_ragflow_api_key.md); otherwise, an error message would appear.
|
||||
2. Hover over an intended chat assistant **>** **Edit** to show the **iframe** window:
|
||||
|
||||
|
||||
|
||||
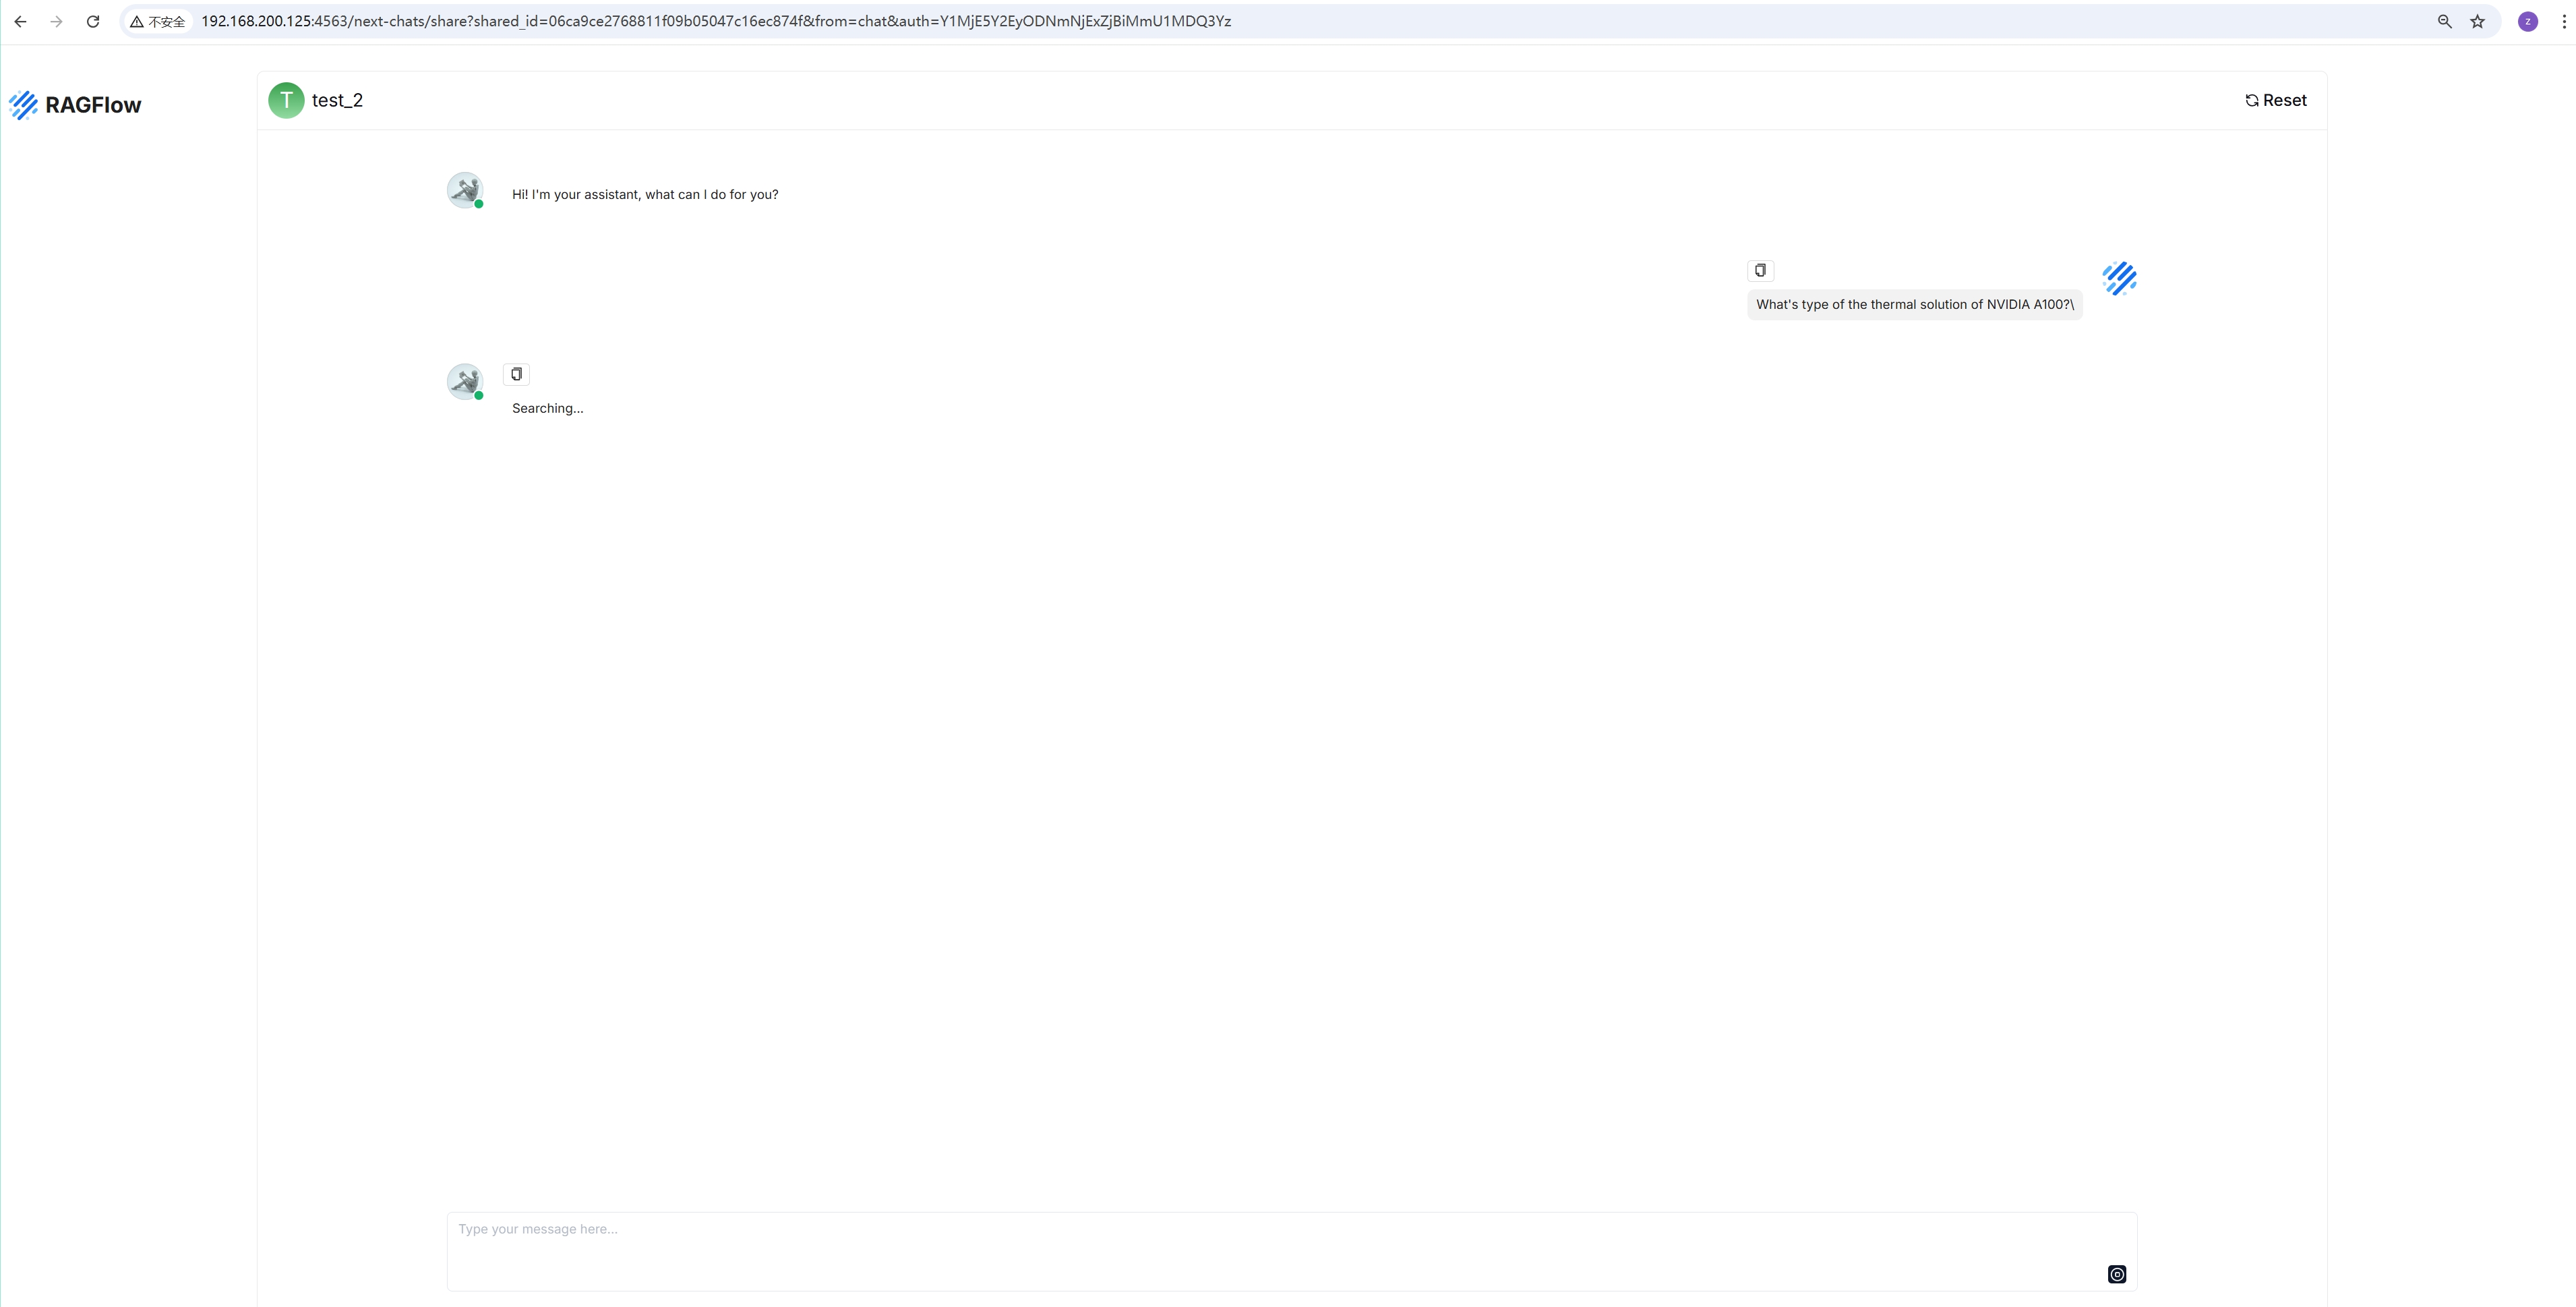
3. Copy the iframe and embed it into your webpage.
|
||||
|
||||
|
||||
@@ -0,0 +1,23 @@
|
||||
---
|
||||
sidebar_position: 4
|
||||
title: Multimodel Comparison
|
||||
sidebar_label: Multimodel_Comparison
|
||||
slug: /chat_Multimodel_Comparison
|
||||
sidebar_custom_props:
|
||||
categoryIcon: LucideTestTube
|
||||
---
|
||||
|
||||
|
||||
|
||||
# Multi-model Comparison
|
||||
|
||||
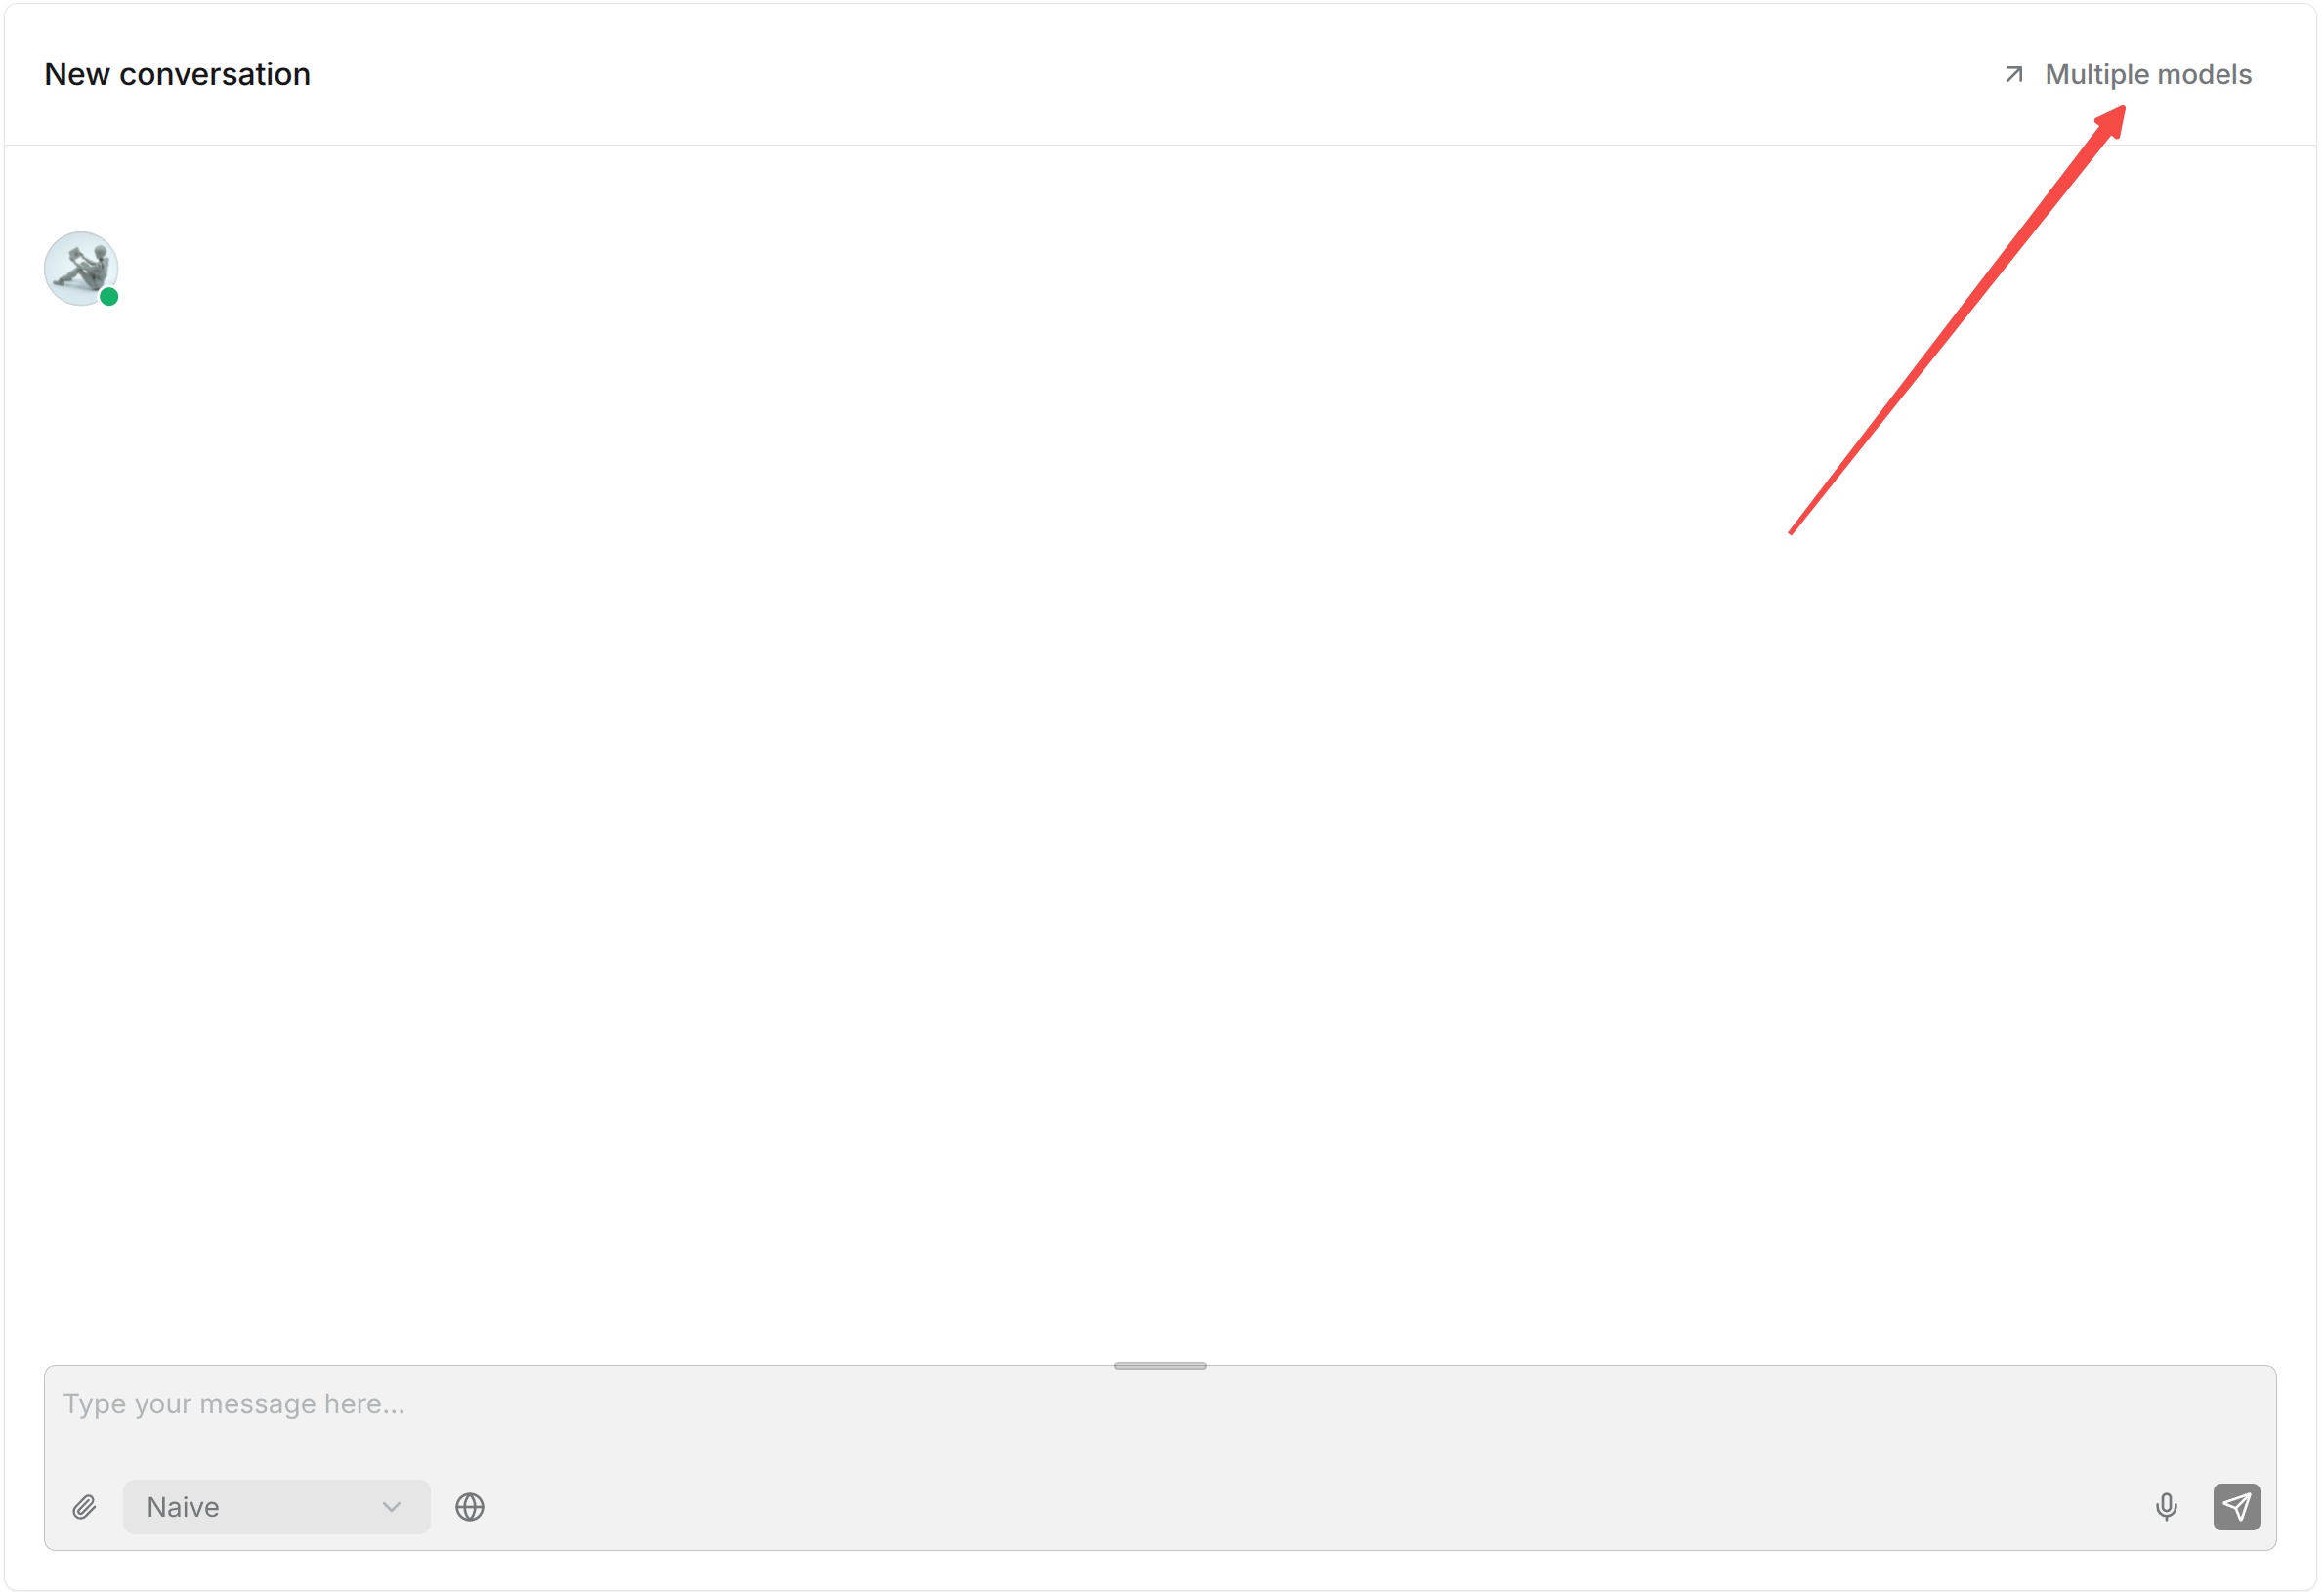
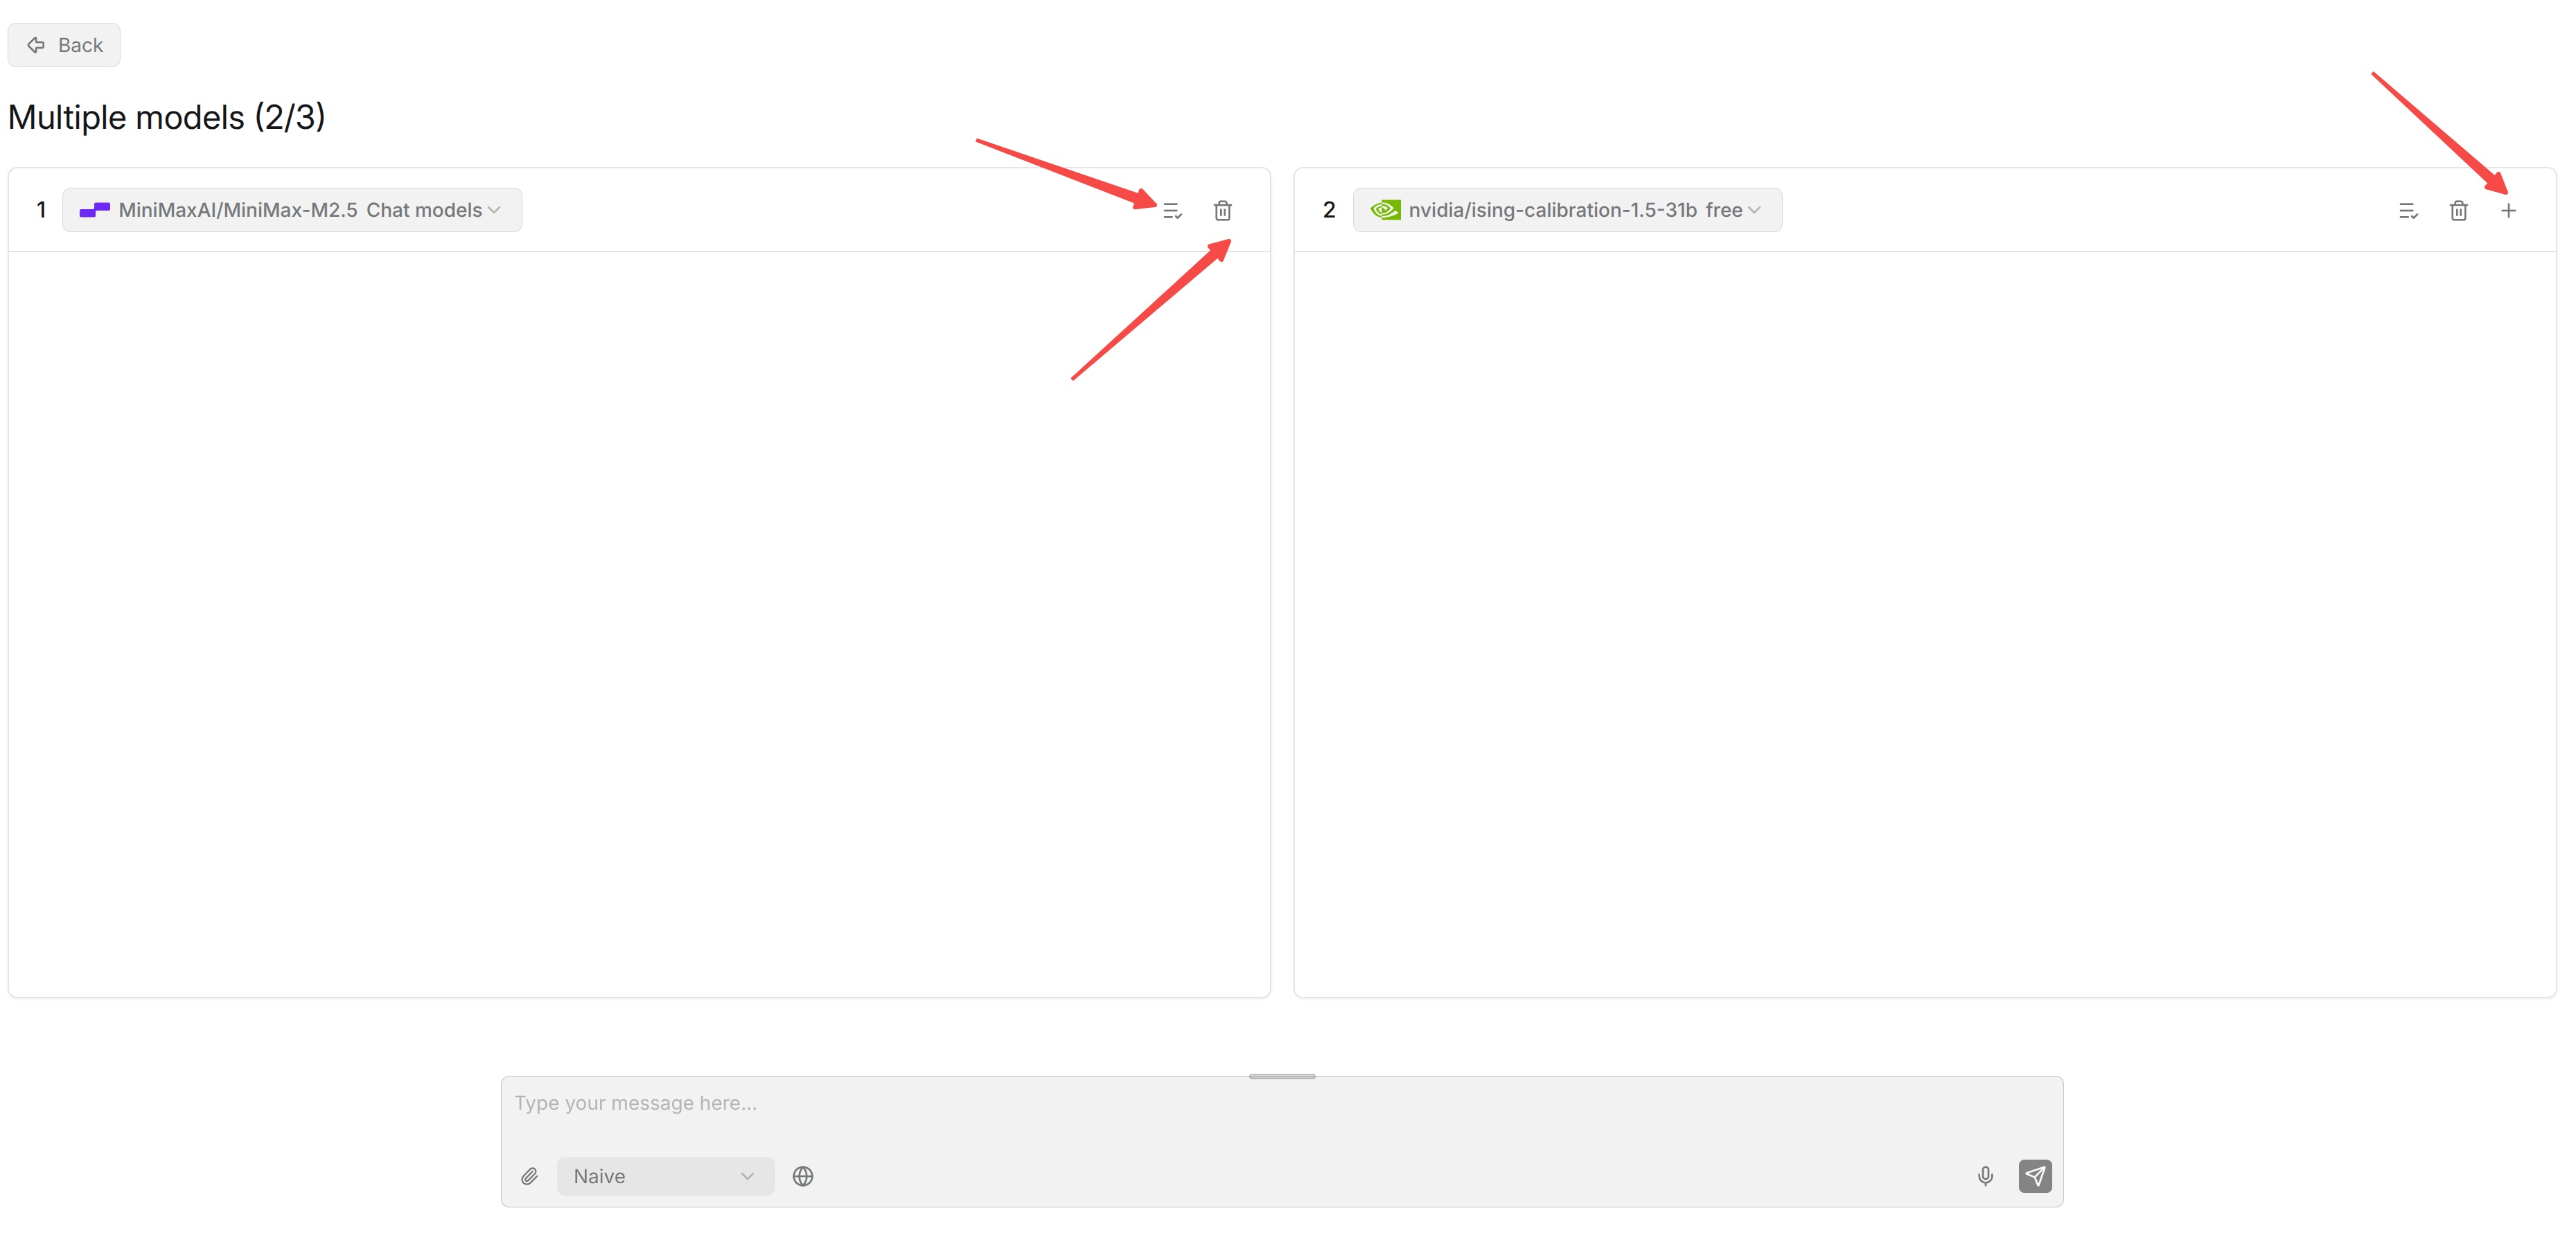
Multi-model comparison tests several models simultaneously with the same Chat configuration and the same question, then displays the answer generated by each model.
|
||||
|
||||
Select the models to compare, enter a test question, and run the comparison. Focus on whether each answer is accurate, whether it correctly uses knowledge base content, and how the answers differ between models.
|
||||
|
||||
|
||||
|
||||
|
||||
|
||||
Use representative questions from actual business scenarios instead of selecting a model based on a single question. Multi-model comparison is primarily intended for model selection and debugging. For example, after changing a model provider or model version, use the same questions to quickly compare the practical performance of the old and new models.
|
||||
|
||||
@@ -0,0 +1,76 @@
|
||||
---
|
||||
sidebar_position: 2
|
||||
title: Using Chat conversations
|
||||
sidebar_label: Using Chat conversations
|
||||
slug: /using_chat_conversations
|
||||
sidebar_custom_props:
|
||||
categoryIcon: LucideMessagesSquare
|
||||
---
|
||||
|
||||
# Using Chat conversations
|
||||
|
||||
After entering a Chat, users can ask questions in different conversations. The conversation list appears on the left, the current conversation appears in the center, and the message input box appears at the bottom.
|
||||
|
||||
A Chat can contain multiple conversations. Each conversation maintains its own context, while all conversations share the knowledge bases, model, system prompt, and retrieval parameters configured for the Chat.
|
||||
|
||||
## Create and Manage conversations
|
||||
|
||||
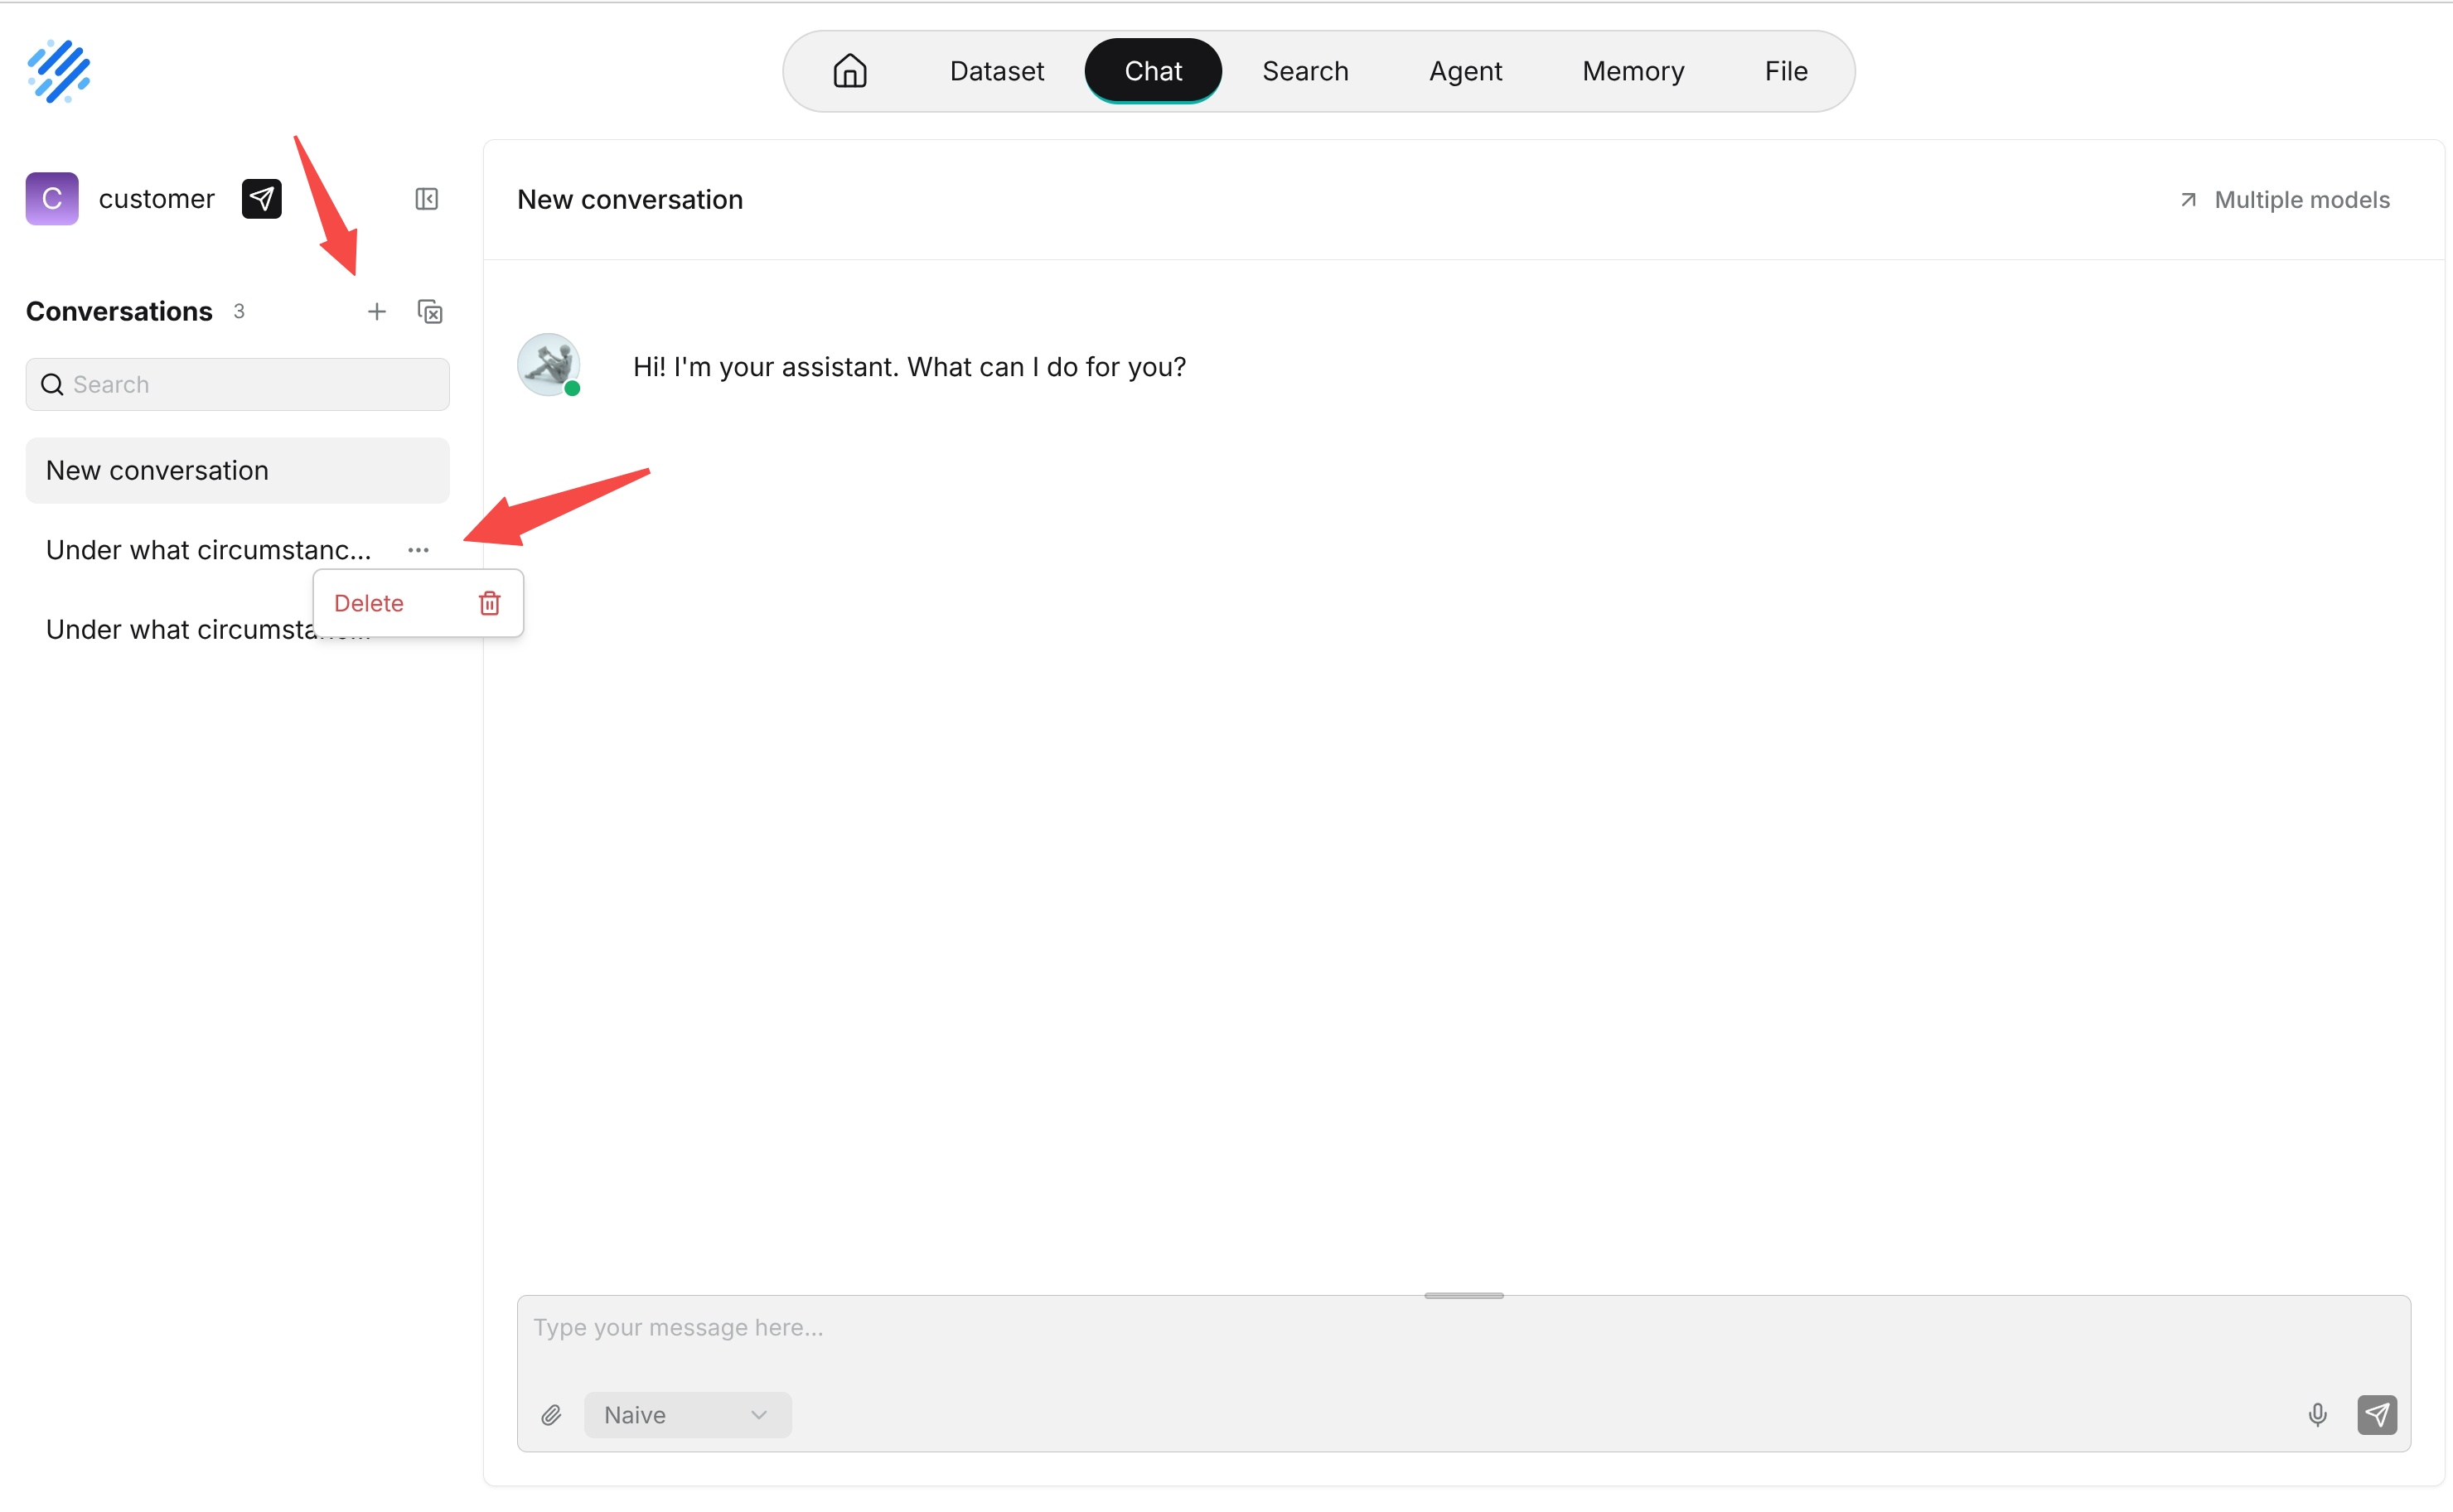
Click **+** in the conversation list to create a conversation. After you send the first message, the system generates a conversation name from the conversation.
|
||||
|
||||
You can perform the following conversation operations:
|
||||
|
||||
- **Switch conversations**: Click a conversation name to open its history and continue the conversation.
|
||||
- **Search conversations**: Use the search box to filter existing conversations by name.
|
||||
- **Delete conversations**: Use the **More** menu beside a conversation. You can also select multiple conversations and delete them together.
|
||||
|
||||
|
||||
|
||||
Use different conversations for different topics. For example, after discussing a product issue, create a new conversation before starting a completely different task so that the earlier context does not affect subsequent answers.
|
||||
|
||||
## Send a Question
|
||||
|
||||
Enter a question in the message box and press **Enter**, or click **Send**. Press **Shift+Enter** to insert a line break.
|
||||
|
||||
While an answer is being generated, click **Stop** to interrupt it. Before sending a question, you can select a Thinking mode, enable or disable web search, and add attachments.
|
||||
|
||||
Chat generates an answer using the current conversation history together with the Chat's configured knowledge bases, model, and system prompt.
|
||||
|
||||
## Upload Files
|
||||
|
||||
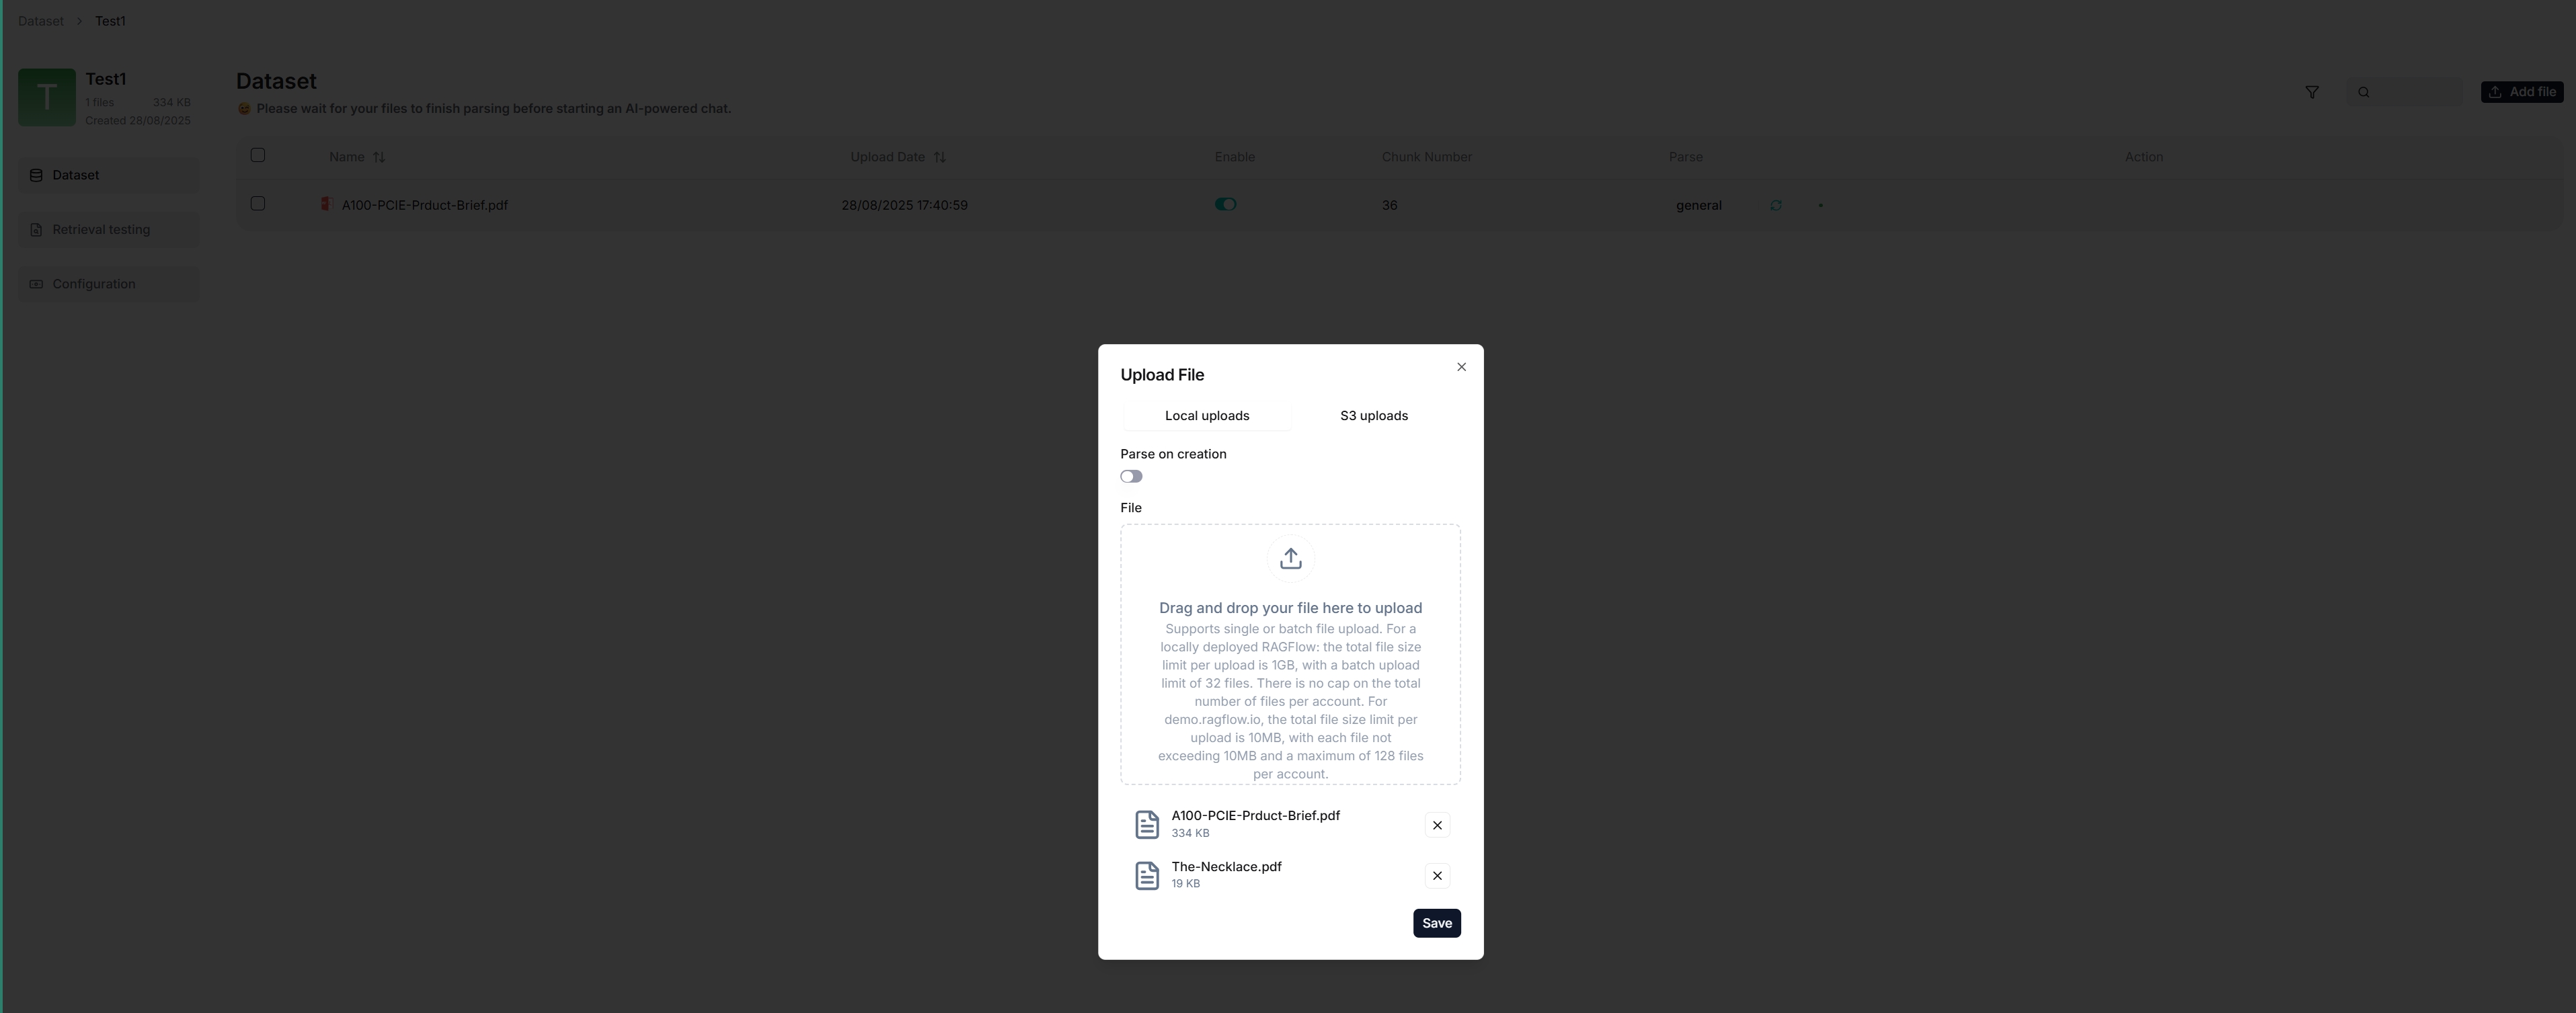
Click the paperclip icon in the message box, or drag files into the message box, to send files with your question as attachments. Uploaded files appear above the message box; remove any unnecessary files before sending.
|
||||
|
||||
Text files can be parsed into text for the model to reference. Processing images requires a model with multimodal capabilities.
|
||||
|
||||
|
||||
|
||||
Files uploaded in a conversation provide supplemental context only and are not automatically added to a knowledge base. To make a file permanently available for knowledge base retrieval, add it to a knowledge base and complete parsing.
|
||||
|
||||
The supported number, size, and types of files depend on the deployment and answer configuration. Follow the instructions displayed in the interface.
|
||||
|
||||
## Use Voice Input
|
||||
|
||||
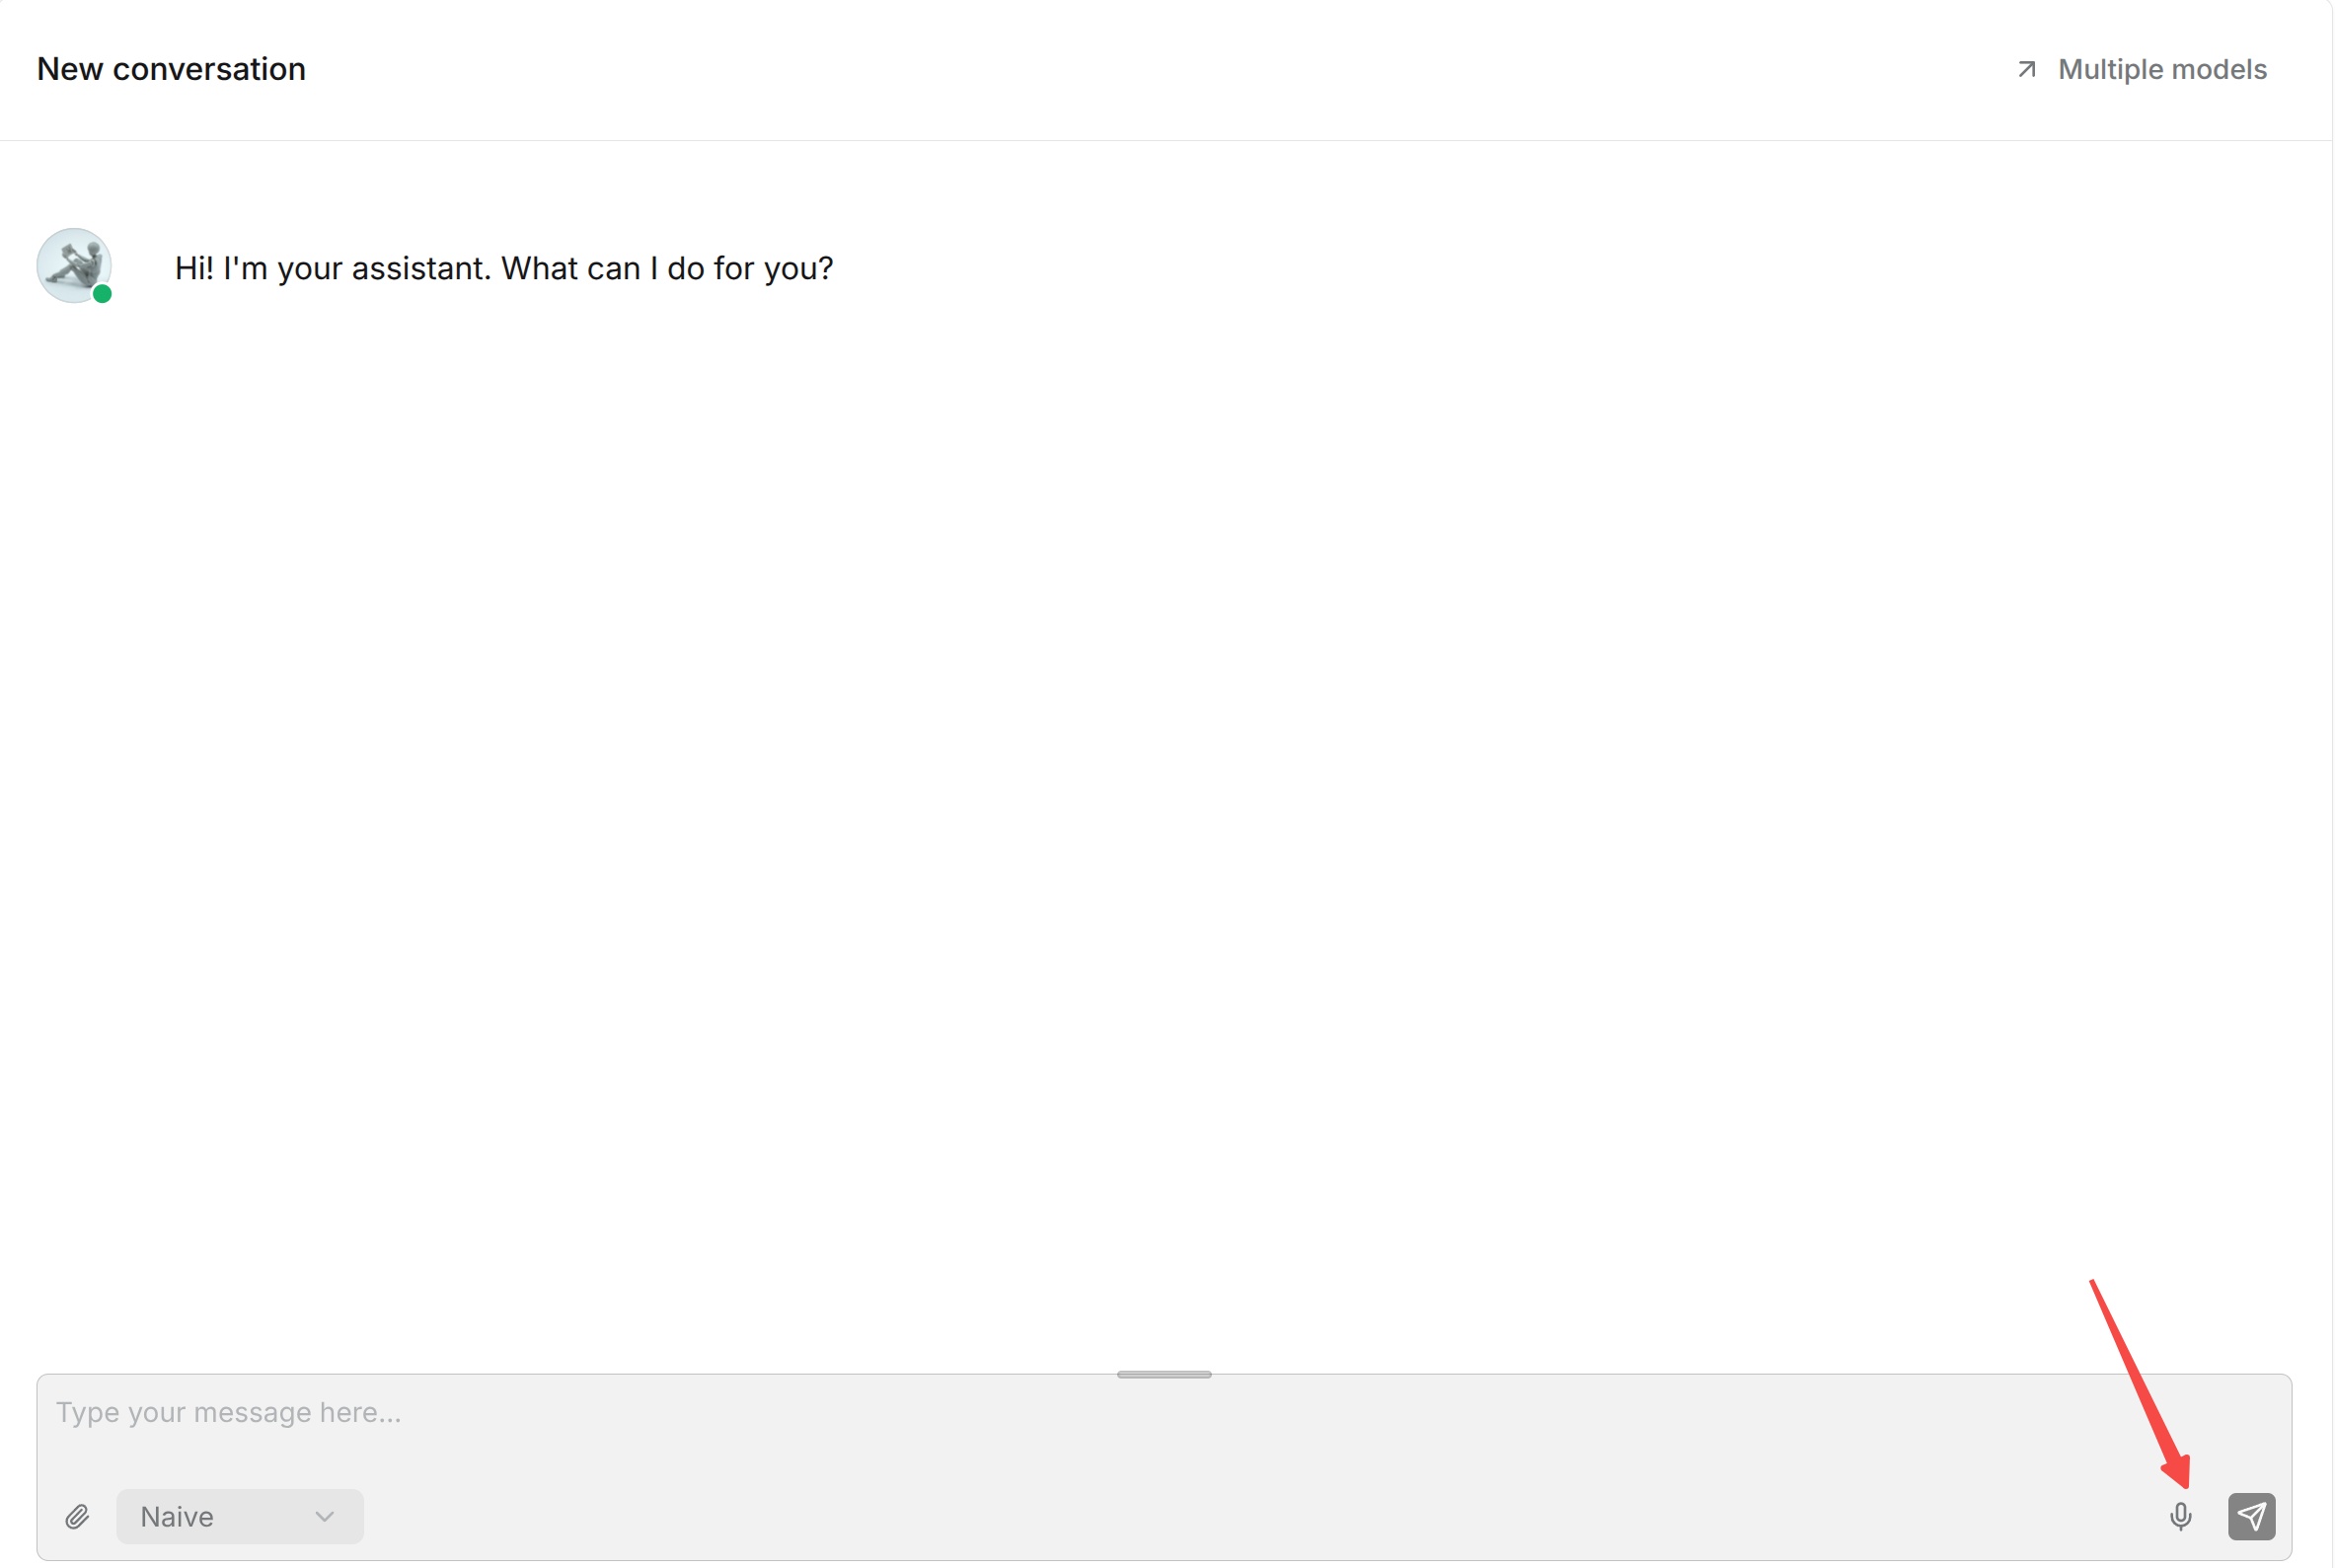
Click the microphone icon in the message box to start recording, then click it again to finish. The browser may request microphone permission the first time you use this feature.
|
||||
|
||||
After recording, the system converts the speech to text with the configured speech recognition model and sends it as a question.
|
||||
|
||||
|
||||
|
||||
## Embed into a Website
|
||||
|
||||
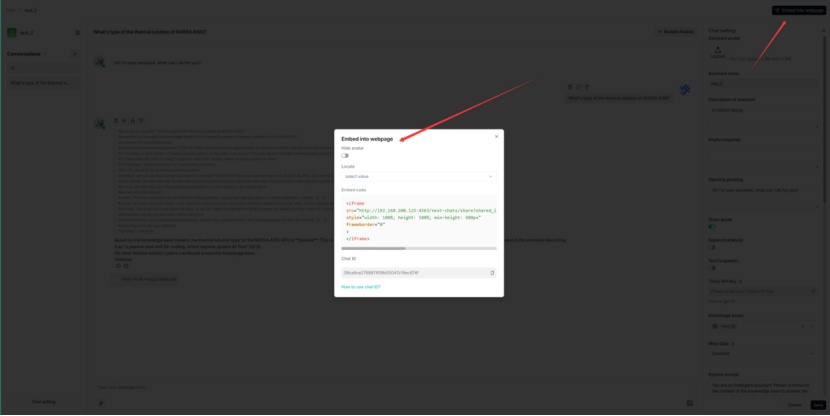
Click the paper-airplane icon next to the Chat name to open **Embed into website**. Use this configuration to integrate Chat into an external webpage or business system.
|
||||
|
||||
RAGFlow provides HTTP and Python APIs for integration:
|
||||
|
||||
- [Acquire a RAGFlow API key](../../develop/acquire_ragflow_api_key.md)
|
||||
- [HTTP API reference](../../references/http_api_reference.md)
|
||||
- [Python API reference](../../references/python_api_reference.md)
|
||||
|
||||
You can also embed the created Chat assistant in a third-party webpage with an iframe:
|
||||
|
||||
1. [Acquire an API key](../../develop/acquire_ragflow_api_key.md) before continuing. Otherwise, an error occurs.
|
||||
2. Hover over the target Chat assistant and click **Edit** to open the iframe window.
|
||||
3. Copy the iframe code and embed it in your webpage.
|
||||
|
||||
|
||||
|
||||
|
||||
Reference in New Issue
Block a user