mirror of
https://github.com/infiniflow/ragflow.git
synced 2026-10-12 02:16:39 +00:00
docs: remove unnecessary docs & adjust page layout (#18146)
remove unnecessary docs
adjust page layout
fix some images layout
add chat channel docs
This commit is contained in:
 YanZhang
@@ -1,6 +1,6 @@
|
||||
{
|
||||
"label": "Agents",
|
||||
"position": 3,
|
||||
"position": 5,
|
||||
"link": {
|
||||
"type": "generated-index",
|
||||
"description": "RAGFlow v0.8.0 introduces an agent mechanism, featuring a no-code workflow editor on the front end and a comprehensive graph-based task orchestration framework on the backend."
|
||||
|
||||
+16
-4
@@ -1,14 +1,26 @@
|
||||
---
|
||||
sidebar_position: 2
|
||||
title: "Relationship Between Agent and Knowledge Base Q&A"
|
||||
sidebar_label: "Relationship Between Agent and Knowledge Base Q&A"
|
||||
slug: /relationship_between_agent_and_knowledge_base_qa
|
||||
title: Agent Overview
|
||||
sidebar_label: Agent Overview
|
||||
slug: /agent_overview
|
||||
sidebar_custom_props: {
|
||||
categoryIcon: RagAiAgent
|
||||
}
|
||||
---
|
||||
|
||||
# Relationship Between Agent and Knowledge Base Q&A
|
||||
# Agent Overview
|
||||
|
||||
## Purpose of Agent
|
||||
Agent is the business workflow orchestration capability in RAGFlow. Users can add components on a no-code canvas and define execution order via connections. Components can be executed sequentially, or enter different paths according to conditional branches, classification results or loop logic.
|
||||
|
||||
Agents are commonly used in the following scenarios:
|
||||
- Answering user questions based on knowledge bases.
|
||||
- Identifying user intents and routing to different processing flows.
|
||||
- Calling HTTP interfaces, databases, MCP tools or custom code.
|
||||
- Splitting and batch processing long texts.
|
||||
- Saving session memory or exporting processing results.
|
||||
|
||||
## Relationship Between Agent and Knowledge Base Q&A
|
||||
- **Chat**: Suitable for applications mainly based on knowledge base Q&A and multi-turn dialogue.
|
||||
- **Agent**: Suitable for business workflows requiring conditional branching, tool calling, data processing or multi-step orchestration.
|
||||
|
||||
@@ -1,11 +0,0 @@
|
||||
{
|
||||
"label": "Agent Overview",
|
||||
"position": 2,
|
||||
"link": {
|
||||
"type": "generated-index",
|
||||
"description": "Agent Overview"
|
||||
},
|
||||
"customProps": {
|
||||
"categoryIcon": "RagAiAgent"
|
||||
}
|
||||
}
|
||||
@@ -1,19 +0,0 @@
|
||||
---
|
||||
sidebar_position: 1
|
||||
title: Purpose of Agent
|
||||
sidebar_label: Purpose of Agent
|
||||
slug: /purpose_of_agent
|
||||
sidebar_custom_props: {
|
||||
categoryIcon: RagAiAgent
|
||||
}
|
||||
---
|
||||
|
||||
# Purpose of Agent
|
||||
Agent is the business workflow orchestration capability in RAGFlow. Users can add components on a no-code canvas and define execution order via connections. Components can be executed sequentially, or enter different paths according to conditional branches, classification results or loop logic.
|
||||
|
||||
Agents are commonly used in the following scenarios:
|
||||
- Answering user questions based on knowledge bases.
|
||||
- Identifying user intents and routing to different processing flows.
|
||||
- Calling HTTP interfaces, databases, MCP tools or custom code.
|
||||
- Splitting and batch processing long texts.
|
||||
- Saving session memory or exporting processing results.
|
||||
@@ -9,154 +9,209 @@ sidebar_custom_props: {
|
||||
---
|
||||
|
||||
# Basic Component Configuration
|
||||
## Begin Component
|
||||
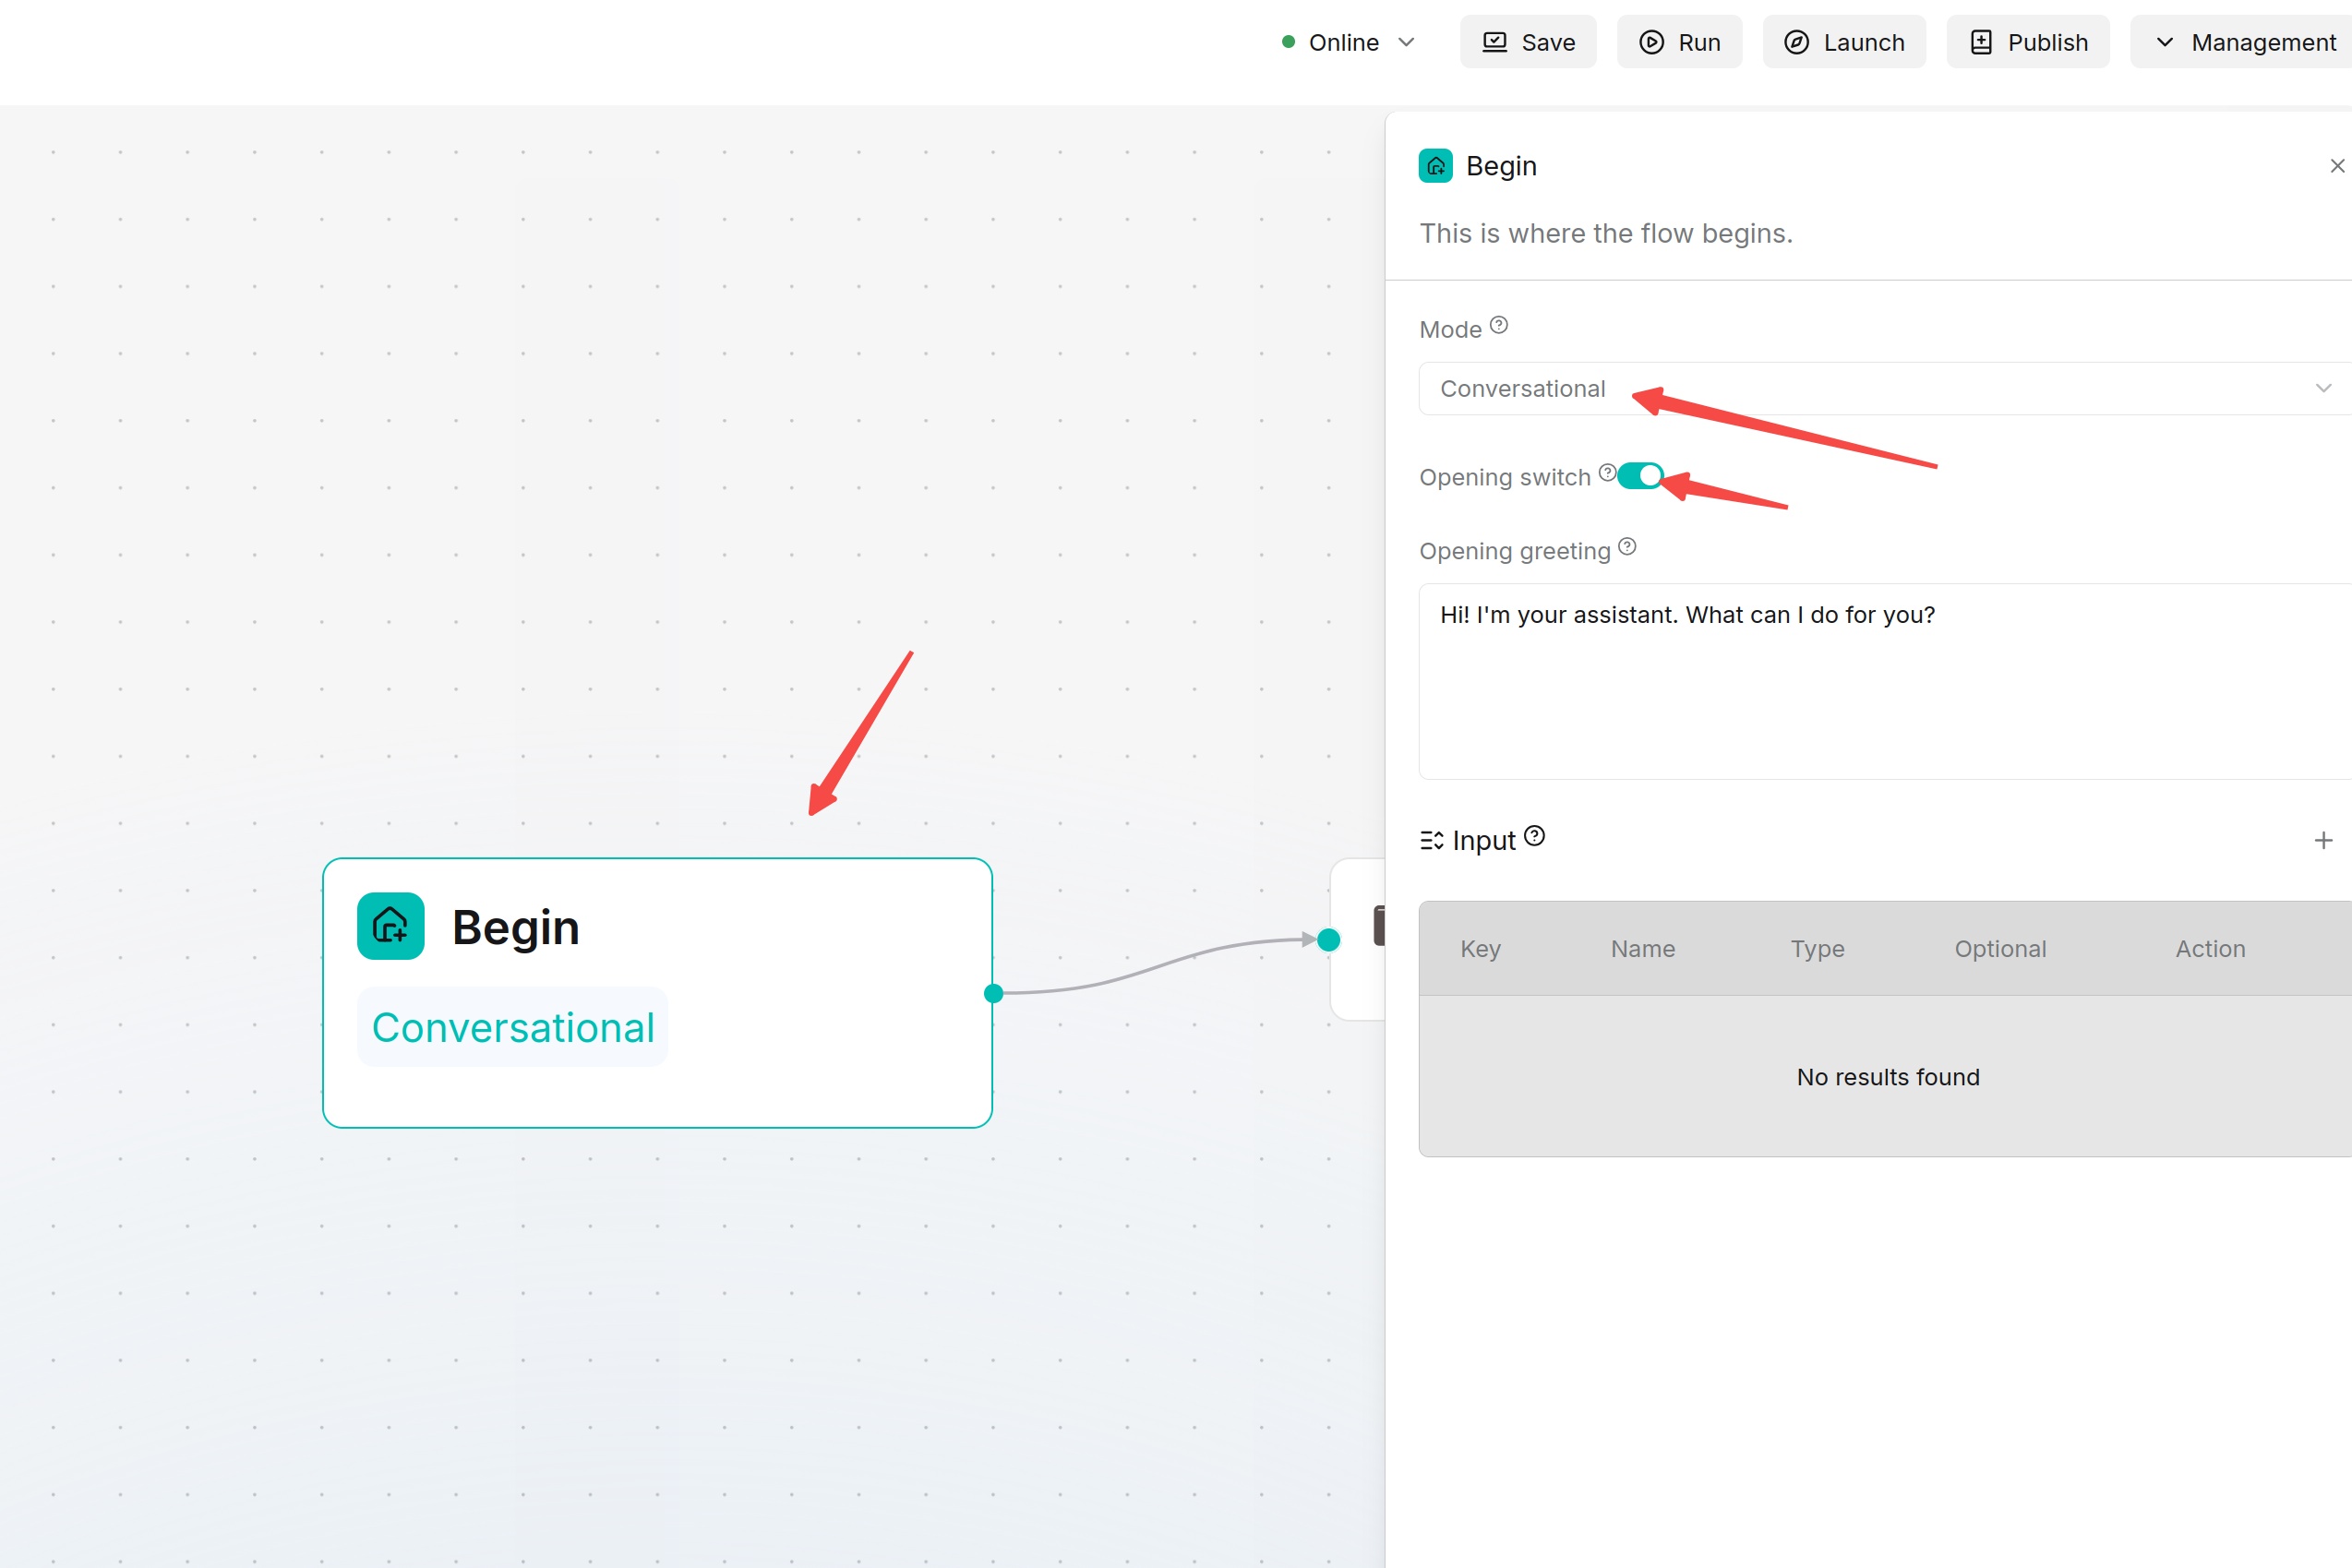
`Begin` is the start of the Agent workflow, used to set trigger mode, opening greeting and global input variables. Every Agent must contain exactly one Begin component.
|
||||
|
||||
### Trigger Modes
|
||||
- **Conversational**: Triggered via dialogue, suitable for regular chat Agents.
|
||||
- **Task**: Started as a task, suitable for non-dialog automated workflows.
|
||||
- **Webhook**: Triggered by external HTTP requests, suitable for system integration, automation tasks and third-party callbacks.
|
||||
When Webhook mode is selected, the system generates the Agent Webhook URL. You can further configure request method, security authentication, request Schema and response mode.
|
||||
## Begin Component
|
||||
|
||||
`Begin` is the starting point of an Agent workflow. It is used to set the trigger mode, opening greeting, and global input variables. Every Agent must contain a `Begin` component.
|
||||
|
||||
### Trigger Mode
|
||||
|
||||
`Begin` supports the following modes:
|
||||
|
||||
- **Conversational**: Triggered from a conversation. This is suitable for regular chat-style Agents.
|
||||
- **Task**: Started as a task. This is suitable for non-conversational automated workflows.
|
||||
- **Webhook**: Triggered by external HTTP requests. This is suitable for system integration, automation tasks, and third-party callbacks.
|
||||
|
||||
When `Webhook` mode is selected, the system generates the current Agent's Webhook URL. You can continue to configure the request method, security authentication, request schema, and response method.
|
||||
|
||||
### Opening Greeting
|
||||
In Conversational mode, set the first message sent by the Agent in Opening greeting. The greeting should clearly describe supported capabilities instead of lengthy introductions.
|
||||
|
||||
In `Conversational` mode, you can set the first message that the Agent says to the user in **Opening greeting**. The opening greeting should describe what the Agent can handle, and should not be written as a lengthy product introduction.
|
||||
|
||||
Example:
|
||||
> Hello, I can help you query product materials, compare models and generate installation suggestions.
|
||||
> Please describe your question or upload files for analysis.
|
||||
|
||||
### Input Variables
|
||||
Input defines parameters users need to provide before dialogue starts. After configuration, subsequent components can reference these inputs via variables.
|
||||
|
||||
On the Input section of the Begin configuration panel, click the `+` button to add new input variables.
|
||||
|
||||
Common fields:
|
||||
- **Name**: Display name of variable
|
||||
- **Type**: Variable type
|
||||
- **Key**: Variable key referenced by downstream components
|
||||
- **Optional**: Whether this input is optional
|
||||
|
||||
Variable Types:
|
||||
| Type | Description |
|
||||
| ---- | ---- |
|
||||
| Single-line text | Short text input: names, keywords, serial numbers |
|
||||
| Paragraph text | Long content: requirement descriptions, prompts, problem details |
|
||||
| Dropdown options | Predefined selection list, suitable for fixed options such as language, department |
|
||||
| File upload | Allow users to upload files as workflow input for document analysis and image processing. Uploaded files will NOT be automatically saved to knowledge bases and are only used within the current workflow. |
|
||||
| Number | Numeric input: quantity, threshold, Top K value, maximum return entries |
|
||||
| Boolean | Toggle (True/False) to enable functions or confirm execution branches |
|
||||
|
||||
:::tip NOTE
|
||||
Files uploaded through the Begin component are only used as workflow input. They will not be automatically saved to knowledge bases, nor use knowledge base parsing, OCR or chunking capabilities. File content can be passed to subsequent components as variables and limited by model context length.
|
||||
:::
|
||||
> Hello, I can help you query product materials, compare models, and generate installation suggestions.
|
||||
> Please describe your question, or upload the files that need to be analyzed.
|
||||
|
||||
|
||||
|
||||
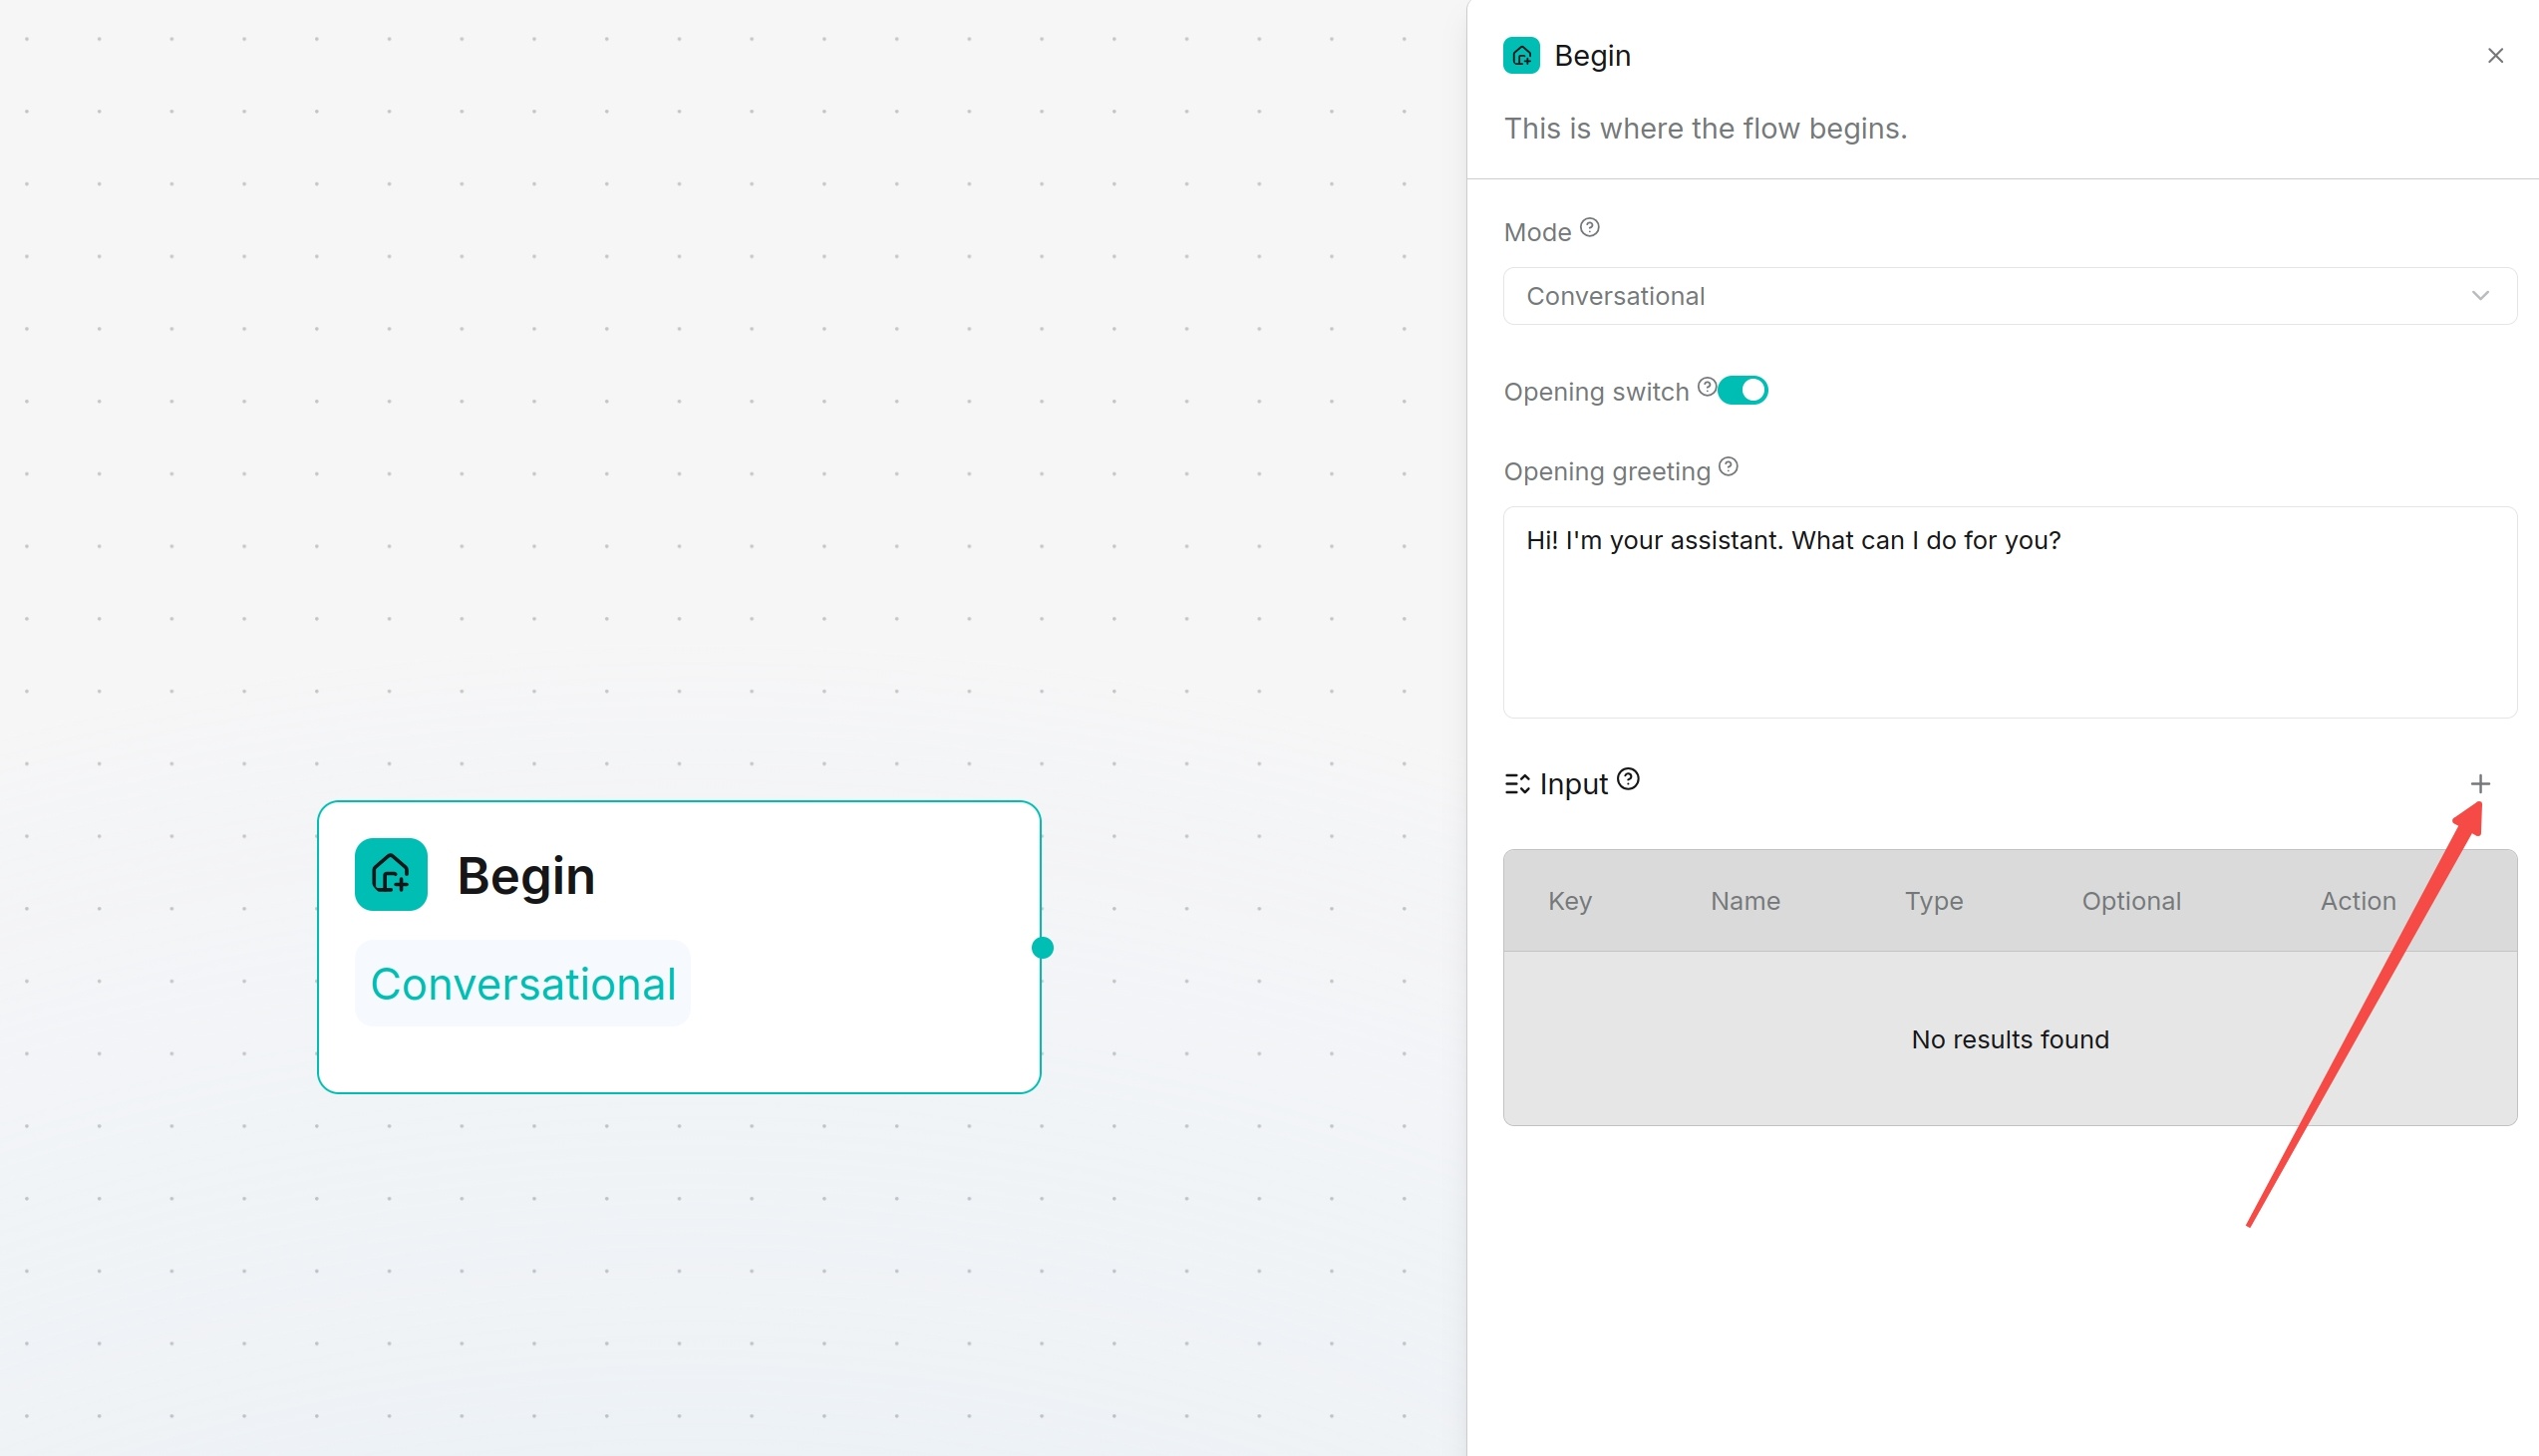
### Input Variables
|
||||
|
||||
`Input` is used to define the input parameters that users need to provide before starting a conversation. After configuration, subsequent components can reference these inputs through variables.
|
||||
|
||||
In the **Input** area of the right configuration panel for the `Begin` component, click the `+` button in the upper right corner to add an input variable.
|
||||
|
||||
Common fields are as follows:
|
||||
|
||||
- **Name**: The variable display name.
|
||||
- **Type**: The variable type, including single-line text, paragraph text, dropdown options, file upload, number, and Boolean.
|
||||
- **Key**: The variable key, used by subsequent components for reference.
|
||||
- **Optional**: Whether the input is optional.
|
||||
|
||||
Variable types:
|
||||
|
||||
| Type | Description |
|
||||
| --- | --- |
|
||||
| Single-line text | Used to enter short text, such as names, keywords, and serial numbers. |
|
||||
| Paragraph text | Used to enter longer content, such as problem descriptions, requirement descriptions, and prompts. |
|
||||
| Dropdown options | Provides predefined options for users to select. You can click **Add option** to add multiple options. This is suitable for fixed-value inputs such as language, department, and model type. |
|
||||
| File upload | Allows users to upload files as workflow input. This can be used for document analysis, image processing, and similar scenarios. Uploaded files are not automatically saved to knowledge bases, and are used only in the current workflow. |
|
||||
| Number | Used to enter numeric values, such as quantity, threshold, `Top K`, and maximum returned items. |
|
||||
| Boolean | Provides a switch (`True`/`False`) or yes/no option, used to control whether a feature is enabled or whether a branch is executed. |
|
||||
|
||||
:::tip NOTE
|
||||
|
||||
Files uploaded through the `Begin` component are used only as input for the current workflow. They are not automatically saved to knowledge bases, and they do not use knowledge base parsing, OCR, or chunking capabilities. File content can be passed to subsequent components as variables, and is limited by the model context length.
|
||||
|
||||
:::
|
||||
|
||||
|
||||
|
||||
## Agent Component
|
||||
The Agent component invokes LLMs for reasoning, content generation, task planning and tool calling. It can process user questions independently or cooperate with retrieval, HTTP requests, code, databases and sub-agents to complete multi-step tasks.
|
||||
|
||||
Capabilities:
|
||||
- Reason, reflect and adjust logic based on context and execution results
|
||||
- Call tools or sub-agents to complete tasks
|
||||
- Control reply style, task boundaries and output format via system & user prompts
|
||||
The Agent component is used to call large language models for reasoning, content generation, task planning, and tool calling. It can process user questions independently, or work with components such as knowledge retrieval, HTTP requests, code, databases, and sub-agents to complete multi-step tasks.
|
||||
|
||||
The Agent component can work independently and has the following capabilities:
|
||||
|
||||
- Reason, reflect, and adjust based on context and execution results.
|
||||
- Call tools or sub-agents to complete tasks.
|
||||
- Control reply style, task boundaries, and output format through system prompts and user prompts.
|
||||
|
||||
### Basic Configuration
|
||||
|
||||
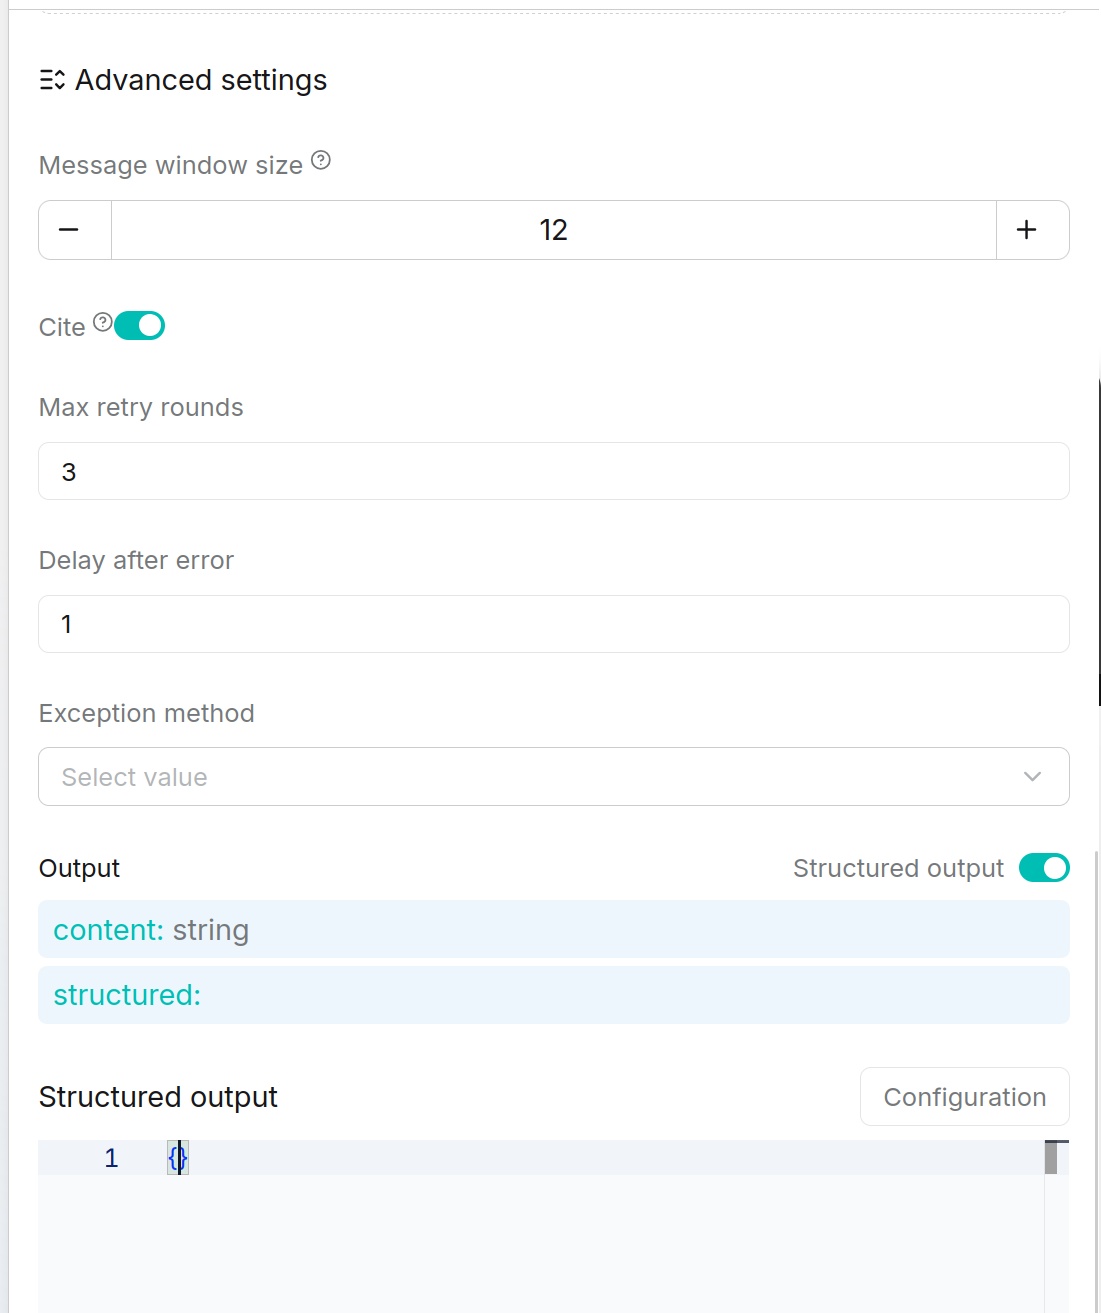
Common configuration items for the Agent component include `Model`, `System prompt`, `User prompt`, `Tools`, `Agent`, `Message window size`, `Max retries`, `Delay after error`, `Max reflection rounds`, and `Output`.
|
||||
|
||||
Configuration steps:
|
||||
|
||||
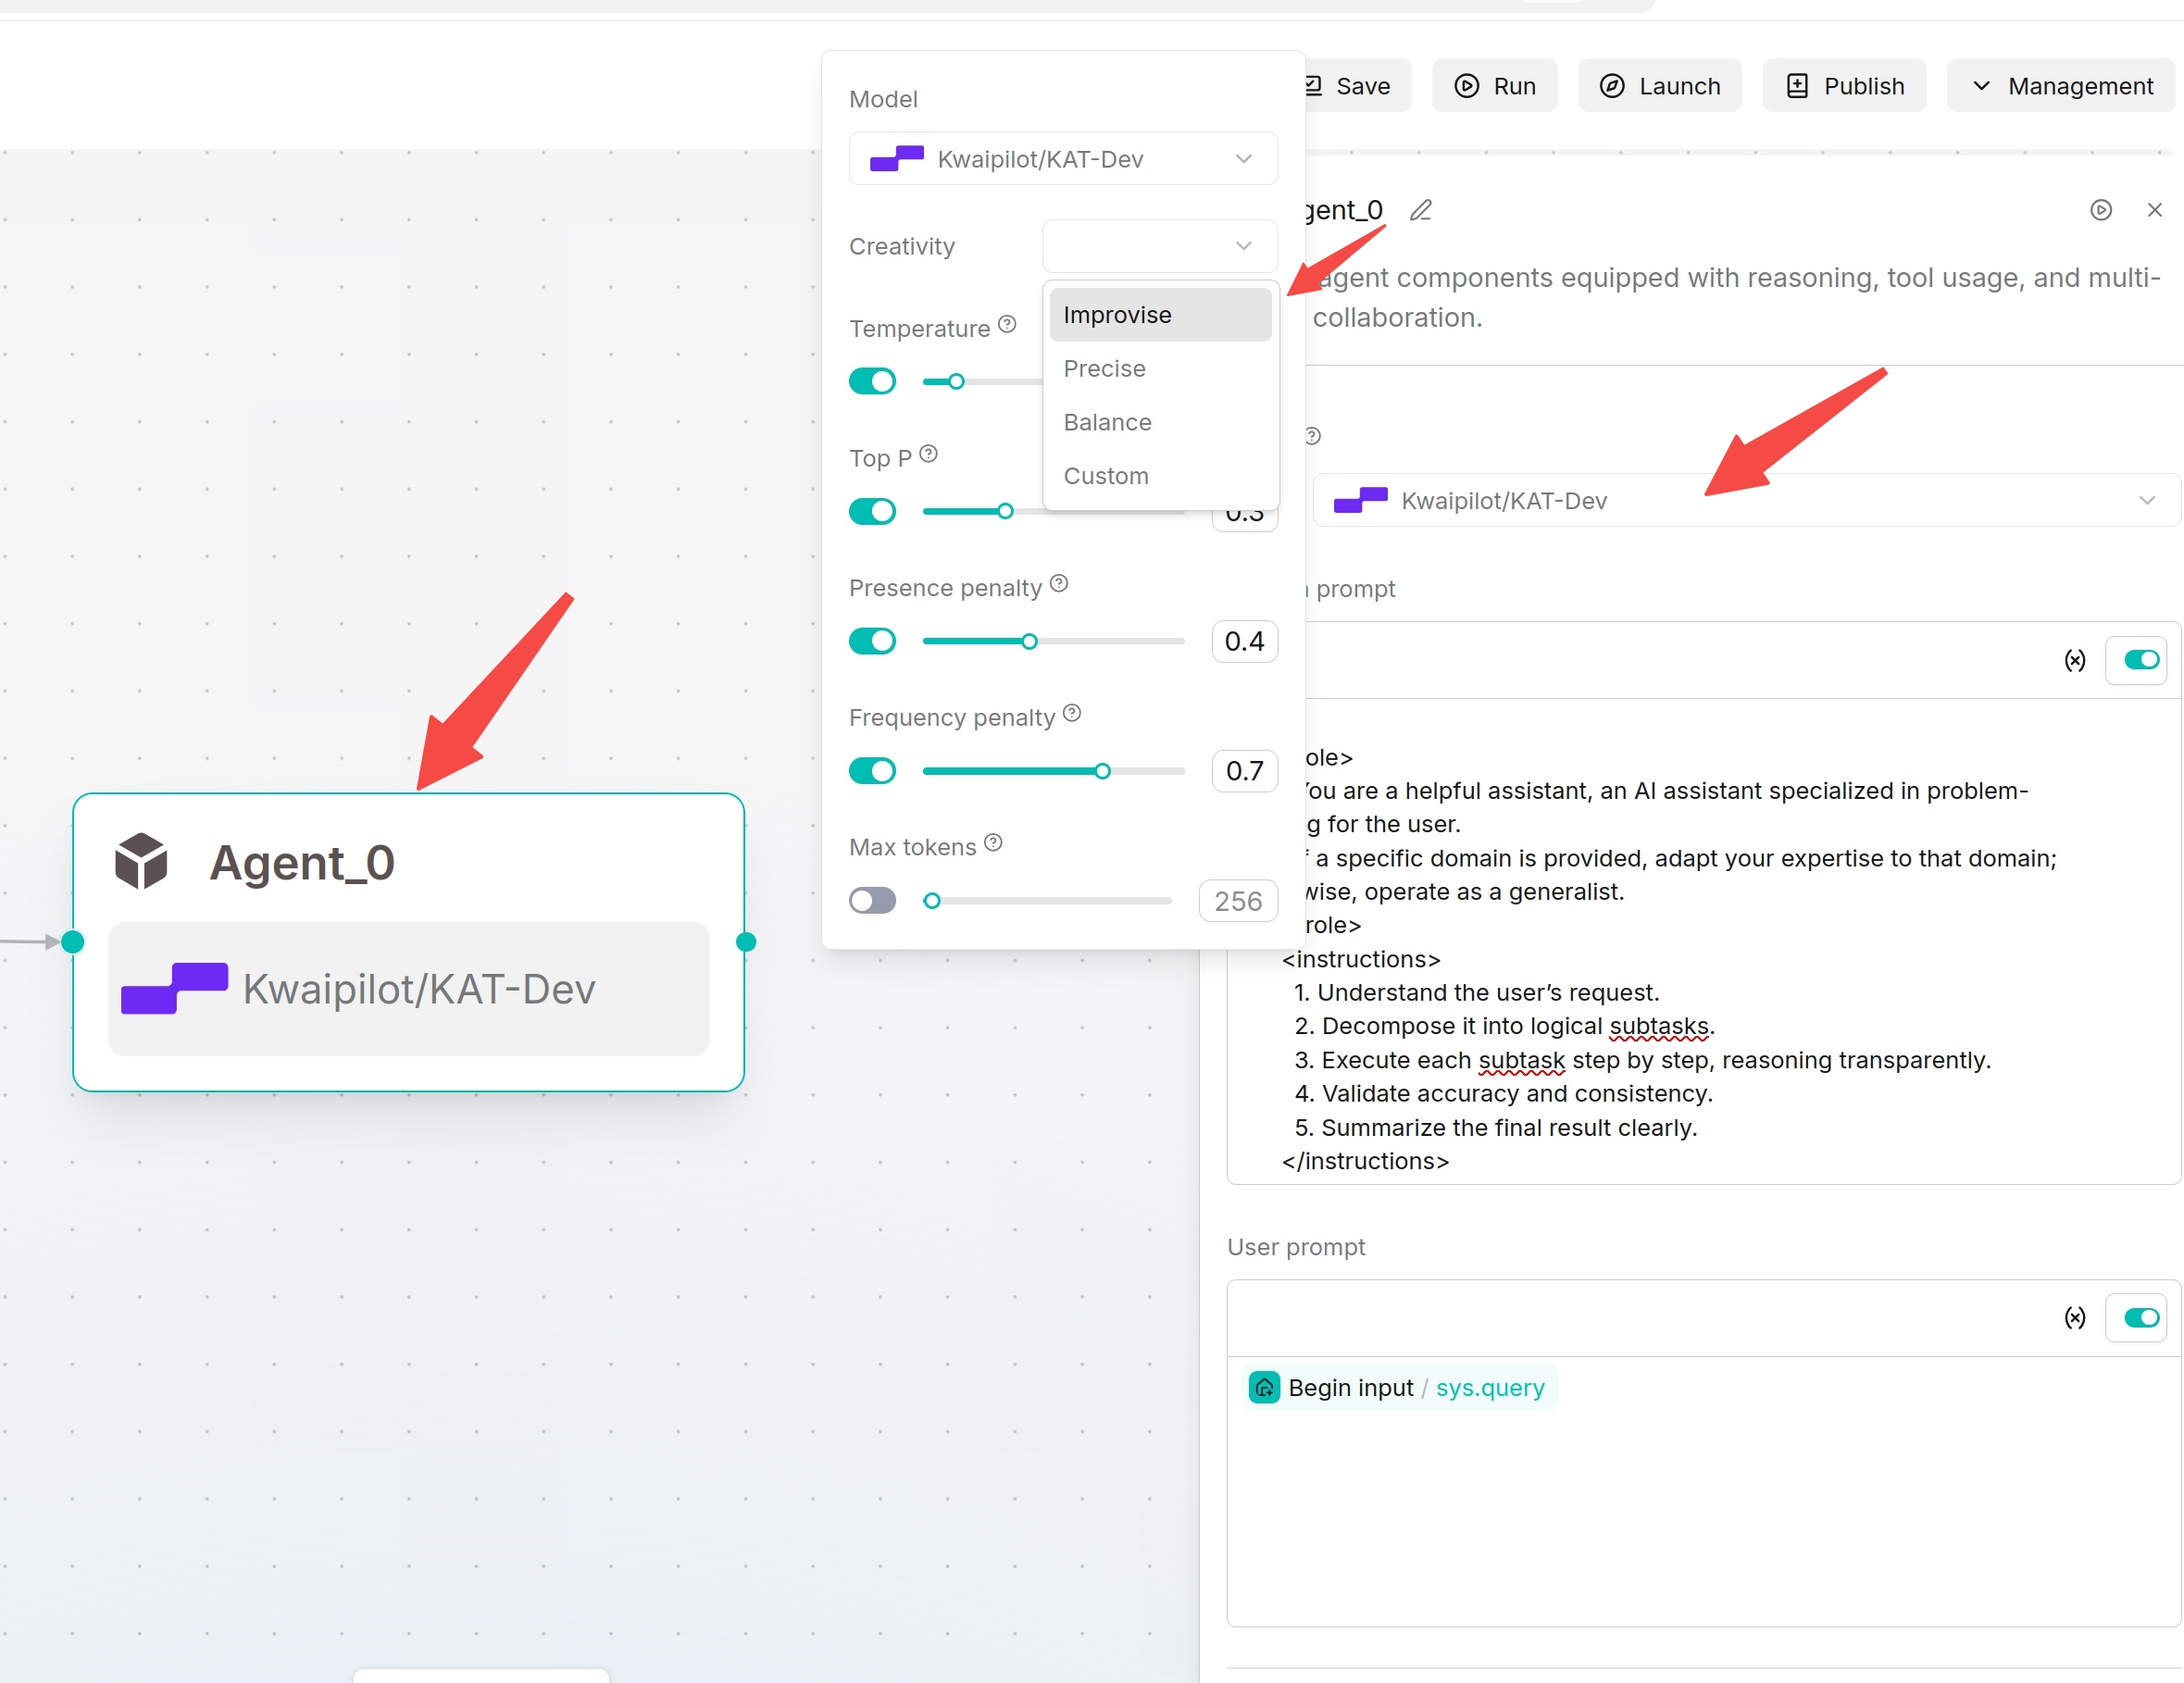
### Basic Configuration Steps
|
||||
1. Click the Agent component to open the right configuration panel.
|
||||
2. Select a chat model in Model.
|
||||
3. Adjust Creativity or keep Precise by default.
|
||||
4. Define role, constraints and output format in System prompt.
|
||||
5. Write task instructions in User prompt and insert variables by typing `/`.
|
||||
6. Add Tools or sub-Agents if retrieval, SQL, HTTP, MCP or nested agents are required.
|
||||
7. Set output variable name.
|
||||
2. Select a chat model in **Model**.
|
||||
3. Set **Creativity** as needed, or keep **Precise**.
|
||||
4. Describe the role, constraints, and output format in **System prompt**.
|
||||
5. Write the task in **User prompt**, and insert variables by typing `/`.
|
||||
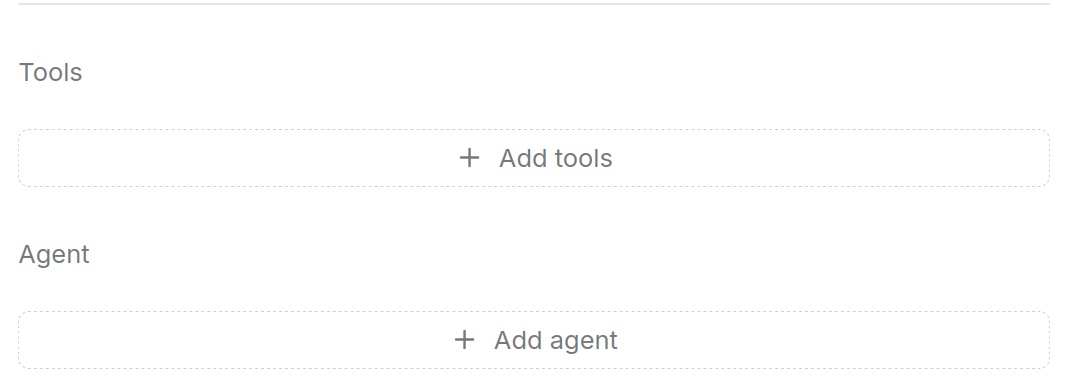
6. If retrieval, SQL, HTTP, MCP, or sub-Agents are required, add **Tools** or **Agent**.
|
||||
7. Set the output variable name.
|
||||
8. Save and run tests.
|
||||
|
||||
### Prompt Configuration
|
||||
- **System Prompt**: Define model role and behavior boundaries.
|
||||
- **User Prompt**: Define current task and input data.
|
||||
|
||||
If the Agent component follows a Retrieval component, usually reference `formalized_content` in User Prompt to make the model answer based on retrieved documents.
|
||||
|
||||
Example:
|
||||
> Please answer `/Retrieval_0.formalized_content` according to `/sys.query`. If retrieval results are insufficient, clearly state that confirmation cannot be obtained from the knowledge base and do not fabricate answers.
|
||||
|
||||
### Tools & Sub-Agents
|
||||
When tools or sub-Agents are attached under an Agent component, the current Agent acts as a planner to judge when to invoke these capabilities. Tools include Retrieval, Execute SQL, HTTP Request, MCP Server and other available components. Sub-Agents split complex tasks for multi-role collaboration.
|
||||
|
||||
It is recommended to specify trigger conditions in system prompts:
|
||||
> Retrieve knowledge base when questions involve product documents; call HTTP interface when querying order status.
|
||||
|
||||
:::tip NOTE
|
||||
Tool calling, sub-agents, reflection rounds and larger message window size will increase response latency. Prioritize simple pipelines for regular Q&A; enable planning logic only when necessary.
|
||||
:::
|
||||
### Advanced Settings
|
||||
Advanced settings control context management, exception handling and output format during runtime. Keep default values in most cases; adjust when optimizing effect or adapting to business requirements.
|
||||
|
||||
| Parameter | Description | Suggestion |
|
||||
| ---- | ---- | ---- |
|
||||
| Message window size | Number of historical messages retained during LLM reasoning. Larger windows provide more context but consume more tokens. | Keep default; increase for multi-turn dialogue, decrease for single-turn tasks |
|
||||
| Citation | Whether to return source citations in answers when using knowledge bases. | Enable for knowledge Q&A scenarios |
|
||||
| Max retries | Maximum retry attempts after Agent execution failure. | Keep default; increase under unstable network |
|
||||
| Delay after error | Waiting time (seconds) before each retry to avoid continuous failed requests. | Keep default |
|
||||
| Exception handling method | Execution policy when exceptions occur. | Adjust based on business requirements |
|
||||
|
||||
### Output Configuration
|
||||
Two output types are supported:
|
||||
1. **content**: Default natural language text returned by Agent
|
||||
2. **structured**: Structured data output. After enabling Structured output, define the format with JSON Schema to standardize returned fields for Code, HTTP Request, SQL and conditional judgment nodes.
|
||||
|
||||
|
||||
|
||||
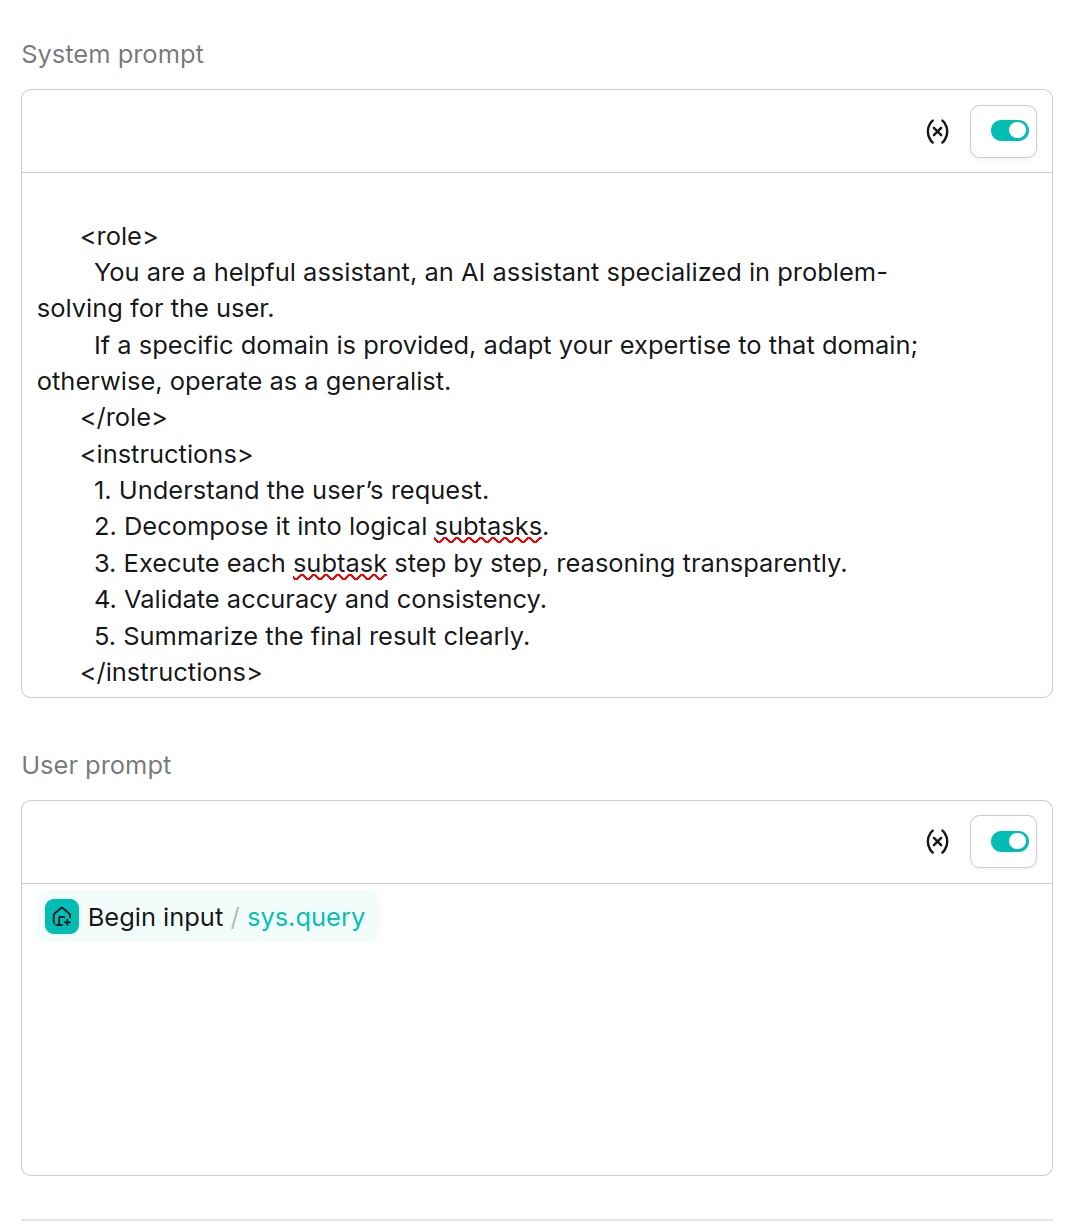
### Prompt Configuration
|
||||
|
||||
The system prompt is used to define the model role and behavior boundaries. The user prompt is used to define the current task and input data.
|
||||
|
||||
If the Agent component follows a knowledge retrieval component, you usually need to reference `formalized_content` in the user prompt so that the model answers based on the retrieval results.
|
||||
|
||||
Example:
|
||||
|
||||
> Please answer `/sys.query` based on `/Retrieval_0.formalized_content`. If the retrieval results are insufficient, clearly state that confirmation cannot be obtained from the knowledge base, and do not fabricate answers.
|
||||
|
||||
|
||||
|
||||
### Tools and Sub-Agents
|
||||
|
||||
When tools or sub-agents are added under an Agent component, the current Agent acts as a planner and determines when to call these capabilities. Tools can be knowledge retrieval (`Retrieval`), Execute SQL, HTTP Request, MCP Server, or other available components. Sub-agents are used to split complex tasks and assign them to different roles for collaboration.
|
||||
|
||||
It is recommended to describe tool trigger conditions in the system prompt. For example: "Call knowledge base retrieval first when product documents are involved" or "Call the HTTP API when order status is involved".
|
||||
|
||||
:::tip NOTE
|
||||
|
||||
Tool calling, sub-agents, reflection rounds, and a larger message window size all increase response time. For regular Q&A, prefer a simple workflow. Enable tools and multi-agent planning only when planning is truly required.
|
||||
|
||||
:::
|
||||
|
||||
|
||||
|
||||
### Advanced Settings
|
||||
|
||||
Advanced settings are used to control context management, exception handling, output format, and other runtime behavior for the Agent node. In most cases, keep the default configuration. When you need to optimize Agent execution results or adapt to a specific business scenario, adjust these settings based on actual requirements.
|
||||
|
||||
Parameter description:
|
||||
|
||||
| Parameter | Description | Suggestion |
|
||||
| --- | --- | --- |
|
||||
| Message window size | Sets the number of historical messages retained by the Agent during reasoning. A larger window provides more context, but increases token consumption. | Keep the default value in general. Increase it for multi-turn conversations, and decrease it for single-turn tasks. |
|
||||
| Citation | Specifies whether to return citation information in answers. When the Agent uses knowledge bases or retrieval results to generate answers, source citations can be enabled to make it easier to view the basis for the answer. | Recommended for knowledge base Q&A scenarios. |
|
||||
| Max retries | The maximum number of retries after Agent execution fails. When model calls or tool calls fail, the system automatically retries. | Keep the default value. Increase it when the network is unstable. |
|
||||
| Delay after error | The waiting time, in seconds, before each retry. This helps avoid another failure caused by continuous requests within a short time. | Keep the default value in general. |
|
||||
| Exception handling method | Sets how the Agent handles exceptions during execution. Different options determine whether execution continues, exception information is returned, or another handling policy is used after an error occurs. | Select based on business requirements. Keep the default value if there are no special requirements. |
|
||||
|
||||
`Output` is used to configure the output content of the Agent node.
|
||||
|
||||
| Configuration item | Description |
|
||||
| --- | --- |
|
||||
| `content` | The natural language text returned by the Agent. This is the default output. |
|
||||
| `structured` | Structured data returned by the Agent. After structured output is enabled, results can be output according to a predefined JSON Schema, making it easier for subsequent nodes to read and process. |
|
||||
|
||||
For structured output, after enabling **Structured output**, click **Configuration** to configure the output structure. Users can define the returned data format according to JSON Schema, such as specifying field names, data types, and required fields. The Agent tries to return results according to the configured structure, making it easier to pass data to nodes such as Code, HTTP Request, SQL, and condition judgment for automated processing.
|
||||
|
||||
|
||||
|
||||
## Knowledge Retrieval Component
|
||||
|
||||
## Retrieval Component
|
||||
The Retrieval component fetches relevant content from specified knowledge bases or memory. It can be used as an independent workflow component or as a tool inside an Agent component.
|
||||
The knowledge retrieval component is used to retrieve relevant content from specified knowledge bases or memories. It can be used as a regular workflow component, or as a tool for the Agent component.
|
||||
|
||||
Configuration Steps:
|
||||
1. Click the Retrieval component.
|
||||
2. Select query source for Query variable (commonly `sys.query`).
|
||||
3. Select one or more knowledge bases or Memory as retrieval source.
|
||||
4. Adjust similarity threshold, keyword similarity weight and Top N.
|
||||
5. Enable Cross-language search for multilingual scenarios.
|
||||
6. Enable Use knowledge graph for multi-hop graph Q&A.
|
||||
7. Run and test retrieval results.
|
||||
Configuration steps:
|
||||
|
||||
Parameter Explanation:
|
||||
- **Similarity threshold**: Filter low-relevance chunks. Higher values enforce stricter matching but may omit useful content.
|
||||
- **Keyword similarity weight**: Control vector weight in comprehensive similarity. All knowledge bases used together must share the same embedding model.
|
||||
- **Top N**: Number of chunks passed to downstream components. Too few leads to insufficient information; too many increases latency and token usage.
|
||||
- **Rerank model**: Improve sorting of retrieved results, adds latency. Disable for latency-sensitive Agents.
|
||||
|
||||
Initial Configuration Reference:
|
||||
| Parameter | Suggested Value | Scenario | Description |
|
||||
| ---- | ---- | ---- | ---- |
|
||||
| Top N | 3~5 | FAQ, short knowledge entries | Faster response for clear answers |
|
||||
| Top N | 5~10 | Product documentation, help center | Default recommended range |
|
||||
| Top N | 10~20 | Legal contracts, long document analysis | More context, higher token consumption |
|
||||
| Similarity threshold | 0.2 | Loose recall | Questions with diverse expression patterns |
|
||||
| Similarity threshold | 0.5 | General Q&A | Default starting value |
|
||||
| Similarity threshold | 0.8 | Strict precise matching | Scenarios requiring exact terminology matching |
|
||||
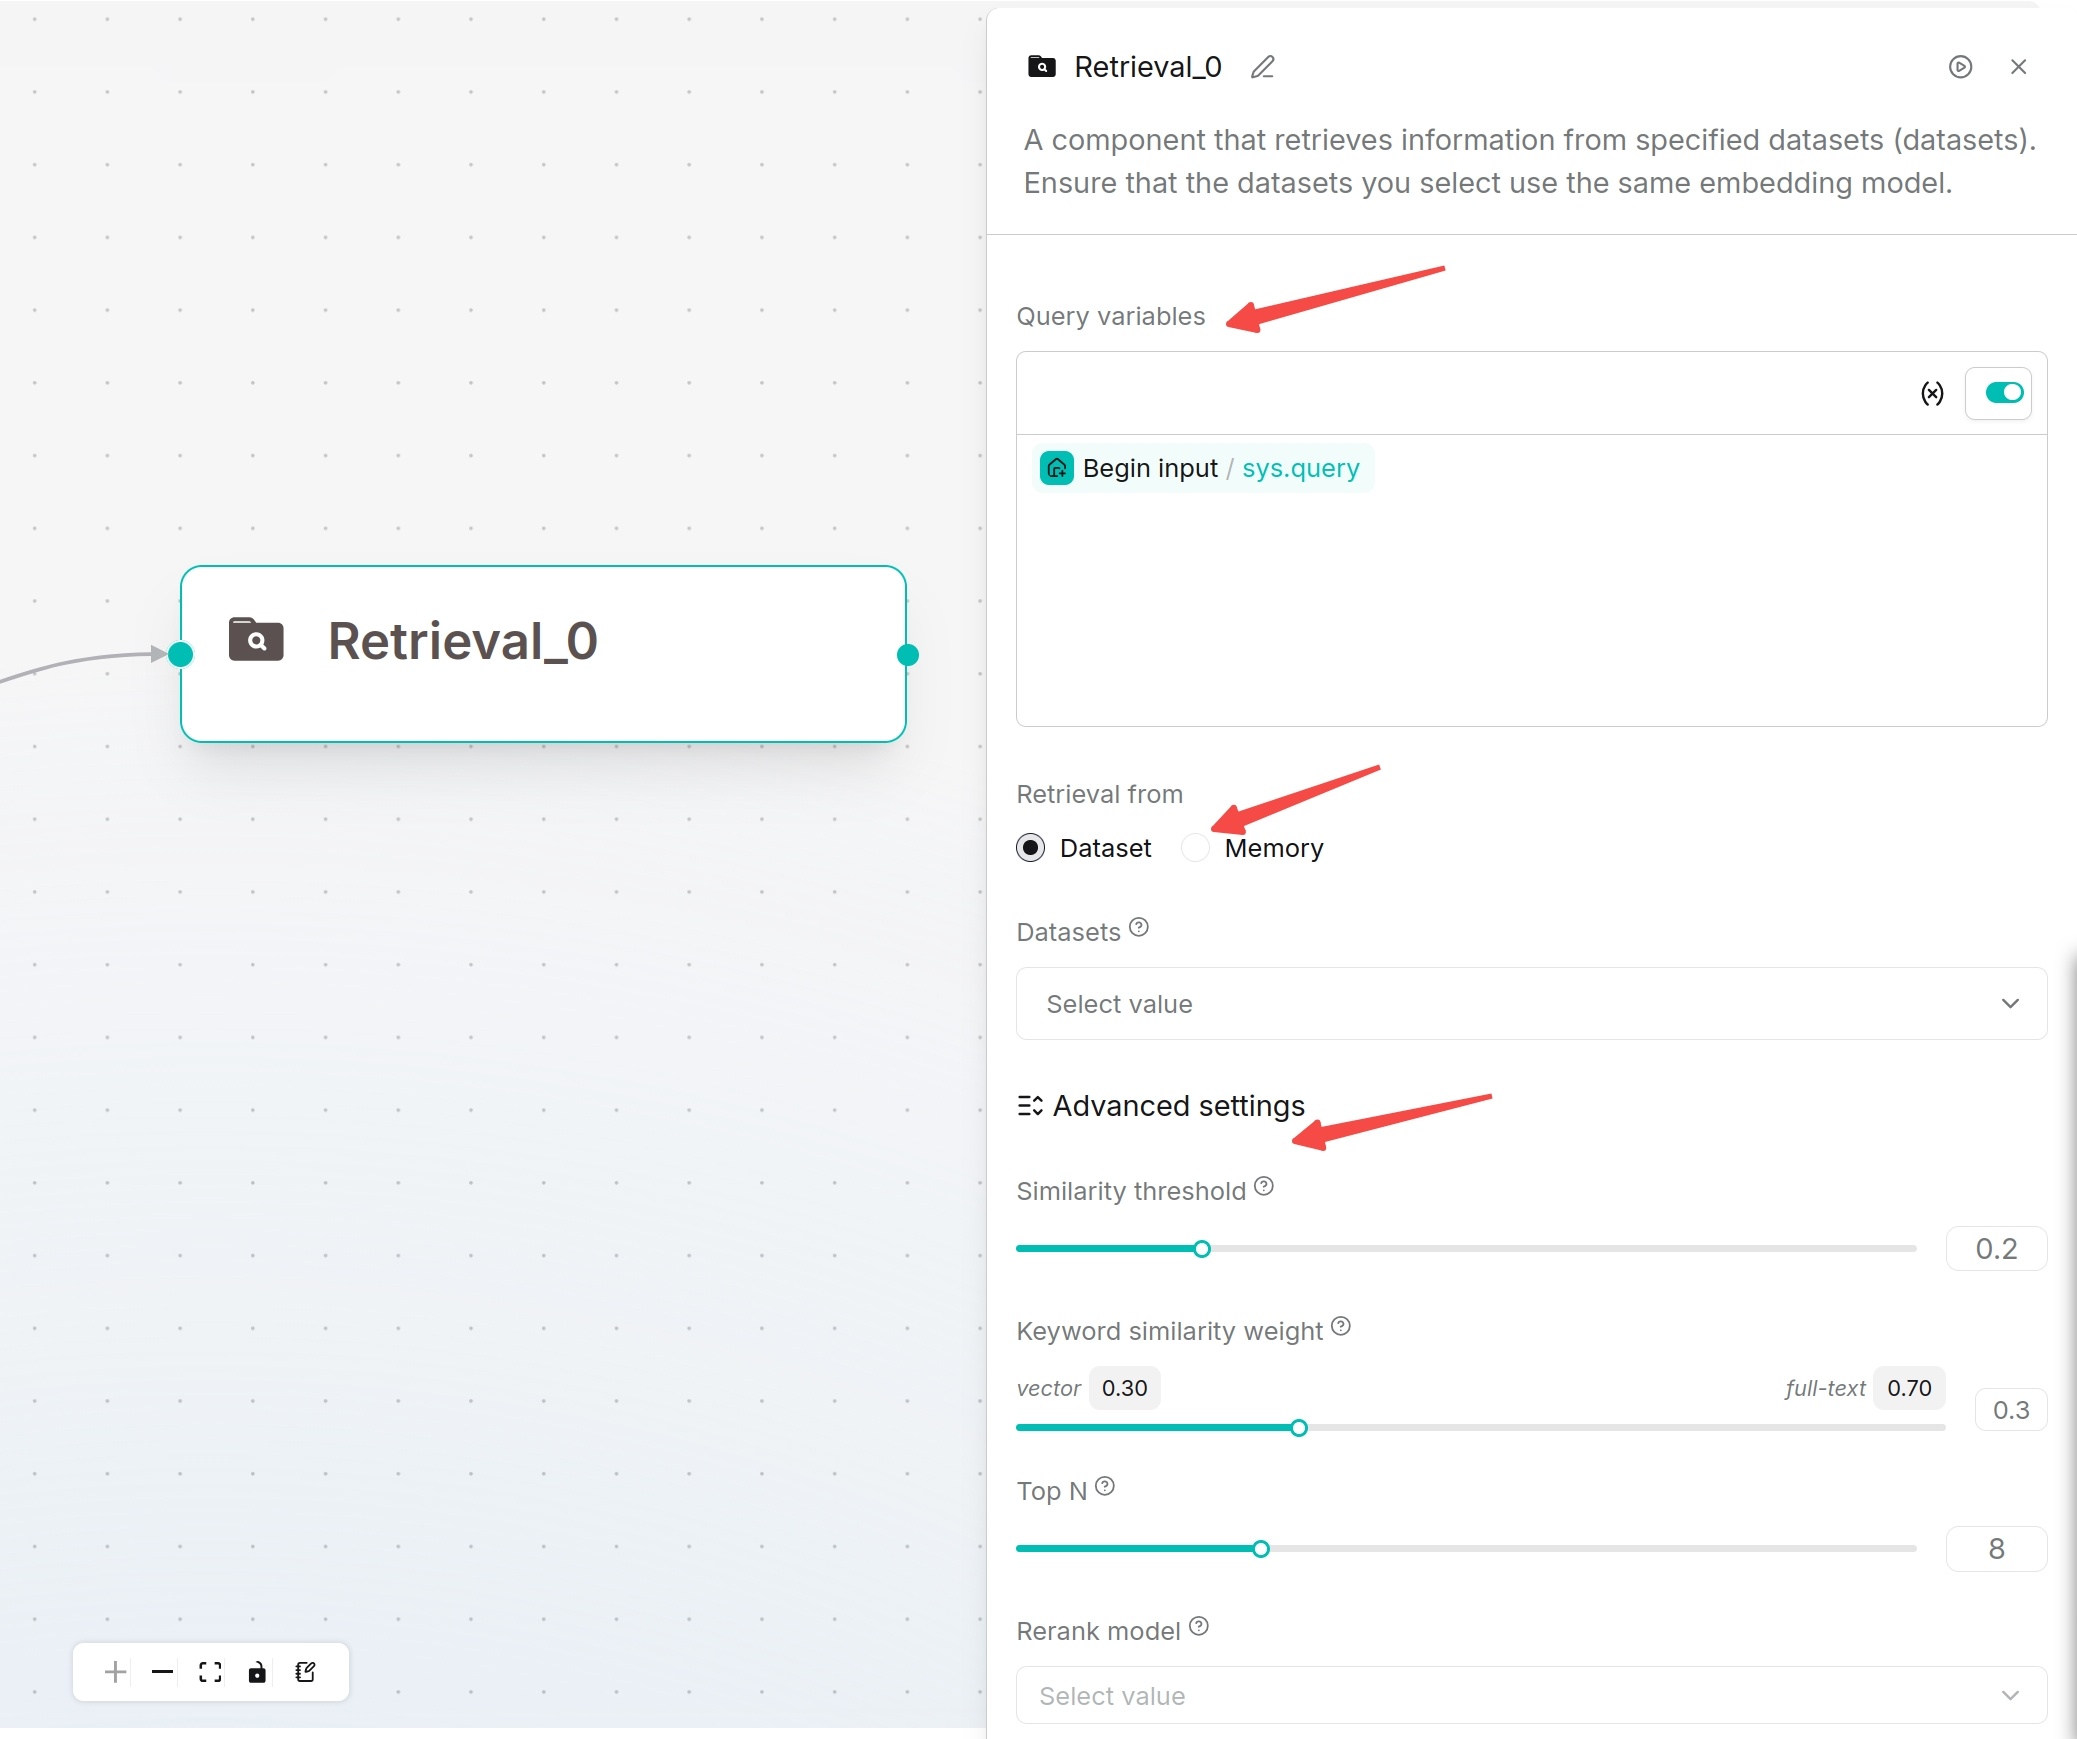
1. Click the knowledge retrieval component.
|
||||
2. In **Query variable**, select the query source. `sys.query` is commonly used.
|
||||
3. In **Retrieval source**, select one or more knowledge bases, or select **Memory**.
|
||||
4. Adjust **Similarity threshold**, **Keyword similarity weight**, and **Top N** as needed.
|
||||
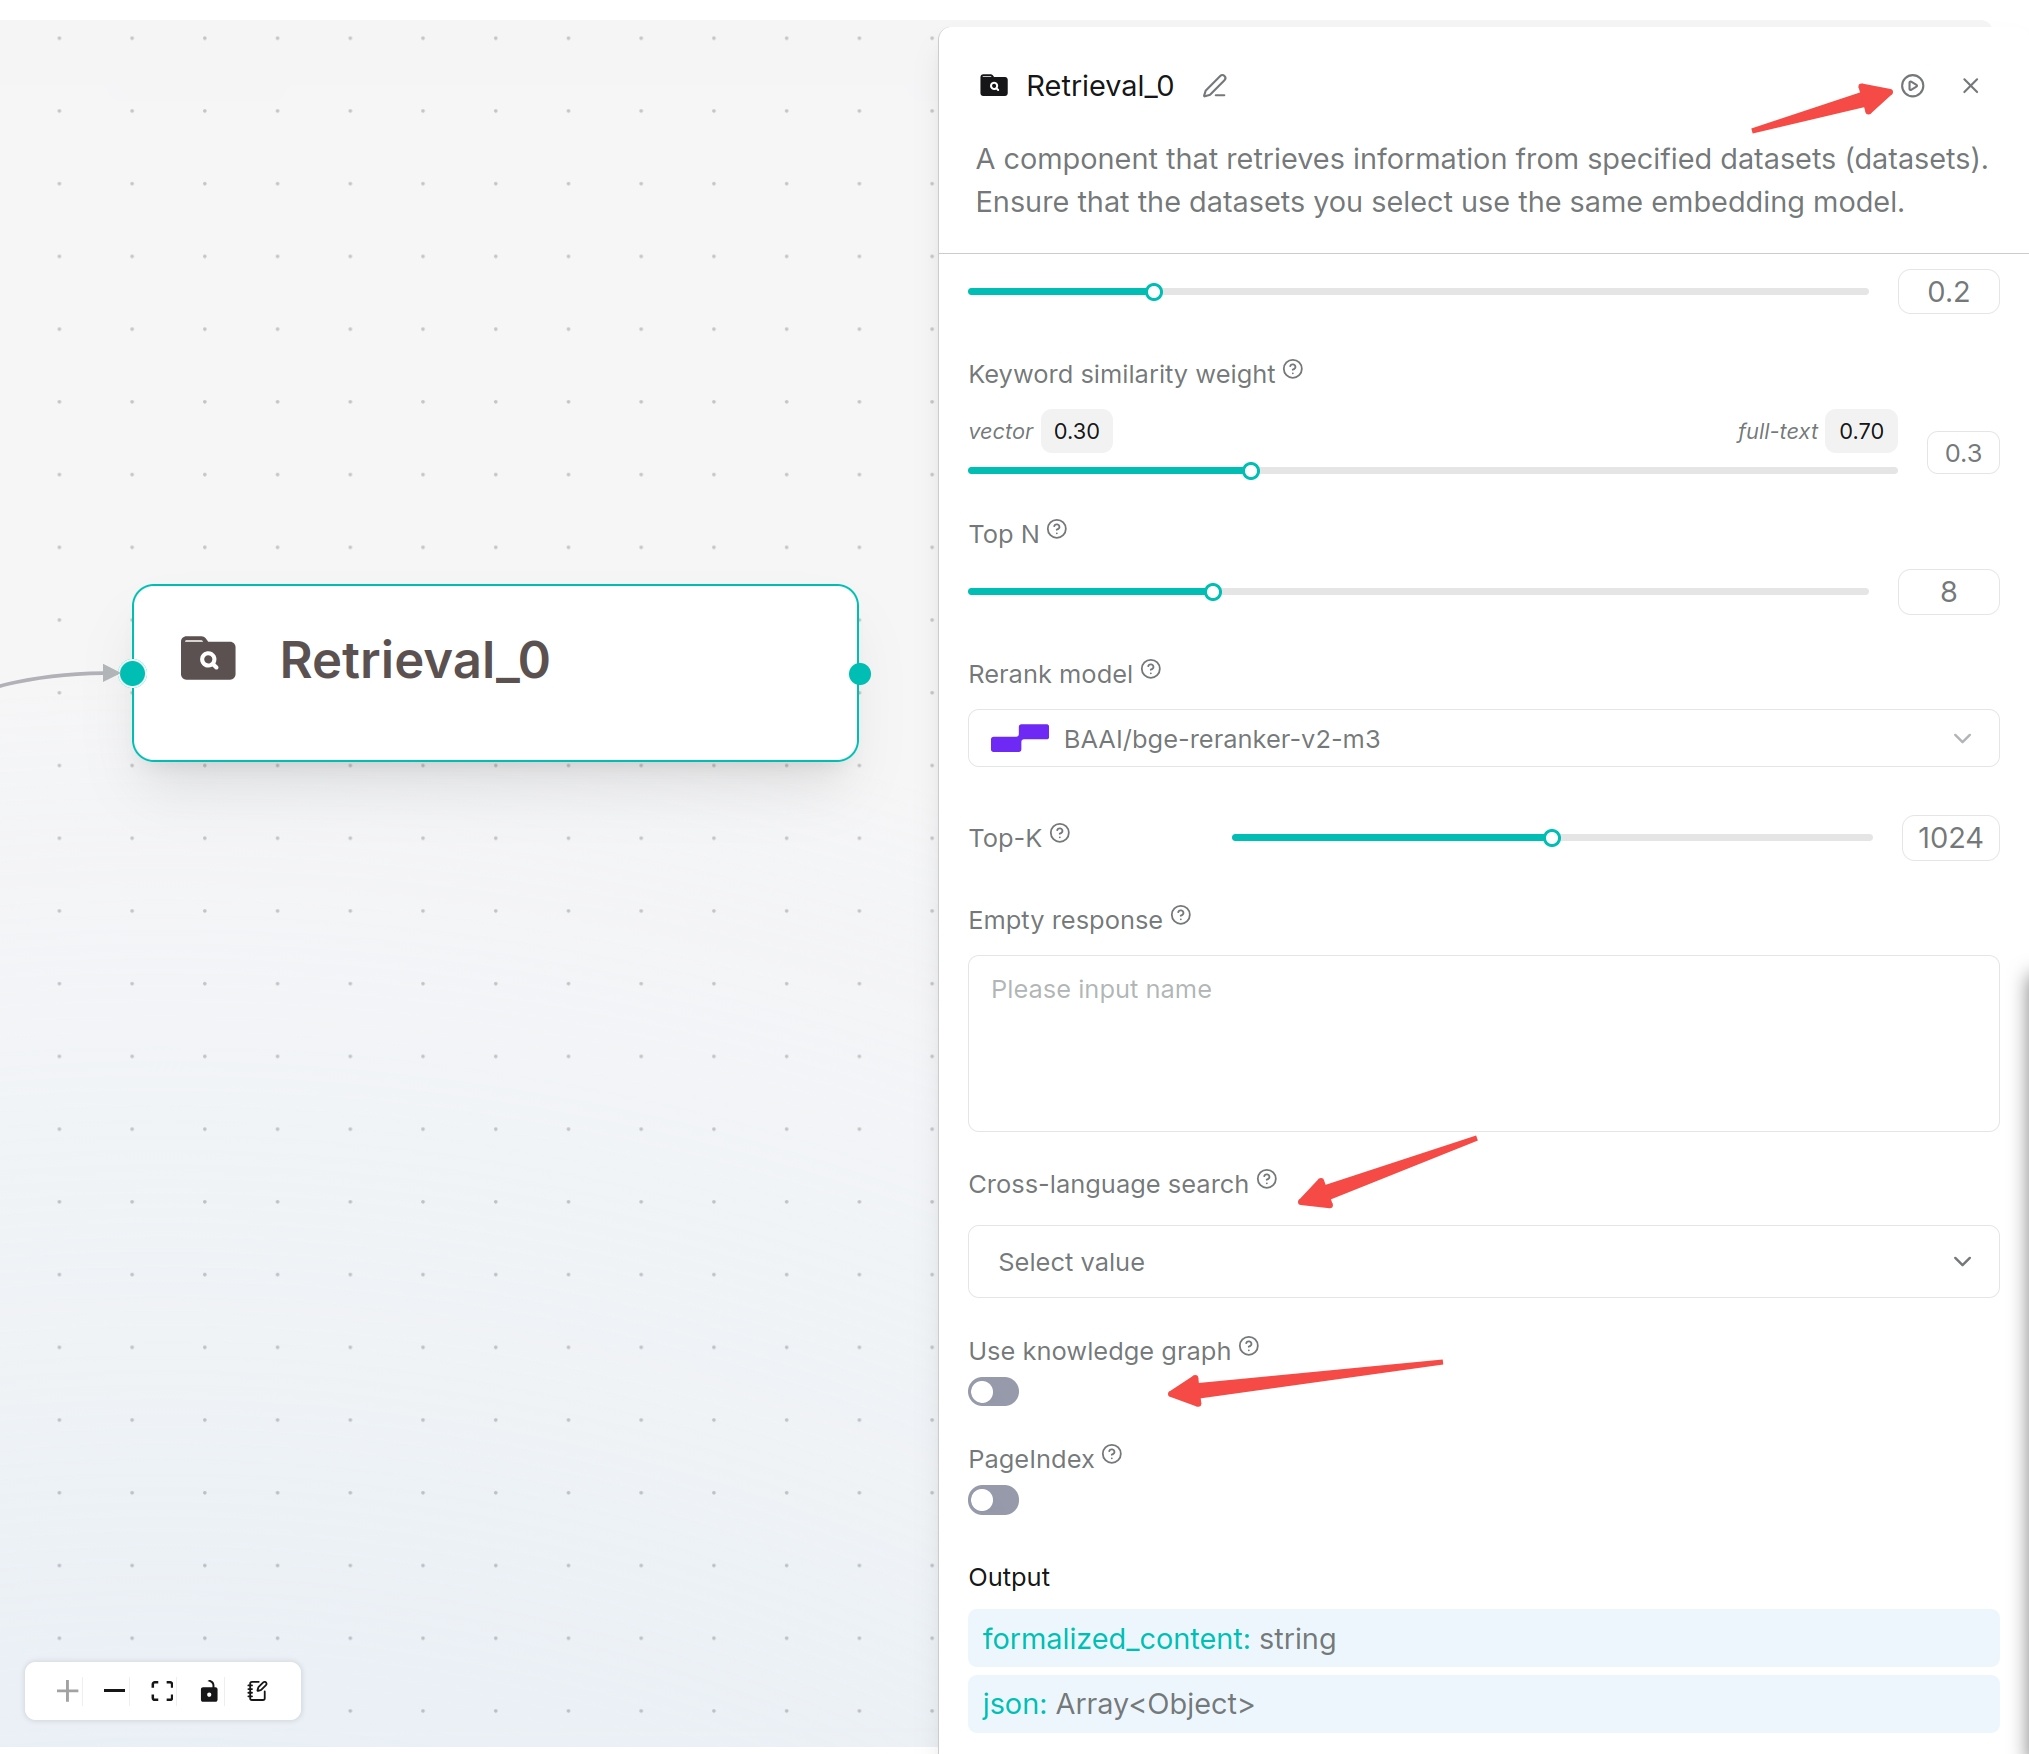
5. For cross-language retrieval, select a **Cross-language search** language.
|
||||
6. For graph multi-hop Q&A, enable **Use knowledge graph**.
|
||||
7. Click **Run** to test the retrieval results.
|
||||
|
||||
|
||||
|
||||
|
||||
|
||||
### Parameter Description
|
||||
|
||||
## Message Component
|
||||
The Message component outputs static or dynamic content to users, usually as the final component of a workflow. It supports fixed text and variable insertion. Multiple message entries can be configured; the system randomly selects one to send.
|
||||
**Similarity threshold** is used to filter low-relevance chunks. The higher the threshold, the stricter the returned content, but useful information may be missed.
|
||||
|
||||
When Begin uses Webhook mode with Final response as response method, the Message component can set HTTP status codes (200 ~ 399).
|
||||
**Keyword similarity weight** is used to control the weight of vector similarity in the overall similarity score. When retrieving from multiple knowledge bases together, make sure they use the same embedding model.
|
||||
|
||||
**Save to Memory**: Enable this option to store dialogue sessions into specified memory. Bind User ID to associate conversations with users; subsequent retrieval can query memory filtered by user ID.
|
||||
**Top N** specifies the number of chunks sent to subsequent components. Too few chunks may result in insufficient information, while too many chunks may increase response time and context pressure.
|
||||
|
||||
Applicable scenarios: Output final answers, branch hints, fallback replies or display intermediate processing results. Output content will be sent to dialogue windows, webhook responses or embedded pages.
|
||||
Enabling a **Rerank model** usually improves the sorting of knowledge retrieval results, but also adds model call latency. For Agents that are sensitive to speed, you can leave reranking disabled at first.
|
||||
|
||||
`Similarity threshold` is used to filter low-relevance chunks. The higher the threshold, the stricter the returned content, but useful information may be missed.
|
||||
|
||||
### Configuration Suggestions
|
||||
|
||||
The following values are only initial configuration references. Actual results are affected by the embedding model, document quality, chunking method, and business questions. Adjust them based on knowledge retrieval test results.
|
||||
|
||||
Retrieval parameters directly affect answer coverage, accuracy, and response time. You can start with the settings in the following table, and then optimize them based on real questions.
|
||||
|
||||
| Parameter | Suggested Value | Scenario | Description |
|
||||
| --- | --- | --- | --- |
|
||||
| Top N | 3-5 | FAQ and short knowledge entries | Faster responses for clear answers. |
|
||||
| Top N | 5-10 | Product documentation and help centers | Default recommended range. |
|
||||
| Top N | 10-20 | Legal contracts and long document analysis | More context with higher token consumption. |
|
||||
| Similarity threshold | 0.2 | Loose recall | Questions with diverse expressions. |
|
||||
| Similarity threshold | 0.5 | General Q&A | Default starting value. |
|
||||
| Similarity threshold | 0.8 | Strict precise matching | Scenarios that require exact terminology matching. |
|
||||
|
||||
## Reply Message Component
|
||||
|
||||
The message is used to output static or dynamic messages to users, and is usually used as the final component of a workflow. It can directly write fixed text, or insert upstream variables.
|
||||
|
||||
### Configuration Method
|
||||
|
||||
Write the output content in the message. Type `/` or click the variable button to insert component outputs.
|
||||
|
||||
If multiple messages are added, the system randomly selects one of them to send. When the `Begin` component selects `Webhook` and the response method is `Final response`, the reply message component can set an HTTP status code in the range of 200 to 399.
|
||||
|
||||
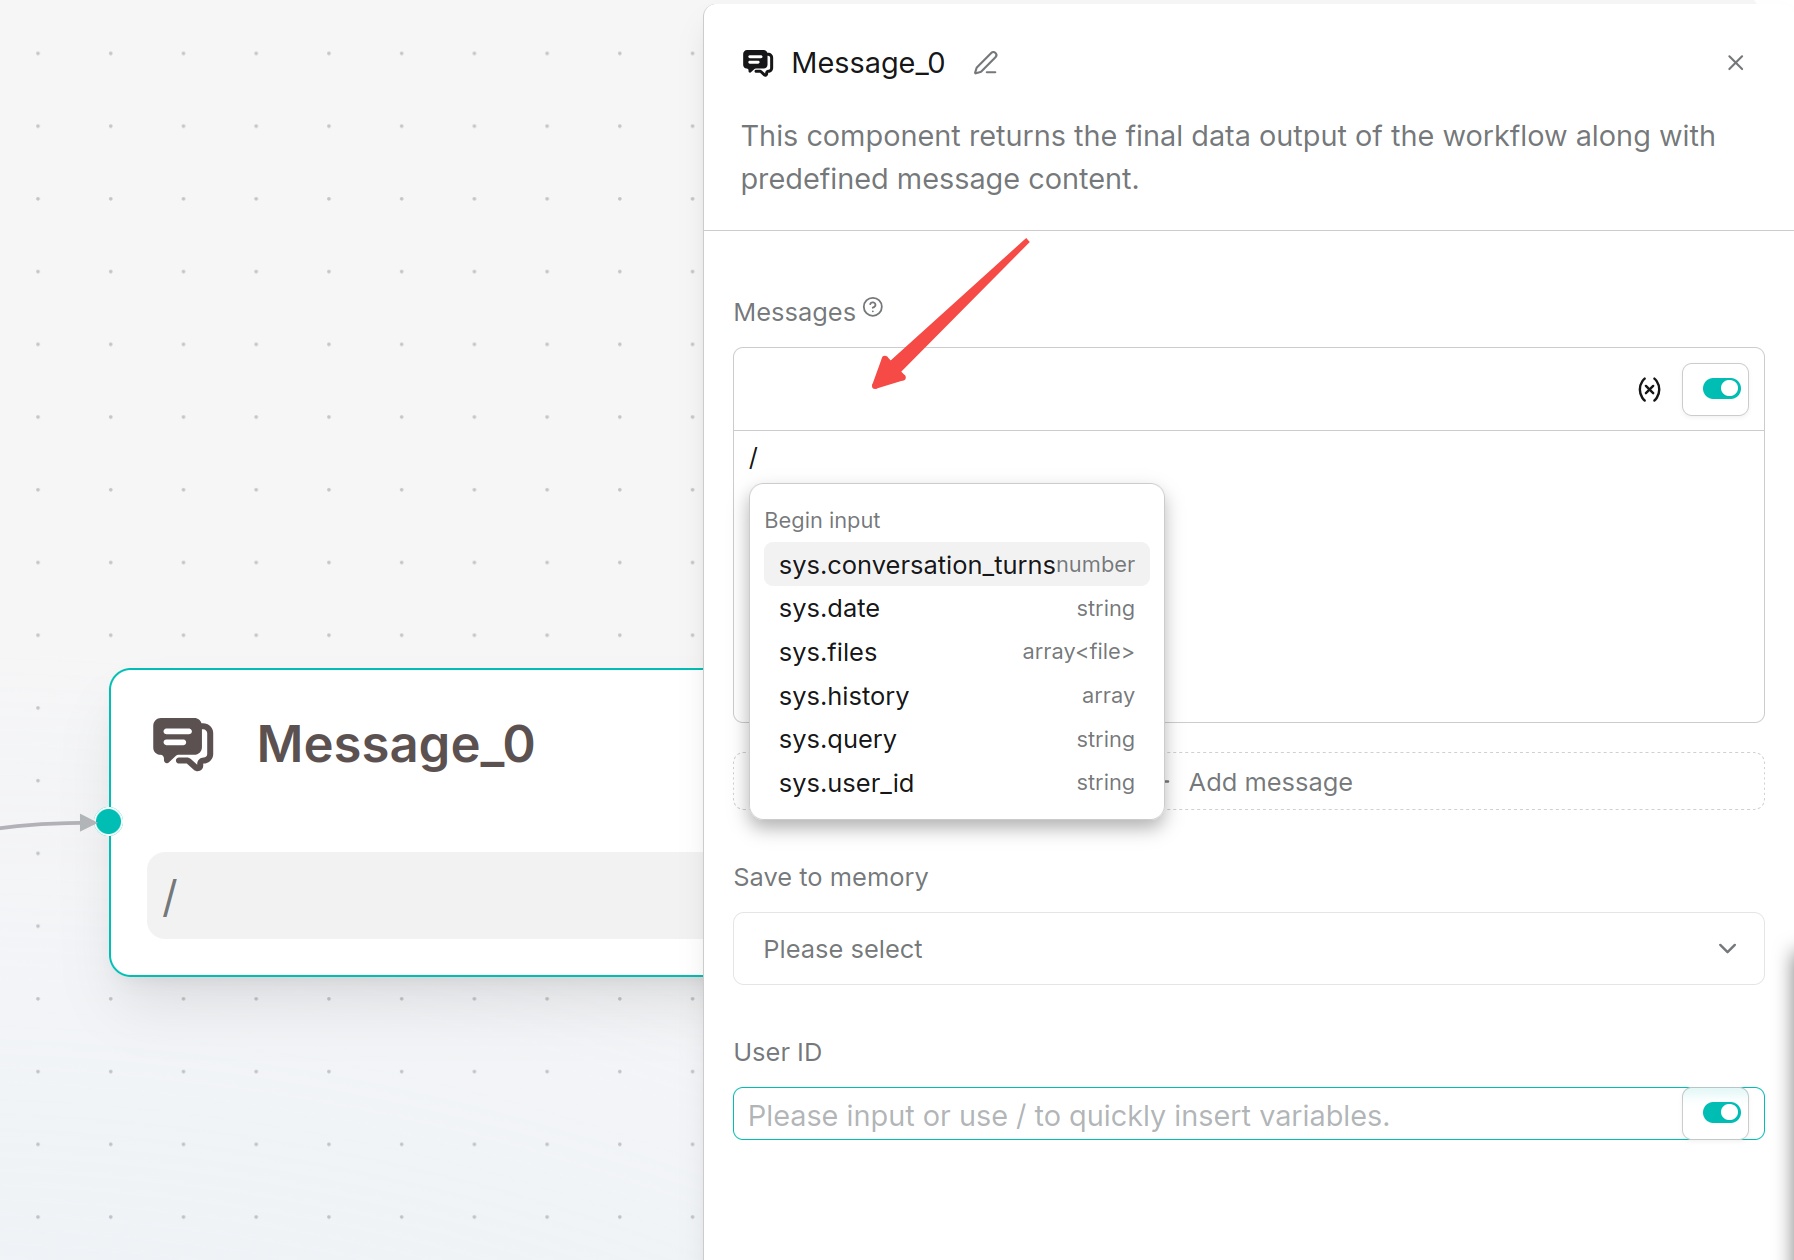
|
||||
|
||||
### Save to Memory
|
||||
|
||||
The reply message component can choose to save to memory, storing the conversation in the specified memory. After enabling **User ID**, conversations can be associated with user IDs, and subsequent knowledge retrieval can query related memories by user ID.
|
||||
|
||||
### Applicable Scenarios
|
||||
|
||||
This component is suitable for outputting final answers, branch hints, fallback replies, or displaying intermediate processing results to users.
|
||||
|
||||
### Output Result
|
||||
|
||||
The message outputs the configured text or variable content to the conversation window, webhook response, or embedded page.
|
||||
|
||||
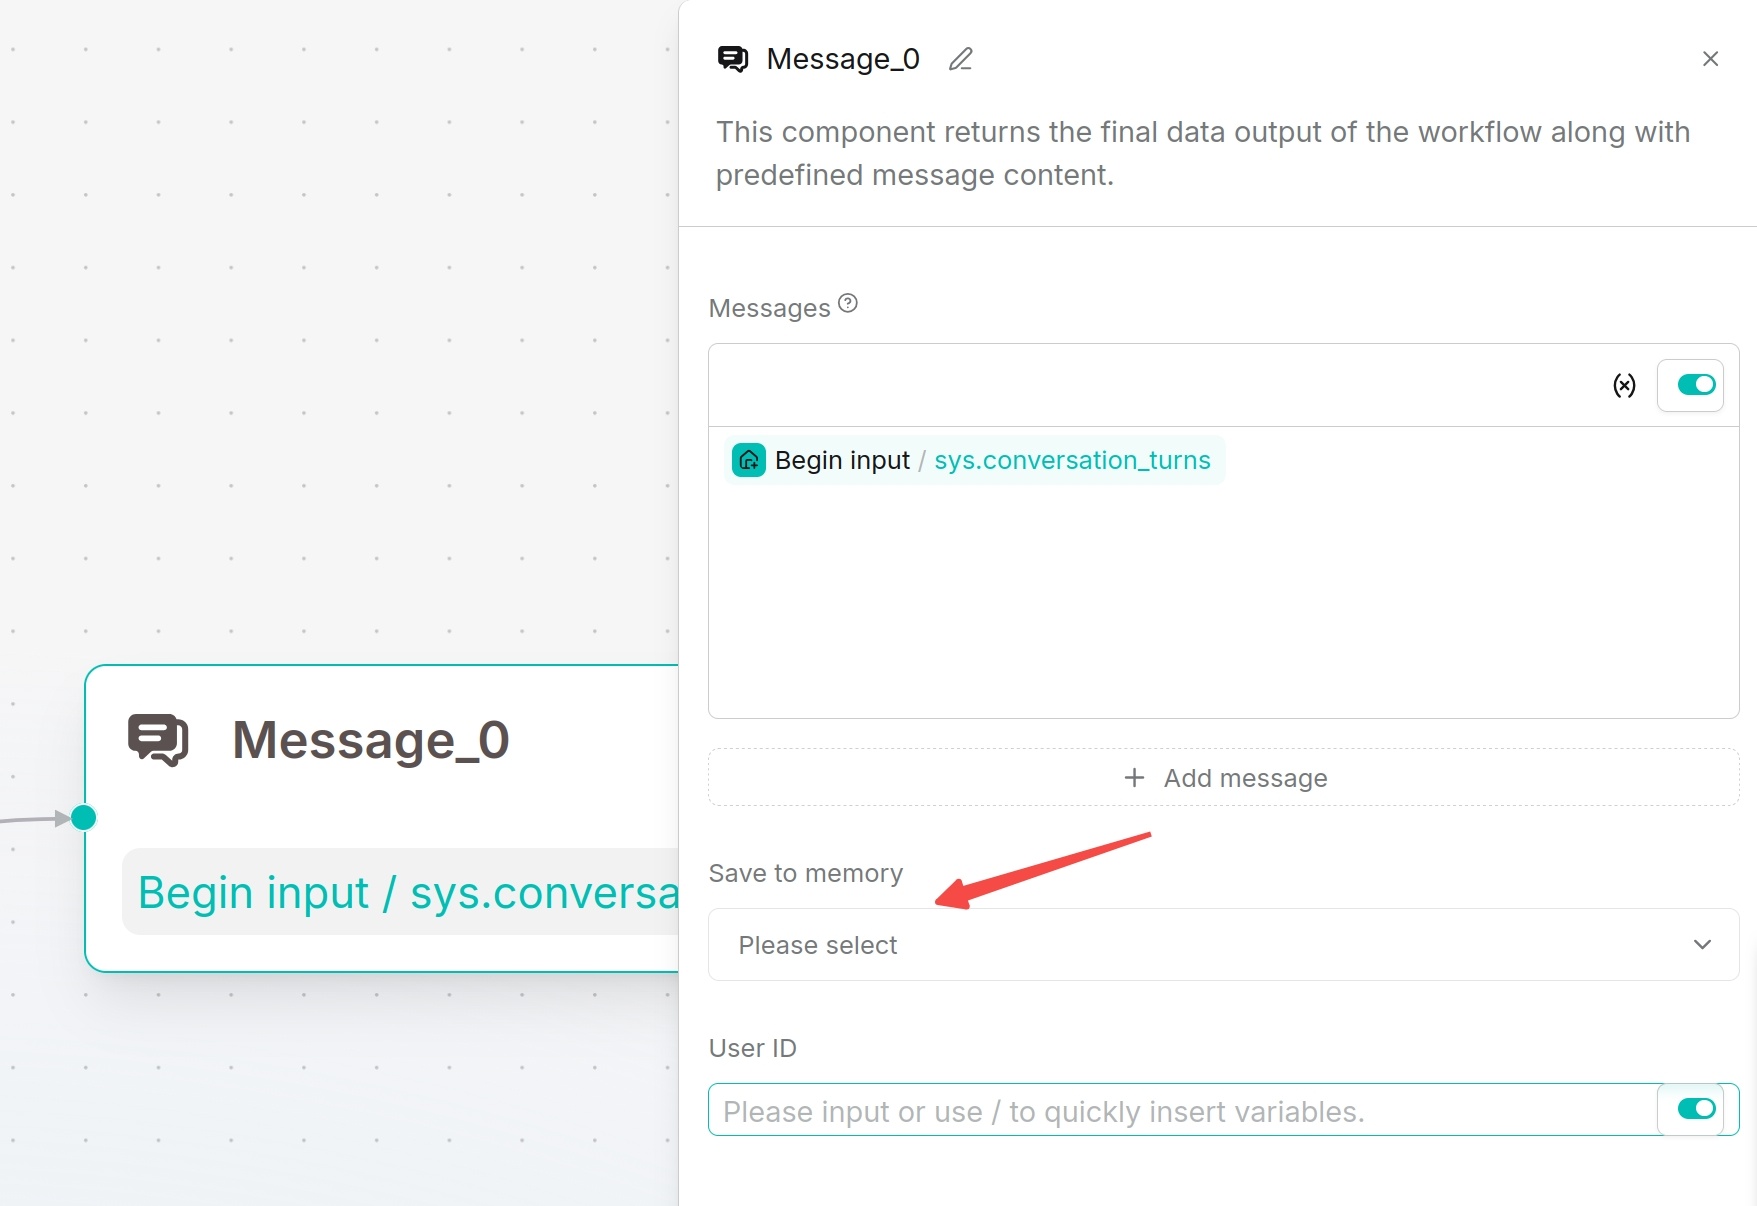
|
||||
|
||||
@@ -44,6 +44,8 @@ Configuration Steps:
|
||||
4. Select processing operation in Operations and fill corresponding configurations.
|
||||
5. Save and run tests.
|
||||
|
||||
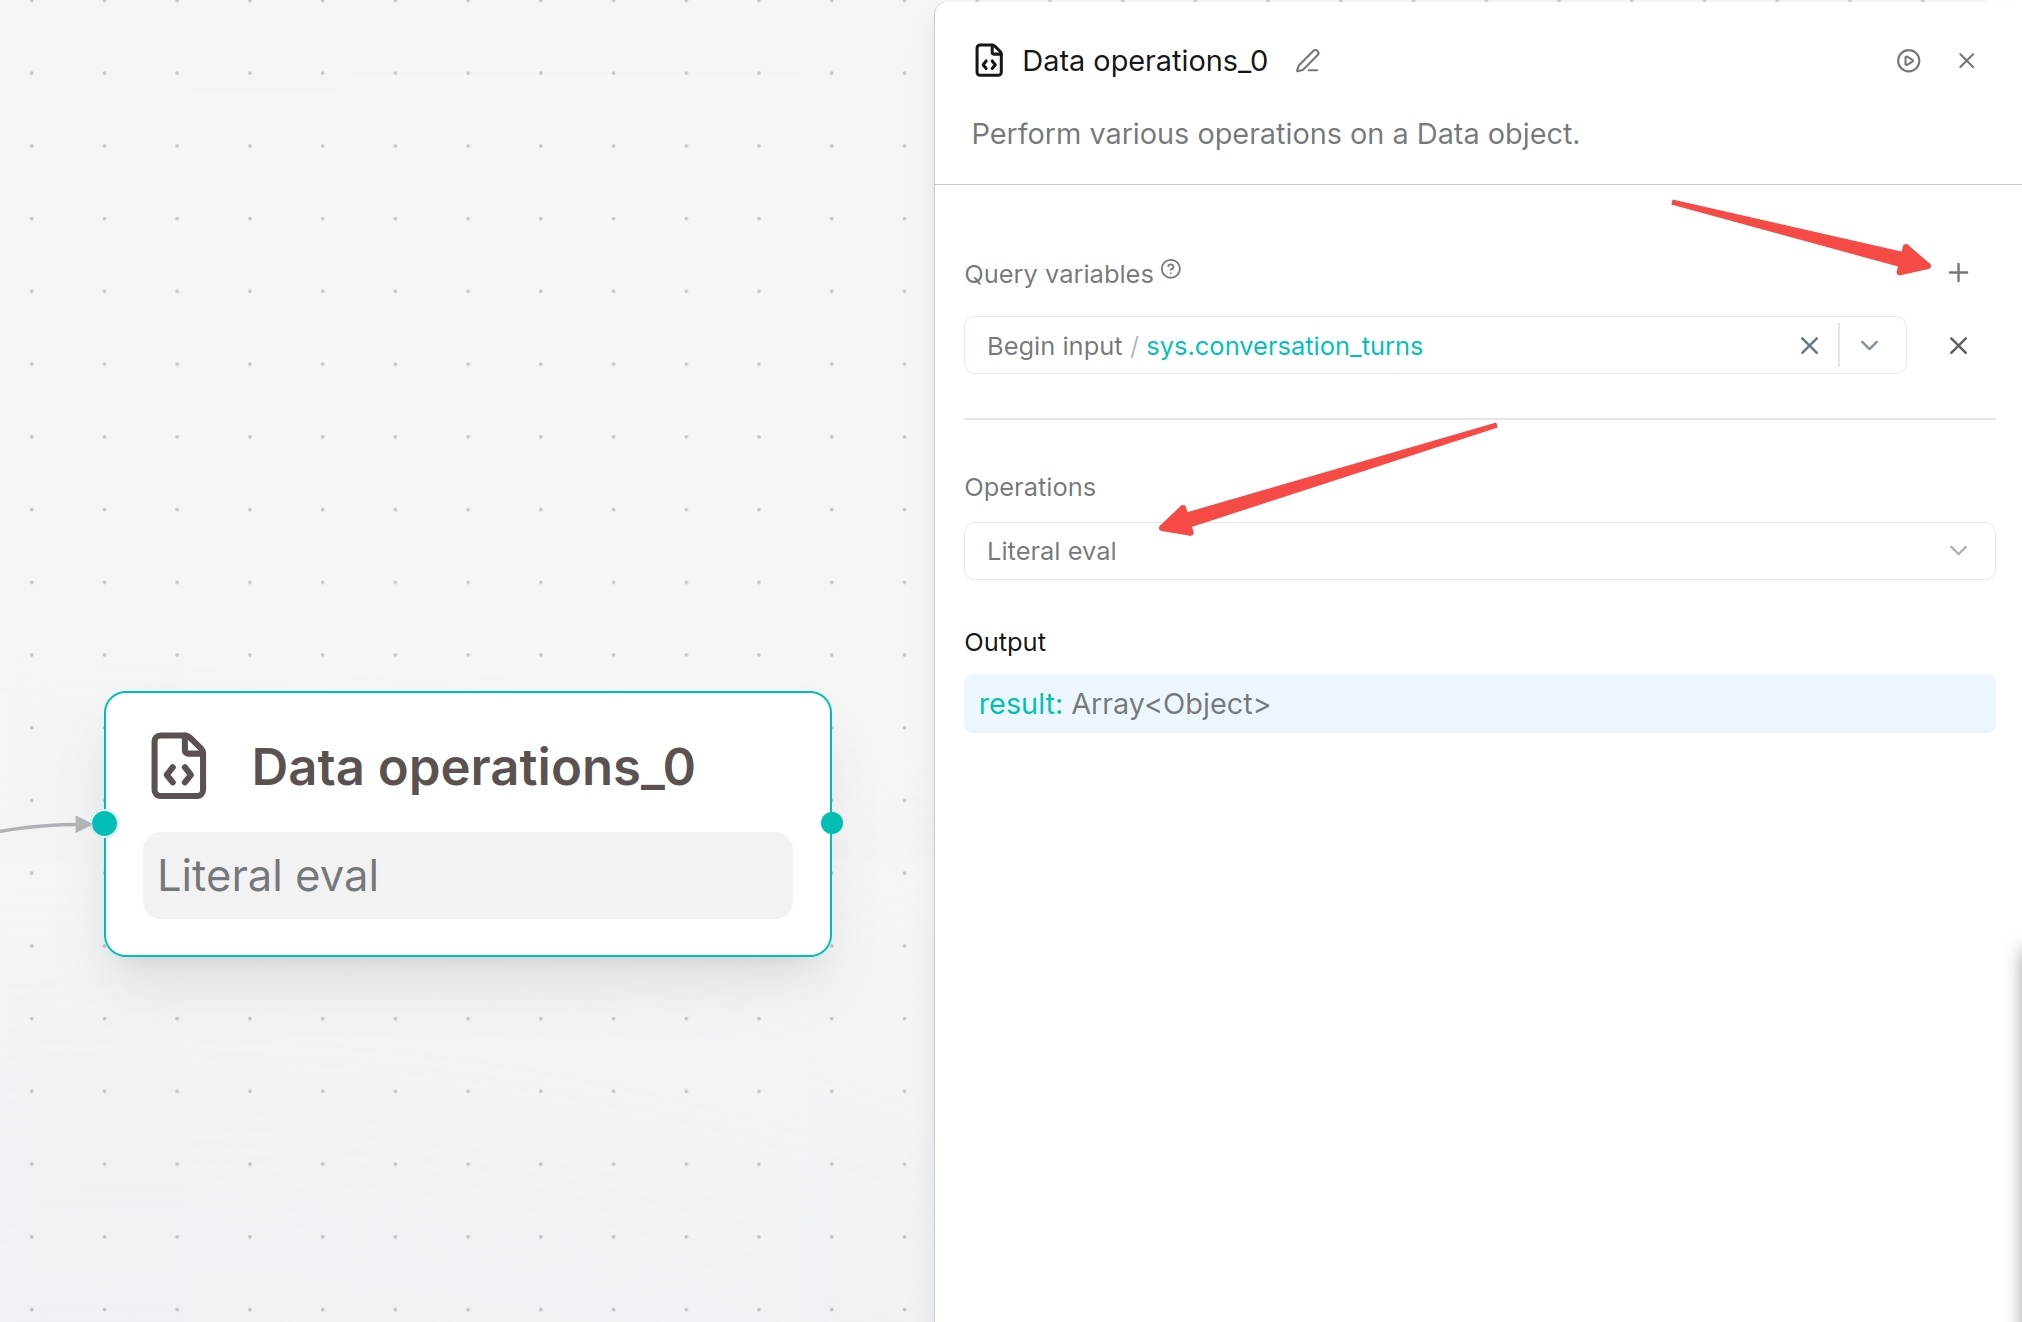
|
||||
|
||||
Output: Processed data stored in variable `result`.
|
||||
|
||||
Supported Operations:
|
||||
@@ -57,14 +59,28 @@ Supported Operations:
|
||||
| Remove keys | Delete specified fields | Remove unnecessary sensitive or unused fields |
|
||||
| Rename keys | Rename object field keys | Unify field naming standards |
|
||||
|
||||

|
||||
|
||||
|
||||
|
||||
## Variable Assignor Component
|
||||
Variable Assignor writes or updates variables during workflow execution. It can save upstream results to target variables and support overwrite, clear, append and arithmetic operations for numbers, arrays and objects.
|
||||
|
||||
Configuration:
|
||||
Add variable rules. Select target variable, choose operation type, and fill constant or reference variable as value if required. Multiple rules execute sequentially.
|
||||
Configuration Steps:
|
||||
1. Click the **Variable Assigner** component and add a new variable rule under **Variables**.
|
||||
2. Select the target variable to be updated.
|
||||
3. Select an assignment operation, such as **Overwrite**, **Set**, **Append**, or **Add**.
|
||||
4. If the selected operation requires a value, select a variable from the right panel or enter a fixed value.
|
||||
5. To update multiple variables at once, continue adding variable rules. The system will execute them sequentially in the order they are added.
|
||||
|
||||
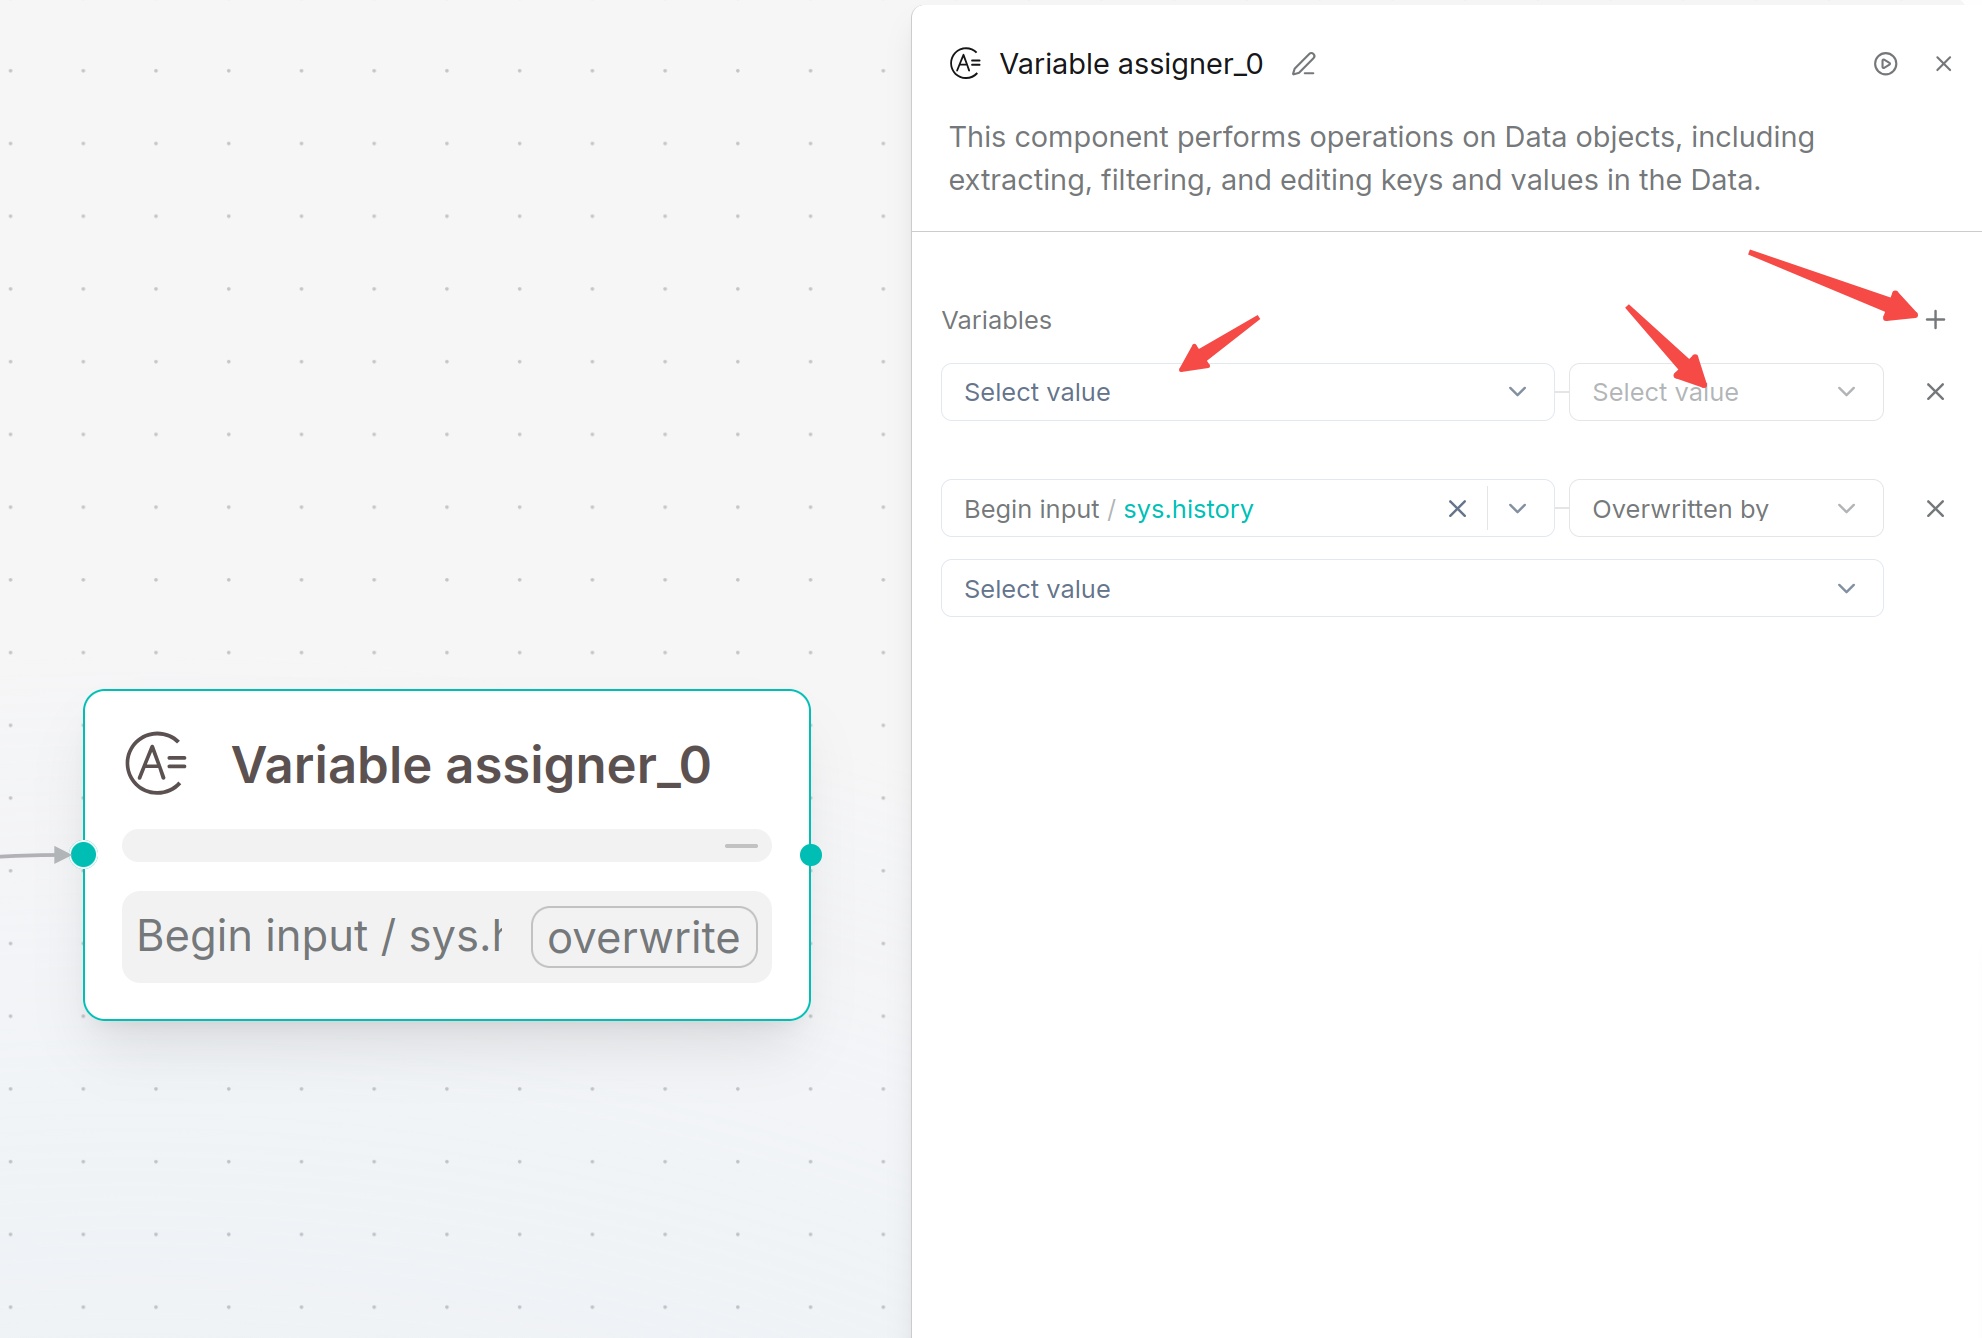
|
||||
|
||||
Parameter Description:
|
||||
|
||||
| Parameter | Type | Required | Description |
|
||||
|---|---|---|---|
|
||||
| Target Variable | Variable | Yes | Select the variable to be written or updated. Supports component output variables, system variables, environment variables, session variables, and other variable types. |
|
||||
| Operation | Enum | Yes | Select the operation to be performed on the target variable. The system will automatically display available operations based on the variable type. |
|
||||
| Value | Variable / Constant | Conditional | The value used for the operation. You can select another variable or enter a fixed value (depending on the supported operation type). Some operations do not require a value. |
|
||||
|
||||
Supported Operations:
|
||||
| Operation | Requires Value | Description |
|
||||
@@ -73,37 +89,88 @@ Supported Operations:
|
||||
| Set | Yes | Assign fixed constant value to target variable |
|
||||
| Clear | No | Empty the target variable |
|
||||
|
||||

|
||||
|
||||
|
||||
## List Operation Component
|
||||
List Operation processes array data, supporting element extraction, head/tail fetching, filtering, sorting and deduplication. Suitable for array outputs from Begin, HTTP Request, Code and SQL.
|
||||
|
||||
Configuration:
|
||||
1. Select array variable in Query variables.
|
||||
2. Choose operation in Operations and fill parameters.
|
||||
3. Optional: Enable Strict mode.
|
||||
Configuration Steps:
|
||||
1. Add the **List** component to the canvas and select it.
|
||||
2. In the **Query variables** section of the right configuration panel, select the array variable to be processed. Click the dropdown menu and choose an array-type variable from the **Begin** node, upstream nodes, or session variables.
|
||||
3. Select the list processing method in **Operations**.
|
||||
4. configure the corresponding parameters based on the selected operation.
|
||||
5. Enable **Strict mode** if required.
|
||||
6. Save the configuration, then click **Run** on the page to test and view the execution results.
|
||||
7. The processed result will be output through the component and can be referenced by subsequent nodes.
|
||||
|
||||
Parameter Description:
|
||||
| Parameter | Required | Description |
|
||||
|---|---|---|
|
||||
| Query variables | Yes | Select the array variable to be processed. |
|
||||
| Operations | Yes | Select the list processing operation. |
|
||||
| Strict mode | No | When enabled, the system performs strict validation during processing and returns an error if an exception occurs. When disabled, the system processes according to the configured rules. |
|
||||
| Operation Parameters | Conditional | Configure the corresponding parameters based on the selected operation, such as N, filter conditions, or sorting rules. |
|
||||
|
||||
Supported Operations:
|
||||
| Operation | Description | Use Case |
|
||||
|---|---|---|
|
||||
| Nth | Retrieves an element at a specified position from the list. | Get the Nth item from the list. |
|
||||
| Head | Retrieves one or more elements from the beginning of the list. | Get the first N items from the list. |
|
||||
| Tail | Retrieves one or more elements from the end of the list. | Get the last N items from the list. |
|
||||
| Filter | Filters elements in the list based on conditions. | Keep data that meets the specified conditions. |
|
||||
| Sort | Sorts the elements in the list. | Sort by specified fields or order. |
|
||||
| Drop duplicates | Removes duplicate elements from the list. | Deduplicate the list data. |
|
||||
|
||||
Operation Configuration Description:
|
||||
| Operation | Description | Configuration |
|
||||
|---|---|---|
|
||||
| Nth | Retrieves an element at a specified position from the list. | Configure **N** to specify the element index (starting from 0). |
|
||||
| Head | Retrieves elements from the beginning of the list. | Configure the return count **N** to return the first N elements. |
|
||||
| Tail | Retrieves elements from the end of the list. | Configure the return count **N** to return the last N elements. |
|
||||
| Filter | Filters list elements based on conditions. | Configure filter conditions and retain only elements that meet the requirements. |
|
||||
| Sort | Sorts elements in the list. | Configure the sorting field and order (ascending or descending). |
|
||||
| Drop duplicates | Removes duplicate elements from the list. | No additional configuration required. Returns the deduplicated list. |
|
||||
|
||||
Strict Mode:
|
||||
- Enabled: Return error when input data format is abnormal
|
||||
- Disabled: Handle abnormal data with default tolerance
|
||||
|
||||
Supported Operations:
|
||||
- Nth: Get element at specified index (starting from 0)
|
||||
- Head: Get first N elements
|
||||
- Tail: Get last N elements
|
||||
- Filter: Filter array by conditions
|
||||
- Sort: Sort array by specified field (asc/desc)
|
||||
- Drop duplicates: Remove duplicate entries
|
||||
|
||||
## Variable Aggregator Component
|
||||
Variable Aggregator combines multiple independent variables into one output group for unified reference by downstream nodes. Widely used in multi-branch conditional workflows to collect data from different branches.
|
||||
|
||||
Configuration:
|
||||
1. Select variables and add into variable groups (default Group0).
|
||||
2. Click `+` to create new variable groups; delete groups via remove button.
|
||||
3. Save configuration and run tests.
|
||||
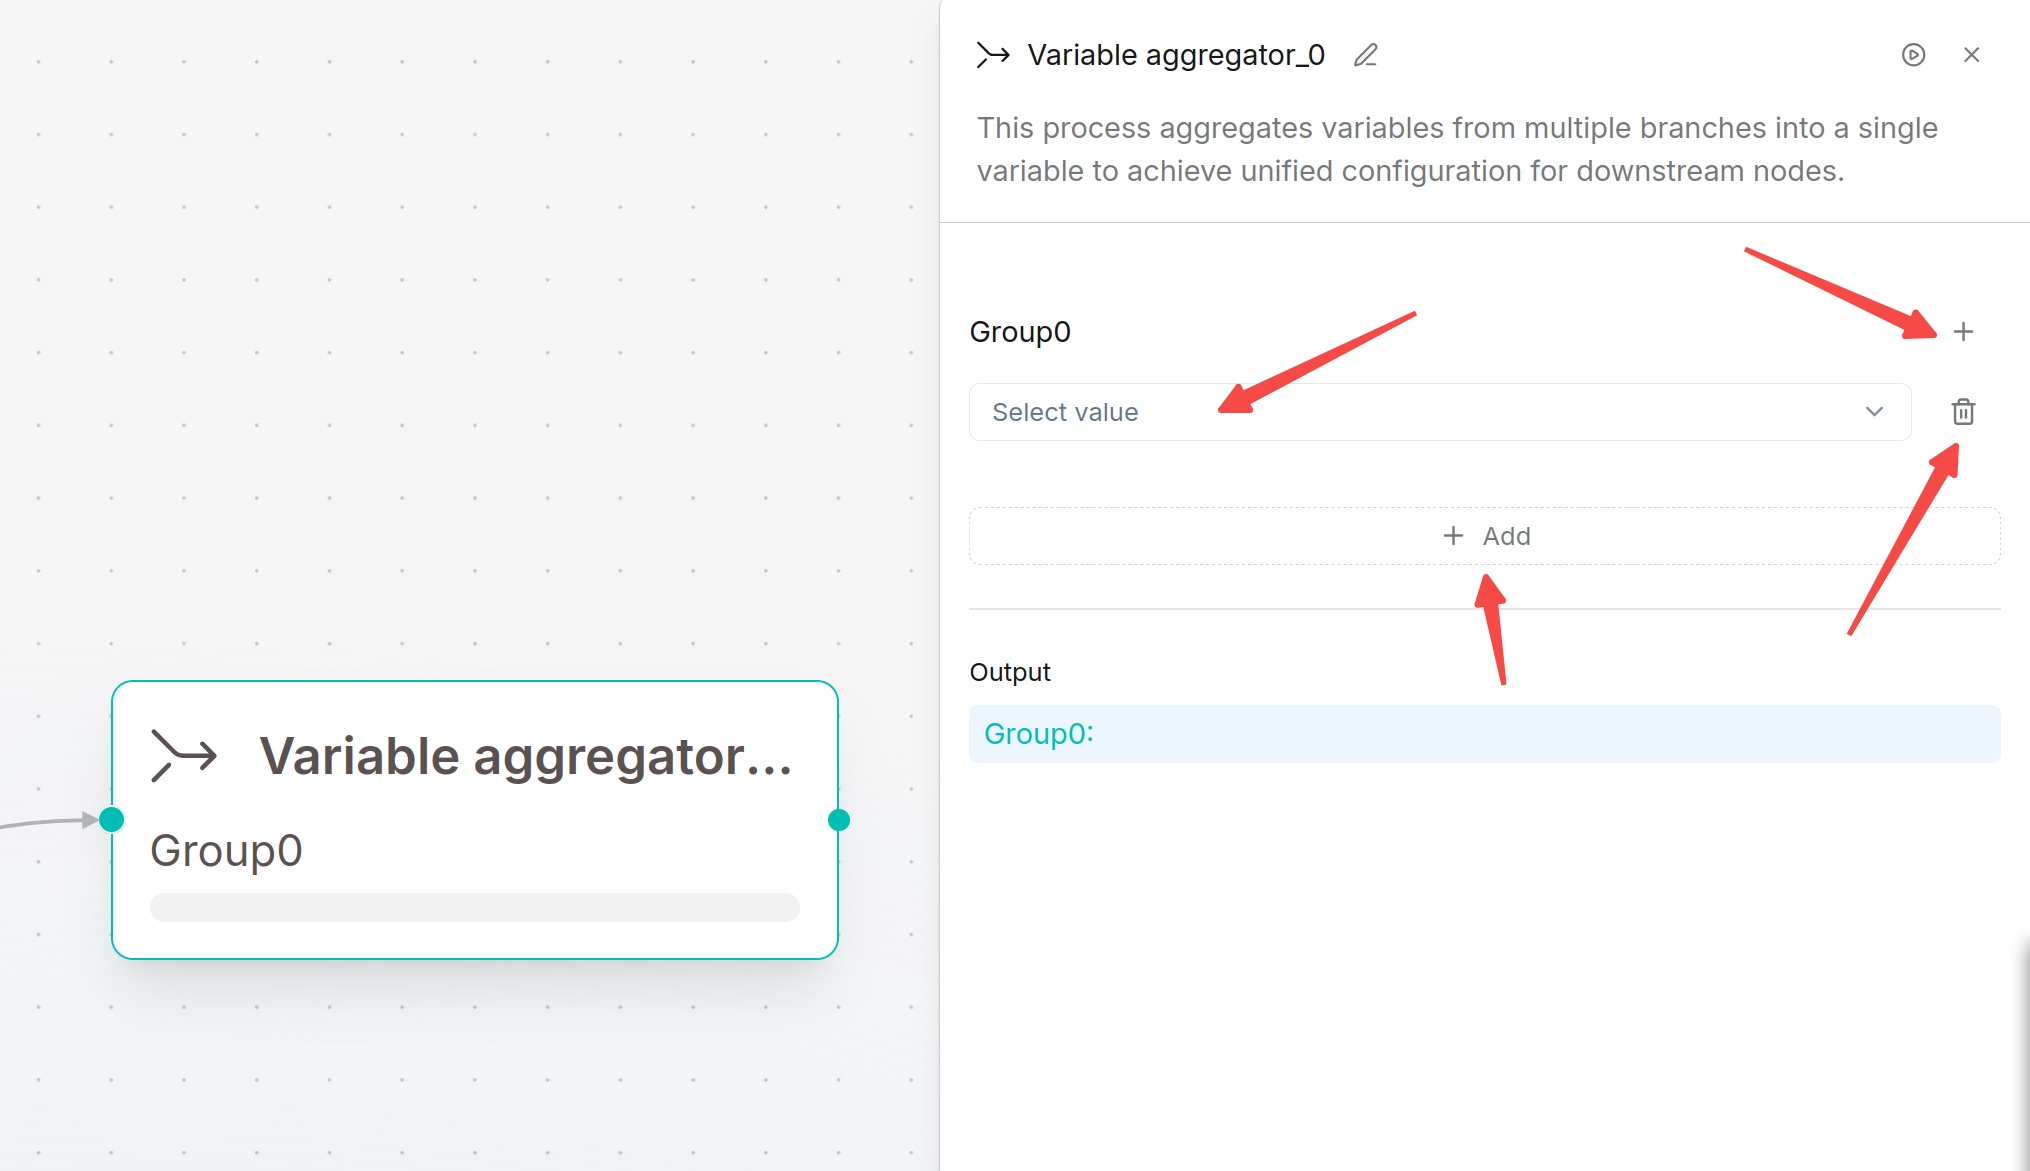
Configuration Steps:
|
||||
1. Add the **Variable Aggregator** component to the canvas and select it.
|
||||
2. In the **Variable Group** (default: **Group0**), click **Select value** and choose the variables to be aggregated.
|
||||
3. Click **Add** to add additional variables to aggregate.
|
||||
4. To create a new variable group, click the **+** icon. To delete a variable group, click the delete button.
|
||||
5. Save the configuration, then click **Run** at the top of the page to test the execution result.
|
||||
6. The aggregated variables will be output through the corresponding variable group name (for example, **Group0**) and can be referenced by subsequent nodes.
|
||||
|
||||
Output: Variables inside each group can be referenced via group name such as `Group0`.
|
||||
> **Note**
|
||||
>
|
||||
> A variable group can contain multiple variables. Multiple variable groups can also be created based on different business requirements for separate aggregation.
|
||||
|
||||
Parameter Description:
|
||||
| Parameter | Required | Description |
|
||||
|---|---|---|
|
||||
| Group | Yes | Variable group used to store variables to be aggregated. A default group **Group0** is created automatically, and additional variable groups can be added. |
|
||||
| Select value | Yes | Select the variables to be aggregated. Supports system variables, **Begin** node inputs, session variables, or output variables from upstream nodes. |
|
||||
| Add | No | Continue adding variables to the current variable group. |
|
||||
| + | No | Create a new variable group. |
|
||||
| Delete | No | Delete the current variable group. |
|
||||
|
||||
Output Result:
|
||||
| Output | Description |
|
||||
|---|---|
|
||||
| Group0 (or other variable group name) | Outputs the variables after aggregation in the current variable group. The output can be directly referenced by subsequent nodes. |
|
||||
|
||||
Usage Instructions:
|
||||
| Operation | Description |
|
||||
|---|---|
|
||||
| Add Variable | Select variables in **Select value**, then click **Add** to continue adding multiple variables. |
|
||||
| Create Variable Group | Click the **+** icon to create a new variable group. |
|
||||
| Delete Variable Group | Click the delete button for the variable group to remove the current group. |
|
||||
| Reference Output | Subsequent nodes can directly reference the variable group (for example, **Group0**) as an input. |
|
||||
|
||||
|
||||
|
||||
@@ -10,558 +10,718 @@ sidebar_custom_props: {
|
||||
|
||||
# Tool Components
|
||||
|
||||
Tool components extend an Agent's ability to retrieve information, query data, call external systems and generate deliverables. Select tools according to the business scenario and configure only the parameters required by the workflow.
|
||||
Tool components connect external search, databases, HTTP APIs, email sending, document generation, financial queries, and browser automation capabilities to Agents. When building Agents, first understand each tool's purpose and security boundaries.
|
||||
|
||||
## Tool Selection Suggestions
|
||||
|
||||
- Use web search or extraction tools when the Agent needs public web information.
|
||||
- Use academic retrieval tools when the Agent needs papers, medical literature or research references.
|
||||
- Use SQL and financial query tools when the Agent needs structured data or market information.
|
||||
- Use HTTP Request and Email for communication with external systems.
|
||||
- Use Document Generator and Browser for content generation and automation tasks.
|
||||
| Tool Category | Typical Components | Use Case |
|
||||
| --- | --- | --- |
|
||||
| Web search | Tavily, Google, DuckDuckGo, SearXNG, Keenable | Retrieve web pages, news, public information, or content from specified sites. |
|
||||
| Academic search | Google Scholar, ArXiv, PubMed, BGPT | Retrieve papers, medical literature, and research materials. |
|
||||
| Data and financial queries | Execute SQL, Yahoo Finance, WenCai | Query databases, market data, or financial screening results. |
|
||||
| Content output | Email, Document Generator | Send emails or generate downloadable documents. |
|
||||
| Browser automation | Browser | Access web pages, read page content, or perform multi-step browser tasks. |
|
||||
|
||||
## Web Page and Information Retrieval
|
||||
|
||||
### Tavily Search (TavilySearch)
|
||||
|
||||
Tavily Search retrieves web results through Tavily. It is suitable for public web search, news search and supplementing knowledge base retrieval with external information.
|
||||
Tavily is a web search service for LLMs. It is suitable for retrieving general web information, news, and content that needs to be limited to specific domains. Keep queries focused on a single topic and avoid overly long natural-language questions.
|
||||
|
||||
#### Parameter Description
|
||||
|
||||
| Parameter | Type | Required | Default | Description |
|
||||
| ---- | ---- | ---- | ---- | ---- |
|
||||
| `query` | string | Yes | `{sys.query}` | Search keywords or question. |
|
||||
| `topic` | string | No | `general` | Search topic. Common values are `general` and `news`. |
|
||||
| `search_depth` | string | No | `basic` | Search depth. Common values are `basic` and `advanced`. |
|
||||
| `top_n` | integer | No | 10 | Maximum number of returned results. |
|
||||
| Parameter | Type | Required | Default Value | Description |
|
||||
| --- | --- | --- | --- | --- |
|
||||
| Query | string | Yes | Current user input | Search keywords. |
|
||||
| Topic | string | No | general | Search type. Options are `general` or `news`. |
|
||||
| Include Domains | array[string] | No | Empty list | Keep only results from these domains, such as `www.nasa.gov`. |
|
||||
| Exclude Domains | array[string] | No | Empty list | Exclude results from these domains. |
|
||||
| API Key | string | No | Empty | Tavily API key. |
|
||||
| Search Depth | string | No | basic | Search depth. Options are `basic` or `advanced`. |
|
||||
| Max Results | integer | No | 6 | Maximum number of results. |
|
||||
| Days | integer | No | 14 | Time range in days for news retrieval. |
|
||||
| Include Answer | boolean | No | false | Whether to request Tavily's answer field. |
|
||||
| Include Raw Content | boolean | No | false | Whether to request raw page content. |
|
||||
| Include Images | boolean | No | false | Whether to request images. |
|
||||
| Include Image Descriptions | boolean | No | false | Whether to request image descriptions. |
|
||||
|
||||
#### Supported Parameter Values
|
||||
|
||||
- `topic`: `general`, `news`
|
||||
- `search_depth`: `basic`, `advanced`
|
||||
| Parameter | Supported Value | Description |
|
||||
| --- | --- | --- |
|
||||
| Topic | general | General web search. |
|
||||
| Topic | news | News retrieval. |
|
||||
| Search Depth | basic | Basic search. |
|
||||
| Search Depth | advanced | Deep search. |
|
||||
|
||||
#### Configuration Example
|
||||
|
||||
```json
|
||||
{
|
||||
"query": "RAGFlow open source",
|
||||
"topic": "general",
|
||||
"search_depth": "basic"
|
||||
}
|
||||
```
|
||||
| Configuration Item | Example Value |
|
||||
| --- | --- |
|
||||
| URLs | `["https://www.ragflow.io/docs/dev/"]` |
|
||||
| Extract Depth | basic |
|
||||
| Format | markdown |
|
||||
| API Key | |
|
||||
| Include Images | false |
|
||||
|
||||
#### Output Result
|
||||
|
||||
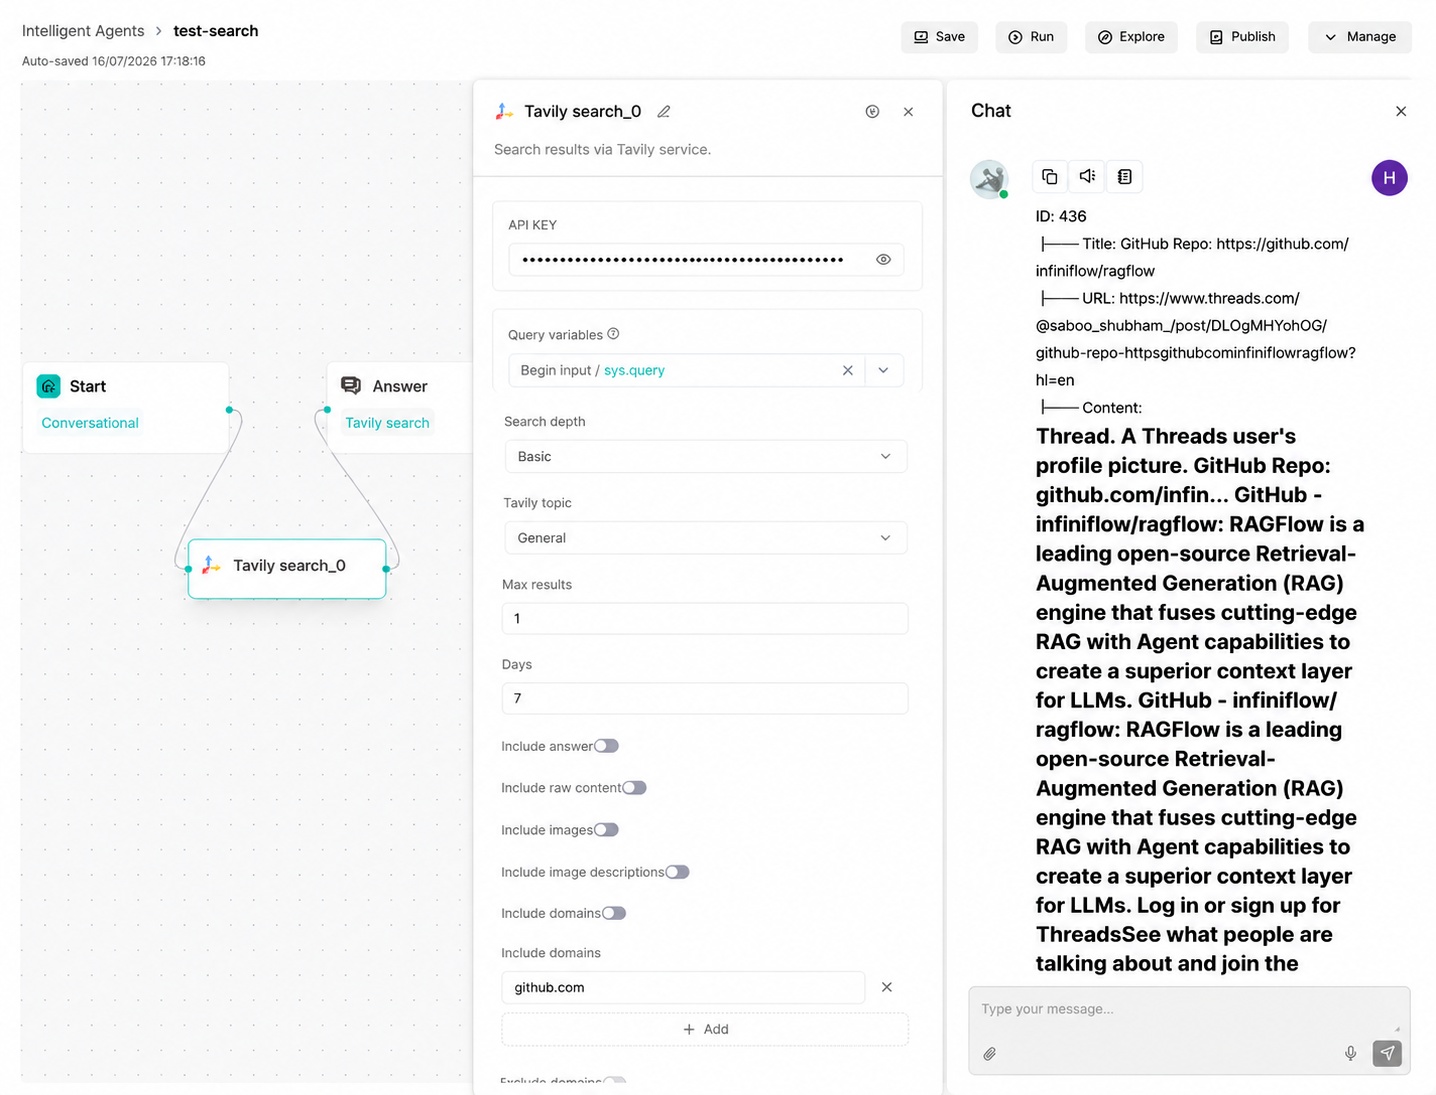
The component returns search result items, including titles, URLs, snippets and related metadata. Downstream Agent or Message components can reference the result content for answer generation.
|
||||
The output usually contains search result summaries, titles, links, snippets, and optional image information. `formalized_content` is commonly passed to the Agent to generate answers, while JSON is used by subsequent nodes to read structured fields.
|
||||
|
||||
|
||||
|
||||
|
||||
### Tavily Extract (TavilyExtract)
|
||||
|
||||
Tavily Extract extracts content from specified web pages. It is suitable for reading known URLs, article pages, documentation pages or web pages found by a previous search step.
|
||||
Tavily Extract reads the body content of one or more known URLs. A common workflow is to use Tavily Search to obtain links, then pass those links to this component to extract page content.
|
||||
|
||||
#### Parameter Description
|
||||
|
||||
| Parameter | Type | Required | Default | Description |
|
||||
| ---- | ---- | ---- | ---- | ---- |
|
||||
| `urls` | array/string | Yes | Empty | One or more URLs to extract. |
|
||||
| `extract_depth` | string | No | `basic` | Extraction depth. Common values are `basic` and `advanced`. |
|
||||
| `format` | string | No | `markdown` | Output format, such as `text` or `markdown`. |
|
||||
| Parameter | Type | Required | Default Value | Description |
|
||||
| --- | --- | --- | --- | --- |
|
||||
| URLs | array[string] | Yes | Empty list | URL list to extract. If input is a string, it is split by English commas. |
|
||||
| Extract Depth | string | No | basic | `advanced` can extract more tables and embedded content, with higher cost and latency. |
|
||||
| Format | string | No | markdown | Extraction result format. Options are `markdown` or `text`. |
|
||||
| API Key | string | No | Empty | Tavily API key. |
|
||||
| Include Images | boolean | No | false | Whether to include images. |
|
||||
|
||||
#### Supported Parameter Values
|
||||
|
||||
- `extract_depth`: `basic`, `advanced`
|
||||
- `format`: `text`, `markdown`
|
||||
| Parameter | Supported Value | Description |
|
||||
| --- | --- | --- |
|
||||
| Extract Depth | basic | Basic extraction. |
|
||||
| Extract Depth | advanced | Extracts more tables and embedded content, with higher latency and cost. |
|
||||
| Format | markdown | Markdown format. |
|
||||
| Format | text | Plain text format. |
|
||||
|
||||
#### Configuration Example
|
||||
|
||||
```json
|
||||
{
|
||||
"urls": ["https://ragflow.io/docs"],
|
||||
"extract_depth": "basic",
|
||||
"format": "markdown"
|
||||
}
|
||||
```
|
||||
| Configuration Item | Example Value |
|
||||
| --- | --- |
|
||||
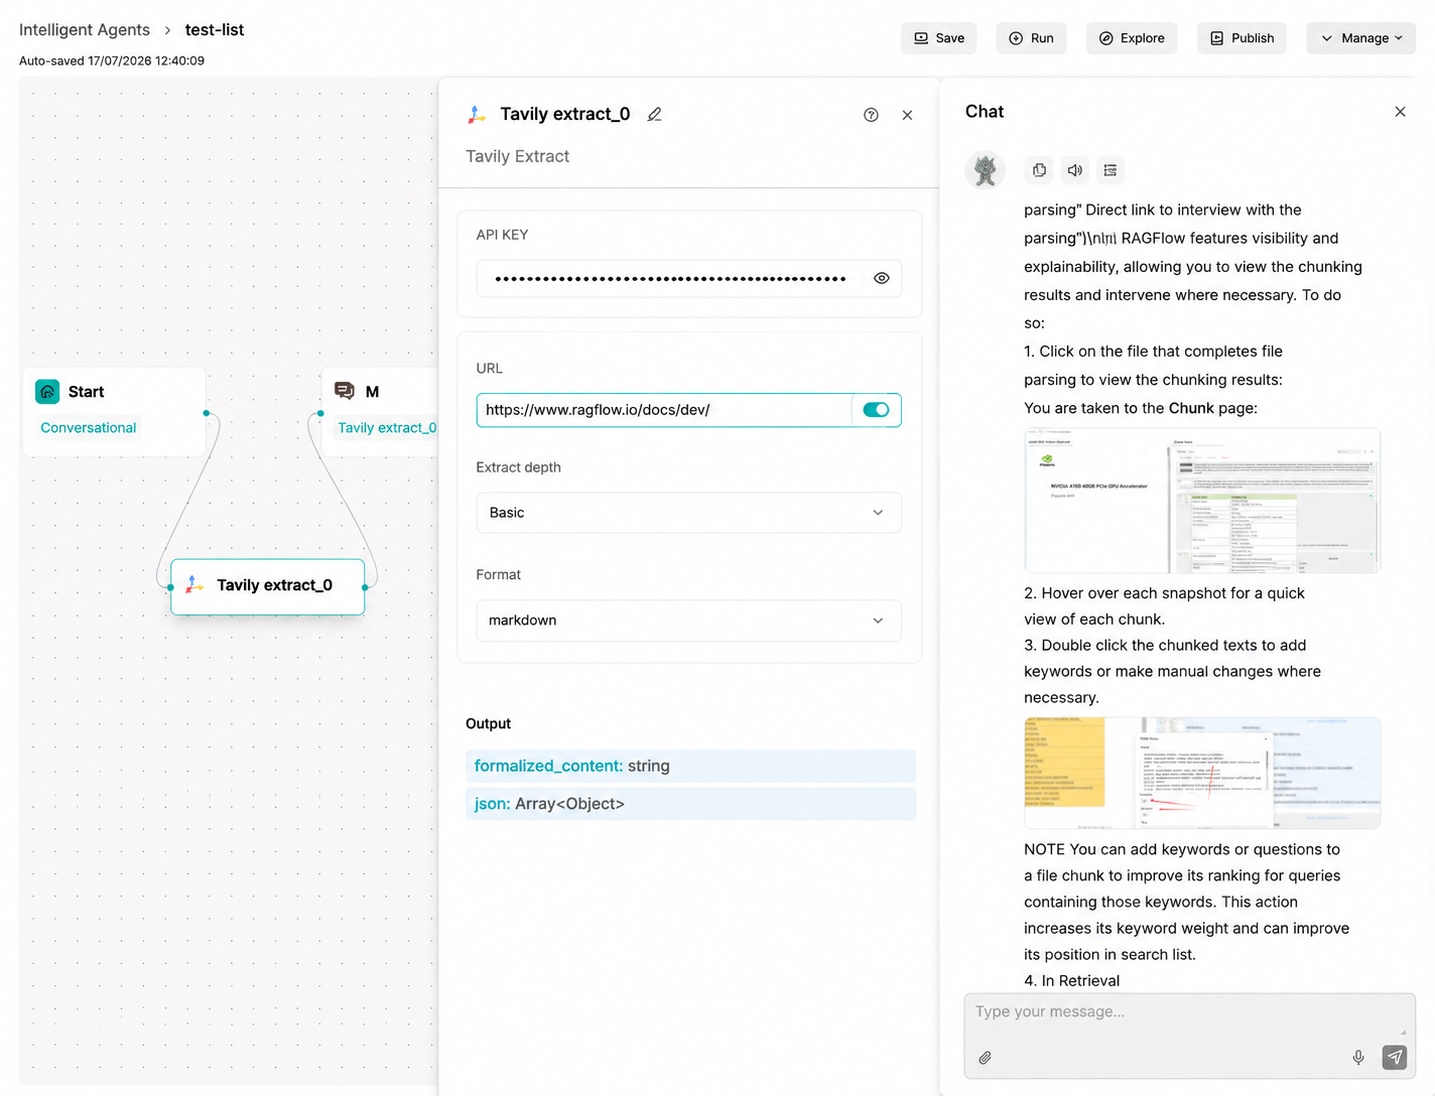
| URLs | `["https://www.ragflow.io/docs/dev/"]` |
|
||||
| Extract Depth | basic |
|
||||
| Format | markdown |
|
||||
| API Key | |
|
||||
| Include Images | false |
|
||||
|
||||
#### Output Result
|
||||
|
||||
The component returns extracted page text and metadata. The extracted text can be passed to Agent, Text Processing or Data Operation components.
|
||||
The output contains the page body, title, URL, and extraction status. `formalized_content` is commonly used as Agent context, while JSON preserves the structured extraction result for each URL.
|
||||
|
||||
|
||||
|
||||
|
||||
### Google Search (Google)
|
||||
|
||||
Google Search retrieves public web results through Google. It is suitable for broad web search scenarios where a Google-compatible search capability has been configured.
|
||||
Google Search obtains Google organic search results through SerpApi. It is suitable for web retrieval that requires country and language targeting.
|
||||
|
||||
#### Parameter Description
|
||||
|
||||
| Parameter | Type | Required | Default | Description |
|
||||
| ---- | ---- | ---- | ---- | ---- |
|
||||
| `query` | string | Yes | `{sys.query}` | Search keywords. |
|
||||
| `top_n` | integer | No | 10 | Maximum number of returned results. |
|
||||
| Parameter | Type | Required | Default Value | Description |
|
||||
| --- | --- | --- | --- | --- |
|
||||
| Query | string | Yes | Current user input | Search keywords. |
|
||||
| Start | integer | No | 0 | Result offset. In document semantics, this is the pagination starting point. |
|
||||
| Num | integer | No | 6 | Number of requested results. |
|
||||
| API Key | string | Yes | Empty | SerpApi API key. |
|
||||
| Country | string | No | cn | Google region code, such as `cn`, `us`, or `jp`. |
|
||||
| Language | string | No | en | Google interface/result language code, such as `zh-CN` or `en`. |
|
||||
|
||||
#### Configuration Example
|
||||
|
||||
```json
|
||||
{
|
||||
"query": "RAGFlow Agent workflow"
|
||||
}
|
||||
```
|
||||
| Configuration Item | Example Value |
|
||||
| --- | --- |
|
||||
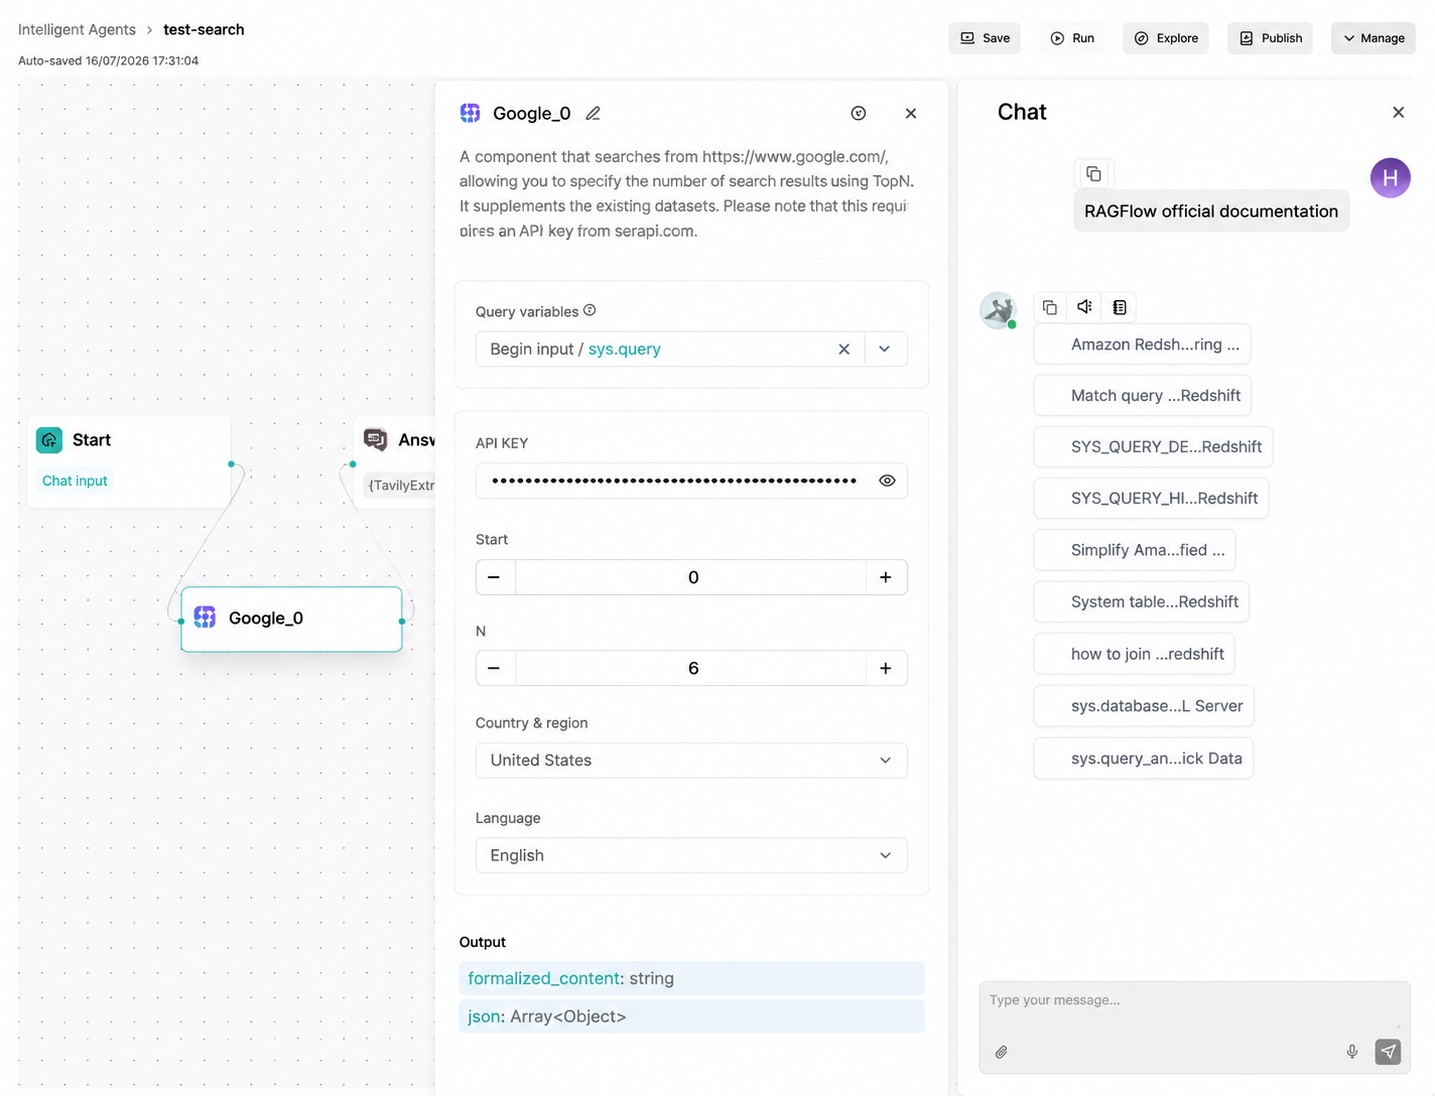
| Query | RAGFlow official documentation |
|
||||
| Start | 0 |
|
||||
| Num | 6 |
|
||||
| API Key | |
|
||||
| Country | cn |
|
||||
| Language | en |
|
||||
|
||||
#### Output Result
|
||||
|
||||
The component returns search result titles, URLs and summaries for downstream processing.
|
||||
The output contains search result titles, links, and summaries. The organized text can be passed to the Agent for summarization, or subsequent nodes can read the link list from JSON.
|
||||
|
||||
|
||||
|
||||
|
||||
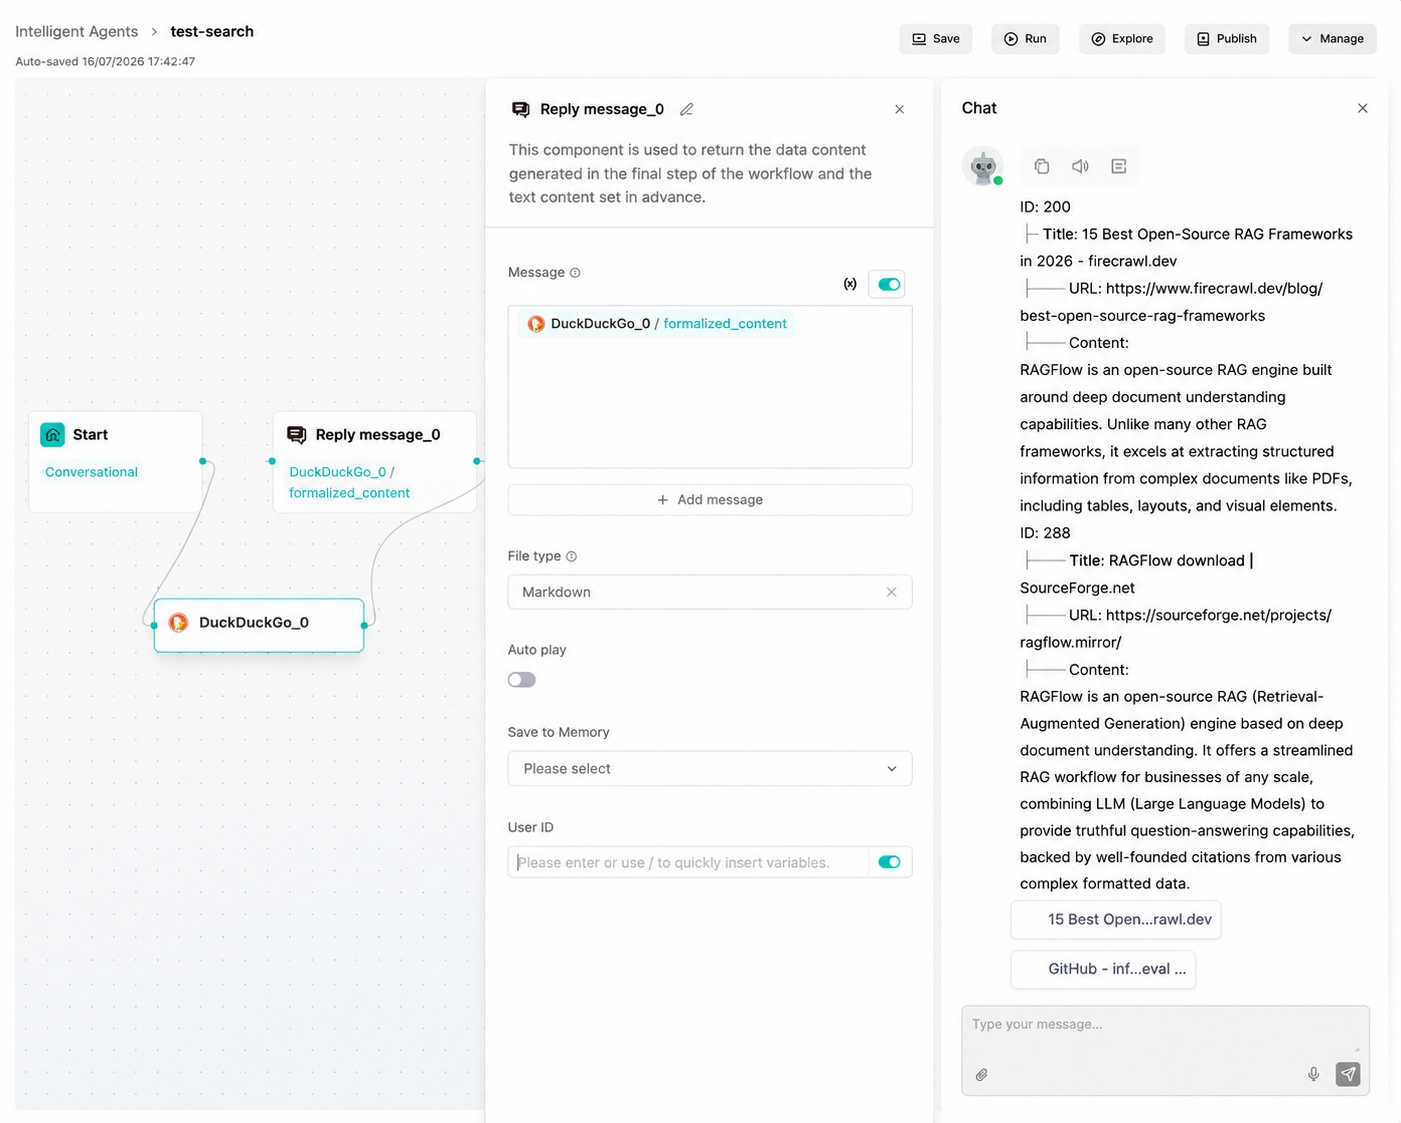
### DuckDuckGo (DuckDuckGo)
|
||||
|
||||
DuckDuckGo is a privacy-focused search engine component. It does not require a separate API key and can be used for general web and news retrieval.
|
||||
|
||||
#### Parameter Description
|
||||
|
||||
| Parameter | Type | Required | Default | Description |
|
||||
| ---- | ---- | ---- | ---- | ---- |
|
||||
| `query` | string | Yes | `{sys.query}` | Search keywords. |
|
||||
| `channel` | string | No | `general` | Channel exposed by tool metadata, such as `general` or `news`. |
|
||||
| `top_n` | integer | No | 10 | Maximum number of returned results. |
|
||||
| Parameter | Type | Required | Default Value | Description |
|
||||
| --- | --- | --- | --- | --- |
|
||||
| Query | string | Yes | Current user input | Search keywords. |
|
||||
| Channel | string | No | general | Message channel: `general` or `news`. |
|
||||
| Top N | integer | Node configuration | 10 | Maximum number of returned results. |
|
||||
|
||||
#### Configuration Example
|
||||
|
||||
```json
|
||||
{
|
||||
"query": "RAGFlow open source",
|
||||
"channel": "general"
|
||||
}
|
||||
```
|
||||
| Configuration Item | Example Value |
|
||||
| --- | --- |
|
||||
| Query | RAGFlow open source |
|
||||
| Channel | general |
|
||||
| Top N | 10 |
|
||||
|
||||
#### Output Result
|
||||
|
||||
The component returns web search result items. Confirm parameter mapping in the current version before using news retrieval.
|
||||
The output contains titles, links, and summaries returned by DuckDuckGo. It can be used for web material summarization, news lead organization, or subsequent page extraction.
|
||||
|
||||
|
||||
|
||||
|
||||
|
||||
|
||||
### SearXNG (SearXNG)
|
||||
|
||||
SearXNG searches through a configured SearXNG instance. It is suitable for teams that need self-hosted or privacy-oriented meta-search.
|
||||
SearXNG is a self-hostable privacy-oriented meta-search engine. This component calls a user-provided SearXNG instance and is suitable for scenarios that need control over retrieval sources or internal search deployment.
|
||||
|
||||
#### Parameter Description
|
||||
|
||||
| Parameter | Type | Required | Default | Description |
|
||||
| ---- | ---- | ---- | ---- | ---- |
|
||||
| `query` | string | Yes | `{sys.query}` | Search keywords. |
|
||||
| `top_n` | integer | No | 10 | Maximum number of returned results. |
|
||||
| `base_url` | string | Yes | Empty | SearXNG service address. |
|
||||
| Parameter | Type | Required | Default Value | Description |
|
||||
| --- | --- | --- | --- | --- |
|
||||
| Query | string | Yes | Current user input | Search keywords. |
|
||||
| SearXNG URL | string | Yes | Empty | SearXNG instance base URL, such as `https://searxng.example.com`. |
|
||||
| Top N | integer | No | 10 | Maximum number of results. |
|
||||
|
||||
#### Configuration Example
|
||||
|
||||
```json
|
||||
{
|
||||
"query": "retrieval augmented generation",
|
||||
"base_url": "https://searxng.example.com"
|
||||
}
|
||||
```
|
||||
| Configuration Item | Example Value |
|
||||
| --- | --- |
|
||||
| Query | RAGFlow documentation |
|
||||
| SearXNG URL | `https://<your-searxng-host>` |
|
||||
| Top N | 10 |
|
||||
|
||||
#### Output Result
|
||||
|
||||
The component returns normalized search results from the configured SearXNG service.
|
||||
The output contains titles, links, summaries, and source information returned by SearXNG. Before use, configure a reachable SearXNG service address and pass the system security checks.
|
||||
|
||||
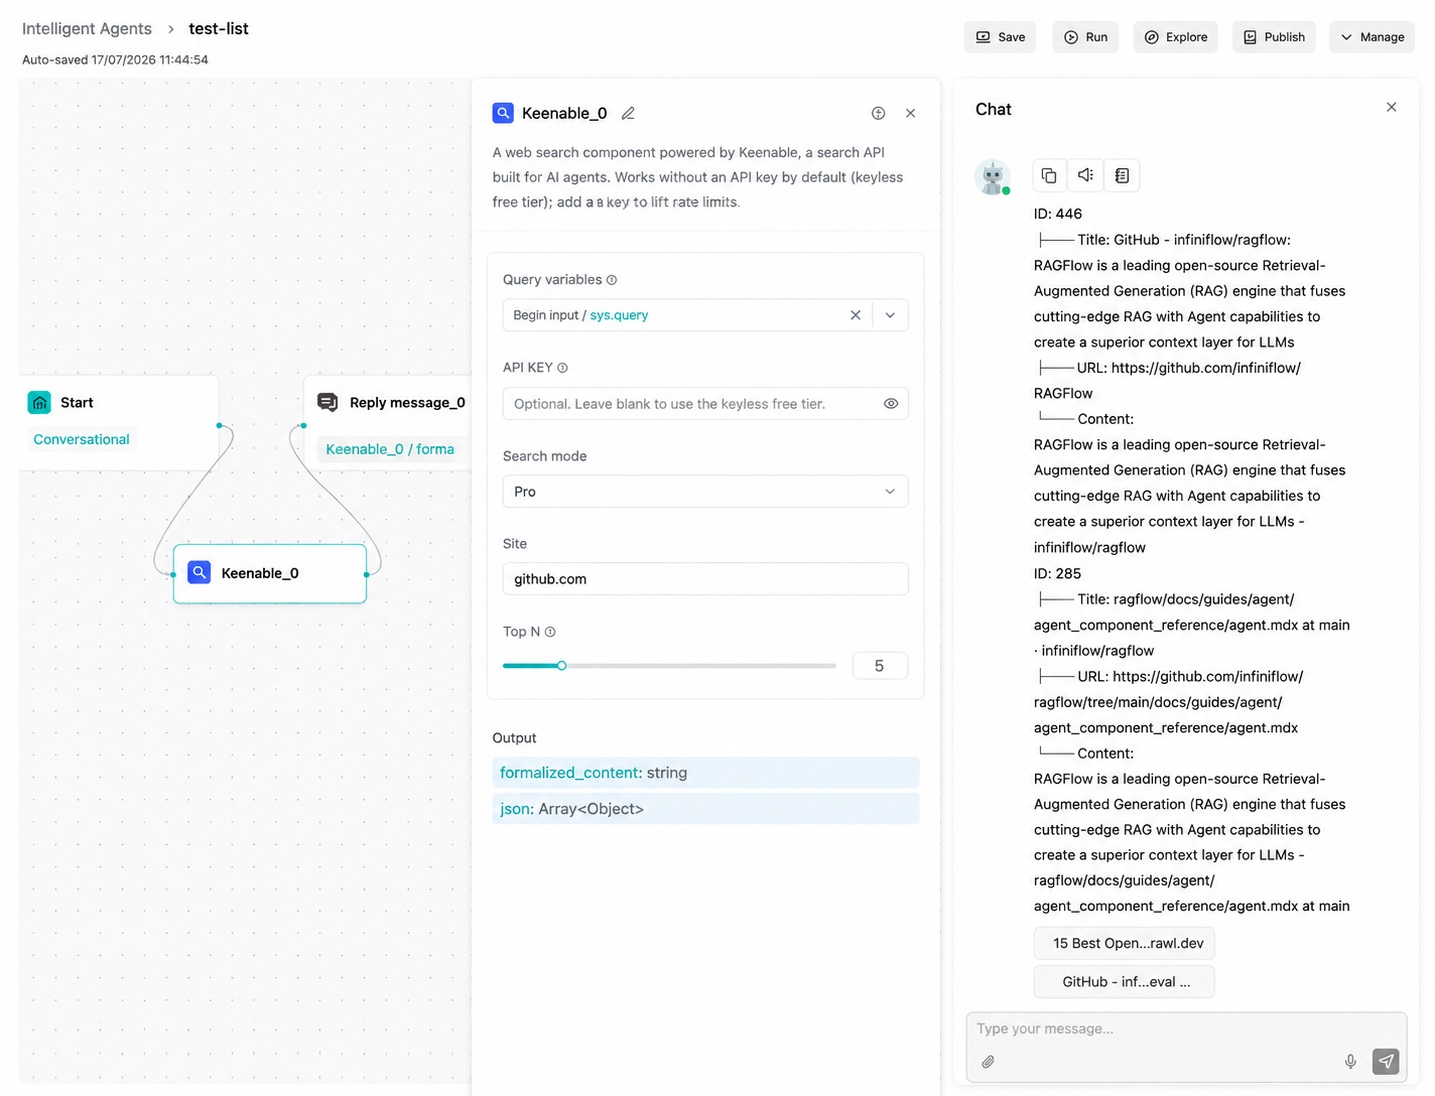
### Keenable (KeenableSearch)
|
||||
|
||||
Keenable Search retrieves information through the configured Keenable service. Use it when the workflow requires that search provider.
|
||||
Keenable is a web search API for AI Agents. By default, it supports a public free path without a key. After configuring a key, you can increase the limit and enable low-latency realtime mode.
|
||||
|
||||
#### Parameter Description
|
||||
|
||||
| Parameter | Type | Required | Default | Description |
|
||||
| ---- | ---- | ---- | ---- | ---- |
|
||||
| `query` | string | Yes | `{sys.query}` | Search keywords. |
|
||||
| `top_n` | integer | No | 10 | Maximum number of returned results. |
|
||||
| Field | Type | Required | Default Value | Description |
|
||||
| --- | --- | --- | --- | --- |
|
||||
| query | string | Yes | `{sys.query}` | Search keywords. |
|
||||
| site | string | No | Empty | Limit results to a single domain, such as `techcrunch.com`. |
|
||||
| api_key | string | Node configuration | Empty | Optional Keenable API key. |
|
||||
| mode | string | Node configuration | pro | `pro` for deeper retrieval or `realtime` for low latency. `realtime` requires an API key. |
|
||||
| top_n | integer | Node configuration | 10 | Maximum number of results. |
|
||||
| KEENABLE_API_URL | Environment variable | Deployment configuration | `https://api.keenable.ai` | Service API base URL. Production environments must use HTTPS. Local loopback addresses can use HTTP. |
|
||||
|
||||
#### Configuration Example
|
||||
|
||||
```json
|
||||
{
|
||||
"query": "enterprise RAG deployment"
|
||||
}
|
||||
```
|
||||
| Configuration Item | Example Value |
|
||||
| --- | --- |
|
||||
| Query | RAGFlow Agent workflow |
|
||||
| Site | github.com |
|
||||
| API Key | |
|
||||
| Mode | pro |
|
||||
| Top N | 10 |
|
||||
| Keenable API URL | `https://api.keenable.ai` |
|
||||
|
||||
#### Output Result
|
||||
|
||||
The component returns search results that can be used by downstream Agent or Message components.
|
||||
The output contains search entries, summaries, and links returned by Keenable. It can be summarized by the Agent or passed to subsequent retrieval or extraction nodes. Do not set `realtime` for keyless trial runs.
|
||||
|
||||
|
||||
|
||||
|
||||
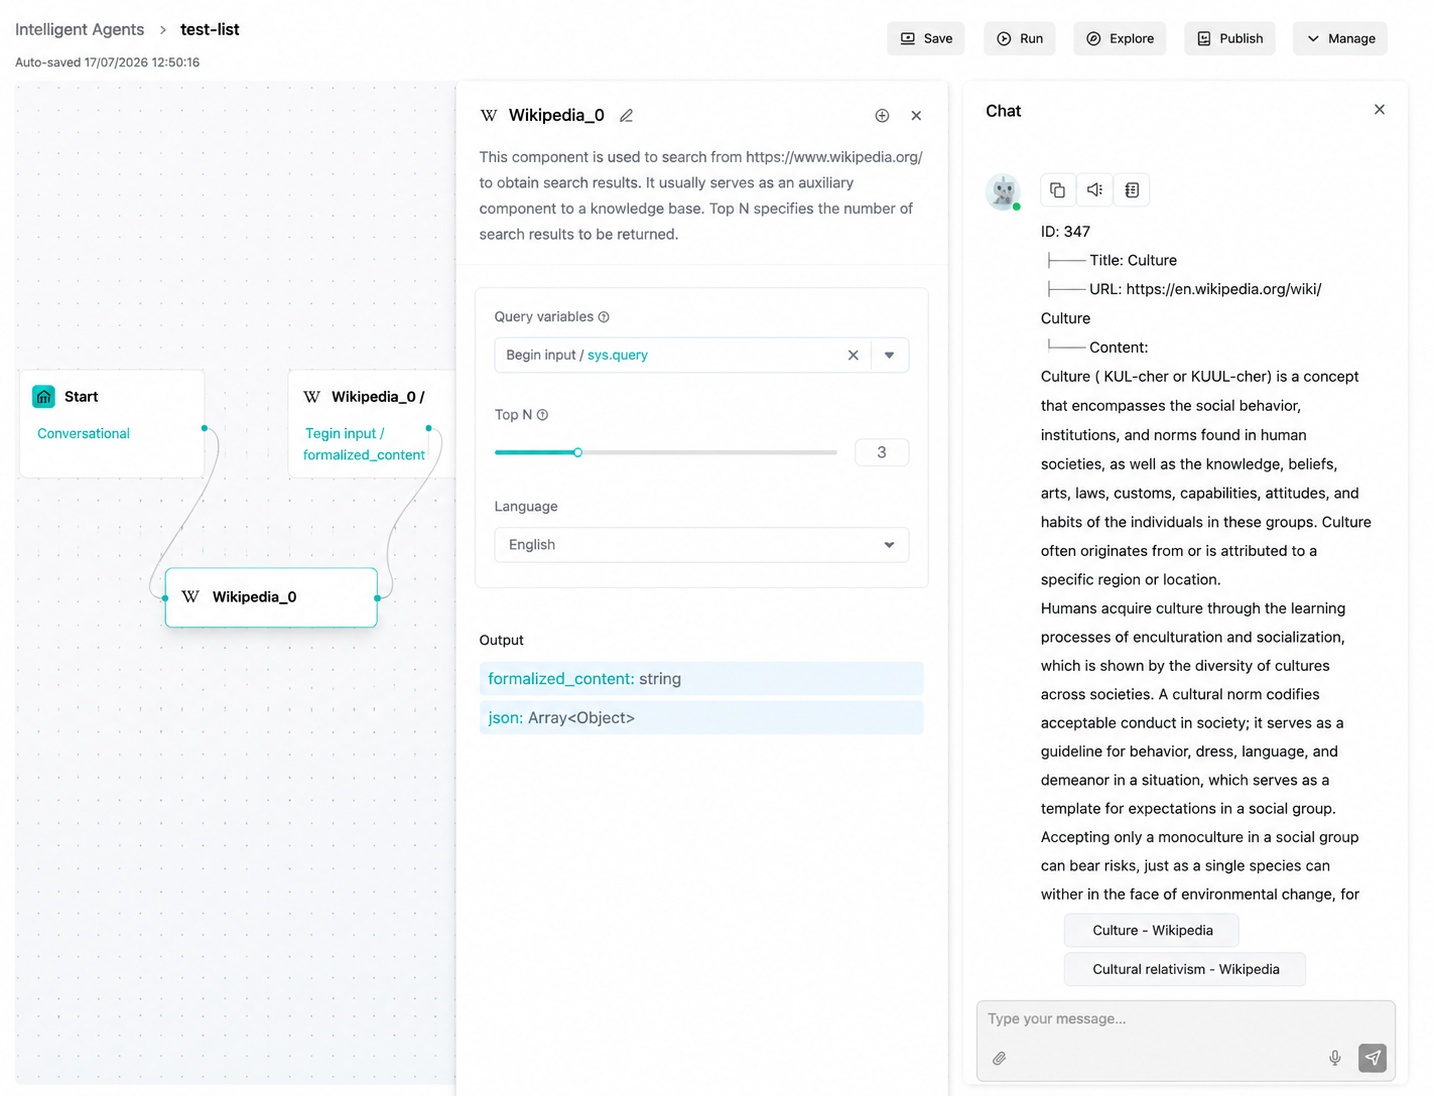
### Wikipedia (Wikipedia)
|
||||
|
||||
Wikipedia searches encyclopedia entries and extracts summaries. It is suitable for querying clear entities, concepts and historical events.
|
||||
The Wikipedia component searches encyclopedia entries and extracts entry summaries. It is suitable for querying clear entities, concepts, and historical events. Query terms should be as close as possible to the entry title.
|
||||
|
||||
#### Parameter Description
|
||||
|
||||
| Parameter | Type | Required | Default | Description |
|
||||
| ---- | ---- | ---- | ---- | ---- |
|
||||
| `query` | string | Yes | `{sys.query}` | Specific entry topic or keyword. |
|
||||
| `top_n` | integer | No | 10 | Maximum number of entries. |
|
||||
| `language` | string | No | `en` | Wikipedia language code, such as `zh`, `en` or `ja`. |
|
||||
| Field | Type | Required | Default Value | Description |
|
||||
| --- | --- | --- | --- | --- |
|
||||
| query | string | Yes | `{sys.query}` | Specific entry topic or keyword. |
|
||||
| top_n | integer | Node configuration | 10 | Maximum number of search entries. |
|
||||
| language | string | Node configuration | en | Wikipedia language code, such as `zh`, `en`, or `ja`. |
|
||||
|
||||
#### Configuration Example
|
||||
|
||||
```json
|
||||
{
|
||||
"query": "culture"
|
||||
}
|
||||
```
|
||||
| Configuration Item | Example Value |
|
||||
| --- | --- |
|
||||
| Query | culture |
|
||||
| Top N | 10 |
|
||||
| Language | en |
|
||||
|
||||
#### Output Result
|
||||
|
||||
The component returns matching entries, summaries and related metadata.
|
||||
The output contains the titles, summaries, and page links of matching entries. It is suitable for generating concept explanations or background descriptions with the Agent.
|
||||
|
||||
|
||||
|
||||
### GitHub (GitHub)
|
||||
|
||||
The GitHub component searches repositories through the GitHub Repository Search API and sorts by popularity by default. It is suitable for finding open-source projects, reference implementations, and technology ecosystems.
|
||||
|
||||
#### Parameter Description
|
||||
|
||||
| Field | Type | Required | Default Value | Description |
|
||||
| --- | --- | --- | --- | --- |
|
||||
| query | string | Yes | `{sys.query}` | GitHub repository search syntax or keywords. |
|
||||
| top_n | integer | Node configuration | 10 | Maximum number of returned repositories. |
|
||||
|
||||
#### Configuration Example
|
||||
|
||||
| Configuration Item | Example Value |
|
||||
| --- | --- |
|
||||
| Query | RAGFlow |
|
||||
| Top N | 10 |
|
||||
|
||||
#### Output Result
|
||||
|
||||
The output contains repository, issue, code, or user search entries, usually including names, links, summaries, update times, and other information. The output includes repository names, links, descriptions, and stars.
|
||||
|
||||
|
||||
|
||||
## Academic Literature Retrieval
|
||||
|
||||
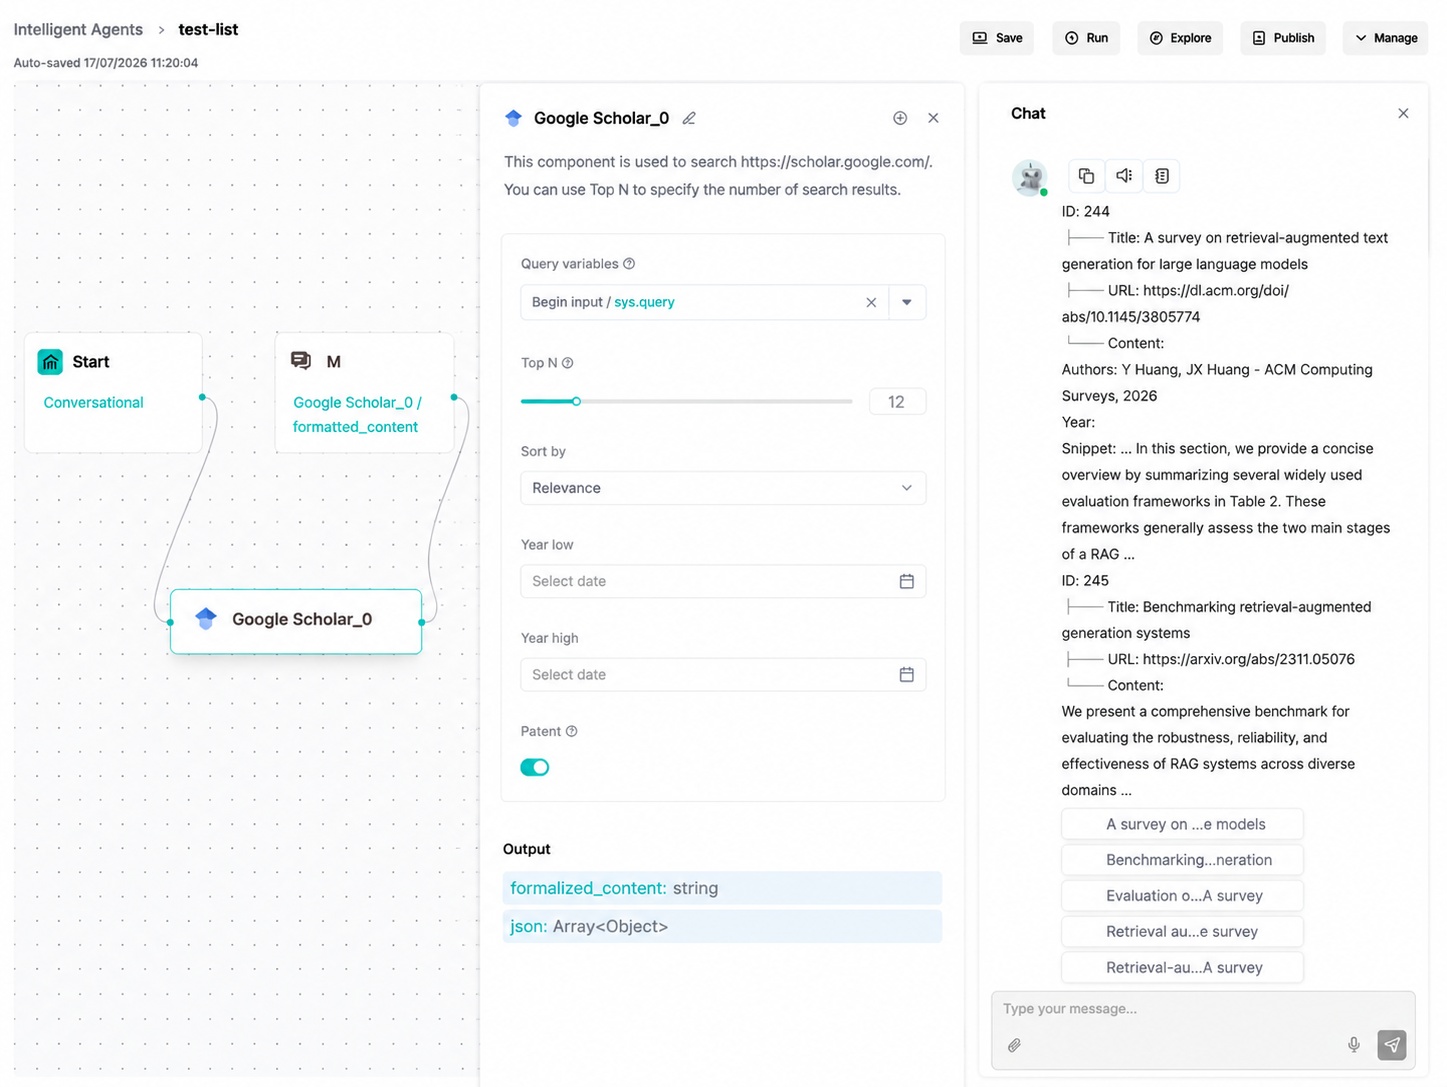
### Google Scholar (GoogleScholar)
|
||||
|
||||
Google Scholar retrieves papers, theses, books, abstracts and other academic materials. It is suitable for preliminary literature discovery and should not replace verification of original papers and citation details.
|
||||
Google Scholar is used to retrieve papers, dissertations, books, abstracts, and other academic materials. It is suitable for preliminary literature discovery before a research review, but should not replace verification of original texts and citation information.
|
||||
|
||||
#### Parameter Description
|
||||
|
||||
| Parameter | Type | Required | Default | Description |
|
||||
| ---- | ---- | ---- | ---- | ---- |
|
||||
| `query` | string | Yes | `{sys.query}` | Paper topic or keywords. |
|
||||
| `top_n` | integer | No | 12 | Maximum number of papers. |
|
||||
| `sort_by` | string | No | `relevance` | Sort method: `date` or `relevance`. |
|
||||
| `year_low` | integer/null | No | `null` | Earliest publication year. |
|
||||
| `year_high` | integer/null | No | `null` | Latest publication year. |
|
||||
| `patents` | boolean | No | `true` | Whether to include patents. |
|
||||
| Field | Type | Required | Default Value | Description |
|
||||
| --- | --- | --- | --- | --- |
|
||||
| query | string | Yes | `{sys.query}` | Paper topic or keyword. |
|
||||
| top_n | integer | Node configuration | 12 | Maximum number of papers. |
|
||||
| sort_by | string | Node configuration | relevance | Sorting method: `date` or `relevance`. |
|
||||
| year_low | integer/null | Node configuration | null | Earliest publication year. |
|
||||
| year_high | integer/null | Node configuration | null | Latest publication year. |
|
||||
| patents | boolean | Node configuration | true | Whether to include patents. |
|
||||
|
||||
#### Configuration Example
|
||||
|
||||
```json
|
||||
{
|
||||
"query": "retrieval augmented generation evaluation"
|
||||
}
|
||||
```
|
||||
| Configuration Item | Example Value |
|
||||
| --- | --- |
|
||||
| Query | retrieval augmented generation evaluation |
|
||||
| Top N | 12 |
|
||||
| Sort By | relevance |
|
||||
| Year Low | null |
|
||||
| Year High | null |
|
||||
| Patents | true |
|
||||
|
||||
#### Output Result
|
||||
|
||||
The component returns paper titles, authors, abstracts, links and related metadata when available.
|
||||
The output contains academic retrieval entries such as paper titles, authors, abstracts, source links, and citation information. It is suitable for literature reviews or research lead organization.
|
||||
|
||||
|
||||
|
||||
|
||||
### ArXiv (ArXiv)
|
||||
|
||||
ArXiv retrieves preprints from arXiv. It is suitable for computer science, mathematics, physics and related research scenarios.
|
||||
ArXiv is used to retrieve open preprints across fields such as computer science, mathematics, physics, and quantitative finance. ArXiv papers may not have undergone peer review, so mark their preprint nature when using the results.
|
||||
|
||||
#### Parameter Description
|
||||
|
||||
| Parameter | Type | Required | Default | Description |
|
||||
| ---- | ---- | ---- | ---- | ---- |
|
||||
| `query` | string | Yes | `{sys.query}` | Paper topic or keywords. |
|
||||
| `top_n` | integer | No | 10 | Maximum number of returned papers. |
|
||||
| Field | Type | Required | Default Value | Description |
|
||||
| --- | --- | --- | --- | --- |
|
||||
| query | string | Yes | `{sys.query}` | Retrieval keywords. |
|
||||
| top_n | integer | Node configuration | 12 | Maximum number of returned papers. |
|
||||
| sort_by | string | Node configuration | submittedDate | Sorting method: `submittedDate`, `lastUpdatedDate`, or `relevance`. |
|
||||
|
||||
#### Configuration Example
|
||||
|
||||
```json
|
||||
{
|
||||
"query": "large language model agents"
|
||||
}
|
||||
```
|
||||
| Configuration Item | Example Value |
|
||||
| --- | --- |
|
||||
| Query | large language model agents |
|
||||
| Top N | 12 |
|
||||
| Sort By | submittedDate |
|
||||
|
||||
#### Output Result
|
||||
|
||||
The component returns paper metadata such as title, authors, abstract, publication time and URL.
|
||||
|
||||
|
||||
The output contains paper titles, authors, abstracts, publication times, categories, and paper links. It can be used by the Agent to generate paper summaries or research comparisons.
|
||||
|
||||

|
||||
|
||||
### PubMed (PubMed)
|
||||
|
||||
PubMed retrieves biomedical and life science literature. It is suitable for medical, pharmaceutical and biological literature searches.
|
||||
PubMed is used to retrieve life science and biomedical literature. The component queries through NCBI E-utilities and returns titles, authors, journals, DOIs, abstracts, and other information.
|
||||
|
||||
#### Parameter Description
|
||||
|
||||
| Parameter | Type | Required | Default | Description |
|
||||
| ---- | ---- | ---- | ---- | ---- |
|
||||
| `query` | string | Yes | `{sys.query}` | Biomedical literature query. |
|
||||
| `top_n` | integer | No | 10 | Maximum number of returned papers. |
|
||||
| Field | Type | Required | Default Value | Description |
|
||||
| --- | --- | --- | --- | --- |
|
||||
| query | string | Yes | `{sys.query}` | PubMed search term. Medical subject headings or Boolean retrieval expressions are supported. |
|
||||
| top_n | integer | Node configuration | 12 | Maximum number of papers. |
|
||||
| email | string | Node configuration | `[email protected]` | NCBI Entrez contact email. Replace it with a real maintainer email in production. |
|
||||
|
||||
#### Configuration Example
|
||||
|
||||
```json
|
||||
{
|
||||
"query": "diabetes treatment guideline"
|
||||
}
|
||||
```
|
||||
| Configuration Item | Example Value |
|
||||
| --- | --- |
|
||||
| Query | COVID-19 vaccine effectiveness |
|
||||
| Top N | 12 |
|
||||
| Email | `[email protected]` |
|
||||
|
||||
#### Output Result
|
||||
|
||||
The component returns PubMed records, abstracts and publication metadata when available.
|
||||
|
||||
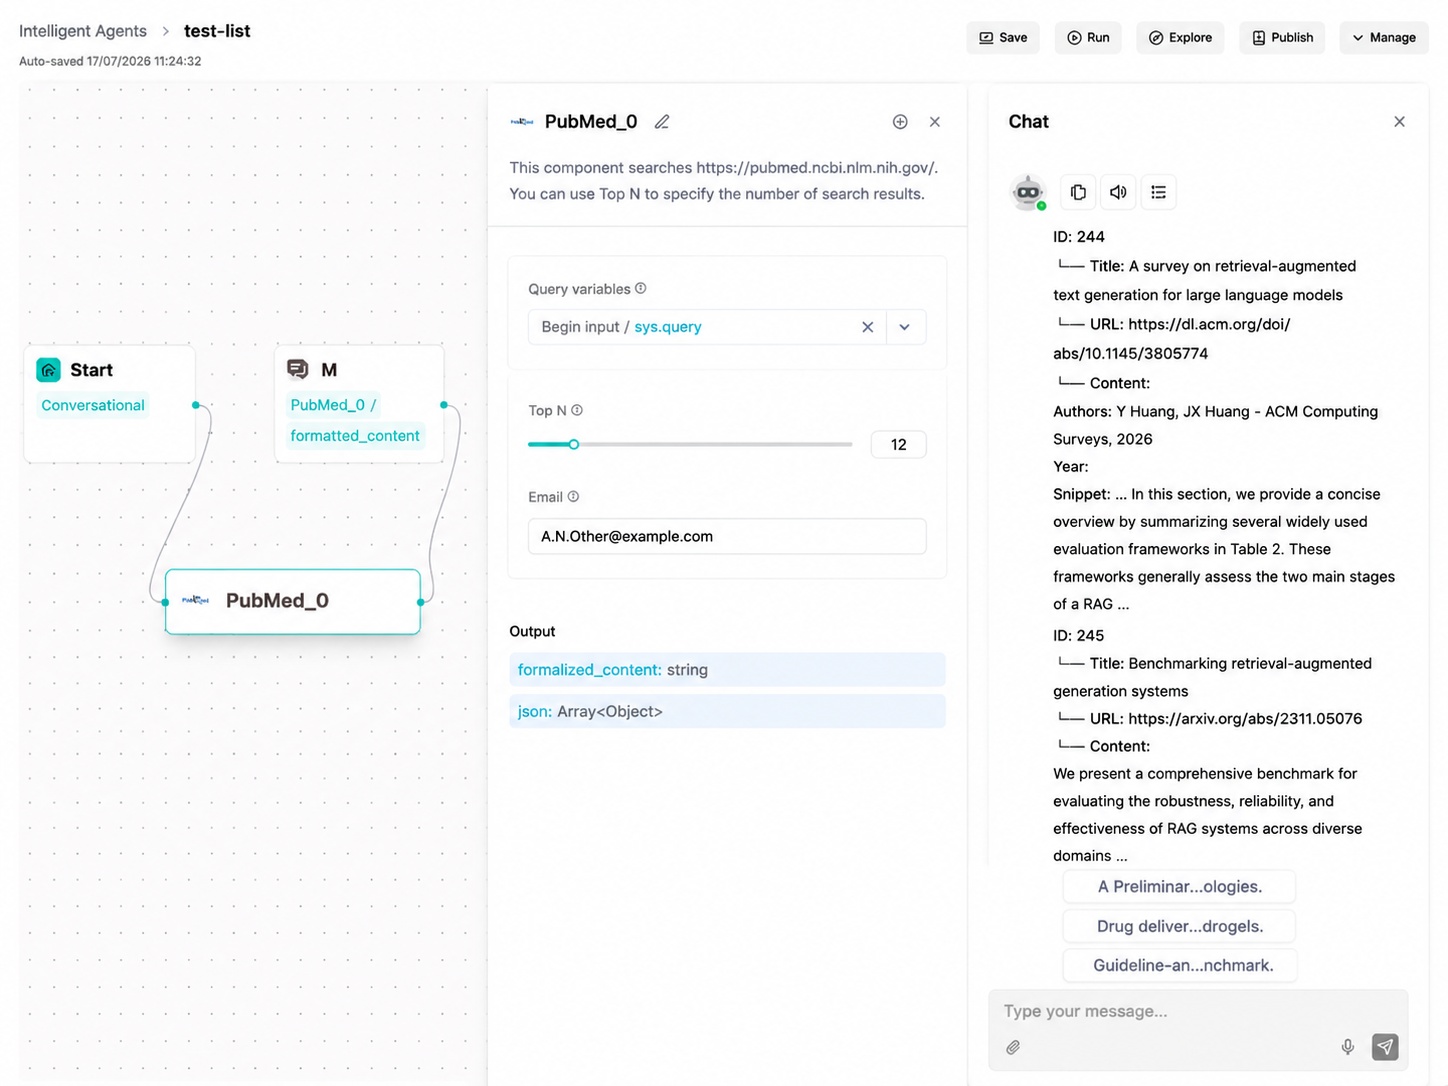
|
||||
The output contains medical literature titles, authors, journals, abstracts, publication dates, and PubMed links. It is suitable for medical literature retrieval scenarios.
|
||||
|
||||

|
||||
|
||||
### BGPT (BGPT)
|
||||
|
||||
BGPT is used for literature or biomedical-related retrieval scenarios supported by the configured BGPT service.
|
||||
BGPT retrieves scientific papers and returns structured evidence, including research methods, sample sizes, results, limitations, conflicts of interest, data availability, and falsifiability tips. It is suitable for evaluating scientific claims, not only for finding paper abstracts.
|
||||
|
||||
#### Parameter Description
|
||||
|
||||
| Parameter | Type | Required | Default | Description |
|
||||
| ---- | ---- | ---- | ---- | ---- |
|
||||
| `query` | string | Yes | `{sys.query}` | Query content. |
|
||||
| `top_n` | integer | No | 10 | Maximum number of returned results. |
|
||||
| Field | Type | Required | Default Value | Description |
|
||||
| --- | --- | --- | --- | --- |
|
||||
| query | string | Yes | `{sys.query}` | Natural-language scientific retrieval question. |
|
||||
| top_n | integer | Node configuration | 10 | Maximum number of results. |
|
||||
| api_key | string | Node configuration | Empty | Optional API key. If not configured, the public service path is used. |
|
||||
| days_back | integer/null | Node configuration | null | Optional. Limits retrieval to content from the most recent number of days. |
|
||||
|
||||
#### Configuration Example
|
||||
|
||||
```json
|
||||
{
|
||||
"query": "gene therapy review"
|
||||
}
|
||||
```
|
||||
| Configuration Item | Example Value |
|
||||
| --- | --- |
|
||||
| Query | Does sleep deprivation impair working memory in adults? |
|
||||
| Top N | 10 |
|
||||
| API Key | |
|
||||
| Days Back | null |
|
||||
|
||||
#### Output Result
|
||||
|
||||
The component returns retrieval results from the BGPT service for downstream reference.
|
||||
|
||||
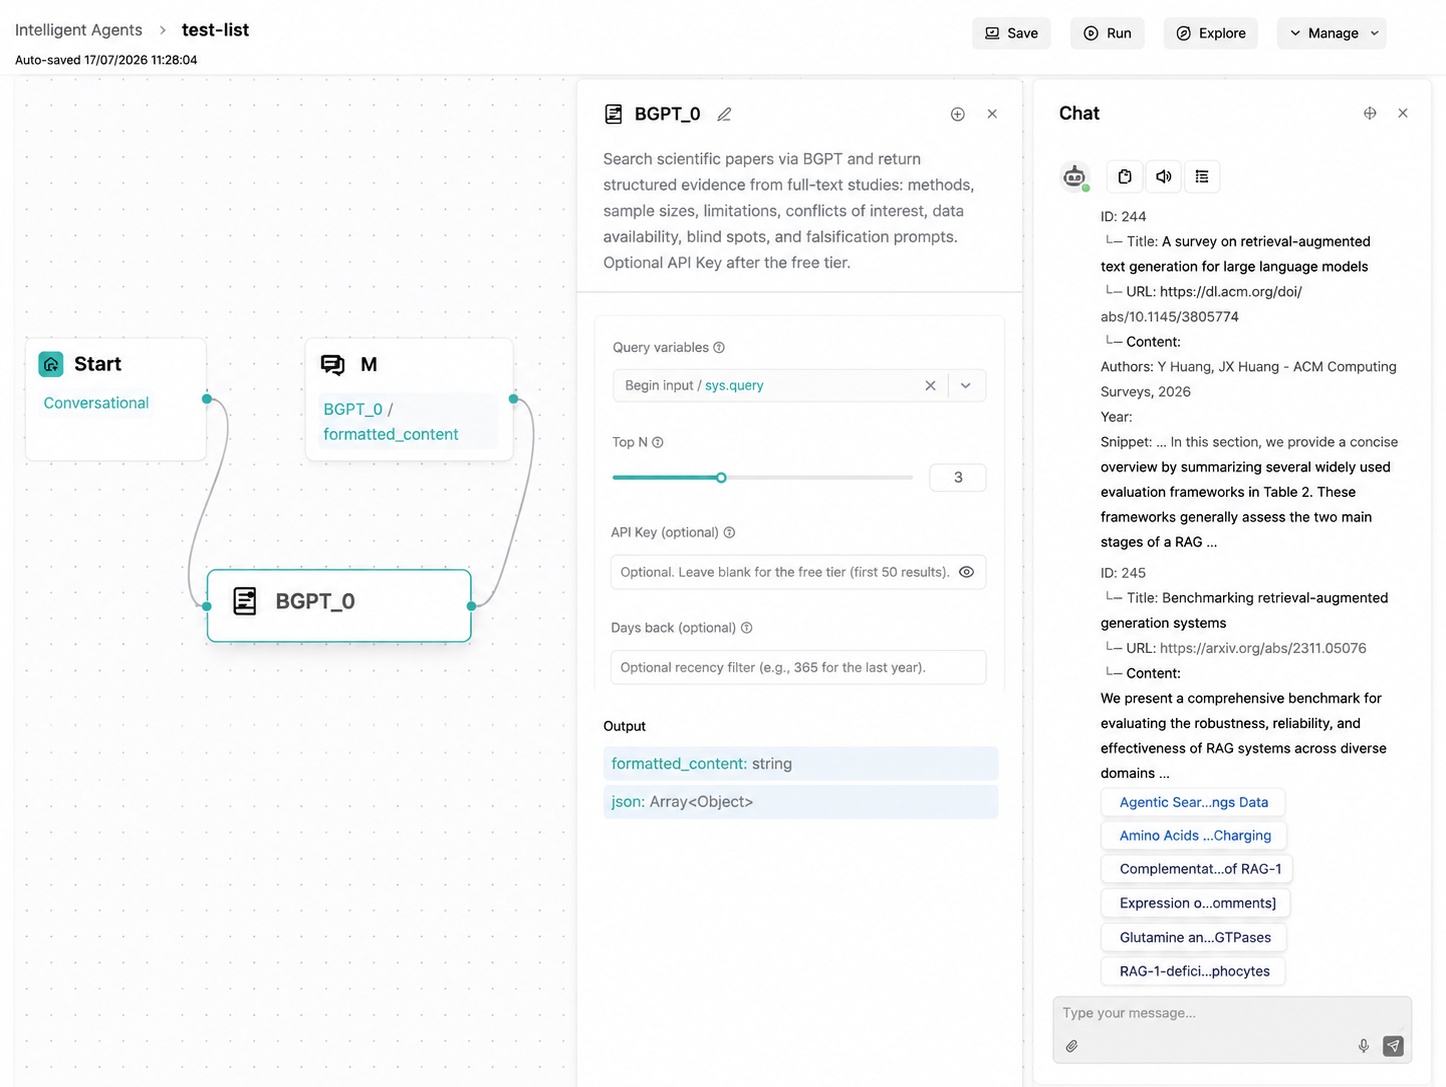
|
||||
The output contains biomedical knowledge retrieval results and summaries, which can be further summarized, compared, or used to generate research explanations by subsequent Agents.
|
||||
|
||||

|
||||
|
||||
## Data and Financial Queries
|
||||
|
||||
### Execute SQL (ExeSQL)
|
||||
|
||||
Execute SQL runs SQL queries against configured databases. It is suitable for structured data query, report generation and business data analysis.
|
||||
Execute SQL connects to an external database and executes SQL statements. The result is formatted as text or table content.
|
||||
|
||||
To protect system security, the database address must pass server-side security checks. To connect to a local or internal database, first confirm that the deployment environment allows access.
|
||||
|
||||
#### Parameter Description
|
||||
|
||||
| Parameter | Type | Required | Default | Description |
|
||||
| ---- | ---- | ---- | ---- | ---- |
|
||||
| `query` | string | Yes | Empty | SQL statement or natural-language query converted into SQL by the workflow. |
|
||||
| `db_type` | string | No | Empty | Database type. |
|
||||
| `database` | string | No | Empty | Target database or connection name. |
|
||||
| Field | Type | Required | Default Value | Description |
|
||||
| --- | --- | --- | --- | --- |
|
||||
| sql | string | Yes | `{sys.query}` | SQL to execute. Canvas variables can be included. |
|
||||
| db_type | string | Yes | mysql | Supports `mysql`, `postgres`, `mariadb`, `mssql`, `IBMDB2`, `trino`, and `oceanbase`. |
|
||||
| database | string | Yes | Empty | Database name. Trino uses `catalog.schema` or `catalog`. |
|
||||
| username | string | Yes | Empty | Database account. |
|
||||
| host | string | Yes | Empty | Database address, which must pass server-side security checks. |
|
||||
| port | integer | Yes | 3306 | Database port. |
|
||||
| password | string | Conditionally required | Empty | Database password. It can be empty for Trino. |
|
||||
| max_records | integer | No | 1024 | Maximum number of records returned per statement. |
|
||||
|
||||
#### Supported Values
|
||||
|
||||
Supported database types depend on the current deployment and configured connections.
|
||||
| Parameter | Supported Value | Description |
|
||||
| --- | --- | --- |
|
||||
| Database Type | mysql | MySQL |
|
||||
| Database Type | postgres | PostgreSQL |
|
||||
| Database Type | mariadb | MariaDB |
|
||||
| Database Type | mssql | Microsoft SQL Server |
|
||||
| Database Type | IBMDB2 | IBM DB2 |
|
||||
| Database Type | trino | Trino |
|
||||
| Database Type | oceanbase | OceanBase |
|
||||
|
||||
#### Configuration Example
|
||||
|
||||
```json
|
||||
{
|
||||
"query": "select count(*) from orders"
|
||||
}
|
||||
```
|
||||
| Configuration Item | Example Value |
|
||||
| --- | --- |
|
||||
| SQL | `SELECT * FROM XXX;` |
|
||||
| Database Type | mysql |
|
||||
| Database | demo_sql |
|
||||
| Username | ragflow_reader |
|
||||
| Host | `<host>` |
|
||||
| Port | 3306 |
|
||||
| Password | `<read-only database account password>` |
|
||||
| Max Records | 10 |
|
||||
|
||||
#### Output Result
|
||||
|
||||
The component returns query results, error information or structured rows for downstream components.
|
||||
The output contains SQL execution results, field names, and record content. You can pass formatted text to the Agent for explanation, or let subsequent nodes read structured results.
|
||||
|
||||
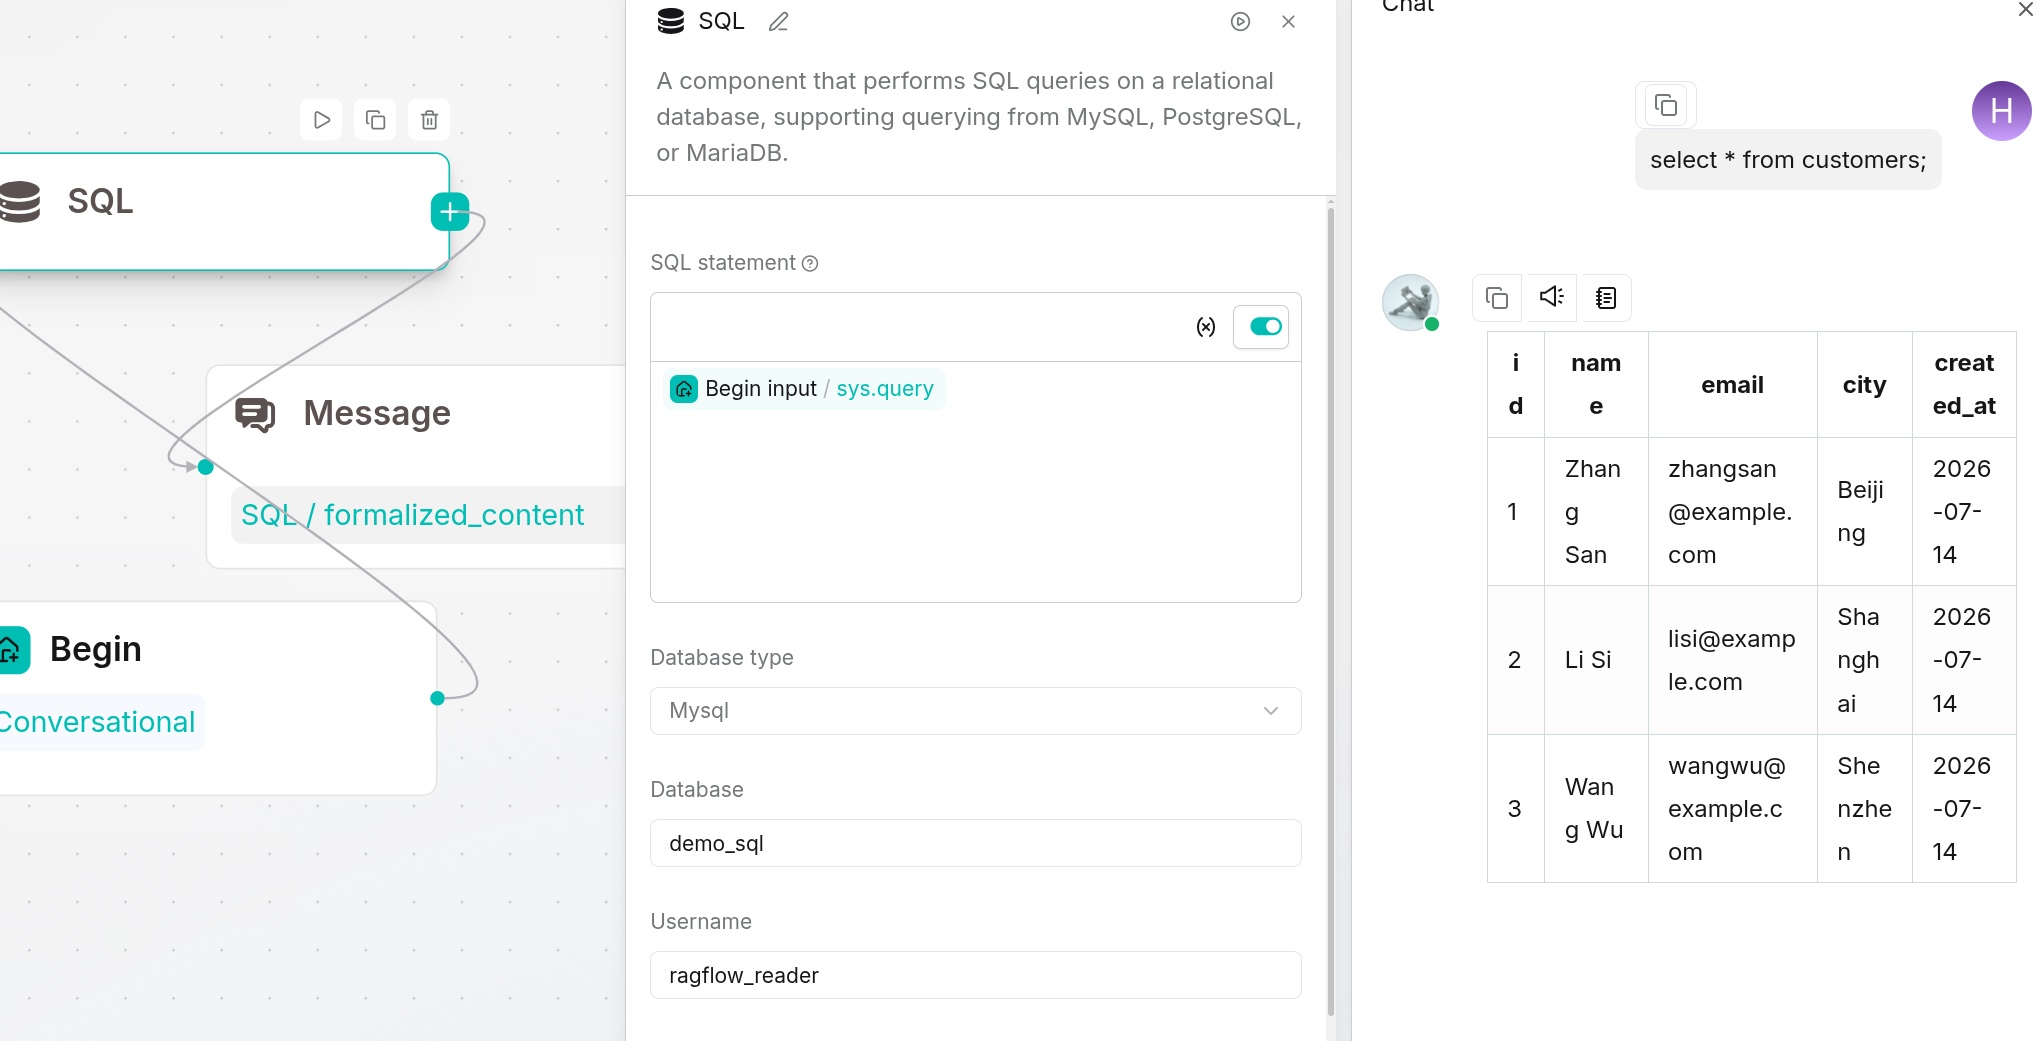
|
||||
|
||||
|
||||
### Yahoo Finance (YahooFinance)
|
||||
|
||||
Yahoo Finance queries market and financial information. It is suitable for stocks, funds, indexes and other market data supported by the service.
|
||||
The Yahoo Finance component queries stock quotes, company profiles, historical market data, financial statements, and news through `yfinance`, and outputs the selected content as a Markdown report.
|
||||
|
||||
#### Parameter Description
|
||||
|
||||
| Parameter | Type | Required | Default | Description |
|
||||
| ---- | ---- | ---- | ---- | ---- |
|
||||
| `ticker` | string | Yes | Empty | Stock, fund or index symbol. |
|
||||
| `query` | string | No | `{sys.query}` | Natural-language financial query. |
|
||||
| `top_n` | integer | No | 10 | Maximum number of returned results. |
|
||||
| Field | Type | Required | Default Value | Description |
|
||||
| --- | --- | --- | --- | --- |
|
||||
| stock_code | string | Yes | `{sys.query}` | Stock code or company name. Use exchange-standard codes when possible. |
|
||||
| info | boolean | Node configuration | true | Output company and quote information. |
|
||||
| history | boolean | Node configuration | false | Output historical market data. |
|
||||
| count | boolean | Node configuration | false | Share count switch defined by the code. |
|
||||
| financials | boolean | Node configuration | false | The current implementation outputs calendar information. |
|
||||
| income_stmt | boolean | Node configuration | false | Income statement switch defined by the code. |
|
||||
| balance_sheet | boolean | Node configuration | false | Output balance sheet and quarterly balance sheet. |
|
||||
| cash_flow_statement | boolean | Node configuration | false | Output cash flow statement and quarterly cash flow statement. |
|
||||
| news | boolean | Node configuration | true | Output related news. |
|
||||
|
||||
#### Supported Values
|
||||
|
||||
Symbols and markets depend on Yahoo Finance data availability.
|
||||
| Parameter | Supported Value | Description |
|
||||
| --- | --- | --- |
|
||||
|
||||
#### Configuration Example
|
||||
|
||||
```json
|
||||
{
|
||||
"ticker": "AAPL"
|
||||
}
|
||||
```
|
||||
| Configuration Item | Example Value |
|
||||
| --- | --- |
|
||||
| Stock Code | AAPL |
|
||||
| Info | true |
|
||||
| History | false |
|
||||
| Count | false |
|
||||
| Financials | false |
|
||||
| Income Statement | false |
|
||||
| Balance Sheet | false |
|
||||
| Cash Flow Statement | false |
|
||||
| News | true |
|
||||
|
||||
#### Output Result
|
||||
|
||||
The component returns financial data, market summaries or related metadata.
|
||||
The output contains a financial query report and structured market data, which can be used by subsequent Agents to generate market overviews or indicator explanations.
|
||||
|
||||
### WenCai (WenCai)
|
||||
|
||||
WenCai performs financial data screening through natural-language conditions, covering stocks, indexes, funds, Hong Kong stocks, U.S. stocks, futures and other query types.
|
||||
WenCai is used to screen financial data such as stocks, indices, funds, Hong Kong stocks, U.S. stocks, futures, and other instruments based on natural-language conditions.
|
||||
|
||||
#### Parameter Description
|
||||
|
||||
| Parameter | Type | Required | Default | Description |
|
||||
| ---- | ---- | ---- | ---- | ---- |
|
||||
| `query` | string | Yes | `{sys.query}` | Stock selection or financial condition, such as "A-shares with P/E ratio below 20". |
|
||||
| `top_n` | integer | No | 10 | Maximum number of results. |
|
||||
| `query_type` | string | No | `stock` | Query type. |
|
||||
| Field | Type | Required | Default Value | Description |
|
||||
| --- | --- | --- | --- | --- |
|
||||
| query | string | Yes | `{sys.query}` | Stock selection or financial condition, such as "A-shares with P/E ratio below 20". |
|
||||
| top_n | integer | Node configuration | 10 | Maximum number of results. The frontend default may be 20. |
|
||||
| query_type | string | Node configuration | stock | Supports `stock`, `zhishu`, `fund`, `hkstock`, `usstock`, `threeboard`, `conbond`, `insurance`, `futures`, `lccp`, and `foreign_exchange`. |
|
||||
|
||||
#### Supported Query Types
|
||||
|
||||
`stock`, `zhishu`, `fund`, `hkstock`, `usstock`, `threeboard`, `conbond`, `insurance`, `futures`, `lccp`, `foreign_exchange`.
|
||||
| Type | Description |
|
||||
| --- | --- |
|
||||
| stock | A-share stocks |
|
||||
| zhishu | Indices |
|
||||
| fund | Funds |
|
||||
| hkstock | Hong Kong stocks |
|
||||
| usstock | U.S. stocks |
|
||||
| threeboard | NEEQ |
|
||||
| conbond | Convertible bonds |
|
||||
| insurance | Insurance |
|
||||
| futures | Futures |
|
||||
| lccp | Wealth management products |
|
||||
| foreign_exchange | Foreign exchange |
|
||||
|
||||
#### Configuration Example
|
||||
|
||||
```json
|
||||
{
|
||||
"query": "A-shares with P/E ratio below 20 and net profit growth above 20%"
|
||||
}
|
||||
```
|
||||
| Configuration Item | Example Value |
|
||||
| --- | --- |
|
||||
| Query | A-shares with P/E ratio below 20 and net profit YoY growth above 20% |
|
||||
| Top N | 10 |
|
||||
| Query Type | stock |
|
||||
|
||||
#### Output Result
|
||||
|
||||
The component returns matched financial instruments and related fields. In some versions, the runtime may return an empty report if the actual WenCai call is disabled.
|
||||
The output contains a financial data list that matches the natural-language screening condition. It can be used for displaying stock selection results, subsequent filtering, or Agent explanation.
|
||||
|
||||
:::tip NOTE
|
||||
|
||||
Before using the WenCai component, confirm that the WenCai query service is available in the current environment. If the service is not enabled, the component will not return real financial data.
|
||||
|
||||
:::
|
||||
|
||||
## Communication and External Systems
|
||||
|
||||
### Email
|
||||
|
||||
The Email component sends emails through configured mail service parameters. It is suitable for notification, approval, report delivery and workflow result distribution.
|
||||
The Email component sends HTML emails through SMTP and supports multiple CC addresses. The current version supports recipients, CC recipients, subject, and email body. It does not support adding attachments or BCC recipients through this component.
|
||||
|
||||
#### Parameter Description
|
||||
|
||||
| Parameter | Type | Required | Default | Description |
|
||||
| ---- | ---- | ---- | ---- | ---- |
|
||||
| `to` | string/list | Yes | Empty | Recipient address or addresses. |
|
||||
| `subject` | string | Yes | Empty | Email subject. |
|
||||
| `content` | string | Yes | Empty | Email body. |
|
||||
| `attachments` | array | No | Empty | Attachment variables or file references. |
|
||||
| Field | Type | Required | Default Value | Description |
|
||||
| --- | --- | --- | --- | --- |
|
||||
| to_email | string | Yes | `{sys.query}` | Recipient email address. |
|
||||
| cc_email | string | No | Empty | CC email addresses. Separate multiple addresses with English commas. |
|
||||
| content | string | No | Empty | Email body, sent as HTML content. |
|
||||
| subject | string | No | Empty | Email subject. |
|
||||
| smtp_server | string | Node configuration | Empty | SMTP server address. |
|
||||
| smtp_port | integer | Node configuration | 465 | SMTP port. Port 465 uses SSL, and other ports use STARTTLS. |
|
||||
| email | string | Node configuration | Empty | Sender email address. |
|
||||
| smtp_username | string | Node configuration | Empty | SMTP login account. If empty, the sender email address is used. |
|
||||
| password | string | Node configuration | Empty | SMTP authorization code or password. |
|
||||
| sender_name | string | Node configuration | Empty | Sender display name. |
|
||||
|
||||
:::tip NOTE
|
||||
|
||||
Although some SMTP fields are displayed as optional in the UI, a valid SMTP service address, sender account, and authentication information must be provided before sending email.
|
||||
|
||||
:::
|
||||
|
||||
#### Configuration Example
|
||||
|
||||
```json
|
||||
{
|
||||
"to": "us[email protected]",
|
||||
"subject": "Workflow result",
|
||||
"content": "Please check the generated result."
|
||||
}
|
||||
```
|
||||
| Configuration Item | Example Value |
|
||||
| --- | --- |
|
||||
| To Email | receiver@example.com |
|
||||
| CC Email | |
|
||||
| Content | `<p>This is a test email sent by RAGFlow.</p>` |
|
||||
| Subject | RAGFlow email tool test |
|
||||
| SMTP Server | |
|
||||
| SMTP Port | 465 |
|
||||
| Email | |
|
||||
| SMTP Username | |
|
||||
| Password | |
|
||||
| Sender Name | |
|
||||
|
||||
#### Output Result
|
||||
|
||||
The component returns send status and error information when sending fails.
|
||||
The output contains sending status and error information. `success` being `true` means the email was sent successfully. If sending fails, check the SMTP address, account, password, and recipient.
|
||||
|
||||
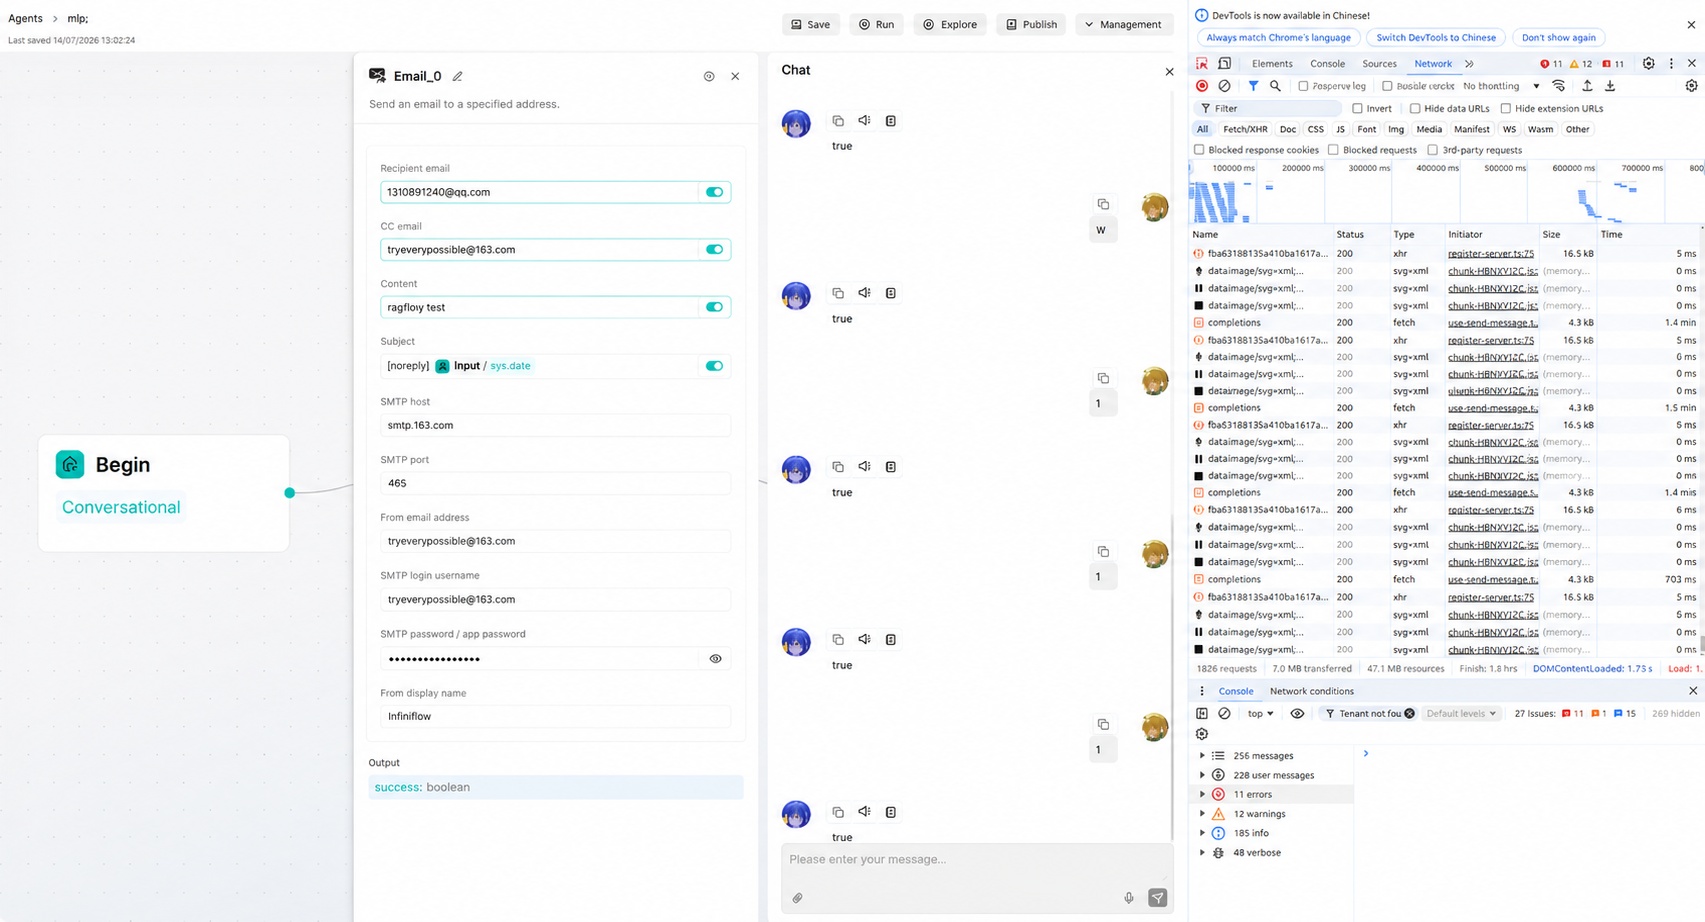
|
||||
|
||||
|
||||
### HTTP Request (Invoke)
|
||||
|
||||
HTTP Request calls external HTTP interfaces. It is suitable for querying order status, writing work orders, triggering third-party services and integrating business systems.
|
||||
The HTTP Request component calls external HTTP APIs, allowing business systems, third-party services, or self-built APIs to be connected to Agent workflows.
|
||||
|
||||
#### Parameter Description
|
||||
|
||||
| Parameter | Type | Required | Default | Description |
|
||||
| ---- | ---- | ---- | ---- | ---- |
|
||||
| `url` | string | Yes | Empty | Request URL. |
|
||||
| `method` | string | No | `GET` | HTTP method. |
|
||||
| `headers` | string/object | No | `{}` | Request headers. |
|
||||
| `variables` | array | No | Empty | Variables passed into the request. |
|
||||
| `timeout` | integer | No | 60 | Request timeout in seconds. |
|
||||
| `proxy` | string | No | Empty | Optional HTTP/HTTPS proxy address. |
|
||||
| `clean_html` | boolean | No | `false` | Whether to clean HTML tags from the response. |
|
||||
| `datatype` | string | No | `json` | Python request body type: `json` or `formdata`. |
|
||||
| `body` | string | No | Empty | Raw request body supported by the Go runtime. |
|
||||
| `content_type` | string | No | Empty | Content-Type in the Go runtime; POST/PUT defaults to `application/json`. |
|
||||
| Field | Type | Required | Default Value | Description |
|
||||
| --- | --- | --- | --- | --- |
|
||||
| url | string | Yes | Empty | API address. Canvas variables can be used. The Python implementation can add `http://` to addresses with missing protocols, while the Go implementation requires `http://` or `https://` explicitly. |
|
||||
| method | string | Yes | get | Python supports `get`, `post`, and `put`; the Go implementation also supports `DELETE`. |
|
||||
| headers | string/object | No | Empty | Request headers in JSON object format. Variables can be used in values. |
|
||||
| variables | array[object] | No | `[]` | Request parameter list. Each item usually contains `key`, `value`, and `ref`. |
|
||||
| timeout | integer | No | 60 | Request timeout in seconds. The Go default is 30 seconds. |
|
||||
| proxy | string | No | Empty | Optional HTTP/HTTPS proxy address. |
|
||||
| clean_html | boolean | No | false | Whether to clean HTML tags from the response. |
|
||||
| datatype | string | No | json | Python request body type: `json` or `formdata`. |
|
||||
| body | string | No | Empty | Raw request body supported by the Go runtime. |
|
||||
| content_type | string | No | Empty | Go runtime `Content-Type`; POST/PUT default to `application/json`. |
|
||||
|
||||
#### Supported Values
|
||||
|
||||
- `method`: `GET`, `POST`, `PUT`, `DELETE`, `PATCH`
|
||||
- `datatype`: `json`, `formdata`
|
||||
| Parameter | Supported Value | Description |
|
||||
| --- | --- | --- |
|
||||
| Method | GET | GET request. |
|
||||
| Method | POST | POST request. |
|
||||
| Method | PUT | PUT request. |
|
||||
| Proxy | HTTP | HTTP proxy. |
|
||||
| Proxy | HTTPS | HTTPS proxy address. |
|
||||
|
||||
#### Configuration Example
|
||||
|
||||
```json
|
||||
{
|
||||
"url": "https://1.1.1.1/cdn-cgi/trace",
|
||||
"method": "GET",
|
||||
"timeout": 30,
|
||||
"headers": "{}",
|
||||
"proxy": "",
|
||||
"clean_html": false,
|
||||
"datatype": "json",
|
||||
"variables": []
|
||||
}
|
||||
```
|
||||
| Configuration Item | Example Value |
|
||||
| --- | --- |
|
||||
| URL | `https://1.1.1.1/cdn-cgi/trace` |
|
||||
| Method | GET |
|
||||
| Headers | `{}` |
|
||||
| Variables | `[]` |
|
||||
| Timeout | 30 |
|
||||
| Proxy | |
|
||||
| Clean HTML | false |
|
||||
| Data Type | json |
|
||||
| Body | |
|
||||
| Content Type | |
|
||||
|
||||
#### Output Result
|
||||
|
||||
The component returns HTTP response content, status information and error details for downstream processing.
|
||||
The output contains response status code, response headers, and response body. Text responses can be passed to the Agent for summarization, while JSON responses can be read by subsequent nodes.
|
||||
|
||||
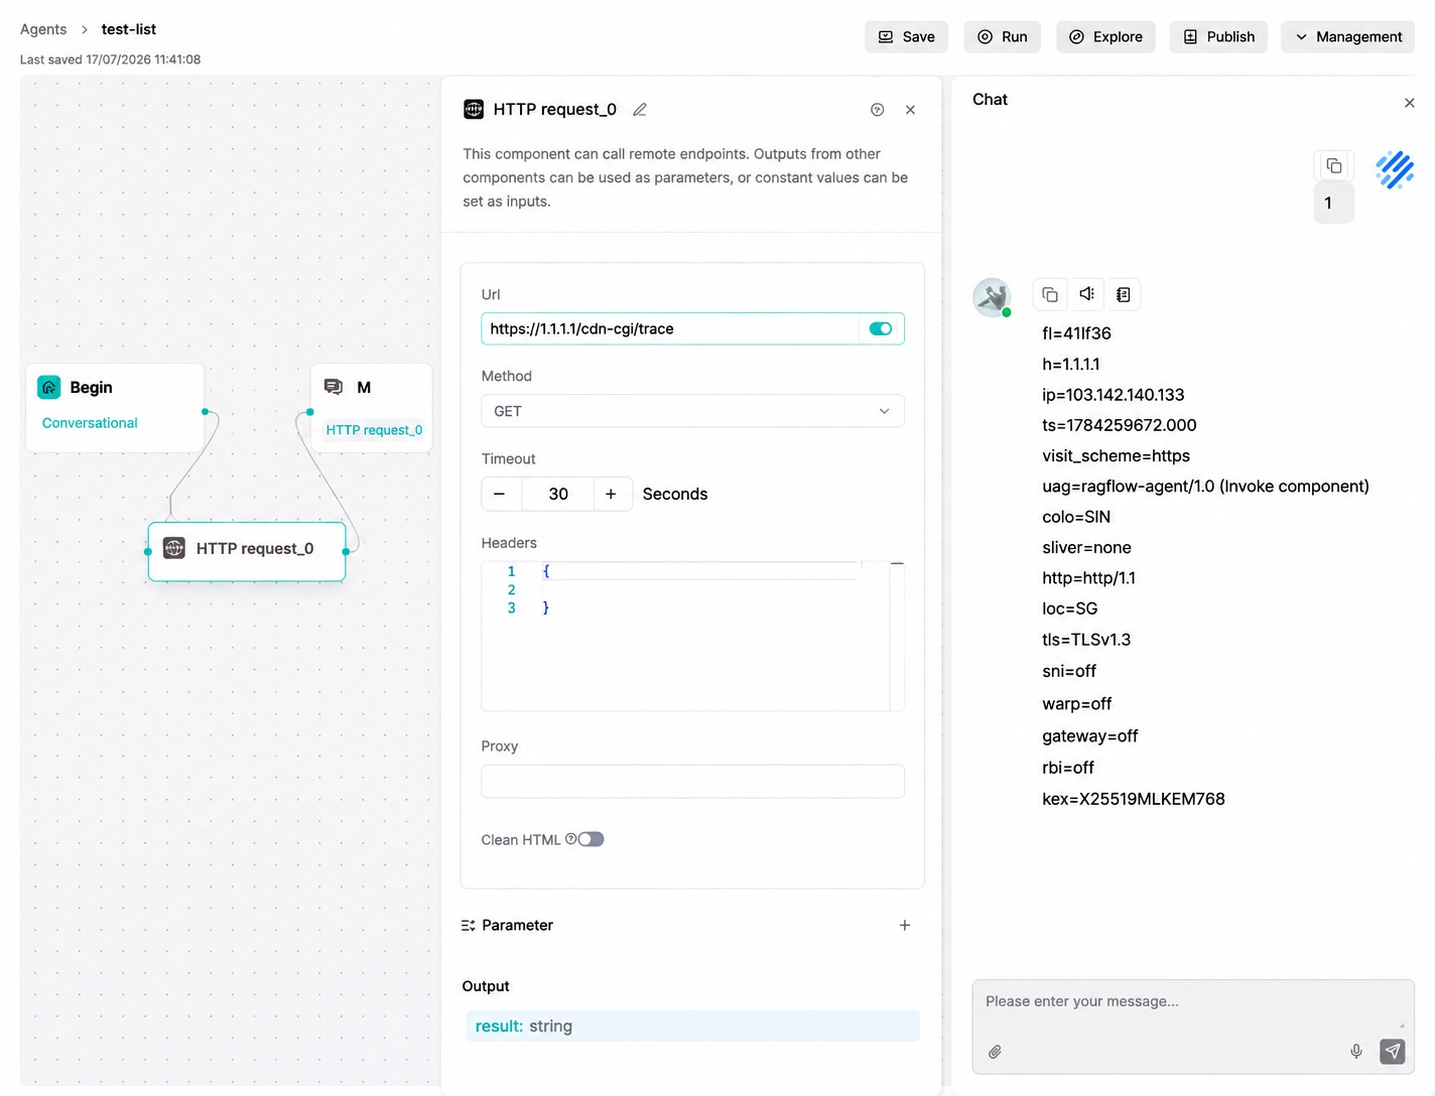
|
||||
|
||||
|
||||
## Content Generation and Automation
|
||||
|
||||
### Document Generator (DocGenerator)
|
||||
|
||||
Document Generator creates documents from workflow inputs and templates. It is suitable for reports, contracts, summaries and structured document output.
|
||||
The Document Generator component outputs Markdown content as PDF, DOCX, TXT, Markdown, or HTML files, and stores the generated files in Agent attachment storage.
|
||||
|
||||
#### Parameter Description
|
||||
|
||||
| Parameter | Type | Required | Default | Description |
|
||||
| ---- | ---- | ---- | ---- | ---- |
|
||||
| `content` | string | Yes | Empty | Document content or template-filled content. |
|
||||
| `output_format` | string | No | Empty | Output file format. |
|
||||
| `filename` | string | No | Empty | Generated file name. |
|
||||
| Field | Type | Required | Default Value | Description |
|
||||
| --- | --- | --- | --- | --- |
|
||||
| content | string | Yes | Empty | Markdown content to generate. Upstream outputs can be referenced. |
|
||||
| output_format | string | Yes | pdf | Output format: `pdf`, `docx`, `txt`, `markdown`, or `html`. |
|
||||
| filename | string | No | Empty | File name. If empty, it is generated automatically, and illegal file name characters are cleaned. |
|
||||
| header_text | string | No | Empty | Header text. Applies to PDF/DOCX. |
|
||||
| footer_text | string | No | Empty | Footer text. Applies to PDF/DOCX. |
|
||||
| watermark_text | string | No | Empty | Watermark text. Supported by PDF/DOCX/HTML according to the implementation. |
|
||||
| add_page_numbers | boolean | No | true | Whether to add page numbers. Mainly used for PDF/DOCX. |
|
||||
| add_timestamp | boolean | No | true | Whether to add generation time. |
|
||||
| include_download_info_in_content | boolean | No | false | Whether to keep the download information marker in the content. |
|
||||
| font_size | number | No | 12 | Font size, which must be greater than or equal to 12. |
|
||||
|
||||
#### Supported Values
|
||||
|
||||
Supported output formats depend on the current deployment and component configuration.
|
||||
| Parameter | Supported Value | Description |
|
||||
| --- | --- | --- |
|
||||
| Output Format | pdf | PDF document. |
|
||||
| Output Format | docx | Word document. |
|
||||
| Output Format | html | HTML document. |
|
||||
| Output Format | txt | Text file. |
|
||||
| Output Format | markdown | Markdown file. |
|
||||
| Font Size | >=12 | Font size must be greater than or equal to 12. |
|
||||
|
||||
#### Configuration Example
|
||||
|
||||
```json
|
||||
{
|
||||
"content": "Generate a weekly report based on the workflow result.",
|
||||
"output_format": "docx",
|
||||
"filename": "weekly_report"
|
||||
}
|
||||
```
|
||||
| Configuration Item | Example Value |
|
||||
| --- | --- |
|
||||
| Content | `# RAGFlow Agent
|
||||
Test This document is generated by the DocGenerator component.` |
|
||||
| Output Format | pdf |
|
||||
| Filename | ragflow-agent-test.pdf |
|
||||
| Header Text | RAGFlow |
|
||||
| Footer Text | Internal Test |
|
||||
| Watermark Text | DRAFT |
|
||||
| Add Page Numbers | true |
|
||||
| Add Timestamp | true |
|
||||
| Include Download Info In Content | false |
|
||||
| Font Size | 12 |
|
||||
|
||||
#### Output Result
|
||||
|
||||
The component returns generated file information and downloadable output variables.
|
||||
The output contains generated file attachment information, download links, and file names. Users can preview, download, or pass the file to subsequent nodes for further processing.
|
||||
|
||||
|
||||
|
||||
### Browser (Browser)
|
||||
|
||||
### Browser
|
||||
|
||||
Browser performs browser-based automation tasks. It is suitable for opening pages, collecting page information and executing browser workflows that require visual interaction.
|
||||
Browser is an LLM-driven browser automation component. It can access web pages, perform multi-step operations, read page content, upload source files, and collect downloaded files based on natural-language tasks. It depends on the configured model and the browser automation dependencies in the runtime environment.
|
||||
|
||||
#### Parameter Description
|
||||
|
||||
| Parameter | Type | Required | Default | Description |
|
||||
| ---- | ---- | ---- | ---- | ---- |
|
||||
| `task` | string | Yes | Empty | Browser automation task description. |
|
||||
| `url` | string | No | Empty | Initial page URL. |
|
||||
| `timeout` | integer | No | Empty | Task timeout. |
|
||||
| Field | Type | Required | Default Value | Description |
|
||||
| --- | --- | --- | --- | --- |
|
||||
| llm_id | string | Yes | Empty | Configured chat model ID used by Browser. The Go path can accept `model_id` as an alias. |
|
||||
| prompts | string | Yes | `{sys.query}` | Natural-language browser task. Canvas variables are supported. The Go path can accept `prompt` as an alias. |
|
||||
| max_steps | integer | No | 30 | Maximum number of browser execution steps. Effective in the Python path. The current Go Stagehand path accepts this field but does not use it during execution. |
|
||||
| headless | boolean | No | true | Whether to run the browser in headless mode. |
|
||||
| enable_default_extensions | boolean | No | false | Whether to enable default `browser-use` extensions. |
|
||||
| chromium_sandbox | boolean | No | false | Whether to enable the Chromium sandbox. In Docker root environments, keep this disabled in general. |
|
||||
| persist_session | boolean | No | true | Whether to reuse the browser user directory for the same node. Effective in the Python path. |
|
||||
| upload_sources | array/string | No | `[]` | File IDs, URLs, or upstream variable references for the browser task. |
|
||||
| url | string | No | Empty | Compatibility field accepted by the current Go component. It does not participate in Stagehand execution. |
|
||||
| timeout | integer | No | 0 | Compatibility field accepted by the current Go component. It does not participate in Stagehand execution. |
|
||||
|
||||
#### Supported Values
|
||||
|
||||
Supported browser actions depend on the current deployment and browser automation capability.
|
||||
| Parameter | Supported Value | Description |
|
||||
| --- | --- | --- |
|
||||
| Upload Sources | File ID | File ID uploaded to RAGFlow. |
|
||||
| Upload Sources | URL | Accessible file or web page URL. |
|
||||
| Upload Sources | Upstream variable reference | File or resource reference from a previous node. |
|
||||
|
||||
#### Configuration Example
|
||||
|
||||
```json
|
||||
{
|
||||
"url": "https://example.com",
|
||||
"task": "Open the page and extract the main content."
|
||||
}
|
||||
```
|
||||
| Configuration Item | Example Value |
|
||||
| --- | --- |
|
||||
| LLM ID | `<configured chat model ID>` |
|
||||
| Prompt | Open https://www.ragflow.io, identify the main navigation items, and return them as a concise bullet list. |
|
||||
| Max Steps | 10 |
|
||||
| Headless | true |
|
||||
| Enable Default Extensions | false |
|
||||
| Chromium Sandbox | false |
|
||||
| Persist Session | true |
|
||||
| Upload Sources | `[]` |
|
||||
| URL | |
|
||||
| Timeout | 0 |
|
||||
|
||||
#### Output Result
|
||||
|
||||
The component returns browser execution results, extracted content or error information.
|
||||
The output contains the browser task execution summary, extracted page content, and any generated download file information. Avoid assigning Browser tasks that involve login, payment, or irreversible submissions.
|
||||
|
||||
@@ -0,0 +1,62 @@
|
||||
---
|
||||
sidebar_position: 3
|
||||
title: Creation and Management
|
||||
sidebar_label: Creation and Management
|
||||
slug: /creation_and_management
|
||||
sidebar_custom_props: {
|
||||
categoryIcon: RagAiAgent
|
||||
}
|
||||
---
|
||||
|
||||
# Creation and Management
|
||||
|
||||
## Access Agent Page
|
||||
After logging into RAGFlow, click **Agent** in the top navigation bar to enter the Agent page. Created Agents are displayed as cards. Click an existing card to continue editing; click the creation entry to create a new Agent.
|
||||
|
||||
## Create from Template
|
||||
RAGFlow provides Agent templates for different business scenarios. When creating from a template, the system presets common components and connections. Users only need to modify models, knowledge bases, prompts, interface addresses or output content.
|
||||
|
||||
Steps:
|
||||
1. Enter the Agent page.
|
||||
2. Click **Create agent**.
|
||||
3. Select an appropriate template on the template page, such as Deep Research, Knowledge Base Q&A, Data Analysis or E-commerce Customer Service template.
|
||||
4. Enter the Agent name.
|
||||
5. Click **OK**.
|
||||
6. After entering the canvas, check the configuration of each component and save.
|
||||
|
||||
|
||||
|
||||
|
||||
|
||||
|
||||
|
||||
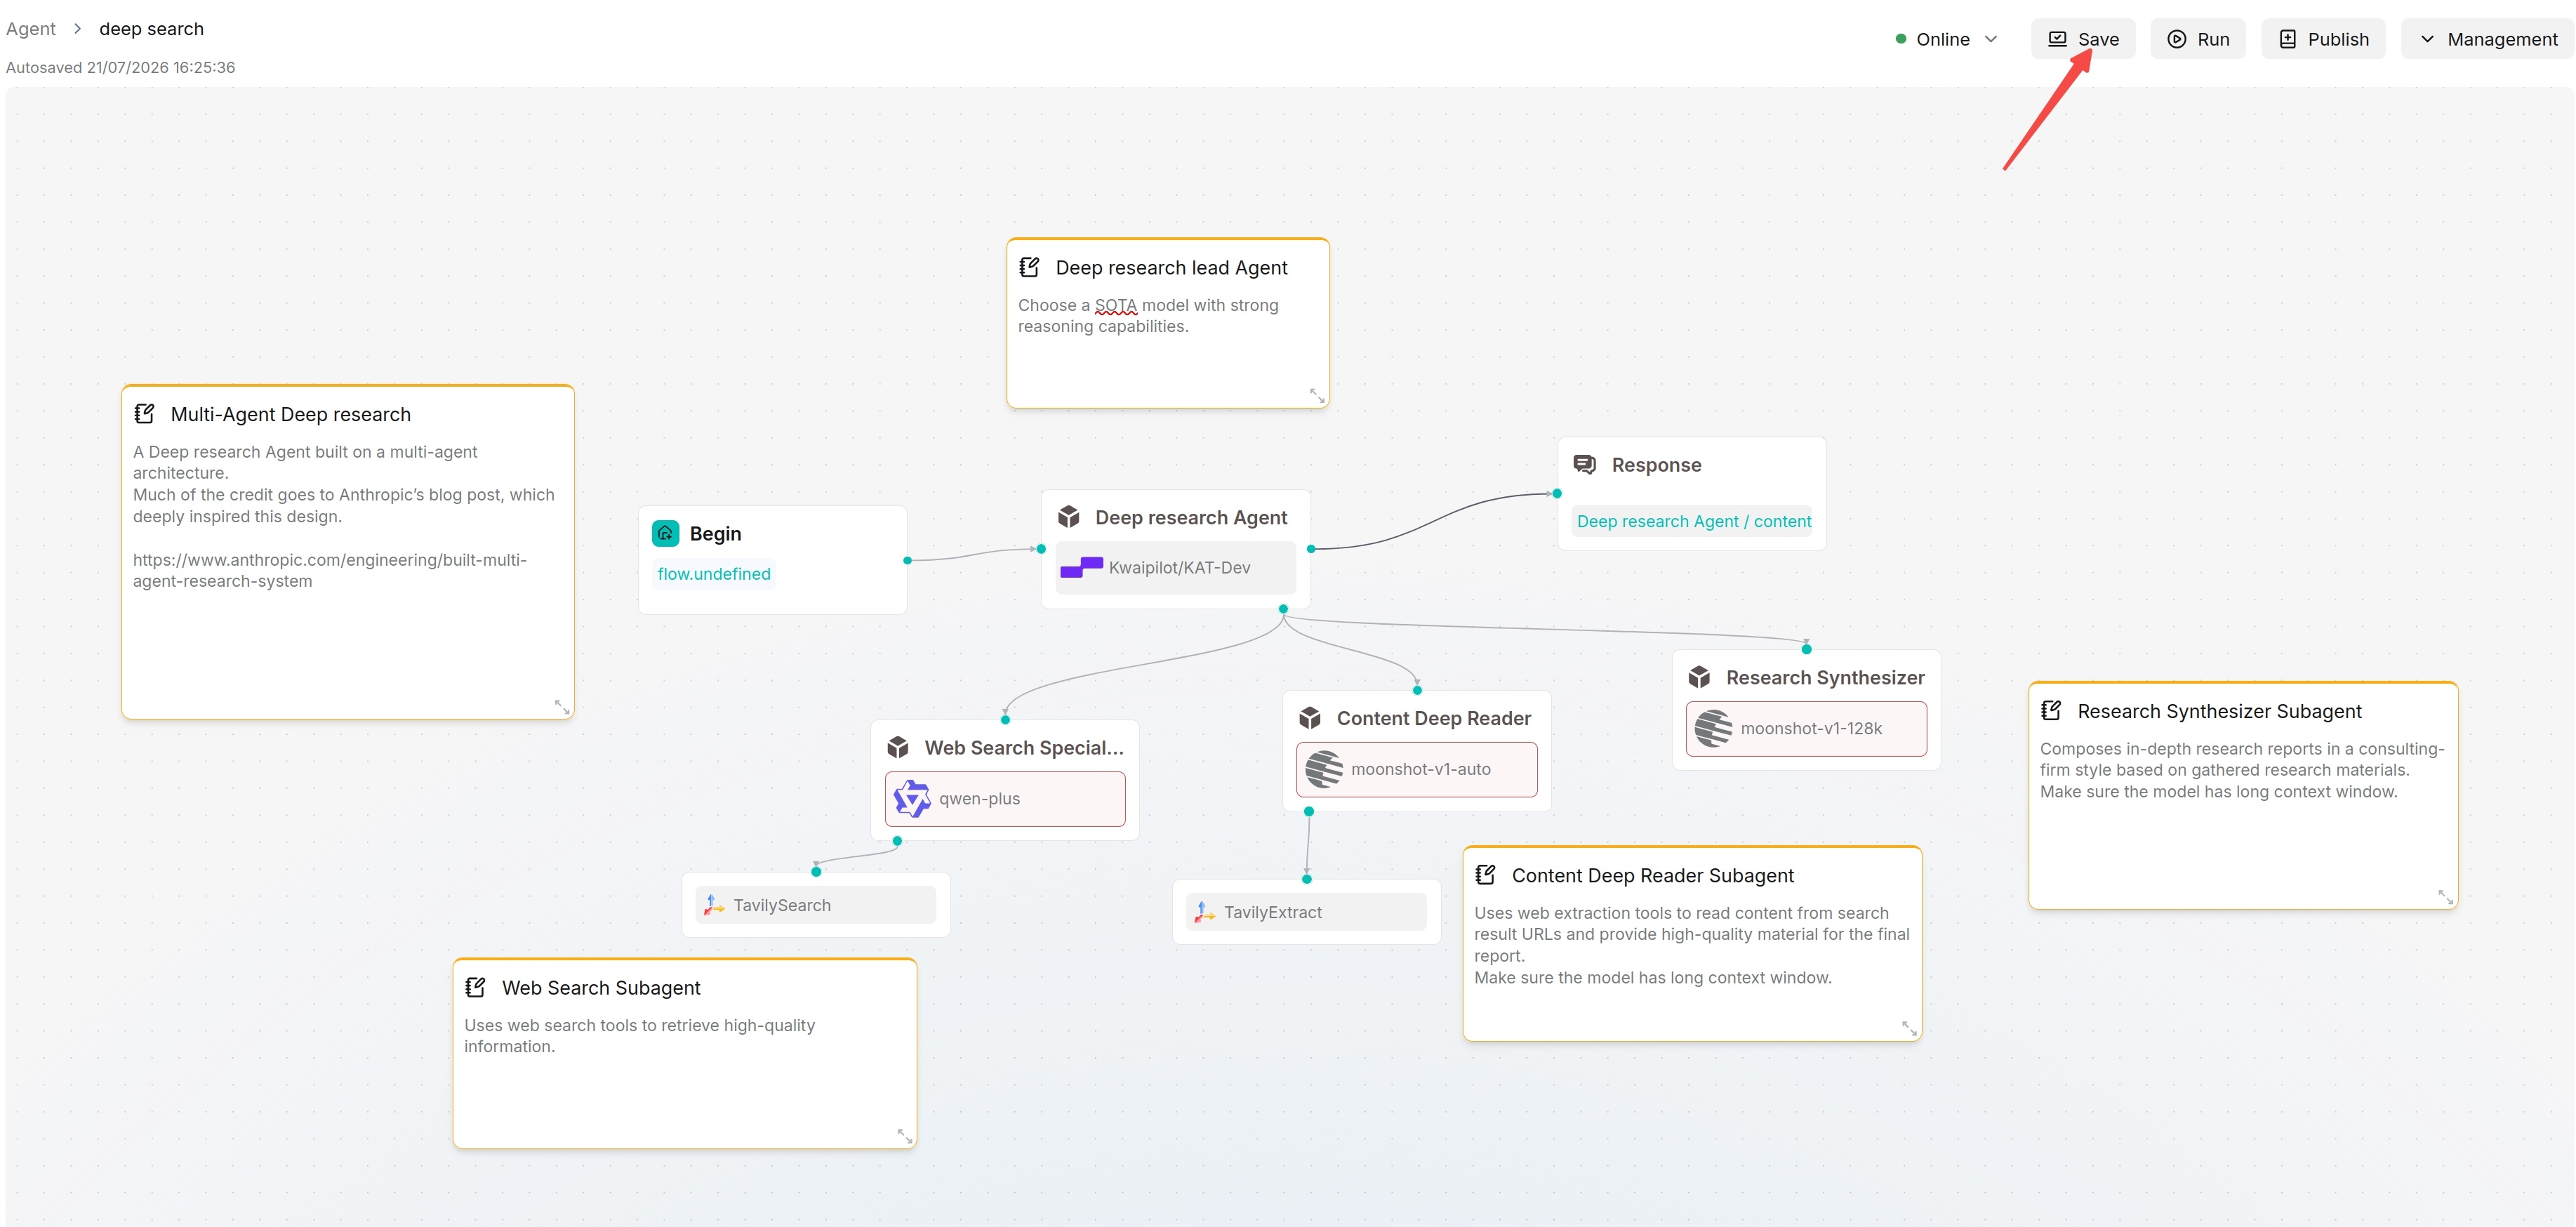
|
||||
|
||||
## Create from Blank Agent
|
||||
When creating a blank Agent, the canvas contains a default `Begin` component. Users can click the plus sign next to the Begin component or other components to add downstream components.
|
||||
|
||||
Steps:
|
||||
1. Enter the Agent page.
|
||||
2. Click **Create agent**.
|
||||
3. Select blank creation.
|
||||
4. Enter the Agent name and select the agent type.
|
||||
5. Enter the canvas.
|
||||
6. Click the plus sign next to the `Begin` component, and add components according to business processes.
|
||||
7. Configure each component.
|
||||
8. Click **Save**.
|
||||
|
||||
:::tip NOTE
|
||||
The `Begin` component is the start of the workflow. Each Agent can only have one Begin component and it cannot be deleted. After creation, configure Begin first, then configure subsequent components.
|
||||
:::
|
||||
|
||||
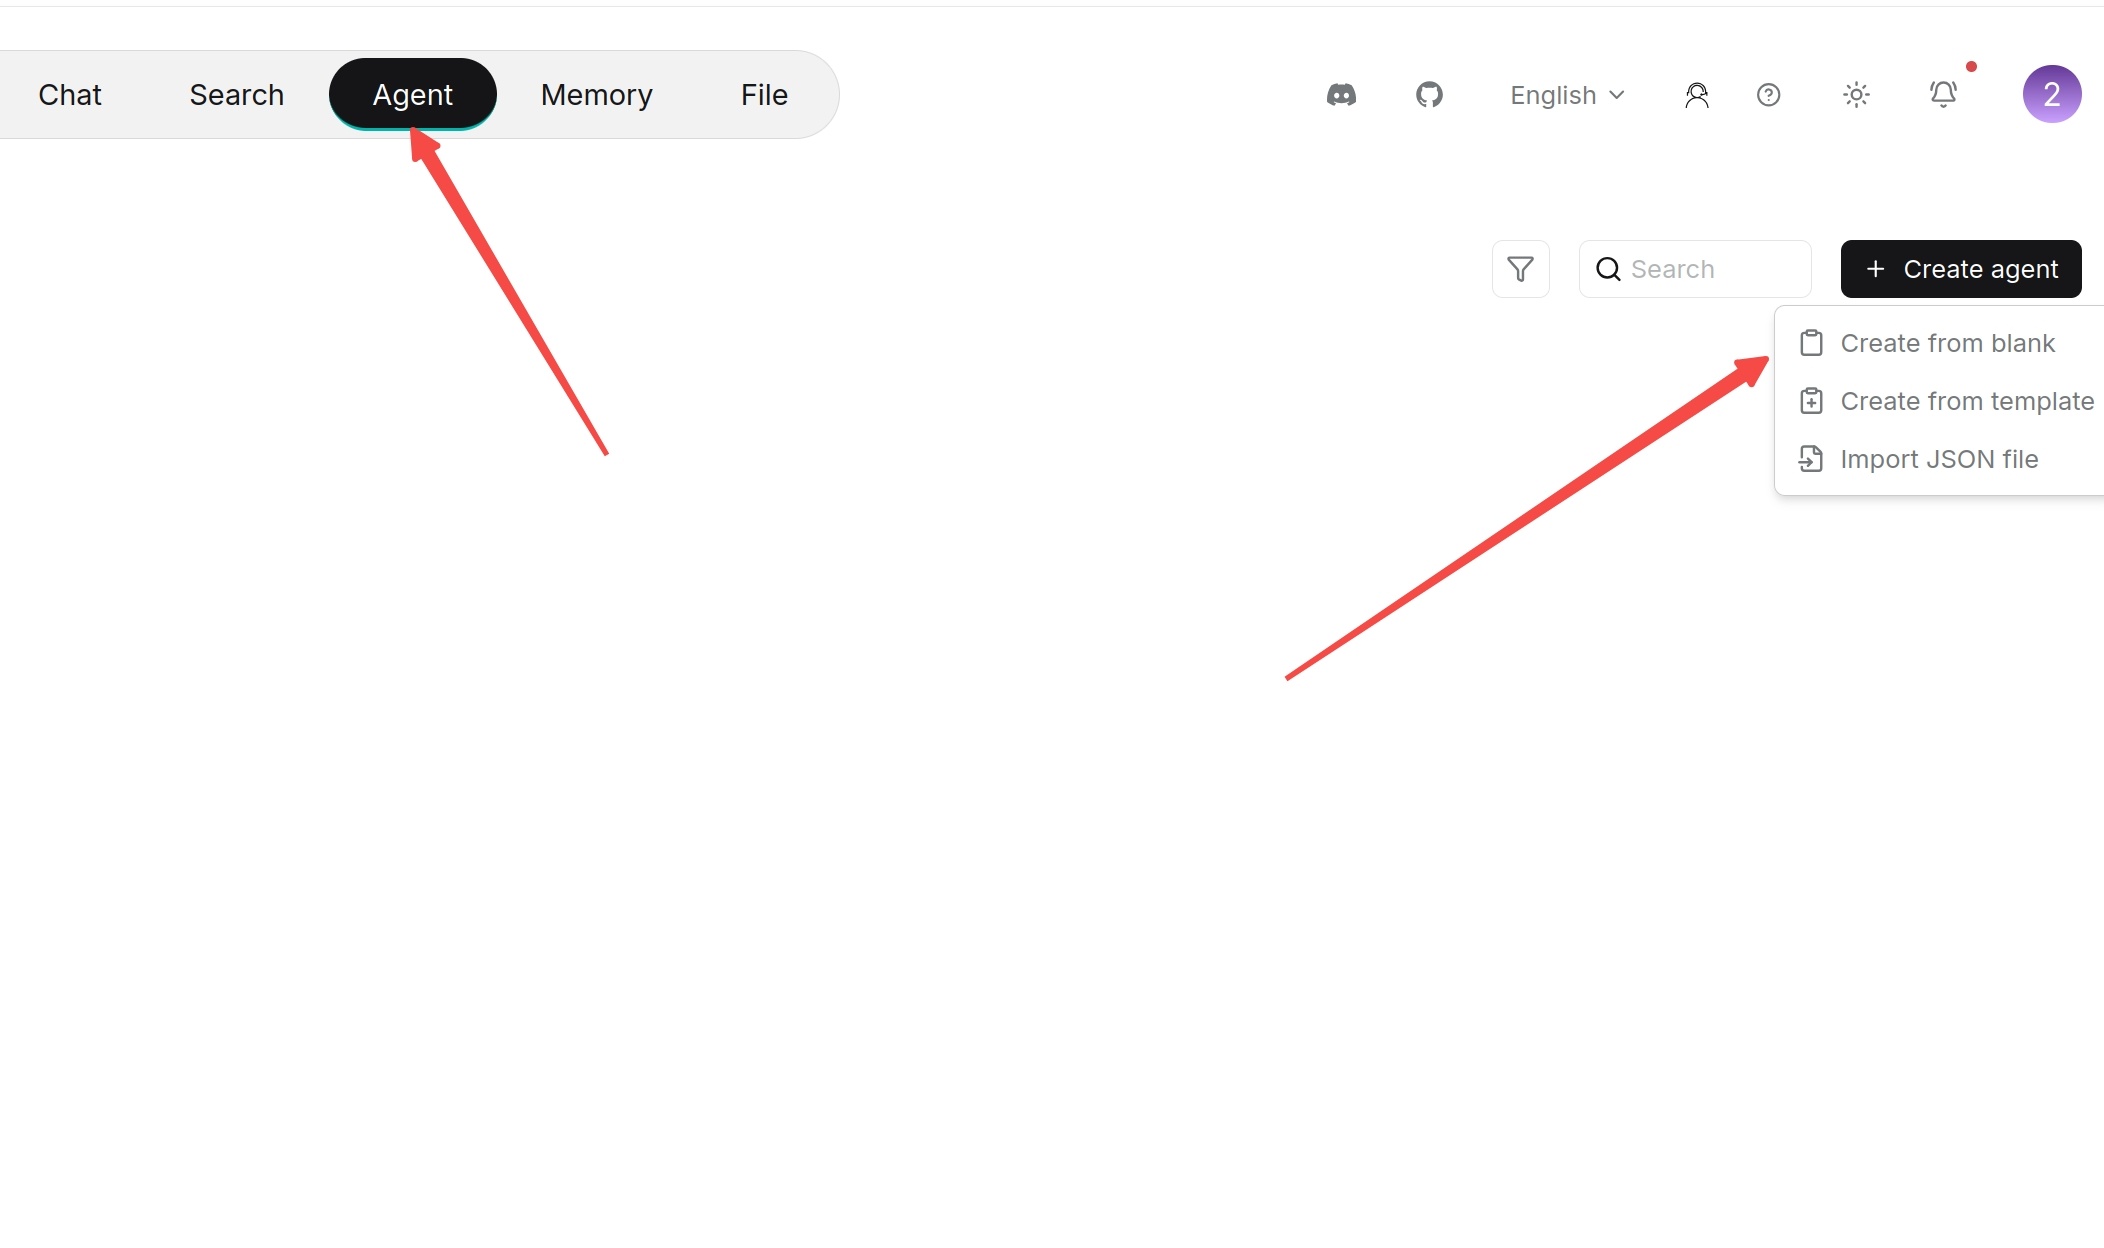
|
||||
|
||||
|
||||
|
||||
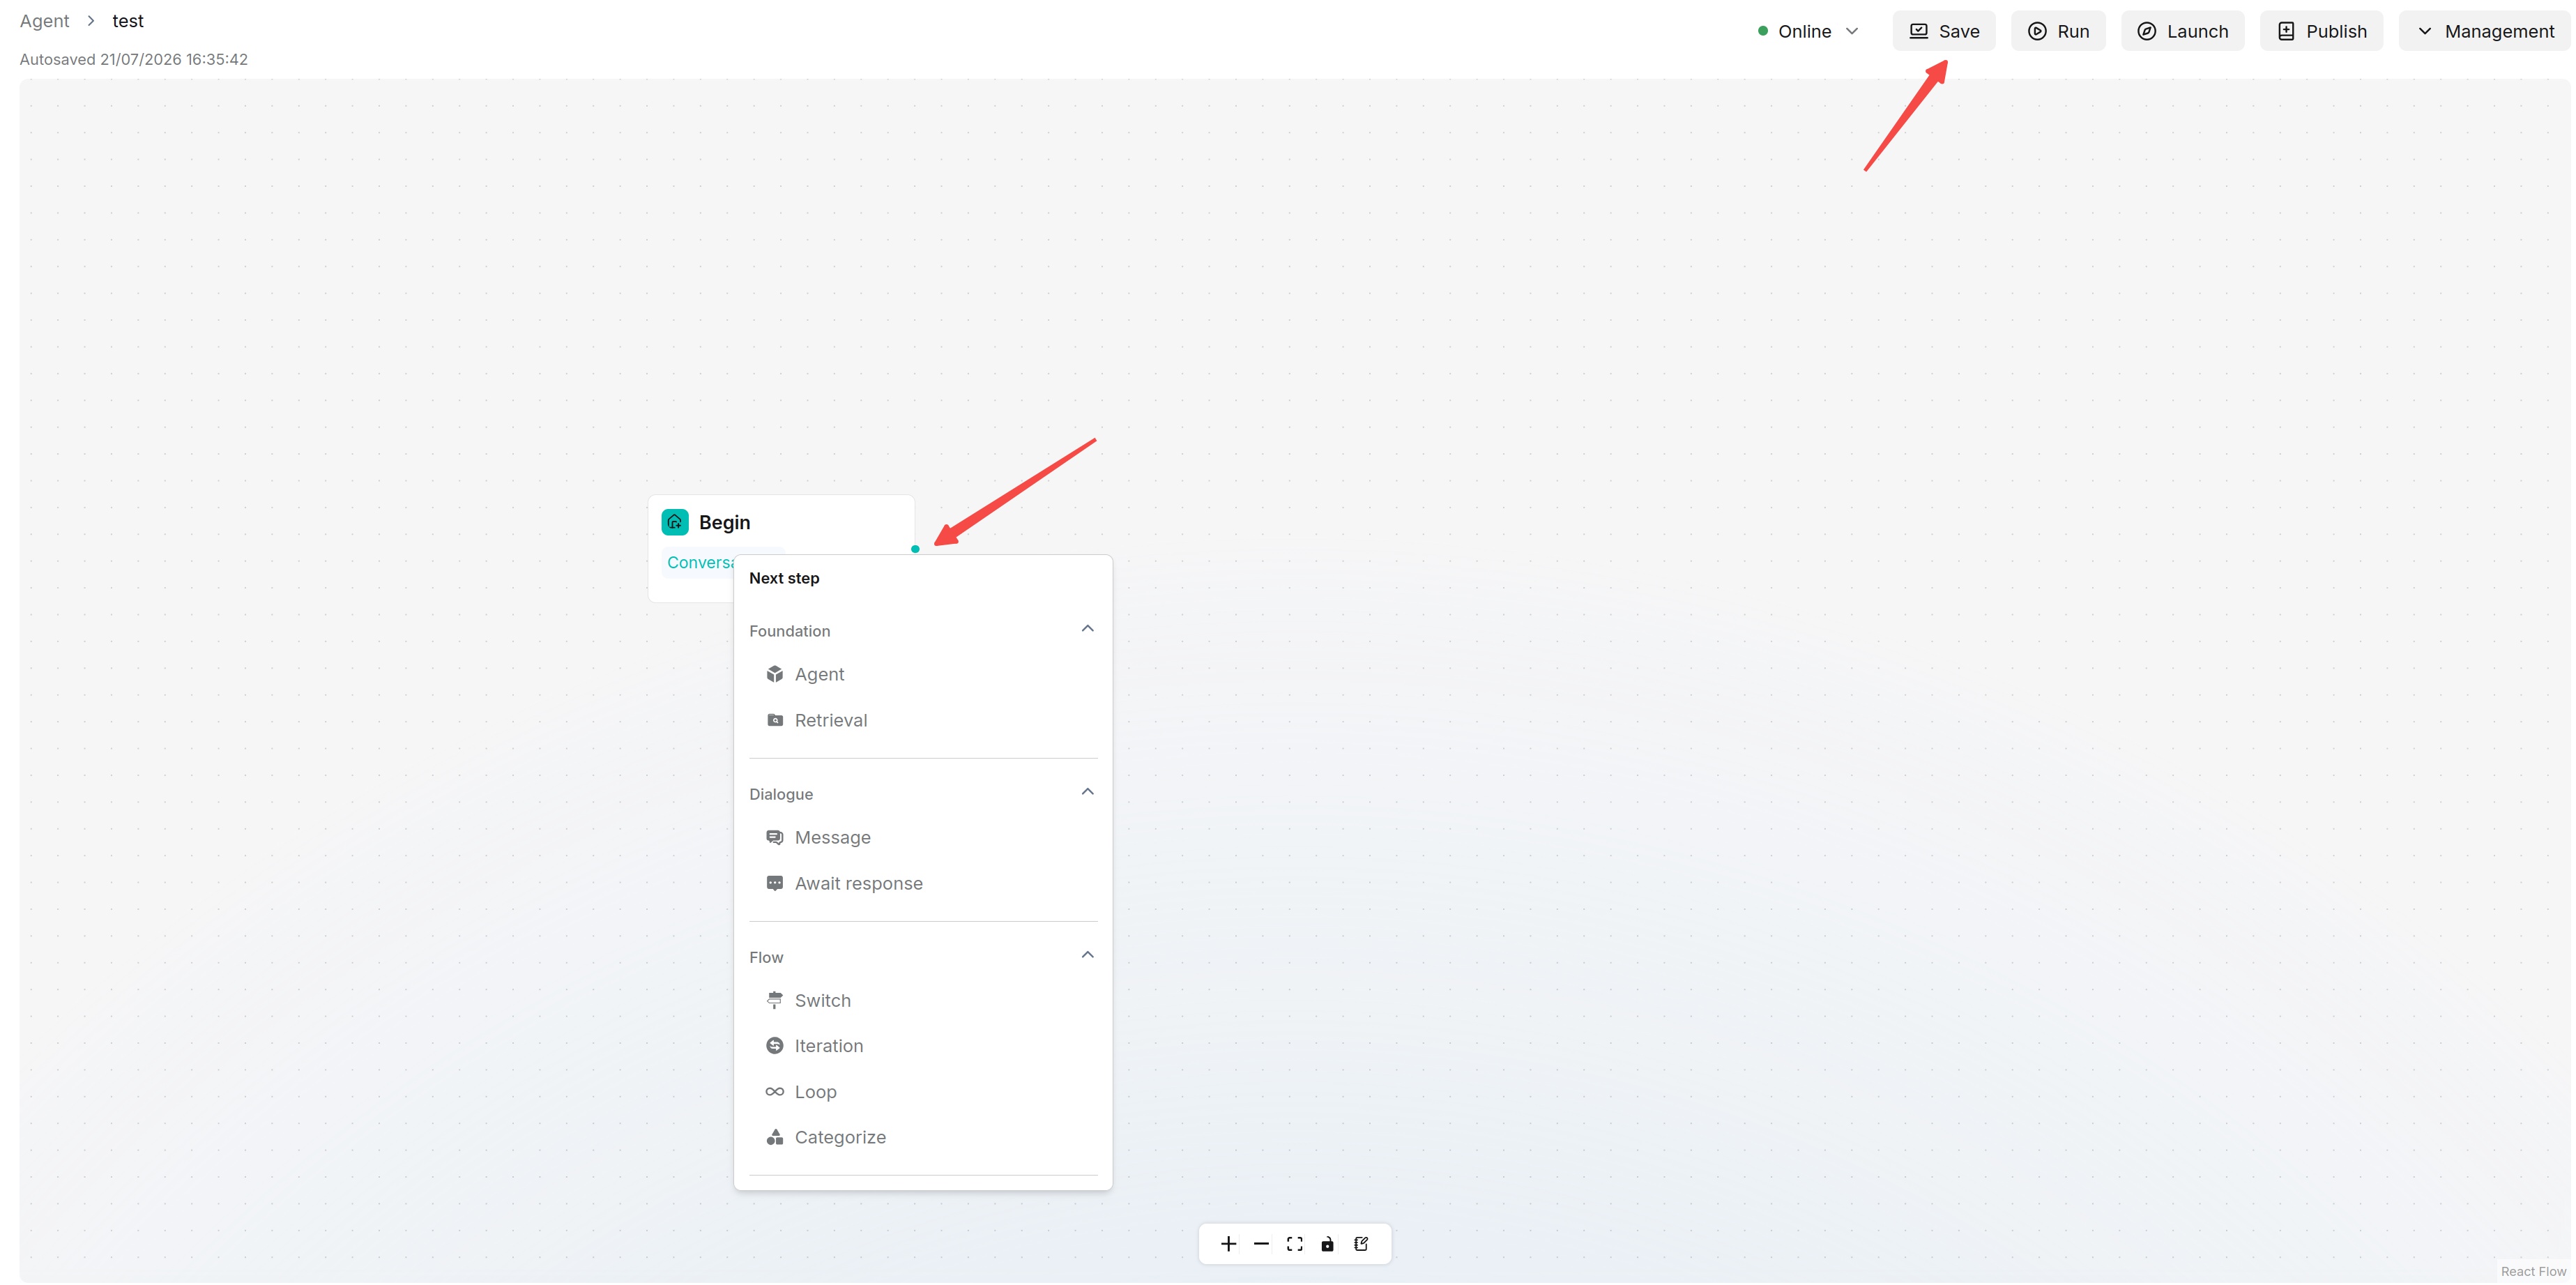
|
||||
|
||||
## Search, Copy and Delete Agent
|
||||
In the Agent list, you can search for target Agents by name. If copy, delete or other operation entries are available on the interface, confirm the Agent name and permission scope before operation. Deletion is usually irreversible. Please confirm whether the Agent is referenced by embedded web pages, API calls or other workflows.
|
||||
|
||||
## Save Agent
|
||||
Click **Save** in time after editing the canvas. Saving only records the current configuration. Whether it immediately affects published or embedded Agents depends on the version publishing mechanism and deployment strategy. Re-run tests before external usage.
|
||||
@@ -1,11 +0,0 @@
|
||||
{
|
||||
"label": "Creation and Management",
|
||||
"position": 3,
|
||||
"link": {
|
||||
"type": "generated-index",
|
||||
"description": "Creation and Management"
|
||||
},
|
||||
"customProps": {
|
||||
"categoryIcon": "RagAiAgent"
|
||||
}
|
||||
}
|
||||
@@ -1,12 +0,0 @@
|
||||
---
|
||||
sidebar_position: 1
|
||||
title: Access Agent Page
|
||||
sidebar_label: Access Agent Page
|
||||
slug: /access_agent_page
|
||||
sidebar_custom_props: {
|
||||
categoryIcon: RagAiAgent
|
||||
}
|
||||
---
|
||||
|
||||
# Access Agent Page
|
||||
After logging into RAGFlow, click **Agent** in the top navigation bar to enter the Agent page. Created Agents are displayed as cards. Click an existing card to continue editing; click the creation entry to create a new Agent.
|
||||
@@ -1,32 +0,0 @@
|
||||
---
|
||||
sidebar_position: 3
|
||||
title: Create from Blank Agent
|
||||
sidebar_label: Create from Blank Agent
|
||||
slug: /create_from_blank_agent
|
||||
sidebar_custom_props: {
|
||||
categoryIcon: RagAiAgent
|
||||
}
|
||||
---
|
||||
|
||||
# Create from Blank Agent
|
||||
When creating a blank Agent, the canvas contains a default `Begin` component. Users can click the plus sign next to the Begin component or other components to add downstream components.
|
||||
|
||||
Steps:
|
||||
1. Enter the Agent page.
|
||||
2. Click **Create agent**.
|
||||
3. Select blank creation.
|
||||
4. Enter the Agent name and select the agent type.
|
||||
5. Enter the canvas.
|
||||
6. Click the plus sign next to the `Begin` component, and add components according to business processes.
|
||||
7. Configure each component.
|
||||
8. Click **Save**.
|
||||
|
||||
:::tip NOTE
|
||||
The `Begin` component is the start of the workflow. Each Agent can only have one Begin component and it cannot be deleted. After creation, configure Begin first, then configure subsequent components.
|
||||
:::
|
||||
|
||||

|
||||
|
||||

|
||||
|
||||

|
||||
@@ -1,28 +0,0 @@
|
||||
---
|
||||
sidebar_position: 2
|
||||
title: Create from Template
|
||||
sidebar_label: Create from Template
|
||||
slug: /create_from_template
|
||||
sidebar_custom_props: {
|
||||
categoryIcon: RagAiAgent
|
||||
}
|
||||
---
|
||||
|
||||
# Create from Template
|
||||
RAGFlow provides Agent templates for different business scenarios. When creating from a template, the system presets common components and connections. Users only need to modify models, knowledge bases, prompts, interface addresses or output content.
|
||||
|
||||
Steps:
|
||||
1. Enter the Agent page.
|
||||
2. Click **Create agent**.
|
||||
3. Select an appropriate template on the template page, such as Deep Research, Knowledge Base Q&A, Data Analysis or E-commerce Customer Service template.
|
||||
4. Enter the Agent name.
|
||||
5. Click **OK**.
|
||||
6. After entering the canvas, check the configuration of each component and save.
|
||||
|
||||

|
||||
|
||||

|
||||
|
||||

|
||||
|
||||

|
||||
@@ -1,12 +0,0 @@
|
||||
---
|
||||
sidebar_position: 5
|
||||
title: Save Agent
|
||||
sidebar_label: Save Agent
|
||||
slug: /save_agent
|
||||
sidebar_custom_props: {
|
||||
categoryIcon: RagAiAgent
|
||||
}
|
||||
---
|
||||
|
||||
# Save Agent
|
||||
Click **Save** in time after editing the canvas. Saving only records the current configuration. Whether it immediately affects published or embedded Agents depends on the version publishing mechanism and deployment strategy. Re-run tests before external usage.
|
||||
@@ -1,12 +0,0 @@
|
||||
---
|
||||
sidebar_position: 4
|
||||
title: "Search, Copy and Delete Agent"
|
||||
sidebar_label: "Search, Copy and Delete Agent"
|
||||
slug: /search_copy_and_delete_agent
|
||||
sidebar_custom_props: {
|
||||
categoryIcon: RagAiAgent
|
||||
}
|
||||
---
|
||||
|
||||
# Search, Copy and Delete Agent
|
||||
In the Agent list, you can search for target Agents by name. If copy, delete or other operation entries are available on the interface, confirm the Agent name and permission scope before operation. Deletion is usually irreversible. Please confirm whether the Agent is referenced by embedded web pages, API calls or other workflows.
|
||||
+7
-5
@@ -1,14 +1,16 @@
|
||||
---
|
||||
sidebar_position: 1
|
||||
title: Embed Agent Via Webpage
|
||||
sidebar_label: Embed Agent Via Webpage
|
||||
slug: /embed_agent_via_webpage
|
||||
sidebar_position: 5
|
||||
title: Embed into Web Pages
|
||||
sidebar_label: Embed into Web Pages
|
||||
slug: /embed_into_web_pages
|
||||
sidebar_custom_props: {
|
||||
categoryIcon: RagAiAgent
|
||||
}
|
||||
---
|
||||
|
||||
# Embed Agent Via Webpage
|
||||
# Embed into Web Pages
|
||||
|
||||
## Embed Agent Via Webpage
|
||||
You can embed the Agent into third-party web pages using iframe.
|
||||
|
||||
Prerequisite: You must obtain an API Key.
|
||||
@@ -1,11 +0,0 @@
|
||||
{
|
||||
"label": "Embed into Web Pages",
|
||||
"position": 5,
|
||||
"link": {
|
||||
"type": "generated-index",
|
||||
"description": "Embed into Web Pages"
|
||||
},
|
||||
"customProps": {
|
||||
"categoryIcon": "RagAiAgent"
|
||||
}
|
||||
}
|
||||
+12
-5
@@ -1,14 +1,16 @@
|
||||
---
|
||||
sidebar_position: 1
|
||||
title: Import Agent
|
||||
sidebar_label: Import Agent
|
||||
slug: /import_agent
|
||||
sidebar_position: 4
|
||||
title: Import and Export Agents
|
||||
sidebar_label: Import and Export Agents
|
||||
slug: /import_and_export_agents
|
||||
sidebar_custom_props: {
|
||||
categoryIcon: RagAiAgent
|
||||
}
|
||||
---
|
||||
|
||||
# Import Agent
|
||||
# Import and Export Agents
|
||||
|
||||
## Import Agent
|
||||
- First-time import: Upload the JSON file, fill in corresponding information, drag or click to upload the file, then save.
|
||||
- Non-first-time import: Upload the JSON file, fill in corresponding information, drag or click to upload the file, then save.
|
||||
|
||||
@@ -17,3 +19,8 @@ sidebar_custom_props: {
|
||||
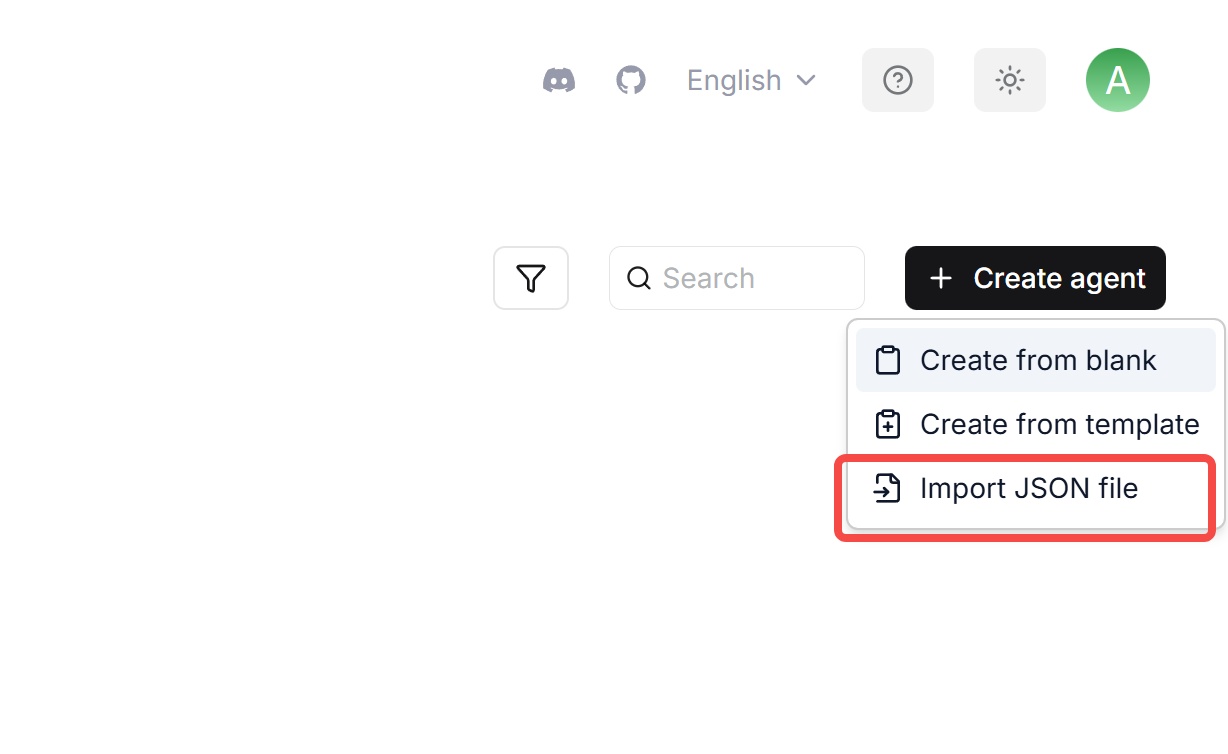
|
||||
|
||||
|
||||
|
||||
## Export Agent
|
||||
Open an Agent, click **Manage** in the upper right corner, then click export.
|
||||
|
||||
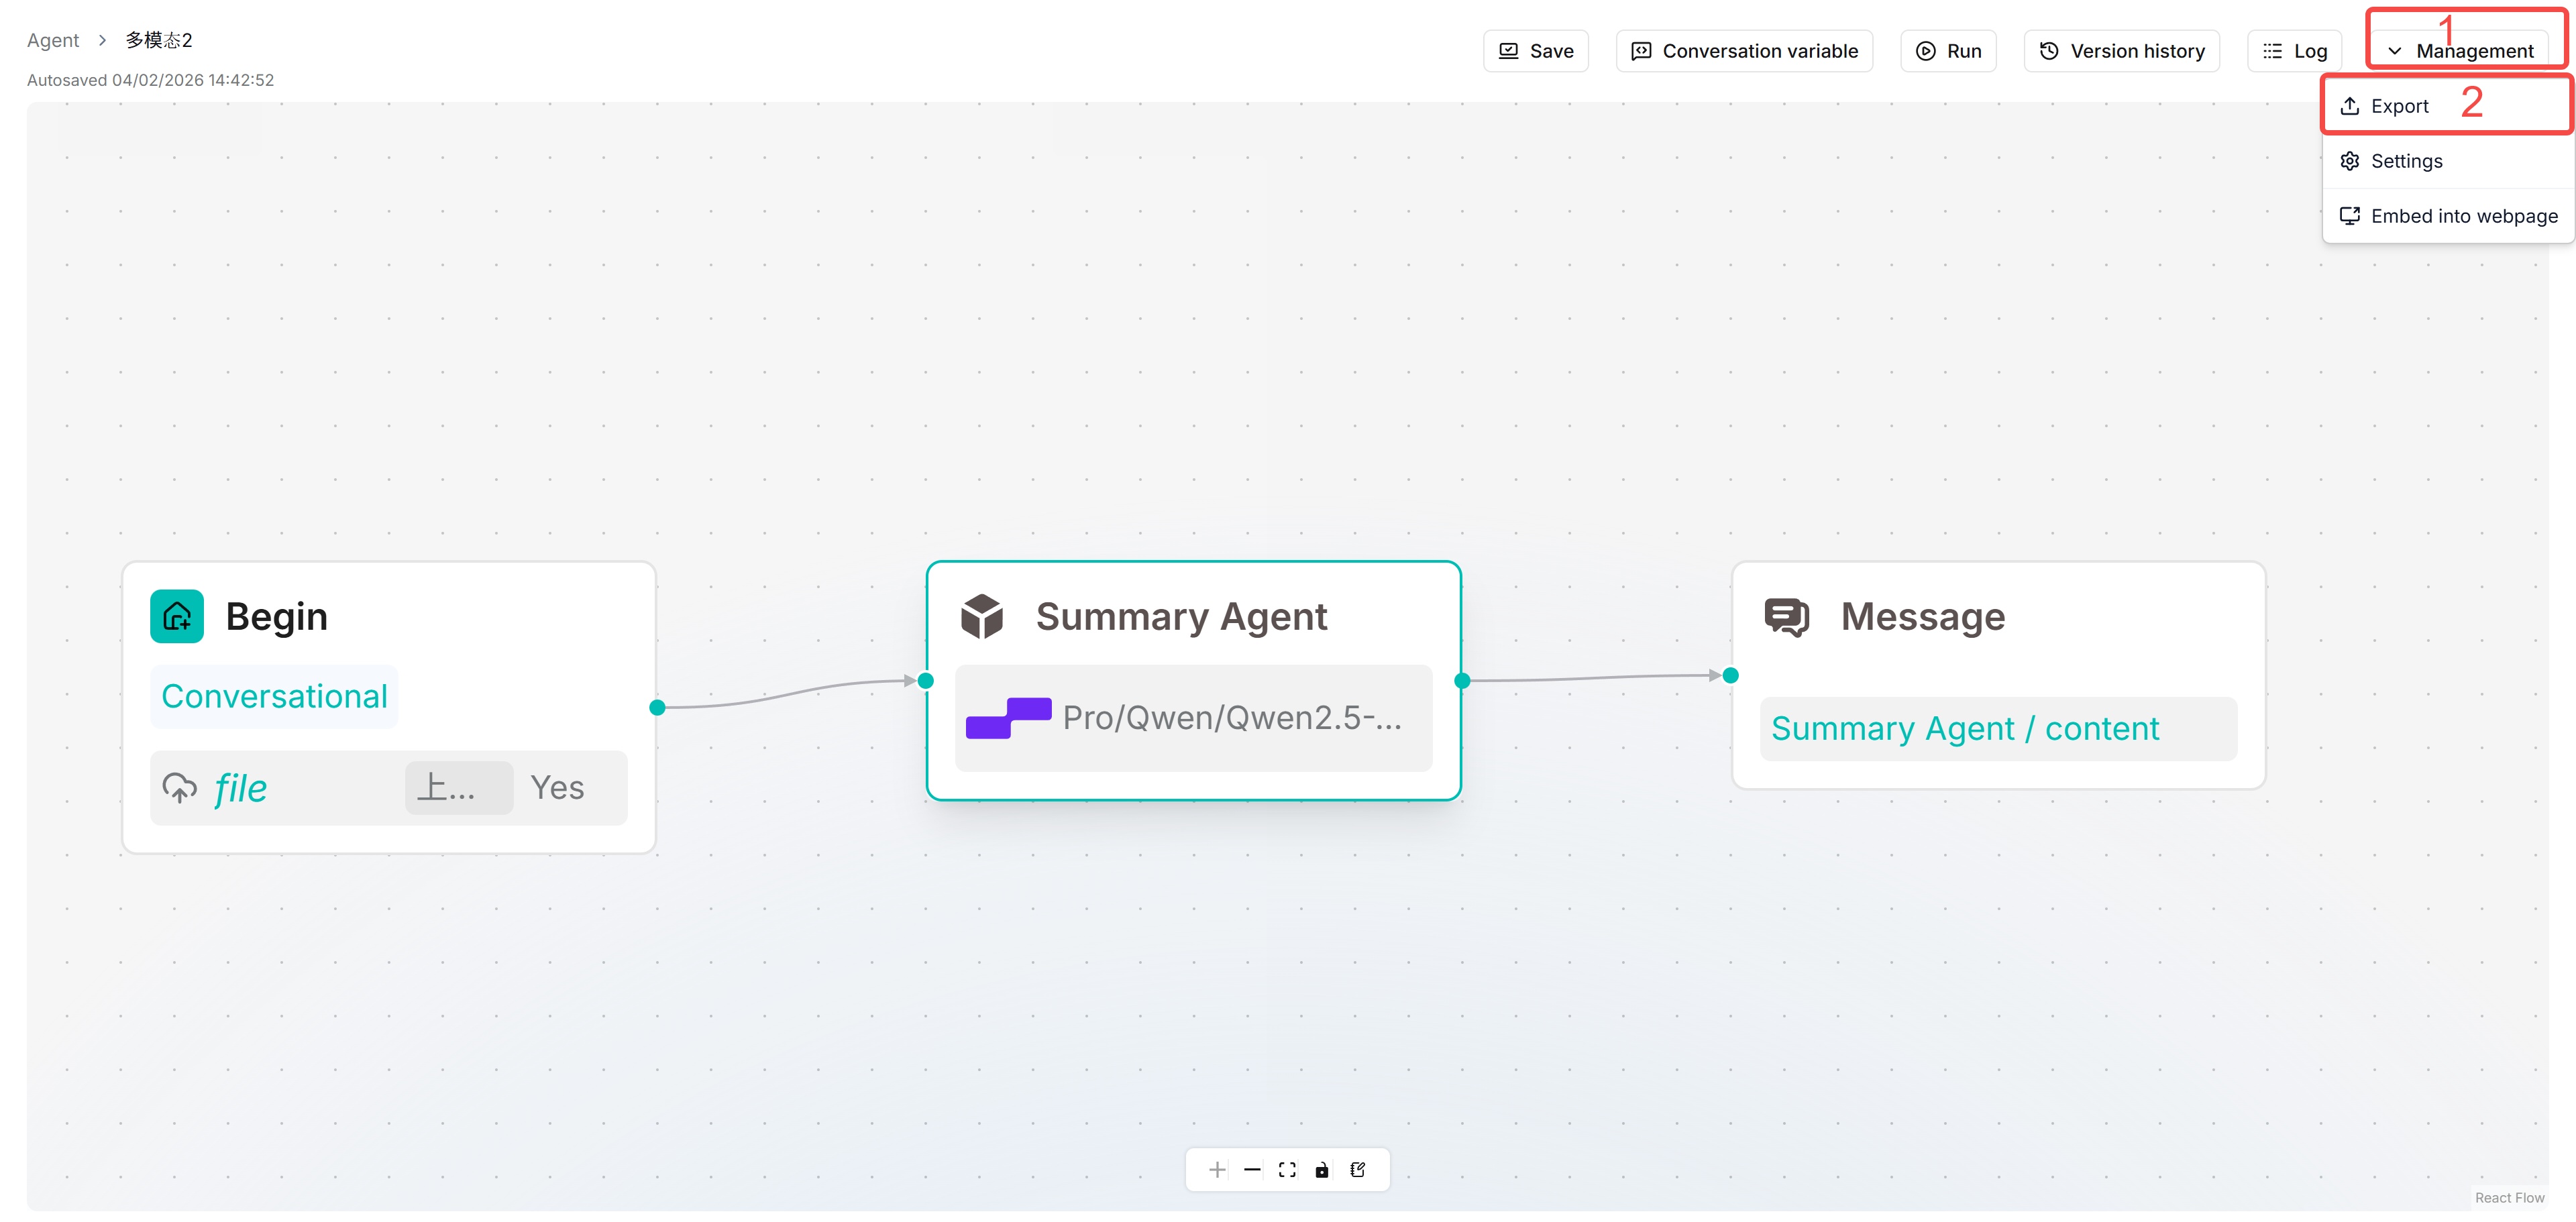
|
||||
@@ -1,11 +0,0 @@
|
||||
{
|
||||
"label": "Import and Export Agents",
|
||||
"position": 4,
|
||||
"link": {
|
||||
"type": "generated-index",
|
||||
"description": "Import and Export Agents"
|
||||
},
|
||||
"customProps": {
|
||||
"categoryIcon": "RagAiAgent"
|
||||
}
|
||||
}
|
||||
@@ -1,14 +0,0 @@
|
||||
---
|
||||
sidebar_position: 2
|
||||
title: Export Agent
|
||||
sidebar_label: Export Agent
|
||||
slug: /export_agent
|
||||
sidebar_custom_props: {
|
||||
categoryIcon: RagAiAgent
|
||||
}
|
||||
---
|
||||
|
||||
# Export Agent
|
||||
Open an Agent, click **Manage** in the upper right corner, then click export.
|
||||
|
||||

|
||||
@@ -0,0 +1,57 @@
|
||||
---
|
||||
sidebar_position: 6
|
||||
title: Understand the Canvas
|
||||
sidebar_label: Understand the Canvas
|
||||
slug: /understand_the_canvas
|
||||
sidebar_custom_props: {
|
||||
categoryIcon: RagAiAgent
|
||||
}
|
||||
---
|
||||
|
||||
# Understand the Canvas
|
||||
|
||||
## Add Components
|
||||
Click the plus sign next to any component on the canvas to select the next component. Common components include:
|
||||
`Begin`, `Agent`, `Retrieval`, `Message`, `Await response`, `Switch`, `Iteration`, `Categorize`, `Code`, `Text processing`, `Execute SQL`, `HTTP Request`, and pipeline-related components: `Parser`, `Title chunker`, `Token chunker`, `Transformer`, `Indexer`.
|
||||
|
||||
After adding a component, click the component itself to open the configuration panel on the right. Fields in the configuration panel define input data, processing logic, output variables, and references for subsequent steps.
|
||||
|
||||
## Use Variables
|
||||
Components on the Agent canvas support variable references to implement data transmission between components. Variable sources include system variables, global variables defined in the Begin component, and outputs from upstream components.
|
||||
|
||||
In input boxes supporting variable references, type `/` or click the variable button next to the input box to open the variable selector.
|
||||
|
||||
Common variables:
|
||||
| Variable | Description |
|
||||
| ---- | ---- |
|
||||
| `sys.query` | Current user input question |
|
||||
| `formalized_content` | Sorted text results from Retrieval, SQL or tool components |
|
||||
| `chunks` | Fragment set output by document parsing or chunking components |
|
||||
| `content` | Main text output from Agent, Code or other components |
|
||||
|
||||
Operation Steps:
|
||||
1. Enter the Agent page and open the target canvas for editing.
|
||||
2. Select a component supporting variable references, e.g. Agent, Retrieval, Message, Code, HTTP Request, SQL.
|
||||
3. On the right configuration panel, click the input box that needs variable reference, such as System Prompt, User Prompt, Query, etc.
|
||||
4. Open the variable selector via either method:
|
||||
- Type `/` inside the input box
|
||||
- Click the variable icon next to the input box (may display as `{}`, `+` or other icons in different versions)
|
||||
5. Select required variables in the selector. Available variables include:
|
||||
- System variables such as `sys.query`
|
||||
- Global variables defined in the Begin component
|
||||
- Output variables from upstream components
|
||||
6. After selection, the variable will be automatically inserted into the input box.
|
||||
7. Save component configuration and run the Agent to verify data transmission.
|
||||
|
||||
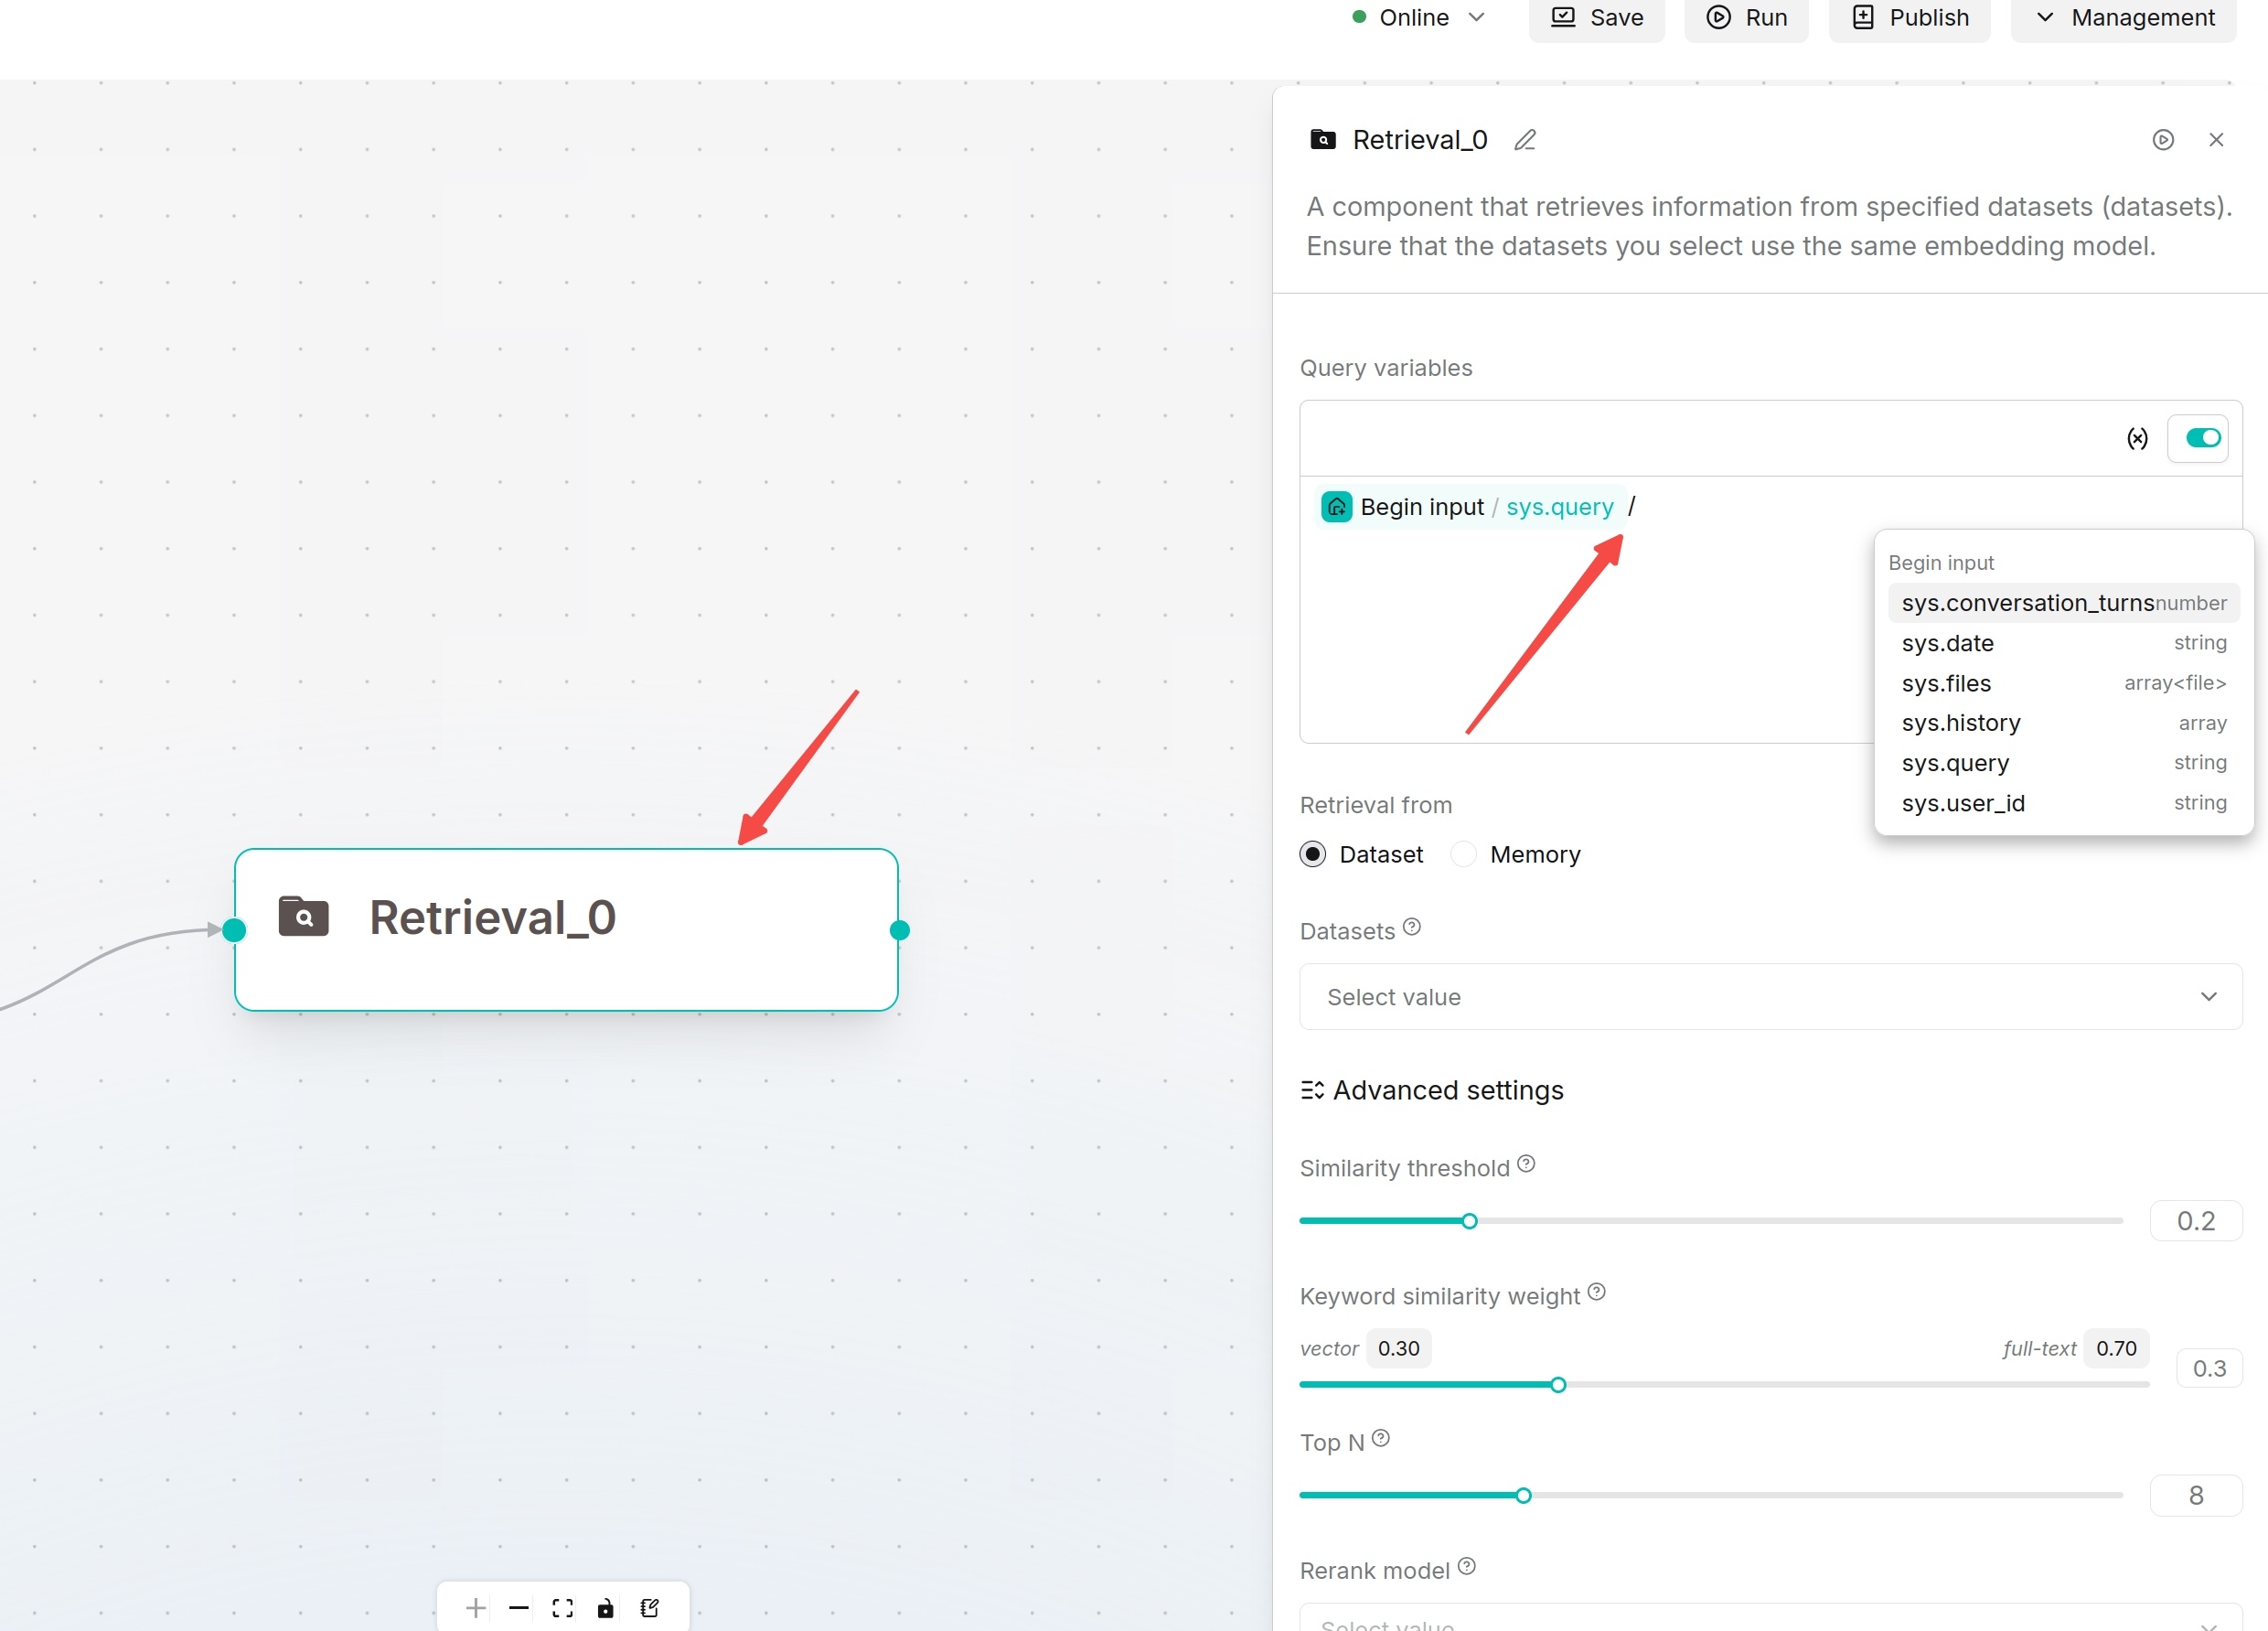
|
||||
|
||||
## Save & Run
|
||||
After configuration, click **Save** to save the Agent. During debugging, click **Run** at the top of the canvas, enter test questions and observe the execution result of each component. If a component returns no output, check input variables, model configuration, knowledge base permissions, external interface addresses or tool configuration.
|
||||
|
||||
|
||||
|
||||
## Component Connection Rules
|
||||
Connections define component execution order. Sequential components run along a single path. Branch components such as `Switch` and `Categorize` route workflows to different exits according to conditions. `Iteration` executes sub-processes in loops. Components not connected to the execution path will not run. Before deleting a component, check upstream/downstream connections and variable references to avoid missing inputs for subsequent nodes.
|
||||
|
||||
## Configuration Panel
|
||||
Click any canvas component to open the right-side configuration panel, which displays fields, input variables, output variables and runtime parameters. Recommended workflow: confirm which variable the component reads → configure processing logic → verify downstream nodes reference correct outputs.
|
||||
@@ -1,11 +0,0 @@
|
||||
{
|
||||
"label": "Understand the Canvas",
|
||||
"position": 6,
|
||||
"link": {
|
||||
"type": "generated-index",
|
||||
"description": "Understand the Canvas"
|
||||
},
|
||||
"customProps": {
|
||||
"categoryIcon": "RagAiAgent"
|
||||
}
|
||||
}
|
||||
@@ -1,15 +0,0 @@
|
||||
---
|
||||
sidebar_position: 1
|
||||
title: Add Components
|
||||
sidebar_label: Add Components
|
||||
slug: /add_components
|
||||
sidebar_custom_props: {
|
||||
categoryIcon: RagAiAgent
|
||||
}
|
||||
---
|
||||
|
||||
# Add Components
|
||||
Click the plus sign next to any component on the canvas to select the next component. Common components include:
|
||||
`Begin`, `Agent`, `Retrieval`, `Message`, `Await response`, `Switch`, `Iteration`, `Categorize`, `Code`, `Text processing`, `Execute SQL`, `HTTP Request`, and pipeline-related components: `Parser`, `Title chunker`, `Token chunker`, `Transformer`, `Indexer`.
|
||||
|
||||
After adding a component, click the component itself to open the configuration panel on the right. Fields in the configuration panel define input data, processing logic, output variables, and references for subsequent steps.
|
||||
@@ -1,12 +0,0 @@
|
||||
---
|
||||
sidebar_position: 4
|
||||
title: Component Connection Rules
|
||||
sidebar_label: Component Connection Rules
|
||||
slug: /component_connection_rules
|
||||
sidebar_custom_props: {
|
||||
categoryIcon: RagAiAgent
|
||||
}
|
||||
---
|
||||
|
||||
# Component Connection Rules
|
||||
Connections define component execution order. Sequential components run along a single path. Branch components such as `Switch` and `Categorize` route workflows to different exits according to conditions. `Iteration` executes sub-processes in loops. Components not connected to the execution path will not run. Before deleting a component, check upstream/downstream connections and variable references to avoid missing inputs for subsequent nodes.
|
||||
@@ -1,12 +0,0 @@
|
||||
---
|
||||
sidebar_position: 5
|
||||
title: Configuration Panel
|
||||
sidebar_label: Configuration Panel
|
||||
slug: /configuration_panel
|
||||
sidebar_custom_props: {
|
||||
categoryIcon: RagAiAgent
|
||||
}
|
||||
---
|
||||
|
||||
# Configuration Panel
|
||||
Click any canvas component to open the right-side configuration panel, which displays fields, input variables, output variables and runtime parameters. Recommended workflow: confirm which variable the component reads → configure processing logic → verify downstream nodes reference correct outputs.
|
||||
@@ -1,14 +0,0 @@
|
||||
---
|
||||
sidebar_position: 3
|
||||
title: "Save & Run"
|
||||
sidebar_label: "Save & Run"
|
||||
slug: /save_and_run
|
||||
sidebar_custom_props: {
|
||||
categoryIcon: RagAiAgent
|
||||
}
|
||||
---
|
||||
|
||||
# Save & Run
|
||||
After configuration, click **Save** to save the Agent. During debugging, click **Run** at the top of the canvas, enter test questions and observe the execution result of each component. If a component returns no output, check input variables, model configuration, knowledge base permissions, external interface addresses or tool configuration.
|
||||
|
||||

|
||||
@@ -1,38 +0,0 @@
|
||||
---
|
||||
sidebar_position: 2
|
||||
title: Use Variables
|
||||
sidebar_label: Use Variables
|
||||
slug: /use_variables
|
||||
sidebar_custom_props: {
|
||||
categoryIcon: RagAiAgent
|
||||
}
|
||||
---
|
||||
|
||||
# Use Variables
|
||||
Components on the Agent canvas support variable references to implement data transmission between components. Variable sources include system variables, global variables defined in the Begin component, and outputs from upstream components.
|
||||
|
||||
In input boxes supporting variable references, type `/` or click the variable button next to the input box to open the variable selector.
|
||||
|
||||
Common variables:
|
||||
| Variable | Description |
|
||||
| ---- | ---- |
|
||||
| `sys.query` | Current user input question |
|
||||
| `formalized_content` | Sorted text results from Retrieval, SQL or tool components |
|
||||
| `chunks` | Fragment set output by document parsing or chunking components |
|
||||
| `content` | Main text output from Agent, Code or other components |
|
||||
|
||||
Operation Steps:
|
||||
1. Enter the Agent page and open the target canvas for editing.
|
||||
2. Select a component supporting variable references, e.g. Agent, Retrieval, Message, Code, HTTP Request, SQL.
|
||||
3. On the right configuration panel, click the input box that needs variable reference, such as System Prompt, User Prompt, Query, etc.
|
||||
4. Open the variable selector via either method:
|
||||
- Type `/` inside the input box
|
||||
- Click the variable icon next to the input box (may display as `{}`, `+` or other icons in different versions)
|
||||
5. Select required variables in the selector. Available variables include:
|
||||
- System variables such as `sys.query`
|
||||
- Global variables defined in the Begin component
|
||||
- Output variables from upstream components
|
||||
6. After selection, the variable will be automatically inserted into the input box.
|
||||
7. Save component configuration and run the Agent to verify data transmission.
|
||||
|
||||

|
||||
@@ -1,5 +1,5 @@
|
||||
---
|
||||
sidebar_position: 2
|
||||
sidebar_position: 4
|
||||
title: Search
|
||||
sidebar_label: Search
|
||||
slug: /ai_search
|
||||
|
||||
@@ -1,6 +1,6 @@
|
||||
{
|
||||
"label": "Chat",
|
||||
"position": 1,
|
||||
"position": 2,
|
||||
"link": {
|
||||
"type": "generated-index",
|
||||
"description": "Chat-specific guides."
|
||||
|
||||
@@ -0,0 +1,11 @@
|
||||
{
|
||||
"label": "Chat Channels",
|
||||
"position": 3,
|
||||
"link": {
|
||||
"type": "generated-index",
|
||||
"description": "Guides on configuring chat channels and connecting them to Chat."
|
||||
},
|
||||
"customProps": {
|
||||
"categoryIcon": "LucideMessagesSquare"
|
||||
}
|
||||
}
|
||||
@@ -0,0 +1,219 @@
|
||||
---
|
||||
sidebar_position: 2
|
||||
title: Channel Access and Configuration
|
||||
sidebar_label: Channel Access and Configuration
|
||||
slug: /channel_access_and_configuration
|
||||
sidebar_custom_props: {
|
||||
categoryIcon: LucideMessagesSquare
|
||||
}
|
||||
---
|
||||
|
||||
# Channel Access and Configuration
|
||||
|
||||
## Discord
|
||||
|
||||
Users can chat with a Chat directly in Discord. This is suitable for community support, product Q&A, user feedback collection, and similar scenarios.
|
||||
|
||||
Configuration prerequisites:
|
||||
|
||||
- Create an application and bot in the Discord Developer Portal.
|
||||
- Obtain the `BotToken` on the **Bot** page.
|
||||
- Generate an invitation link on the **OAuth2** page and select the `bot` scope.
|
||||
- Grant the bot permissions to send messages and read message history.
|
||||
- Invite the bot to the target server.
|
||||
|
||||
Configuration parameters:
|
||||
|
||||
- **Name**: The channel name displayed in RAGFlow, used to distinguish different Discord bots.
|
||||
- **BotToken**: The Discord bot authentication credential. Obtain it from **Discord Developer Portal > Bot**. An incorrect value causes the bot to fail to connect to Discord.
|
||||
- **ApplicationID** (optional): The Discord application identifier. Obtain it from **Discord Developer Portal > General Information**. Leaving it empty does not affect basic message receiving and replying.
|
||||
|
||||
Usage:
|
||||
|
||||
When adding a Discord channel in RAGFlow, fill in the `BotToken` obtained from the Discord Developer Portal and connect the channel to a Chat after saving it. The bot must join the target server and have permissions to read and send messages. If `MessageContentIntent` is not enabled, the bot may appear online but fail to read the body text of user messages.
|
||||
|
||||
Connection verification:
|
||||
|
||||
After completing configuration, send a test message to the bot in Discord to verify whether replies are received normally.
|
||||
|
||||
## DingTalk
|
||||
|
||||
The DingTalk channel is suitable for organizational collaboration scenarios. Members can complete knowledge Q&A, process consultation, and business support in DingTalk conversations.
|
||||
|
||||
Configuration prerequisites:
|
||||
|
||||
- Create an application in the DingTalk Open Platform.
|
||||
- Add bot capabilities to the application.
|
||||
- Enable permissions related to bot message sending and cards, such as `qyapi_robot_sendmsg`, `Card.Streaming.Write`, and `Card.Instance.Write`.
|
||||
- Publish the application version to make the configuration take effect.
|
||||
- Obtain the `ClientID` and `ClientSecret`.
|
||||
|
||||
Configuration parameters:
|
||||
|
||||
- **Name**: The channel name displayed in RAGFlow, used to distinguish different DingTalk bots.
|
||||
- **ClientID**: The DingTalk application identity identifier. Obtain it from **DingTalk Open Platform > Application Credentials**. An incorrect value causes message connection establishment to fail.
|
||||
- **ClientSecret**: The DingTalk application secret. Obtain it from **DingTalk Open Platform > Application Credentials**. An incorrect value causes DingTalk platform authentication to fail.
|
||||
|
||||
Usage:
|
||||
|
||||
When adding a DingTalk channel in RAGFlow, fill in the `ClientID` and `ClientSecret` from the DingTalk Open Platform and connect the channel to a Chat after saving it. DingTalk replies depend on the conversation `Webhook` returned in message events. Therefore, the user must first send a message to the bot in DingTalk before RAGFlow can return a reply in the corresponding conversation.
|
||||
|
||||
Connection verification:
|
||||
|
||||
After completing configuration, send a test message to the bot in DingTalk to verify whether replies are received normally.
|
||||
|
||||
## Feishu / Lark
|
||||
|
||||
The Feishu / Lark channel helps organization members use knowledge assistants in daily chat windows. It is suitable for enterprise knowledge Q&A, customer service collaboration, and internal business assistants.
|
||||
|
||||
Configuration prerequisites:
|
||||
|
||||
- Create an application in the Feishu Open Platform or Lark Developer Console.
|
||||
- Enable bot capabilities.
|
||||
- Configure long connections or event subscriptions.
|
||||
- Enable permissions related to user IDs, messages, and groups.
|
||||
- Obtain the `AppID` and `AppSecret`.
|
||||
|
||||
Configuration parameters:
|
||||
|
||||
- **Name**: The channel name displayed in RAGFlow, used to distinguish different Feishu / Lark bots.
|
||||
- **AppID**: The Feishu / Lark application identifier. Obtain it from **Feishu Open Platform / Lark Developer Console > Application Credentials**. An incorrect value causes the bot to fail to establish a connection.
|
||||
- **AppSecret**: The Feishu / Lark application secret. Obtain it from **Feishu Open Platform / Lark Developer Console > Application Credentials**. An incorrect value causes the bot to fail to receive or send messages.
|
||||
- **Domain**: The platform region setting. Select **Feishu(mainland)** for mainland China Feishu, and select **Lark(international)** for the international Lark version. An incorrect selection causes authentication or API calls to fail.
|
||||
|
||||
Usage:
|
||||
|
||||
When adding a Feishu / Lark channel in RAGFlow, fill in the `AppID` and `AppSecret` from the open platform and select the `Domain` based on the platform where the application is located. After saving the configuration, connect the channel to a Chat and add the bot to the Feishu / Lark conversation where it will be used.
|
||||
|
||||
Connection verification:
|
||||
|
||||
After completing configuration, send a test message to the bot in Feishu or Lark to verify whether replies are received normally.
|
||||
|
||||
## QQ Bot
|
||||
|
||||
The QQ Bot channel is suitable for providing automatic Q&A services to QQ users. It can cover one-on-one chats, group chats, channels, private messages, and other conversation scenarios.
|
||||
|
||||
Configuration prerequisites:
|
||||
|
||||
- Create a bot in the QQ Open Platform or QQ Bot Open Platform.
|
||||
- Obtain the bot `AppID`.
|
||||
- Obtain the bot `ClientSecret`.
|
||||
- Enable the message event permissions required for use.
|
||||
- Add the bot to the QQ conversation scope it needs to serve.
|
||||
|
||||
Configuration parameters:
|
||||
|
||||
- **Name**: The channel name displayed in RAGFlow, used to distinguish different QQ bots.
|
||||
- **AppID**: The QQ bot application identifier. Obtain it from **QQ Bot Platform > Application Information**. An incorrect value causes the bot to fail to connect to the gateway.
|
||||
- **ClientSecret**: The QQ bot application secret. Obtain it from **QQ Bot Platform > Application Credentials**. An incorrect value causes authentication to fail.
|
||||
- **BaseURL** (optional): The base address of the QQ Bot API. Keep the default value in ordinary environments. Fill it in only when using a proxy or a specified API address. An incorrect value causes gateway address retrieval or message sending to fail.
|
||||
|
||||
Usage:
|
||||
|
||||
When adding a QQ Bot channel in RAGFlow, fill in the `AppID` and `ClientSecret` obtained from the QQ platform and connect the channel to a Chat after saving it. In ordinary public network environments, keep `BaseURL` empty and use the system default address. Fill in this parameter only when the platform requires another API domain name, a proxy gateway, or a private forwarding address.
|
||||
|
||||
Connection verification:
|
||||
|
||||
After completing configuration, send a test message to the bot in QQ to verify whether replies are received normally.
|
||||
|
||||
## Telegram
|
||||
|
||||
The Telegram channel supports real-time conversations with users through a bot. It is suitable for overseas user services, community operations, and lightweight message bot scenarios.
|
||||
|
||||
Configuration prerequisites:
|
||||
|
||||
- Use BotFather to create a Telegram bot.
|
||||
- Obtain the `BotToken`.
|
||||
- If using the bot in a group, add it to the target group.
|
||||
- Check the bot privacy mode and group permissions.
|
||||
|
||||
Configuration parameters:
|
||||
|
||||
- **Name**: The channel name displayed in RAGFlow, used to distinguish different Telegram bots.
|
||||
- **BotToken**: The Telegram bot authentication credential. Obtain it from **Telegram > BotFather**. An incorrect value causes the bot to fail to start.
|
||||
|
||||
Usage:
|
||||
|
||||
If you need to use the bot in a group, add it to the target group and confirm that it can receive the messages that need to be processed. Group privacy mode may affect whether the bot can read ordinary messages.
|
||||
|
||||
Connection verification:
|
||||
|
||||
After completing configuration, send a test message to the bot in Telegram to verify whether replies are received normally.
|
||||
|
||||
## WeCom
|
||||
|
||||
The WeCom channel is suitable for providing knowledge Q&A, employee services, and business bot capabilities inside an enterprise. You can select `Webhook` or `WebSocket` access based on the deployment environment.
|
||||
|
||||
Configuration prerequisites:
|
||||
|
||||
- Create a WeCom application or smart bot based on the access method.
|
||||
- When using `Webhook`, prepare the enterprise ID, application ID, application secret, and callback configuration.
|
||||
- When using `WebSocket`, create a smart bot through the WeCom API.
|
||||
- Obtain the `BotID` and `Secret` required by the `WebSocket` method.
|
||||
- Confirm that the bot has been enabled in WeCom.
|
||||
|
||||
Configuration parameters:
|
||||
|
||||
WeCom supports two connection methods: `Webhook` and `WebSocket`. Different parameters are required for different methods.
|
||||
|
||||
Parameters required by the `Webhook` method:
|
||||
|
||||
- **Name**: The channel name displayed in RAGFlow, used to distinguish different WeCom bots.
|
||||
- **ConnectionType**: Select `Webhook`. After selecting it, you need to fill in `CorpID`, `AgentID`, `Secret`, `Token`, and `AESKey`.
|
||||
- **Secret**: The WeCom application secret. Obtain it from **WeCom Admin Console > Application Management**. An incorrect value causes WeCom messages to fail to send.
|
||||
- **CorpID**: The enterprise subject identifier. Obtain it from **WeCom Admin Console > Enterprise Information**. An incorrect value causes callback verification or API authentication to fail.
|
||||
- **AgentID**: The WeCom application identifier. Obtain it from **WeCom Admin Console > Application Management**. An incorrect value causes application message sending to fail.
|
||||
- **Token**: The callback signature verification credential. Obtain it from **WeCom Admin Console > Callback Configuration**. An incorrect value causes callback verification to fail.
|
||||
- **AESKey**: The message encryption and decryption key. Obtain it from **WeCom Admin Console > Callback Configuration**. An incorrect value causes messages to fail to decrypt.
|
||||
|
||||
Parameters required by the `WebSocket` method:
|
||||
|
||||
- **Name**: The channel name displayed in RAGFlow, used to distinguish different WeCom bots.
|
||||
- **ConnectionType**: Select `WebSocket`. After selecting it, you only need to fill in `BotID` and `Secret`.
|
||||
- **BotID**: The WeCom smart bot identifier. Obtain it from **WeCom Admin Console > Smart Bot**. An incorrect value causes long-connection subscription to fail.
|
||||
- **Secret**: The long-connection subscription secret. Obtain it from **WeCom Admin Console > Smart Bot**. An incorrect value causes `WebSocket` authentication to fail.
|
||||
|
||||
Usage:
|
||||
|
||||
The credentials for `Webhook` and `WebSocket` cannot be mixed. When selecting `WebSocket`, first create a smart bot in WeCom, then fill the obtained `BotID` and `Secret` into RAGFlow. When selecting `Webhook`, fill in `CorpID`, `AgentID`, `Secret`, `Token`, and `AESKey` according to the WeCom application callback configuration.
|
||||
|
||||
After saving the channel, connect the WeCom channel to a Chat. After the connection succeeds, users can send messages to the bot in WeCom, and the bot calls the bound Chat to return replies.
|
||||
|
||||
Connection verification:
|
||||
|
||||
After completing configuration, send a test message to the bot in WeCom to verify whether replies are received normally.
|
||||
|
||||
## WhatsApp
|
||||
|
||||
The WhatsApp channel connects an account through QR pairing. It is suitable for service scenarios that use WhatsApp to stay in contact with external users. This method does not require open platform keys to be filled in on the page.
|
||||
|
||||
Configuration prerequisites:
|
||||
|
||||
- Prepare a WhatsApp account that can be connected.
|
||||
- Confirm that the mobile WhatsApp app can scan QR codes.
|
||||
- Confirm that the mobile app can access **Linked devices**.
|
||||
- Confirm that the RAGFlow backend `WhatsAppGateway` is running normally.
|
||||
|
||||
Configuration parameters:
|
||||
|
||||
- **Name**: The channel name displayed in RAGFlow, used to distinguish different WhatsApp connections.
|
||||
|
||||
WhatsApp completes account connection through QR pairing. You do not need to fill in open platform keys on the page. After filling in the name and saving the channel, wait a few seconds until the page generates the QR code used for pairing.
|
||||
|
||||
Usage:
|
||||
|
||||
When adding a WhatsApp channel, fill in the name first and save it. After saving, the page may first display prompt information. Wait a few seconds and use the mobile phone to scan the QR code after it is generated.
|
||||
|
||||
Complete the scanning operation in the mobile WhatsApp app: go to settings, click **Linked devices**, select **Link a device**, and then scan the QR code on the RAGFlow page. After successful scanning, subsequent messages sent by users to this WhatsApp account enter RAGFlow.
|
||||
|
||||
WhatsApp depends on the `WhatsAppGateway` in the RAGFlow backend. By default, RAGFlow connects to the local gateway service and stores the login state in the gateway data directory. Ordinary users do not need to fill in these gateway parameters on the page. If the administrator has separately configured the gateway address, access token, or session directory for the deployment environment, use the runtime environment provided by the administrator.
|
||||
|
||||
Connection verification:
|
||||
|
||||
After completing QR scanning and connecting the channel to a Chat, use another WhatsApp account to send a test message to this account and verify whether replies are received normally.
|
||||
|
||||
:::caution NOTE
|
||||
|
||||
After deleting a WhatsApp channel or clearing the gateway login state, you may need to scan the QR code again for pairing. If the QR code is not displayed for a long time, confirm that `WhatsAppGateway` has started and check network connectivity between the backend service and the gateway.
|
||||
|
||||
:::
|
||||
@@ -0,0 +1,67 @@
|
||||
---
|
||||
sidebar_position: 1
|
||||
title: Chat Channels Overview
|
||||
sidebar_label: Chat Channels Overview
|
||||
slug: /chat_channels_overview
|
||||
sidebar_custom_props: {
|
||||
categoryIcon: LucideMessagesSquare
|
||||
}
|
||||
---
|
||||
|
||||
# Chat Channels Overview
|
||||
|
||||
This chapter describes how to configure chat channels in RAGFlow, including supported platforms, the parameters required by each platform, the workflow for connecting a Chat, and connection verification methods.
|
||||
|
||||
With chat channels, users can chat with a Chat directly in chat applications such as Discord, Telegram, WeCom, and Feishu / Lark. User messages from third-party platforms enter RAGFlow, where the bound Chat generates replies and sends them back to the original chat window.
|
||||
|
||||
Chat channels are responsible only for platform access and message forwarding. Reply content, knowledge base scope, model capabilities, and answer quality are determined by the bound chat model.
|
||||
|
||||
**Supported channels**
|
||||
|
||||
| Chat channel | Access method | Requires an open platform or developer backend | Use case |
|
||||
| --- | --- | --- | --- |
|
||||
| Discord | `BotToken` | Yes | Suitable for Discord community support, product Q&A, and user feedback collection. |
|
||||
| DingTalk | `ClientID` + `ClientSecret` | Yes | Suitable for knowledge Q&A, process consultation, and collaboration support within DingTalk organizations. |
|
||||
| Feishu / Lark | `AppID` + `AppSecret` | Yes | Suitable for enterprise knowledge assistants and internal business Q&A in Feishu or Lark. |
|
||||
| QQ Bot | `AppID` + `ClientSecret` | Yes | Suitable for QQ user services, community Q&A, and channel interactions. |
|
||||
| Telegram | `BotToken` | Yes | Suitable for overseas user services, community operations, and real-time bot conversations. |
|
||||
| WeCom | `Webhook` or `WebSocket` | Yes | Suitable for employee services, knowledge Q&A, and business bots in WeCom. |
|
||||
| WhatsApp | QR pairing | No | Log in to a WhatsApp account by scanning a QR code and forward messages to a Chat. |
|
||||
|
||||
**Enter the Chat Channels page**
|
||||
|
||||
After logging in to RAGFlow, go to **User Settings** and click **Chat channels**. The upper part of the page displays added chat channels, and the lower part displays the channel types currently available to add.
|
||||
|
||||
When using this feature for the first time, the page indicates that no chat channel has been added. You can select the platform you need from the **Available channels** area.
|
||||
|
||||
**General configuration and operation workflow**
|
||||
|
||||
Before completing chat channel configuration, select the appropriate platform based on your actual use case, then create the channel and complete the connection configuration. After configuration, users can connect the chat channel to a Chat and interact with the bot through a third-party platform.
|
||||
|
||||
Operation steps:
|
||||
|
||||
1. Enter the **Chat channels** page.
|
||||
2. Select the platform you need from the **Available channels** area.
|
||||
3. Create the channel and fill in its name.
|
||||
4. Fill in the corresponding credentials or complete QR pairing based on the selected platform.
|
||||
5. Save the channel configuration.
|
||||
6. Connect the chat channel to a Chat.
|
||||
7. Send a test message to the bot in the corresponding third-party platform.
|
||||
|
||||
For some platforms, after saving, it may take a few seconds before the page displays the connection status, QR code, or follow-up operation prompts. Follow the page prompts and do not repeatedly create channels before the QR code or status has been generated.
|
||||
|
||||
After adding a channel, you need to connect it to a Chat. If the channel is enabled but not connected to a Chat, RAGFlow can receive external messages but will not generate replies.
|
||||
|
||||
After you modify bot credentials or the channel type, RAGFlow automatically restarts the corresponding channel connection. If the credentials are incorrect, the channel may fail to start. Return to the third-party platform to confirm whether the bot status, permissions, and keys are valid.
|
||||
|
||||
Configuration result:
|
||||
|
||||
After configuration is complete and the channel is connected to a Chat, the bot in the third-party platform becomes available. When a user sends a message in the corresponding chat application, the bot calls the bound Chat to generate an answer and returns the answer to the original chat window.
|
||||
|
||||
After successful configuration, you can usually see the following results:
|
||||
|
||||
- The bot is online or can be invoked normally in the corresponding platform.
|
||||
- User messages can be received by RAGFlow.
|
||||
- Answers generated by the Chat are returned to the same chat window.
|
||||
|
||||
For example, after completing Discord channel configuration, users can send messages directly to the bot in Discord. The bot calls the bound Chat and returns replies. For the WhatsApp channel, after filling in the name and saving it, the page generates a QR code after a few seconds. After QR pairing is complete and the channel is connected to a Chat, other users who send messages to that WhatsApp account can receive Chat replies.
|
||||
@@ -0,0 +1,23 @@
|
||||
---
|
||||
sidebar_position: 3
|
||||
title: Connect Chat
|
||||
sidebar_label: Connect Chat
|
||||
slug: /connect_chat_channel
|
||||
sidebar_custom_props: {
|
||||
categoryIcon: LucideMessagesSquare
|
||||
}
|
||||
---
|
||||
|
||||
# Connect Chat
|
||||
|
||||
After a chat channel is added successfully, you need to connect it to a Chat. After the connection is complete, user messages received from external channels enter the Chat for answering.
|
||||
|
||||
Operation steps:
|
||||
|
||||
1. Find the added channel on the **Chat channels** page.
|
||||
2. Click the connection or edit entry for that channel.
|
||||
3. Select the target Chat from the available Chat list.
|
||||
4. Save the configuration.
|
||||
5. Return to the corresponding third-party platform and send a test message to the bot.
|
||||
|
||||
If the test message receives no reply, first check whether the channel has been connected to a Chat. Then check whether the bot is online, whether third-party platform permissions are complete, and whether the Chat itself can answer normally on the RAGFlow page.
|
||||
@@ -0,0 +1,27 @@
|
||||
---
|
||||
sidebar_position: 4
|
||||
title: FAQ
|
||||
sidebar_label: FAQ
|
||||
slug: /chat_channels_faq
|
||||
sidebar_custom_props: {
|
||||
categoryIcon: LucideMessagesSquare
|
||||
}
|
||||
---
|
||||
|
||||
# FAQ
|
||||
|
||||
## The Channel Is Saved Successfully but Does Not Reply
|
||||
|
||||
First confirm that the channel has been connected to a Chat. If it is not connected to a Chat, RAGFlow ignores external messages and does not generate replies.
|
||||
|
||||
## The Bot Cannot Start
|
||||
|
||||
Check whether the third-party platform credentials are correct, whether the bot has been enabled, and whether message event permissions have been granted. After credentials are modified, RAGFlow automatically restarts the corresponding channel connection.
|
||||
|
||||
## Messages Can Be Received but Replies Fail
|
||||
|
||||
Check whether the bot has permission to send messages, and confirm that the bound Chat can answer normally on the RAGFlow page. For `WeCom Webhook`, also confirm that `CorpID`, `AgentID`, and `Secret` can obtain `access_token` normally.
|
||||
|
||||
## The WhatsApp QR Code Is Not Displayed
|
||||
|
||||
First confirm that the channel has been saved, then wait a few seconds to see whether the page generates a QR code. If the QR code is still not displayed, confirm that `WhatsAppGateway` has started and that the RAGFlow backend can access the gateway service. If the login state has expired or been cleared, scan the QR code again for pairing.
|
||||
@@ -1,6 +1,6 @@
|
||||
{
|
||||
"label": "Data Sources",
|
||||
"position": 0.5,
|
||||
"position": 10,
|
||||
"link": {
|
||||
"type": "generated-index",
|
||||
"description": "Guides on adding and configuring data sources."
|
||||
|
||||
@@ -1,6 +1,6 @@
|
||||
{
|
||||
"label": "Datasets",
|
||||
"position": 0,
|
||||
"position": 1,
|
||||
"link": {
|
||||
"type": "generated-index",
|
||||
"description": "Guides on configuring a dataset."
|
||||
|
||||
@@ -1,6 +1,6 @@
|
||||
{
|
||||
"label": "File Management",
|
||||
"position": 3.6,
|
||||
"position": 7,
|
||||
"link": {
|
||||
"type": "generated-index",
|
||||
"description": "Guides on creating folders, uploading files, managing file operations, linking knowledge bases, and batch file management in RAGFlow."
|
||||
|
||||
@@ -14,7 +14,6 @@ The file management page allows you to add files directly to a knowledge base. A
|
||||
|
||||
|
||||
|
||||
|
||||
|
||||
## Link a Single File
|
||||
|
||||
|
||||
@@ -1,6 +1,6 @@
|
||||
{
|
||||
"label": "Memory",
|
||||
"position": 3.5,
|
||||
"position": 6,
|
||||
"link": {
|
||||
"type": "generated-index",
|
||||
"description": "Guides on creating, configuring, and using Memory with Agents."
|
||||
|
||||
@@ -22,7 +22,6 @@ A memory must be connected to an Agent before historical messages can be written
|
||||
|
||||
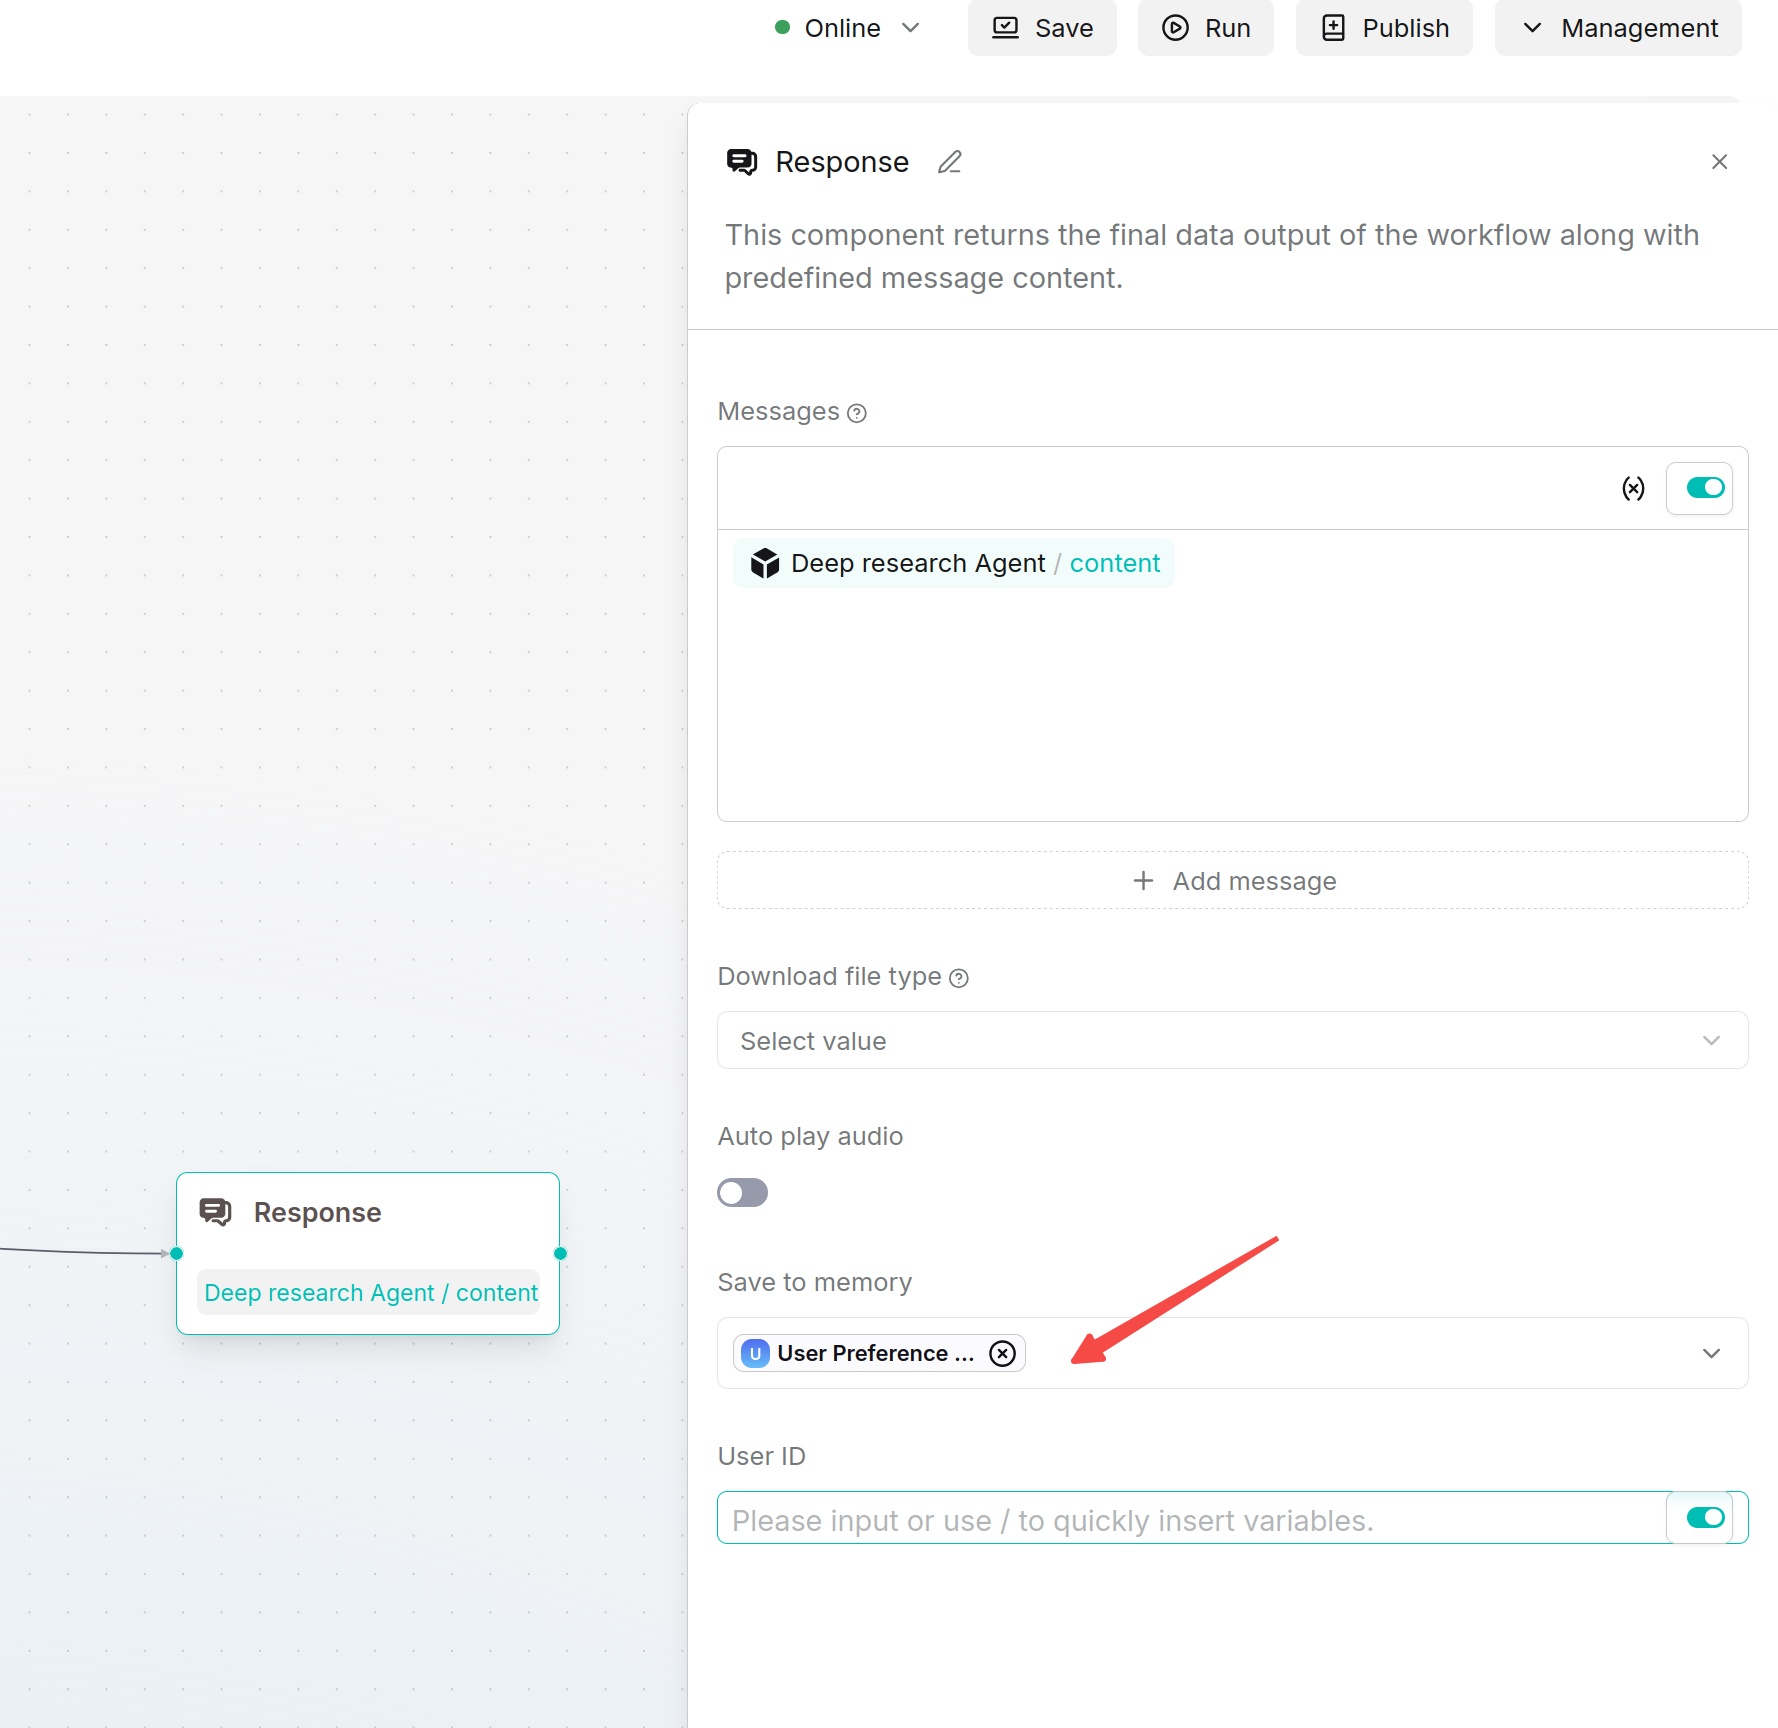
|
||||
|
||||
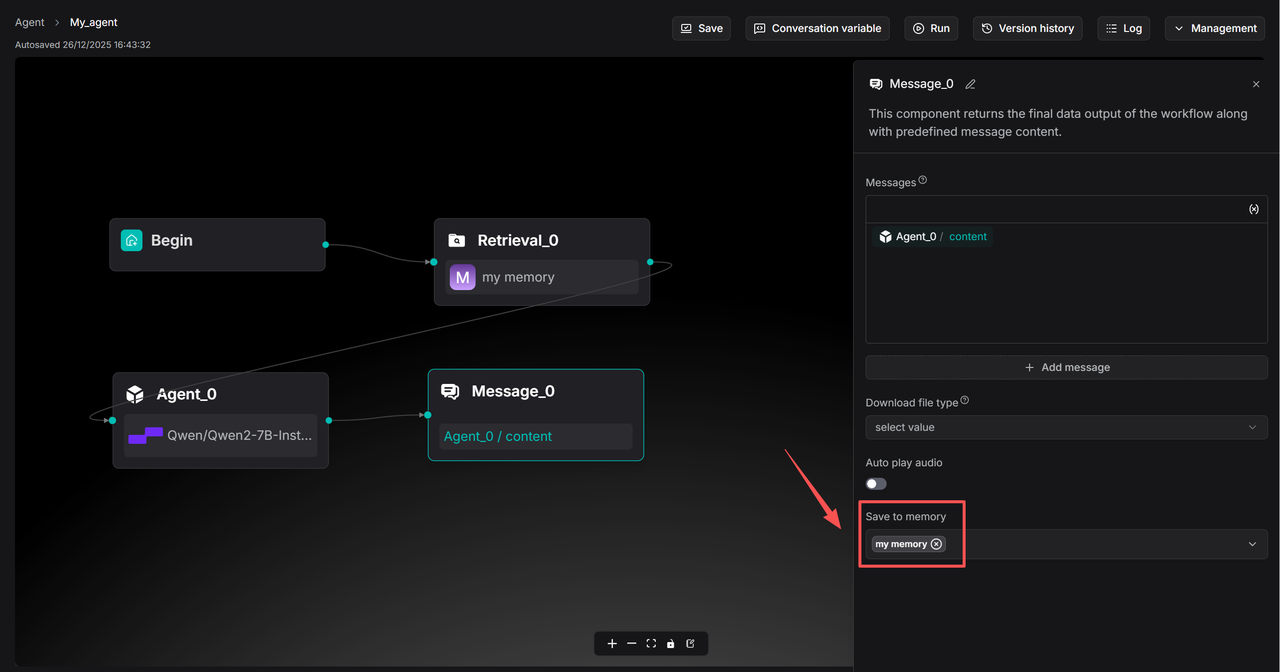
|
||||
|
||||
### Let an Agent Retrieve from Memory
|
||||
|
||||
@@ -33,6 +32,5 @@ A memory must be connected to an Agent before historical messages can be written
|
||||
5. Connect the retrieval result to a subsequent large language model or answer component, so that the Agent can use the retrieved historical context.
|
||||
6. Save and run a test, and check whether the answer correctly references historical memories.
|
||||
|
||||
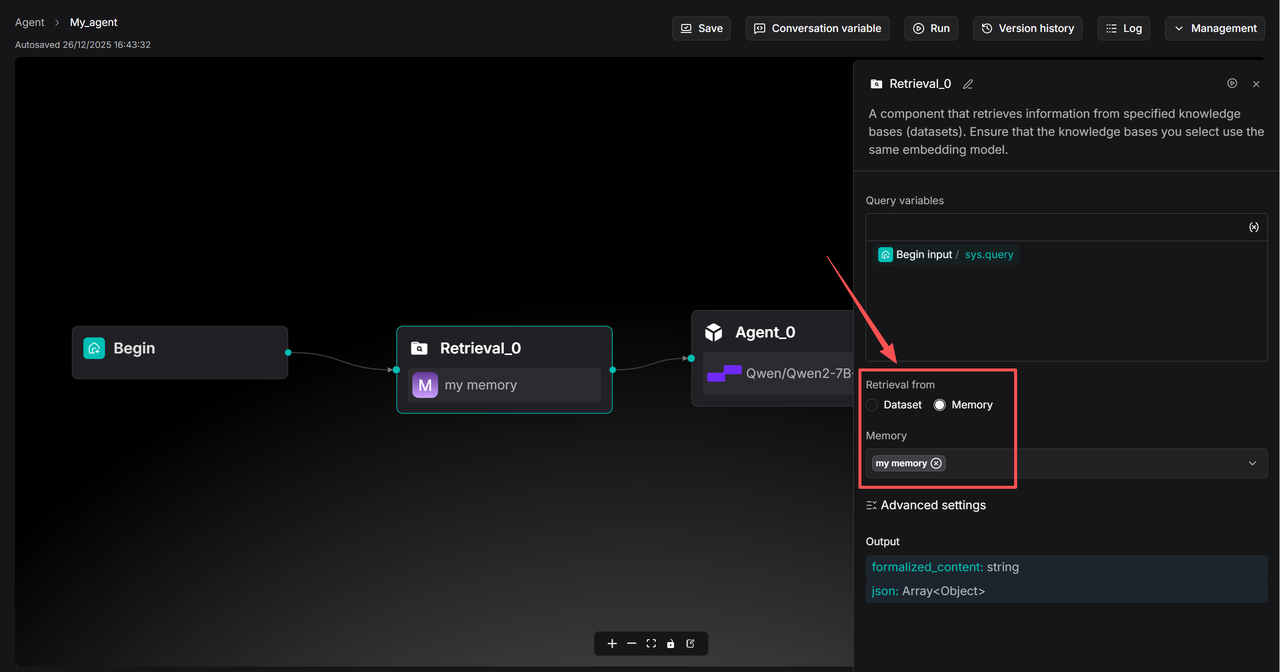
|
||||
|
||||
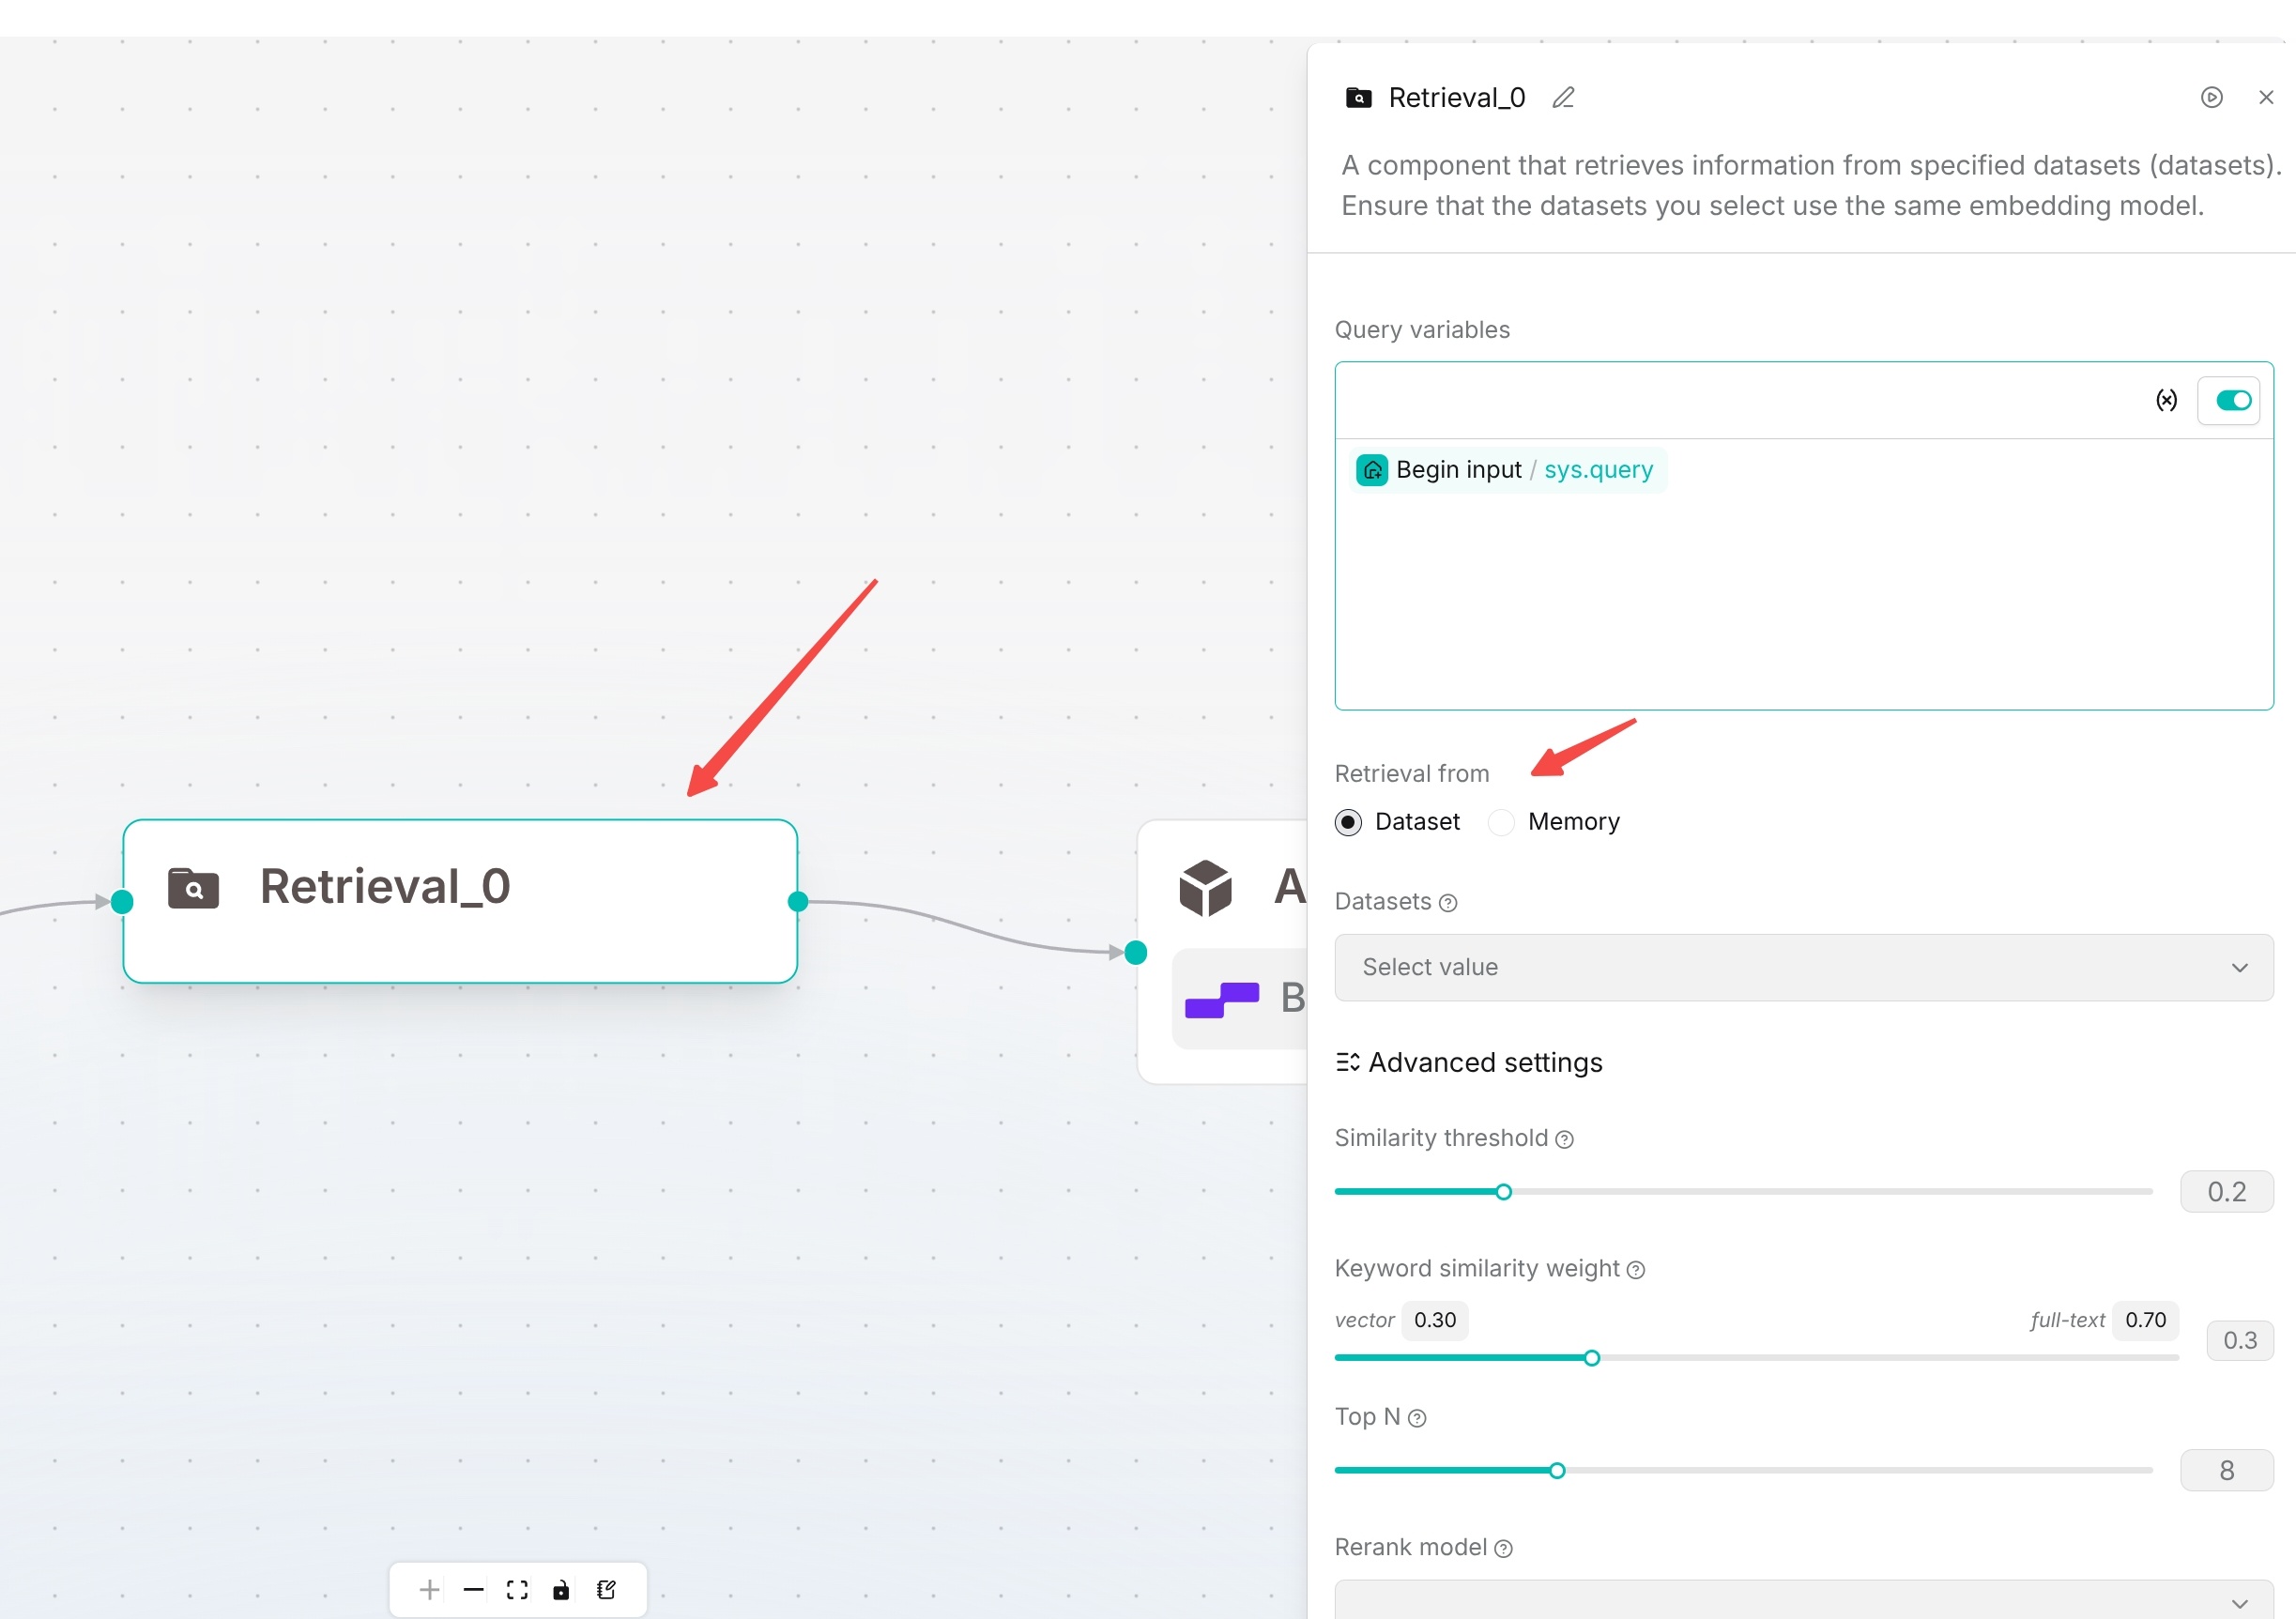
|
||||
|
||||
@@ -12,7 +12,7 @@ sidebar_custom_props: {
|
||||
|
||||
This chapter describes how to create and configure memories in RAGFlow, view and manage messages, and save and retrieve memories in Agents. Memories are used to save conversation content and extraction results generated during Agent execution, helping Agents reuse historical context in subsequent conversations or tasks.
|
||||
|
||||
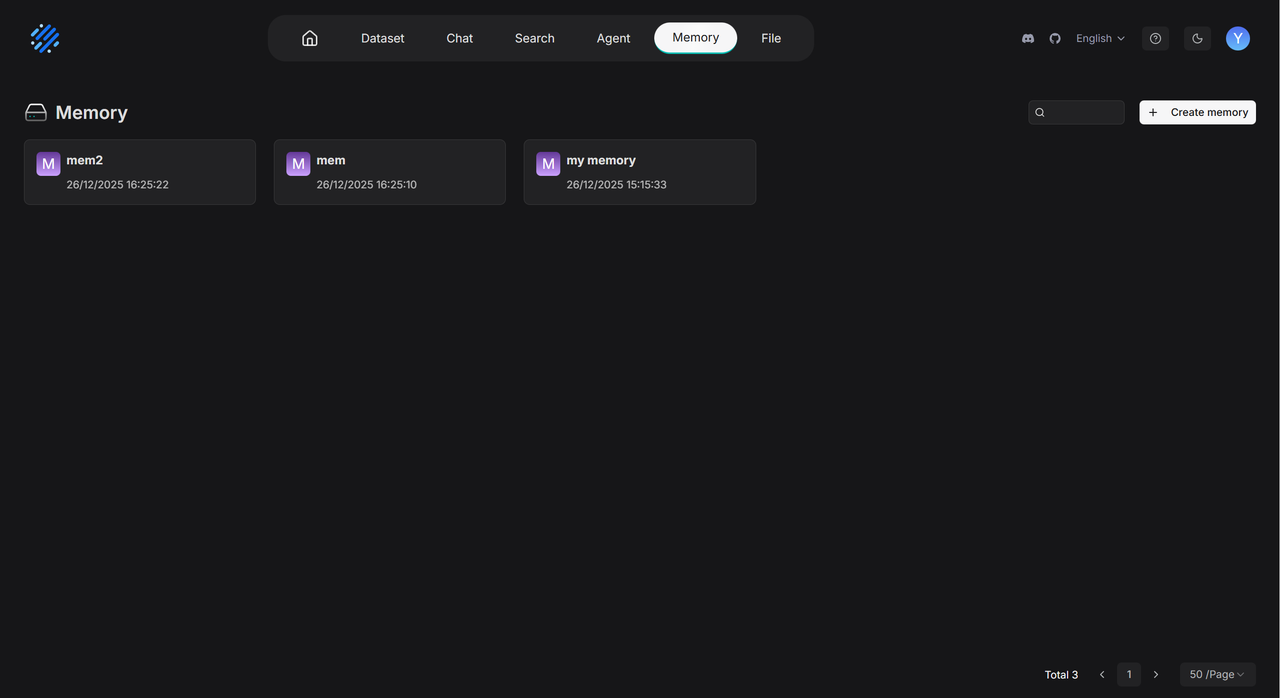
|
||||
|
||||
|
||||
## Create Memory
|
||||
|
||||
|
||||
@@ -12,8 +12,6 @@ sidebar_custom_props: {
|
||||
|
||||
The message page is used to view messages written to memory and control whether messages participate in subsequent retrieval. The left side provides **Messages** and **Configurations** entries, and the right side displays the message list, search, and filters.
|
||||
|
||||
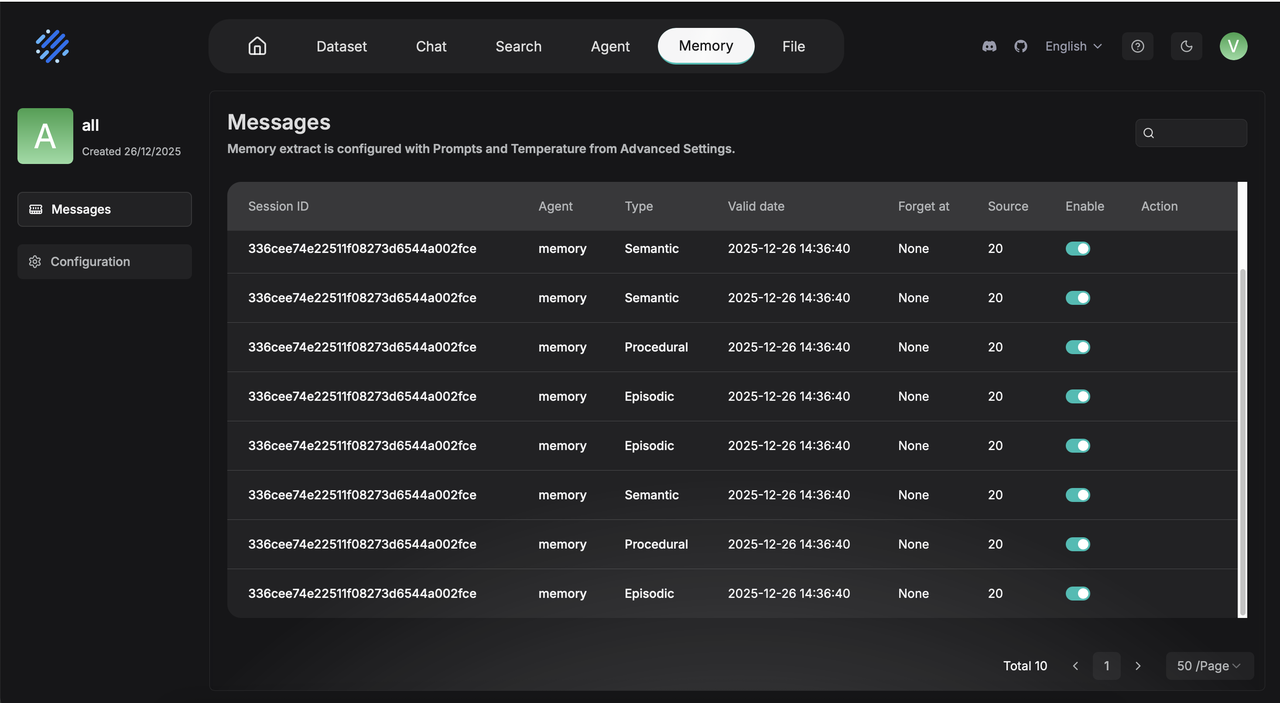
|
||||
|
||||
Memory extraction uses the prompts and temperature in **Advanced Settings** on the configuration page. If the extraction result does not meet expectations, check these configurations first.
|
||||
|
||||
Users can search messages in the current memory's message list, or narrow the search scope through conditional filters.
|
||||
@@ -31,3 +29,5 @@ The message list displays information such as sessions, source Agents, message t
|
||||
| Forgotten at | The time when this message was forgotten. If it has not been forgotten, this is usually displayed as **None** or left empty. |
|
||||
| Enabled | Controls whether this message participates in subsequent retrieval. After it is disabled, the message is still retained, but it no longer affects Agent retrieval results. |
|
||||
| Operation | Used to view, copy, view logs, or forget messages. The specific buttons depend on the current permissions and message status. |
|
||||
|
||||
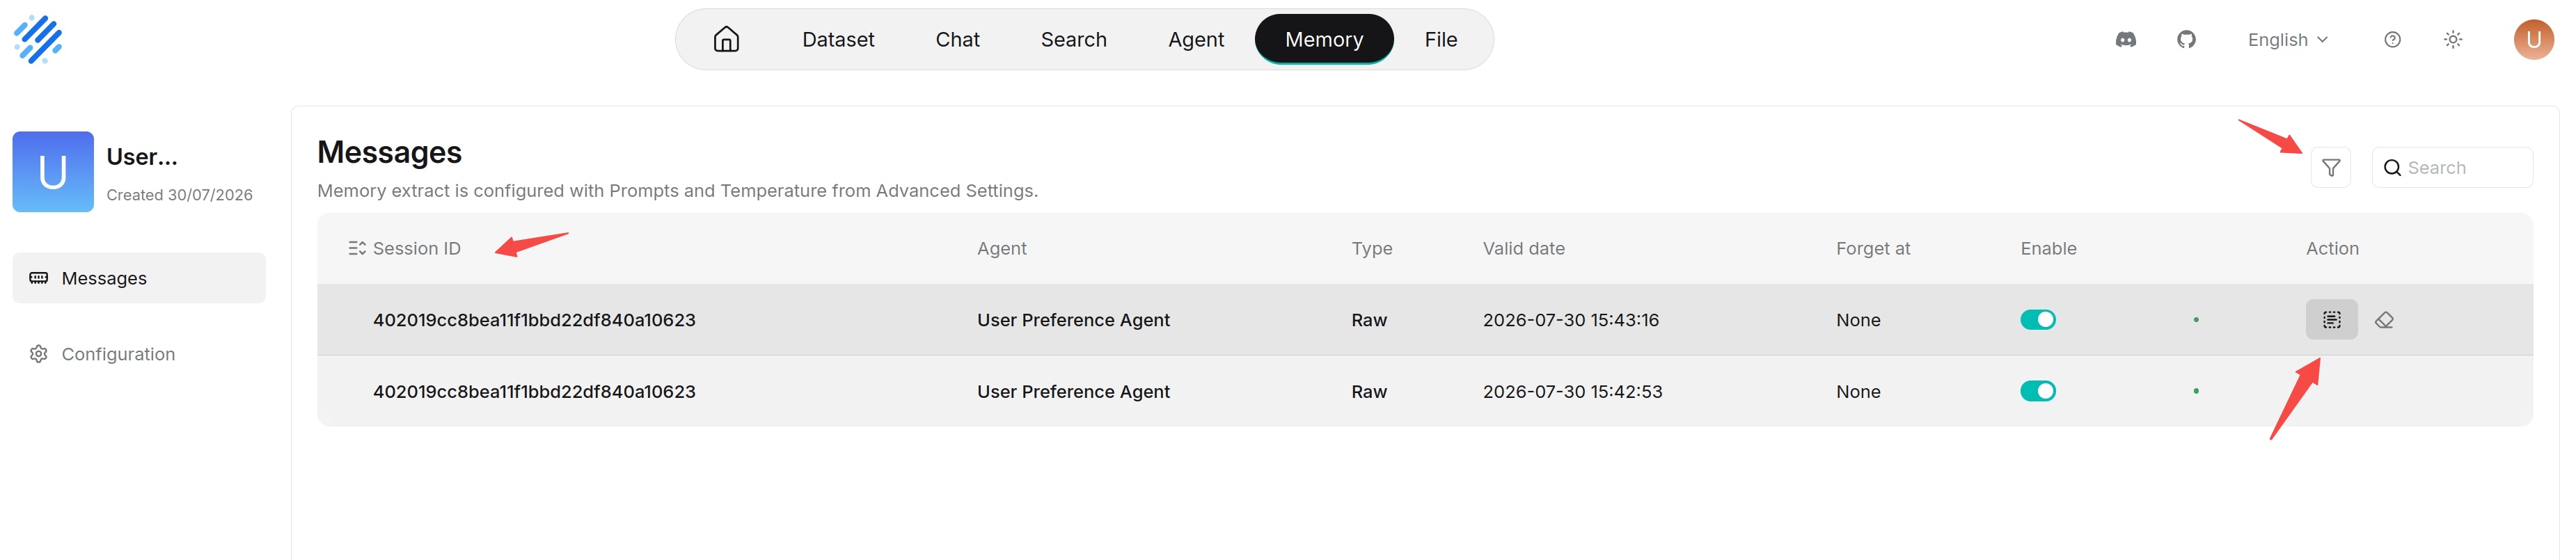
|
||||
@@ -1,6 +1,6 @@
|
||||
{
|
||||
"label": "Models",
|
||||
"position": 8,
|
||||
"position": 9,
|
||||
"link": {
|
||||
"type": "generated-index",
|
||||
"description": "Guides on model settings."
|
||||
|
||||
@@ -1,6 +1,6 @@
|
||||
{
|
||||
"label": "Team",
|
||||
"position": 4,
|
||||
"position": 8,
|
||||
"link": {
|
||||
"type": "generated-index",
|
||||
"description": "Team-specific guides."
|
||||
|
||||
Reference in New Issue
Block a user