 Stefan HeandByronHsu
b735584899
## Summary
<!--- This is a required section; please describe the main purpose of
this proposed code change. --->
Closes https://github.com/linkedin/Liger-Kernel/issues/451

This PR implements dynamic dependency management that automatically
detects the user's hardware platform (CUDA, ROCm, or CPU) and installs
the appropriate dependencies. This ensures a smoother installation
experience across different hardware configurations.

### Key Changes
- Added `_get_platform()` function to detect hardware platform using
`nvidia-smi` or `rocm-smi`
- Implemented `get_default_dependencies()` to return platform-specific
core dependencies
- Implemented `get_optional_dependencies()` to handle dev and
transformers extras
- Updated `pyproject.toml` to use dynamic dependencies from setup.py

### Platform-specific Dependencies
- **CUDA/CPU**:
  - Core: torch>=2.1.2, triton>=2.3.1
- Full dev environment including transformers, testing tools, and
visualization libraries

- **ROCm**:
- Core: torch>=2.6.0.dev, triton>=3.0.0, plus ROCm-specific requirements
  - Streamlined dev dependencies focused on essential tools


<!---
## Details
This is an optional section; is there anything specific that reviewers
should be aware of?
--->

### setup.py vs pyproject.toml

#### setup.py
- Traditional Python package configuration
- Allows dynamic configuration via Python code
- Needed for complex/conditional dependencies
- Supports custom build steps

#### pyproject.toml
- Modern, static configuration (PEP 517/518)
- Cleaner, declarative format
- Works well with modern tools (poetry, hatch)
- Preferred for simple packages

#### Using Both
- `pyproject.toml`: Build system specs, basic metadata
- `setup.py`: Dynamic dependencies, custom build logic

- Common in projects needing both static config and dynamic install
-
## Testing Done (In Progress)
<!--- This is a required section; please describe how this change was
tested. --->
1. Clone the repository
2. Test installation on different platforms:
   ```bash
   # Basic installation
   pip install -e .

   # With dev tools
   pip install -e .[dev]

   # With transformers
   pip install -e .[dev,transformers]
   ```

- [x] CPU
- [x] CUDA - NVIDIA
  Tested with following config
  - NVIDIA-SMI 535.129.03
  - Driver Version: 535.129.03
  - CUDA Version: 12.2
- [ ] ROCm - AMD
  - Need help from the community to test on ROCm platform

<!--
Replace BLANK with your device type. For example, A100-80G-PCIe

Complete the following tasks before sending your PR, and replace `[ ]`
with
`[x]` to indicate you have done them.
-->

## Hardware Type:

- NVIDIA-SMI 535.129.03
- CUDA Version: 12.2

- [x] run `make test` to ensure correctness
- [x] run `make checkstyle` to ensure code style
- [x] run `make test-convergence` to ensure convergence

---------

Co-authored-by: ByronHsu <[email protected]>
Liger Kernel: Efficient Triton Kernels for LLM Training
| Stable | Nightly | Discord | Build | ||
|---|---|---|---|---|---|
|

|
|
|
|


|
Installation | Getting Started | Examples | High-level APIs | Low-level APIs | Cite our work
Latest News 🔥
- [2024/12/15] We release LinkedIn Engineering Blog - Liger-Kernel: Empowering an open source ecosystem of Triton Kernels for Efficient LLM Training
- [2024/11/6] We release v0.4.0: Full AMD support, Tech Report, Modal CI, Llama-3.2-Vision!
- [2024/10/21] We have released the tech report of Liger Kernel on Arxiv: https://arxiv.org/pdf/2410.10989
- [2024/9/6] We release v0.2.1 (X post). 2500+ Stars, 10+ New Contributors, 50+ PRs, 50k Downloads in two weeks!
- [2024/8/31] CUDA MODE talk, Liger-Kernel: Real-world Triton kernel for LLM Training, Slides
- [2024/8/23] Official release: check out our X post
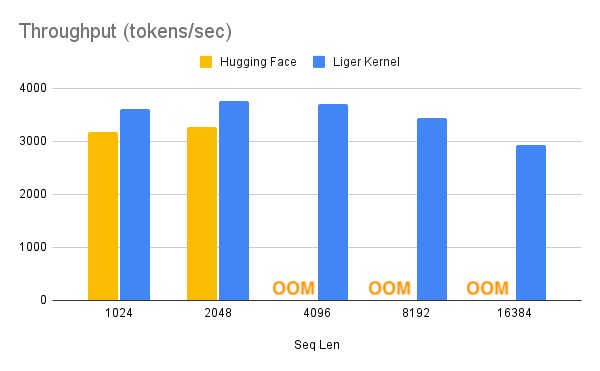
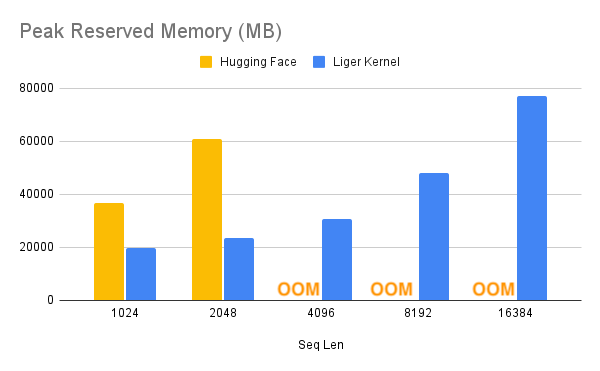
Liger Kernel is a collection of Triton kernels designed specifically for LLM training. It can effectively increase multi-GPU training throughput by 20% and reduces memory usage by 60%. We have implemented Hugging Face Compatible RMSNorm, RoPE, SwiGLU, CrossEntropy, FusedLinearCrossEntropy, and more to come. The kernel works out of the box with Flash Attention, PyTorch FSDP, and Microsoft DeepSpeed. We welcome contributions from the community to gather the best kernels for LLM training.
We've also added optimized Post-Training kernels that deliver up to 80% memory savings for alignment and distillation tasks. We support losses like DPO, CPO, ORPO, SimPO, JSD, and many more.
Supercharge Your Model with Liger Kernel
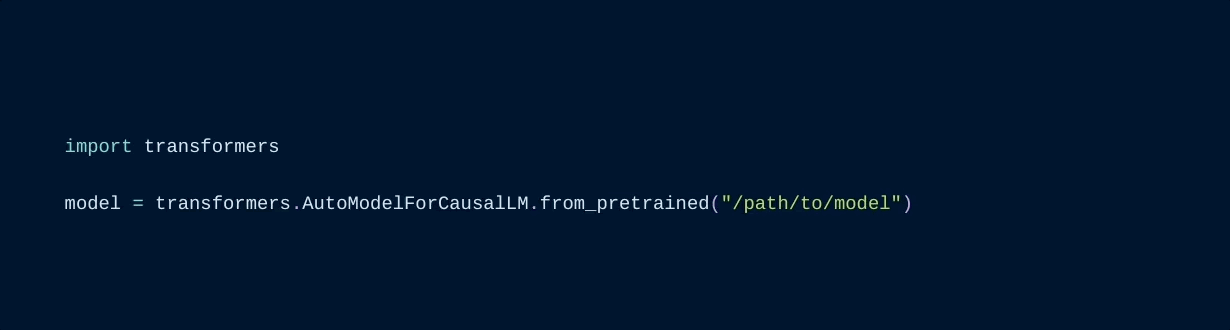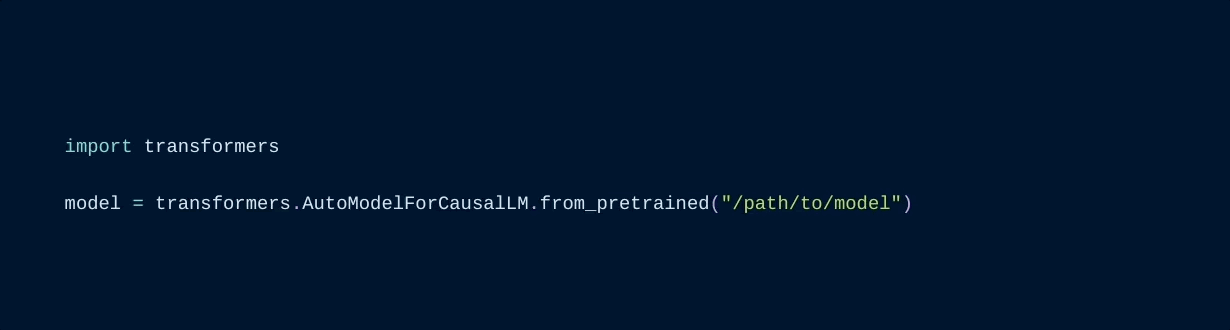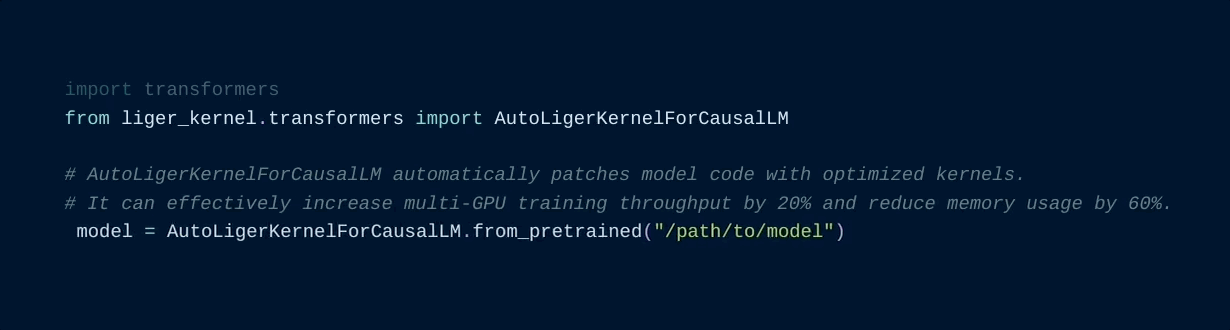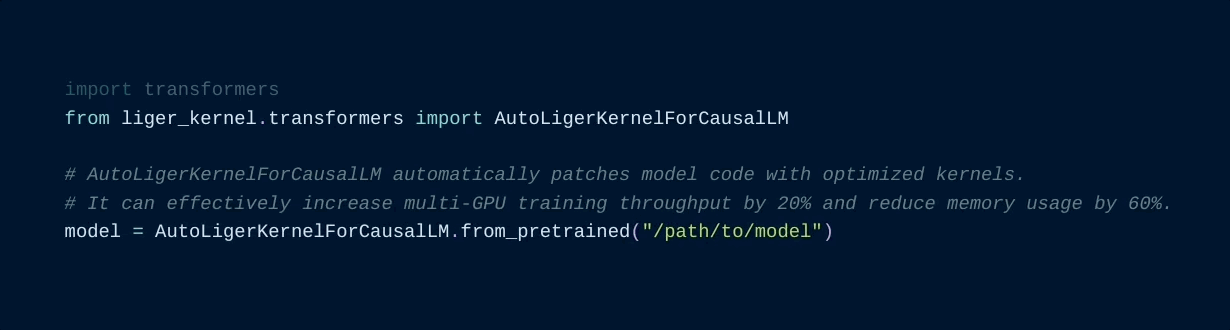
With one line of code, Liger Kernel can increase throughput by more than 20% and reduce memory usage by 60%, thereby enabling longer context lengths, larger batch sizes, and massive vocabularies.
| Speed Up | Memory Reduction |
|---|---|
 |
 |
Note:
- Benchmark conditions: LLaMA 3-8B, Batch Size = 8, Data Type =
bf16, Optimizer = AdamW, Gradient Checkpointing = True, Distributed Strategy = FSDP1 on 8 A100s.- Hugging Face models start to OOM at a 4K context length, whereas Hugging Face + Liger Kernel scales up to 16K.
Examples
| Use Case | Description |
|---|---|
| Hugging Face Trainer | Train LLaMA 3-8B ~20% faster with over 40% memory reduction on Alpaca dataset using 4 A100s with FSDP |
| Lightning Trainer | Increase 15% throughput and reduce memory usage by 40% with LLaMA3-8B on MMLU dataset using 8 A100s with DeepSpeed ZeRO3 |
| Medusa Multi-head LLM (Retraining Phase) | Reduce memory usage by 80% with 5 LM heads and improve throughput by 40% using 8 A100s with FSDP |
| Vision-Language Model SFT | Finetune Qwen2-VL on image-text data using 4 A100s with FSDP |
| Liger ORPO Trainer | Align Llama 3.2 using Liger ORPO Trainer with FSDP with 50% memory reduction |
Key Features
- Ease of use: Simply patch your Hugging Face model with one line of code, or compose your own model using our Liger Kernel modules.
- Time and memory efficient: In the same spirit as Flash-Attn, but for layers like RMSNorm, RoPE, SwiGLU, and CrossEntropy! Increases multi-GPU training throughput by 20% and reduces memory usage by 60% with kernel fusion, in-place replacement, and chunking techniques.
- Exact: Computation is exact—no approximations! Both forward and backward passes are implemented with rigorous unit tests and undergo convergence testing against training runs without Liger Kernel to ensure accuracy.
- Lightweight: Liger Kernel has minimal dependencies, requiring only Torch and Triton—no extra libraries needed! Say goodbye to dependency headaches!
- Multi-GPU supported: Compatible with multi-GPU setups (PyTorch FSDP, DeepSpeed, DDP, etc.).
- Trainer Framework Integration: Axolotl, LLaMa-Factory, SFTTrainer, Hugging Face Trainer, SWIFT
Installation
Dependencies
CUDA
torch >= 2.1.2triton >= 2.3.0
ROCm
torch >= 2.5.0Install according to the instruction in Pytorch official webpage.triton >= 3.0.0Install from pypi. (e.g.pip install triton==3.0.0)
Optional Dependencies
transformers >= 4.x: Required if you plan to use the transformers models patching APIs. The specific model you are working will dictate the minimum version of transformers.
Note: Our kernels inherit the full spectrum of hardware compatibility offered by Triton.
To install the stable version:
$ pip install liger-kernel
To install the nightly version:
$ pip install liger-kernel-nightly
To install from source:
git clone https://github.com/linkedin/Liger-Kernel.git
cd Liger-Kernel

# Install Default Dependencies
# Setup.py will detect whether you are using AMD or NVIDIA
pip install -e .

# Setup Development Dependencies
pip install -e ".[dev]"
Getting Started
There are a couple of ways to apply Liger kernels, depending on the level of customization required.
1. Use AutoLigerKernelForCausalLM
Using the AutoLigerKernelForCausalLM is the simplest approach, as you don't have to import a model-specific patching API. If the model type is supported, the modeling code will be automatically patched using the default settings.
from liger_kernel.transformers import AutoLigerKernelForCausalLM

# This AutoModel wrapper class automatically monkey-patches the
# model with the optimized Liger kernels if the model is supported.
model = AutoLigerKernelForCausalLM.from_pretrained("path/to/some/model")
2. Apply Model-Specific Patching APIs
Using the patching APIs, you can swap Hugging Face models with optimized Liger Kernels.
import transformers
from liger_kernel.transformers import apply_liger_kernel_to_llama

# 1a. Adding this line automatically monkey-patches the model with the optimized Liger kernels
apply_liger_kernel_to_llama()

# 1b. You could alternatively specify exactly which kernels are applied
apply_liger_kernel_to_llama(
  rope=True,
  swiglu=True,
  cross_entropy=True,
  fused_linear_cross_entropy=False,
  rms_norm=False
)

# 2. Instantiate patched model
model = transformers.AutoModelForCausalLM("path/to/llama/model")
3. Compose Your Own Model
You can take individual kernels to compose your models.
from liger_kernel.transformers import LigerFusedLinearCrossEntropyLoss
import torch.nn as nn
import torch

model = nn.Linear(128, 256).cuda()

# fuses linear + cross entropy layers together and performs chunk-by-chunk computation to reduce memory
loss_fn = LigerFusedLinearCrossEntropyLoss()

input = torch.randn(4, 128, requires_grad=True, device="cuda")
target = torch.randint(256, (4, ), device="cuda")

loss = loss_fn(model.weight, input, target)
loss.backward()
High-level APIs
AutoModel
| AutoModel Variant | API |
|---|---|
| AutoModelForCausalLM | liger_kernel.transformers.AutoLigerKernelForCausalLM |
Patching
| Model | API | Supported Operations |
|---|---|---|
| LLaMA 2 & 3 | liger_kernel.transformers.apply_liger_kernel_to_llama |
RoPE, RMSNorm, SwiGLU, CrossEntropyLoss, FusedLinearCrossEntropy |
| LLaMA 3.2-Vision | liger_kernel.transformers.apply_liger_kernel_to_mllama |
RoPE, RMSNorm, SwiGLU, CrossEntropyLoss, FusedLinearCrossEntropy |
| Mistral | liger_kernel.transformers.apply_liger_kernel_to_mistral |
RoPE, RMSNorm, SwiGLU, CrossEntropyLoss, FusedLinearCrossEntropy |
| Mixtral | liger_kernel.transformers.apply_liger_kernel_to_mixtral |
RoPE, RMSNorm, SwiGLU, CrossEntropyLoss, FusedLinearCrossEntropy |
| Gemma1 | liger_kernel.transformers.apply_liger_kernel_to_gemma |
RoPE, RMSNorm, GeGLU, CrossEntropyLoss, FusedLinearCrossEntropy |
| Gemma2 | liger_kernel.transformers.apply_liger_kernel_to_gemma2 |
RoPE, RMSNorm, GeGLU, CrossEntropyLoss, FusedLinearCrossEntropy |
| Qwen2, Qwen2.5, & QwQ | liger_kernel.transformers.apply_liger_kernel_to_qwen2 |
RoPE, RMSNorm, SwiGLU, CrossEntropyLoss, FusedLinearCrossEntropy |
| Qwen2-VL | liger_kernel.transformers.apply_liger_kernel_to_qwen2_vl |
RMSNorm, LayerNorm, SwiGLU, CrossEntropyLoss, FusedLinearCrossEntropy |
| Phi3 & Phi3.5 | liger_kernel.transformers.apply_liger_kernel_to_phi3 |
RoPE, RMSNorm, SwiGLU, CrossEntropyLoss, FusedLinearCrossEntropy |
Low-level APIs
Fused Linearkernels combine linear layers with losses, reducing memory usage by up to 80% - ideal for HBM-constrained workloads.- Other kernels use fusion and in-place techniques for memory and performance optimization.
Model Kernels
| Kernel | API |
|---|---|
| RMSNorm | liger_kernel.transformers.LigerRMSNorm |
| LayerNorm | liger_kernel.transformers.LigerLayerNorm |
| RoPE | liger_kernel.transformers.liger_rotary_pos_emb |
| SwiGLU | liger_kernel.transformers.LigerSwiGLUMLP |
| GeGLU | liger_kernel.transformers.LigerGEGLUMLP |
| CrossEntropy | liger_kernel.transformers.LigerCrossEntropyLoss |
| Fused Linear CrossEntropy | liger_kernel.transformers.LigerFusedLinearCrossEntropyLoss |
Alignment Kernels
| Kernel | API |
|---|---|
| Fused Linear CPO Loss | liger_kernel.chunked_loss.LigerFusedLinearCPOLoss |
| Fused Linear DPO Loss | liger_kernel.chunked_loss.LigerFusedLinearDPOLoss |
| Fused Linear ORPO Loss | liger_kernel.chunked_loss.LigerFusedLinearORPOLoss |
| Fused Linear SimPO Loss | liger_kernel.chunked_loss.LigerFusedLinearSimPOLoss |
Distillation Kernels
| Kernel | API |
|---|---|
| KLDivergence | liger_kernel.transformers.LigerKLDIVLoss |
| JSD | liger_kernel.transformers.LigerJSD |
| Fused Linear JSD | liger_kernel.transformers.LigerFusedLinearJSD |
Experimental Kernels
| Kernel | API |
|---|---|
| Embedding | liger_kernel.transformers.experimental.LigerEmbedding |
| Matmul int2xint8 | liger_kernel.transformers.experimental.matmul |
Contributing, Acknowledgements, and License
Sponsorship and Collaboration
- AMD: Providing AMD GPUs for our AMD CI.
- Intel: Providing Intel GPUs for our Intel CI.
- Modal: Free 3000 credits from GPU MODE IRL for our NVIDIA CI.
- EmbeddedLLM: Making Liger Kernel run fast and stable on AMD.
- HuggingFace: Integrating Liger Kernel into Hugging Face Transformers and TRL.
- Lightning AI: Integrating Liger Kernel into Lightning Thunder.
- Axolotl: Integrating Liger Kernel into Axolotl.
- Llama-Factory: Integrating Liger Kernel into Llama-Factory.
Contact
- For issues, create a Github ticket in this repository
- For open discussion, join our discord channel
- For formal collaboration, send an email to [email protected]
Cite this work
Biblatex entry:
@article{hsu2024ligerkernelefficienttriton,
      title={Liger Kernel: Efficient Triton Kernels for LLM Training},
      author={Pin-Lun Hsu and Yun Dai and Vignesh Kothapalli and Qingquan Song and Shao Tang and Siyu Zhu and Steven Shimizu and Shivam Sahni and Haowen Ning and Yanning Chen},
      year={2024},
      eprint={2410.10989},
      archivePrefix={arXiv},
      primaryClass={cs.LG},
      url={https://arxiv.org/abs/2410.10989},
      journal={arXiv preprint arXiv:2410.10989},
}