mirror of
https://github.com/microsoft/semantic-kernel.git
synced 2026-10-12 02:19:06 +00:00
Update docs (#3)
Improve the main readme, supporting both users willing to clone and run
samples, developers looking to create a new app using the nuget package,
and contributors looking for ways to participate.

Added additional technical docs, explaining some important concepts and
touching on various aspects of the project, e.g. architecture and
nomenclature.
This commit is contained in:
 Devis Lucato
+39
-29
@@ -1,34 +1,39 @@
|
||||
# Contributing to Semantic Kernel
|
||||
|
||||
You can contribute to Semantic Kernel with issues and pull requests (PRs). Simply filing issues
|
||||
for problems you encounter is a great way to contribute. Contributing code is greatly appreciated.
|
||||
You can contribute to Semantic Kernel with issues and pull requests (PRs). Simply
|
||||
filing issues for problems you encounter is a great way to contribute. Contributing
|
||||
code is greatly appreciated.
|
||||
|
||||
## Reporting Issues
|
||||
|
||||
We always welcome bug reports, API proposals and overall feedback. Here are a few tips on how
|
||||
you can make reporting your issue as effective as possible.
|
||||
We always welcome bug reports, API proposals and overall feedback. Here are a few
|
||||
tips on how you can make reporting your issue as effective as possible.
|
||||
|
||||
### Where to Report
|
||||
|
||||
New issues can be reported in our [list of issues](https://github.com/semantic-kernel/issues).
|
||||
|
||||
Before filing a new issue, please search the list of issues to make sure it does not already exist.
|
||||
Before filing a new issue, please search the list of issues to make sure it does
|
||||
not already exist.
|
||||
|
||||
If you do find an existing issue for what you wanted to report, please include your own feedback
|
||||
in the discussion. Do consider upvoting (👍 reaction) the original post, as this helps us
|
||||
prioritize popular issues in our backlog.
|
||||
If you do find an existing issue for what you wanted to report, please include
|
||||
your own feedback in the discussion. Do consider upvoting (👍 reaction) the original
|
||||
post, as this helps us prioritize popular issues in our backlog.
|
||||
|
||||
### Writing a Good Bug Report
|
||||
|
||||
Good bug reports make it easier for maintainers to verify and root cause the underlying problem.
|
||||
The better a bug report, the faster the problem will be resolved. Ideally, a bug report should
|
||||
contain the following information:
|
||||
Good bug reports make it easier for maintainers to verify and root cause the
|
||||
underlying problem.
|
||||
The better a bug report, the faster the problem will be resolved. Ideally, a bug
|
||||
report should contain the following information:
|
||||
|
||||
- A high-level description of the problem.
|
||||
- A _minimal reproduction_, i.e. the smallest size of code/configuration required to reproduce the wrong behavior.
|
||||
- A _minimal reproduction_, i.e. the smallest size of code/configuration required
|
||||
to reproduce the wrong behavior.
|
||||
- A description of the _expected behavior_, contrasted with the _actual behavior_ observed.
|
||||
- Information on the environment: OS/distribution, CPU architecture, SDK version, etc.
|
||||
- Additional information, e.g. Is it a regression from previous versions? Are there any known workarounds?
|
||||
- Additional information, e.g. Is it a regression from previous versions? Are there
|
||||
any known workarounds?
|
||||
|
||||
## Contributing Changes
|
||||
|
||||
@@ -38,8 +43,10 @@ Project maintainers will merge accepted code changes from contributors.
|
||||
|
||||
DO's:
|
||||
|
||||
- **DO** follow the standard .NET [coding style](https://learn.microsoft.com/dotnet/csharp/fundamentals/coding-style/coding-conventions)
|
||||
- **DO** give priority to the current style of the project or file you're changing if it diverges from the general guidelines.
|
||||
- **DO** follow the standard
|
||||
[.NET coding style](https://learn.microsoft.com/dotnet/csharp/fundamentals/coding-style/coding-conventions)
|
||||
- **DO** give priority to the current style of the project or file you're changing
|
||||
if it diverges from the general guidelines.
|
||||
- **DO** include tests when adding new features. When fixing bugs, start with
|
||||
adding a test that highlights how the current behavior is broken.
|
||||
- **DO** keep the discussions focused. When a new or related topic comes up
|
||||
@@ -53,15 +60,15 @@ DON'Ts:
|
||||
a discussion so we can agree on a direction before you invest a large amount of time.
|
||||
- **DON'T** commit code that you didn't write. If you find code that you think is a good
|
||||
fit to add to Semantic Kernel, file an issue and start a discussion before proceeding.
|
||||
- **DON'T** submit PRs that alter licensing related files or headers. If you believe there's
|
||||
a problem with them, file an issue and we'll be happy to discuss it.
|
||||
- **DON'T** submit PRs that alter licensing related files or headers. If you believe
|
||||
there's a problem with them, file an issue and we'll be happy to discuss it.
|
||||
- **DON'T** make new APIs without filing an issue and discussing with us first.
|
||||
|
||||
### Breaking Changes
|
||||
|
||||
Contributions must maintain API signature and behavioral compatibility. Contributions that include
|
||||
breaking changes will be rejected. Please file an issue to discuss your idea or change if you
|
||||
believe that a breaking change is warranted.
|
||||
Contributions must maintain API signature and behavioral compatibility. Contributions
|
||||
that include breaking changes will be rejected. Please file an issue to discuss
|
||||
your idea or change if you believe that a breaking change is warranted.
|
||||
|
||||
### Suggested Workflow
|
||||
|
||||
@@ -70,13 +77,15 @@ We use and recommend the following workflow:
|
||||
1. Create an issue for your work.
|
||||
- You can skip this step for trivial changes.
|
||||
- Reuse an existing issue on the topic, if there is one.
|
||||
- Get agreement from the team and the community that your proposed change is a good one.
|
||||
- Clearly state that you are going to take on implementing it, if that's the case. You can
|
||||
request that the issue be assigned to you. Note: The issue filer and the implementer
|
||||
don't have to be the same person.
|
||||
- Get agreement from the team and the community that your proposed change is
|
||||
a good one.
|
||||
- Clearly state that you are going to take on implementing it, if that's the case.
|
||||
You can request that the issue be assigned to you. Note: The issue filer and
|
||||
the implementer don't have to be the same person.
|
||||
2. Create a personal fork of the repository on GitHub (if you don't already have one).
|
||||
3. In your fork, create a branch off of main (`git checkout -b mybranch`).
|
||||
- Name the branch so that it clearly communicates your intentions, such as issue-123 or githubhandle-issue.
|
||||
- Name the branch so that it clearly communicates your intentions, such as
|
||||
"issue-123" or "githubhandle-issue".
|
||||
4. Make and commit your changes to your branch.
|
||||
5. Add new tests corresponding to your change, if applicable.
|
||||
6. Build the repository with your changes.
|
||||
@@ -90,8 +99,9 @@ We use and recommend the following workflow:
|
||||
|
||||
### PR - CI Process
|
||||
|
||||
The continuous integration (CI) system will automatically perform the required builds and
|
||||
run tests (including the ones you are expected to run) for PRs. Builds and test runs must be clean.
|
||||
The continuous integration (CI) system will automatically perform the required
|
||||
builds and run tests (including the ones you are expected to run) for PRs. Builds
|
||||
and test runs must be clean.
|
||||
|
||||
If the CI build fails for any reason, the PR issue will be updated with a link that
|
||||
can be used to determine the cause of the failure.
|
||||
If the CI build fails for any reason, the PR issue will be updated with a link
|
||||
that can be used to determine the cause of the failure.
|
||||
|
||||
@@ -2,52 +2,86 @@
|
||||
|
||||
[](https://github.com/microsoft/semantic-kernel/actions/workflows/dotnet-ci.yml)
|
||||
|
||||
This repository is where we (Microsoft) develop the Semantic Kernel product together with you, the community.
|
||||
**Semantic Kernel (SK)** is a lightweight SDK enabling integration of AI Large
|
||||
Language Models (LLMs) with conventional programming languages. The SK extensible
|
||||
programming model combines natural language **semantic functions**, traditional
|
||||
code **native functions**, and **embeddings-based memory** unlocking new potential
|
||||
and adding value to applications with AI.
|
||||
|
||||
## About Semantic Kernel
|
||||
SK supports
|
||||
[prompt templating](docs/PROMPT_TEMPLATE_LANGUAGE.md), function
|
||||
chaining,
|
||||
[vectorized memory](docs/EMBEDDINGS.md), and
|
||||
[intelligent planning](docs/PLANNER.md)
|
||||
capabilities out of the box.
|
||||
|
||||
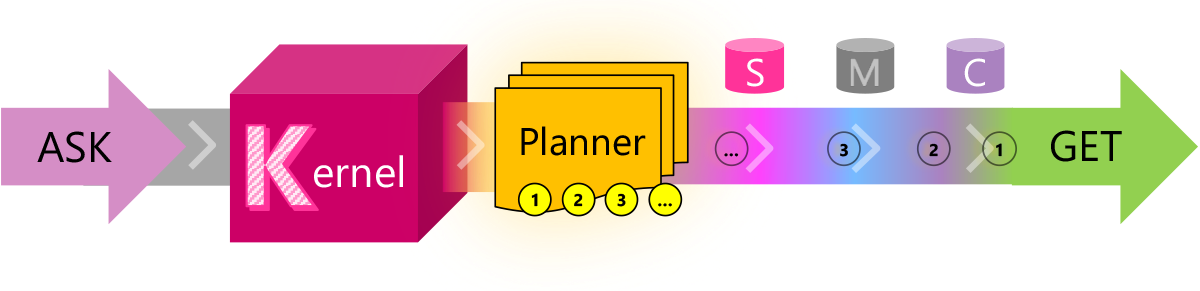
Semantic Kernel is a lightweight SDK that offers a simple, powerful, and consistent programming model mixing
|
||||
traditional code with AI and "semantic" functions, covering multiple programming languages and platforms.
|
||||
|
||||
|
||||
Semantic Kernel is designed to support and encapsulate several design patterns from the latest in AI research
|
||||
such that developers can infuse their applications with complex skills like prompt chaining, recursive reasoning,
|
||||
summarization, zero/few-shot learning, contextual memory, long-term memory, embeddings, semantic indexing,
|
||||
planning, and accessing external knowledge stores as well as your own data.
|
||||
Semantic Kernel is designed to support and encapsulate several design patterns from the
|
||||
latest in AI research, such that developers can infuse their applications with complex
|
||||
[skills](docs/SKILLS.md) like [prompt](docs/PROMPT_TEMPLATE_LANGUAGE.md) chaining,
|
||||
recursive reasoning, summarization, zero/few-shot learning, contextual memory,
|
||||
long-term memory, [embeddings](docs/EMBEDDINGS.md), semantic indexing, [planning](docs/PLANNER.md),
|
||||
and accessing external knowledge stores as well as your own data.
|
||||
|
||||
## Getting Started ⚡
|
||||
By joining the SK community, you can build AI-first apps faster and have a front-row
|
||||
peek at how the SDK is being built. SK has been released as open-source so that more
|
||||
pioneering developers can join us in crafting the future of this landmark moment
|
||||
in the history of computing.
|
||||
|
||||
To get started with Semantic Kernel, you can clone the semantic-kernel repository:
|
||||
## Samples ⚡
|
||||
|
||||
If you would like a quick overview about how Semantic Kernel can integrate with your
|
||||
app, start by cloning the repository:
|
||||
|
||||
```shell
|
||||
git clone https://github.com/microsoft/semantic-kernel.git
|
||||
```
|
||||
|
||||
And then run the [getting started notebook](samples/notebooks/dotnet/Getting-Started-Notebook.ipynb)
|
||||
or try the samples:
|
||||
and try these examples:
|
||||
|
||||
- [Simple chat summary](samples/apps/chat-summary-webapp-react/README.md) (**Recommended**)
|
||||
- [Book creator](samples/apps/book-creator-webapp-react/README.md)
|
||||
- [Authentication and APIs](samples/apps/auth-api-webapp-react/README.md)
|
||||
| | |
|
||||
| ----------------------------------------------------------------------- | --------------------------------------------------------------------------------------------------------------------------------- |
|
||||
| [Simple chat summary](samples/apps/chat-summary-webapp-react/README.md) | Use ready-to-use skills and get those skills into your app easily. |
|
||||
| [Book creator](samples/apps/book-creator-webapp-react/README.md) | Use planner to deconstruct a complex goal and envision using the planner in your app. |
|
||||
| [Authentication and APIs](samples/apps/auth-api-webapp-react/README.md) | Use a basic connector pattern to authenticate and connect to an API and imagine integrating external data into your app's LLM AI. |
|
||||
|
||||
Alternatively, you can also can create a C# app that uses the SDK (see next section).
|
||||
For a more hands-on overview, you can also run the
|
||||
[Getting Started notebook](samples/notebooks/dotnet/Getting-Started-Notebook.ipynb),
|
||||
looking into the syntax, creating
|
||||
[Semantic Functions](docs/GLOSSARY.md),
|
||||
working with Memory, and see how the kernel works.
|
||||
|
||||
**IMPORTANT** - You will need an [Open AI Key](https://openai.com/api/) or
|
||||
[Azure Open AI Service key](https://learn.microsoft.com/azure/cognitive-services/openai/quickstart?pivots=rest-api)
|
||||
to get started.
|
||||
**Please note:**
|
||||
|
||||
**IMPORTANT** - There are [software requirements](https://aka.ms/SK-Requirements)
|
||||
you may need to satisfy for running the samples and notebooks.
|
||||
- You will need an
|
||||
[Open AI API Key](https://openai.com/api/) or
|
||||
[Azure Open AI service key](https://learn.microsoft.com/azure/cognitive-services/openai/quickstart?pivots=rest-api)
|
||||
to get started.
|
||||
- There are a few software requirements you may need to satisfy before running examples and notebooks:
|
||||
1. [Azure Functions Core Tools](https://learn.microsoft.com/azure/azure-functions/functions-run-local)
|
||||
used for running the kernel as a local API, required by the web apps.
|
||||
2. [Yarn](https://yarnpkg.com/getting-started/install) used for installing
|
||||
web apps' dependencies.
|
||||
3. [.NET 7](https://dotnet.microsoft.com/download) and VS Code
|
||||
[Polyglot extension](https://marketplace.visualstudio.com/items?itemName=ms-dotnettools.dotnet-interactive-vscode)
|
||||
to run the notebooks.
|
||||
|
||||
## Use Semantic Kernel in a C# Console App
|
||||
## Get Started with Semantic Kernel ⚡
|
||||
|
||||
Here is a quick example of how to use Semantic Kernel from a C# app.
|
||||
Here is a quick example of how to use Semantic Kernel from a C# console app.
|
||||
|
||||
Create a new project targeting .NET 3.1 or newer, and add the
|
||||
`Microsoft.SemanticKernel` nuget package.
|
||||
1. Create a new project, targeting .NET 3.1 or newer, and add the
|
||||
`Microsoft.SemanticKernel` nuget package:
|
||||
|
||||
Copy and paste the following code into your project, with your Azure OpenAI
|
||||
key in hand. If you need to create one, go
|
||||
[here](https://learn.microsoft.com/azure/cognitive-services/openai/quickstart?pivots=rest-api).
|
||||
dotnet add package Microsoft.SemanticKernel --version <version number>
|
||||
|
||||
See [nuget.org](https://www.nuget.org/packages/Microsoft.SemanticKernel/) for
|
||||
the latest version and more instructions.
|
||||
|
||||
2. Copy and paste the following code into your project, with your Azure OpenAI
|
||||
key in hand (you can create one
|
||||
[here](https://learn.microsoft.com/azure/cognitive-services/openai/quickstart?pivots=rest-api)).
|
||||
|
||||
```csharp
|
||||
using Microsoft.SemanticKernel;
|
||||
@@ -56,7 +90,7 @@ using Microsoft.SemanticKernel.KernelExtensions;
|
||||
var kernel = Kernel.Builder.Build();
|
||||
|
||||
kernel.Config.AddAzureOpenAICompletionBackend(
|
||||
"azure_davinci", // Internal alias
|
||||
"davinci-backend", // Alias used by the kernel
|
||||
"text-davinci-003", // Azure OpenAI *Deployment ID*
|
||||
"https://contoso.openai.azure.com/", // Azure OpenAI *Endpoint*
|
||||
"...your Azure OpenAI Key..." // Azure OpenAI *Key*
|
||||
@@ -90,12 +124,22 @@ Console.WriteLine(summary);
|
||||
|
||||
## Contributing and Community
|
||||
|
||||
There are many ways in which you can participate in this project:
|
||||
We welcome your contributions and suggestions to SK community! One of the easiest
|
||||
ways to participate is to engage in discussions in the GitHub repository.
|
||||
Bug reports and fixes are welcome!
|
||||
|
||||
- [Contribute](CONTRIBUTING.md) to the project
|
||||
- Submit [Issues](https://github.com/microsoft/semantic-kernel/issues)
|
||||
- Join the [Discord community](https://aka.ms/SKDiscord)
|
||||
- Learn more at the [documentation site](https://aka.ms/SK-Docs)
|
||||
For new features, components, or extensions, please open an issue and discuss with
|
||||
us before sending a PR. This is to avoid rejection as we might be taking the core
|
||||
in a different direction, but also to consider the impact on the larger ecosystem.
|
||||
|
||||
To learn more and get started, please read our [Contributing page](CONTRIBUTING.md)
|
||||
and check some of our documentation:
|
||||
|
||||
* [SK Prompt Template Language](docs/PROMPT_TEMPLATE_LANGUAGE.md)
|
||||
* [SKills and Functions](docs/SKILLS.md)
|
||||
* [Embeddings and Semantic Memory](docs/EMBEDDINGS.md)
|
||||
* [SK Planner](docs/PLANNER.md)
|
||||
* [SK Notebooks](samples/notebooks/dotnet/README.md)
|
||||
|
||||
## Code of Conduct
|
||||
|
||||
|
||||
+1
-1
@@ -2,7 +2,7 @@
|
||||
|
||||
Cosine similarity is a measure of the degree of similarity between two vectors in
|
||||
a multi-dimensional space. It is commonly used in artificial intelligence and natural
|
||||
language processing to compare [embeddings](README.md),
|
||||
language processing to compare [embeddings](EMBEDDINGS.md),
|
||||
which are numerical representations of
|
||||
words or other objects.
|
||||
|
||||
@@ -7,7 +7,7 @@ elements of each vector and then summing the results.
|
||||
|
||||
The dot product has many applications in computer science, particularly in artificial
|
||||
intelligence and machine learning. One common use case for the dot product is to
|
||||
measure the similarity between two vectors, such as word [embeddings](README.md)
|
||||
measure the similarity between two vectors, such as word [embeddings](EMBEDDINGS.md)
|
||||
or image embeddings. This can be useful when trying to find similar words or images
|
||||
in a dataset.
|
||||
|
||||
@@ -21,7 +21,18 @@ meaningful representations of words that can be used in machine learning models.
|
||||
Embeddings can be used in many different applications, including sentiment analysis,
|
||||
document classification, and recommendation systems. They are particularly useful
|
||||
when working with unstructured text data where traditional methods like bag-of-words
|
||||
models struggle.
|
||||
models struggle, and are a fundamental part of **SK Semantic Memory**.
|
||||
|
||||
**Semantic Memory** is similar to how the human brain stores and retrieves knowledge about
|
||||
the world. Embeddings are used to create a semantic memory by **representing concepts
|
||||
or entities as vectors in a high-dimensional space**. This approach allows the model
|
||||
to learn relationships between concepts and make inferences based on similarity or
|
||||
distance between vector representations. For example, the Semantic Memory can be
|
||||
trained to understand that "Word" and "Excel" are related concepts because they are
|
||||
both document types and both Microsoft products, even though they use different
|
||||
file formats and provide different features. This type of memory is useful in
|
||||
many applications, including question-answering systems, natural language understanding,
|
||||
and knowledge graphs.
|
||||
|
||||
Software developers can use pre-trained embedding model, or train their one with their
|
||||
own custom datasets. Pre-trained embedding models have been trained on large amounts
|
||||
@@ -36,23 +47,27 @@ the meaning of words in a computationally efficient manner.
|
||||
|
||||
Some examples about embeddings applications.
|
||||
|
||||
1. Recommender systems: Embeddings can be used to represent the items in a recommender
|
||||
system, allowing for more accurate recommendations based on similarity between items.
|
||||
1. Semantic Memory: Embeddings can be used to create a semantic memory, by which
|
||||
a machine can learn to understand the meanings of words and sentences and can
|
||||
understand the relationships between them.
|
||||
|
||||
2. Natural Language Processing (NLP): Embeddings can be used to represent words or
|
||||
sentences in NLP tasks such as sentiment analysis, named entity recognition, and
|
||||
text classification.
|
||||
|
||||
3. Image recognition: Embeddings can be used to represent images in computer vision
|
||||
3. Recommender systems: Embeddings can be used to represent the items in a recommender
|
||||
system, allowing for more accurate recommendations based on similarity between items.
|
||||
|
||||
4. Image recognition: Embeddings can be used to represent images in computer vision
|
||||
tasks such as object detection and image classification.
|
||||
|
||||
4. Anomaly detection: Embeddings can be used to represent data points in high-dimensional
|
||||
5. Anomaly detection: Embeddings can be used to represent data points in high-dimensional
|
||||
datasets, making it easier to identify outliers or anomalous data points.
|
||||
|
||||
5. Graph analysis: Embeddings can be used to represent nodes in a graph, allowing
|
||||
6. Graph analysis: Embeddings can be used to represent nodes in a graph, allowing
|
||||
for more efficient graph analysis and visualization.
|
||||
|
||||
6. Personalization: Embeddings can be used to represent users in personalized recommendation
|
||||
7. Personalization: Embeddings can be used to represent users in personalized recommendation
|
||||
systems or personalized search engines.
|
||||
|
||||
## Vector Operations used with Embeddings
|
||||
+1
-1
@@ -12,7 +12,7 @@ In higher dimensions, this formula can be generalized to:
|
||||
d = √(x2 - x1)² + (y2 - y1)² + ... + (zn - zn-1)²
|
||||
|
||||
Euclidean distance has many applications in computer science and artificial intelligence,
|
||||
particularly when working with [embeddings](README.md). Embeddings are numerical
|
||||
particularly when working with [embeddings](EMBEDDINGS.md). Embeddings are numerical
|
||||
representations of data that capture the underlying structure and relationships
|
||||
between different data points. They are commonly used in natural language processing,
|
||||
computer vision, and recommendation systems.
|
||||
@@ -3,7 +3,7 @@
|
||||
To wrap your mind around the concepts we present throughout the kernel, here is a glossary of
|
||||
commonly used terms
|
||||
|
||||
**Semantic Kernel (SK)** - The orchestrator that fulfills a user's ASK with SK's available SKILLS.
|
||||
**Semantic Kernel (SK)** - The orchestrator that fulfills a user's ASK with SK's available [SKILLS](SKILLS.md).
|
||||
|
||||
**Ask** - What a user requests to the Semantic Kernel to help achieve the user's goal.
|
||||
|
||||
@@ -13,18 +13,19 @@ commonly used terms
|
||||
|
||||
- "We have a SKILL for using Office better"
|
||||
|
||||
**Function** - A computational machine comprised of Semantic AI and/or native code that's available in a SKILL.
|
||||
**Function** - A computational machine comprised of Semantic AI and/or native code that's available in a [SKILL](SKILLS.md).
|
||||
|
||||
- "The Office SKILL has many FUNCTIONs"
|
||||
|
||||
**Native Function** - expressed with traditional computing language (C#, Python, Typescript)
|
||||
and easily integrates with SK
|
||||
|
||||
**Semantic Function** - expressed in natural language in a text file "*skprompt.txt*" using SK's Prompt
|
||||
Template language. Each semantic function is defined by a unique prompt template file, developed using modern
|
||||
**Semantic Function** - expressed in natural language in a text file "*skprompt.txt*" using SK's
|
||||
[Prompt Template language](PROMPT_TEMPLATE_LANGUAGE.md).
|
||||
Each semantic function is defined by a unique prompt template file, developed using modern
|
||||
**prompt engineering** techniques.
|
||||
|
||||
**Memory** - a collection of semantic knowledge, based on facts, events, documents, indexed with **embeddings**.
|
||||
**Memory** - a collection of semantic knowledge, based on facts, events, documents, indexed with **[embeddings](EMBEDDINGS.md)**.
|
||||
|
||||
<p align="center">
|
||||
<img width="682" alt="image" src="https://user-images.githubusercontent.com/371009/221690406-caaff98e-87b5-40b7-9c58-cfa9623789b5.png">
|
||||
@@ -0,0 +1,41 @@
|
||||
# SK Planner
|
||||
|
||||

|
||||
|
||||
The planner works backwards from a goal that’s provided from a user's ASK.
|
||||
|
||||

|
||||
|
||||
We call this approach "goal-oriented AI" — harking back to the early days of AI
|
||||
when researchers aspired for computers to beat the world's reigning chess champion.
|
||||
That grand goal was achieved eventually, but with the unusual competence of new
|
||||
LLM AI models to provide step-by-step directions for practically any goal can be
|
||||
attainable when the right
|
||||
[skills](SKILLS.md)
|
||||
are available.
|
||||
|
||||
Because the planner has access to either a pre-defined library of pre-made skills
|
||||
and/or a dynamically defined set of skills it is able to fulfill an
|
||||
[ASK](GLOSSARY.md)
|
||||
with confidence. In addition, the planner calls upon memories to best situate the
|
||||
ASK's context and connectors to call APIs and to leverage other external
|
||||
capabilities.
|
||||
|
||||
# What is the value of "goal-oriented" AI?
|
||||
|
||||
The *[Jobs To Be Done (JTBD)](https://hbr.org/2016/09/know-your-customers-jobs-to-be-done)*
|
||||
movement has popularized a shift in moving from work outputs to work outcomes. Instead
|
||||
of focusing on the features or the functions of a product or a service, the JTBD
|
||||
approach emphasizes the goals and desires of the customer or the user, and the value
|
||||
or the benefit that they seek or expect from using the product or service. By
|
||||
understanding and articulating the JTBD of the customer or the user, a product or
|
||||
service can be designed and delivered more effectively. You just need to make the
|
||||
right ASK that isn't just "turn on the lights" and instead a more challenging goal
|
||||
like "I want a job promotion."
|
||||
|
||||
# What if the Planner needs a Skill that's unavailable?
|
||||
|
||||
The planner will operate within the skills it has available. In the event that a
|
||||
desired skill does not exist, the planner can suggest you to create the skill.
|
||||
Or, depending upon the level of complexity the kernel can help you write the missing
|
||||
skill.
|
||||
@@ -1,7 +1,20 @@
|
||||
Prompts are the inputs or queries that a user or a program gives to an LLM AI,
|
||||
in order to elicit a specific response from the model.
|
||||
|
||||
Prompts can be natural
|
||||
language sentences or questions, or code snippets or commands, or any combination
|
||||
of text or code, depending on the domain and the task.
|
||||
|
||||
Prompts can also be nested
|
||||
or chained, meaning that the output of one prompt can be used as the input of another
|
||||
prompt, creating more complex and dynamic interactions with the model.
|
||||
|
||||
# SK Prompt Template Syntax
|
||||
|
||||
The Semantic Kernel prompt template language is a simple and powerful way to
|
||||
define and compose AI functions **using plain text**.
|
||||
define and compose AI
|
||||
[functions](GLOSSARY.md)
|
||||
**using plain text**.
|
||||
You can use it to create natural language prompts, generate responses, extract
|
||||
information, **invoke other prompts** or perform any other task that can be
|
||||
expressed with text.
|
||||
@@ -0,0 +1,80 @@
|
||||
# What are Skills?
|
||||
|
||||

|
||||
|
||||
A skill refers to a domain of expertise made available to the kernel as a single
|
||||
function, or as a group of functions related to the skill* The design of SK skills
|
||||
has prioritized maximum flexibility for the developer to be both lightweight and
|
||||
extensible.
|
||||
|
||||
# What is a Function?
|
||||
|
||||

|
||||
|
||||
A function is the basic building block for a skill. A function can be expressed
|
||||
as either:
|
||||
|
||||
1. an LLM AI prompt — also called a "semantic" function
|
||||
2. native computer code -- also called a "native" function
|
||||
|
||||
When using native computer code, it's also possible to invoke an LLM AI prompt —
|
||||
which means that there can be functions that are hybrid LLM AI × native code as well.
|
||||
|
||||
Functions can be connected end-to-end, or "chained together," to create more powerful
|
||||
capabilities. When they are represented as pure LLM AI prompts in semantic functions,
|
||||
the word "function" and "prompt" can be used interchangeably.
|
||||
|
||||
# What is the relationship between semantic functions and skills?
|
||||
|
||||
A skill is the container in which functions live. You can think of a semantic skill
|
||||
as a directory of folders that contain multiple directories of semantic functions
|
||||
or a single directory as well.
|
||||
|
||||
```
|
||||
SkillName (directory name)
|
||||
│
|
||||
└─── Function1Name (directory name)
|
||||
│
|
||||
└─── Function2Name (directory name)
|
||||
```
|
||||
|
||||
Each function directory will have an skprompt.txt file and a config.json file. There's
|
||||
much more to learn about semantic functions in Building Semantic Functions if you
|
||||
wish to go deeper.
|
||||
|
||||
# What is the relationship between native functions and skills?
|
||||
|
||||
Native functions are loosely inspired by Azure Functions and exist as individual
|
||||
native skill files as in MyNativeSkill.cs below:
|
||||
|
||||
```
|
||||
MyAppSource
|
||||
│
|
||||
└───MySkillsDirectory
|
||||
│
|
||||
└─── MySemanticSkill (a directory)
|
||||
| │
|
||||
| └─── MyFirstSemanticFunction (a directory)
|
||||
| └─── MyOtherSemanticFunction (a directory)
|
||||
│
|
||||
└─── MyNativeSkill.cs (a file)
|
||||
└─── MyOtherNativeSkill.cs (a file)
|
||||
```
|
||||
|
||||
Each file will contain multiple native functions that are associated with a skill.
|
||||
|
||||
# Where to find skills in the GitHub repo
|
||||
|
||||
Skills are stored in one of three places:
|
||||
|
||||
1. Core Skills: these are skills available at any time to the kernel that embody
|
||||
a few standard capabilities like working with time, text, files, http requests,
|
||||
and the [Planner](PLANNER.md). The core skills can be found
|
||||
[here](../dotnet/src/SemanticKernel/CoreSkills).
|
||||
|
||||
2. Semantic Skills: these skills are managed by you in a directory of your choice.
|
||||
|
||||
3. Native Skills: these skills are also managed by you in a directory of your choice.
|
||||
|
||||
For more examples of skills, and the ones that we use in our sample apps, look inside
|
||||
the [/samples/skills](../samples/skills) folder.
|
||||
@@ -13,5 +13,4 @@ stores as well as your own data.
|
||||
## Getting Started ⚡
|
||||
|
||||
- Check out the [GitHub repository](https://github.com/microsoft/semantic-kernel) for the latest updates
|
||||
- Join the [Discord community](https://aka.ms/SKDiscord)
|
||||
- Learn more at the [documentation site](https://aka.ms/SK-Docs)
|
||||
|
||||
@@ -39,7 +39,3 @@ Each function will call Microsoft Graph and/or Open AI to perform the tasks.
|
||||
|
||||
> [!CAUTION]
|
||||
> Each function will call Open AI which will use tokens that you will be billed for.
|
||||
|
||||
## Next Steps
|
||||
|
||||
Join the [Discord community](https://aka.ms/SKDiscord).
|
||||
|
||||
@@ -34,8 +34,6 @@ creates a plan for the functions to run based on the ask. You can see the plan a
|
||||
[Authentication and APIs](../auth-api-webapp-react/README.md) – learn how to connect
|
||||
to external API's with authentication while using Semantic Kernel.
|
||||
|
||||
Join the [Discord community](https://aka.ms/SKDiscord).
|
||||
|
||||
## Deeper Learning Tips
|
||||
|
||||
- Try modifying the language that the book is translated to via editing
|
||||
|
||||
@@ -37,9 +37,7 @@ can edit or just add more to the chat while you are on the page.
|
||||
## Next Steps: Try a more advanced sample app
|
||||
|
||||
[Book creator](../book-creator-webapp-react/README.md) – learn how Planner and chaining
|
||||
of semantic functions can be used in your app
|
||||
|
||||
Join the [Discord community](https://aka.ms/SKDiscord).
|
||||
of semantic functions can be used in your app.
|
||||
|
||||
## Deeper Learning Tips
|
||||
|
||||
|
||||
@@ -40,5 +40,3 @@ Sample app learning examples:
|
||||
- [Authentication and APIs](../../apps/auth-api-webapp-react/README.md) – learn how to connect to external
|
||||
API's with authentication while using Semantic Kernel
|
||||
- GitHub Repo Q&A (coming soon) – learn how Memories and Embeddings can be used in your app
|
||||
|
||||
Join the [Discord community](https://aka.ms/SKDiscord).
|
||||
|
||||
@@ -213,21 +213,6 @@
|
||||
"- [Book creator](../../apps/book-creator-webapp-react/README.md) – learn how Planner and chaining of semantic functions can be used in your app\n",
|
||||
"- [Authenication and APIs](../../dotnet/graph-api-skills/README.md) – learn how to connect to external API's with authenication while using Semantic Kernel"
|
||||
]
|
||||
},
|
||||
{
|
||||
"attachments": {},
|
||||
"cell_type": "markdown",
|
||||
"metadata": {
|
||||
"dotnet_interactive": {
|
||||
"language": "csharp"
|
||||
},
|
||||
"polyglot_notebook": {
|
||||
"kernelName": "csharp"
|
||||
}
|
||||
},
|
||||
"source": [
|
||||
"Join the [Discord community](https://aka.ms/SKDiscord)."
|
||||
]
|
||||
}
|
||||
],
|
||||
"metadata": {
|
||||
|
||||
Reference in New Issue
Block a user