f5eef7da8a
Removes the `/expr` runtime-introspection endpoint, everything that
exists only
to serve it, and the forked expression library it depended on.

### Why

`/expr` evaluated a caller-supplied expression against live in-process
objects
(`param`, `proxy`, `cache`, and the component servers) and returned the
result.
It was useful for reading an effective config value or unexported state
without
a debugger or a rebuild, but the cost is hard to justify for what it
does:

- It required a fork of `expr-lang/expr` whose purpose is to remove the
library's sandbox. The first commit on that fork is "Support the private
field
and auto change the struct to the point when exec the method". Upstream
deliberately refuses unexported-field access; the fork exists to allow
it.
- That fork sits on a personal account, is 81 commits behind upstream,
and was
last pushed in May 2025. `go.mod` pinned it through `replace`, making it
build-critical. Every other `replace` in that block points at
`milvus-io/*`.
- Nothing else imports the library. `pkg/util/expr/expr.go` was the only
importer, using four symbols: `expr.Compile`, `expr.Env`,
`expr.WithContext`
and `vm.VM.Run`. The fork's ~550 lines of product code add no API; they
change
the behaviour of those four calls. Swapping back to upstream would
therefore
still compile and still pass CI, and break only at runtime — no test in
the
tree exercises unexported-field access, pointer-method calls,
`mapValue`, the
  `view` builtin, or automatic type conversion.

Removing the endpoint removes the only reason the fork was there.

### What is removed

- the `pkg/util/expr` package
- nine `expr.Init` / `expr.Register` call sites across roles, datacoord,
  datanode, proxy, meta cache, querycoord, querynode and rootcoord
- the `/static/` Expr Executor page (`internal/http/static/index.html`,
whose
only function was to call `/expr`), `static_view.go`, `StaticPath` and
its
  route registration
- the `/expr` handler in `internal/http/server.go`, `ExprPath` in
`router.go`,
and `CheckExprAuth` / `checkExprRootAuth` / the two auth-mode constants
in
  `internal/http/rbac.go`
- `common.security.exprEnabled` and `common.security.exprAuthMode`, and
their
  entries in `configs/milvus.yaml`
- `github.com/expr-lang/expr` and its `replace` to
`github.com/SimFG/expr`, from
  both `go.mod` and `pkg/go.mod`

### The Expr privilege

v3.0.0 shipped `Expr` as a grantable RBAC privilege for this endpoint.
The name
cannot simply be dropped: grant and revoke share one validation path
(`ddl_callbacks_rbac_privilege.go` dispatches on request version, not on
grant-vs-revoke), so an undefined name would leave grants made on v3.0.0
both
unusable and unrevocable, clearable only by editing etcd by hand.

The second commit rejects the grant explicitly instead, with a message
that says
why, and leaves every other path untouched. The name stays recognized
and inert
so existing grants remain listable and revocable, and can be dropped
entirely
once no supported release still has the endpoint.

### What is deliberately kept

`CheckPrivilege`, `RegisterGetUserRoleFunc`,
`RegisterPasswordVerifyFunc` and
`parseHTTPAuth` in `internal/http/rbac.go`. These are general HTTP RBAC
helpers
rather than expr-specific, and #52580 builds on that surface. After this
change
only tests call `CheckPrivilege`; that is intentional, not an oversight.

### Verification

Unit tests pass for `internal/http`, `internal/rootcoord` and
`pkg/util`,
including `TestExprPrivilegeDefinition` and a new
`TestIsDeprecatedExprPrivilege`
that covers both the API and metastore spellings plus negative cases.

Behaviour was also checked against a running instance rather than
inferred:

```
route removal
  /expr                    404 "404 page not found"
  /nonexistent-route-xyz   404 "404 page not found"   identical response
  /healthz, /metrics       200                        server is healthy
  /expr on a build that still registers it            500 from expr.Exec

privilege guard
  grant  Expr (v2)   rejected: privilege "Expr" is deprecated: the /expr
  grant  Expr (v1)   rejected   endpoint it granted access to has been removed
  revoke Expr (v2)   accepted
  revoke Expr (v1)   accepted
  grant/revoke Load  accepted   (control)

a pre-existing v3.0.0 grant
  wrote grantee-id/<id>/PrivilegeExpr directly into etcd, restarted the cluster
  describe_role      shows Global/Expr alongside Global/CreateDatabase
  revoke Expr        succeeds
  describe_role      only CreateDatabase remains
  etcd               the PrivilegeExpr key is gone, no orphan left behind
```

### Scope note

This does not close the unauthenticated `:9091` surface. `/metrics` and
`/debug/pprof/` remain unauthenticated; that is #52580's subject. This
change
removes one route from that port and the supply-chain exposure behind
it.

---------

Signed-off-by: zhenshan.cao <[email protected]>
Signed-off-by: Zack <[email protected]>
Co-authored-by: Zack <[email protected]>
Co-authored-by: Claude Fable 5 <[email protected]>



What is Milvus?
🐦 Milvus is a high-performance vector database built for scale. It powers AI applications by efficiently organizing and searching vast amounts of unstructured data, such as text, images, and multi-modal information.
🧑💻 Written in Go and C++, Milvus implements hardware acceleration for CPU/GPU to achieve best-in-class vector search performance. Thanks to its fully-distributed and K8s-native architecture, Milvus can scale horizontally, handle tens of thousands of search queries on billions of vectors, and keep data fresh with real-time streaming updates. Milvus also supports Standalone mode for single machine deployment. Milvus Lite is a lightweight version good for quickstart in python with pip install.
Want to use Milvus with zero setup? Try out Zilliz Cloud ☁️ for free. Milvus is available as a fully managed service on Zilliz Cloud, with Serverless, Dedicated and BYOC options available.
For questions about how to use Milvus, join the community on Discord to get help. For reporting problems, file bugs and feature requests in GitHub Issues or ask in Discussions.
The Milvus open-source project is under LF AI & Data Foundation, distributed with Apache 2.0 License, with Zilliz as its major contributor.
Quickstart
$ pip install -U pymilvus
This installs pymilvus, the Python SDK for Milvus. Use MilvusClient to create a client:
from pymilvus import MilvusClient
-
You can also try Milvus Lite for quickstart by installing
pymilvus[milvus-lite]. To create a local vector database, simply instantiate a client with a local file name for persisting data:client = MilvusClient("milvus_demo.db") -
You can also specify the credentials to connect to your deployed Milvus server or Zilliz Cloud:
client = MilvusClient(
  uri="<endpoint_of_self_hosted_milvus_or_zilliz_cloud>",
  token="<username_and_password_or_zilliz_cloud_api_key>")
With the client, you can create collection:
client.create_collection(
    collection_name="demo_collection",
    dimension=768,  # The vectors we will use in this demo have 768 dimensions
)
Ingest data:
res = client.insert(collection_name="demo_collection", data=data)
Perform vector search:
query_vectors = embedding_fn.encode_queries(["Who is Alan Turing?", "What is AI?"])
res = client.search(
    collection_name="demo_collection",  # target collection
    data=query_vectors,  # a list of one or more query vectors, supports batch
    limit=2,  # how many results to return (topK)
    output_fields=["vector", "text", "subject"],  # what fields to return
)
Why Milvus
Milvus is designed to handle vector search at scale. It stores vectors, which are learned representations of unstructured data, together with other scalar data types such as integers, strings, and JSON objects. Users can conduct efficient vector search with metadata filtering or hybrid search. Here are why developers choose Milvus as the vector database for AI applications:
High Performance at Scale and High Availability
- Milvus features a distributed architecture that separates compute and storage. Milvus can horizontally scale and adapt to diverse traffic patterns, achieving optimal performance by independently increasing query nodes for read-heavy workload and data node for write-heavy workload. The stateless microservices on K8s allow quick recovery from failure, ensuring high availability. The support for replicas further enhances fault tolerance and throughput by loading data segments on multiple query nodes. See benchmark for performance comparison.
Support for Various Vector Index Types and Hardware Acceleration
- Milvus separates the system and core vector search engine, allowing it to support all major vector index types that are optimized for different scenarios, including HNSW, IVF, FLAT (brute-force), SCANN, and DiskANN, with quantization-based variations and mmap. Milvus optimizes vector search for advanced features such as metadata filtering and range search. Additionally, Milvus implements hardware acceleration to enhance vector search performance and supports GPU indexing, such as NVIDIA's CAGRA.
Flexible Multi-tenancy and Hot/Cold Storage
- Milvus supports multi-tenancy through isolation at database, collection, partition, or partition key level. The flexible strategies allow a single cluster to handle hundreds to millions of tenants, also ensures optimized search performance and flexible access control. Milvus enhances cost-effectiveness with hot/cold storage. Frequently accessed hot data can be stored in memory or on SSDs for better performance, while less-accessed cold data is kept on slower, cost-effective storage. This mechanism can significantly reduce costs while maintaining high performance for critical tasks.
Sparse Vector for Full Text Search and Hybrid Search
- In addition to semantic search through dense vector, Milvus also natively supports full text search with BM25 as well as learned sparse embeddings such as SPLADE and BGE-M3. Users can store sparse vectors and dense vectors in the same collection, and define functions to rerank results from multiple search requests. See examples of Hybrid Search with semantic search + full text search.
Data Security and Fine-grain Access Control
- Milvus ensures data security by implementing mandatory user authentication, TLS encryption, and Role-Based Access Control (RBAC). User authentication ensures that only authorized users with valid credentials can access the database, while TLS encryption secures all communications within the network. Additionally, RBAC allows for fine-grained access control by assigning specific permissions to users based on their roles. These features make Milvus a robust and secure choice for enterprise applications, protecting sensitive data from unauthorized access and potential breaches.
Milvus is trusted by AI developers to build applications such as text and image search, Retrieval-Augmented Generation (RAG), and recommendation systems. Milvus powers many mission-critical businesses for startups and enterprises.
Demos and Tutorials
Here is a selection of demos and tutorials to show how to build various types of AI applications made with Milvus:
You can explore a comprehensive Tutorials Overview covering topics such as Retrieval-Augmented Generation (RAG), Semantic Search, Hybrid Search, Question Answering, Recommendation Systems, and various quick-start guides. These resources are designed to help you get started quickly and efficiently.
| Tutorial | Use Case | Related Milvus Features |
|---|---|---|
| Build RAG with Milvus | RAG | vector search |
| Advanced RAG Optimizations | RAG | vector search, full text search |
| Full Text Search with Milvus | Text Search | full text search |
| Hybrid Search with Milvus | Hybrid Search | hybrid search, multi vector, dense embedding, sparse embedding |
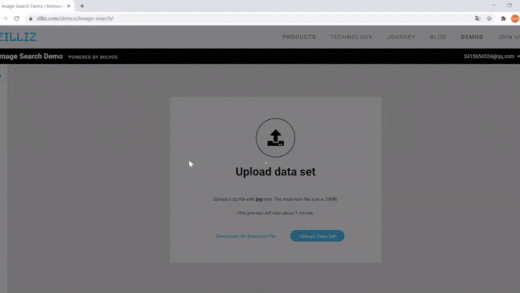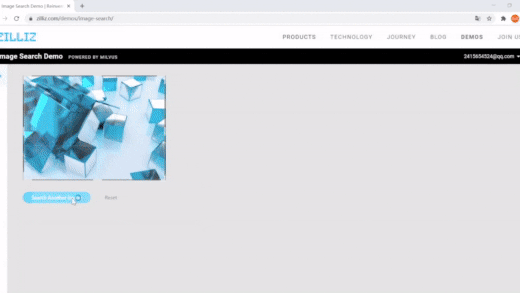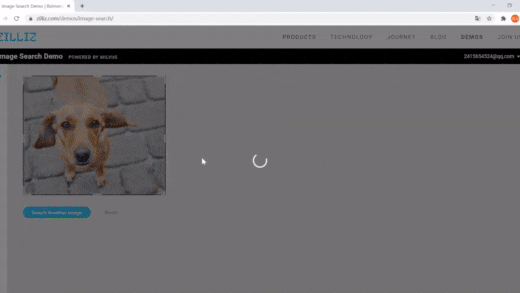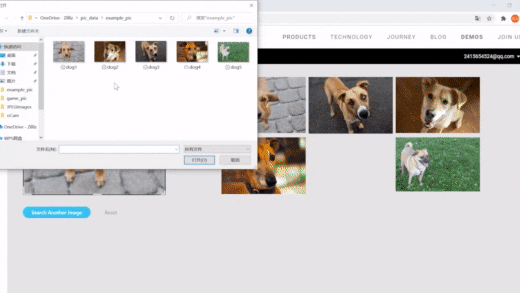
| Image Search with Milvus | Semantic Search | vector search, dynamic field |
| Multimodal Search using Multi Vectors | Semantic Search | multi vector, hybrid search |
| Movie Recommendation with Milvus | Recommendation System | vector search |
| Graph RAG with Milvus | RAG | graph search |
| Contextual Retrieval with Milvus | Quickstart | vector search |
| Vector Visualization | Quickstart | vector search |
| HDBSCAN Clustering with Milvus | Quickstart | vector search |
| Use ColPali for Multi-Modal Retrieval with Milvus | Quickstart | vector search |
|
|
|
| Image Search | RAG | Drug Discovery |
|---|
Ecosystem and Integration
Milvus integrates with a comprehensive suite of AI development tools, such as LangChain, LlamaIndex, OpenAI and HuggingFace, making it an ideal vector store for GenAI applications such as Retrieval-Augmented Generation (RAG). Milvus works with both open-source embedding models and embedding services, in text, image and video modalities. Milvus also provides a convenient utility pymilvus[model], users can use the simple wrapper code to transform unstructured data into vector embeddings and leverage reranking models for optimized search results. The Milvus ecosystem also includes Attu for GUI-based administration, Birdwatcher for system debugging, Prometheus/Grafana for monitoring, Milvus CDC for data synchronization, VTS for data migration and data connectors for Spark, Kafka, Fivetran, and Airbyte to build search pipelines.
Check out https://milvus.io/docs/integrations_overview.md for more details.
Documentation
For guidance on installation, usage, deployment, and administration, check out Milvus Docs. For technical milestones and enhancement proposals, check out issues on GitHub.
Contributing
The Milvus open-source project accepts contributions from everyone. See Guidelines for Contributing for details on submitting patches and the development workflow. See our community repository to learn about project governance and access more community resources.
Build Milvus from Source Code
Requirements:
-
Linux systems (Ubuntu 20.04 or later recommended):
Go: >= 1.21 CMake: >= 3.26.4 && CMake < 4 GCC: >= 11 Python: > 3.8 and <= 3.11 -
MacOS systems with x86_64 (Big Sur 11.5 or later recommended):
Go: >= 1.21 CMake: >= 3.26.4 && CMake < 4 llvm: >= 15 Python: > 3.8 and <= 3.11 -
MacOS systems with Apple Silicon (Monterey 12.0.1 or later recommended):
Go: >= 1.21 (Arch=ARM64)
CMake: >= 3.26.4 && CMake < 4
llvm: >= 15
Python: > 3.8 and  <= 3.11
Clone Milvus repo and build.
# Clone github repository.
$ git clone https://github.com/milvus-io/milvus.git

# Install third-party dependencies.
$ cd milvus/
$ ./scripts/install_deps.sh

# Compile Milvus.
$ make
For full instructions, see developer's documentation.
Community
Join the Milvus community on Discord to share your suggestions, advice, and questions with our engineering team.
To learn the latest news about Milvus, follow us on social media:
You can also check out our FAQ page to discover solutions or answers to your issues or questions, and subscribe to Milvus mailing lists:
Reference
Reference to cite when you use Milvus in a research paper:
@inproceedings{2021milvus,
  title={Milvus: A Purpose-Built Vector Data Management System},
  author={Wang, Jianguo and Yi, Xiaomeng and Guo, Rentong and Jin, Hai and Xu, Peng and Li, Shengjun and Wang, Xiangyu and Guo, Xiangzhou and Li, Chengming and Xu, Xiaohai and others},
  booktitle={Proceedings of the 2021 International Conference on Management of Data},
  pages={2614--2627},
  year={2021}
}

@article{2022manu,
  title={Manu: a cloud native vector database management system},
  author={Guo, Rentong and Luan, Xiaofan and Xiang, Long and Yan, Xiao and Yi, Xiaomeng and Luo, Jigao and Cheng, Qianya and Xu, Weizhi and Luo, Jiarui and Liu, Frank and others},
  journal={Proceedings of the VLDB Endowment},
  volume={15},
  number={12},
  pages={3548--3561},
  year={2022},
  publisher={VLDB Endowment}
}