mirror of
https://github.com/neuml/txtai.git
synced 2026-10-11 21:39:55 +00:00
Added examples
This commit is contained in:
 davidmezzetti
@@ -1,6 +1,6 @@
|
||||
# txtai: AI-powered search engine
|
||||
|
||||
txtai builds an AI-powered index over sets of text. txtai supports building text indices to perform similarity searches and create extractive question-answering based systems.
|
||||
txtai builds an AI-powered index over sections of text. txtai supports building text indices to perform similarity searches and create extractive question-answering based systems.
|
||||
|
||||
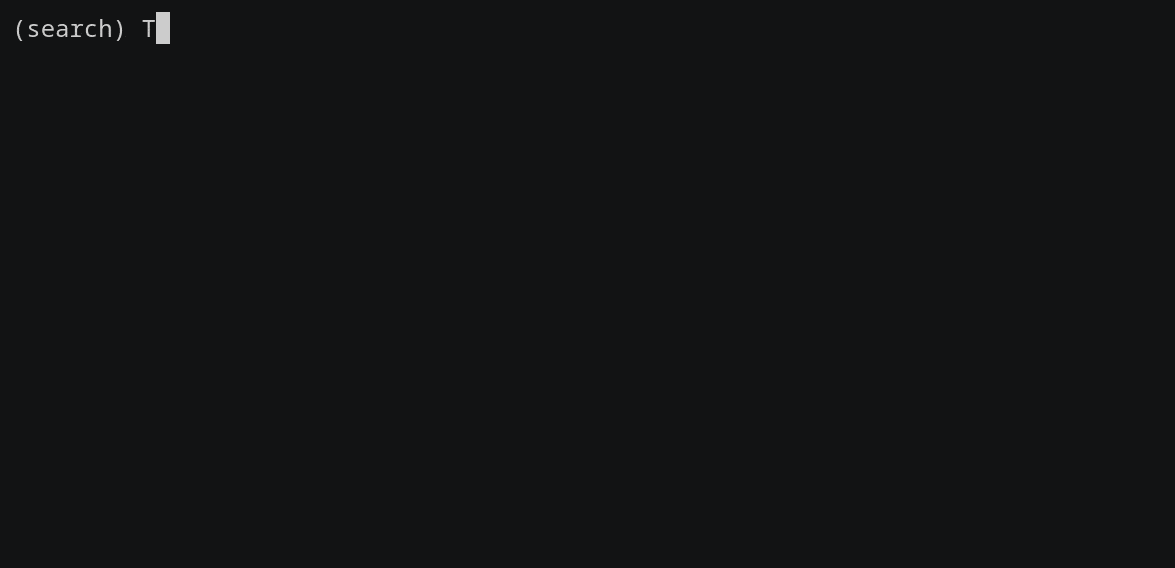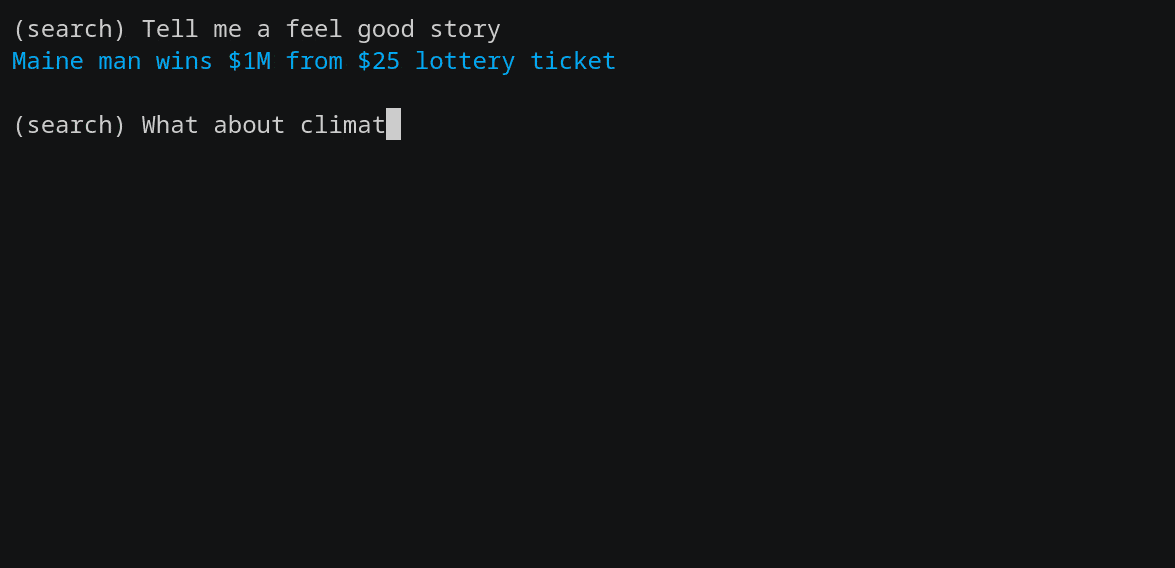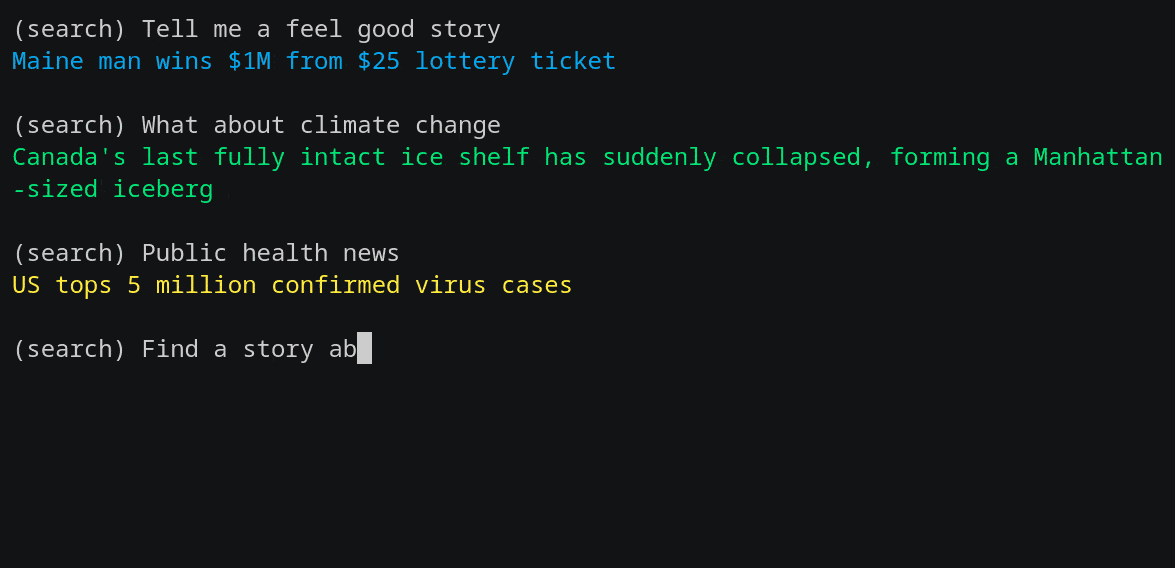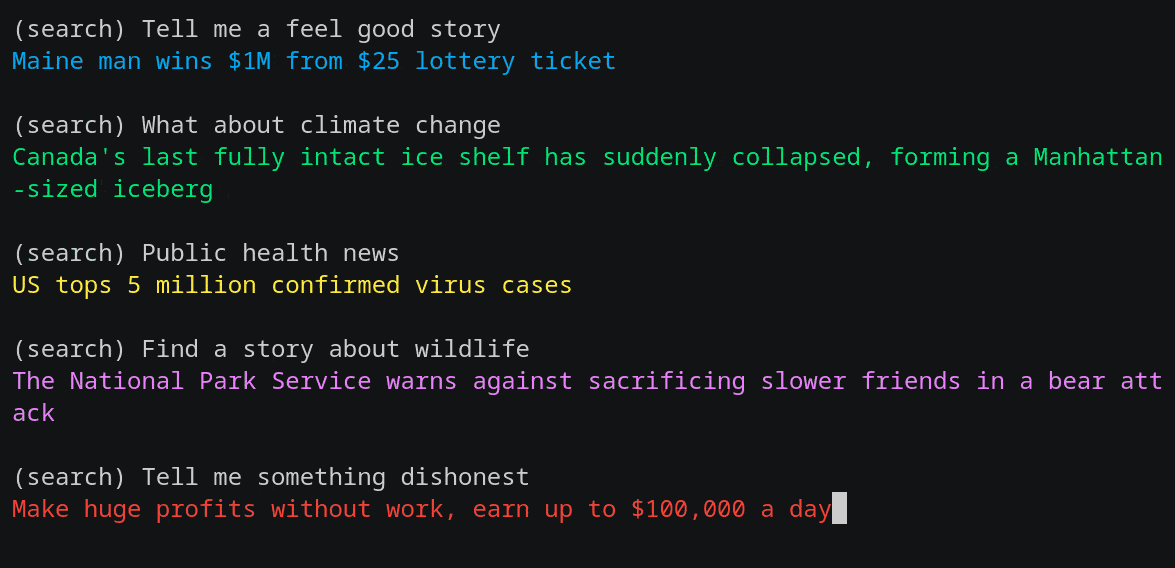
|
||||
|
||||
@@ -35,4 +35,15 @@ This project has dependencies that require compiling native code. Linux envirome
|
||||
pip install torch===1.6.0 torchvision===0.7.0 -f https://download.pytorch.org/whl/torch_stable.html
|
||||
```
|
||||
|
||||
## Tutorials
|
||||
## Examples
|
||||
|
||||
The examples directory has a series of examples and notebooks giving an overview of txtai. See the list of notebooks below.
|
||||
|
||||
### Notebooks
|
||||
|
||||
| Notebook | Description | |
|
||||
|:----------|:-------------|------:|
|
||||
| [Introducing txtai](https://github.com/neuml/txtai/blob/master/examples/01_Introducing_txtai.ipynb) | Overview of the functionality provided by txtai |[](https://colab.research.google.com/github/neuml/txtai/blob/master/examples/01_Introducing_txtai.ipynb) |
|
||||
| [Extractive QA with txtai](https://github.com/neuml/txtai/blob/master/examples/02_Extractive_QA_with_txtai) | Extractive question-answering with txtai |[](https://colab.research.google.com/github/neuml/txtai/blob/master/examples/02_Extractive_QA_with_txtai.ipynb) |
|
||||
| [Build an Embeddings index from a data source](https://github.com/neuml/txtai/blob/master/examples/03_Build_an_Embeddings_index_from_a_data_source.ipynb) | Embeddings index from a data source backed by word embeddings |[](https://colab.research.google.com/github/neuml/txtai/blob/master/examples/03_Build_an_Embeddings_index_from_a_data_source) |
|
||||
| [Extractive QA with Elasticsearch](https://github.com/neuml/txtai/blob/master/examples/04_Extractive_QA_with_Elasticsearch.ipynb) | Extractive question-answering with Elasticsearch |[](https://colab.research.google.com/github/neuml/txtai/blob/master/examples/04_Extractive_QA_with_Elasticsearch.ipynb) |
|
||||
|
||||

Binary file not shown.
|
Before Width: | Height: | Size: 46 KiB After Width: | Height: | Size: 46 KiB |
@@ -0,0 +1,359 @@
|
||||
{
|
||||
"nbformat": 4,
|
||||
"nbformat_minor": 0,
|
||||
"metadata": {
|
||||
"kernelspec": {
|
||||
"name": "python3",
|
||||
"display_name": "Python 3",
|
||||
"language": "python"
|
||||
},
|
||||
"language_info": {
|
||||
"name": "python",
|
||||
"version": "3.7.6",
|
||||
"mimetype": "text/x-python",
|
||||
"codemirror_mode": {
|
||||
"name": "ipython",
|
||||
"version": 3
|
||||
},
|
||||
"pygments_lexer": "ipython3",
|
||||
"nbconvert_exporter": "python",
|
||||
"file_extension": ".py"
|
||||
},
|
||||
"colab": {
|
||||
"name": "01 - Introducing txtai",
|
||||
"provenance": []
|
||||
}
|
||||
},
|
||||
"cells": [
|
||||
{
|
||||
"cell_type": "markdown",
|
||||
"metadata": {
|
||||
"id": "POWZoSJR6XzK",
|
||||
"colab_type": "text"
|
||||
},
|
||||
"source": [
|
||||
"# Part 1: Introducing txtai\n",
|
||||
"\n",
|
||||
"[txtai](https://github.com/neuml/txtai) builds an AI-powered index over sections of text. txtai supports building text indices to perform similarity searches and create extractive question-answering based systems. \n",
|
||||
"\n",
|
||||
"NeuML uses txtai and/or the concepts behind it to power all of our Natural Language Processing (NLP) applications. Example applications:\n",
|
||||
"\n",
|
||||
"- [cord19q](https://github.com/neuml/cord19q) - COVID-19 literature analysis\n",
|
||||
"- [paperai](https://github.com/neuml/paperai) - AI-powered literature discovery and review engine for medical/scientific papers\n",
|
||||
"- [neuspo](https://neuspo.com) - a fact-driven, real-time sports event and news site\n",
|
||||
"- [codequestion](https://github.com/neuml/codequestion) - Ask coding questions directly from the terminal\n",
|
||||
"\n",
|
||||
"txtai is built on the following stack:\n",
|
||||
"\n",
|
||||
"- [sentence-transformers](https://github.com/UKPLab/sentence-transformers)\n",
|
||||
"- [transformers](https://github.com/huggingface/transformers)\n",
|
||||
"- [faiss](https://github.com/facebookresearch/faiss)\n",
|
||||
"- Python 3.6+\n",
|
||||
"\n",
|
||||
"This notebook gives an overview of txtai and how to run similarity searches."
|
||||
]
|
||||
},
|
||||
{
|
||||
"cell_type": "markdown",
|
||||
"metadata": {
|
||||
"id": "qa_PPKVX6XzN",
|
||||
"colab_type": "text"
|
||||
},
|
||||
"source": [
|
||||
"# Install dependencies\n",
|
||||
"\n",
|
||||
"Install txtai and all dependencies"
|
||||
]
|
||||
},
|
||||
{
|
||||
"cell_type": "code",
|
||||
"metadata": {
|
||||
"_uuid": "8f2839f25d086af736a60e9eeb907d3b93b6e0e5",
|
||||
"_cell_guid": "b1076dfc-b9ad-4769-8c92-a6c4dae69d19",
|
||||
"trusted": true,
|
||||
"_kg_hide-output": true,
|
||||
"id": "24q-1n5i6XzQ",
|
||||
"colab_type": "code",
|
||||
"colab": {}
|
||||
},
|
||||
"source": [
|
||||
"%%capture\n",
|
||||
"!pip install git+https://github.com/neuml/txtai"
|
||||
],
|
||||
"execution_count": 1,
|
||||
"outputs": []
|
||||
},
|
||||
{
|
||||
"cell_type": "markdown",
|
||||
"metadata": {
|
||||
"id": "vHxb_jm16Xzd",
|
||||
"colab_type": "text"
|
||||
},
|
||||
"source": [
|
||||
"# Create an Embeddings instance\n",
|
||||
"\n",
|
||||
"The Embeddings instance is the main entrypoint for txtai. An Embeddings instance defines the method used to tokenize and convert a text section into an embeddings vector. "
|
||||
]
|
||||
},
|
||||
{
|
||||
"cell_type": "code",
|
||||
"metadata": {
|
||||
"trusted": true,
|
||||
"id": "QxX9EtIc6Xzg",
|
||||
"colab_type": "code",
|
||||
"colab": {}
|
||||
},
|
||||
"source": [
|
||||
"%%capture\n",
|
||||
"\n",
|
||||
"from txtai.embeddings import Embeddings\n",
|
||||
"\n",
|
||||
"# Create embeddings model, backed by sentence-transformers & transformers\n",
|
||||
"embeddings = Embeddings({\"method\": \"transformers\", \"path\": \"sentence-transformers/bert-base-nli-mean-tokens\"})"
|
||||
],
|
||||
"execution_count": 2,
|
||||
"outputs": []
|
||||
},
|
||||
{
|
||||
"cell_type": "markdown",
|
||||
"metadata": {
|
||||
"id": "JAO61bcy6Xzo",
|
||||
"colab_type": "text"
|
||||
},
|
||||
"source": [
|
||||
"# Running similarity queries\n",
|
||||
"\n",
|
||||
"An embedding instance relies on the underlying transformer model to build text embeddings. The following example shows how to use an transformers Embedding instance to run similarity searches for a list of different concepts."
|
||||
]
|
||||
},
|
||||
{
|
||||
"cell_type": "code",
|
||||
"metadata": {
|
||||
"_uuid": "d629ff2d2480ee46fbb7e2d37f6b5fab8052498a",
|
||||
"_cell_guid": "79c7e3d0-c299-4dcb-8224-4455121ee9b0",
|
||||
"trusted": true,
|
||||
"id": "2j_CFGDR6Xzp",
|
||||
"colab_type": "code",
|
||||
"colab": {
|
||||
"base_uri": "https://localhost:8080/",
|
||||
"height": 191
|
||||
},
|
||||
"outputId": "a92c2d3e-1b6d-473a-bc7e-7adc067fa868"
|
||||
},
|
||||
"source": [
|
||||
"import numpy as np\n",
|
||||
"\n",
|
||||
"sections = [\"US tops 5 million confirmed virus cases\",\n",
|
||||
" \"Canada's last fully intact ice shelf has suddenly collapsed, forming a Manhattan-sized iceberg\",\n",
|
||||
" \"Beijing mobilises invasion craft along coast as Taiwan tensions escalate\",\n",
|
||||
" \"The National Park Service warns against sacrificing slower friends in a bear attack\",\n",
|
||||
" \"Maine man wins $1M from $25 lottery ticket\",\n",
|
||||
" \"Make huge profits without work, earn up to $100,000 a day\"]\n",
|
||||
"\n",
|
||||
"print(\"%-20s %s\" % (\"Query\", \"Best Match\"))\n",
|
||||
"print(\"-\" * 50)\n",
|
||||
"\n",
|
||||
"for query in (\"feel good story\", \"climate change\", \"health\", \"war\", \"wildlife\", \"asia\", \"north america\", \"dishonest junk\"):\n",
|
||||
" # Get index of best section that best matches query\n",
|
||||
" uid = np.argmax(embeddings.similarity(query, sections))\n",
|
||||
"\n",
|
||||
" print(\"%-20s %s\" % (query, sections[uid]))"
|
||||
],
|
||||
"execution_count": 3,
|
||||
"outputs": [
|
||||
{
|
||||
"output_type": "stream",
|
||||
"text": [
|
||||
"Query Best Match\n",
|
||||
"--------------------------------------------------\n",
|
||||
"feel good story Maine man wins $1M from $25 lottery ticket\n",
|
||||
"climate change Canada's last fully intact ice shelf has suddenly collapsed, forming a Manhattan-sized iceberg\n",
|
||||
"health US tops 5 million confirmed virus cases\n",
|
||||
"war Beijing mobilises invasion craft along coast as Taiwan tensions escalate\n",
|
||||
"wildlife The National Park Service warns against sacrificing slower friends in a bear attack\n",
|
||||
"asia Beijing mobilises invasion craft along coast as Taiwan tensions escalate\n",
|
||||
"north america US tops 5 million confirmed virus cases\n",
|
||||
"dishonest junk Make huge profits without work, earn up to $100,000 a day\n"
|
||||
],
|
||||
"name": "stdout"
|
||||
}
|
||||
]
|
||||
},
|
||||
{
|
||||
"cell_type": "markdown",
|
||||
"metadata": {
|
||||
"id": "kIMbLW0t6Xzw",
|
||||
"colab_type": "text"
|
||||
},
|
||||
"source": [
|
||||
"The example above shows for almost all of the queries, the actual text isn't stored in the list of text sections. This is the true power of transformer models over token based search. What you get out of the box is 🔥🔥🔥!"
|
||||
]
|
||||
},
|
||||
{
|
||||
"cell_type": "markdown",
|
||||
"metadata": {
|
||||
"id": "DLIjSzbq6Xzx",
|
||||
"colab_type": "text"
|
||||
},
|
||||
"source": [
|
||||
"# Building an Embeddings index\n",
|
||||
"\n",
|
||||
"For small lists of texts, the method above works. But for larger repositories of documents, it doesn't make sense to tokenize and convert to embeddings on each query. txtai supports building pre-computed indices which signficantly improve performance. \n",
|
||||
"\n",
|
||||
"Building on the previous example, the following example runs an index method to build and store the text embeddings. In this case, only the query is converted to an embeddings vector each search. "
|
||||
]
|
||||
},
|
||||
{
|
||||
"cell_type": "code",
|
||||
"metadata": {
|
||||
"trusted": true,
|
||||
"id": "cXfZtdHD6Xzy",
|
||||
"colab_type": "code",
|
||||
"colab": {
|
||||
"base_uri": "https://localhost:8080/",
|
||||
"height": 191
|
||||
},
|
||||
"outputId": "eca8eb29-7ac8-445b-f9b9-6b5cea3280a5"
|
||||
},
|
||||
"source": [
|
||||
"# Create an index for the list of sections\n",
|
||||
"embeddings.index([(uid, text, None) for uid, text in enumerate(sections)])\n",
|
||||
"\n",
|
||||
"print(\"%-20s %s\" % (\"Query\", \"Best Match\"))\n",
|
||||
"print(\"-\" * 50)\n",
|
||||
"\n",
|
||||
"# Run an embeddings search for each query\n",
|
||||
"for query in (\"feel good story\", \"climate change\", \"health\", \"war\", \"wildlife\", \"asia\", \"north america\", \"dishonest junk\"):\n",
|
||||
" # Extract uid of first result\n",
|
||||
" # search result format: (uid, score)\n",
|
||||
" uid = embeddings.search(query, 1)[0][0]\n",
|
||||
"\n",
|
||||
" # Print section\n",
|
||||
" print(\"%-20s %s\" % (query, sections[uid]))"
|
||||
],
|
||||
"execution_count": 4,
|
||||
"outputs": [
|
||||
{
|
||||
"output_type": "stream",
|
||||
"text": [
|
||||
"Query Best Match\n",
|
||||
"--------------------------------------------------\n",
|
||||
"feel good story Maine man wins $1M from $25 lottery ticket\n",
|
||||
"climate change Canada's last fully intact ice shelf has suddenly collapsed, forming a Manhattan-sized iceberg\n",
|
||||
"health US tops 5 million confirmed virus cases\n",
|
||||
"war Beijing mobilises invasion craft along coast as Taiwan tensions escalate\n",
|
||||
"wildlife The National Park Service warns against sacrificing slower friends in a bear attack\n",
|
||||
"asia Beijing mobilises invasion craft along coast as Taiwan tensions escalate\n",
|
||||
"north america US tops 5 million confirmed virus cases\n",
|
||||
"dishonest junk Make huge profits without work, earn up to $100,000 a day\n"
|
||||
],
|
||||
"name": "stdout"
|
||||
}
|
||||
]
|
||||
},
|
||||
{
|
||||
"cell_type": "markdown",
|
||||
"metadata": {
|
||||
"id": "6TCVl6QA6Xz5",
|
||||
"colab_type": "text"
|
||||
},
|
||||
"source": [
|
||||
"# Embeddings load/save\n",
|
||||
"\n",
|
||||
"Embeddings indices can be saved to disk and reloaded. At this time, indices are not incrementally created, the index needs a full rebuild to incorporate new data. But that enhancement is in the backlog."
|
||||
]
|
||||
},
|
||||
{
|
||||
"cell_type": "code",
|
||||
"metadata": {
|
||||
"trusted": true,
|
||||
"id": "5gyO90Hc6Xz7",
|
||||
"colab_type": "code",
|
||||
"colab": {
|
||||
"base_uri": "https://localhost:8080/",
|
||||
"height": 34
|
||||
},
|
||||
"outputId": "92e1358d-4dcf-4982-8811-061f0bfa9a88"
|
||||
},
|
||||
"source": [
|
||||
"embeddings.save(\"index\")\n",
|
||||
"\n",
|
||||
"embeddings = Embeddings()\n",
|
||||
"embeddings.load(\"index\")\n",
|
||||
"\n",
|
||||
"uid = embeddings.search(\"climate change\", 1)[0][0]\n",
|
||||
"print(sections[uid])"
|
||||
],
|
||||
"execution_count": 5,
|
||||
"outputs": [
|
||||
{
|
||||
"output_type": "stream",
|
||||
"text": [
|
||||
"Canada's last fully intact ice shelf has suddenly collapsed, forming a Manhattan-sized iceberg\n"
|
||||
],
|
||||
"name": "stdout"
|
||||
}
|
||||
]
|
||||
},
|
||||
{
|
||||
"cell_type": "code",
|
||||
"metadata": {
|
||||
"trusted": true,
|
||||
"id": "d2uCotAE6X0J",
|
||||
"colab_type": "code",
|
||||
"colab": {
|
||||
"base_uri": "https://localhost:8080/",
|
||||
"height": 34
|
||||
},
|
||||
"outputId": "14f16d54-ca02-4099-9478-24ba8054d3e3"
|
||||
},
|
||||
"source": [
|
||||
"!ls index"
|
||||
],
|
||||
"execution_count": 6,
|
||||
"outputs": [
|
||||
{
|
||||
"output_type": "stream",
|
||||
"text": [
|
||||
"config\tembeddings\n"
|
||||
],
|
||||
"name": "stdout"
|
||||
}
|
||||
]
|
||||
},
|
||||
{
|
||||
"cell_type": "markdown",
|
||||
"metadata": {
|
||||
"id": "aDIF3tYt6X0O",
|
||||
"colab_type": "text"
|
||||
},
|
||||
"source": [
|
||||
"# Embedding methods\n",
|
||||
"\n",
|
||||
"Embeddings supports two methods for creating text vectors, the sentence-transformers library and word embeddings vectors. Both methods have their merits as shown below:\n",
|
||||
"\n",
|
||||
"- [sentence-transformers](https://github.com/UKPLab/sentence-transformers)\n",
|
||||
" - Creates a single embeddings vector via mean pooling of vectors generated by the transformers library. \n",
|
||||
" - Supports models stored on Hugging Face's model hub or stored locally. \n",
|
||||
" - See sentence-transformers for details on how to create custom models, which can be kept local or uploaded to Hugging Face's model hub.\n",
|
||||
" - Base models require significant compute capability (GPU preferred). Possible to build smaller/lighter weight models that tradeoff accuracy for speed.\n",
|
||||
"- word embeddings\n",
|
||||
" - Creates a single embeddings vector via BM25 scoring of each word component. See this [Medium article](https://towardsdatascience.com/building-a-sentence-embedding-index-with-fasttext-and-bm25-f07e7148d240) for the logic behind this method.\n",
|
||||
" - Backed by the [pymagnitude](https://github.com/plasticityai/magnitude) library. Pre-trained word vectors can be installed from the referenced link.\n",
|
||||
" - See [vectors.py](https://github.com/neuml/txtai/blob/master/src/python/txtai/vectors.py) for code that can build word vectors for custom datasets.\n",
|
||||
" - Significantly better performance with default models. For larger datasets, it offers a good tradeoff of speed and accuracy."
|
||||
]
|
||||
},
|
||||
{
|
||||
"cell_type": "markdown",
|
||||
"metadata": {
|
||||
"id": "0Nw7nbHg6X0P",
|
||||
"colab_type": "text"
|
||||
},
|
||||
"source": [
|
||||
"# Next\n",
|
||||
"In part 2 of this series, we'll look at how to use txtai to run extractive searches"
|
||||
]
|
||||
}
|
||||
]
|
||||
}
|
||||
@@ -0,0 +1,175 @@
|
||||
{
|
||||
"nbformat": 4,
|
||||
"nbformat_minor": 0,
|
||||
"metadata": {
|
||||
"colab": {
|
||||
"name": "02 - Extractive QA with txtai",
|
||||
"provenance": []
|
||||
},
|
||||
"kernelspec": {
|
||||
"name": "python3",
|
||||
"display_name": "Python 3"
|
||||
}
|
||||
},
|
||||
"cells": [
|
||||
{
|
||||
"cell_type": "markdown",
|
||||
"metadata": {
|
||||
"id": "vwELCooy4ljr",
|
||||
"colab_type": "text"
|
||||
},
|
||||
"source": [
|
||||
"# Part 2: Extractive QA with txtai\n",
|
||||
"\n",
|
||||
"In Part 1, we gave a general overview of txtai, the backing technology and examples of how to use it for similarity searches. This notebook builds on that and extends to building extractive question-answering systems."
|
||||
]
|
||||
},
|
||||
{
|
||||
"cell_type": "markdown",
|
||||
"metadata": {
|
||||
"id": "ew7orE2O441o",
|
||||
"colab_type": "text"
|
||||
},
|
||||
"source": [
|
||||
"# Install dependencies\n",
|
||||
"\n",
|
||||
"Install txtai and all dependencies"
|
||||
]
|
||||
},
|
||||
{
|
||||
"cell_type": "code",
|
||||
"metadata": {
|
||||
"id": "LPQTb25tASIG",
|
||||
"colab_type": "code",
|
||||
"colab": {}
|
||||
},
|
||||
"source": [
|
||||
"%%capture\n",
|
||||
"!pip install git+https://github.com/neuml/txtai"
|
||||
],
|
||||
"execution_count": 1,
|
||||
"outputs": []
|
||||
},
|
||||
{
|
||||
"cell_type": "markdown",
|
||||
"metadata": {
|
||||
"id": "_YnqorRKAbLu",
|
||||
"colab_type": "text"
|
||||
},
|
||||
"source": [
|
||||
"# Create an Embeddings and Extractor instances\n",
|
||||
"\n",
|
||||
"The Embeddings instance is the main entrypoint for txtai. An Embeddings instance defines the method used to tokenize and convert a segment of text into an embeddings vector.\n",
|
||||
"\n",
|
||||
"The Extractor instance is the entrypoint for extractive question-answering.\n",
|
||||
"\n",
|
||||
"Both the Embeddings and Extractor instances take a path to a transformer model. Any model on the [Hugging Face model hub](https://huggingface.co/models) can be used in place of the models below."
|
||||
]
|
||||
},
|
||||
{
|
||||
"cell_type": "code",
|
||||
"metadata": {
|
||||
"id": "OUc9gqTyAYnm",
|
||||
"colab_type": "code",
|
||||
"colab": {}
|
||||
},
|
||||
"source": [
|
||||
"%%capture\n",
|
||||
"\n",
|
||||
"from txtai.embeddings import Embeddings\n",
|
||||
"from txtai.extractor import Extractor\n",
|
||||
"\n",
|
||||
"# Create embeddings model, backed by sentence-transformers & transformers\n",
|
||||
"embeddings = Embeddings({\"method\": \"transformers\", \"path\": \"sentence-transformers/bert-base-nli-mean-tokens\"})\n",
|
||||
"\n",
|
||||
"# Create extractor instance\n",
|
||||
"extractor = Extractor(embeddings, \"distilbert-base-cased-distilled-squad\")"
|
||||
],
|
||||
"execution_count": 2,
|
||||
"outputs": []
|
||||
},
|
||||
{
|
||||
"cell_type": "code",
|
||||
"metadata": {
|
||||
"id": "4X5z3UjnAGe7",
|
||||
"colab_type": "code",
|
||||
"colab": {
|
||||
"base_uri": "https://localhost:8080/",
|
||||
"height": 330
|
||||
},
|
||||
"outputId": "4e376662-57d1-4841-eeb5-622aaaf286c3"
|
||||
},
|
||||
"source": [
|
||||
"sections = [\"Giants hit 3 HRs to down Dodgers\",\n",
|
||||
" \"Giants 5 Dodgers 4 final\",\n",
|
||||
" \"Dodgers drop Game 2 against the Giants, 5-4\",\n",
|
||||
" \"Blue Jays 2 Red Sox 1 final\",\n",
|
||||
" \"Red Sox lost to the Blue Jays, 2-1\",\n",
|
||||
" \"Blue Jays at Red Sox is over. Score: 2-1\",\n",
|
||||
" \"Phillies win over the Braves, 5-0\",\n",
|
||||
" \"Phillies 5 Braves 0 final\",\n",
|
||||
" \"Final: Braves lose to the Phillies in the series opener, 5-0\",\n",
|
||||
" \"Final score: Flyers 4 Lightning 1\",\n",
|
||||
" \"Flyers 4 Lightning 1 final\",\n",
|
||||
" \"Flyers win 4-1\"]\n",
|
||||
"\n",
|
||||
"# Add unique id to each section to assist with qa extraction\n",
|
||||
"sections = [(uid, section) for uid, section in enumerate(sections)]\n",
|
||||
"\n",
|
||||
"questions = [\"What team won the game?\", \"What was score?\"]\n",
|
||||
"\n",
|
||||
"execute = lambda query: extractor(sections, [(question, query, question, False) for question in questions])\n",
|
||||
"\n",
|
||||
"for query in [\"Red Sox - Blue Jays\", \"Phillies - Braves\", \"Dodgers - Giants\", \"Flyers - Lightning\"]:\n",
|
||||
" print(\"----\", query, \"----\")\n",
|
||||
" for answer in execute(query):\n",
|
||||
" print(answer)\n",
|
||||
" print()\n",
|
||||
"\n",
|
||||
"# Ad-hoc questions\n",
|
||||
"question = \"What hockey team won?\"\n",
|
||||
"\n",
|
||||
"print(\"----\", question, \"----\")\n",
|
||||
"print(extractor(sections, [(question, question, question, False)]))"
|
||||
],
|
||||
"execution_count": 3,
|
||||
"outputs": [
|
||||
{
|
||||
"output_type": "stream",
|
||||
"text": [
|
||||
"---- Red Sox - Blue Jays ----\n",
|
||||
"('What team won the game?', 'Blue Jays')\n",
|
||||
"('What was score?', '2-1')\n",
|
||||
"\n",
|
||||
"---- Phillies - Braves ----\n",
|
||||
"('What team won the game?', 'Phillies')\n",
|
||||
"('What was score?', '5-0')\n",
|
||||
"\n",
|
||||
"---- Dodgers - Giants ----\n",
|
||||
"('What team won the game?', 'Giants')\n",
|
||||
"('What was score?', '5-4')\n",
|
||||
"\n",
|
||||
"---- Flyers - Lightning ----\n",
|
||||
"('What team won the game?', 'Flyers')\n",
|
||||
"('What was score?', '4-1')\n",
|
||||
"\n",
|
||||
"---- What hockey team won? ----\n",
|
||||
"[('What hockey team won?', 'Flyers')]\n"
|
||||
],
|
||||
"name": "stdout"
|
||||
}
|
||||
]
|
||||
},
|
||||
{
|
||||
"cell_type": "markdown",
|
||||
"metadata": {
|
||||
"id": "k-9gHzrp8ZXA",
|
||||
"colab_type": "text"
|
||||
},
|
||||
"source": [
|
||||
"# Next\n",
|
||||
"In part 3 of this series, we'll look at how to use txtai on larger datasets and explore using word embeddings vs transformer embeddings"
|
||||
]
|
||||
}
|
||||
]
|
||||
}
|
||||
@@ -0,0 +1,546 @@
|
||||
{
|
||||
"nbformat": 4,
|
||||
"nbformat_minor": 0,
|
||||
"metadata": {
|
||||
"colab": {
|
||||
"name": "03 - Build an Embeddings index from a data source",
|
||||
"provenance": [],
|
||||
"collapsed_sections": []
|
||||
},
|
||||
"kernelspec": {
|
||||
"name": "python3",
|
||||
"display_name": "Python 3"
|
||||
}
|
||||
},
|
||||
"cells": [
|
||||
{
|
||||
"cell_type": "markdown",
|
||||
"metadata": {
|
||||
"id": "WDbhGHtG8jFE",
|
||||
"colab_type": "text"
|
||||
},
|
||||
"source": [
|
||||
"# Part 3: Build an Embeddings index from a data source\n",
|
||||
"\n",
|
||||
"In Part 1, we gave a general overview of txtai, the backing technology and examples of how to use it for similarity searches. Part 2 covered how to use txtai for extractive question-answer systems.\n",
|
||||
"\n",
|
||||
"The previous examples worked on data stored in memory for demo purposes. For real world large-scale use cases, data is usually stored in a database (Elasticsearch, SQL, MongoDB, files, etc). This example covers reading data from SQLite, building a Embedding index backed by word embeddings and running queries against the generated Embeddings index.\n",
|
||||
"\n",
|
||||
"This example covers functionality found in the [paperai](https://github.com/neuml/paperai) library. See that library for a full solution that can be used with the dataset discussed below."
|
||||
]
|
||||
},
|
||||
{
|
||||
"cell_type": "markdown",
|
||||
"metadata": {
|
||||
"id": "UQ0fCwXn9bcH",
|
||||
"colab_type": "text"
|
||||
},
|
||||
"source": [
|
||||
"# Install dependencies\n",
|
||||
"\n",
|
||||
"Install txtai and all dependencies"
|
||||
]
|
||||
},
|
||||
{
|
||||
"cell_type": "code",
|
||||
"metadata": {
|
||||
"id": "czPYSA2Q9ZHO",
|
||||
"colab_type": "code",
|
||||
"colab": {}
|
||||
},
|
||||
"source": [
|
||||
"%%capture\n",
|
||||
"!pip install git+https://github.com/neuml/txtai"
|
||||
],
|
||||
"execution_count": 1,
|
||||
"outputs": []
|
||||
},
|
||||
{
|
||||
"cell_type": "markdown",
|
||||
"metadata": {
|
||||
"id": "SN9SCZKQ9fJF",
|
||||
"colab_type": "text"
|
||||
},
|
||||
"source": [
|
||||
"# Download data\n",
|
||||
"\n",
|
||||
"This example is going to work off a subset of the [CORD-19](https://www.semanticscholar.org/cord19) dataset. COVID-19 Open Research Dataset (CORD-19) is a free resource of scholarly articles, aggregated by a coalition of leading research groups, covering COVID-19 and the coronavirus family of viruses.\n",
|
||||
"\n",
|
||||
"The following download is SQLite database with a subject of CORD-19, generated from a [Kaggle notebook](https://www.kaggle.com/davidmezzetti/cord-19-slim/output). More information on this data format, can be found in the [CORD-19 Analysis](https://www.kaggle.com/davidmezzetti/cord-19-analysis-with-sentence-embeddings) notebook."
|
||||
]
|
||||
},
|
||||
{
|
||||
"cell_type": "code",
|
||||
"metadata": {
|
||||
"id": "TONQ4_Kv9dtd",
|
||||
"colab_type": "code",
|
||||
"colab": {
|
||||
"base_uri": "https://localhost:8080/",
|
||||
"height": 228
|
||||
},
|
||||
"outputId": "6bbacf83-d695-42ec-cce0-0f92b1534ca4"
|
||||
},
|
||||
"source": [
|
||||
"!wget https://www.kaggleusercontent.com/kf/40510829/eyJhbGciOiJkaXIiLCJlbmMiOiJBMTI4Q0JDLUhTMjU2In0..FX7Ote_I-Y88MBPQHRIdUQ.tTr7P3B_eUL_yWN33Usz0Rk1KXtc4DjT_cdjkl5W4WbEcZ-0FJX2jSWTHYMVACtLYuMJJrf6eJN28OzWhDMnTysBu3wfDrd4ly5bu_wJKCnZajICQgQHs_b8hbRVMOzfdG6xEyl9CVYnZNU2cI3QuOshcWxoB0skdKD4d26O_Q4e_nrd8DqEixP47tI2Hu1F00w0vMykzgNwp7SwQ2Z9HoNCO8HtmcjEHq0A4lZ4303YkpjORtZQEO3S-j54fFlIAahT-9VvsFNofitK5VAlR0EyG9r3cOqh2LQDCL7kj5p3MxG8dvHmrTqggLVOwiuKHUIH8u59TemSMLsNRS29W-5fFlHfaItV4dEuiBxCIgQXHcKUDCDGEjeFcPgqpJnNHsnh0pebWDuRQR_fdQ-r8mWgN9qLnosrFBak9tM25G7gqxyUI90GMWAUyP4yj2EAEc8asX9rUsirC8QDHmrmOCUe0cmZvodRUi0ss7lTiLTwm55d9VPXjQn4jQ6tFs-dmjXEx0AwF2Mw1c1jhgzCXwgQj6ybUKemr_6wj1VFYj3VVvCXpk1nZObl-IB6-m7v5CIoXGLot_KFsVtyItRk-wX-B_L3W3aS9dOIfb7bX4s5_aNzXaDKvxrcafwlOQui.vS_FL4EArO8rkBo3xpDF2w/articles.sqlite"
|
||||
],
|
||||
"execution_count": 2,
|
||||
"outputs": [
|
||||
{
|
||||
"output_type": "stream",
|
||||
"text": [
|
||||
"--2020-08-11 15:42:03-- https://www.kaggleusercontent.com/kf/40510829/eyJhbGciOiJkaXIiLCJlbmMiOiJBMTI4Q0JDLUhTMjU2In0..FX7Ote_I-Y88MBPQHRIdUQ.tTr7P3B_eUL_yWN33Usz0Rk1KXtc4DjT_cdjkl5W4WbEcZ-0FJX2jSWTHYMVACtLYuMJJrf6eJN28OzWhDMnTysBu3wfDrd4ly5bu_wJKCnZajICQgQHs_b8hbRVMOzfdG6xEyl9CVYnZNU2cI3QuOshcWxoB0skdKD4d26O_Q4e_nrd8DqEixP47tI2Hu1F00w0vMykzgNwp7SwQ2Z9HoNCO8HtmcjEHq0A4lZ4303YkpjORtZQEO3S-j54fFlIAahT-9VvsFNofitK5VAlR0EyG9r3cOqh2LQDCL7kj5p3MxG8dvHmrTqggLVOwiuKHUIH8u59TemSMLsNRS29W-5fFlHfaItV4dEuiBxCIgQXHcKUDCDGEjeFcPgqpJnNHsnh0pebWDuRQR_fdQ-r8mWgN9qLnosrFBak9tM25G7gqxyUI90GMWAUyP4yj2EAEc8asX9rUsirC8QDHmrmOCUe0cmZvodRUi0ss7lTiLTwm55d9VPXjQn4jQ6tFs-dmjXEx0AwF2Mw1c1jhgzCXwgQj6ybUKemr_6wj1VFYj3VVvCXpk1nZObl-IB6-m7v5CIoXGLot_KFsVtyItRk-wX-B_L3W3aS9dOIfb7bX4s5_aNzXaDKvxrcafwlOQui.vS_FL4EArO8rkBo3xpDF2w/articles.sqlite\n",
|
||||
"Resolving www.kaggleusercontent.com (www.kaggleusercontent.com)... 35.190.26.106\n",
|
||||
"Connecting to www.kaggleusercontent.com (www.kaggleusercontent.com)|35.190.26.106|:443... connected.\n",
|
||||
"HTTP request sent, awaiting response... 200 OK\n",
|
||||
"Length: 8065024 (7.7M) [application/octet-stream]\n",
|
||||
"Saving to: ‘articles.sqlite’\n",
|
||||
"\n",
|
||||
"\rarticles.sqlite 0%[ ] 0 --.-KB/s \rarticles.sqlite 100%[===================>] 7.69M --.-KB/s in 0.07s \n",
|
||||
"\n",
|
||||
"2020-08-11 15:42:03 (109 MB/s) - ‘articles.sqlite’ saved [8065024/8065024]\n",
|
||||
"\n"
|
||||
],
|
||||
"name": "stdout"
|
||||
}
|
||||
]
|
||||
},
|
||||
{
|
||||
"cell_type": "markdown",
|
||||
"metadata": {
|
||||
"id": "bzdaJiZYBIHE",
|
||||
"colab_type": "text"
|
||||
},
|
||||
"source": [
|
||||
"# Build Word Vectors\n",
|
||||
"\n",
|
||||
"This example will build a search system backed by word embeddings. While note quite as powerful as transformer embeddings, they often provide a good tradeoff of performance to functionality for an embedding based search system.\n",
|
||||
"\n",
|
||||
"For this notebook, we'll build our own custom embeddings for demo purposes. A number of pre-trained word embedding models are available:\n",
|
||||
"\n",
|
||||
" - [General language models from pymagnitude](https://github.com/plasticityai/magnitude)\n",
|
||||
" - [CORD-19 fastText](https://www.kaggle.com/davidmezzetti/cord19-fasttext-vectors)"
|
||||
]
|
||||
},
|
||||
{
|
||||
"cell_type": "code",
|
||||
"metadata": {
|
||||
"id": "fJcn-CAH-u3K",
|
||||
"colab_type": "code",
|
||||
"colab": {
|
||||
"base_uri": "https://localhost:8080/",
|
||||
"height": 156
|
||||
},
|
||||
"outputId": "67406a51-0819-4845-84da-63d0ad6677f1"
|
||||
},
|
||||
"source": [
|
||||
"import os\n",
|
||||
"import sqlite3\n",
|
||||
"import tempfile\n",
|
||||
"\n",
|
||||
"from txtai.tokenizer import Tokenizer\n",
|
||||
"from txtai.vectors import WordVectors\n",
|
||||
"\n",
|
||||
"print(\"Streaming tokens to temporary file\")\n",
|
||||
"\n",
|
||||
"# Stream tokens to temp working file\n",
|
||||
"with tempfile.NamedTemporaryFile(mode=\"w\", suffix=\".txt\", delete=False) as output:\n",
|
||||
" # Save file path\n",
|
||||
" tokens = output.name\n",
|
||||
"\n",
|
||||
" db = sqlite3.connect(\"articles.sqlite\")\n",
|
||||
" cur = db.cursor()\n",
|
||||
" cur.execute(\"SELECT Text from sections\")\n",
|
||||
"\n",
|
||||
" for row in cur:\n",
|
||||
" output.write(\" \".join(row[0]) + \"\\n\")\n",
|
||||
"\n",
|
||||
" # Free database resources\n",
|
||||
" db.close()\n",
|
||||
"\n",
|
||||
"# Build word vectors model - 300 dimensions, 3 min occurrences\n",
|
||||
"WordVectors.build(tokens, 300, 3, \"cord19-300d\")\n",
|
||||
"\n",
|
||||
"# Remove temporary tokens file\n",
|
||||
"os.remove(tokens)\n",
|
||||
"\n",
|
||||
"# Show files\n",
|
||||
"!ls -l"
|
||||
],
|
||||
"execution_count": 3,
|
||||
"outputs": [
|
||||
{
|
||||
"output_type": "stream",
|
||||
"text": [
|
||||
"Streaming tokens to temporary file\n",
|
||||
"Building 300 dimension model\n",
|
||||
"Converting vectors to magnitude format\n",
|
||||
"total 9024\n",
|
||||
"-rw-r--r-- 1 root root 8065024 Aug 11 15:42 articles.sqlite\n",
|
||||
"-rw-r--r-- 1 root root 360448 Aug 11 15:43 cord19-300d.magnitude\n",
|
||||
"-rw-r--r-- 1 root root 807886 Aug 11 15:43 cord19-300d.txt\n",
|
||||
"drwxr-xr-x 1 root root 4096 Jul 30 16:30 sample_data\n"
|
||||
],
|
||||
"name": "stdout"
|
||||
}
|
||||
]
|
||||
},
|
||||
{
|
||||
"cell_type": "markdown",
|
||||
"metadata": {
|
||||
"id": "_UxcC1-JGH-d",
|
||||
"colab_type": "text"
|
||||
},
|
||||
"source": [
|
||||
"# Build an embeddings index\n",
|
||||
"\n",
|
||||
"The following steps builds an embeddings index using the word vector model just created. This model builds a BM25 + fastText index. BM25 is used to build a weighted average of the word embeddings for a section. More information on this method can be found in this [Medium article](https://towardsdatascience.com/building-a-sentence-embedding-index-with-fasttext-and-bm25-f07e7148d240?gi=79da927aa10). "
|
||||
]
|
||||
},
|
||||
{
|
||||
"cell_type": "code",
|
||||
"metadata": {
|
||||
"id": "5PrrxGRPGHqX",
|
||||
"colab_type": "code",
|
||||
"colab": {
|
||||
"base_uri": "https://localhost:8080/",
|
||||
"height": 52
|
||||
},
|
||||
"outputId": "f00ead87-aeaa-4243-8b68-663c01f30520"
|
||||
},
|
||||
"source": [
|
||||
"import sqlite3\n",
|
||||
"\n",
|
||||
"import regex as re\n",
|
||||
"\n",
|
||||
"from txtai.embeddings import Embeddings\n",
|
||||
"from txtai.tokenizer import Tokenizer\n",
|
||||
"\n",
|
||||
"def stream():\n",
|
||||
" # Connection to database file\n",
|
||||
" db = sqlite3.connect(\"articles.sqlite\")\n",
|
||||
" cur = db.cursor()\n",
|
||||
"\n",
|
||||
" # Select tagged sentences without a NLP label. NLP labels are set for non-informative sentences.\n",
|
||||
" cur.execute(\"SELECT Id, Name, Text FROM sections WHERE (labels is null or labels NOT IN ('FRAGMENT', 'QUESTION')) AND tags is not null\")\n",
|
||||
"\n",
|
||||
" count = 0\n",
|
||||
" for row in cur:\n",
|
||||
" # Unpack row\n",
|
||||
" uid, name, text = row\n",
|
||||
"\n",
|
||||
" # Only process certain document sections\n",
|
||||
" if not name or not re.search(r\"background|(?<!.*?results.*?)discussion|introduction|reference\", name.lower()):\n",
|
||||
" # Tokenize text\n",
|
||||
" tokens = Tokenizer.tokenize(text)\n",
|
||||
"\n",
|
||||
" document = (uid, tokens, None)\n",
|
||||
"\n",
|
||||
" count += 1\n",
|
||||
" if count % 1000 == 0:\n",
|
||||
" print(\"Streamed %d documents\" % (count), end=\"\\r\")\n",
|
||||
"\n",
|
||||
" # Skip documents with no tokens parsed\n",
|
||||
" if tokens:\n",
|
||||
" yield document\n",
|
||||
"\n",
|
||||
" print(\"Iterated over %d total rows\" % (count))\n",
|
||||
"\n",
|
||||
" # Free database resources\n",
|
||||
" db.close()\n",
|
||||
"\n",
|
||||
"# BM25 + fastText vectors\n",
|
||||
"embeddings = Embeddings({\"path\": \"cord19-300d.magnitude\",\n",
|
||||
" \"scoring\": \"bm25\",\n",
|
||||
" \"pca\": 3})\n",
|
||||
"\n",
|
||||
"# Build scoring index if scoring method provided\n",
|
||||
"if embeddings.config.get(\"scoring\"):\n",
|
||||
" embeddings.score(stream())\n",
|
||||
"\n",
|
||||
"# Build embeddings index\n",
|
||||
"embeddings.index(stream())\n"
|
||||
],
|
||||
"execution_count": 4,
|
||||
"outputs": [
|
||||
{
|
||||
"output_type": "stream",
|
||||
"text": [
|
||||
"Iterated over 21499 total rows\n",
|
||||
"Iterated over 21499 total rows\n"
|
||||
],
|
||||
"name": "stdout"
|
||||
}
|
||||
]
|
||||
},
|
||||
{
|
||||
"cell_type": "markdown",
|
||||
"metadata": {
|
||||
"id": "zHk24su3e_gb",
|
||||
"colab_type": "text"
|
||||
},
|
||||
"source": [
|
||||
"# Query data\n",
|
||||
"\n",
|
||||
"The following runs a query against the embeddings index for the terms \"comorbidities risk factors\". It finds the top 5 matches and returns the corresponding documents associated with each match."
|
||||
]
|
||||
},
|
||||
{
|
||||
"cell_type": "code",
|
||||
"metadata": {
|
||||
"id": "CRbDhvvDKEl-",
|
||||
"colab_type": "code",
|
||||
"colab": {
|
||||
"base_uri": "https://localhost:8080/",
|
||||
"height": 293
|
||||
},
|
||||
"outputId": "d0e9afef-f761-450c-ec9b-2724b6aa0922"
|
||||
},
|
||||
"source": [
|
||||
"import pandas as pd\n",
|
||||
"\n",
|
||||
"from IPython.display import display, HTML\n",
|
||||
"\n",
|
||||
"pd.set_option(\"display.max_colwidth\", None)\n",
|
||||
"\n",
|
||||
"db = sqlite3.connect(\"articles.sqlite\")\n",
|
||||
"cur = db.cursor()\n",
|
||||
"\n",
|
||||
"results = []\n",
|
||||
"for uid, score in embeddings.search(\"comorbidities risk factors\", 5):\n",
|
||||
" cur.execute(\"SELECT article, text FROM sections WHERE id = ?\", [uid])\n",
|
||||
" uid, text = cur.fetchone()\n",
|
||||
"\n",
|
||||
" cur.execute(\"SELECT Title, Published, Reference from articles where id = ?\", [uid])\n",
|
||||
" results.append(cur.fetchone() + (text,))\n",
|
||||
"\n",
|
||||
"# Free database resources\n",
|
||||
"db.close()\n",
|
||||
"\n",
|
||||
"df = pd.DataFrame(results, columns=[\"Title\", \"Published\", \"Reference\", \"Match\"])\n",
|
||||
"\n",
|
||||
"display(HTML(df.to_html(index=False)))"
|
||||
],
|
||||
"execution_count": 5,
|
||||
"outputs": [
|
||||
{
|
||||
"output_type": "display_data",
|
||||
"data": {
|
||||
"text/html": [
|
||||
"<table border=\"1\" class=\"dataframe\">\n",
|
||||
" <thead>\n",
|
||||
" <tr style=\"text-align: right;\">\n",
|
||||
" <th>Title</th>\n",
|
||||
" <th>Published</th>\n",
|
||||
" <th>Reference</th>\n",
|
||||
" <th>Match</th>\n",
|
||||
" </tr>\n",
|
||||
" </thead>\n",
|
||||
" <tbody>\n",
|
||||
" <tr>\n",
|
||||
" <td>Prevalence and Impact of Myocardial Injury in Patients Hospitalized with COVID-19 Infection</td>\n",
|
||||
" <td>2020-04-24 00:00:00</td>\n",
|
||||
" <td>http://medrxiv.org/cgi/content/short/2020.04.20.20072702v1?rss=1</td>\n",
|
||||
" <td>This risk was consistent across patients stratified by history of CVD, risk factors but no CVD, and neither CVD nor risk factors.</td>\n",
|
||||
" </tr>\n",
|
||||
" <tr>\n",
|
||||
" <td>COVID-19 and associations with frailty and multimorbidity: a prospective analysis of UK Biobank participants</td>\n",
|
||||
" <td>2020-07-23 00:00:00</td>\n",
|
||||
" <td>https://www.ncbi.nlm.nih.gov/pubmed/32705587/</td>\n",
|
||||
" <td>The identification of risk factors for contracting COVID-19 is crucial, to inform public health policy and to facilitate the appropriate distribution of healthcare resources.</td>\n",
|
||||
" </tr>\n",
|
||||
" <tr>\n",
|
||||
" <td>Does apolipoprotein E genotype predict COVID-19 severity?</td>\n",
|
||||
" <td>2020-04-27 00:00:00</td>\n",
|
||||
" <td>https://doi.org/10.1093/qjmed/hcaa142</td>\n",
|
||||
" <td>Of interest, apoE4 has also been associated with some of the comorbid risk factors associated with severe COVID-19, such as atherosclerosis and hypertension .</td>\n",
|
||||
" </tr>\n",
|
||||
" <tr>\n",
|
||||
" <td>COVID-19 and associations with frailty and multimorbidity: a prospective analysis of UK Biobank participants</td>\n",
|
||||
" <td>2020-07-23 00:00:00</td>\n",
|
||||
" <td>https://www.ncbi.nlm.nih.gov/pubmed/32705587/</td>\n",
|
||||
" <td>Number of comorbidity groupings were then summed, and categorised (0–1; 2; 3 or ≥ 4 comorbidity groupings).</td>\n",
|
||||
" </tr>\n",
|
||||
" <tr>\n",
|
||||
" <td>COVID-19 and associations with frailty and multimorbidity: a prospective analysis of UK Biobank participants</td>\n",
|
||||
" <td>2020-07-23 00:00:00</td>\n",
|
||||
" <td>https://www.ncbi.nlm.nih.gov/pubmed/32705587/</td>\n",
|
||||
" <td>Number of comorbidity groupings were then summed, and categorised (0-1; 2; 3 or ≥ 4 comorbidity groupings).</td>\n",
|
||||
" </tr>\n",
|
||||
" </tbody>\n",
|
||||
"</table>"
|
||||
],
|
||||
"text/plain": [
|
||||
"<IPython.core.display.HTML object>"
|
||||
]
|
||||
},
|
||||
"metadata": {
|
||||
"tags": []
|
||||
}
|
||||
}
|
||||
]
|
||||
},
|
||||
{
|
||||
"cell_type": "markdown",
|
||||
"metadata": {
|
||||
"id": "XSf68I-ZfXOG",
|
||||
"colab_type": "text"
|
||||
},
|
||||
"source": [
|
||||
"# Extracting additional columns from query results\n",
|
||||
"\n",
|
||||
"The example above uses the Embeddings index to find the top 5 best matches. In addition to this, an Extractor instance is used to ask additional questions over the search results, creating a richer query response."
|
||||
]
|
||||
},
|
||||
{
|
||||
"cell_type": "code",
|
||||
"metadata": {
|
||||
"id": "TLVOTQJchvTi",
|
||||
"colab_type": "code",
|
||||
"colab": {}
|
||||
},
|
||||
"source": [
|
||||
"%%capture\n",
|
||||
"from txtai.extractor import Extractor\n",
|
||||
"\n",
|
||||
"# Create extractor instance using qa model designed for the CORD-19 dataset\n",
|
||||
"extractor = Extractor(embeddings, \"NeuML/bert-small-cord19qa\")"
|
||||
],
|
||||
"execution_count": 6,
|
||||
"outputs": []
|
||||
},
|
||||
{
|
||||
"cell_type": "code",
|
||||
"metadata": {
|
||||
"id": "19fmKawThs6d",
|
||||
"colab_type": "code",
|
||||
"colab": {
|
||||
"base_uri": "https://localhost:8080/",
|
||||
"height": 293
|
||||
},
|
||||
"outputId": "15c337b5-7c6d-4b5e-98aa-e3996a799737"
|
||||
},
|
||||
"source": [
|
||||
"db = sqlite3.connect(\"articles.sqlite\")\n",
|
||||
"cur = db.cursor()\n",
|
||||
"\n",
|
||||
"results = []\n",
|
||||
"for uid, score in embeddings.search(\"comorbidities risk factors\", 5):\n",
|
||||
" cur.execute(\"SELECT article, text FROM sections WHERE id = ?\", [uid])\n",
|
||||
" uid, text = cur.fetchone()\n",
|
||||
"\n",
|
||||
" # Get list of document text sections to use for the context\n",
|
||||
" cur.execute(\"SELECT Id, Name, Text FROM sections WHERE (labels is null or labels NOT IN ('FRAGMENT', 'QUESTION')) AND article = ?\", [uid])\n",
|
||||
" sections = []\n",
|
||||
" for sid, name, text in cur.fetchall():\n",
|
||||
" if not name or not re.search(r\"background|(?<!.*?results.*?)discussion|introduction|reference\", name.lower()):\n",
|
||||
" sections.append((sid, text))\n",
|
||||
"\n",
|
||||
" cur.execute(\"SELECT Title, Published, Reference from articles where id = ?\", [uid])\n",
|
||||
" article = cur.fetchone()\n",
|
||||
"\n",
|
||||
" # Use QA extractor to derive additional columns\n",
|
||||
" answers = extractor(sections, [(\"Risk Factors\", \"risk factor\", \"What are names of risk factors?\", False),\n",
|
||||
" (\"Locations\", \"city country state\", \"What locations?\", False)])\n",
|
||||
"\n",
|
||||
" results.append(article + (text,) + tuple([answer[1] for answer in answers]))\n",
|
||||
"\n",
|
||||
"# Free database resources\n",
|
||||
"db.close()\n",
|
||||
"\n",
|
||||
"df = pd.DataFrame(results, columns=[\"Title\", \"Published\", \"Reference\", \"Match\", \"Risk Factors\", \"Locations\"])\n",
|
||||
"display(HTML(df.to_html(index=False)))"
|
||||
],
|
||||
"execution_count": 7,
|
||||
"outputs": [
|
||||
{
|
||||
"output_type": "display_data",
|
||||
"data": {
|
||||
"text/html": [
|
||||
"<table border=\"1\" class=\"dataframe\">\n",
|
||||
" <thead>\n",
|
||||
" <tr style=\"text-align: right;\">\n",
|
||||
" <th>Title</th>\n",
|
||||
" <th>Published</th>\n",
|
||||
" <th>Reference</th>\n",
|
||||
" <th>Match</th>\n",
|
||||
" <th>Risk Factors</th>\n",
|
||||
" <th>Locations</th>\n",
|
||||
" </tr>\n",
|
||||
" </thead>\n",
|
||||
" <tbody>\n",
|
||||
" <tr>\n",
|
||||
" <td>Prevalence and Impact of Myocardial Injury in Patients Hospitalized with COVID-19 Infection</td>\n",
|
||||
" <td>2020-04-24 00:00:00</td>\n",
|
||||
" <td>http://medrxiv.org/cgi/content/short/2020.04.20.20072702v1?rss=1</td>\n",
|
||||
" <td>Stratified by Troponin Levels, N = 2736 All Patients All rights reserved.</td>\n",
|
||||
" <td>no CVD, and neither CVD nor risk factors</td>\n",
|
||||
" <td>Mount Sinai Health System</td>\n",
|
||||
" </tr>\n",
|
||||
" <tr>\n",
|
||||
" <td>COVID-19 and associations with frailty and multimorbidity: a prospective analysis of UK Biobank participants</td>\n",
|
||||
" <td>2020-07-23 00:00:00</td>\n",
|
||||
" <td>https://www.ncbi.nlm.nih.gov/pubmed/32705587/</td>\n",
|
||||
" <td>The age range at baseline within our sample was 40–69 years, but it is important to note that this was during 2006–2010, and the age range at COVID-19 diagnosis was substantially older (50–84 years).</td>\n",
|
||||
" <td>Frailty and multimorbidity</td>\n",
|
||||
" <td>None</td>\n",
|
||||
" </tr>\n",
|
||||
" <tr>\n",
|
||||
" <td>Does apolipoprotein E genotype predict COVID-19 severity?</td>\n",
|
||||
" <td>2020-04-27 00:00:00</td>\n",
|
||||
" <td>https://doi.org/10.1093/qjmed/hcaa142</td>\n",
|
||||
" <td>If so, this group could be targeted more aggressively from the outset of the disease.</td>\n",
|
||||
" <td>None</td>\n",
|
||||
" <td>None</td>\n",
|
||||
" </tr>\n",
|
||||
" <tr>\n",
|
||||
" <td>COVID-19 and associations with frailty and multimorbidity: a prospective analysis of UK Biobank participants</td>\n",
|
||||
" <td>2020-07-23 00:00:00</td>\n",
|
||||
" <td>https://www.ncbi.nlm.nih.gov/pubmed/32705587/</td>\n",
|
||||
" <td>The age range at baseline within our sample was 40–69 years, but it is important to note that this was during 2006–2010, and the age range at COVID-19 diagnosis was substantially older (50–84 years).</td>\n",
|
||||
" <td>Frailty and multimorbidity</td>\n",
|
||||
" <td>None</td>\n",
|
||||
" </tr>\n",
|
||||
" <tr>\n",
|
||||
" <td>COVID-19 and associations with frailty and multimorbidity: a prospective analysis of UK Biobank participants</td>\n",
|
||||
" <td>2020-07-23 00:00:00</td>\n",
|
||||
" <td>https://www.ncbi.nlm.nih.gov/pubmed/32705587/</td>\n",
|
||||
" <td>The age range at baseline within our sample was 40–69 years, but it is important to note that this was during 2006–2010, and the age range at COVID-19 diagnosis was substantially older (50–84 years).</td>\n",
|
||||
" <td>Frailty and multimorbidity</td>\n",
|
||||
" <td>None</td>\n",
|
||||
" </tr>\n",
|
||||
" </tbody>\n",
|
||||
"</table>"
|
||||
],
|
||||
"text/plain": [
|
||||
"<IPython.core.display.HTML object>"
|
||||
]
|
||||
},
|
||||
"metadata": {
|
||||
"tags": []
|
||||
}
|
||||
}
|
||||
]
|
||||
},
|
||||
{
|
||||
"cell_type": "markdown",
|
||||
"metadata": {
|
||||
"id": "ColTLy--rWfR",
|
||||
"colab_type": "text"
|
||||
},
|
||||
"source": [
|
||||
"In the example above, the Embeddings index is used to find the top N results for a given query. On top of that, a question-answer extractor is used to derive additional columns based on a list of questions. In this case, the \"Risk Factors\" and \"Location\" columns were pulled from the document text."
|
||||
]
|
||||
},
|
||||
{
|
||||
"cell_type": "markdown",
|
||||
"metadata": {
|
||||
"id": "KWyoysauy7Pr",
|
||||
"colab_type": "text"
|
||||
},
|
||||
"source": [
|
||||
"# Next\n",
|
||||
"In part 4 of this series, we'll use combine the power of Elasticsearch with Extractive QA to build a large-scale, advanced search system.\n"
|
||||
]
|
||||
}
|
||||
]
|
||||
}
|
||||
@@ -0,0 +1,460 @@
|
||||
{
|
||||
"nbformat": 4,
|
||||
"nbformat_minor": 0,
|
||||
"metadata": {
|
||||
"colab": {
|
||||
"name": "04 - Extractive QA with Elasticsearch",
|
||||
"provenance": []
|
||||
},
|
||||
"kernelspec": {
|
||||
"name": "python3",
|
||||
"display_name": "Python 3"
|
||||
}
|
||||
},
|
||||
"cells": [
|
||||
{
|
||||
"cell_type": "markdown",
|
||||
"metadata": {
|
||||
"id": "zzZbP0LM6m5z",
|
||||
"colab_type": "text"
|
||||
},
|
||||
"source": [
|
||||
"# Extractive QA with Elasticsearch\n",
|
||||
"\n",
|
||||
"txtai is datastore agnostic, the library analyzes sets of text. The following example shows how extractive question-answering can be added on top of an Elasticesearch system."
|
||||
]
|
||||
},
|
||||
{
|
||||
"cell_type": "markdown",
|
||||
"metadata": {
|
||||
"id": "xk7t5Jcd6reO",
|
||||
"colab_type": "text"
|
||||
},
|
||||
"source": [
|
||||
"# Install txtai and Elasticsearch\n",
|
||||
"\n",
|
||||
"Install txtai and Elasticsearch. Start an instance of Elasticsearch directly within this notebook. "
|
||||
]
|
||||
},
|
||||
{
|
||||
"cell_type": "code",
|
||||
"metadata": {
|
||||
"id": "0y1UA4-q-YdA",
|
||||
"colab_type": "code",
|
||||
"colab": {}
|
||||
},
|
||||
"source": [
|
||||
"%%capture\n",
|
||||
"\n",
|
||||
"# Install txtai and elasticsearch python client\n",
|
||||
"!pip install git+https://github.com/neuml/txtai elasticsearch\n",
|
||||
"\n",
|
||||
"# Download and extract elasticsearch\n",
|
||||
"!wget https://artifacts.elastic.co/downloads/elasticsearch/elasticsearch-7.8.1-linux-x86_64.tar.gz\n",
|
||||
"!tar -xzf elasticsearch-7.8.1-linux-x86_64.tar.gz\n",
|
||||
"!chown -R daemon:daemon elasticsearch-7.8.1"
|
||||
],
|
||||
"execution_count": 16,
|
||||
"outputs": []
|
||||
},
|
||||
{
|
||||
"cell_type": "code",
|
||||
"metadata": {
|
||||
"id": "3ZfJeWbM6wmj",
|
||||
"colab_type": "code",
|
||||
"colab": {}
|
||||
},
|
||||
"source": [
|
||||
"import os\n",
|
||||
"from subprocess import Popen, PIPE, STDOUT\n",
|
||||
"\n",
|
||||
"# Start and wait for server\n",
|
||||
"server = Popen(['elasticsearch-7.8.1/bin/elasticsearch'], stdout=PIPE, stderr=STDOUT, preexec_fn=lambda: os.setuid(1))\n",
|
||||
"!sleep 30"
|
||||
],
|
||||
"execution_count": 17,
|
||||
"outputs": []
|
||||
},
|
||||
{
|
||||
"cell_type": "markdown",
|
||||
"metadata": {
|
||||
"id": "TWEn4w68-D1y",
|
||||
"colab_type": "text"
|
||||
},
|
||||
"source": [
|
||||
"# Download data\n",
|
||||
"\n",
|
||||
"This example is going to work off a subset of the [CORD-19](https://www.semanticscholar.org/cord19) dataset. COVID-19 Open Research Dataset (CORD-19) is a free resource of scholarly articles, aggregated by a coalition of leading research groups, covering COVID-19 and the coronavirus family of viruses.\n",
|
||||
"\n",
|
||||
"The following download is SQLite database with a subject of CORD-19, generated from a [Kaggle notebook](https://www.kaggle.com/davidmezzetti/cord-19-slim/output). More information on this data format, can be found in the [CORD-19 Analysis](https://www.kaggle.com/davidmezzetti/cord-19-analysis-with-sentence-embeddings) notebook."
|
||||
]
|
||||
},
|
||||
{
|
||||
"cell_type": "code",
|
||||
"metadata": {
|
||||
"id": "8tVrIqSq-KBa",
|
||||
"colab_type": "code",
|
||||
"colab": {
|
||||
"base_uri": "https://localhost:8080/",
|
||||
"height": 228
|
||||
},
|
||||
"outputId": "7f46594f-b0f2-4994-dc0b-70e50fe132fc"
|
||||
},
|
||||
"source": [
|
||||
"!wget https://www.kaggleusercontent.com/kf/40510829/eyJhbGciOiJkaXIiLCJlbmMiOiJBMTI4Q0JDLUhTMjU2In0..FX7Ote_I-Y88MBPQHRIdUQ.tTr7P3B_eUL_yWN33Usz0Rk1KXtc4DjT_cdjkl5W4WbEcZ-0FJX2jSWTHYMVACtLYuMJJrf6eJN28OzWhDMnTysBu3wfDrd4ly5bu_wJKCnZajICQgQHs_b8hbRVMOzfdG6xEyl9CVYnZNU2cI3QuOshcWxoB0skdKD4d26O_Q4e_nrd8DqEixP47tI2Hu1F00w0vMykzgNwp7SwQ2Z9HoNCO8HtmcjEHq0A4lZ4303YkpjORtZQEO3S-j54fFlIAahT-9VvsFNofitK5VAlR0EyG9r3cOqh2LQDCL7kj5p3MxG8dvHmrTqggLVOwiuKHUIH8u59TemSMLsNRS29W-5fFlHfaItV4dEuiBxCIgQXHcKUDCDGEjeFcPgqpJnNHsnh0pebWDuRQR_fdQ-r8mWgN9qLnosrFBak9tM25G7gqxyUI90GMWAUyP4yj2EAEc8asX9rUsirC8QDHmrmOCUe0cmZvodRUi0ss7lTiLTwm55d9VPXjQn4jQ6tFs-dmjXEx0AwF2Mw1c1jhgzCXwgQj6ybUKemr_6wj1VFYj3VVvCXpk1nZObl-IB6-m7v5CIoXGLot_KFsVtyItRk-wX-B_L3W3aS9dOIfb7bX4s5_aNzXaDKvxrcafwlOQui.vS_FL4EArO8rkBo3xpDF2w/articles.sqlite"
|
||||
],
|
||||
"execution_count": 18,
|
||||
"outputs": [
|
||||
{
|
||||
"output_type": "stream",
|
||||
"text": [
|
||||
"--2020-08-11 15:41:39-- https://www.kaggleusercontent.com/kf/40510829/eyJhbGciOiJkaXIiLCJlbmMiOiJBMTI4Q0JDLUhTMjU2In0..FX7Ote_I-Y88MBPQHRIdUQ.tTr7P3B_eUL_yWN33Usz0Rk1KXtc4DjT_cdjkl5W4WbEcZ-0FJX2jSWTHYMVACtLYuMJJrf6eJN28OzWhDMnTysBu3wfDrd4ly5bu_wJKCnZajICQgQHs_b8hbRVMOzfdG6xEyl9CVYnZNU2cI3QuOshcWxoB0skdKD4d26O_Q4e_nrd8DqEixP47tI2Hu1F00w0vMykzgNwp7SwQ2Z9HoNCO8HtmcjEHq0A4lZ4303YkpjORtZQEO3S-j54fFlIAahT-9VvsFNofitK5VAlR0EyG9r3cOqh2LQDCL7kj5p3MxG8dvHmrTqggLVOwiuKHUIH8u59TemSMLsNRS29W-5fFlHfaItV4dEuiBxCIgQXHcKUDCDGEjeFcPgqpJnNHsnh0pebWDuRQR_fdQ-r8mWgN9qLnosrFBak9tM25G7gqxyUI90GMWAUyP4yj2EAEc8asX9rUsirC8QDHmrmOCUe0cmZvodRUi0ss7lTiLTwm55d9VPXjQn4jQ6tFs-dmjXEx0AwF2Mw1c1jhgzCXwgQj6ybUKemr_6wj1VFYj3VVvCXpk1nZObl-IB6-m7v5CIoXGLot_KFsVtyItRk-wX-B_L3W3aS9dOIfb7bX4s5_aNzXaDKvxrcafwlOQui.vS_FL4EArO8rkBo3xpDF2w/articles.sqlite\n",
|
||||
"Resolving www.kaggleusercontent.com (www.kaggleusercontent.com)... 35.190.26.106\n",
|
||||
"Connecting to www.kaggleusercontent.com (www.kaggleusercontent.com)|35.190.26.106|:443... connected.\n",
|
||||
"HTTP request sent, awaiting response... 200 OK\n",
|
||||
"Length: 8065024 (7.7M) [application/octet-stream]\n",
|
||||
"Saving to: ‘articles.sqlite.1’\n",
|
||||
"\n",
|
||||
"\rarticles.sqlite.1 0%[ ] 0 --.-KB/s \rarticles.sqlite.1 100%[===================>] 7.69M --.-KB/s in 0.1s \n",
|
||||
"\n",
|
||||
"2020-08-11 15:41:39 (77.5 MB/s) - ‘articles.sqlite.1’ saved [8065024/8065024]\n",
|
||||
"\n"
|
||||
],
|
||||
"name": "stdout"
|
||||
}
|
||||
]
|
||||
},
|
||||
{
|
||||
"cell_type": "markdown",
|
||||
"metadata": {
|
||||
"id": "hSWFzkCn61tM",
|
||||
"colab_type": "text"
|
||||
},
|
||||
"source": [
|
||||
"# Load data into Elasticsearch\n",
|
||||
"\n",
|
||||
"The following block copies rows from SQLite to Elasticsearch."
|
||||
]
|
||||
},
|
||||
{
|
||||
"cell_type": "code",
|
||||
"metadata": {
|
||||
"id": "So-OBvUT61QD",
|
||||
"colab_type": "code",
|
||||
"colab": {
|
||||
"base_uri": "https://localhost:8080/",
|
||||
"height": 34
|
||||
},
|
||||
"outputId": "8ccfed53-bc46-4619-9b82-31a30ce38b55"
|
||||
},
|
||||
"source": [
|
||||
"import sqlite3\n",
|
||||
"\n",
|
||||
"import regex as re\n",
|
||||
"\n",
|
||||
"from elasticsearch import Elasticsearch, helpers\n",
|
||||
"\n",
|
||||
"# Connect to ES instance\n",
|
||||
"es = Elasticsearch(hosts=[\"http://localhost:9200\"], timeout=60, retry_on_timeout=True)\n",
|
||||
"\n",
|
||||
"# Connection to database file\n",
|
||||
"db = sqlite3.connect(\"articles.sqlite\")\n",
|
||||
"cur = db.cursor()\n",
|
||||
"\n",
|
||||
"# Elasticsearch bulk buffer\n",
|
||||
"buffer = []\n",
|
||||
"rows = 0\n",
|
||||
"\n",
|
||||
"# Select tagged sentences without a NLP label. NLP labels are set for non-informative sentences.\n",
|
||||
"cur.execute(\"SELECT s.Id, Article, Title, Published, Reference, Name, Text FROM sections s JOIN articles a on s.article=a.id WHERE (s.labels is null or s.labels NOT IN ('FRAGMENT', 'QUESTION')) AND s.tags is not null\")\n",
|
||||
"for row in cur:\n",
|
||||
" # Build dict of name-value pairs for fields\n",
|
||||
" article = dict(zip((\"id\", \"article\", \"title\", \"published\", \"reference\", \"name\", \"text\"), row))\n",
|
||||
" name = article[\"name\"]\n",
|
||||
"\n",
|
||||
" # Only process certain document sections\n",
|
||||
" if not name or not re.search(r\"background|(?<!.*?results.*?)discussion|introduction|reference\", name.lower()):\n",
|
||||
" # Bulk action fields\n",
|
||||
" article[\"_id\"] = article[\"id\"]\n",
|
||||
" article[\"_index\"] = \"articles\"\n",
|
||||
"\n",
|
||||
" # Buffer article\n",
|
||||
" buffer.append(article)\n",
|
||||
"\n",
|
||||
" # Increment number of articles processed\n",
|
||||
" rows += 1\n",
|
||||
"\n",
|
||||
" # Bulk load every 1000 records\n",
|
||||
" if rows % 1000 == 0:\n",
|
||||
" helpers.bulk(es, buffer)\n",
|
||||
" buffer = []\n",
|
||||
"\n",
|
||||
" print(\"Inserted {} articles\".format(rows), end=\"\\r\")\n",
|
||||
"\n",
|
||||
"if buffer:\n",
|
||||
" helpers.bulk(es, buffer)\n",
|
||||
"\n",
|
||||
"print(\"Total articles inserted: {}\".format(rows))\n"
|
||||
],
|
||||
"execution_count": 19,
|
||||
"outputs": [
|
||||
{
|
||||
"output_type": "stream",
|
||||
"text": [
|
||||
"Total articles inserted: 21499\n"
|
||||
],
|
||||
"name": "stdout"
|
||||
}
|
||||
]
|
||||
},
|
||||
{
|
||||
"cell_type": "markdown",
|
||||
"metadata": {
|
||||
"id": "X5RO-VNwzMAo",
|
||||
"colab_type": "text"
|
||||
},
|
||||
"source": [
|
||||
"# Query data\n",
|
||||
"\n",
|
||||
"The following runs a query against Elasticsearch for the terms \"comorbidities risk factors\". It finds the top 5 matches and returns the corresponding documents associated with each match.\n",
|
||||
"\n"
|
||||
]
|
||||
},
|
||||
{
|
||||
"cell_type": "code",
|
||||
"metadata": {
|
||||
"id": "ucd9mwSfFTMm",
|
||||
"colab_type": "code",
|
||||
"colab": {
|
||||
"base_uri": "https://localhost:8080/",
|
||||
"height": 293
|
||||
},
|
||||
"outputId": "5c3b9acf-25b9-4782-faff-a098da84916b"
|
||||
},
|
||||
"source": [
|
||||
"import pandas as pd\n",
|
||||
"\n",
|
||||
"from IPython.display import display, HTML\n",
|
||||
"\n",
|
||||
"pd.set_option(\"display.max_colwidth\", None)\n",
|
||||
"\n",
|
||||
"query = {\n",
|
||||
" \"_source\": [\"article\", \"title\", \"published\", \"reference\", \"text\"],\n",
|
||||
" \"size\": 5,\n",
|
||||
" \"query\": {\n",
|
||||
" \"query_string\": {\"query\": \"comorbidities risk factors\"}\n",
|
||||
" }\n",
|
||||
"}\n",
|
||||
"\n",
|
||||
"results = []\n",
|
||||
"for result in es.search(index=\"articles\", body=query)[\"hits\"][\"hits\"]:\n",
|
||||
" source = result[\"_source\"]\n",
|
||||
" results.append((source[\"title\"], source[\"published\"], source[\"reference\"], source[\"text\"]))\n",
|
||||
"\n",
|
||||
"df = pd.DataFrame(results, columns=[\"Title\", \"Published\", \"Reference\", \"Match\"])\n",
|
||||
"\n",
|
||||
"display(HTML(df.to_html(index=False)))"
|
||||
],
|
||||
"execution_count": 20,
|
||||
"outputs": [
|
||||
{
|
||||
"output_type": "display_data",
|
||||
"data": {
|
||||
"text/html": [
|
||||
"<table border=\"1\" class=\"dataframe\">\n",
|
||||
" <thead>\n",
|
||||
" <tr style=\"text-align: right;\">\n",
|
||||
" <th>Title</th>\n",
|
||||
" <th>Published</th>\n",
|
||||
" <th>Reference</th>\n",
|
||||
" <th>Match</th>\n",
|
||||
" </tr>\n",
|
||||
" </thead>\n",
|
||||
" <tbody>\n",
|
||||
" <tr>\n",
|
||||
" <td>Management of osteoarthritis during COVID‐19 pandemic</td>\n",
|
||||
" <td>2020-05-21 00:00:00</td>\n",
|
||||
" <td>https://doi.org/10.1002/cpt.1910</td>\n",
|
||||
" <td>Indeed, risk factors are sex, obesity, genetic factors and mechanical factors (3) .</td>\n",
|
||||
" </tr>\n",
|
||||
" <tr>\n",
|
||||
" <td>Prevalence and Impact of Myocardial Injury in Patients Hospitalized with COVID-19 Infection</td>\n",
|
||||
" <td>2020-04-24 00:00:00</td>\n",
|
||||
" <td>http://medrxiv.org/cgi/content/short/2020.04.20.20072702v1?rss=1</td>\n",
|
||||
" <td>This risk was consistent across patients stratified by history of CVD, risk factors but no CVD, and neither CVD nor risk factors.</td>\n",
|
||||
" </tr>\n",
|
||||
" <tr>\n",
|
||||
" <td>Lower prevalence of antibodies neutralizing SARS-CoV-2 in group O French blood donors</td>\n",
|
||||
" <td>2020-07-15 00:00:00</td>\n",
|
||||
" <td>https://www.ncbi.nlm.nih.gov/pubmed/32679056/</td>\n",
|
||||
" <td>Age, sex and various comorbidities have been identified as factors worsening the prognosis of the disease.</td>\n",
|
||||
" </tr>\n",
|
||||
" <tr>\n",
|
||||
" <td>Does apolipoprotein E genotype predict COVID-19 severity?</td>\n",
|
||||
" <td>2020-04-27 00:00:00</td>\n",
|
||||
" <td>https://doi.org/10.1093/qjmed/hcaa142</td>\n",
|
||||
" <td>Risk factors associated with subsequent death include older age, hypertension, diabetes, ischemic heart disease, obesity and chronic lung disease; however, sometimes there are no obvious risk factors .</td>\n",
|
||||
" </tr>\n",
|
||||
" <tr>\n",
|
||||
" <td>Risk Stratification for Healthcare workers during the CoViD-19 Pandemic; using demographics, co-morbid disease and clinical domain in order to assign clinical duties</td>\n",
|
||||
" <td>2020-05-09 00:00:00</td>\n",
|
||||
" <td>http://medrxiv.org/cgi/content/short/2020.05.05.20091967v1?rss=1</td>\n",
|
||||
" <td>A risk stratification tool was compiled using a Caucasian female <50years with no comorbidities as a reference.</td>\n",
|
||||
" </tr>\n",
|
||||
" </tbody>\n",
|
||||
"</table>"
|
||||
],
|
||||
"text/plain": [
|
||||
"<IPython.core.display.HTML object>"
|
||||
]
|
||||
},
|
||||
"metadata": {
|
||||
"tags": []
|
||||
}
|
||||
}
|
||||
]
|
||||
},
|
||||
{
|
||||
"cell_type": "code",
|
||||
"metadata": {
|
||||
"id": "mwBTrCkcOM_H",
|
||||
"colab_type": "code",
|
||||
"colab": {}
|
||||
},
|
||||
"source": [
|
||||
"%%capture\n",
|
||||
"from txtai.embeddings import Embeddings\n",
|
||||
"from txtai.extractor import Extractor\n",
|
||||
"\n",
|
||||
"# Create embeddings model, backed by sentence-transformers & transformers\n",
|
||||
"embeddings = Embeddings({\"method\": \"transformers\", \"path\": \"sentence-transformers/bert-base-nli-stsb-mean-tokens\"})\n",
|
||||
"\n",
|
||||
"# Create extractor instance using qa model designed for the CORD-19 dataset\n",
|
||||
"extractor = Extractor(embeddings, \"NeuML/bert-small-cord19qa\")"
|
||||
],
|
||||
"execution_count": 21,
|
||||
"outputs": []
|
||||
},
|
||||
{
|
||||
"cell_type": "code",
|
||||
"metadata": {
|
||||
"id": "Yv75Lh-cOpL9",
|
||||
"colab_type": "code",
|
||||
"colab": {
|
||||
"base_uri": "https://localhost:8080/",
|
||||
"height": 328
|
||||
},
|
||||
"outputId": "4e341551-5af7-492f-e5c9-1904f8bf3689"
|
||||
},
|
||||
"source": [
|
||||
"document = {\n",
|
||||
" \"_source\": [\"id\", \"name\", \"text\"],\n",
|
||||
" \"size\": 1000,\n",
|
||||
" \"query\": {\n",
|
||||
" \"term\": {\"article\": None}\n",
|
||||
" },\n",
|
||||
" \"sort\" : [\"id\"]\n",
|
||||
"}\n",
|
||||
"\n",
|
||||
"def sections(article):\n",
|
||||
" rows = []\n",
|
||||
"\n",
|
||||
" search = document.copy()\n",
|
||||
" search[\"query\"][\"term\"][\"article\"] = article\n",
|
||||
"\n",
|
||||
" for result in es.search(index=\"articles\", body=search)[\"hits\"][\"hits\"]:\n",
|
||||
" source = result[\"_source\"]\n",
|
||||
" sid, name, text = source[\"id\"], source[\"name\"], source[\"text\"]\n",
|
||||
"\n",
|
||||
" if not name or not re.search(r\"background|(?<!.*?results.*?)discussion|introduction|reference\", name.lower()):\n",
|
||||
" rows.append((sid, text))\n",
|
||||
" \n",
|
||||
" return rows\n",
|
||||
"\n",
|
||||
"results = []\n",
|
||||
"for result in es.search(index=\"articles\", body=query)[\"hits\"][\"hits\"]:\n",
|
||||
" source = result[\"_source\"]\n",
|
||||
"\n",
|
||||
" # Use QA extractor to derive additional columns\n",
|
||||
" answers = extractor(sections(source[\"article\"]), [(\"Risk factors\", \"risk factor\", \"What are names of risk factors?\", False),\n",
|
||||
" (\"Locations\", \"city country state\", \"What are names of the locations?\", False)])\n",
|
||||
"\n",
|
||||
" results.append((source[\"title\"], source[\"published\"], source[\"reference\"], source[\"text\"]) + tuple([answer[1] for answer in answers]))\n",
|
||||
"\n",
|
||||
"df = pd.DataFrame(results, columns=[\"Title\", \"Published\", \"Reference\", \"Match\", \"Risk Factors\", \"Locations\"])\n",
|
||||
"\n",
|
||||
"display(HTML(df.to_html(index=False)))"
|
||||
],
|
||||
"execution_count": 22,
|
||||
"outputs": [
|
||||
{
|
||||
"output_type": "display_data",
|
||||
"data": {
|
||||
"text/html": [
|
||||
"<table border=\"1\" class=\"dataframe\">\n",
|
||||
" <thead>\n",
|
||||
" <tr style=\"text-align: right;\">\n",
|
||||
" <th>Title</th>\n",
|
||||
" <th>Published</th>\n",
|
||||
" <th>Reference</th>\n",
|
||||
" <th>Match</th>\n",
|
||||
" <th>Risk Factors</th>\n",
|
||||
" <th>Locations</th>\n",
|
||||
" </tr>\n",
|
||||
" </thead>\n",
|
||||
" <tbody>\n",
|
||||
" <tr>\n",
|
||||
" <td>Management of osteoarthritis during COVID‐19 pandemic</td>\n",
|
||||
" <td>2020-05-21 00:00:00</td>\n",
|
||||
" <td>https://doi.org/10.1002/cpt.1910</td>\n",
|
||||
" <td>Indeed, risk factors are sex, obesity, genetic factors and mechanical factors (3) .</td>\n",
|
||||
" <td>Comorbidities</td>\n",
|
||||
" <td>None</td>\n",
|
||||
" </tr>\n",
|
||||
" <tr>\n",
|
||||
" <td>Prevalence and Impact of Myocardial Injury in Patients Hospitalized with COVID-19 Infection</td>\n",
|
||||
" <td>2020-04-24 00:00:00</td>\n",
|
||||
" <td>http://medrxiv.org/cgi/content/short/2020.04.20.20072702v1?rss=1</td>\n",
|
||||
" <td>This risk was consistent across patients stratified by history of CVD, risk factors but no CVD, and neither CVD nor risk factors.</td>\n",
|
||||
" <td>CVD, risk factors but no CVD, and neither CVD</td>\n",
|
||||
" <td>None</td>\n",
|
||||
" </tr>\n",
|
||||
" <tr>\n",
|
||||
" <td>Lower prevalence of antibodies neutralizing SARS-CoV-2 in group O French blood donors</td>\n",
|
||||
" <td>2020-07-15 00:00:00</td>\n",
|
||||
" <td>https://www.ncbi.nlm.nih.gov/pubmed/32679056/</td>\n",
|
||||
" <td>Age, sex and various comorbidities have been identified as factors worsening the prognosis of the disease.</td>\n",
|
||||
" <td>Age, sex and various comorbidities</td>\n",
|
||||
" <td>Paris</td>\n",
|
||||
" </tr>\n",
|
||||
" <tr>\n",
|
||||
" <td>Does apolipoprotein E genotype predict COVID-19 severity?</td>\n",
|
||||
" <td>2020-04-27 00:00:00</td>\n",
|
||||
" <td>https://doi.org/10.1093/qjmed/hcaa142</td>\n",
|
||||
" <td>Risk factors associated with subsequent death include older age, hypertension, diabetes, ischemic heart disease, obesity and chronic lung disease; however, sometimes there are no obvious risk factors .</td>\n",
|
||||
" <td>socioeconomic inequalities and risk factors</td>\n",
|
||||
" <td>None</td>\n",
|
||||
" </tr>\n",
|
||||
" <tr>\n",
|
||||
" <td>Risk Stratification for Healthcare workers during the CoViD-19 Pandemic; using demographics, co-morbid disease and clinical domain in order to assign clinical duties</td>\n",
|
||||
" <td>2020-05-09 00:00:00</td>\n",
|
||||
" <td>http://medrxiv.org/cgi/content/short/2020.05.05.20091967v1?rss=1</td>\n",
|
||||
" <td>A risk stratification tool was compiled using a Caucasian female <50years with no comorbidities as a reference.</td>\n",
|
||||
" <td>Those working with aerosol generating procedures were at increased risk</td>\n",
|
||||
" <td>None</td>\n",
|
||||
" </tr>\n",
|
||||
" </tbody>\n",
|
||||
"</table>"
|
||||
],
|
||||
"text/plain": [
|
||||
"<IPython.core.display.HTML object>"
|
||||
]
|
||||
},
|
||||
"metadata": {
|
||||
"tags": []
|
||||
}
|
||||
}
|
||||
]
|
||||
}
|
||||
]
|
||||
}
|
||||
@@ -0,0 +1,50 @@
|
||||
"""
|
||||
Demo shell
|
||||
"""
|
||||
|
||||
from cmd import Cmd
|
||||
|
||||
import numpy as np
|
||||
|
||||
from txtai.embeddings import Embeddings
|
||||
|
||||
class Shell(Cmd):
|
||||
"""
|
||||
Query shell.
|
||||
"""
|
||||
|
||||
def __init__(self):
|
||||
super(Shell, self).__init__()
|
||||
|
||||
self.intro = "query shell"
|
||||
self.prompt = "(search) "
|
||||
|
||||
self.embeddings = None
|
||||
self.sections = None
|
||||
|
||||
def preloop(self):
|
||||
# Create embeddings model, backed by sentence-transformers & transformers
|
||||
self.embeddings = Embeddings({"method": "transformers", "path": "sentence-transformers/bert-base-nli-mean-tokens"})
|
||||
|
||||
self.sections = ["US tops 5 million confirmed virus cases",
|
||||
"Canada's last fully intact ice shelf has suddenly collapsed, forming a Manhattan-sized iceberg",
|
||||
"Beijing mobilises invasion craft along coast as Taiwan tensions escalate",
|
||||
"The National Park Service warns against sacrificing slower friends in a bear attack",
|
||||
"Maine man wins $1M from $25 lottery ticket",
|
||||
"Make huge profits without work, earn up to $100,000 a day"]
|
||||
|
||||
def default(self, line):
|
||||
# Get index of best section that best matches query
|
||||
uid = np.argmax(self.embeddings.similarity(line, self.sections))
|
||||
print(self.sections[uid])
|
||||
print()
|
||||
|
||||
def main():
|
||||
"""
|
||||
Shell execution loop.
|
||||
"""
|
||||
|
||||
Shell().cmdloop()
|
||||
|
||||
if __name__ == "__main__":
|
||||
main()
|
||||
Reference in New Issue
Block a user