mirror of
https://github.com/neuml/txtai.git
synced 2026-10-11 21:39:55 +00:00
Update documentation for 6.0, closes #513
This commit is contained in:
 davidmezzetti
@@ -2,9 +2,9 @@
|
||||
<img src="https://raw.githubusercontent.com/neuml/txtai/master/logo.png"/>
|
||||
</p>
|
||||
|
||||
<h3 align="center">
|
||||
<p>Semantic search and workflows powered by language models</p>
|
||||
</h3>
|
||||
<p align="center">
|
||||
<b>All-in-one embeddings database</b>
|
||||
</p>
|
||||
|
||||
<p align="center">
|
||||
<a href="https://github.com/neuml/txtai/releases">
|
||||
@@ -29,27 +29,18 @@
|
||||
|
||||
-------------------------------------------------------------------------------------------------------------------------------------------------------
|
||||
|
||||
txtai is an open-source platform for semantic search and workflows powered by language models.
|
||||
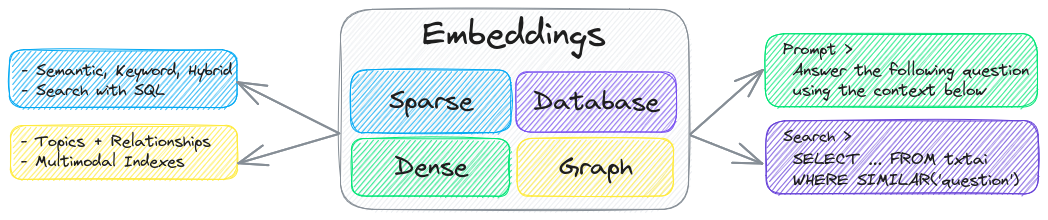
txtai is an all-in-one open-source embeddings database for semantic search, LLM orchestration and language model workflows.
|
||||
|
||||
|
||||
|
||||
|
||||
|
||||
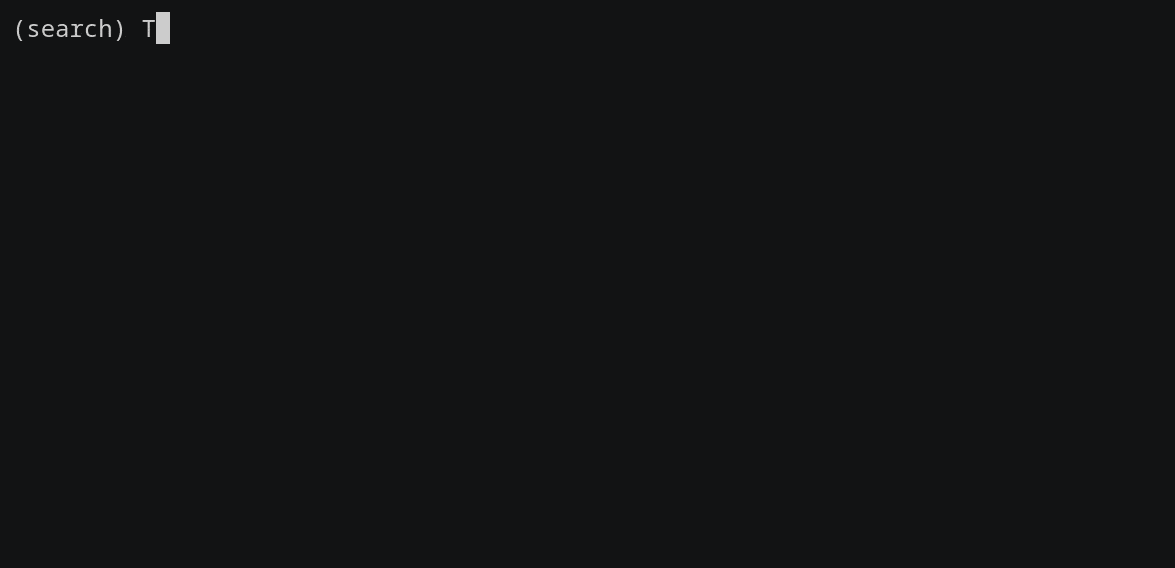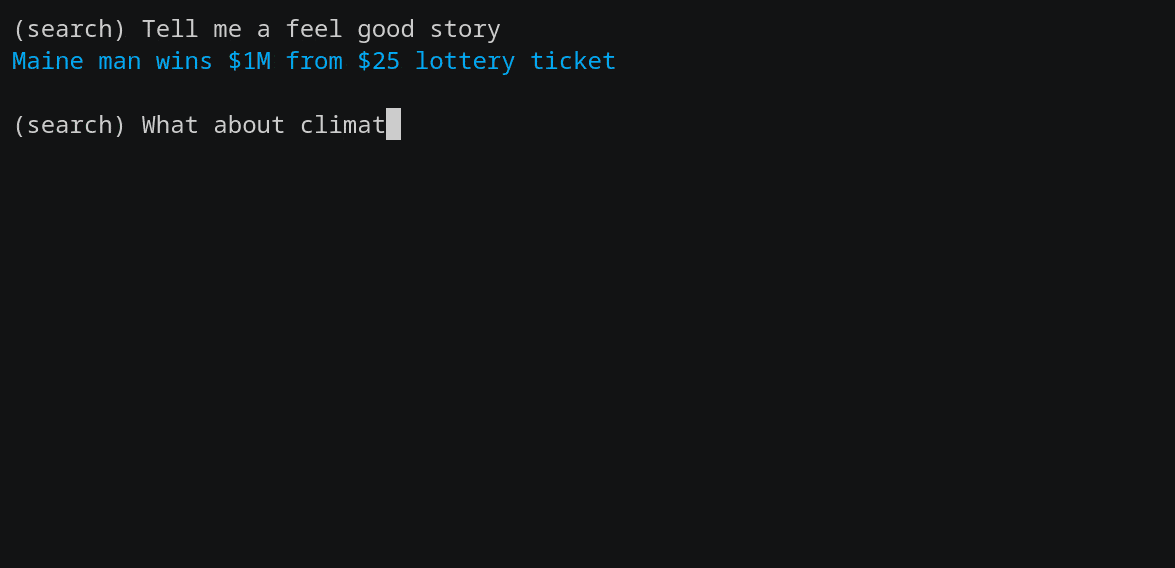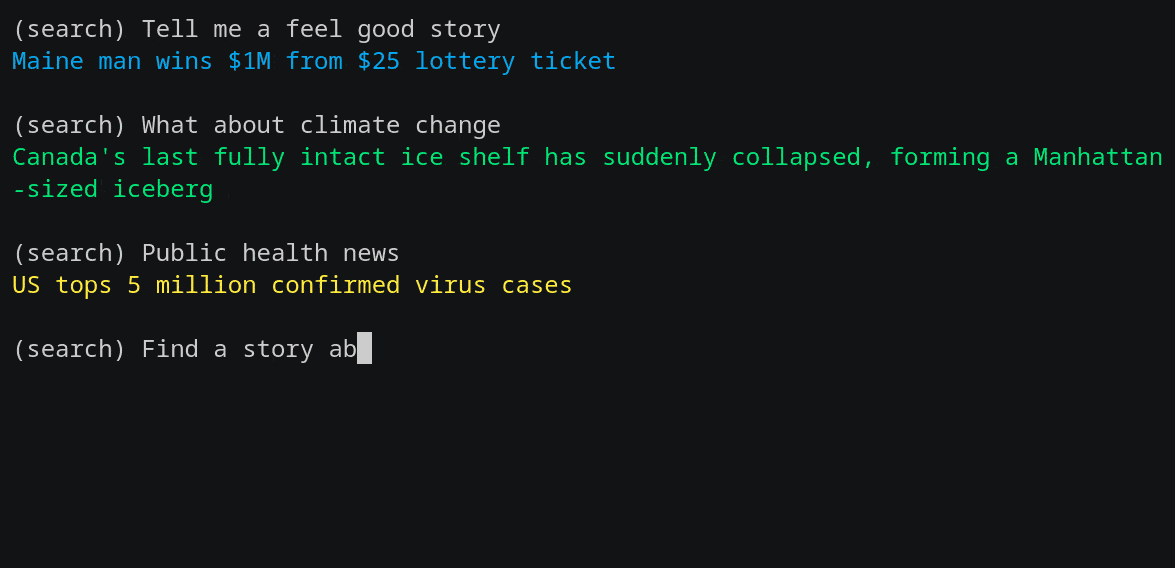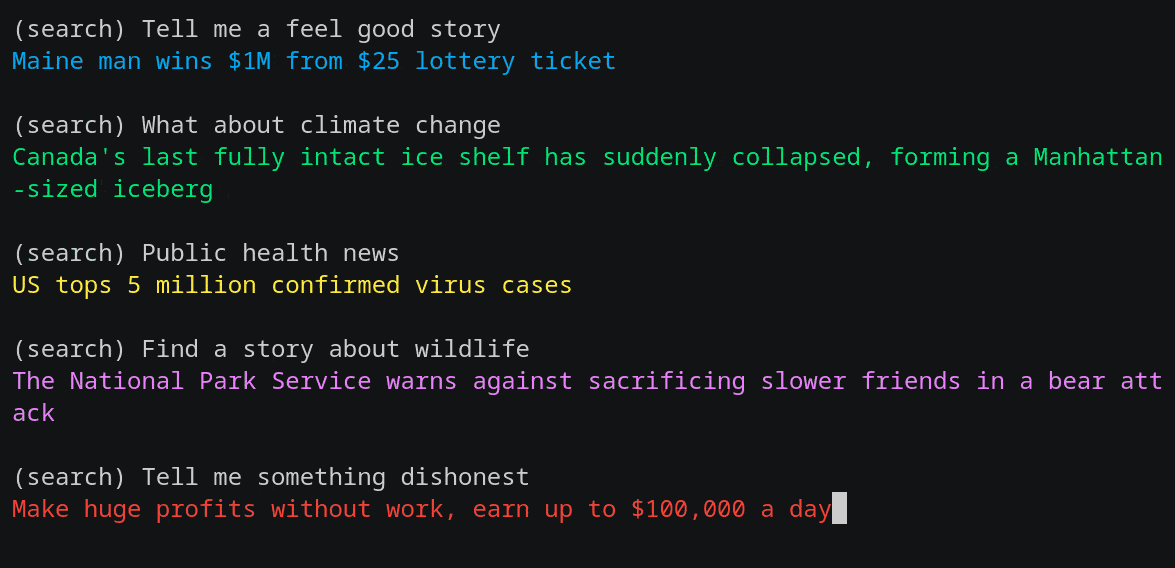
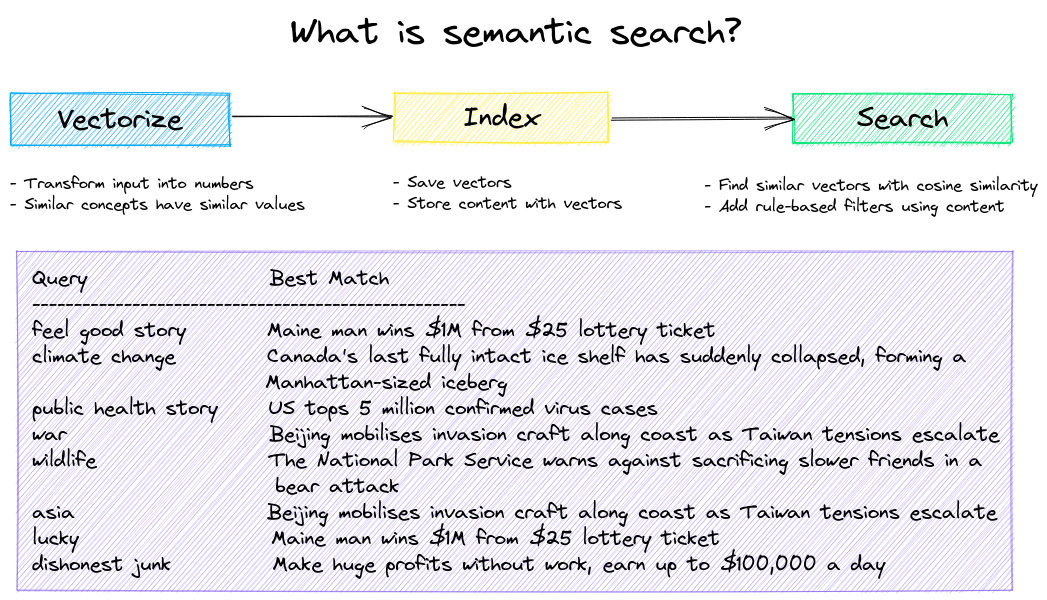
Traditional search systems use keywords to find data. Semantic search has an understanding of natural language and identifies results that have the same meaning, not necessarily the same keywords.
|
||||
Embeddings databases are a union of vector indexes (sparse and dense), graph networks and relational databases. This enables vector search with SQL, topic modeling, retrieval augmented generation and more.
|
||||
|
||||
|
||||
|
||||
|
||||
txtai builds embeddings databases, which are a union of vector indexes and relational databases. This enables vector search with SQL. Embeddings databases can stand on their own and/or serve as a powerful knowledge source for large language model (LLM) prompts.
|
||||
|
||||
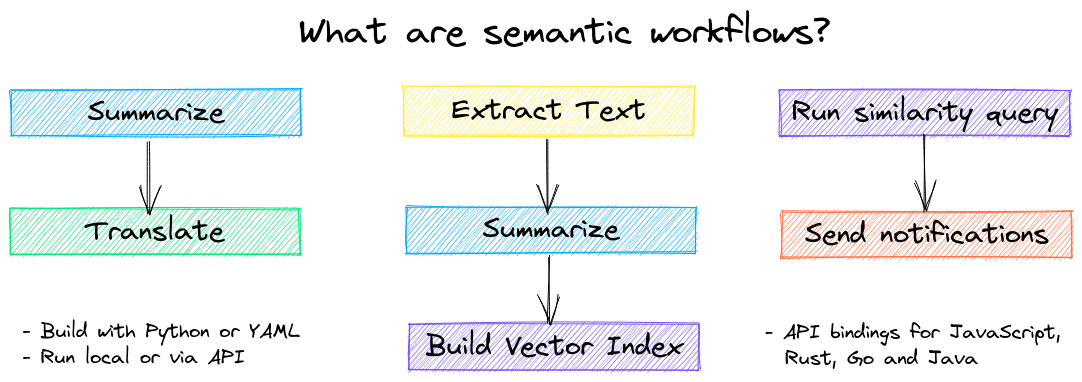
Semantic workflows connect language models together to build intelligent applications.
|
||||
|
||||
|
||||
|
||||
|
||||
Integrate conversational search, retrieval augmented generation (RAG), LLM chains, automatic summarization, transcription, translation and more.
|
||||
Embeddings databases can stand on their own and/or serve as a powerful knowledge source for large language model (LLM) prompts.
|
||||
|
||||
Summary of txtai features:
|
||||
|
||||
- 🔎 Vector search with SQL, object storage, topic modeling, graph analysis, multiple vector index backends ([Faiss](https://github.com/facebookresearch/faiss), [Annoy](https://github.com/spotify/annoy), [Hnswlib](https://github.com/nmslib/hnswlib)) and support for external vector databases
|
||||
- 🔎 Vector search with SQL, object storage, topic modeling, graph analysis and multiple vector index backends (sparse, dense, hybrid, external)
|
||||
- 📄 Create embeddings for text, documents, audio, images and video
|
||||
- 💡 Pipelines powered by language models that run LLM prompts, question-answering, labeling, transcription, translation, summarizations and more
|
||||
- ↪️️ Workflows to join pipelines together and aggregate business logic. txtai processes can be simple microservices or multi-model workflows.
|
||||
@@ -58,19 +49,6 @@ Summary of txtai features:
|
||||
|
||||
txtai is built with Python 3.8+, [Hugging Face Transformers](https://github.com/huggingface/transformers), [Sentence Transformers](https://github.com/UKPLab/sentence-transformers) and [FastAPI](https://github.com/tiangolo/fastapi)
|
||||
|
||||
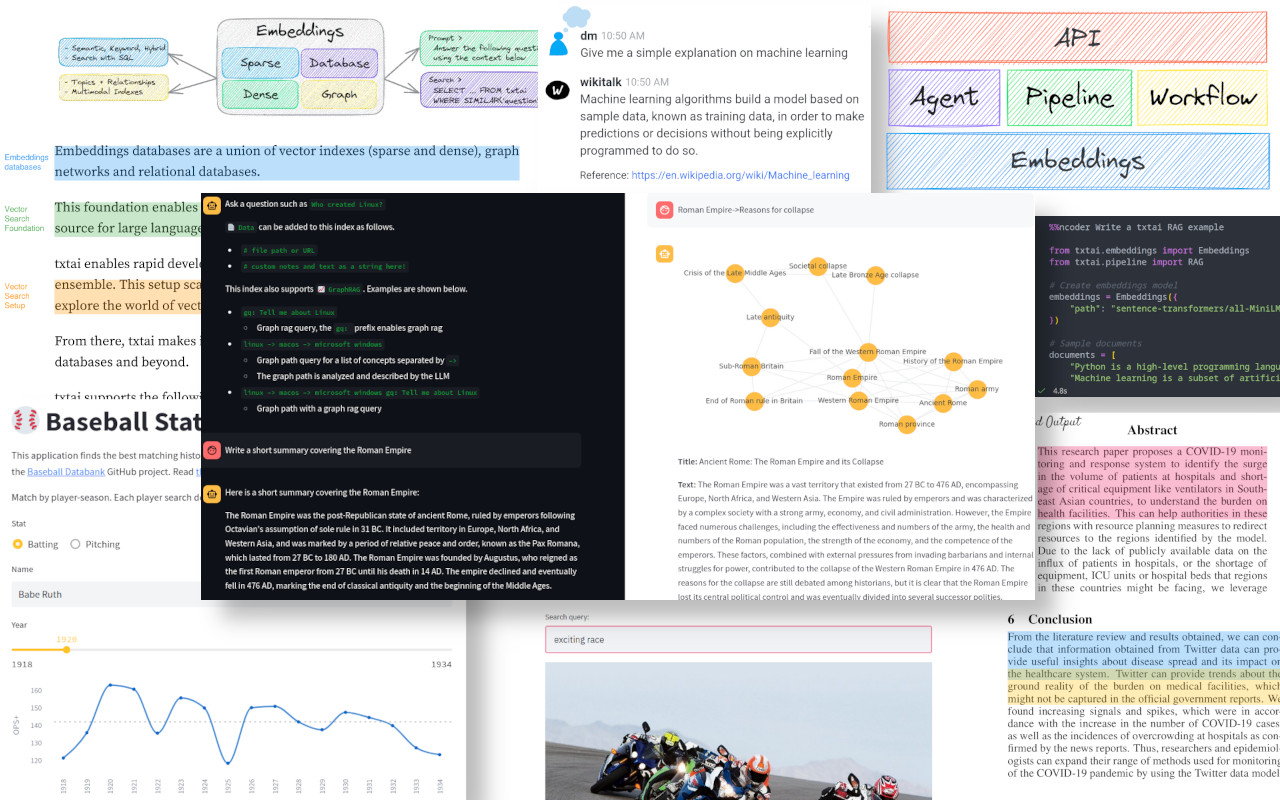
The following applications are powered by txtai.
|
||||
|
||||
|
||||
|
||||
| Application | Description |
|
||||
|:----------|:-------------|
|
||||
| [txtchat](https://github.com/neuml/txtchat) | Conversational search and workflows for all |
|
||||
| [paperai](https://github.com/neuml/paperai) | Semantic search and workflows for medical/scientific papers |
|
||||
| [codequestion](https://github.com/neuml/codequestion) | Semantic search for developers |
|
||||
| [tldrstory](https://github.com/neuml/tldrstory) | Semantic search for headlines and story text |
|
||||
|
||||
In addition to this list, there are also many other [open-source projects](https://github.com/neuml/txtai/network/dependents), [published research](https://scholar.google.com/scholar?q=txtai&hl=en&as_ylo=2022) and closed proprietary/commercial projects that have built on txtai in production.
|
||||
|
||||
## Why txtai?
|
||||
|
||||
|
||||
@@ -81,9 +59,9 @@ New vector databases, LLM frameworks and everything in between are sprouting up
|
||||
- Up and running in minutes with [pip](https://neuml.github.io/txtai/install/) or [Docker](https://neuml.github.io/txtai/cloud/)
|
||||
```python
|
||||
# Get started in a couple lines
|
||||
from txtai.embeddings import Embeddings
|
||||
import txtai
|
||||
|
||||
embeddings = Embeddings()
|
||||
embeddings = txtai.Embeddings()
|
||||
embeddings.index(["Correct", "Not what we hoped"])
|
||||
embeddings.search("positive", 1)
|
||||
#[(0, 0.29862046241760254)]
|
||||
@@ -101,7 +79,64 @@ curl -X GET "http://localhost:8000/search?query=positive"
|
||||
- Run local - no need to ship data off to disparate remote services
|
||||
- Work with micromodels all the way up to large language models (LLMs)
|
||||
- Low footprint - install additional dependencies and scale up when needed
|
||||
- [Learn by example](#examples) - notebooks cover all available functionality
|
||||
- [Learn by example](https://neuml.github.io/txtai/examples) - notebooks cover all available functionality
|
||||
|
||||
## Use Cases
|
||||
|
||||
The following sections give an overview of the main txtai use cases. A comprehensive set of over 50 [example notebooks and applications](https://neuml.github.io/txtai/examples) are also available.
|
||||
|
||||
### Semantic Search
|
||||
|
||||
Build semantic/similarity/vector/neural search applications.
|
||||
|
||||

|
||||
|
||||
Traditional search systems use keywords to find data. Semantic search has an understanding of natural language and identifies results that have the same meaning, not necessarily the same keywords.
|
||||
|
||||

|
||||

|
||||
|
||||
Get started with the following examples.
|
||||
|
||||
| Notebook | Description | |
|
||||
|:----------|:-------------|------:|
|
||||
| [Introducing txtai](https://github.com/neuml/txtai/blob/master/examples/01_Introducing_txtai.ipynb) [▶️](https://www.youtube.com/watch?v=SIezMnVdmMs) | Overview of the functionality provided by txtai | [](https://colab.research.google.com/github/neuml/txtai/blob/master/examples/01_Introducing_txtai.ipynb) |
|
||||
| [Build an Embeddings index with Hugging Face Datasets](https://github.com/neuml/txtai/blob/master/examples/02_Build_an_Embeddings_index_with_Hugging_Face_Datasets.ipynb) | Index and search Hugging Face Datasets | [](https://colab.research.google.com/github/neuml/txtai/blob/master/examples/02_Build_an_Embeddings_index_with_Hugging_Face_Datasets.ipynb) |
|
||||
| [Add semantic search to Elasticsearch](https://github.com/neuml/txtai/blob/master/examples/04_Add_semantic_search_to_Elasticsearch.ipynb) | Add semantic search to existing search systems | [](https://colab.research.google.com/github/neuml/txtai/blob/master/examples/04_Add_semantic_search_to_Elasticsearch.ipynb) |
|
||||
| [Semantic Graphs](https://github.com/neuml/txtai/blob/master/examples/38_Introducing_the_Semantic_Graph.ipynb) | Explore topics, data connectivity and run network analysis| [](https://colab.research.google.com/github/neuml/txtai/blob/master/examples/38_Introducing_the_Semantic_Graph.ipynb) |
|
||||
| [Embeddings in the Cloud](https://github.com/neuml/txtai/blob/master/examples/43_Embeddings_in_the_Cloud.ipynb) | Load and use an embeddings index from the Hugging Face Hub | [](https://colab.research.google.com/github/neuml/txtai/blob/master/examples/43_Embeddings_in_the_Cloud.ipynb) |
|
||||
| [Customize your own embeddings database](https://github.com/neuml/txtai/blob/master/examples/45_Customize_your_own_embeddings_database.ipynb) | Ways to combine vector indexes with relational databases | [](https://colab.research.google.com/github/neuml/txtai/blob/master/examples/45_Customize_your_own_embeddings_database.ipynb) |
|
||||
|
||||
### LLM Orchestration
|
||||
|
||||
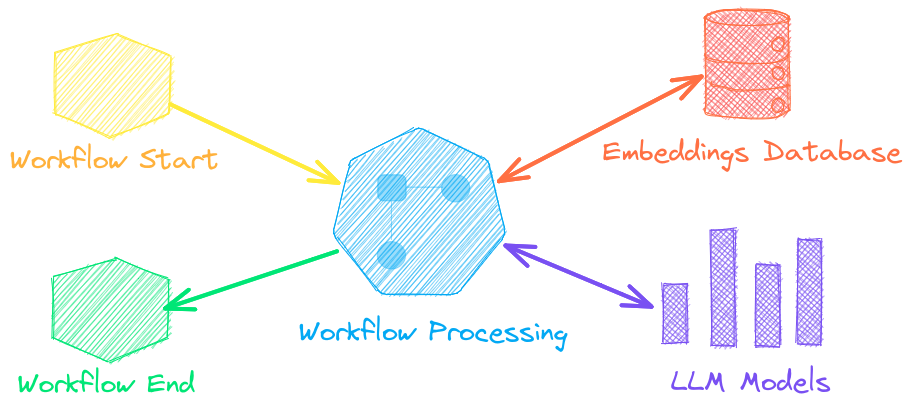
Prompt-driven search, retrieval augmented generation (RAG), pipelines and workflows that interface with large language models (LLMs).
|
||||
|
||||
|
||||
|
||||
Integrate conversational search, LLM chains and self-critique.
|
||||
|
||||
| Notebook | Description | |
|
||||
|:----------|:-------------|------:|
|
||||
| [Prompt-driven search with LLMs](https://github.com/neuml/txtai/blob/master/examples/42_Prompt_driven_search_with_LLMs.ipynb) | Embeddings-guided and Prompt-driven search with Large Language Models (LLMs) | [](https://colab.research.google.com/github/neuml/txtai/blob/master/examples/42_Prompt_driven_search_with_LLMs.ipynb) |
|
||||
| [Prompt templates and task chains](https://github.com/neuml/txtai/blob/master/examples/44_Prompt_templates_and_task_chains.ipynb) | Build model prompts and connect tasks together with workflows | [](https://colab.research.google.com/github/neuml/txtai/blob/master/examples/44_Prompt_templates_and_task_chains.ipynb) |
|
||||
|
||||
### Language Model Workflows
|
||||
|
||||
Language model workflows, also known as semantic workflows, connect language models together to build intelligent applications.
|
||||
|
||||

|
||||

|
||||
|
||||
While LLMs are powerful, there are plenty of smaller, more specialized models that work better and faster for specific tasks. This includes models for extractive question-answering, automatic summarization, text-to-speech, transcription and translation.
|
||||
|
||||
| Notebook | Description | |
|
||||
|:----------|:-------------|------:|
|
||||
| [Run pipeline workflows](https://github.com/neuml/txtai/blob/master/examples/14_Run_pipeline_workflows.ipynb) [▶️](https://www.youtube.com/watch?v=UBMPDCn1gEU) | Simple yet powerful constructs to efficiently process data | [](https://colab.research.google.com/github/neuml/txtai/blob/master/examples/14_Run_pipeline_workflows.ipynb) |
|
||||
| [Extractive QA with txtai](https://github.com/neuml/txtai/blob/master/examples/05_Extractive_QA_with_txtai.ipynb) | Introduction to extractive question-answering with txtai | [](https://colab.research.google.com/github/neuml/txtai/blob/master/examples/05_Extractive_QA_with_txtai.ipynb) |
|
||||
| [Building abstractive text summaries](https://github.com/neuml/txtai/blob/master/examples/09_Building_abstractive_text_summaries.ipynb) | Run abstractive text summarization | [](https://colab.research.google.com/github/neuml/txtai/blob/master/examples/09_Building_abstractive_text_summaries.ipynb) |
|
||||
| [Text to speech generation](https://github.com/neuml/txtai/blob/master/examples/40_Text_to_Speech_Generation.ipynb) | Generate speech from text | [](https://colab.research.google.com/github/neuml/txtai/blob/master/examples/40_Text_to_Speech_Generation.ipynb) |
|
||||
| [Transcribe audio to text](https://github.com/neuml/txtai/blob/master/examples/11_Transcribe_audio_to_text.ipynb) | Convert audio files to text | [](https://colab.research.google.com/github/neuml/txtai/blob/master/examples/11_Transcribe_audio_to_text.ipynb) |
|
||||
| [Translate text between languages](https://github.com/neuml/txtai/blob/master/examples/12_Translate_text_between_languages.ipynb) | Streamline machine translation and language detection | [](https://colab.research.google.com/github/neuml/txtai/blob/master/examples/12_Translate_text_between_languages.ipynb) |
|
||||
|
||||
## Installation
|
||||
|
||||
@@ -116,86 +151,7 @@ pip install txtai
|
||||
|
||||
Python 3.8+ is supported. Using a Python [virtual environment](https://docs.python.org/3/library/venv.html) is recommended.
|
||||
|
||||
See the detailed [install instructions](https://neuml.github.io/txtai/install) for more information covering
|
||||
[optional dependencies](https://neuml.github.io/txtai/install/#optional-dependencies), [environment specific prerequisites](https://neuml.github.io/txtai/install/#environment-specific-prerequisites), [installing from source](https://neuml.github.io/txtai/install/#install-from-source), [conda support](https://neuml.github.io/txtai/install/#conda) and how to [run with containers](https://neuml.github.io/txtai/cloud).
|
||||
|
||||
## Examples
|
||||
|
||||
|
||||
|
||||
|
||||
An abbreviated list of example notebooks and applications giving an overview of txtai are shown below. See the [documentation for the full set of examples](https://neuml.github.io/txtai/examples).
|
||||
|
||||
### Semantic Search
|
||||
|
||||
Build semantic/similarity/vector/neural search applications.
|
||||
|
||||
| Notebook | Description | |
|
||||
|:----------|:-------------|------:|
|
||||
| [Introducing txtai](https://github.com/neuml/txtai/blob/master/examples/01_Introducing_txtai.ipynb) [▶️](https://www.youtube.com/watch?v=SIezMnVdmMs) | Overview of the functionality provided by txtai | [](https://colab.research.google.com/github/neuml/txtai/blob/master/examples/01_Introducing_txtai.ipynb) |
|
||||
| [Build an Embeddings index with Hugging Face Datasets](https://github.com/neuml/txtai/blob/master/examples/02_Build_an_Embeddings_index_with_Hugging_Face_Datasets.ipynb) | Index and search Hugging Face Datasets | [](https://colab.research.google.com/github/neuml/txtai/blob/master/examples/02_Build_an_Embeddings_index_with_Hugging_Face_Datasets.ipynb) |
|
||||
| [Add semantic search to Elasticsearch](https://github.com/neuml/txtai/blob/master/examples/04_Add_semantic_search_to_Elasticsearch.ipynb) | Add semantic search to existing search systems | [](https://colab.research.google.com/github/neuml/txtai/blob/master/examples/04_Add_semantic_search_to_Elasticsearch.ipynb) |
|
||||
| [Semantic Graphs](https://github.com/neuml/txtai/blob/master/examples/38_Introducing_the_Semantic_Graph.ipynb) | Explore topics, data connectivity and run network analysis| [](https://colab.research.google.com/github/neuml/txtai/blob/master/examples/38_Introducing_the_Semantic_Graph.ipynb) |
|
||||
| [Embeddings in the Cloud](https://github.com/neuml/txtai/blob/master/examples/43_Embeddings_in_the_Cloud.ipynb) | Load and use an embeddings index from the Hugging Face Hub | [](https://colab.research.google.com/github/neuml/txtai/blob/master/examples/43_Embeddings_in_the_Cloud.ipynb) |
|
||||
| [Customize your own embeddings database](https://github.com/neuml/txtai/blob/master/examples/45_Customize_your_own_embeddings_database.ipynb) | Ways to combine vector indexes with relational databases | [](https://colab.research.google.com/github/neuml/txtai/blob/master/examples/45_Customize_your_own_embeddings_database.ipynb) |
|
||||
|
||||
### LLM
|
||||
|
||||
Prompt-driven search, retrieval augmented generation (RAG), pipelines and workflows that interface with large language models (LLMs).
|
||||
|
||||
| Notebook | Description | |
|
||||
|:----------|:-------------|------:|
|
||||
| [Prompt-driven search with LLMs](https://github.com/neuml/txtai/blob/master/examples/42_Prompt_driven_search_with_LLMs.ipynb) | Embeddings-guided and Prompt-driven search with Large Language Models (LLMs) | [](https://colab.research.google.com/github/neuml/txtai/blob/master/examples/42_Prompt_driven_search_with_LLMs.ipynb) |
|
||||
| [Prompt templates and task chains](https://github.com/neuml/txtai/blob/master/examples/44_Prompt_templates_and_task_chains.ipynb) | Build model prompts and connect tasks together with workflows | [](https://colab.research.google.com/github/neuml/txtai/blob/master/examples/44_Prompt_templates_and_task_chains.ipynb) |
|
||||
|
||||
### Pipelines
|
||||
|
||||
Transform data with language model backed pipelines.
|
||||
|
||||
| Notebook | Description | |
|
||||
|:----------|:-------------|------:|
|
||||
| [Extractive QA with txtai](https://github.com/neuml/txtai/blob/master/examples/05_Extractive_QA_with_txtai.ipynb) | Introduction to extractive question-answering with txtai | [](https://colab.research.google.com/github/neuml/txtai/blob/master/examples/05_Extractive_QA_with_txtai.ipynb) |
|
||||
| [Apply labels with zero shot classification](https://github.com/neuml/txtai/blob/master/examples/07_Apply_labels_with_zero_shot_classification.ipynb) | Use zero shot learning for labeling, classification and topic modeling | [](https://colab.research.google.com/github/neuml/txtai/blob/master/examples/07_Apply_labels_with_zero_shot_classification.ipynb) |
|
||||
| [Building abstractive text summaries](https://github.com/neuml/txtai/blob/master/examples/09_Building_abstractive_text_summaries.ipynb) | Run abstractive text summarization | [](https://colab.research.google.com/github/neuml/txtai/blob/master/examples/09_Building_abstractive_text_summaries.ipynb) |
|
||||
| [Extract text from documents](https://github.com/neuml/txtai/blob/master/examples/10_Extract_text_from_documents.ipynb) | Extract text from PDF, Office, HTML and more | [](https://colab.research.google.com/github/neuml/txtai/blob/master/examples/10_Extract_text_from_documents.ipynb) |
|
||||
| [Text to speech generation](https://github.com/neuml/txtai/blob/master/examples/40_Text_to_Speech_Generation.ipynb) | Generate speech from text | [](https://colab.research.google.com/github/neuml/txtai/blob/master/examples/40_Text_to_Speech_Generation.ipynb) |
|
||||
| [Transcribe audio to text](https://github.com/neuml/txtai/blob/master/examples/11_Transcribe_audio_to_text.ipynb) | Convert audio files to text | [](https://colab.research.google.com/github/neuml/txtai/blob/master/examples/11_Transcribe_audio_to_text.ipynb) |
|
||||
| [Translate text between languages](https://github.com/neuml/txtai/blob/master/examples/12_Translate_text_between_languages.ipynb) | Streamline machine translation and language detection | [](https://colab.research.google.com/github/neuml/txtai/blob/master/examples/12_Translate_text_between_languages.ipynb) |
|
||||
| [Generate image captions and detect objects](https://github.com/neuml/txtai/blob/master/examples/25_Generate_image_captions_and_detect_objects.ipynb) | Captions and object detection for images | [](https://colab.research.google.com/github/neuml/txtai/blob/master/examples/25_Generate_image_captions_and_detect_objects.ipynb) |
|
||||
|
||||
### Workflows
|
||||
|
||||
Efficiently process data at scale.
|
||||
|
||||
| Notebook | Description | |
|
||||
|:----------|:-------------|------:|
|
||||
| [Run pipeline workflows](https://github.com/neuml/txtai/blob/master/examples/14_Run_pipeline_workflows.ipynb) [▶️](https://www.youtube.com/watch?v=UBMPDCn1gEU) | Simple yet powerful constructs to efficiently process data | [](https://colab.research.google.com/github/neuml/txtai/blob/master/examples/14_Run_pipeline_workflows.ipynb) |
|
||||
| [Workflow Scheduling](https://github.com/neuml/txtai/blob/master/examples/27_Workflow_scheduling.ipynb) | Schedule workflows with cron expressions | [](https://colab.research.google.com/github/neuml/txtai/blob/master/examples/27_Workflow_scheduling.ipynb) |
|
||||
| [Push notifications with workflows](https://github.com/neuml/txtai/blob/master/examples/28_Push_notifications_with_workflows.ipynb) | Generate and push notifications with workflows | [](https://colab.research.google.com/github/neuml/txtai/blob/master/examples/28_Push_notifications_with_workflows.ipynb) |
|
||||
|
||||
### Model Training
|
||||
|
||||
Train NLP models.
|
||||
|
||||
| Notebook | Description | |
|
||||
|:----------|:-------------|------:|
|
||||
| [Train a text labeler](https://github.com/neuml/txtai/blob/master/examples/16_Train_a_text_labeler.ipynb) | Build text sequence classification models | [](https://colab.research.google.com/github/neuml/txtai/blob/master/examples/16_Train_a_text_labeler.ipynb) |
|
||||
| [Train a QA model](https://github.com/neuml/txtai/blob/master/examples/19_Train_a_QA_model.ipynb) | Build and fine-tune question-answering models | [](https://colab.research.google.com/github/neuml/txtai/blob/master/examples/19_Train_a_QA_model.ipynb) |
|
||||
| [Train a language model from scratch](https://github.com/neuml/txtai/blob/master/examples/41_Train_a_language_model_from_scratch.ipynb) | Build new language models | [](https://colab.research.google.com/github/neuml/txtai/blob/master/examples/41_Train_a_language_model_from_scratch.ipynb) |
|
||||
|
||||
### Applications
|
||||
|
||||
Series of example applications with txtai. Links to hosted versions on [Hugging Face Spaces](https://hf.co/spaces) also provided.
|
||||
|
||||
| Application | Description | |
|
||||
|:-------------|:-------------|------:|
|
||||
| [Basic similarity search](https://github.com/neuml/txtai/blob/master/examples/similarity.py) | Basic similarity search example. Data from the original txtai demo. |[🤗](https://hf.co/spaces/NeuML/similarity)|
|
||||
| [Baseball stats](https://github.com/neuml/txtai/blob/master/examples/baseball.py) | Match historical baseball player stats using vector search. |[🤗](https://hf.co/spaces/NeuML/baseball)|
|
||||
| [Book search](https://github.com/neuml/txtai/blob/master/examples/books.py) | Book similarity search application. Index book descriptions and query using natural language statements. |*Local run only*|
|
||||
| [Image search](https://github.com/neuml/txtai/blob/master/examples/images.py) | Image similarity search application. Index a directory of images and run searches to identify images similar to the input query. |[🤗](https://hf.co/spaces/NeuML/imagesearch)|
|
||||
| [Summarize an article](https://github.com/neuml/txtai/blob/master/examples/article.py) | Summarize an article. Workflow that extracts text from a webpage and builds a summary. |[🤗](https://hf.co/spaces/NeuML/articlesummary)|
|
||||
| [Wiki search](https://github.com/neuml/txtai/blob/master/examples/wiki.py) | Wikipedia search application. Queries Wikipedia API and summarizes the top result. |[🤗](https://hf.co/spaces/NeuML/wikisummary)|
|
||||
| [Workflow builder](https://github.com/neuml/txtai/blob/master/examples/workflows.py) | Build and execute txtai workflows. Connect summarization, text extraction, transcription, translation and similarity search pipelines together to run unified workflows. |[🤗](https://hf.co/spaces/NeuML/txtai)|
|
||||
See the detailed [install instructions](https://neuml.github.io/txtai/install) for more information covering [optional dependencies](https://neuml.github.io/txtai/install/#optional-dependencies), [environment specific prerequisites](https://neuml.github.io/txtai/install/#environment-specific-prerequisites), [installing from source](https://neuml.github.io/txtai/install/#install-from-source), [conda support](https://neuml.github.io/txtai/install/#conda) and how to [run with containers](https://neuml.github.io/txtai/cloud).
|
||||
|
||||
## Model guide
|
||||
|
||||
@@ -226,9 +182,20 @@ See the following links to learn more.
|
||||
- [MTSB Leaderboard](https://hf.co/spaces/mteb/leaderboard)
|
||||
- [Open LLM Leaderboard](https://hf.co/spaces/HuggingFaceH4/open_llm_leaderboard)
|
||||
|
||||
## Documentation
|
||||
## Powered by txtai
|
||||
|
||||
[Full documentation on txtai](https://neuml.github.io/txtai) including configuration settings for embeddings, pipelines, workflows, API and a FAQ with common questions/issues is available.
|
||||
The following applications are powered by txtai.
|
||||
|
||||

|
||||
|
||||
| Application | Description |
|
||||
|:----------|:-------------|
|
||||
| [txtchat](https://github.com/neuml/txtchat) | Conversational search and workflows for all |
|
||||
| [paperai](https://github.com/neuml/paperai) | Semantic search and workflows for medical/scientific papers |
|
||||
| [codequestion](https://github.com/neuml/codequestion) | Semantic search for developers |
|
||||
| [tldrstory](https://github.com/neuml/tldrstory) | Semantic search for headlines and story text |
|
||||
|
||||
In addition to this list, there are also many other [open-source projects](https://github.com/neuml/txtai/network/dependents), [published research](https://scholar.google.com/scholar?q=txtai&hl=en&as_ylo=2022) and closed proprietary/commercial projects that have built on txtai in production.
|
||||
|
||||
## Further Reading
|
||||
|
||||
@@ -245,6 +212,10 @@ See the following links to learn more.
|
||||
- [Insights from the txtai console](https://medium.com/neuml/insights-from-the-txtai-console-d307c28e149e)
|
||||
- [The big and small of txtai](https://medium.com/neuml/the-big-and-small-of-txtai-4ca405c1b82)
|
||||
|
||||
## Documentation
|
||||
|
||||
[Full documentation on txtai](https://neuml.github.io/txtai) including configuration settings for embeddings, pipelines, workflows, API and a FAQ with common questions/issues is available.
|
||||
|
||||
## Contributing
|
||||
|
||||
For those who would like to contribute to txtai, please see [this guide](https://github.com/neuml/.github/blob/master/CONTRIBUTING.md).
|
||||
|
||||

Binary file not shown.
|
After Width: | Height: | Size: 420 KiB |
File diff suppressed because it is too large
Load Diff

Binary file not shown.
|
After Width: | Height: | Size: 422 KiB |
File diff suppressed because it is too large
Load Diff

Binary file not shown.
|
After Width: | Height: | Size: 230 KiB |
+9
-31
@@ -4,9 +4,9 @@
|
||||
<img src="https://raw.githubusercontent.com/neuml/txtai/master/logo.png"/>
|
||||
</p>
|
||||
|
||||
<h3 align="center">
|
||||
<p>Semantic search and workflows powered by language models</p>
|
||||
</h3>
|
||||
<p align="center">
|
||||
<b>All-in-one embeddings database</b>
|
||||
</p>
|
||||
|
||||
<p align="center">
|
||||
<a href="https://github.com/neuml/txtai/releases">
|
||||
@@ -31,27 +31,18 @@
|
||||
|
||||
-------------------------------------------------------------------------------------------------------------------------------------------------------
|
||||
|
||||
txtai is an open-source platform for semantic search and workflows powered by language models.
|
||||
txtai is an all-in-one open-source embeddings database for semantic search, LLM orchestration and language model workflows.
|
||||
|
||||

|
||||

|
||||

|
||||
|
||||
Traditional search systems use keywords to find data. Semantic search has an understanding of natural language and identifies results that have the same meaning, not necessarily the same keywords.
|
||||
Embeddings databases are a union of vector indexes (sparse and dense), graph networks and relational databases. This enables vector search with SQL, topic modeling, retrieval augmented generation and more.
|
||||
|
||||

|
||||

|
||||
|
||||
txtai builds embeddings databases, which are a union of vector indexes and relational databases. This enables vector search with SQL. Embeddings databases can stand on their own and/or serve as a powerful knowledge source for large language model (LLM) prompts.
|
||||
|
||||
Semantic workflows connect language models together to build intelligent applications.
|
||||
|
||||

|
||||

|
||||
|
||||
Integrate conversational search, retrieval augmented generation (RAG), LLM chains, automatic summarization, transcription, translation and more.
|
||||
Embeddings databases can stand on their own and/or serve as a powerful knowledge source for large language model (LLM) prompts.
|
||||
|
||||
Summary of txtai features:
|
||||
|
||||
- 🔎 Vector search with SQL, object storage, topic modeling, graph analysis, multiple vector index backends ([Faiss](https://github.com/facebookresearch/faiss), [Annoy](https://github.com/spotify/annoy), [Hnswlib](https://github.com/nmslib/hnswlib)) and support for external vector databases
|
||||
- 🔎 Vector search with SQL, object storage, topic modeling, graph analysis and multiple vector index backends (sparse, dense, hybrid, external)
|
||||
- 📄 Create embeddings for text, documents, audio, images and video
|
||||
- 💡 Pipelines powered by language models that run LLM prompts, question-answering, labeling, transcription, translation, summarizations and more
|
||||
- ↪️️ Workflows to join pipelines together and aggregate business logic. txtai processes can be simple microservices or multi-model workflows.
|
||||
@@ -59,16 +50,3 @@ Summary of txtai features:
|
||||
- ☁️ Cloud-native architecture that scales out with container orchestration systems (e.g. Kubernetes)
|
||||
|
||||
txtai is built with Python 3.8+, [Hugging Face Transformers](https://github.com/huggingface/transformers), [Sentence Transformers](https://github.com/UKPLab/sentence-transformers) and [FastAPI](https://github.com/tiangolo/fastapi)
|
||||
|
||||
The following applications are powered by txtai.
|
||||
|
||||

|
||||
|
||||
| Application | Description |
|
||||
|:----------|:-------------|
|
||||
| [txtchat](https://github.com/neuml/txtchat) | Conversational search and workflows for all |
|
||||
| [paperai](https://github.com/neuml/paperai) | Semantic search and workflows for medical/scientific papers |
|
||||
| [codequestion](https://github.com/neuml/codequestion) | Semantic search for developers |
|
||||
| [tldrstory](https://github.com/neuml/tldrstory) | Semantic search for headlines and story text |
|
||||
|
||||
In addition to this list, there are also many other [open-source projects](https://github.com/neuml/txtai/network/dependents), [published research](https://scholar.google.com/scholar?q=txtai&hl=en&as_ylo=2022) and closed proprietary/commercial projects that have built on txtai in production.
|
||||
|
||||
@@ -0,0 +1,14 @@
|
||||
# Powered by txtai
|
||||
|
||||
The following applications are powered by txtai.
|
||||
|
||||

|
||||
|
||||
| Application | Description |
|
||||
|:----------|:-------------|
|
||||
| [txtchat](https://github.com/neuml/txtchat) | Conversational search and workflows for all |
|
||||
| [paperai](https://github.com/neuml/paperai) | Semantic search and workflows for medical/scientific papers |
|
||||
| [codequestion](https://github.com/neuml/codequestion) | Semantic search for developers |
|
||||
| [tldrstory](https://github.com/neuml/tldrstory) | Semantic search for headlines and story text |
|
||||
|
||||
In addition to this list, there are also many other [open-source projects](https://github.com/neuml/txtai/network/dependents), [published research](https://scholar.google.com/scholar?q=txtai&hl=en&as_ylo=2022) and closed proprietary/commercial projects that have built on txtai in production.
|
||||
@@ -0,0 +1,56 @@
|
||||
# Use Cases
|
||||
|
||||
The following sections give an overview of the main txtai use cases. A comprehensive set of over 50 [example notebooks and applications](../examples) are also available.
|
||||
|
||||
## Semantic Search
|
||||
|
||||
Build semantic/similarity/vector/neural search applications.
|
||||
|
||||

|
||||
|
||||
Traditional search systems use keywords to find data. Semantic search has an understanding of natural language and identifies results that have the same meaning, not necessarily the same keywords.
|
||||
|
||||

|
||||

|
||||
|
||||
Get started with the following examples.
|
||||
|
||||
| Notebook | Description | |
|
||||
|:----------|:-------------|------:|
|
||||
| [Introducing txtai](https://github.com/neuml/txtai/blob/master/examples/01_Introducing_txtai.ipynb) [▶️](https://www.youtube.com/watch?v=SIezMnVdmMs) | Overview of the functionality provided by txtai | [](https://colab.research.google.com/github/neuml/txtai/blob/master/examples/01_Introducing_txtai.ipynb) |
|
||||
| [Build an Embeddings index with Hugging Face Datasets](https://github.com/neuml/txtai/blob/master/examples/02_Build_an_Embeddings_index_with_Hugging_Face_Datasets.ipynb) | Index and search Hugging Face Datasets | [](https://colab.research.google.com/github/neuml/txtai/blob/master/examples/02_Build_an_Embeddings_index_with_Hugging_Face_Datasets.ipynb) |
|
||||
| [Add semantic search to Elasticsearch](https://github.com/neuml/txtai/blob/master/examples/04_Add_semantic_search_to_Elasticsearch.ipynb) | Add semantic search to existing search systems | [](https://colab.research.google.com/github/neuml/txtai/blob/master/examples/04_Add_semantic_search_to_Elasticsearch.ipynb) |
|
||||
| [Semantic Graphs](https://github.com/neuml/txtai/blob/master/examples/38_Introducing_the_Semantic_Graph.ipynb) | Explore topics, data connectivity and run network analysis| [](https://colab.research.google.com/github/neuml/txtai/blob/master/examples/38_Introducing_the_Semantic_Graph.ipynb) |
|
||||
| [Embeddings in the Cloud](https://github.com/neuml/txtai/blob/master/examples/43_Embeddings_in_the_Cloud.ipynb) | Load and use an embeddings index from the Hugging Face Hub | [](https://colab.research.google.com/github/neuml/txtai/blob/master/examples/43_Embeddings_in_the_Cloud.ipynb) |
|
||||
| [Customize your own embeddings database](https://github.com/neuml/txtai/blob/master/examples/45_Customize_your_own_embeddings_database.ipynb) | Ways to combine vector indexes with relational databases | [](https://colab.research.google.com/github/neuml/txtai/blob/master/examples/45_Customize_your_own_embeddings_database.ipynb) |
|
||||
|
||||
## LLM Orchestration
|
||||
|
||||
Prompt-driven search, retrieval augmented generation (RAG), pipelines and workflows that interface with large language models (LLMs).
|
||||
|
||||

|
||||
|
||||
Integrate conversational search, LLM chains and self-critique.
|
||||
|
||||
| Notebook | Description | |
|
||||
|:----------|:-------------|------:|
|
||||
| [Prompt-driven search with LLMs](https://github.com/neuml/txtai/blob/master/examples/42_Prompt_driven_search_with_LLMs.ipynb) | Embeddings-guided and Prompt-driven search with Large Language Models (LLMs) | [](https://colab.research.google.com/github/neuml/txtai/blob/master/examples/42_Prompt_driven_search_with_LLMs.ipynb) |
|
||||
| [Prompt templates and task chains](https://github.com/neuml/txtai/blob/master/examples/44_Prompt_templates_and_task_chains.ipynb) | Build model prompts and connect tasks together with workflows | [](https://colab.research.google.com/github/neuml/txtai/blob/master/examples/44_Prompt_templates_and_task_chains.ipynb) |
|
||||
|
||||
## Language Model Workflows
|
||||
|
||||
Language model workflows, also known as semantic workflows, connect language models together to build intelligent applications.
|
||||
|
||||

|
||||

|
||||
|
||||
While LLMs are powerful, there are plenty of smaller, more specialized models that work better and faster for specific tasks. This includes models for extractive question-answering, automatic summarization, text-to-speech, transcription and translation.
|
||||
|
||||
| Notebook | Description | |
|
||||
|:----------|:-------------|------:|
|
||||
| [Run pipeline workflows](https://github.com/neuml/txtai/blob/master/examples/14_Run_pipeline_workflows.ipynb) [▶️](https://www.youtube.com/watch?v=UBMPDCn1gEU) | Simple yet powerful constructs to efficiently process data | [](https://colab.research.google.com/github/neuml/txtai/blob/master/examples/14_Run_pipeline_workflows.ipynb) |
|
||||
| [Extractive QA with txtai](https://github.com/neuml/txtai/blob/master/examples/05_Extractive_QA_with_txtai.ipynb) | Introduction to extractive question-answering with txtai | [](https://colab.research.google.com/github/neuml/txtai/blob/master/examples/05_Extractive_QA_with_txtai.ipynb) |
|
||||
| [Building abstractive text summaries](https://github.com/neuml/txtai/blob/master/examples/09_Building_abstractive_text_summaries.ipynb) | Run abstractive text summarization | [](https://colab.research.google.com/github/neuml/txtai/blob/master/examples/09_Building_abstractive_text_summaries.ipynb) |
|
||||
| [Text to speech generation](https://github.com/neuml/txtai/blob/master/examples/40_Text_to_Speech_Generation.ipynb) | Generate speech from text | [](https://colab.research.google.com/github/neuml/txtai/blob/master/examples/40_Text_to_Speech_Generation.ipynb) |
|
||||
| [Transcribe audio to text](https://github.com/neuml/txtai/blob/master/examples/11_Transcribe_audio_to_text.ipynb) | Convert audio files to text | [](https://colab.research.google.com/github/neuml/txtai/blob/master/examples/11_Transcribe_audio_to_text.ipynb) |
|
||||
| [Translate text between languages](https://github.com/neuml/txtai/blob/master/examples/12_Translate_text_between_languages.ipynb) | Streamline machine translation and language detection | [](https://colab.research.google.com/github/neuml/txtai/blob/master/examples/12_Translate_text_between_languages.ipynb) |
|
||||
+2
-2
@@ -8,9 +8,9 @@ New vector databases, LLM frameworks and everything in between are sprouting up
|
||||
- Up and running in minutes with [pip](../install/) or [Docker](../cloud/)
|
||||
```python
|
||||
# Get started in a couple lines
|
||||
from txtai.embeddings import Embeddings
|
||||
import txtai
|
||||
|
||||
embeddings = Embeddings()
|
||||
embeddings = txtai.Embeddings()
|
||||
embeddings.index(["Correct", "Not what we hoped"])
|
||||
embeddings.search("positive", 1)
|
||||
#[(0, 0.29862046241760254)]
|
||||
|
||||

Binary file not shown.
|
Before Width: | Height: | Size: 29 KiB After Width: | Height: | Size: 13 KiB |
+3
-1
@@ -52,8 +52,8 @@ markdown_extensions:
|
||||
nav:
|
||||
- Home: index.md
|
||||
- Why txtai?: why.md
|
||||
- Use Cases: usecases.md
|
||||
- Installation: install.md
|
||||
- Examples: examples.md
|
||||
- Model Guide: models.md
|
||||
- Embeddings:
|
||||
- embeddings/index.md
|
||||
@@ -114,5 +114,7 @@ nav:
|
||||
- Configuration: api/configuration.md
|
||||
- Methods: api/methods.md
|
||||
- Cloud: cloud.md
|
||||
- Examples: examples.md
|
||||
- FAQ: faq.md
|
||||
- Powered by txtai: poweredby.md
|
||||
- Further Reading: further.md
|
||||
|
||||
Reference in New Issue
Block a user