mirror of
https://github.com/neuml/txtai.git
synced 2026-10-12 02:19:52 +00:00
Compare commits
| Author | SHA1 | Date | |
|---|---|---|---|
 davidmezzetti |
652a494e4a | ||
|
davidmezzetti
|
b8aef4601c | ||
|
davidmezzetti
|
f97d3384fe | ||
|
davidmezzetti
|
c15090a303 | ||
|
davidmezzetti
|
780a78904e | ||
|
davidmezzetti
|
f7c5c62e4f | ||
|
davidmezzetti
|
d390dcb4c5 | ||
|
davidmezzetti
|
e227cf5929 | ||
|
davidmezzetti
|
8ff136b22b | ||
|
davidmezzetti
|
a0ab014e96 | ||
|
davidmezzetti
|
34f625313c | ||
|
davidmezzetti
|
fc76c92659 | ||
|
davidmezzetti
|
7343d08475 | ||
|
davidmezzetti
|
2ed7c7fec4 | ||
|
davidmezzetti
|
f2512f5316 | ||
|
davidmezzetti
|
30bb6562c0 | ||
|
davidmezzetti
|
db4e6dc340 | ||
|
davidmezzetti
|
1031be0d2f | ||
|
davidmezzetti
|
de6da9daba | ||
|
davidmezzetti
|
3732f917ae | ||
|
davidmezzetti
|
fd03e77751 | ||
|
davidmezzetti
|
d1bcdc591f | ||
|
davidmezzetti
|
0e4966443b | ||
|
davidmezzetti
|
4f4fce8635 | ||
|
davidmezzetti
|
38ad65a251 | ||
|
davidmezzetti
|
d294627ba9 | ||
|
davidmezzetti
|
73415837c4 | ||
|
davidmezzetti
|
68d2477f4f | ||
|
davidmezzetti
|
e11db82dd9 | ||
|
davidmezzetti
|
57b2018f66 | ||
|
davidmezzetti
|
cd39c56ca0 | ||
|
davidmezzetti
|
47dbe81e48 | ||
|
davidmezzetti
|
f1e05a442a | ||
|
davidmezzetti
|
10906e8494 | ||
|
davidmezzetti
|
3458a529af | ||
|
davidmezzetti
|
2583c83afb | ||
|
davidmezzetti
|
246e4449f8 | ||
|
davidmezzetti
|
b90b2f4460 | ||
|
davidmezzetti
|
716d6bcedb | ||
|
davidmezzetti
|
34543a0162 | ||
|
davidmezzetti
|
9b56d2ae20 | ||
|
davidmezzetti
|
089c96bf14 | ||
|
davidmezzetti
|
1e3db617db | ||
|
davidmezzetti
|
6d4417c125 | ||
|
davidmezzetti
|
1f82d54009 | ||
|
davidmezzetti
|
47146228e5 | ||
|
davidmezzetti
|
f0eb46b85d | ||
|
davidmezzetti
|
b23aba8116 | ||
|
davidmezzetti
|
6ff95297b7 | ||
|
davidmezzetti
|
bba76f5704 | ||
|
davidmezzetti
|
2a50557df1 | ||
|
davidmezzetti
|
b3a1599f5d | ||
|
davidmezzetti
|
58f585d694 | ||
|
davidmezzetti
|
5fd6835d03 | ||
|
davidmezzetti
|
40904f92cc | ||
|
davidmezzetti
|
7e83c61176 | ||
|
davidmezzetti
|
b9e84d99f3 | ||
|
davidmezzetti
|
6ac0a8cfea | ||
|
davidmezzetti
|
9faae5dbbd | ||
|
davidmezzetti
|
39a085bb9d | ||
|
davidmezzetti
|
b87fa34f6a | ||
|
davidmezzetti
|
53564bb8bc | ||
|
davidmezzetti
|
a208f77d16 | ||
|
davidmezzetti
|
1658be7ad4 | ||
|
davidmezzetti
|
3b4e9d602b | ||
|
davidmezzetti
|
7cf670627b | ||
|
davidmezzetti
|
9e6bb9269f | ||
|
davidmezzetti
|
2c71f9aa42 | ||
|
davidmezzetti
|
631c01438d | ||
|
davidmezzetti
|
a0bd420890 | ||
|
davidmezzetti
|
368e822b6f | ||
|
davidmezzetti
|
5dbb948c85 | ||
|
davidmezzetti
|
b1a3b97514 | ||
|
davidmezzetti
|
5419381faf | ||
|
davidmezzetti
|
e2215b7fad | ||
|
davidmezzetti
|
502d0e5d0a | ||
|
davidmezzetti
|
bd4f98d21f | ||
|
davidmezzetti
|
ef6ca7d457 | ||
|
davidmezzetti
|
6a9a281cf7 | ||
|
davidmezzetti
|
75ec616e2a | ||
|
davidmezzetti
|
a3ec37a3f2 | ||
|
davidmezzetti
|
52a192526e | ||
|
davidmezzetti
|
de15603ce3 | ||
|
davidmezzetti
|
3e9d03a953 | ||
|
davidmezzetti
|
b2c9bbf7c4 | ||
|
davidmezzetti
|
7e83b99676 | ||
|
davidmezzetti
|
03a20d0755 | ||
|
davidmezzetti
|
e11d73f4ea | ||
|
davidmezzetti
|
983fe9f2c9 | ||
|
davidmezzetti
|
4fd3fc48e7 | ||
|
davidmezzetti
|
5ae223bbd9 | ||
|
davidmezzetti
|
03785a0880 | ||
|
davidmezzetti
|
5ae58e7add | ||
|
davidmezzetti
|
eeb2f7448a | ||
|
davidmezzetti
|
086ab428fd | ||
|
davidmezzetti
|
b42a252538 | ||
|
davidmezzetti
|
9fc2ebe23c | ||
|
davidmezzetti
|
75124014ec | ||
|
davidmezzetti
|
5a0649ffbd | ||
|
davidmezzetti
|
759bb71d28 | ||
|
davidmezzetti
|
b2adcb9d6d | ||
|
davidmezzetti
|
006f834609 | ||
|
davidmezzetti
|
69a7918376 | ||
|
davidmezzetti
|
e5db879127 | ||
|
davidmezzetti
|
17b0d05eb8 | ||
|
davidmezzetti
|
b835d56587 | ||
|
davidmezzetti
|
1d353a28a3 | ||
|
davidmezzetti
|
4907be4346 | ||
|
davidmezzetti
|
1368f655c9 | ||
|
davidmezzetti
|
b71684734c | ||
|
davidmezzetti
|
1f78957aa6 | ||
|
davidmezzetti
|
17963dfb78 | ||
|
davidmezzetti
|
1513eb8390 | ||
|
davidmezzetti
|
44c560e6f4 | ||
|
davidmezzetti
|
5f7bcc3f90 | ||
|
davidmezzetti
|
d5ea573319 | ||
|
davidmezzetti
|
9f6e9ba151 | ||
|
davidmezzetti
|
cc4eff89b4 | ||
|
davidmezzetti
|
34fd08958f | ||
|
davidmezzetti
|
8215b23fab | ||
|
davidmezzetti
|
2fc5b1267f | ||
|
davidmezzetti
|
b7dd0456b0 | ||
|
davidmezzetti
|
b49b0ad02b | ||
|
davidmezzetti
|
80f51b38af | ||
|
davidmezzetti
|
f7227e5c9f | ||
|
davidmezzetti
|
272b998d5e | ||
|
davidmezzetti
|
7a14f444c1 | ||
|
davidmezzetti
|
bb275cc6d9 | ||
|
davidmezzetti
|
d4d51504cc | ||
|
davidmezzetti
|
5fce31c44a | ||
|
davidmezzetti
|
7ff248d6c9 | ||
|
davidmezzetti
|
dce29bffe6 | ||
|
davidmezzetti
|
86ea27194f | ||
|
davidmezzetti
|
960f6b6ae7 | ||
|
davidmezzetti
|
82b9a03ccb | ||
|
davidmezzetti
|
06364a839e | ||
|
davidmezzetti
|
83f625cc32 | ||
|
davidmezzetti
|
4a43da04c2 | ||
|
davidmezzetti
|
b81116b00f | ||
|
davidmezzetti
|
eb981b8cdc | ||
|
davidmezzetti
|
f58e534fb9 | ||
|
davidmezzetti
|
3d9fa98667 | ||
|
davidmezzetti
|
8b7c8f719d | ||
|
davidmezzetti
|
7d752357a5 | ||
|
davidmezzetti
|
9db430fabd | ||
|
davidmezzetti
|
74def21234 | ||
|
davidmezzetti
|
8fbbc8da58 | ||
|
davidmezzetti
|
081e0245c3 | ||
|
davidmezzetti
|
e9f162bd47 | ||
|
davidmezzetti
|
6d7370ad80 | ||
|
davidmezzetti
|
8c3f5deb44 | ||
|
davidmezzetti
|
4e08912507 | ||
|
davidmezzetti
|
918711e6b6 | ||
|
davidmezzetti
|
d5f8ae8310 | ||
|
davidmezzetti
|
935a88947b | ||
|
davidmezzetti
|
975ba144df | ||
|
davidmezzetti
|
8544d2eb36 | ||
|
davidmezzetti
|
d01d30fdfe | ||
|
davidmezzetti
|
e6b2db47c4 | ||
|
davidmezzetti
|
0422b6c19f | ||
|
davidmezzetti
|
f9ee1c414a | ||
|
davidmezzetti
|
4716fcd5d9 | ||
|
davidmezzetti
|
c357e53244 | ||
|
davidmezzetti
|
f1b3350aa5 | ||
|
davidmezzetti
|
debf254680 | ||
|
davidmezzetti
|
69ebf850c4 | ||
|
davidmezzetti
|
c0851b6c05 | ||
|
davidmezzetti
|
bb8a647d28 | ||
|
davidmezzetti
|
53863e693e | ||
|
davidmezzetti
|
54ea19fae2 | ||
|
davidmezzetti
|
c4302d2301 | ||
|
davidmezzetti
|
9a8ce920a7 | ||
|
davidmezzetti
|
64e5eb4a38 | ||
|
davidmezzetti
|
db0f5af0e0 | ||
|
davidmezzetti
|
178c7cdc0a | ||
|
davidmezzetti
|
0c33995ecd | ||
|
davidmezzetti
|
7c045a71c4 | ||
|
davidmezzetti
|
dd3e191e4c | ||
|
davidmezzetti
|
983f45d480 | ||
|
davidmezzetti
|
4f1efd062c | ||
|
davidmezzetti
|
b5f4c3cfe3 | ||
|
davidmezzetti
|
92d038c598 | ||
|
davidmezzetti
|
ac23c79703 | ||
|
davidmezzetti
|
0ccb577574 | ||
|
davidmezzetti
|
4becd9055c | ||
|
davidmezzetti
|
9c91c6ab52 | ||
|
davidmezzetti
|
f00b5c8e15 | ||
|
davidmezzetti
|
097dd861b4 | ||
|
davidmezzetti
|
e3d6b9ddb2 | ||
|
davidmezzetti
|
1e9b3e490d | ||
|
davidmezzetti
|
1d69371a8e | ||
|
davidmezzetti
|
665b6b09d5 | ||
|
davidmezzetti
|
874e13589b | ||
|
davidmezzetti
|
417517f0cd | ||
|
davidmezzetti
|
a91defbd66 | ||
|
davidmezzetti
|
722dddb467 | ||
|
davidmezzetti
|
70a4073db6 | ||
|
davidmezzetti
|
ad3b5be5c4 | ||
|
davidmezzetti
|
b8d339a92b | ||
|
davidmezzetti
|
b6afdfde59 | ||
|
davidmezzetti
|
31114a860c | ||
|
davidmezzetti
|
1de9299ba6 | ||
|
davidmezzetti
|
e574217e61 | ||
|
davidmezzetti
|
30446eab75 | ||
|
davidmezzetti
|
53ce647b18 | ||
|
davidmezzetti
|
ef36934feb | ||
|
davidmezzetti
|
9ccd2e576e | ||
|
davidmezzetti
|
ba79cf68fa | ||
|
davidmezzetti
|
5c16e6f4cc | ||
|
davidmezzetti
|
563ba7f77c | ||
|
davidmezzetti
|
e84d7c003b | ||
|
davidmezzetti
|
78ecb7e831 | ||
|
davidmezzetti
|
f38ee901bb | ||
|
davidmezzetti
|
469a2fa2a9 | ||
|
davidmezzetti
|
6b03186f4e | ||
|
davidmezzetti
|
4d502670a0 | ||
|
davidmezzetti
|
77eb297c81 | ||
|
davidmezzetti
|
caa342176b | ||
|
davidmezzetti
|
ec0bc4467c | ||
|
davidmezzetti
|
3a2bfeb203 | ||
|
davidmezzetti
|
ee644646d7 | ||
|
davidmezzetti
|
8db4f3b53b | ||
|
davidmezzetti
|
c7a688682a | ||
|
davidmezzetti
|
24470d88d4 | ||
|
davidmezzetti
|
5d7ca2a9be | ||
|
davidmezzetti
|
46d95d16c6 | ||
|
davidmezzetti
|
c642a0e4e5 | ||
|
davidmezzetti
|
ae69c27ece | ||
|
davidmezzetti
|
172cd601bc | ||
|
davidmezzetti
|
525578c20d | ||
|
davidmezzetti
|
dc3758536b | ||
|
davidmezzetti
|
b18ed6c36a | ||
|
davidmezzetti
|
79aae2d31f | ||
|
davidmezzetti
|
cfb0975fbe | ||
|
davidmezzetti
|
12d0685e1a | ||
|
davidmezzetti
|
e25de85396 | ||
|
davidmezzetti
|
4d9a231617 | ||
|
davidmezzetti
|
ef8226da8f | ||
|
davidmezzetti
|
8c1214be60 | ||
|
davidmezzetti
|
98c0a98a11 | ||
|
davidmezzetti
|
9e5face23d | ||
|
davidmezzetti
|
ad43ff0f73 | ||
|
davidmezzetti
|
fd1d2b61e2 | ||
|
davidmezzetti
|
3157cf3476 | ||
|
davidmezzetti
|
74f3146137 | ||
|
davidmezzetti
|
d9c6320492 | ||
|
davidmezzetti
|
9d1ced6beb | ||
|
davidmezzetti
|
a47a95dcef | ||
|
davidmezzetti
|
0aee1b0893 | ||
|
davidmezzetti
|
1e449cb9ad | ||
|
davidmezzetti
|
9f2433a967 | ||
|
davidmezzetti
|
689970aa8a | ||
|
davidmezzetti
|
ad6efae447 | ||
|
davidmezzetti
|
d101ea10f7 | ||
|
davidmezzetti
|
0fe9d15d30 | ||
|
davidmezzetti
|
d2f834f253 | ||
|
davidmezzetti
|
6b600d9c1f | ||
|
davidmezzetti
|
0aa1c430aa | ||
|
davidmezzetti
|
40a2481789 | ||
|
davidmezzetti
|
6116080f13 | ||
|
davidmezzetti
|
66e7478e60 | ||
|
davidmezzetti
|
357d709828 | ||
|
davidmezzetti
|
cd10488618 | ||
|
davidmezzetti
|
48cba4a6b6 | ||
|
davidmezzetti
|
223245bae0 | ||
|
davidmezzetti
|
1c95af8d0a | ||
|
davidmezzetti
|
e81155b41a | ||
|
davidmezzetti
|
3a587267ee | ||
|
davidmezzetti
|
2340550488 | ||
|
davidmezzetti
|
110f6d2197 | ||
|
davidmezzetti
|
dd5003f51a | ||
|
davidmezzetti
|
d3f9df828f | ||
|
davidmezzetti
|
f602401442 | ||
|
davidmezzetti
|
0f45aee3d0 | ||
|
davidmezzetti
|
db197cdfea | ||
|
davidmezzetti
|
8929a50a03 | ||
|
davidmezzetti
|
baae46efc2 | ||
|
davidmezzetti
|
5ec442ea11 | ||
|
davidmezzetti
|
51e6886687 | ||
|
davidmezzetti
|
0010f3c7b7 | ||
|
davidmezzetti
|
2fe2a80c61 | ||
|
davidmezzetti
|
8801c87c02 | ||
|
davidmezzetti
|
9e42df4617 | ||
|
davidmezzetti
|
ac52c80ed5 | ||
|
davidmezzetti
|
b6cbe880f6 | ||
|
davidmezzetti
|
9b677d6854 | ||
|
davidmezzetti
|
d1288d0997 | ||
|
davidmezzetti
|
0b10ffef38 | ||
|
davidmezzetti
|
b0763492ab | ||
|
davidmezzetti
|
52f0e2065d | ||
|
davidmezzetti
|
bc6f11bcaa | ||
|
davidmezzetti
|
2337954a15 | ||
|
David Mezzetti
|
626e9ccc3f | ||
|
David Mezzetti
|
84632cc148 | ||
|
csheargm
|
f954f63071 | ||
|
csheargm
|
39ded2f75b | ||
|
davidmezzetti
|
6a08bb12c7 | ||
|
davidmezzetti
|
9f22956d89 | ||
|
davidmezzetti
|
348623b7c9 | ||
|
davidmezzetti
|
0a1e18fbc5 | ||
|
davidmezzetti
|
e906601830 | ||
|
davidmezzetti
|
ad53c56b96 | ||
|
davidmezzetti
|
391ee24e76 | ||
|
davidmezzetti
|
bd354453f1 | ||
|
davidmezzetti
|
816e652268 | ||
|
davidmezzetti
|
c90cb8e457 | ||
|
davidmezzetti
|
e45c4d59f4 | ||
|
davidmezzetti
|
d70f9bc3fc |
@@ -0,0 +1,7 @@
|
||||
[run]
|
||||
source = src/python
|
||||
concurrency = multiprocessing
|
||||
disable_warnings = no-data-collected
|
||||
|
||||
[combine]
|
||||
disable_warnings = no-data-collected
|
||||
@@ -0,0 +1,49 @@
|
||||
# GitHub Actions build workflow
|
||||
name: build
|
||||
|
||||
on: ["push", "pull_request"]
|
||||
|
||||
jobs:
|
||||
build:
|
||||
runs-on: ${{ matrix.os }}
|
||||
strategy:
|
||||
matrix:
|
||||
os: [ubuntu-latest, macos-latest, windows-latest]
|
||||
|
||||
steps:
|
||||
- uses: actions/checkout@v2
|
||||
- uses: actions/setup-python@v2
|
||||
with:
|
||||
python-version: 3.6
|
||||
- uses: actions/setup-java@v1
|
||||
with:
|
||||
java-version: 1.8
|
||||
|
||||
- name: Install dependencies - Linux
|
||||
run: sudo apt-get install libsndfile1
|
||||
if: matrix.os == 'ubuntu-latest'
|
||||
|
||||
- name: Install dependencies - MacOS
|
||||
run: brew install libomp
|
||||
if: matrix.os == 'macos-latest'
|
||||
|
||||
- name: Install dependencies - Windows
|
||||
run: choco install wget
|
||||
if: matrix.os == 'windows-latest'
|
||||
|
||||
- name: Build
|
||||
run: |
|
||||
pip install -U pip wheel coverage coveralls
|
||||
pip install .[all]
|
||||
python -c "import nltk; nltk.download('punkt')"
|
||||
python --version
|
||||
make data coverage
|
||||
|
||||
- uses: pre-commit/[email protected]
|
||||
if: matrix.os == 'ubuntu-latest'
|
||||
|
||||
- name: Test Coverage
|
||||
run: coveralls --service=github
|
||||
if: matrix.os == 'ubuntu-latest'
|
||||
env:
|
||||
GITHUB_TOKEN: ${{ secrets.GITHUB_TOKEN }}
|
||||
@@ -0,0 +1,16 @@
|
||||
name: docs
|
||||
on:
|
||||
push:
|
||||
branches:
|
||||
- master
|
||||
jobs:
|
||||
deploy:
|
||||
runs-on: ubuntu-latest
|
||||
steps:
|
||||
- uses: actions/checkout@v2
|
||||
- uses: actions/setup-python@v2
|
||||
with:
|
||||
python-version: 3.6
|
||||
- run: pip install mkdocs-material mkdocstrings git+https://github.com/neuml/txtai#egg=txtai[all]
|
||||
- run: mkdocs gh-deploy --force
|
||||
|
||||
@@ -0,0 +1,13 @@
|
||||
repos:
|
||||
- repo: https://github.com/pycqa/pylint
|
||||
rev: pylint-2.6.0
|
||||
hooks:
|
||||
- id: pylint
|
||||
args:
|
||||
- -d import-error
|
||||
- -d duplicate-code
|
||||
- repo: https://github.com/ambv/black
|
||||
rev: stable
|
||||
hooks:
|
||||
- id: black
|
||||
language_version: python3
|
||||
@@ -17,4 +17,4 @@ min-public-methods=0
|
||||
max-line-length=150
|
||||
|
||||
[MESSAGES CONTROL]
|
||||
disable=I0011,R0201,W0105,W0108,W0110,W0141,W0621,W0640
|
||||
disable=R0201
|
||||
|
||||
-32
@@ -1,32 +0,0 @@
|
||||
# Travis CI build script - test on all supported platforms
|
||||
os: linux
|
||||
dist: xenial
|
||||
language: python
|
||||
jobs:
|
||||
include:
|
||||
- name: "Linux"
|
||||
script:
|
||||
- make coverage
|
||||
after_success:
|
||||
- coveralls
|
||||
- name: "macOS"
|
||||
os: osx
|
||||
osx_image: xcode11.4
|
||||
language: shell
|
||||
script:
|
||||
- make PYTHON=python3 test
|
||||
- name: "Windows"
|
||||
os: windows
|
||||
language: shell
|
||||
env: PATH=/c/Python36:/c/Python36/Scripts:$PATH
|
||||
before_install:
|
||||
- choco install make
|
||||
- choco install python --version 3.6.8
|
||||
- python -m pip install -U pip wheel
|
||||
- python -m pip install torch==1.6.0+cpu torchvision==0.7.0+cpu -f https://download.pytorch.org/whl/torch_stable.html
|
||||
install:
|
||||
- pip3 install -U pip wheel coverage coveralls
|
||||
- pip3 install .
|
||||
- python3 --version || python --version
|
||||
script:
|
||||
- make test
|
||||
@@ -175,7 +175,7 @@
|
||||
|
||||
END OF TERMS AND CONDITIONS
|
||||
|
||||
Copyright 2020 NeuML LLC
|
||||
Copyright 2020- NeuML LLC
|
||||
|
||||
Licensed under the Apache License, Version 2.0 (the "License");
|
||||
you may not use this file except in compliance with the License.
|
||||
|
||||
@@ -8,13 +8,23 @@ export PYTHONPATH := ${SRC_DIR}:${TEST_DIR}:${PYTHONPATH}
|
||||
export PATH := ${TEST_DIR}:${PATH}
|
||||
export PYTHONWARNINGS := ignore
|
||||
|
||||
# Disable tokenizer parallelism for tests
|
||||
export TOKENIZERS_PARALLELISM := false
|
||||
|
||||
# Default python executable if not provided
|
||||
PYTHON ?= python
|
||||
|
||||
# Download test data
|
||||
data:
|
||||
mkdir -p /tmp/txtai
|
||||
wget -N https://github.com/neuml/txtai/releases/download/v2.0.0/tests.tar.gz -P /tmp
|
||||
tar -xvzf /tmp/tests.tar.gz -C /tmp
|
||||
|
||||
# Unit tests
|
||||
test:
|
||||
${PYTHON} -m unittest discover -v -s ${TEST_DIR}
|
||||
|
||||
# Run tests while calculating code coverage
|
||||
coverage:
|
||||
coverage run --source=${SRC_DIR} -m unittest discover -v -s ${TEST_DIR}
|
||||
coverage run -m unittest discover -v -s ${TEST_DIR}
|
||||
coverage combine
|
||||
|
||||
@@ -1,175 +1,135 @@
|
||||
# txtai: AI-powered search engine
|
||||
<p align="center">
|
||||
<img src="https://raw.githubusercontent.com/neuml/txtai/master/logo.png"/>
|
||||
</p>
|
||||
|
||||
[](https://github.com/neuml/txtai/releases)
|
||||
[](https://github.com/neuml/txtai/releases)
|
||||
[](https://github.com/neuml/txtai/issues)
|
||||
[](https://github.com/neuml/txtai)
|
||||
[](https://travis-ci.org/neuml/txtai)
|
||||
[](https://coveralls.io/github/neuml/txtai?branch=master)
|
||||
<h3 align="center">
|
||||
<p>Build AI-powered semantic search applications</p>
|
||||
</h3>
|
||||
|
||||
txtai builds an AI-powered index over sections of text. txtai supports building text indices to perform similarity searches and create extractive question-answering based systems.
|
||||
<p align="center">
|
||||
<a href="https://github.com/neuml/txtai/releases">
|
||||
<img src="https://img.shields.io/github/release/neuml/txtai.svg?style=flat&color=success" alt="Version"/>
|
||||
</a>
|
||||
<a href="https://github.com/neuml/txtai/releases">
|
||||
<img src="https://img.shields.io/github/release-date/neuml/txtai.svg?style=flat&color=blue" alt="GitHub Release Date"/>
|
||||
</a>
|
||||
<a href="https://github.com/neuml/txtai/issues">
|
||||
<img src="https://img.shields.io/github/issues/neuml/txtai.svg?style=flat&color=success" alt="GitHub issues"/>
|
||||
</a>
|
||||
<a href="https://github.com/neuml/txtai">
|
||||
<img src="https://img.shields.io/github/last-commit/neuml/txtai.svg?style=flat&color=blue" alt="GitHub last commit"/>
|
||||
</a>
|
||||
<a href="https://github.com/neuml/txtai/actions?query=workflow%3Abuild">
|
||||
<img src="https://github.com/neuml/txtai/workflows/build/badge.svg" alt="Build Status"/>
|
||||
</a>
|
||||
<a href="https://coveralls.io/github/neuml/txtai?branch=master">
|
||||
<img src="https://img.shields.io/coveralls/github/neuml/txtai" alt="Coverage Status">
|
||||
</a>
|
||||
</p>
|
||||
|
||||
-------------------------------------------------------------------------------------------------------------------------------------------------------
|
||||
|
||||
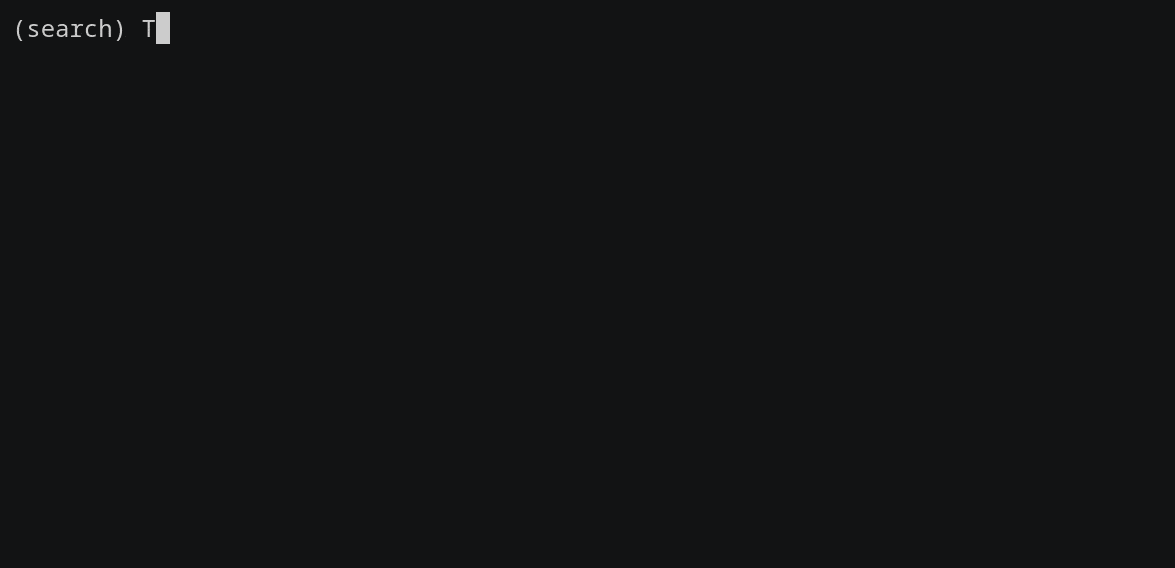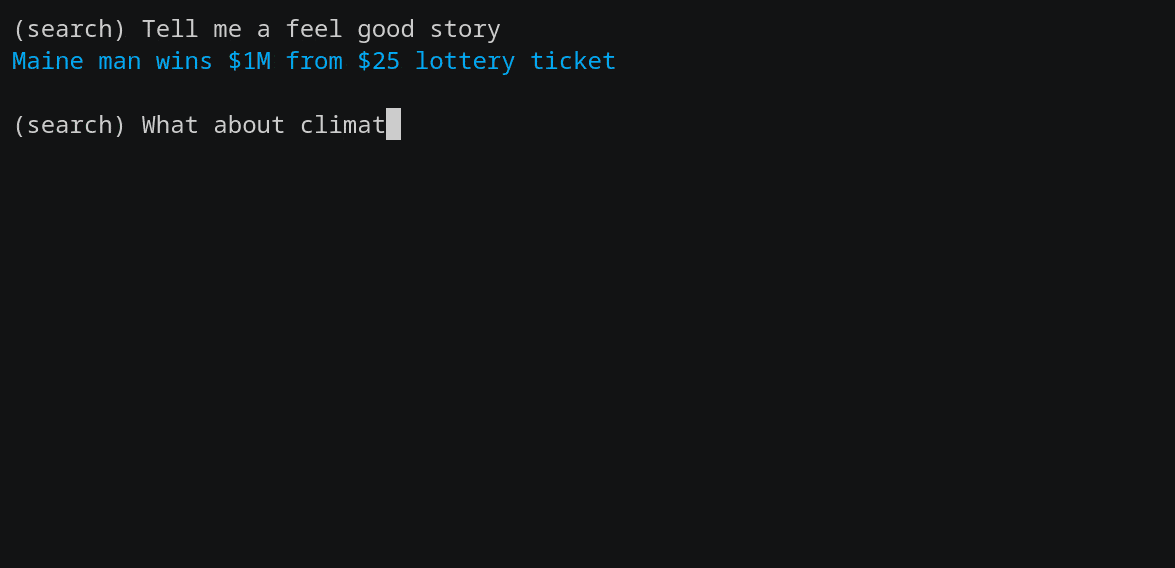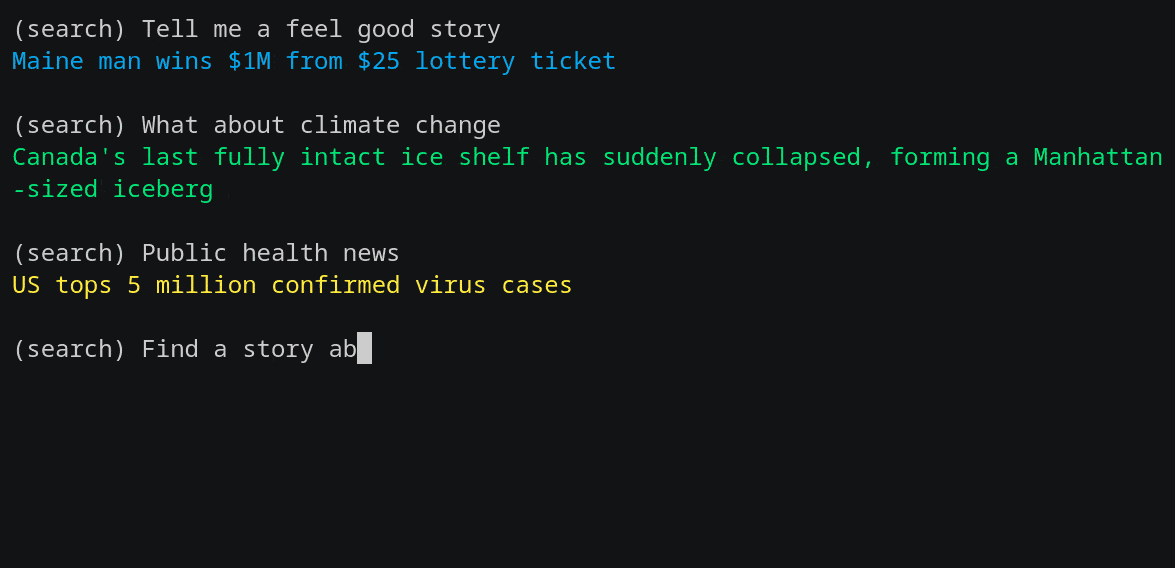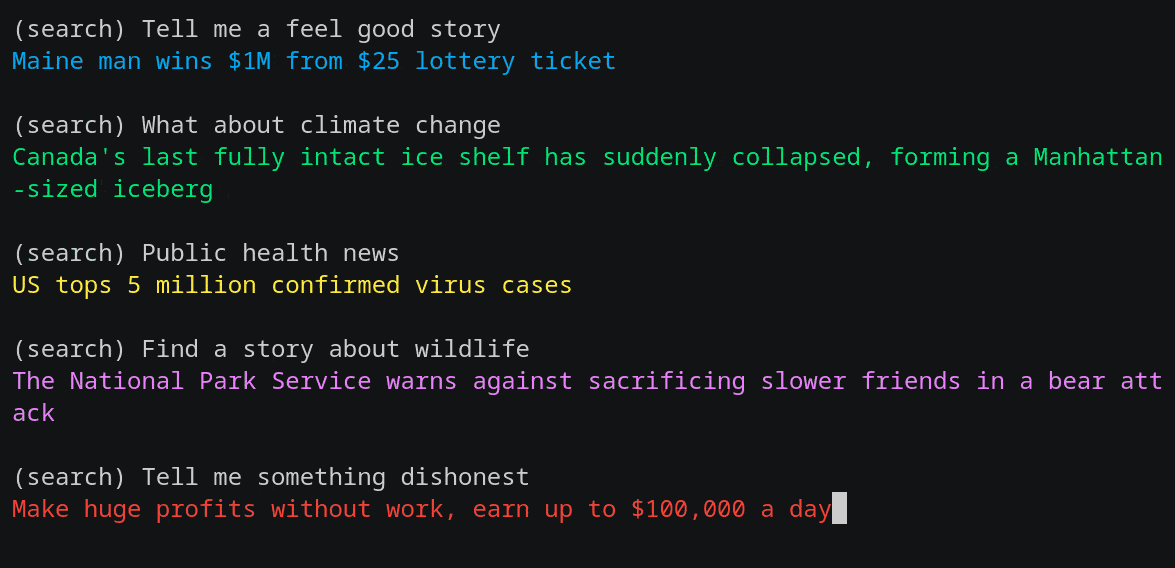
txtai executes machine-learning workflows to transform data and build AI-powered semantic search applications.
|
||||
|
||||
|
||||
|
||||
NeuML uses txtai and/or the concepts behind it to power all of our Natural Language Processing (NLP) applications. Example applications:
|
||||
Traditional search systems use keywords to find data. Semantic search applications have an understanding of natural language and identify results that have the same meaning, not necessarily the same keywords.
|
||||
|
||||
- [cord19q](https://github.com/neuml/cord19q) - COVID-19 literature analysis
|
||||
- [paperai](https://github.com/neuml/paperai) - AI-powered literature discovery and review engine for medical/scientific papers
|
||||
- [neuspo](https://neuspo.com) - a fact-driven, real-time sports event and news site
|
||||
- [codequestion](https://github.com/neuml/codequestion) - Ask coding questions directly from the terminal
|
||||
Backed by state-of-the-art machine learning models, data is transformed into vector representations for search (also known as embeddings). Innovation is happening at a rapid pace, models can understand concepts in documents, audio, images and more.
|
||||
|
||||
txtai is built on the following stack:
|
||||
Summary of txtai features:
|
||||
|
||||
- [sentence-transformers](https://github.com/UKPLab/sentence-transformers)
|
||||
- [transformers](https://github.com/huggingface/transformers)
|
||||
- [faiss](https://github.com/facebookresearch/faiss)
|
||||
- Python 3.6+
|
||||
- 🔎 Large-scale similarity search with multiple index backends ([Faiss](https://github.com/facebookresearch/faiss), [Annoy](https://github.com/spotify/annoy), [Hnswlib](https://github.com/nmslib/hnswlib))
|
||||
- 📄 Create embeddings for text snippets, documents, audio, images and video. Supports transformers and word vectors.
|
||||
- 💡 Machine-learning pipelines to run extractive question-answering, zero-shot labeling, transcription, translation, summarization and text extraction
|
||||
- ↪️️ Workflows that join pipelines together to aggregate business logic. txtai processes can be microservices or full-fledged indexing workflows.
|
||||
- 🔗 API bindings for [JavaScript](https://github.com/neuml/txtai.js), [Java](https://github.com/neuml/txtai.java), [Rust](https://github.com/neuml/txtai.rs) and [Go](https://github.com/neuml/txtai.go)
|
||||
- ☁️ Cloud-native architecture that scales out with container orchestration systems (e.g. Kubernetes)
|
||||
|
||||
Applications range from similarity search to complex NLP-driven data extractions to generate structured databases. The following applications are powered by txtai.
|
||||
|
||||
| Application | Description |
|
||||
|:----------|:-------------|
|
||||
| [paperai](https://github.com/neuml/paperai) | AI-powered literature discovery and review engine for medical/scientific papers |
|
||||
| [tldrstory](https://github.com/neuml/tldrstory) | AI-powered understanding of headlines and story text |
|
||||
| [neuspo](https://neuspo.com) | Fact-driven, real-time sports event and news site |
|
||||
| [codequestion](https://github.com/neuml/codequestion) | Ask coding questions directly from the terminal |
|
||||
|
||||
txtai is built with Python 3.6+, [Hugging Face Transformers](https://github.com/huggingface/transformers), [Sentence Transformers](https://github.com/UKPLab/sentence-transformers) and [FastAPI](https://github.com/tiangolo/fastapi)
|
||||
|
||||
## Installation
|
||||
|
||||
The easiest way to install is via pip and PyPI
|
||||
|
||||
pip install txtai
|
||||
|
||||
You can also install txtai directly from GitHub. Using a Python Virtual Environment is recommended.
|
||||
Python 3.6+ is supported. Using a Python [virtual environment](https://docs.python.org/3/library/venv.html) is recommended.
|
||||
|
||||
pip install git+https://github.com/neuml/txtai
|
||||
|
||||
Python 3.6+ is supported
|
||||
|
||||
### Troubleshooting
|
||||
This project has dependencies that require compiling native code. Windows and macOS systems require the following additional steps. Most Linux environments will install without any additional steps.
|
||||
|
||||
#### Windows
|
||||
|
||||
- Install C++ Build Tools - https://visualstudio.microsoft.com/visual-cpp-build-tools/
|
||||
- PyTorch Windows binaries are not on PyPI, the following url link must be added when installing
|
||||
|
||||
```
|
||||
pip install txtai -f https://download.pytorch.org/whl/torch_stable.html
|
||||
```
|
||||
|
||||
See [pytorch.org](https://pytorch.org) for more information.
|
||||
|
||||
#### macOS
|
||||
|
||||
- Run the following before installing
|
||||
|
||||
```
|
||||
brew install libomp
|
||||
```
|
||||
|
||||
See [this link](https://github.com/kyamagu/faiss-wheels#prerequisite) for more information.
|
||||
See the detailed [install instructions](https://neuml.github.io/txtai/install) for more information covering
|
||||
[installing from source](https://neuml.github.io/txtai/install/#install-from-source),
|
||||
[environment specific prerequisites](https://neuml.github.io/txtai/install/#environment-specific-prerequisites) and
|
||||
[optional dependencies](https://neuml.github.io/txtai/install/#optional-dependencies).
|
||||
|
||||
## Examples
|
||||
|
||||
The examples directory has a series of examples and notebooks giving an overview of txtai. See the list of notebooks below.
|
||||
The examples directory has a series of notebooks and applications giving an overview of txtai. See the sections below.
|
||||
|
||||
### Notebooks
|
||||
### Semantic Search
|
||||
|
||||
| Notebook | Description | |
|
||||
Build semantic/similarity/vector search applications.
|
||||
|
||||
| Notebook | Description | |
|
||||
|:----------|:-------------|------:|
|
||||
| [Introducing txtai](https://github.com/neuml/txtai/blob/master/examples/01_Introducing_txtai.ipynb) | Overview of the functionality provided by txtai |[](https://colab.research.google.com/github/neuml/txtai/blob/master/examples/01_Introducing_txtai.ipynb) |
|
||||
| [Extractive QA with txtai](https://github.com/neuml/txtai/blob/master/examples/02_Extractive_QA_with_txtai.ipynb) | Extractive question-answering with txtai |[](https://colab.research.google.com/github/neuml/txtai/blob/master/examples/02_Extractive_QA_with_txtai.ipynb) |
|
||||
| [Build an Embeddings index from a data source](https://github.com/neuml/txtai/blob/master/examples/03_Build_an_Embeddings_index_from_a_data_source.ipynb) | Embeddings index from a data source backed by word embeddings |[](https://colab.research.google.com/github/neuml/txtai/blob/master/examples/03_Build_an_Embeddings_index_from_a_data_source.ipynb) |
|
||||
| [Extractive QA with Elasticsearch](https://github.com/neuml/txtai/blob/master/examples/04_Extractive_QA_with_Elasticsearch.ipynb) | Extractive question-answering with Elasticsearch |[](https://colab.research.google.com/github/neuml/txtai/blob/master/examples/04_Extractive_QA_with_Elasticsearch.ipynb) |
|
||||
| [Introducing txtai](https://github.com/neuml/txtai/blob/master/examples/01_Introducing_txtai.ipynb) | Overview of the functionality provided by txtai | [](https://colab.research.google.com/github/neuml/txtai/blob/master/examples/01_Introducing_txtai.ipynb) |
|
||||
| [Build an Embeddings index with Hugging Face Datasets](https://github.com/neuml/txtai/blob/master/examples/02_Build_an_Embeddings_index_with_Hugging_Face_Datasets.ipynb) | Index and search Hugging Face Datasets | [](https://colab.research.google.com/github/neuml/txtai/blob/master/examples/02_Build_an_Embeddings_index_with_Hugging_Face_Datasets.ipynb) |
|
||||
| [Build an Embeddings index from a data source](https://github.com/neuml/txtai/blob/master/examples/03_Build_an_Embeddings_index_from_a_data_source.ipynb) | Index and search a data source with word embeddings | [](https://colab.research.google.com/github/neuml/txtai/blob/master/examples/03_Build_an_Embeddings_index_from_a_data_source.ipynb) |
|
||||
| [Add semantic search to Elasticsearch](https://github.com/neuml/txtai/blob/master/examples/04_Add_semantic_search_to_Elasticsearch.ipynb) | Add semantic search to existing search systems | [](https://colab.research.google.com/github/neuml/txtai/blob/master/examples/04_Add_semantic_search_to_Elasticsearch.ipynb) |
|
||||
| [API Gallery](https://github.com/neuml/txtai/blob/master/examples/08_API_Gallery.ipynb) | Using txtai in JavaScript, Java, Rust and Go | [](https://colab.research.google.com/github/neuml/txtai/blob/master/examples/08_API_Gallery.ipynb) |
|
||||
| [Similarity search with images](https://github.com/neuml/txtai/blob/master/examples/13_Similarity_search_with_images.ipynb) | Embed images and text into the same space for search | [](https://colab.research.google.com/github/neuml/txtai/blob/master/examples/13_Similarity_search_with_images.ipynb) |
|
||||
| [Distributed embeddings cluster](https://github.com/neuml/txtai/blob/master/examples/15_Distributed_embeddings_cluster.ipynb) | Distribute an embeddings index across multiple data nodes | [](https://colab.research.google.com/github/neuml/txtai/blob/master/examples/15_Distributed_embeddings_cluster.ipynb) |
|
||||
|
||||
## Configuration
|
||||
### Pipelines and Workflows
|
||||
|
||||
The following section goes over available settings for Embeddings and Extractor instances.
|
||||
NLP-backed data transformation pipelines and workflows.
|
||||
|
||||
### Embeddings
|
||||
| Notebook | Description | |
|
||||
|:----------|:-------------|------:|
|
||||
| [Extractive QA with txtai](https://github.com/neuml/txtai/blob/master/examples/05_Extractive_QA_with_txtai.ipynb) | Introduction to extractive question-answering with txtai | [](https://colab.research.google.com/github/neuml/txtai/blob/master/examples/05_Extractive_QA_with_txtai.ipynb) |
|
||||
| [Extractive QA with Elasticsearch](https://github.com/neuml/txtai/blob/master/examples/06_Extractive_QA_with_Elasticsearch.ipynb) | Run extractive question-answering queries with Elasticsearch | [](https://colab.research.google.com/github/neuml/txtai/blob/master/examples/06_Extractive_QA_with_Elasticsearch.ipynb) |
|
||||
| [Apply labels with zero shot classification](https://github.com/neuml/txtai/blob/master/examples/07_Apply_labels_with_zero_shot_classification.ipynb) | Use zero shot learning for labeling, classification and topic modeling | [](https://colab.research.google.com/github/neuml/txtai/blob/master/examples/07_Apply_labels_with_zero_shot_classification.ipynb) |
|
||||
| [Building abstractive text summaries](https://github.com/neuml/txtai/blob/master/examples/09_Building_abstractive_text_summaries.ipynb) | Run abstractive text summarization | [](https://colab.research.google.com/github/neuml/txtai/blob/master/examples/09_Building_abstractive_text_summaries.ipynb) |
|
||||
| [Extract text from documents](https://github.com/neuml/txtai/blob/master/examples/10_Extract_text_from_documents.ipynb) | Extract text from PDF, Office, HTML and more | [](https://colab.research.google.com/github/neuml/txtai/blob/master/examples/10_Extract_text_from_documents.ipynb) |
|
||||
| [Transcribe audio to text](https://github.com/neuml/txtai/blob/master/examples/11_Transcribe_audio_to_text.ipynb) | Convert audio files to text | [](https://colab.research.google.com/github/neuml/txtai/blob/master/examples/11_Transcribe_audio_to_text.ipynb) |
|
||||
| [Translate text between languages](https://github.com/neuml/txtai/blob/master/examples/12_Translate_text_between_languages.ipynb) | Streamline machine translation and language detection | [](https://colab.research.google.com/github/neuml/txtai/blob/master/examples/12_Translate_text_between_languages.ipynb) |
|
||||
| [Run pipeline workflows](https://github.com/neuml/txtai/blob/master/examples/14_Run_pipeline_workflows.ipynb) | Simple yet powerful constructs to efficiently process data | [](https://colab.research.google.com/github/neuml/txtai/blob/master/examples/14_Run_pipeline_workflows.ipynb) |
|
||||
|
||||
Embeddings methods are set through the constructor. Examples below.
|
||||
### Model Training
|
||||
|
||||
```python
|
||||
# Transformers embeddings model
|
||||
Embeddings({"method": "transformers",
|
||||
"path": "sentence-transformers/bert-base-nli-mean-tokens"})
|
||||
Train NLP models.
|
||||
|
||||
# Word embeddings model
|
||||
Embeddings({"path": vectors,
|
||||
"storevectors": True,
|
||||
"scoring": "bm25",
|
||||
"pca": 3,
|
||||
"quantize": True})
|
||||
```
|
||||
| Notebook | Description | |
|
||||
|:----------|:-------------|------:|
|
||||
| [Train a text labeler](https://github.com/neuml/txtai/blob/master/examples/16_Train_a_text_labeler.ipynb) | Build text sequence classification models | [](https://colab.research.google.com/github/neuml/txtai/blob/master/examples/16_Train_a_text_labeler.ipynb) |
|
||||
| [Train without labels](https://github.com/neuml/txtai/blob/master/examples/17_Train_without_labels.ipynb) | Use zero-shot classifiers to train new models | [](https://colab.research.google.com/github/neuml/txtai/blob/master/examples/17_Train_without_labels.ipynb) |
|
||||
| [Train a QA model](https://github.com/neuml/txtai/blob/master/examples/19_Train_a_QA_model.ipynb) | Build and fine-tune question-answering models | [](https://colab.research.google.com/github/neuml/txtai/blob/master/examples/19_Train_a_QA_model.ipynb) |
|
||||
| [Export and run models with ONNX](https://github.com/neuml/txtai/blob/master/examples/18_Export_and_run_models_with_ONNX.ipynb) | Export models with ONNX, run natively in JavaScript, Java and Rust | [](https://colab.research.google.com/github/neuml/txtai/blob/master/examples/18_Export_and_run_models_with_ONNX.ipynb) |
|
||||
|
||||
#### method
|
||||
```yaml
|
||||
method: transformers|words
|
||||
```
|
||||
### Applications
|
||||
|
||||
Sets the sentence embeddings method to use. When set to _transformers_, the embeddings object builds sentence embeddings using the sentence transformers. Otherwise a word embeddings model is used. Defaults to words.
|
||||
Series of example applications with txtai.
|
||||
|
||||
#### path
|
||||
```yaml
|
||||
path: string
|
||||
```
|
||||
| Application | Description |
|
||||
|:----------|:-------------|
|
||||
| [Demo query shell](https://github.com/neuml/txtai/blob/master/examples/demo.py) | Basic similarity search example. Used in the original txtai demo. |
|
||||
| [Book search](https://github.com/neuml/txtai/blob/master/examples/books.py) | Book similarity search application. Index book descriptions and query using natural language statements. |
|
||||
| [Image search](https://github.com/neuml/txtai/blob/master/examples/images.py) | Image similarity search application. Index a directory of images and run searches to identify images similar to the input query. |
|
||||
| [Wiki search](https://github.com/neuml/txtai/blob/master/examples/wiki.py) | Wikipedia search application. Queries Wikipedia API and summarizes the top result. |
|
||||
| [Workflow builder](https://github.com/neuml/txtai/blob/master/examples/workflows.py) | Build and execute txtai workflows. Connect summarization, text extraction, transcription, translation and similarity search pipelines together to run unified workflows. |
|
||||
|
||||
Required field that sets the path for a vectors model. When method set to _transformers_, this must be a path to a Hugging Face transformers model. Otherwise,
|
||||
it must be a path to a local word embeddings model.
|
||||
### Documentation
|
||||
|
||||
#### storevectors
|
||||
```yaml
|
||||
storevectors: boolean
|
||||
```
|
||||
[Full documentation on txtai](https://neuml.github.io/txtai) including configuration settings for pipelines, workflows, indexing and the API.
|
||||
|
||||
Enables copying of a vectors model set in path into the embeddings models output directory on save. This option enables a fully encapsulated index with no external file dependencies.
|
||||
### Contributing
|
||||
|
||||
#### scoring
|
||||
```yaml
|
||||
scoring: bm25|tfidf|sif
|
||||
```
|
||||
|
||||
For word embedding models, a scoring model allows building weighted averages of word vectors for a given sentence. Supports BM25, tf-idf and SIF (smooth inverse frequency) methods. If a scoring method is not provided, mean sentence embeddings are built.
|
||||
|
||||
#### pca
|
||||
```yaml
|
||||
pca: int
|
||||
```
|
||||
|
||||
Removes _n_ principal components from generated sentence embeddings. When enabled, a TruncatedSVD model is built to help with dimensionality reduction. After pooling of vectors creates a single sentence embedding, this method is applied.
|
||||
|
||||
#### backend
|
||||
```yaml
|
||||
backend: annoy|faiss|hnsw
|
||||
```
|
||||
|
||||
Approximate Nearest Neighbor (ANN) index backend for storing generated sentence embeddings. Defaults to Faiss for Linux/macOS and Annoy for Windows. Faiss currently is not supported on Windows.
|
||||
|
||||
#### quantize
|
||||
```yaml
|
||||
quantize: boolean
|
||||
```
|
||||
|
||||
Enables quanitization of generated sentence embeddings. If the index backend supports it, sentence embeddings will be stored with 8-bit precision vs 32-bit.
|
||||
Only Faiss currently supports quantization.
|
||||
|
||||
### Extractor
|
||||
|
||||
Extractor methods are set as constructor arguments. Examples below.
|
||||
|
||||
```python
|
||||
Extractor(embeddings, path, quantize)
|
||||
```
|
||||
|
||||
#### embeddings
|
||||
```yaml
|
||||
embeddings: Embeddings object instance
|
||||
```
|
||||
|
||||
Embeddings object instance. Used to query and find candidate text snippets to run the question-answer model against.
|
||||
|
||||
#### path
|
||||
```yaml
|
||||
path: string
|
||||
```
|
||||
|
||||
Required path to a Hugging Face SQuAD fine-tuned model. Used to answer questions.
|
||||
|
||||
#### quantize
|
||||
```yaml
|
||||
quantize: boolean
|
||||
```
|
||||
|
||||
Enables dynamic quantization of the Hugging Face model. This is a runtime setting and doesn't save space. It is used to improve the inference time performance of the QA model.
|
||||
For those who would like to contribute to txtai, please see [this guide](https://github.com/neuml/.github/blob/master/CONTRIBUTING.md).
|
||||
|
||||
@@ -0,0 +1,42 @@
|
||||
FROM nvidia/cuda:10.2-base-ubuntu18.04
|
||||
LABEL maintainer="NeuML"
|
||||
LABEL repository="txtai"
|
||||
|
||||
# Locale environment variables
|
||||
ENV LC_ALL=C.UTF-8
|
||||
ENV LANG=C.UTF-8
|
||||
|
||||
# Expose default uvicorn port
|
||||
EXPOSE 8000
|
||||
|
||||
# Install required packages
|
||||
RUN apt-get update && \
|
||||
apt-get -y --no-install-recommends install libgomp1 libsndfile1 gcc g++ python3.6 python3-dev python3-pip && \
|
||||
rm -rf /var/lib/apt/lists
|
||||
|
||||
# Install txtai project and dependencies
|
||||
RUN ln -s /usr/bin/python3.6 /usr/bin/python && \
|
||||
python -m pip install --no-cache-dir -U pip wheel setuptools && \
|
||||
python -m pip install --no-cache-dir txtai[api,pipeline] && \
|
||||
python -c "import nltk; nltk.download('punkt')"
|
||||
|
||||
# Cleanup build packages
|
||||
RUN apt-get -y purge gcc g++ python3-dev && apt-get -y autoremove
|
||||
|
||||
# Generate YAML file
|
||||
RUN echo "path: /txtai" > index.yml && \
|
||||
echo "writable: True" >> index.yml && \
|
||||
echo "embeddings:" >> index.yml && \
|
||||
echo " method: transformers" >> index.yml && \
|
||||
echo " path: sentence-transformers/nli-mpnet-base-v2" >> index.yml && \
|
||||
echo "extractor:" >> index.yml && \
|
||||
echo " path: distilbert-base-cased-distilled-squad" >> index.yml && \
|
||||
echo "labels:" >> index.yml
|
||||
|
||||
# Cache models in Docker image
|
||||
RUN python -c "from transformers import AutoModel; AutoModel.from_pretrained('sentence-transformers/nli-mpnet-base-v2')" && \
|
||||
python -c "from transformers import AutoModel; AutoModel.from_pretrained('distilbert-base-cased-distilled-squad')" && \
|
||||
python -c "from transformers import AutoModel; AutoModel.from_pretrained('facebook/bart-large-mnli')"
|
||||
|
||||
# Start script on all interfaces (localhost + bridged interface)
|
||||
ENTRYPOINT CONFIG=index.yml uvicorn --host 0.0.0.0 "txtai.api:app"
|
||||
+121
@@ -0,0 +1,121 @@
|
||||
# API
|
||||
|
||||
txtai has a full-featured API that can optionally be enabled for any txtai process. All functionality found in txtai can be accessed via the API. The following is an example configuration and startup script for the API.
|
||||
|
||||
Note that this configuration file enables all functionality. It is suggested that separate processes are used for each instance of a txtai component. Components can be joined together with workflows.
|
||||
|
||||
```yaml
|
||||
# Index file path
|
||||
path: /tmp/index
|
||||
|
||||
# Allow indexing of documents
|
||||
writable: True
|
||||
|
||||
# Enbeddings index
|
||||
embeddings:
|
||||
path: sentence-transformers/nli-mpnet-base-v2
|
||||
|
||||
# Extractive QA
|
||||
extractor:
|
||||
path: distilbert-base-cased-distilled-squad
|
||||
|
||||
# Zero-shot labeling
|
||||
labels:
|
||||
|
||||
# Similarity
|
||||
similarity:
|
||||
|
||||
# Text segmentation
|
||||
segmentation:
|
||||
sentences: true
|
||||
|
||||
# Text summarization
|
||||
summary:
|
||||
|
||||
# Text extraction
|
||||
textractor:
|
||||
paragraphs: true
|
||||
minlength: 100
|
||||
join: true
|
||||
|
||||
# Transcribe audio to text
|
||||
transcription:
|
||||
|
||||
# Translate text between languages
|
||||
translation:
|
||||
|
||||
# Workflow definitions
|
||||
workflow:
|
||||
sumfrench:
|
||||
tasks:
|
||||
- action: textractor
|
||||
task: storage
|
||||
ids: false
|
||||
- action: summary
|
||||
- action: translation
|
||||
args: ["fr"]
|
||||
sumspanish:
|
||||
tasks:
|
||||
- action: textractor
|
||||
task: url
|
||||
- action: summary
|
||||
- action: translation
|
||||
args: ["es"]
|
||||
```
|
||||
|
||||
Assuming this YAML content is stored in a file named index.yml, the following command starts the API process.
|
||||
|
||||
```
|
||||
CONFIG=index.yml uvicorn "txtai.api:app"
|
||||
```
|
||||
|
||||
uvicorn is a full-featured production ready server with support for SSL and more. See the [uvicorn deployment guide](https://www.uvicorn.org/deployment/) for details.
|
||||
|
||||
## Docker
|
||||
|
||||
A Dockerfile with commands to install txtai, all dependencies and default configuration is available in this repository.
|
||||
|
||||
The Dockerfile can be copied from the docker directory on GitHub locally. The following commands show how to run the API process.
|
||||
|
||||
```bash
|
||||
docker build -t txtai.api -f docker/api.Dockerfile .
|
||||
docker run --name txtai.api -p 8000:8000 --rm -it txtai.api
|
||||
|
||||
# Alternatively, if nvidia-docker is installed, the build will support GPU runtimes
|
||||
docker run --name txtai.api --runtime=nvidia -p 8000:8000 --rm -it txtai.api
|
||||
```
|
||||
|
||||
This will bring up an API instance without having to install Python, txtai or any dependencies on your machine!
|
||||
|
||||
## Distributed embeddings clusters
|
||||
|
||||
The API supports combining multiple API instances into a single logical embeddings index. An example configuration is shown below.
|
||||
|
||||
```yaml
|
||||
cluster:
|
||||
shards:
|
||||
- http://127.0.0.1:8002
|
||||
- http://127.0.0.1:8003
|
||||
```
|
||||
|
||||
This configuration aggregates the API instances above as index shards. Data is evenly split among each of the shards at index time. Queries are run in parallel against each shard and the results are joined together. This method allows horizontal scaling and supports very large index clusters.
|
||||
|
||||
This method is only recommended for data sets in the 1 billion+ records. The ANN libraries can easily support smaller data sizes and this method is not worth the additional complexity. At this time, new shards can not be added after building the initial index.
|
||||
|
||||
## Differences between Python and API
|
||||
|
||||
The txtai API provides all the major functionality found in this project. But there are differences due to the nature of JSON and differences across the supported programming languages. For example, any Python callable method is available at a named endpoint (i.e. instead of summary() the method call would be summary.summary()).
|
||||
Return types vary as tuples are returned as objects via the API.
|
||||
|
||||
## Supported language bindings
|
||||
|
||||
The following programming languages have txtai bindings:
|
||||
|
||||
- [JavaScript](https://github.com/neuml/txtai.js)
|
||||
- [Java](https://github.com/neuml/txtai.java)
|
||||
- [Rust](https://github.com/neuml/txtai.rs)
|
||||
- [Go](https://github.com/neuml/txtai.go)
|
||||
|
||||
See each of the projects above for details on how to install and use. Please add an issue to request additional language bindings!
|
||||
|
||||
::: txtai.api.application
|
||||
@@ -0,0 +1,148 @@
|
||||
# Embeddings
|
||||
An Embeddings instance is the engine that provides similarity search. Embeddings can be used to run ad-hoc similarity comparisions or build/search large indices.
|
||||
|
||||
Embeddings parameters are set through the constructor. Examples below.
|
||||
|
||||
```python
|
||||
# Transformers embeddings model
|
||||
Embeddings({"method": "transformers",
|
||||
"path": "sentence-transformers/nli-mpnet-base-v2"})
|
||||
|
||||
# Word embeddings model
|
||||
Embeddings({"method": "words",
|
||||
"path": vectors,
|
||||
"storevectors": True,
|
||||
"scoring": "bm25",
|
||||
"pca": 3,
|
||||
"quantize": True})
|
||||
```
|
||||
|
||||
## Configuration
|
||||
|
||||
### method
|
||||
```yaml
|
||||
method: transformers|sentence-transformers|words
|
||||
```
|
||||
|
||||
Sentence embeddings method to use. Options listed below.
|
||||
|
||||
#### transformers
|
||||
|
||||
Builds sentence embeddings using a transformers model. While this can be any transformers model, it works best with
|
||||
[models trained](https://huggingface.co/models?search=sentence-transformers) to build sentence embeddings.
|
||||
|
||||
#### sentence-transformers
|
||||
|
||||
Same as transformers but loads models with the sentence-transformers library.
|
||||
|
||||
#### words
|
||||
|
||||
Builds sentence embeddings using a word embeddings model.
|
||||
|
||||
sentence-transformers and words require the [similarity](https://neuml.github.io/txtai/install/#similarity) extras package to be installed.
|
||||
|
||||
The method is inferred using the _path_ if not provided.
|
||||
|
||||
### path
|
||||
```yaml
|
||||
path: string
|
||||
```
|
||||
|
||||
Required field that sets the path for a vectors model. When using a transformers/sentence-transformers model, this can be any model on the
|
||||
[Hugging Face Model Hub](https://huggingface.co/models) or a local file path. Otherwise, it must be a local file path to a word embeddings model.
|
||||
|
||||
### backend
|
||||
```yaml
|
||||
backend: faiss|annoy|hnsw
|
||||
```
|
||||
|
||||
Approximate Nearest Neighbor (ANN) index backend for storing generated sentence embeddings. Defaults to Faiss. Additional backends require the
|
||||
[similarity](https://neuml.github.io/txtai/install/#similarity) extras package to be installed.
|
||||
|
||||
Backend-specific settings are set with a corresponding configuration object having the same name as the backend (i.e. annoy, faiss, or hnsw). None of these are required and are set to defaults if omitted.
|
||||
|
||||
### faiss
|
||||
```yaml
|
||||
faiss:
|
||||
components: Comma separated list of components - defaults to None
|
||||
nprobe: search probe setting (int) - defaults to 6
|
||||
```
|
||||
|
||||
See Faiss documentation on the [index factory](https://github.com/facebookresearch/faiss/wiki/The-index-factory) and [search](https://github.com/facebookresearch/faiss/wiki/Faster-search) for more information on these parameters.
|
||||
|
||||
### annoy
|
||||
```yaml
|
||||
annoy:
|
||||
ntrees: number of trees (int) - defaults to 10
|
||||
searchk: search_k search setting (int) - defaults to -1
|
||||
```
|
||||
|
||||
See [Annoy documentation](https://github.com/spotify/annoy#full-python-api) for more information on these parameters.
|
||||
|
||||
### hnsw
|
||||
```yaml
|
||||
hnsw:
|
||||
efconstruction: ef_construction param for init_index (int) - defaults to 200
|
||||
m: M param for init_index (int) - defaults to 16
|
||||
randomseed: random-seed param for init_index (init) - defaults to 100
|
||||
efsearch: ef search param (int) - defaults to None and not set
|
||||
```
|
||||
|
||||
See [Hnswlib documentation](https://github.com/nmslib/hnswlib/blob/master/ALGO_PARAMS.md) for more information on these parameters.
|
||||
|
||||
### quantize
|
||||
```yaml
|
||||
quantize: boolean
|
||||
```
|
||||
|
||||
Enables quanitization of generated sentence embeddings. If the index backend supports it, sentence embeddings will be stored with 8-bit precision vs 32-bit.
|
||||
Only Faiss currently supports quantization.
|
||||
|
||||
## Additional configuration for Transformers models
|
||||
|
||||
### tokenize
|
||||
```yaml
|
||||
tokenize: boolean
|
||||
```
|
||||
|
||||
Enables string tokenization (defaults to false). This method applies tokenization rules that only work with English language text and may increase the quality of
|
||||
English language sentence embeddings in some situations.
|
||||
|
||||
## Additional configuration for Word embedding models
|
||||
|
||||
Word embeddings provide a good tradeoff of performance to functionality for a similarity search system. With that being said, Transformers models are making great progress in scaling performance down to smaller models and are the preferred vector backend in txtai for most cases.
|
||||
|
||||
Word embeddings models require the [similarity](https://neuml.github.io/txtai/install/#similarity) extras package to be installed.
|
||||
|
||||
### storevectors
|
||||
```yaml
|
||||
storevectors: boolean
|
||||
```
|
||||
|
||||
Enables copying of a vectors model set in path into the embeddings models output directory on save. This option enables a fully encapsulated index with no external file dependencies.
|
||||
|
||||
### scoring
|
||||
```yaml
|
||||
scoring: bm25|tfidf|sif
|
||||
```
|
||||
|
||||
A scoring model builds weighted averages of word vectors for a given sentence. Supports BM25, TF-IDF and SIF (smooth inverse frequency) methods. If a scoring method is not provided, mean sentence embeddings are built.
|
||||
|
||||
### pca
|
||||
```yaml
|
||||
pca: int
|
||||
```
|
||||
|
||||
Removes _n_ principal components from generated sentence embeddings. When enabled, a TruncatedSVD model is built to help with dimensionality reduction. After pooling of vectors creates a single sentence embedding, this method is applied.
|
||||
|
||||
::: txtai.embeddings.Embeddings.__init__
|
||||
::: txtai.embeddings.Embeddings.batchsearch
|
||||
::: txtai.embeddings.Embeddings.batchsimilarity
|
||||
::: txtai.embeddings.Embeddings.batchtransform
|
||||
::: txtai.embeddings.Embeddings.index
|
||||
::: txtai.embeddings.Embeddings.load
|
||||
::: txtai.embeddings.Embeddings.save
|
||||
::: txtai.embeddings.Embeddings.score
|
||||
::: txtai.embeddings.Embeddings.search
|
||||
::: txtai.embeddings.Embeddings.similarity
|
||||
::: txtai.embeddings.Embeddings.transform
|
||||
@@ -0,0 +1,55 @@
|
||||
# Examples
|
||||
|
||||
The examples directory has a series of notebooks and applications giving an overview of txtai. See the sections below.
|
||||
|
||||
## Semantic Search
|
||||
|
||||
Build semantic/similarity/vector search applications.
|
||||
|
||||
| Notebook | Description | |
|
||||
|:----------|:-------------|------:|
|
||||
| [Introducing txtai](https://github.com/neuml/txtai/blob/master/examples/01_Introducing_txtai.ipynb) | Overview of the functionality provided by txtai | [](https://colab.research.google.com/github/neuml/txtai/blob/master/examples/01_Introducing_txtai.ipynb) |
|
||||
| [Build an Embeddings index with Hugging Face Datasets](https://github.com/neuml/txtai/blob/master/examples/02_Build_an_Embeddings_index_with_Hugging_Face_Datasets.ipynb) | Index and search Hugging Face Datasets | [](https://colab.research.google.com/github/neuml/txtai/blob/master/examples/02_Build_an_Embeddings_index_with_Hugging_Face_Datasets.ipynb) |
|
||||
| [Build an Embeddings index from a data source](https://github.com/neuml/txtai/blob/master/examples/03_Build_an_Embeddings_index_from_a_data_source.ipynb) | Index and search a data source with word embeddings | [](https://colab.research.google.com/github/neuml/txtai/blob/master/examples/03_Build_an_Embeddings_index_from_a_data_source.ipynb) |
|
||||
| [Add semantic search to Elasticsearch](https://github.com/neuml/txtai/blob/master/examples/04_Add_semantic_search_to_Elasticsearch.ipynb) | Add semantic search to existing search systems | [](https://colab.research.google.com/github/neuml/txtai/blob/master/examples/04_Add_semantic_search_to_Elasticsearch.ipynb) |
|
||||
| [API Gallery](https://github.com/neuml/txtai/blob/master/examples/08_API_Gallery.ipynb) | Using txtai in JavaScript, Java, Rust and Go | [](https://colab.research.google.com/github/neuml/txtai/blob/master/examples/08_API_Gallery.ipynb) |
|
||||
| [Similarity search with images](https://github.com/neuml/txtai/blob/master/examples/13_Similarity_search_with_images.ipynb) | Embed images and text into the same space for search | [](https://colab.research.google.com/github/neuml/txtai/blob/master/examples/13_Similarity_search_with_images.ipynb) |
|
||||
| [Distributed embeddings cluster](https://github.com/neuml/txtai/blob/master/examples/15_Distributed_embeddings_cluster.ipynb) | Distribute an embeddings index across multiple data nodes | [](https://colab.research.google.com/github/neuml/txtai/blob/master/examples/15_Distributed_embeddings_cluster.ipynb) |
|
||||
|
||||
## Pipelines and Workflows
|
||||
|
||||
NLP-backed data transformation pipelines and workflows.
|
||||
|
||||
| Notebook | Description | |
|
||||
|:----------|:-------------|------:|
|
||||
| [Extractive QA with txtai](https://github.com/neuml/txtai/blob/master/examples/05_Extractive_QA_with_txtai.ipynb) | Introduction to extractive question-answering with txtai | [](https://colab.research.google.com/github/neuml/txtai/blob/master/examples/05_Extractive_QA_with_txtai.ipynb) |
|
||||
| [Extractive QA with Elasticsearch](https://github.com/neuml/txtai/blob/master/examples/06_Extractive_QA_with_Elasticsearch.ipynb) | Run extractive question-answering queries with Elasticsearch | [](https://colab.research.google.com/github/neuml/txtai/blob/master/examples/06_Extractive_QA_with_Elasticsearch.ipynb) |
|
||||
| [Apply labels with zero shot classification](https://github.com/neuml/txtai/blob/master/examples/07_Apply_labels_with_zero_shot_classification.ipynb) | Use zero shot learning for labeling, classification and topic modeling | [](https://colab.research.google.com/github/neuml/txtai/blob/master/examples/07_Apply_labels_with_zero_shot_classification.ipynb) |
|
||||
| [Building abstractive text summaries](https://github.com/neuml/txtai/blob/master/examples/09_Building_abstractive_text_summaries.ipynb) | Run abstractive text summarization | [](https://colab.research.google.com/github/neuml/txtai/blob/master/examples/09_Building_abstractive_text_summaries.ipynb) |
|
||||
| [Extract text from documents](https://github.com/neuml/txtai/blob/master/examples/10_Extract_text_from_documents.ipynb) | Extract text from PDF, Office, HTML and more | [](https://colab.research.google.com/github/neuml/txtai/blob/master/examples/10_Extract_text_from_documents.ipynb) |
|
||||
| [Transcribe audio to text](https://github.com/neuml/txtai/blob/master/examples/11_Transcribe_audio_to_text.ipynb) | Convert audio files to text | [](https://colab.research.google.com/github/neuml/txtai/blob/master/examples/11_Transcribe_audio_to_text.ipynb) |
|
||||
| [Translate text between languages](https://github.com/neuml/txtai/blob/master/examples/12_Translate_text_between_languages.ipynb) | Streamline machine translation and language detection | [](https://colab.research.google.com/github/neuml/txtai/blob/master/examples/12_Translate_text_between_languages.ipynb) |
|
||||
| [Run pipeline workflows](https://github.com/neuml/txtai/blob/master/examples/14_Run_pipeline_workflows.ipynb) | Simple yet powerful constructs to efficiently process data | [](https://colab.research.google.com/github/neuml/txtai/blob/master/examples/14_Run_pipeline_workflows.ipynb) |
|
||||
|
||||
## Model Training
|
||||
|
||||
Train NLP models.
|
||||
|
||||
| Notebook | Description | |
|
||||
|:----------|:-------------|------:|
|
||||
| [Train a text labeler](https://github.com/neuml/txtai/blob/master/examples/16_Train_a_text_labeler.ipynb) | Build text sequence classification models | [](https://colab.research.google.com/github/neuml/txtai/blob/master/examples/16_Train_a_text_labeler.ipynb) |
|
||||
| [Train without labels](https://github.com/neuml/txtai/blob/master/examples/17_Train_without_labels.ipynb) | Use zero-shot classifiers to train new models | [](https://colab.research.google.com/github/neuml/txtai/blob/master/examples/17_Train_without_labels.ipynb) |
|
||||
| [Train a QA model](https://github.com/neuml/txtai/blob/master/examples/19_Train_a_QA_model.ipynb) | Build and fine-tune question-answering models | [](https://colab.research.google.com/github/neuml/txtai/blob/master/examples/19_Train_a_QA_model.ipynb) |
|
||||
| [Export and run models with ONNX](https://github.com/neuml/txtai/blob/master/examples/18_Export_and_run_models_with_ONNX.ipynb) | Export models with ONNX, run natively in JavaScript, Java and Rust | [](https://colab.research.google.com/github/neuml/txtai/blob/master/examples/18_Export_and_run_models_with_ONNX.ipynb) |
|
||||
|
||||
## Applications
|
||||
|
||||
Series of example applications with txtai.
|
||||
|
||||
| Application | Description |
|
||||
|:----------|:-------------|
|
||||
| [Demo query shell](https://github.com/neuml/txtai/blob/master/examples/demo.py) | Basic similarity search example. Used in the original txtai demo. |
|
||||
| [Book search](https://github.com/neuml/txtai/blob/master/examples/books.py) | Book similarity search application. Index book descriptions and query using natural language statements. |
|
||||
| [Image search](https://github.com/neuml/txtai/blob/master/examples/images.py) | Image similarity search application. Index a directory of images and run searches to identify images similar to the input query. |
|
||||
| [Wiki search](https://github.com/neuml/txtai/blob/master/examples/wiki.py) | Wikipedia search application. Queries Wikipedia API and summarizes the top result. |
|
||||
| [Workflow builder](https://github.com/neuml/txtai/blob/master/examples/workflows.py) | Build and execute txtai workflows. Connect summarization, text extraction, transcription, translation and similarity search pipelines together to run unified workflows. |
|
||||

Binary file not shown.
|
After Width: | Height: | Size: 12 KiB |
@@ -0,0 +1,60 @@
|
||||
#
|
||||
|
||||
<p align="center">
|
||||
<img src="https://raw.githubusercontent.com/neuml/txtai/master/logo.png"/>
|
||||
</p>
|
||||
|
||||
<h3 align="center">
|
||||
<p>Build AI-powered semantic search applications</p>
|
||||
</h3>
|
||||
|
||||
<p align="center">
|
||||
<a href="https://github.com/neuml/txtai/releases">
|
||||
<img src="https://img.shields.io/github/release/neuml/txtai.svg?style=flat&color=success" alt="Version"/>
|
||||
</a>
|
||||
<a href="https://github.com/neuml/txtai/releases">
|
||||
<img src="https://img.shields.io/github/release-date/neuml/txtai.svg?style=flat&color=blue" alt="GitHub Release Date"/>
|
||||
</a>
|
||||
<a href="https://github.com/neuml/txtai/issues">
|
||||
<img src="https://img.shields.io/github/issues/neuml/txtai.svg?style=flat&color=success" alt="GitHub issues"/>
|
||||
</a>
|
||||
<a href="https://github.com/neuml/txtai">
|
||||
<img src="https://img.shields.io/github/last-commit/neuml/txtai.svg?style=flat&color=blue" alt="GitHub last commit"/>
|
||||
</a>
|
||||
<a href="https://github.com/neuml/txtai/actions?query=workflow%3Abuild">
|
||||
<img src="https://github.com/neuml/txtai/workflows/build/badge.svg" alt="Build Status"/>
|
||||
</a>
|
||||
<a href="https://coveralls.io/github/neuml/txtai?branch=master">
|
||||
<img src="https://img.shields.io/coveralls/github/neuml/txtai" alt="Coverage Status">
|
||||
</a>
|
||||
</p>
|
||||
|
||||
-------------------------------------------------------------------------------------------------------------------------------------------------------
|
||||
|
||||
txtai executes machine-learning workflows to transform data and build AI-powered semantic search applications.
|
||||
|
||||

|
||||
|
||||
Traditional search systems use keywords to find data. Semantic search applications have an understanding of natural language and identify results that have the same meaning, not necessarily the same keywords.
|
||||
|
||||
Backed by state-of-the-art machine learning models, data is transformed into vector representations for search (also known as embeddings). Innovation is happening at a rapid pace, models can understand concepts in documents, audio, images and more.
|
||||
|
||||
Summary of txtai features:
|
||||
|
||||
- 🔎 Large-scale similarity search with multiple index backends ([Faiss](https://github.com/facebookresearch/faiss), [Annoy](https://github.com/spotify/annoy), [Hnswlib](https://github.com/nmslib/hnswlib))
|
||||
- 📄 Create embeddings for text snippets, documents, audio, images and video. Supports transformers and word vectors.
|
||||
- 💡 Machine-learning pipelines to run extractive question-answering, zero-shot labeling, transcription, translation, summarization and text extraction
|
||||
- ↪️️ Workflows that join pipelines together to aggregate business logic. txtai processes can be microservices or full-fledged indexing workflows.
|
||||
- 🔗 API bindings for [JavaScript](https://github.com/neuml/txtai.js), [Java](https://github.com/neuml/txtai.java), [Rust](https://github.com/neuml/txtai.rs) and [Go](https://github.com/neuml/txtai.go)
|
||||
- ☁️ Cloud-native architecture that scales out with container orchestration systems (e.g. Kubernetes)
|
||||
|
||||
Applications range from similarity search to complex NLP-driven data extractions to generate structured databases. The following applications are powered by txtai.
|
||||
|
||||
| Application | Description |
|
||||
|:----------|:-------------|
|
||||
| [paperai](https://github.com/neuml/paperai) | AI-powered literature discovery and review engine for medical/scientific papers |
|
||||
| [tldrstory](https://github.com/neuml/tldrstory) | AI-powered understanding of headlines and story text |
|
||||
| [neuspo](https://neuspo.com) | Fact-driven, real-time sports event and news site |
|
||||
| [codequestion](https://github.com/neuml/codequestion) | Ask coding questions directly from the terminal |
|
||||
|
||||
txtai is built with Python 3.6+, [Hugging Face Transformers](https://github.com/huggingface/transformers), [Sentence Transformers](https://github.com/UKPLab/sentence-transformers) and [FastAPI](https://github.com/tiangolo/fastapi)
|
||||
@@ -0,0 +1,80 @@
|
||||
# Installation
|
||||
|
||||
The easiest way to install is via pip and PyPI
|
||||
|
||||
pip install txtai
|
||||
|
||||
Python 3.6+ is supported. Using a Python [virtual environment](https://docs.python.org/3/library/venv.html) is recommended.
|
||||
|
||||
## Install from source
|
||||
|
||||
txtai can also be installed directly from GitHub to access the latest, unreleased features.
|
||||
|
||||
pip install git+https://github.com/neuml/txtai
|
||||
|
||||
## Environment specific prerequisites
|
||||
|
||||
Additional environment specific prerequisites are below.
|
||||
|
||||
### Linux
|
||||
|
||||
Optional audio transcription requires a [system library to be installed](https://github.com/bastibe/python-soundfile#installation)
|
||||
|
||||
### macOS
|
||||
|
||||
Run `brew install libomp` see [this link](https://github.com/kyamagu/faiss-wheels#prerequisite)
|
||||
|
||||
### Windows
|
||||
|
||||
Optional dependencies require [C++ Build Tools](https://visualstudio.microsoft.com/visual-cpp-build-tools/)
|
||||
|
||||
## Optional dependencies
|
||||
|
||||
txtai has the following optional dependencies that can be installed as extras. The patterns below are supported
|
||||
in setup.py install_requires sections.
|
||||
|
||||
### All
|
||||
|
||||
Install all dependencies (mirrors txtai < 3.2)
|
||||
|
||||
```
|
||||
pip install txtai[all]
|
||||
```
|
||||
|
||||
### API
|
||||
|
||||
Serve txtai via a web API.
|
||||
|
||||
```
|
||||
pip install txtai[api]
|
||||
```
|
||||
|
||||
### Pipeline
|
||||
|
||||
All pipelines - default install comes with most common pipelines.
|
||||
|
||||
```
|
||||
pip install txtai[pipeline]
|
||||
```
|
||||
|
||||
### Similarity
|
||||
|
||||
Word vectors, support for sentence-transformers models not on the HF Hub and additional ANN libraries.
|
||||
|
||||
```
|
||||
pip install txtai[similarity]
|
||||
```
|
||||
|
||||
### Workflow
|
||||
|
||||
All workflow tasks - default install comes with most common workflow tasks.
|
||||
|
||||
```
|
||||
pip install txtai[workflow]
|
||||
```
|
||||
|
||||
Multiple dependencies can be specified at the same time.
|
||||
|
||||
```
|
||||
pip install txtai[pipeline,workflow]
|
||||
```
|
||||
@@ -0,0 +1,12 @@
|
||||
# Extractor
|
||||
|
||||
An Extractor pipeline is a combination of an embeddings query and an Extractive QA model. Filtering the context for a QA model helps maximize performance of the model.
|
||||
|
||||
Extractor parameters are set as constructor arguments. Examples below.
|
||||
|
||||
```python
|
||||
Extractor(embeddings, path, quantize, gpu, model, tokenizer)
|
||||
```
|
||||
|
||||
::: txtai.pipeline.Extractor.__init__
|
||||
::: txtai.pipeline.Extractor.__call__
|
||||
@@ -0,0 +1,19 @@
|
||||
# Labels
|
||||
|
||||
A Labels pipeline uses a text classification model to apply labels to input text. This pipeline can classify text using either a zero shot model (dynamic labeling) or a standard text classification model (fixed labeling).
|
||||
|
||||
Labels parameters are set as constructor arguments. Examples below.
|
||||
|
||||
```python
|
||||
# Default configuration
|
||||
Labels()
|
||||
|
||||
# Custom model with zero shot classification
|
||||
Labels("roberta-large-mnli")
|
||||
|
||||
# Model with fixed labels
|
||||
Labels(dynamic=False)
|
||||
```
|
||||
|
||||
::: txtai.pipeline.Labels.__init__
|
||||
::: txtai.pipeline.Labels.__call__
|
||||
@@ -0,0 +1,24 @@
|
||||
# HFOnnx
|
||||
|
||||
Exports a Hugging Face Transformer model to ONNX. Currently, this works best with classification/pooling/qa models. Work is ongoing for sequence to
|
||||
sequence models (summarization, transcription, translation).
|
||||
|
||||
Example on how to use the pipeline below.
|
||||
|
||||
```python
|
||||
from txtai.pipeline import HFOnnx, Labels
|
||||
|
||||
# Model path
|
||||
path = "distilbert-base-uncased-finetuned-sst-2-english"
|
||||
|
||||
# Export model to ONNX
|
||||
onnx = HFOnnx()
|
||||
model = onnx(path, "text-classification", "model.onnx", True)
|
||||
|
||||
# Run inference and validate
|
||||
labels = Labels((model, path), dynamic=False)
|
||||
labels("I am happy")
|
||||
```
|
||||
|
||||
::: txtai.pipeline.HFOnnx.__init__
|
||||
::: txtai.pipeline.HFOnnx.__call__
|
||||
@@ -0,0 +1,19 @@
|
||||
# Pipelines
|
||||
|
||||
txtai provides a generic pipeline processing framework with the only interface requirement being a `__call__` method. Pipelines are flexible and can
|
||||
process various types of data. Pipelines can wrap machine learning models as well as other processes.
|
||||
|
||||
The following pipeline types are currently supported.
|
||||
|
||||
- Hugging Face Transformers pipelines
|
||||
- [Extractive QA](../extractor)
|
||||
- [Labeling](../labels)
|
||||
- [Similarity](../similarity)
|
||||
- [Summary](../summary)
|
||||
- Hugging Face Transformers models
|
||||
- [ONNX](../onnx)
|
||||
- [Trainer](../trainer)
|
||||
- [Transcription](../transcription)
|
||||
- [Translation](../translation)
|
||||
- Data processing calls
|
||||
- [Text extraction](../textractor)
|
||||
@@ -0,0 +1,12 @@
|
||||
# Segmentation
|
||||
|
||||
A Segmentation pipeline segments text into semantic units.
|
||||
|
||||
Segmentation parameters are set as constructor arguments. Examples below.
|
||||
|
||||
```python
|
||||
Segmentation()
|
||||
```
|
||||
|
||||
::: txtai.pipeline.Segmentation.__init__
|
||||
::: txtai.pipeline.Segmentation.__call__
|
||||
@@ -0,0 +1,13 @@
|
||||
## Similarity
|
||||
|
||||
A Similarity pipeline is also a zero shot classifier model where the labels are the queries. The results are transposed to get scores per query/label vs scores per input text.
|
||||
|
||||
Similarity parameters are set as constructor arguments. Examples below.
|
||||
|
||||
```python
|
||||
Similarity()
|
||||
Similarity("roberta-large-mnli")
|
||||
```
|
||||
|
||||
::: txtai.pipeline.Similarity.__init__
|
||||
::: txtai.pipeline.Similarity.__call__
|
||||
@@ -0,0 +1,13 @@
|
||||
# Summary
|
||||
|
||||
A Summary pipeline summarizes text.
|
||||
|
||||
Summary parameters are set as constructor arguments. Examples below.
|
||||
|
||||
```python
|
||||
Summary()
|
||||
Summary("sshleifer/distilbart-cnn-12-3")
|
||||
```
|
||||
|
||||
::: txtai.pipeline.Summary.__init__
|
||||
::: txtai.pipeline.Summary.__call__
|
||||
@@ -0,0 +1,12 @@
|
||||
# Textractor
|
||||
|
||||
A Textractor pipeline extracts and splits text from documents.
|
||||
|
||||
Textractor parameters are set as constructor arguments. Examples below.
|
||||
|
||||
```python
|
||||
Textractor()
|
||||
```
|
||||
|
||||
::: txtai.pipeline.Textractor.__init__
|
||||
::: txtai.pipeline.Textractor.__call__
|
||||
@@ -0,0 +1,36 @@
|
||||
# HFTrainer
|
||||
|
||||
Trains a new Hugging Face Transformer model using the Trainer framework.
|
||||
|
||||
Examples on how to use the trainer below.
|
||||
|
||||
```python
|
||||
import pandas as pd
|
||||
|
||||
from datasets import load_dataset
|
||||
|
||||
from txtai.pipeline import HFTrainer
|
||||
|
||||
trainer = HFTrainer()
|
||||
|
||||
# Pandas DataFrame
|
||||
df = pd.read_csv("training.csv")
|
||||
model, tokenizer = trainer("bert-base-uncased", df)
|
||||
|
||||
# Hugging Face dataset
|
||||
ds = load_dataset("glue", "sst2")
|
||||
model, tokenizer = trainer("bert-base-uncased", ds["train"], columns=("sentence", "label"))
|
||||
|
||||
# List of dicts
|
||||
dt = [{"text": "sentence 1", "label": 0}, {"text": "sentence 2", "label": 1}]]
|
||||
model, tokenizer = trainer("bert-base-uncased", dt)
|
||||
|
||||
# Support additional TrainingArguments
|
||||
model, tokenizer = trainer("bert-base-uncased", dt,
|
||||
learning_rate=3e-5, num_train_epochs=5)
|
||||
```
|
||||
|
||||
All [TrainingArguments](https://huggingface.co/transformers/main_classes/trainer.html#transformers.TrainingArguments) are supported as function arguments to the trainer call.
|
||||
|
||||
::: txtai.pipeline.HFTrainer.__init__
|
||||
::: txtai.pipeline.HFTrainer.__call__
|
||||
@@ -0,0 +1,13 @@
|
||||
# Transcription
|
||||
|
||||
A Transcription pipeline converts speech in audio files to text.
|
||||
|
||||
Transcription parameters are set as constructor arguments. Examples below.
|
||||
|
||||
```python
|
||||
Transcription()
|
||||
Transcription("facebook/wav2vec2-large-960h")
|
||||
```
|
||||
|
||||
::: txtai.pipeline.Transcription.__init__
|
||||
::: txtai.pipeline.Transcription.__call__
|
||||
@@ -0,0 +1,12 @@
|
||||
# Translation
|
||||
|
||||
A Translation pipeline translates text between languages
|
||||
|
||||
Translation parameters are set as constructor arguments. Examples below.
|
||||
|
||||
```python
|
||||
Translation()
|
||||
```
|
||||
|
||||
::: txtai.pipeline.Translation.__init__
|
||||
::: txtai.pipeline.Translation.__call__
|
||||
@@ -0,0 +1,70 @@
|
||||
# Workflows
|
||||
|
||||
Workflows are a simple yet powerful construct that takes a callable and returns elements. Workflows don't know they are working with pipelines but enable efficient processing of pipeline data. Workflows are streaming by nature and work on data in batches, allowing large volumes of data to be processed efficiently.
|
||||
|
||||
An example Workflow is shown below. This workflow will work with both documents and audio files. Documents will have text extracted and summarized. Audio files will be transcribed. Both results will be joined, translated into French and loaded into an Embeddings index.
|
||||
|
||||
```python
|
||||
# file:// prefixes are required to signal to the workflow this is a file and not a text string
|
||||
files = [
|
||||
"file://txtai/article.pdf",
|
||||
"file://txtai/US_tops_5_million.wav",
|
||||
"file://txtai/Canadas_last_fully.wav",
|
||||
"file://txtai/Beijing_mobilises.wav",
|
||||
"file://txtai/The_National_Park.wav",
|
||||
"file://txtai/Maine_man_wins_1_mil.wav",
|
||||
"file://txtai/Make_huge_profits.wav"
|
||||
]
|
||||
|
||||
data = [(x, element, None) for x, element in enumerate(files)]
|
||||
|
||||
# Workflow that extracts text and builds a summary
|
||||
articles = Workflow([
|
||||
FileTask(textractor),
|
||||
Task(lambda x: summary([y[:1024] for y in x]))
|
||||
])
|
||||
|
||||
# Define workflow tasks. Workflows can also be tasks!
|
||||
tasks = [
|
||||
WorkflowTask(articles, r".\.pdf$"),
|
||||
FileTask(transcribe, r"\.wav$"),
|
||||
Task(lambda x: translate(x, "fr")),
|
||||
Task(index, unpack=False)
|
||||
]
|
||||
|
||||
# Workflow that translates text to French
|
||||
workflow = Workflow(tasks)
|
||||
for _ in workflow(data):
|
||||
pass
|
||||
```
|
||||
|
||||
::: txtai.workflow.Workflow.__init__
|
||||
::: txtai.workflow.Workflow.__call__
|
||||
|
||||
## Tasks
|
||||
|
||||
::: txtai.workflow.Task.__init__
|
||||
|
||||
### File Task
|
||||
|
||||
Task that processes file urls
|
||||
|
||||
### Image Task
|
||||
|
||||
Task that processes image urls
|
||||
|
||||
### Service Task
|
||||
|
||||
Task that runs content against a http service
|
||||
|
||||
### Storage Task
|
||||
|
||||
Task that expands a local directory or cloud storage bucket into a list of URLs to process
|
||||
|
||||
### URL Task
|
||||
|
||||
Task that processes urls
|
||||
|
||||
### Workflow Task
|
||||
|
||||
Task that runs a Workflow. Allows creating workflows of workflows.
|
||||
@@ -21,34 +21,42 @@
|
||||
},
|
||||
"colab": {
|
||||
"name": "01 - Introducing txtai",
|
||||
"provenance": []
|
||||
"provenance": [],
|
||||
"collapsed_sections": []
|
||||
}
|
||||
},
|
||||
"cells": [
|
||||
{
|
||||
"cell_type": "markdown",
|
||||
"metadata": {
|
||||
"id": "POWZoSJR6XzK",
|
||||
"colab_type": "text"
|
||||
"id": "POWZoSJR6XzK"
|
||||
},
|
||||
"source": [
|
||||
"# Part 1: Introducing txtai\n",
|
||||
"# Introducing txtai\n",
|
||||
"\n",
|
||||
"[txtai](https://github.com/neuml/txtai) builds an AI-powered index over sections of text. txtai supports building text indices to perform similarity searches and create extractive question-answering based systems. \n",
|
||||
"[txtai](https://github.com/neuml/txtai) executes machine-learning workflows to transform data and build AI-powered semantic search applications. \n",
|
||||
"\n",
|
||||
"NeuML uses txtai and/or the concepts behind it to power all of our Natural Language Processing (NLP) applications. Example applications:\n",
|
||||
"Traditional search systems use keywords to find data. Semantic search applications have an understanding of natural language and identify results that have the same meaning, not necessarily the same keywords.\n",
|
||||
"\n",
|
||||
"Backed by state-of-the-art machine learning models, data is transformed into vector representations for search (also known as embeddings). Innovation is happening at a rapid pace, models can understand concepts in documents, audio, images and more.\n",
|
||||
"\n",
|
||||
"The following is a summary of key features:\n",
|
||||
"\n",
|
||||
"- 🔎 Large-scale similarity search with multiple index backends ([Faiss](https://github.com/facebookresearch/faiss), [Annoy](https://github.com/spotify/annoy), [Hnswlib](https://github.com/nmslib/hnswlib))\n",
|
||||
"- 📄 Create embeddings for text snippets, documents, audio, images and video. Supports transformers and word vectors.\n",
|
||||
"- 💡 Machine-learning pipelines to run extractive question-answering, zero-shot labeling, transcription, translation, summarization and text extraction\n",
|
||||
"- ↪️️ Workflows that join pipelines together to aggregate business logic. txtai processes can be microservices or full-fledged indexing workflows.\n",
|
||||
"- 🔗 API bindings for [JavaScript](https://github.com/neuml/txtai.js), [Java](https://github.com/neuml/txtai.java), [Rust](https://github.com/neuml/txtai.rs) and [Go](https://github.com/neuml/txtai.go)\n",
|
||||
"- ☁️ Cloud-native architecture that scales out with container orchestration systems (e.g. Kubernetes)\n",
|
||||
"\n",
|
||||
"Applications range from similarity search to complex NLP-driven data extractions to generate structured databases. The following applications are powered by txtai.\n",
|
||||
"\n",
|
||||
"- [cord19q](https://github.com/neuml/cord19q) - COVID-19 literature analysis\n",
|
||||
"- [paperai](https://github.com/neuml/paperai) - AI-powered literature discovery and review engine for medical/scientific papers\n",
|
||||
"- [neuspo](https://neuspo.com) - a fact-driven, real-time sports event and news site\n",
|
||||
"- [tldrstory](https://github.com/neuml/tldrstory) - AI-powered understanding of headlines and story text\n",
|
||||
"- [neuspo](https://neuspo.com) - Fact-driven, real-time sports event and news site\n",
|
||||
"- [codequestion](https://github.com/neuml/codequestion) - Ask coding questions directly from the terminal\n",
|
||||
"\n",
|
||||
"txtai is built on the following stack:\n",
|
||||
"\n",
|
||||
"- [sentence-transformers](https://github.com/UKPLab/sentence-transformers)\n",
|
||||
"- [transformers](https://github.com/huggingface/transformers)\n",
|
||||
"- [faiss](https://github.com/facebookresearch/faiss)\n",
|
||||
"- Python 3.6+\n",
|
||||
"txtai is built with Python 3.6+, [Hugging Face Transformers](https://github.com/huggingface/transformers), [Sentence Transformers](https://github.com/UKPLab/sentence-transformers) and [FastAPI](https://github.com/tiangolo/fastapi)\n",
|
||||
"\n",
|
||||
"This notebook gives an overview of txtai and how to run similarity searches."
|
||||
]
|
||||
@@ -56,13 +64,12 @@
|
||||
{
|
||||
"cell_type": "markdown",
|
||||
"metadata": {
|
||||
"id": "qa_PPKVX6XzN",
|
||||
"colab_type": "text"
|
||||
"id": "qa_PPKVX6XzN"
|
||||
},
|
||||
"source": [
|
||||
"# Install dependencies\n",
|
||||
"\n",
|
||||
"Install txtai and all dependencies"
|
||||
"Install `txtai` and all dependencies."
|
||||
]
|
||||
},
|
||||
{
|
||||
@@ -72,22 +79,19 @@
|
||||
"_cell_guid": "b1076dfc-b9ad-4769-8c92-a6c4dae69d19",
|
||||
"trusted": true,
|
||||
"_kg_hide-output": true,
|
||||
"id": "24q-1n5i6XzQ",
|
||||
"colab_type": "code",
|
||||
"colab": {}
|
||||
"id": "24q-1n5i6XzQ"
|
||||
},
|
||||
"source": [
|
||||
"%%capture\n",
|
||||
"!pip install git+https://github.com/neuml/txtai"
|
||||
],
|
||||
"execution_count": 1,
|
||||
"execution_count": null,
|
||||
"outputs": []
|
||||
},
|
||||
{
|
||||
"cell_type": "markdown",
|
||||
"metadata": {
|
||||
"id": "vHxb_jm16Xzd",
|
||||
"colab_type": "text"
|
||||
"id": "vHxb_jm16Xzd"
|
||||
},
|
||||
"source": [
|
||||
"# Create an Embeddings instance\n",
|
||||
@@ -99,9 +103,7 @@
|
||||
"cell_type": "code",
|
||||
"metadata": {
|
||||
"trusted": true,
|
||||
"id": "QxX9EtIc6Xzg",
|
||||
"colab_type": "code",
|
||||
"colab": {}
|
||||
"id": "QxX9EtIc6Xzg"
|
||||
},
|
||||
"source": [
|
||||
"%%capture\n",
|
||||
@@ -109,16 +111,15 @@
|
||||
"from txtai.embeddings import Embeddings\n",
|
||||
"\n",
|
||||
"# Create embeddings model, backed by sentence-transformers & transformers\n",
|
||||
"embeddings = Embeddings({\"method\": \"transformers\", \"path\": \"sentence-transformers/bert-base-nli-mean-tokens\"})"
|
||||
"embeddings = Embeddings({\"path\": \"sentence-transformers/nli-mpnet-base-v2\"})"
|
||||
],
|
||||
"execution_count": 2,
|
||||
"execution_count": null,
|
||||
"outputs": []
|
||||
},
|
||||
{
|
||||
"cell_type": "markdown",
|
||||
"metadata": {
|
||||
"id": "JAO61bcy6Xzo",
|
||||
"colab_type": "text"
|
||||
"id": "JAO61bcy6Xzo"
|
||||
},
|
||||
"source": [
|
||||
"# Running similarity queries\n",
|
||||
@@ -133,33 +134,29 @@
|
||||
"_cell_guid": "79c7e3d0-c299-4dcb-8224-4455121ee9b0",
|
||||
"trusted": true,
|
||||
"id": "2j_CFGDR6Xzp",
|
||||
"colab_type": "code",
|
||||
"colab": {
|
||||
"base_uri": "https://localhost:8080/",
|
||||
"height": 191
|
||||
"base_uri": "https://localhost:8080/"
|
||||
},
|
||||
"outputId": "a92c2d3e-1b6d-473a-bc7e-7adc067fa868"
|
||||
"outputId": "7a9ecc24-94d1-4ab4-a197-196532a10474"
|
||||
},
|
||||
"source": [
|
||||
"import numpy as np\n",
|
||||
"\n",
|
||||
"sections = [\"US tops 5 million confirmed virus cases\",\n",
|
||||
" \"Canada's last fully intact ice shelf has suddenly collapsed, forming a Manhattan-sized iceberg\",\n",
|
||||
" \"Beijing mobilises invasion craft along coast as Taiwan tensions escalate\",\n",
|
||||
" \"The National Park Service warns against sacrificing slower friends in a bear attack\",\n",
|
||||
" \"Maine man wins $1M from $25 lottery ticket\",\n",
|
||||
" \"Make huge profits without work, earn up to $100,000 a day\"]\n",
|
||||
"data = [\"US tops 5 million confirmed virus cases\",\n",
|
||||
" \"Canada's last fully intact ice shelf has suddenly collapsed, forming a Manhattan-sized iceberg\",\n",
|
||||
" \"Beijing mobilises invasion craft along coast as Taiwan tensions escalate\",\n",
|
||||
" \"The National Park Service warns against sacrificing slower friends in a bear attack\",\n",
|
||||
" \"Maine man wins $1M from $25 lottery ticket\",\n",
|
||||
" \"Make huge profits without work, earn up to $100,000 a day\"]\n",
|
||||
"\n",
|
||||
"print(\"%-20s %s\" % (\"Query\", \"Best Match\"))\n",
|
||||
"print(\"-\" * 50)\n",
|
||||
"\n",
|
||||
"for query in (\"feel good story\", \"climate change\", \"health\", \"war\", \"wildlife\", \"asia\", \"north america\", \"dishonest junk\"):\n",
|
||||
"for query in (\"feel good story\", \"climate change\", \"public health story\", \"war\", \"wildlife\", \"asia\", \"lucky\", \"dishonest junk\"):\n",
|
||||
" # Get index of best section that best matches query\n",
|
||||
" uid = np.argmax(embeddings.similarity(query, sections))\n",
|
||||
" uid = embeddings.similarity(query, data)[0][0]\n",
|
||||
"\n",
|
||||
" print(\"%-20s %s\" % (query, sections[uid]))"
|
||||
" print(\"%-20s %s\" % (query, data[uid]))"
|
||||
],
|
||||
"execution_count": 3,
|
||||
"execution_count": null,
|
||||
"outputs": [
|
||||
{
|
||||
"output_type": "stream",
|
||||
@@ -168,11 +165,11 @@
|
||||
"--------------------------------------------------\n",
|
||||
"feel good story Maine man wins $1M from $25 lottery ticket\n",
|
||||
"climate change Canada's last fully intact ice shelf has suddenly collapsed, forming a Manhattan-sized iceberg\n",
|
||||
"health US tops 5 million confirmed virus cases\n",
|
||||
"public health story US tops 5 million confirmed virus cases\n",
|
||||
"war Beijing mobilises invasion craft along coast as Taiwan tensions escalate\n",
|
||||
"wildlife The National Park Service warns against sacrificing slower friends in a bear attack\n",
|
||||
"asia Beijing mobilises invasion craft along coast as Taiwan tensions escalate\n",
|
||||
"north america US tops 5 million confirmed virus cases\n",
|
||||
"lucky Maine man wins $1M from $25 lottery ticket\n",
|
||||
"dishonest junk Make huge profits without work, earn up to $100,000 a day\n"
|
||||
],
|
||||
"name": "stdout"
|
||||
@@ -182,8 +179,7 @@
|
||||
{
|
||||
"cell_type": "markdown",
|
||||
"metadata": {
|
||||
"id": "kIMbLW0t6Xzw",
|
||||
"colab_type": "text"
|
||||
"id": "kIMbLW0t6Xzw"
|
||||
},
|
||||
"source": [
|
||||
"The example above shows for almost all of the queries, the actual text isn't stored in the list of text sections. This is the true power of transformer models over token based search. What you get out of the box is 🔥🔥🔥!"
|
||||
@@ -192,13 +188,12 @@
|
||||
{
|
||||
"cell_type": "markdown",
|
||||
"metadata": {
|
||||
"id": "DLIjSzbq6Xzx",
|
||||
"colab_type": "text"
|
||||
"id": "DLIjSzbq6Xzx"
|
||||
},
|
||||
"source": [
|
||||
"# Building an Embeddings index\n",
|
||||
"\n",
|
||||
"For small lists of texts, the method above works. But for larger repositories of documents, it doesn't make sense to tokenize and convert to embeddings on each query. txtai supports building pre-computed indices which significantly improve performance. \n",
|
||||
"For small lists of texts, the method above works. But for larger repositories of documents, it doesn't make sense to tokenize and convert to embeddings on each query. txtai supports building pre-computed indices which signficantly improve performance. \n",
|
||||
"\n",
|
||||
"Building on the previous example, the following example runs an index method to build and store the text embeddings. In this case, only the query is converted to an embeddings vector each search. "
|
||||
]
|
||||
@@ -208,30 +203,28 @@
|
||||
"metadata": {
|
||||
"trusted": true,
|
||||
"id": "cXfZtdHD6Xzy",
|
||||
"colab_type": "code",
|
||||
"colab": {
|
||||
"base_uri": "https://localhost:8080/",
|
||||
"height": 191
|
||||
"base_uri": "https://localhost:8080/"
|
||||
},
|
||||
"outputId": "eca8eb29-7ac8-445b-f9b9-6b5cea3280a5"
|
||||
"outputId": "df3d534e-74f5-484a-8f89-34611b809823"
|
||||
},
|
||||
"source": [
|
||||
"# Create an index for the list of sections\n",
|
||||
"embeddings.index([(uid, text, None) for uid, text in enumerate(sections)])\n",
|
||||
"# Create an index for the list of text\n",
|
||||
"embeddings.index([(uid, text, None) for uid, text in enumerate(data)])\n",
|
||||
"\n",
|
||||
"print(\"%-20s %s\" % (\"Query\", \"Best Match\"))\n",
|
||||
"print(\"-\" * 50)\n",
|
||||
"\n",
|
||||
"# Run an embeddings search for each query\n",
|
||||
"for query in (\"feel good story\", \"climate change\", \"health\", \"war\", \"wildlife\", \"asia\", \"north america\", \"dishonest junk\"):\n",
|
||||
"for query in (\"feel good story\", \"climate change\", \"public health story\", \"war\", \"wildlife\", \"asia\", \"lucky\", \"dishonest junk\"):\n",
|
||||
" # Extract uid of first result\n",
|
||||
" # search result format: (uid, score)\n",
|
||||
" uid = embeddings.search(query, 1)[0][0]\n",
|
||||
"\n",
|
||||
" # Print section\n",
|
||||
" print(\"%-20s %s\" % (query, sections[uid]))"
|
||||
" # Print text\n",
|
||||
" print(\"%-20s %s\" % (query, data[uid]))"
|
||||
],
|
||||
"execution_count": 4,
|
||||
"execution_count": null,
|
||||
"outputs": [
|
||||
{
|
||||
"output_type": "stream",
|
||||
@@ -240,11 +233,11 @@
|
||||
"--------------------------------------------------\n",
|
||||
"feel good story Maine man wins $1M from $25 lottery ticket\n",
|
||||
"climate change Canada's last fully intact ice shelf has suddenly collapsed, forming a Manhattan-sized iceberg\n",
|
||||
"health US tops 5 million confirmed virus cases\n",
|
||||
"public health story US tops 5 million confirmed virus cases\n",
|
||||
"war Beijing mobilises invasion craft along coast as Taiwan tensions escalate\n",
|
||||
"wildlife The National Park Service warns against sacrificing slower friends in a bear attack\n",
|
||||
"asia Beijing mobilises invasion craft along coast as Taiwan tensions escalate\n",
|
||||
"north america US tops 5 million confirmed virus cases\n",
|
||||
"lucky Maine man wins $1M from $25 lottery ticket\n",
|
||||
"dishonest junk Make huge profits without work, earn up to $100,000 a day\n"
|
||||
],
|
||||
"name": "stdout"
|
||||
@@ -254,13 +247,12 @@
|
||||
{
|
||||
"cell_type": "markdown",
|
||||
"metadata": {
|
||||
"id": "6TCVl6QA6Xz5",
|
||||
"colab_type": "text"
|
||||
"id": "6TCVl6QA6Xz5"
|
||||
},
|
||||
"source": [
|
||||
"# Embeddings load/save\n",
|
||||
"\n",
|
||||
"Embeddings indices can be saved to disk and reloaded. At this time, indices are not incrementally created, the index needs a full rebuild to incorporate new data. But that enhancement is in the backlog."
|
||||
"Embeddings indices can be saved to disk and reloaded."
|
||||
]
|
||||
},
|
||||
{
|
||||
@@ -268,12 +260,10 @@
|
||||
"metadata": {
|
||||
"trusted": true,
|
||||
"id": "5gyO90Hc6Xz7",
|
||||
"colab_type": "code",
|
||||
"colab": {
|
||||
"base_uri": "https://localhost:8080/",
|
||||
"height": 34
|
||||
"base_uri": "https://localhost:8080/"
|
||||
},
|
||||
"outputId": "92e1358d-4dcf-4982-8811-061f0bfa9a88"
|
||||
"outputId": "1853e9ed-622c-4986-e653-04d7d4ab4e4c"
|
||||
},
|
||||
"source": [
|
||||
"embeddings.save(\"index\")\n",
|
||||
@@ -282,9 +272,9 @@
|
||||
"embeddings.load(\"index\")\n",
|
||||
"\n",
|
||||
"uid = embeddings.search(\"climate change\", 1)[0][0]\n",
|
||||
"print(sections[uid])"
|
||||
"print(data[uid])"
|
||||
],
|
||||
"execution_count": 5,
|
||||
"execution_count": null,
|
||||
"outputs": [
|
||||
{
|
||||
"output_type": "stream",
|
||||
@@ -300,17 +290,15 @@
|
||||
"metadata": {
|
||||
"trusted": true,
|
||||
"id": "d2uCotAE6X0J",
|
||||
"colab_type": "code",
|
||||
"colab": {
|
||||
"base_uri": "https://localhost:8080/",
|
||||
"height": 34
|
||||
"base_uri": "https://localhost:8080/"
|
||||
},
|
||||
"outputId": "14f16d54-ca02-4099-9478-24ba8054d3e3"
|
||||
"outputId": "45fc8372-d925-4f89-b1d3-0ae895ed74a8"
|
||||
},
|
||||
"source": [
|
||||
"!ls index"
|
||||
],
|
||||
"execution_count": 6,
|
||||
"execution_count": null,
|
||||
"outputs": [
|
||||
{
|
||||
"output_type": "stream",
|
||||
@@ -324,8 +312,61 @@
|
||||
{
|
||||
"cell_type": "markdown",
|
||||
"metadata": {
|
||||
"id": "aDIF3tYt6X0O",
|
||||
"colab_type": "text"
|
||||
"id": "6m7sYUj_AdOL"
|
||||
},
|
||||
"source": [
|
||||
"# Embeddings update/delete\n",
|
||||
"\n",
|
||||
"Updates and deletes are supported for Embedding indices. The upsert operation will insert new data and update existing data\n",
|
||||
"\n",
|
||||
"The following section runs a query, then updates a value changing the top result and finally deletes the updated value to revert back to the original query results."
|
||||
]
|
||||
},
|
||||
{
|
||||
"cell_type": "code",
|
||||
"metadata": {
|
||||
"colab": {
|
||||
"base_uri": "https://localhost:8080/"
|
||||
},
|
||||
"id": "2CERR0U2Ac8C",
|
||||
"outputId": "796d3e8b-557a-4140-ccfb-6a1a3c3c9474"
|
||||
},
|
||||
"source": [
|
||||
"# Run initial query\n",
|
||||
"uid = embeddings.search(\"feel good story\", 1)[0][0]\n",
|
||||
"print(\"Initial: \", data[uid])\n",
|
||||
"\n",
|
||||
"# Update data\n",
|
||||
"data[0] = \"See it: baby panda born\"\n",
|
||||
"embeddings.upsert([(0, data[0], None)])\n",
|
||||
"\n",
|
||||
"uid = embeddings.search(\"feel good story\", 1)[0][0]\n",
|
||||
"print(\"After update: \", data[uid])\n",
|
||||
"\n",
|
||||
"# Remove record just added from index\n",
|
||||
"embeddings.delete([0])\n",
|
||||
"\n",
|
||||
"# Ensure value matches previous value\n",
|
||||
"uid = embeddings.search(\"feel good story\", 1)[0][0]\n",
|
||||
"print(\"After delete: \", data[uid])"
|
||||
],
|
||||
"execution_count": null,
|
||||
"outputs": [
|
||||
{
|
||||
"output_type": "stream",
|
||||
"text": [
|
||||
"Initial: Maine man wins $1M from $25 lottery ticket\n",
|
||||
"After update: See it: baby panda born\n",
|
||||
"After delete: Maine man wins $1M from $25 lottery ticket\n"
|
||||
],
|
||||
"name": "stdout"
|
||||
}
|
||||
]
|
||||
},
|
||||
{
|
||||
"cell_type": "markdown",
|
||||
"metadata": {
|
||||
"id": "aDIF3tYt6X0O"
|
||||
},
|
||||
"source": [
|
||||
"# Embedding methods\n",
|
||||
@@ -340,20 +381,9 @@
|
||||
"- word embeddings\n",
|
||||
" - Creates a single embeddings vector via BM25 scoring of each word component. See this [Medium article](https://towardsdatascience.com/building-a-sentence-embedding-index-with-fasttext-and-bm25-f07e7148d240) for the logic behind this method.\n",
|
||||
" - Backed by the [pymagnitude](https://github.com/plasticityai/magnitude) library. Pre-trained word vectors can be installed from the referenced link.\n",
|
||||
" - See [vectors.py](https://github.com/neuml/txtai/blob/master/src/python/txtai/vectors.py) for code that can build word vectors for custom datasets.\n",
|
||||
" - See [words.py](https://github.com/neuml/txtai/blob/master/src/python/txtai/vectors/words.py) for code that can build word vectors for custom datasets.\n",
|
||||
" - Significantly better performance with default models. For larger datasets, it offers a good tradeoff of speed and accuracy."
|
||||
]
|
||||
},
|
||||
{
|
||||
"cell_type": "markdown",
|
||||
"metadata": {
|
||||
"id": "0Nw7nbHg6X0P",
|
||||
"colab_type": "text"
|
||||
},
|
||||
"source": [
|
||||
"# Next\n",
|
||||
"In part 2 of this series, we'll look at how to use txtai to run extractive searches"
|
||||
]
|
||||
}
|
||||
]
|
||||
}
|
||||
}
|
||||
@@ -0,0 +1,304 @@
|
||||
{
|
||||
"nbformat": 4,
|
||||
"nbformat_minor": 0,
|
||||
"metadata": {
|
||||
"colab": {
|
||||
"name": "02 - Build an Embeddings index with Hugging Face Datasets",
|
||||
"provenance": [],
|
||||
"collapsed_sections": []
|
||||
},
|
||||
"kernelspec": {
|
||||
"name": "python3",
|
||||
"display_name": "Python 3"
|
||||
},
|
||||
"accelerator": "GPU"
|
||||
},
|
||||
"cells": [
|
||||
{
|
||||
"cell_type": "markdown",
|
||||
"metadata": {
|
||||
"id": "LjmhJ4ad9kBL"
|
||||
},
|
||||
"source": [
|
||||
"# Build an Embeddings index with Hugging Face Datasets\n",
|
||||
"\n",
|
||||
"This notebook shows how txtai can index and search with Hugging Face's [Datasets](https://github.com/huggingface/datasets) library. Datasets opens access to a large and growing list of publicly available datasets. Datasets has functionality to select, transform and filter data stored in each dataset.\n",
|
||||
"\n",
|
||||
"In this example, txtai will be used to index and query a dataset.\n",
|
||||
"\n",
|
||||
"**Make sure to select a GPU runtime when running this notebook**"
|
||||
]
|
||||
},
|
||||
{
|
||||
"cell_type": "markdown",
|
||||
"metadata": {
|
||||
"id": "8tLWvo9v-Q0u"
|
||||
},
|
||||
"source": [
|
||||
"# Install dependencies\n",
|
||||
"\n",
|
||||
"Install `txtai` and all dependencies. Also install `datasets` and a specific [sentence-transformers](https://github.com/UKPLab/sentence-transformers) model that does well with general information retrieval tasks. "
|
||||
]
|
||||
},
|
||||
{
|
||||
"cell_type": "code",
|
||||
"metadata": {
|
||||
"id": "Fa5BCjMFqVKE"
|
||||
},
|
||||
"source": [
|
||||
"%%capture\n",
|
||||
"!pip install git+https://github.com/neuml/txtai\n",
|
||||
"!pip install datasets"
|
||||
],
|
||||
"execution_count": null,
|
||||
"outputs": []
|
||||
},
|
||||
{
|
||||
"cell_type": "markdown",
|
||||
"metadata": {
|
||||
"id": "hOdEv8MH-e5h"
|
||||
},
|
||||
"source": [
|
||||
"# Load dataset and build a txtai index\n",
|
||||
"\n",
|
||||
"In this example, we'll load the `ag_news` dataset, which is a collection of news article headlines. This only takes a single line of code!\n",
|
||||
"\n",
|
||||
"Next, txtai will index the first 10,000 rows of the dataset. A model trained on msmarco is used to compute sentence embeddings. sentence-transformers has a number of [pre-trained models](https://huggingface.co/models?search=sentence-transformers) that can be swapped in.\n",
|
||||
"\n",
|
||||
"In addition to the embeddings index, we'll also create a Similarity instance to re-rank search hits for relevancy. "
|
||||
]
|
||||
},
|
||||
{
|
||||
"cell_type": "code",
|
||||
"metadata": {
|
||||
"id": "3hYRk9JnsM0J"
|
||||
},
|
||||
"source": [
|
||||
"%%capture\n",
|
||||
"from datasets import load_dataset\n",
|
||||
"\n",
|
||||
"from txtai.embeddings import Embeddings\n",
|
||||
"from txtai.pipeline import Similarity\n",
|
||||
"\n",
|
||||
"def stream(dataset, field, limit):\n",
|
||||
" index = 0\n",
|
||||
" for row in dataset:\n",
|
||||
" yield (index, row[field], None)\n",
|
||||
" index += 1\n",
|
||||
"\n",
|
||||
" if index >= limit:\n",
|
||||
" break\n",
|
||||
"\n",
|
||||
"def search(query):\n",
|
||||
" return [(score, dataset[uid][\"text\"]) for uid, score in embeddings.search(query, limit=50)]\n",
|
||||
"\n",
|
||||
"def ranksearch(query):\n",
|
||||
" results = [text for _, text in search(query)]\n",
|
||||
" return [(score, results[x]) for x, score in similarity(query, results)]\n",
|
||||
"\n",
|
||||
"# Load HF dataset\n",
|
||||
"dataset = load_dataset(\"ag_news\", split=\"train\")\n",
|
||||
"\n",
|
||||
"# Create embeddings model, backed by sentence-transformers & transformers\n",
|
||||
"embeddings = Embeddings({\"path\": \"sentence-transformers/msmarco-distilbert-base-v4\"})\n",
|
||||
"embeddings.index(stream(dataset, \"text\", 10000))\n",
|
||||
"\n",
|
||||
"# Create similarity instance for re-ranking\n",
|
||||
"similarity = Similarity(\"valhalla/distilbart-mnli-12-3\")"
|
||||
],
|
||||
"execution_count": null,
|
||||
"outputs": []
|
||||
},
|
||||
{
|
||||
"cell_type": "markdown",
|
||||
"metadata": {
|
||||
"id": "LBhHcX6eFmGI"
|
||||
},
|
||||
"source": [
|
||||
"# Search the dataset\n",
|
||||
"\n",
|
||||
"Now that an index is ready, let's search the data! The following section runs a series of queries and show the results. Like basic search engines, txtai finds token matches. But the real power of txtai is finding semantically similar results.\n",
|
||||
"\n",
|
||||
"sentence-transformers has a great overview on [information retrieval](https://www.sbert.net/examples/applications/information-retrieval/README.html) that is well worth a read. "
|
||||
]
|
||||
},
|
||||
{
|
||||
"cell_type": "code",
|
||||
"metadata": {
|
||||
"id": "YVmbiY92vxEO",
|
||||
"colab": {
|
||||
"base_uri": "https://localhost:8080/",
|
||||
"height": 1000
|
||||
},
|
||||
"outputId": "5d18279c-abf4-4983-b024-252bdb60628d"
|
||||
},
|
||||
"source": [
|
||||
"from IPython.core.display import display, HTML\n",
|
||||
"\n",
|
||||
"def table(query, rows):\n",
|
||||
" html = \"\"\"\n",
|
||||
" <style type='text/css'>\n",
|
||||
" @import url('https://fonts.googleapis.com/css?family=Oswald&display=swap');\n",
|
||||
" table {\n",
|
||||
" border-collapse: collapse;\n",
|
||||
" width: 900px;\n",
|
||||
" }\n",
|
||||
" th, td {\n",
|
||||
" border: 1px solid #9e9e9e;\n",
|
||||
" padding: 10px;\n",
|
||||
" font: 15px Oswald;\n",
|
||||
" }\n",
|
||||
" </style>\n",
|
||||
" \"\"\"\n",
|
||||
"\n",
|
||||
" html += \"<h3>%s</h3><table><thead><tr><th>Score</th><th>Text</th></tr></thead>\" % (query)\n",
|
||||
" for score, text in rows:\n",
|
||||
" html += \"<tr><td>%.4f</td><td>%s</td></tr>\" % (score, text)\n",
|
||||
" html += \"</table>\"\n",
|
||||
"\n",
|
||||
" display(HTML(html))\n",
|
||||
"\n",
|
||||
"for query in [\"Positive Apple reports\", \"Negative Apple reports\", \"Best planets to explore for life\", \"LA Dodgers good news\", \"LA Dodgers bad news\"]:\n",
|
||||
" table(query, ranksearch(query)[:2])\n"
|
||||
],
|
||||
"execution_count": null,
|
||||
"outputs": [
|
||||
{
|
||||
"output_type": "display_data",
|
||||
"data": {
|
||||
"text/html": [
|
||||
"\n",
|
||||
" <style type='text/css'>\n",
|
||||
" @import url('https://fonts.googleapis.com/css?family=Oswald&display=swap');\n",
|
||||
" table {\n",
|
||||
" border-collapse: collapse;\n",
|
||||
" width: 900px;\n",
|
||||
" }\n",
|
||||
" th, td {\n",
|
||||
" border: 1px solid #9e9e9e;\n",
|
||||
" padding: 10px;\n",
|
||||
" font: 15px Oswald;\n",
|
||||
" }\n",
|
||||
" </style>\n",
|
||||
" <h3>Positive Apple reports</h3><table><thead><tr><th>Score</th><th>Text</th></tr></thead><tr><td>0.9941</td><td>Apple's iPod a Huge Hit in Japan The iPod is proving a colossal hit on the Japanese electronics and entertainment giant's home ground. The tiny white machine is catching on as a fashion statement and turning into a cultural icon here, much the same way it won a fanatical following in the United States.</td></tr><tr><td>0.9886</td><td>Apple tops US consumer satisfaction Recent data published by the American Customer Satisfaction Index (ACSI) shows Apple leading the consumer computer industry with the the highest customer satisfaction.</td></tr></table>"
|
||||
],
|
||||
"text/plain": [
|
||||
"<IPython.core.display.HTML object>"
|
||||
]
|
||||
},
|
||||
"metadata": {
|
||||
"tags": []
|
||||
}
|
||||
},
|
||||
{
|
||||
"output_type": "display_data",
|
||||
"data": {
|
||||
"text/html": [
|
||||
"\n",
|
||||
" <style type='text/css'>\n",
|
||||
" @import url('https://fonts.googleapis.com/css?family=Oswald&display=swap');\n",
|
||||
" table {\n",
|
||||
" border-collapse: collapse;\n",
|
||||
" width: 900px;\n",
|
||||
" }\n",
|
||||
" th, td {\n",
|
||||
" border: 1px solid #9e9e9e;\n",
|
||||
" padding: 10px;\n",
|
||||
" font: 15px Oswald;\n",
|
||||
" }\n",
|
||||
" </style>\n",
|
||||
" <h3>Negative Apple reports</h3><table><thead><tr><th>Score</th><th>Text</th></tr></thead><tr><td>0.9847</td><td>Apple Recalls 28,000 Faulty Batteries Sold with 15-inch PowerBook Apple has had to recall up to 28,000 notebook batteries that were sold for use with their 15-inch PowerBook. Apple reports that faulty batteries sold between January 2004 and August 2004 can overheat and pose a fire hazard.</td></tr><tr><td>0.9795</td><td>Apple Announces Voluntary Recall of Powerbook Batteries Apple, in cooperation with the US Consumer Product Safety Commission (CPSC), announced Thursday a voluntary recall of 15 quot; Aluminum PowerBook batteries. The batteries being recalled could potentially overheat, though no injuries relating ...</td></tr></table>"
|
||||
],
|
||||
"text/plain": [
|
||||
"<IPython.core.display.HTML object>"
|
||||
]
|
||||
},
|
||||
"metadata": {
|
||||
"tags": []
|
||||
}
|
||||
},
|
||||
{
|
||||
"output_type": "display_data",
|
||||
"data": {
|
||||
"text/html": [
|
||||
"\n",
|
||||
" <style type='text/css'>\n",
|
||||
" @import url('https://fonts.googleapis.com/css?family=Oswald&display=swap');\n",
|
||||
" table {\n",
|
||||
" border-collapse: collapse;\n",
|
||||
" width: 900px;\n",
|
||||
" }\n",
|
||||
" th, td {\n",
|
||||
" border: 1px solid #9e9e9e;\n",
|
||||
" padding: 10px;\n",
|
||||
" font: 15px Oswald;\n",
|
||||
" }\n",
|
||||
" </style>\n",
|
||||
" <h3>Best planets to explore for life</h3><table><thead><tr><th>Score</th><th>Text</th></tr></thead><tr><td>0.9110</td><td>Tiny 'David' Telescope Finds 'Goliath' Planet A newfound planet detected by a small, 4-inch-diameter telescope demonstrates that we are at the cusp of a new age of planet discovery. Soon, new worlds may be located at an accelerating pace, bringing the detection of the first Earth-sized world one step closer.</td></tr><tr><td>0.9014</td><td>NASA Develops Robust Artificial Intelligence for Planetary Rovers NASA is planning to add a strong dose of artificial intelligence (AI) to planetary rovers to make them much more self-reliant, capable of making basic decisions during a mission. Scientists are developing very complex AI software that enables a higher level of robotic intelligence.</td></tr></table>"
|
||||
],
|
||||
"text/plain": [
|
||||
"<IPython.core.display.HTML object>"
|
||||
]
|
||||
},
|
||||
"metadata": {
|
||||
"tags": []
|
||||
}
|
||||
},
|
||||
{
|
||||
"output_type": "display_data",
|
||||
"data": {
|
||||
"text/html": [
|
||||
"\n",
|
||||
" <style type='text/css'>\n",
|
||||
" @import url('https://fonts.googleapis.com/css?family=Oswald&display=swap');\n",
|
||||
" table {\n",
|
||||
" border-collapse: collapse;\n",
|
||||
" width: 900px;\n",
|
||||
" }\n",
|
||||
" th, td {\n",
|
||||
" border: 1px solid #9e9e9e;\n",
|
||||
" padding: 10px;\n",
|
||||
" font: 15px Oswald;\n",
|
||||
" }\n",
|
||||
" </style>\n",
|
||||
" <h3>LA Dodgers good news</h3><table><thead><tr><th>Score</th><th>Text</th></tr></thead><tr><td>0.9990</td><td>Green's Slam Lifts L.A. Shawn Green connects on a grand slam and a solo homer to lead the Los Angeles Dodgers past the Atlanta Braves 7-4 on Saturday.</td></tr><tr><td>0.9961</td><td>Dodgers 7, Braves 4 Los Angeles, Ca. -- Shawn Green belted a grand slam and a solo homer as Los Angeles beat Mike Hampton and the Atlanta Braves 7-to-4 Saturday afternoon.</td></tr></table>"
|
||||
],
|
||||
"text/plain": [
|
||||
"<IPython.core.display.HTML object>"
|
||||
]
|
||||
},
|
||||
"metadata": {
|
||||
"tags": []
|
||||
}
|
||||
},
|
||||
{
|
||||
"output_type": "display_data",
|
||||
"data": {
|
||||
"text/html": [
|
||||
"\n",
|
||||
" <style type='text/css'>\n",
|
||||
" @import url('https://fonts.googleapis.com/css?family=Oswald&display=swap');\n",
|
||||
" table {\n",
|
||||
" border-collapse: collapse;\n",
|
||||
" width: 900px;\n",
|
||||
" }\n",
|
||||
" th, td {\n",
|
||||
" border: 1px solid #9e9e9e;\n",
|
||||
" padding: 10px;\n",
|
||||
" font: 15px Oswald;\n",
|
||||
" }\n",
|
||||
" </style>\n",
|
||||
" <h3>LA Dodgers bad news</h3><table><thead><tr><th>Score</th><th>Text</th></tr></thead><tr><td>0.9880</td><td>Expos Keep Dodgers at Bay With 8-7 Win (AP) AP - Giovanni Carrara walked Juan Rivera with the bases loaded and two outs in the ninth inning Monday night, spoiling Los Angeles' six-run comeback and handing the Montreal Expos an 8-7 victory over the Dodgers.</td></tr><tr><td>0.9437</td><td>Marlins Defeat Dodgers 6-4 LOS ANGELES - Pinch-hitter Lenny Harris delivered a three-run double off Eric Gagne with two outs in the ninth inning, rallying the Florida Marlins past the Los Angeles Dodgers 6-4 Wednesday night. It was only Gagne's second blown save in 100 chances dating to Aug...</td></tr></table>"
|
||||
],
|
||||
"text/plain": [
|
||||
"<IPython.core.display.HTML object>"
|
||||
]
|
||||
},
|
||||
"metadata": {
|
||||
"tags": []
|
||||
}
|
||||
}
|
||||
]
|
||||
}
|
||||
]
|
||||
}
|
||||
@@ -16,15 +16,14 @@
|
||||
{
|
||||
"cell_type": "markdown",
|
||||
"metadata": {
|
||||
"id": "WDbhGHtG8jFE",
|
||||
"colab_type": "text"
|
||||
"id": "WDbhGHtG8jFE"
|
||||
},
|
||||
"source": [
|
||||
"# Part 3: Build an Embeddings index from a data source\n",
|
||||
"# Build an Embeddings index from a data source\n",
|
||||
"\n",
|
||||
"In Part 1, we gave a general overview of txtai, the backing technology and examples of how to use it for similarity searches. Part 2 covered how to use txtai for extractive question-answer systems.\n",
|
||||
"In Part 1, we gave a general overview of txtai, the backing technology and examples of how to use it for similarity searches. Part 2 covered an embedding index with a larger dataset. \n",
|
||||
"\n",
|
||||
"The previous examples worked on data stored in memory for demo purposes. For real world large-scale use cases, data is usually stored in a database (Elasticsearch, SQL, MongoDB, files, etc). This example covers reading data from SQLite, building a Embedding index backed by word embeddings and running queries against the generated Embeddings index.\n",
|
||||
"For real world large-scale use cases, data is often stored in a database (Elasticsearch, SQL, MongoDB, files, etc). Here we'll show how to read from SQLite, build a Embedding index backed by word embeddings and run queries against the generated Embeddings index.\n",
|
||||
"\n",
|
||||
"This example covers functionality found in the [paperai](https://github.com/neuml/paperai) library. See that library for a full solution that can be used with the dataset discussed below."
|
||||
]
|
||||
@@ -32,95 +31,64 @@
|
||||
{
|
||||
"cell_type": "markdown",
|
||||
"metadata": {
|
||||
"id": "UQ0fCwXn9bcH",
|
||||
"colab_type": "text"
|
||||
"id": "UQ0fCwXn9bcH"
|
||||
},
|
||||
"source": [
|
||||
"# Install dependencies\n",
|
||||
"\n",
|
||||
"Install txtai and all dependencies"
|
||||
"Install `txtai` and all dependencies. Since this notebook is building word vectors, we need to install the similarity extras package."
|
||||
]
|
||||
},
|
||||
{
|
||||
"cell_type": "code",
|
||||
"metadata": {
|
||||
"id": "czPYSA2Q9ZHO",
|
||||
"colab_type": "code",
|
||||
"colab": {}
|
||||
"id": "czPYSA2Q9ZHO"
|
||||
},
|
||||
"source": [
|
||||
"%%capture\n",
|
||||
"!pip install git+https://github.com/neuml/txtai"
|
||||
"!pip install git+https://github.com/neuml/txtai#egg=txtai[similarity]"
|
||||
],
|
||||
"execution_count": 1,
|
||||
"execution_count": null,
|
||||
"outputs": []
|
||||
},
|
||||
{
|
||||
"cell_type": "markdown",
|
||||
"metadata": {
|
||||
"id": "SN9SCZKQ9fJF",
|
||||
"colab_type": "text"
|
||||
"id": "SN9SCZKQ9fJF"
|
||||
},
|
||||
"source": [
|
||||
"# Download data\n",
|
||||
"\n",
|
||||
"This example is going to work off a subset of the [CORD-19](https://www.semanticscholar.org/cord19) dataset. COVID-19 Open Research Dataset (CORD-19) is a free resource of scholarly articles, aggregated by a coalition of leading research groups, covering COVID-19 and the coronavirus family of viruses.\n",
|
||||
"\n",
|
||||
"The following download is SQLite database with a subject of CORD-19, generated from a [Kaggle notebook](https://www.kaggle.com/davidmezzetti/cord-19-slim/output). More information on this data format, can be found in the [CORD-19 Analysis](https://www.kaggle.com/davidmezzetti/cord-19-analysis-with-sentence-embeddings) notebook."
|
||||
"The following download is a SQLite database generated from a [Kaggle notebook](https://www.kaggle.com/davidmezzetti/cord-19-slim/output). More information on this data format, can be found in the [CORD-19 Analysis](https://www.kaggle.com/davidmezzetti/cord-19-analysis-with-sentence-embeddings) notebook."
|
||||
]
|
||||
},
|
||||
{
|
||||
"cell_type": "code",
|
||||
"metadata": {
|
||||
"id": "TONQ4_Kv9dtd",
|
||||
"colab_type": "code",
|
||||
"colab": {
|
||||
"base_uri": "https://localhost:8080/",
|
||||
"height": 315
|
||||
},
|
||||
"outputId": "55f85ebf-946e-44aa-e27e-026436be909e"
|
||||
"id": "TONQ4_Kv9dtd"
|
||||
},
|
||||
"source": [
|
||||
"%%capture\n",
|
||||
"!wget https://github.com/neuml/txtai/releases/download/v1.1.0/tests.gz\n",
|
||||
"!gunzip tests.gz\n",
|
||||
"!mv tests articles.sqlite"
|
||||
],
|
||||
"execution_count": 2,
|
||||
"outputs": [
|
||||
{
|
||||
"output_type": "stream",
|
||||
"text": [
|
||||
"--2020-08-25 01:56:04-- https://github.com/neuml/txtai/releases/download/v1.1.0/tests.gz\n",
|
||||
"Resolving github.com (github.com)... 140.82.112.4\n",
|
||||
"Connecting to github.com (github.com)|140.82.112.4|:443... connected.\n",
|
||||
"HTTP request sent, awaiting response... 302 Found\n",
|
||||
"Location: https://github-production-release-asset-2e65be.s3.amazonaws.com/286301447/080d8800-e653-11ea-8d02-c0c858a09e7a?X-Amz-Algorithm=AWS4-HMAC-SHA256&X-Amz-Credential=AKIAIWNJYAX4CSVEH53A%2F20200825%2Fus-east-1%2Fs3%2Faws4_request&X-Amz-Date=20200825T015604Z&X-Amz-Expires=300&X-Amz-Signature=e135dc0b8f0d7774019d6525aad528b99160aff4007b2a539330c090c29ef9b5&X-Amz-SignedHeaders=host&actor_id=0&repo_id=286301447&response-content-disposition=attachment%3B%20filename%3Dtests.gz&response-content-type=application%2Foctet-stream [following]\n",
|
||||
"--2020-08-25 01:56:04-- https://github-production-release-asset-2e65be.s3.amazonaws.com/286301447/080d8800-e653-11ea-8d02-c0c858a09e7a?X-Amz-Algorithm=AWS4-HMAC-SHA256&X-Amz-Credential=AKIAIWNJYAX4CSVEH53A%2F20200825%2Fus-east-1%2Fs3%2Faws4_request&X-Amz-Date=20200825T015604Z&X-Amz-Expires=300&X-Amz-Signature=e135dc0b8f0d7774019d6525aad528b99160aff4007b2a539330c090c29ef9b5&X-Amz-SignedHeaders=host&actor_id=0&repo_id=286301447&response-content-disposition=attachment%3B%20filename%3Dtests.gz&response-content-type=application%2Foctet-stream\n",
|
||||
"Resolving github-production-release-asset-2e65be.s3.amazonaws.com (github-production-release-asset-2e65be.s3.amazonaws.com)... 52.216.110.243\n",
|
||||
"Connecting to github-production-release-asset-2e65be.s3.amazonaws.com (github-production-release-asset-2e65be.s3.amazonaws.com)|52.216.110.243|:443... connected.\n",
|
||||
"HTTP request sent, awaiting response... 200 OK\n",
|
||||
"Length: 2456199 (2.3M) [application/octet-stream]\n",
|
||||
"Saving to: ‘tests.gz’\n",
|
||||
"\n",
|
||||
"tests.gz 100%[===================>] 2.34M --.-KB/s in 0.09s \n",
|
||||
"\n",
|
||||
"2020-08-25 01:56:05 (24.7 MB/s) - ‘tests.gz’ saved [2456199/2456199]\n",
|
||||
"\n"
|
||||
],
|
||||
"name": "stdout"
|
||||
}
|
||||
]
|
||||
"execution_count": null,
|
||||
"outputs": []
|
||||
},
|
||||
{
|
||||
"cell_type": "markdown",
|
||||
"metadata": {
|
||||
"id": "bzdaJiZYBIHE",
|
||||
"colab_type": "text"
|
||||
"id": "bzdaJiZYBIHE"
|
||||
},
|
||||
"source": [
|
||||
"# Build Word Vectors\n",
|
||||
"\n",
|
||||
"This example will build a search system backed by word embeddings. While note quite as powerful as transformer embeddings, they often provide a good tradeoff of performance to functionality for an embedding based search system.\n",
|
||||
"This example will build a search system backed by word embeddings. Word embeddings provide a good tradeoff of performance to functionality for a similarity search system. With that being said, transformer models are making great progress in scaling performance down to smaller models and are the preferred vector backend for txtai in most cases. \n",
|
||||
"\n",
|
||||
"While not quite as powerful as transformer embeddings, they often provide a g\n",
|
||||
"\n",
|
||||
"For this notebook, we'll build our own custom embeddings for demo purposes. A number of pre-trained word embedding models are available:\n",
|
||||
"\n",
|
||||
@@ -132,12 +100,10 @@
|
||||
"cell_type": "code",
|
||||
"metadata": {
|
||||
"id": "fJcn-CAH-u3K",
|
||||
"colab_type": "code",
|
||||
"colab": {
|
||||
"base_uri": "https://localhost:8080/",
|
||||
"height": 156
|
||||
"base_uri": "https://localhost:8080/"
|
||||
},
|
||||
"outputId": "8ad62b92-55b7-4f2e-af55-f313402574a8"
|
||||
"outputId": "8c744791-0eb3-43bd-da64-107d64310b9a"
|
||||
},
|
||||
"source": [
|
||||
"import os\n",
|
||||
@@ -159,7 +125,7 @@
|
||||
" cur.execute(\"SELECT Text from sections\")\n",
|
||||
"\n",
|
||||
" for row in cur:\n",
|
||||
" output.write(\" \".join(row[0]) + \"\\n\")\n",
|
||||
" output.write(\" \".join(Tokenizer.tokenize(row[0])) + \"\\n\")\n",
|
||||
"\n",
|
||||
" # Free database resources\n",
|
||||
" db.close()\n",
|
||||
@@ -173,7 +139,7 @@
|
||||
"# Show files\n",
|
||||
"!ls -l"
|
||||
],
|
||||
"execution_count": 3,
|
||||
"execution_count": null,
|
||||
"outputs": [
|
||||
{
|
||||
"output_type": "stream",
|
||||
@@ -181,11 +147,11 @@
|
||||
"Streaming tokens to temporary file\n",
|
||||
"Building 300 dimension model\n",
|
||||
"Converting vectors to magnitude format\n",
|
||||
"total 9024\n",
|
||||
"-rw-r--r-- 1 root root 8065024 Aug 25 01:44 articles.sqlite\n",
|
||||
"-rw-r--r-- 1 root root 360448 Aug 25 01:57 cord19-300d.magnitude\n",
|
||||
"-rw-r--r-- 1 root root 807886 Aug 25 01:57 cord19-300d.txt\n",
|
||||
"drwxr-xr-x 1 root root 4096 Jul 30 16:30 sample_data\n"
|
||||
"total 78952\n",
|
||||
"-rw-r--r-- 1 root root 8065024 Aug 25 2020 articles.sqlite\n",
|
||||
"-rw-r--r-- 1 root root 24145920 Aug 17 16:46 cord19-300d.magnitude\n",
|
||||
"-rw-r--r-- 1 root root 48625387 Aug 17 16:46 cord19-300d.txt\n",
|
||||
"drwxr-xr-x 1 root root 4096 Aug 13 13:35 sample_data\n"
|
||||
],
|
||||
"name": "stdout"
|
||||
}
|
||||
@@ -194,25 +160,22 @@
|
||||
{
|
||||
"cell_type": "markdown",
|
||||
"metadata": {
|
||||
"id": "_UxcC1-JGH-d",
|
||||
"colab_type": "text"
|
||||
"id": "_UxcC1-JGH-d"
|
||||
},
|
||||
"source": [
|
||||
"# Build an embeddings index\n",
|
||||
"\n",
|
||||
"The following steps builds an embeddings index using the word vector model just created. This model builds a BM25 + fastText index. BM25 is used to build a weighted average of the word embeddings for a section. More information on this method can be found in this [Medium article](https://towardsdatascience.com/building-a-sentence-embedding-index-with-fasttext-and-bm25-f07e7148d240?gi=79da927aa10). "
|
||||
"The following steps build an embeddings index using the word vector model just created. This model builds a BM25 + fastText index. BM25 is used to build a weighted average of the word embeddings for a section. More information on this method can be found in this [Medium article](https://towardsdatascience.com/building-a-sentence-embedding-index-with-fasttext-and-bm25-f07e7148d240?gi=79da927aa10). "
|
||||
]
|
||||
},
|
||||
{
|
||||
"cell_type": "code",
|
||||
"metadata": {
|
||||
"id": "5PrrxGRPGHqX",
|
||||
"colab_type": "code",
|
||||
"colab": {
|
||||
"base_uri": "https://localhost:8080/",
|
||||
"height": 52
|
||||
"base_uri": "https://localhost:8080/"
|
||||
},
|
||||
"outputId": "36c78d6a-1f01-4e66-d0a8-7d27d3698ab3"
|
||||
"outputId": "caf9d6fc-19b1-4237-bcb9-736bd288c1fc"
|
||||
},
|
||||
"source": [
|
||||
"import sqlite3\n",
|
||||
@@ -267,7 +230,7 @@
|
||||
"# Build embeddings index\n",
|
||||
"embeddings.index(stream())\n"
|
||||
],
|
||||
"execution_count": 4,
|
||||
"execution_count": null,
|
||||
"outputs": [
|
||||
{
|
||||
"output_type": "stream",
|
||||
@@ -282,8 +245,7 @@
|
||||
{
|
||||
"cell_type": "markdown",
|
||||
"metadata": {
|
||||
"id": "zHk24su3e_gb",
|
||||
"colab_type": "text"
|
||||
"id": "zHk24su3e_gb"
|
||||
},
|
||||
"source": [
|
||||
"# Query data\n",
|
||||
@@ -295,12 +257,11 @@
|
||||
"cell_type": "code",
|
||||
"metadata": {
|
||||
"id": "CRbDhvvDKEl-",
|
||||
"colab_type": "code",
|
||||
"colab": {
|
||||
"base_uri": "https://localhost:8080/",
|
||||
"height": 293
|
||||
},
|
||||
"outputId": "3f52b2b9-5307-47af-8dee-fdd9e694250b"
|
||||
"outputId": "6bab2b95-a974-408e-c07d-4b62f313f4c9"
|
||||
},
|
||||
"source": [
|
||||
"import pandas as pd\n",
|
||||
@@ -325,9 +286,17 @@
|
||||
"\n",
|
||||
"df = pd.DataFrame(results, columns=[\"Title\", \"Published\", \"Reference\", \"Match\"])\n",
|
||||
"\n",
|
||||
"# It has been reported that displaying HTML within VSCode doesn't work.\n",
|
||||
"# When using VSCode, the data can be exported to an external HTML file to view.\n",
|
||||
"# See example below.\n",
|
||||
"\n",
|
||||
"# htmlData = df.to_html(index=False)\n",
|
||||
"# with open(\"data.html\", \"w\") as file:\n",
|
||||
"# file.write(htmlData)\n",
|
||||
"\n",
|
||||
"display(HTML(df.to_html(index=False)))"
|
||||
],
|
||||
"execution_count": 5,
|
||||
"execution_count": null,
|
||||
"outputs": [
|
||||
{
|
||||
"output_type": "display_data",
|
||||
@@ -344,34 +313,34 @@
|
||||
" </thead>\n",
|
||||
" <tbody>\n",
|
||||
" <tr>\n",
|
||||
" <td>Prevalence and Impact of Myocardial Injury in Patients Hospitalized with COVID-19 Infection</td>\n",
|
||||
" <td>2020-04-24 00:00:00</td>\n",
|
||||
" <td>http://medrxiv.org/cgi/content/short/2020.04.20.20072702v1?rss=1</td>\n",
|
||||
" <td>This risk was consistent across patients stratified by history of CVD, risk factors but no CVD, and neither CVD nor risk factors.</td>\n",
|
||||
" </tr>\n",
|
||||
" <tr>\n",
|
||||
" <td>COVID-19 and associations with frailty and multimorbidity: a prospective analysis of UK Biobank participants</td>\n",
|
||||
" <td>2020-07-23 00:00:00</td>\n",
|
||||
" <td>https://www.ncbi.nlm.nih.gov/pubmed/32705587/</td>\n",
|
||||
" <td>The identification of risk factors for contracting COVID-19 is crucial, to inform public health policy and to facilitate the appropriate distribution of healthcare resources.</td>\n",
|
||||
" </tr>\n",
|
||||
" <tr>\n",
|
||||
" <td>Quantitative evaluation of olfactory dysfunction in hospitalized patients with Coronavirus [2] (COVID-19)</td>\n",
|
||||
" <td>2020-05-25 00:00:00</td>\n",
|
||||
" <td>https://www.ncbi.nlm.nih.gov/pubmed/32451613/</td>\n",
|
||||
" <td>In addition, these reports included patients with minor COVID-19 symptoms and low-risk factor burden.</td>\n",
|
||||
" </tr>\n",
|
||||
" <tr>\n",
|
||||
" <td>COVID-19 from the perspective of urban and rural general adult mental health services</td>\n",
|
||||
" <td>2020-05-21 00:00:00</td>\n",
|
||||
" <td>https://doi.org/10.1017/ipm.2020.62</td>\n",
|
||||
" <td>At-risk groups among staff members and service users were identified early and prioritised in service changes.</td>\n",
|
||||
" </tr>\n",
|
||||
" <tr>\n",
|
||||
" <td>Management of osteoarthritis during COVID‐19 pandemic</td>\n",
|
||||
" <td>2020-05-21 00:00:00</td>\n",
|
||||
" <td>https://doi.org/10.1002/cpt.1910</td>\n",
|
||||
" <td>Consistently, a recent report indicated diabetes as a risk factor significantly associated with COVID-19 unfavourable clinical outcomes (37) .</td>\n",
|
||||
" <td>Indeed, risk factors are sex, obesity, genetic factors and mechanical factors (3) .</td>\n",
|
||||
" </tr>\n",
|
||||
" <tr>\n",
|
||||
" <td>Work-related and Personal Factors Associated with Mental Well-being during COVID-19 Response: A Survey of Health Care and Other Workers</td>\n",
|
||||
" <td>2020-06-11 00:00:00</td>\n",
|
||||
" <td>http://medrxiv.org/cgi/content/short/2020.06.09.20126722v1?rss=1</td>\n",
|
||||
" <td>Poor family supportive behaviors by supervisors were also associated with these outcomes [1.40 (1.21 - 1.62), 1.69 (1.48 - 1.92), 1.54 (1.44 - 1.64)].</td>\n",
|
||||
" </tr>\n",
|
||||
" <tr>\n",
|
||||
" <td>No evidence that androgen regulation of pulmonary TMPRSS2 explains sex-discordant COVID-19 outcomes</td>\n",
|
||||
" <td>2020-04-21 00:00:00</td>\n",
|
||||
" <td>https://doi.org/10.1101/2020.04.21.051201</td>\n",
|
||||
" <td>In addition to male sex, smoking is a risk factor for COVID-19 susceptibility and poor clinical outcomes .</td>\n",
|
||||
" </tr>\n",
|
||||
" <tr>\n",
|
||||
" <td>Current status of potential therapeutic candidates for the COVID-19 crisis</td>\n",
|
||||
" <td>2020-04-22 00:00:00</td>\n",
|
||||
" <td>https://doi.org/10.1016/j.bbi.2020.04.046</td>\n",
|
||||
" <td>There was no difference on 28-day mortality between heparin users and nonusers.</td>\n",
|
||||
" </tr>\n",
|
||||
" <tr>\n",
|
||||
" <td>COVID-19: what has been learned and to be learned about the novel coronavirus disease</td>\n",
|
||||
" <td>2020-03-15 00:00:00</td>\n",
|
||||
" <td>https://doi.org/10.7150/ijbs.45134</td>\n",
|
||||
" <td>• Three major risk factors for COVID-19 were sex (male), age (≥60), and severe pneumonia.</td>\n",
|
||||
" </tr>\n",
|
||||
" </tbody>\n",
|
||||
"</table>"
|
||||
@@ -389,21 +358,18 @@
|
||||
{
|
||||
"cell_type": "markdown",
|
||||
"metadata": {
|
||||
"id": "XSf68I-ZfXOG",
|
||||
"colab_type": "text"
|
||||
"id": "XSf68I-ZfXOG"
|
||||
},
|
||||
"source": [
|
||||
"# Extracting additional columns from query results\n",
|
||||
"\n",
|
||||
"The example above uses the Embeddings index to find the top 5 best matches. In addition to this, an Extractor instance is used to ask additional questions over the search results, creating a richer query response."
|
||||
"The example above uses the Embeddings index to find the top 5 best matches. In addition to this, an Extractor instance (this will be explained further in part 5) is used to ask additional questions over the search results, creating a richer query response."
|
||||
]
|
||||
},
|
||||
{
|
||||
"cell_type": "code",
|
||||
"metadata": {
|
||||
"id": "TLVOTQJchvTi",
|
||||
"colab_type": "code",
|
||||
"colab": {}
|
||||
"id": "TLVOTQJchvTi"
|
||||
},
|
||||
"source": [
|
||||
"%%capture\n",
|
||||
@@ -412,19 +378,18 @@
|
||||
"# Create extractor instance using qa model designed for the CORD-19 dataset\n",
|
||||
"extractor = Extractor(embeddings, \"NeuML/bert-small-cord19qa\")"
|
||||
],
|
||||
"execution_count": 6,
|
||||
"execution_count": null,
|
||||
"outputs": []
|
||||
},
|
||||
{
|
||||
"cell_type": "code",
|
||||
"metadata": {
|
||||
"id": "19fmKawThs6d",
|
||||
"colab_type": "code",
|
||||
"colab": {
|
||||
"base_uri": "https://localhost:8080/",
|
||||
"height": 293
|
||||
},
|
||||
"outputId": "e5c24448-97b4-444f-d47e-d268ef18aec5"
|
||||
"outputId": "e666b706-1e31-4f82-c39a-e5183c0d66ad"
|
||||
},
|
||||
"source": [
|
||||
"db = sqlite3.connect(\"articles.sqlite\")\n",
|
||||
@@ -436,18 +401,18 @@
|
||||
" uid, text = cur.fetchone()\n",
|
||||
"\n",
|
||||
" # Get list of document text sections to use for the context\n",
|
||||
" cur.execute(\"SELECT Id, Name, Text FROM sections WHERE (labels is null or labels NOT IN ('FRAGMENT', 'QUESTION')) AND article = ?\", [uid])\n",
|
||||
" sections = []\n",
|
||||
" for sid, name, txt in cur.fetchall():\n",
|
||||
" cur.execute(\"SELECT Name, Text FROM sections WHERE (labels is null or labels NOT IN ('FRAGMENT', 'QUESTION')) AND article = ? ORDER BY Id\", [uid])\n",
|
||||
" texts = []\n",
|
||||
" for name, txt in cur.fetchall():\n",
|
||||
" if not name or not re.search(r\"background|(?<!.*?results.*?)discussion|introduction|reference\", name.lower()):\n",
|
||||
" sections.append((sid, txt))\n",
|
||||
" texts.append(txt)\n",
|
||||
"\n",
|
||||
" cur.execute(\"SELECT Title, Published, Reference from articles where id = ?\", [uid])\n",
|
||||
" article = cur.fetchone()\n",
|
||||
"\n",
|
||||
" # Use QA extractor to derive additional columns\n",
|
||||
" answers = extractor(sections, [(\"Risk Factors\", \"risk factors\", \"What risk factors?\", False),\n",
|
||||
" (\"Locations\", \"hospital country\", \"What locations?\", False)])\n",
|
||||
" answers = extractor([(\"Risk Factors\", \"risk factors\", \"What risk factors?\", False),\n",
|
||||
" (\"Locations\", \"hospital country\", \"What locations?\", False)], texts)\n",
|
||||
"\n",
|
||||
" results.append(article + (text,) + tuple([answer[1] for answer in answers]))\n",
|
||||
"\n",
|
||||
@@ -457,7 +422,7 @@
|
||||
"df = pd.DataFrame(results, columns=[\"Title\", \"Published\", \"Reference\", \"Match\", \"Risk Factors\", \"Locations\"])\n",
|
||||
"display(HTML(df.to_html(index=False)))"
|
||||
],
|
||||
"execution_count": 7,
|
||||
"execution_count": null,
|
||||
"outputs": [
|
||||
{
|
||||
"output_type": "display_data",
|
||||
@@ -476,45 +441,45 @@
|
||||
" </thead>\n",
|
||||
" <tbody>\n",
|
||||
" <tr>\n",
|
||||
" <td>Prevalence and Impact of Myocardial Injury in Patients Hospitalized with COVID-19 Infection</td>\n",
|
||||
" <td>2020-04-24 00:00:00</td>\n",
|
||||
" <td>http://medrxiv.org/cgi/content/short/2020.04.20.20072702v1?rss=1</td>\n",
|
||||
" <td>This risk was consistent across patients stratified by history of CVD, risk factors but no CVD, and neither CVD nor risk factors.</td>\n",
|
||||
" <td>neither CVD nor risk factors</td>\n",
|
||||
" <td>New York City hospitals</td>\n",
|
||||
" </tr>\n",
|
||||
" <tr>\n",
|
||||
" <td>COVID-19 and associations with frailty and multimorbidity: a prospective analysis of UK Biobank participants</td>\n",
|
||||
" <td>2020-07-23 00:00:00</td>\n",
|
||||
" <td>https://www.ncbi.nlm.nih.gov/pubmed/32705587/</td>\n",
|
||||
" <td>The identification of risk factors for contracting COVID-19 is crucial, to inform public health policy and to facilitate the appropriate distribution of healthcare resources.</td>\n",
|
||||
" <td>Frailty and multimorbidity</td>\n",
|
||||
" <td>hospital settings</td>\n",
|
||||
" </tr>\n",
|
||||
" <tr>\n",
|
||||
" <td>Quantitative evaluation of olfactory dysfunction in hospitalized patients with Coronavirus [2] (COVID-19)</td>\n",
|
||||
" <td>2020-05-25 00:00:00</td>\n",
|
||||
" <td>https://www.ncbi.nlm.nih.gov/pubmed/32451613/</td>\n",
|
||||
" <td>In addition, these reports included patients with minor COVID-19 symptoms and low-risk factor burden.</td>\n",
|
||||
" <td>patients with minor COVID-19 symptoms and low-risk factor burden</td>\n",
|
||||
" <td>COVID-19 wards</td>\n",
|
||||
" </tr>\n",
|
||||
" <tr>\n",
|
||||
" <td>COVID-19 from the perspective of urban and rural general adult mental health services</td>\n",
|
||||
" <td>2020-05-21 00:00:00</td>\n",
|
||||
" <td>https://doi.org/10.1017/ipm.2020.62</td>\n",
|
||||
" <td>At-risk groups among staff members and service users were identified early and prioritised in service changes.</td>\n",
|
||||
" <td>At-risk groups among staff members and service users</td>\n",
|
||||
" <td>rural regions</td>\n",
|
||||
" </tr>\n",
|
||||
" <tr>\n",
|
||||
" <td>Management of osteoarthritis during COVID‐19 pandemic</td>\n",
|
||||
" <td>2020-05-21 00:00:00</td>\n",
|
||||
" <td>https://doi.org/10.1002/cpt.1910</td>\n",
|
||||
" <td>Consistently, a recent report indicated diabetes as a risk factor significantly associated with COVID-19 unfavourable clinical outcomes (37) .</td>\n",
|
||||
" <td>Indeed, risk factors are sex, obesity, genetic factors and mechanical factors (3) .</td>\n",
|
||||
" <td>sex, obesity, genetic factors and mechanical factors</td>\n",
|
||||
" <td>None</td>\n",
|
||||
" </tr>\n",
|
||||
" <tr>\n",
|
||||
" <td>Work-related and Personal Factors Associated with Mental Well-being during COVID-19 Response: A Survey of Health Care and Other Workers</td>\n",
|
||||
" <td>2020-06-11 00:00:00</td>\n",
|
||||
" <td>http://medrxiv.org/cgi/content/short/2020.06.09.20126722v1?rss=1</td>\n",
|
||||
" <td>Poor family supportive behaviors by supervisors were also associated with these outcomes [1.40 (1.21 - 1.62), 1.69 (1.48 - 1.92), 1.54 (1.44 - 1.64)].</td>\n",
|
||||
" <td>Poor family supportive behaviors</td>\n",
|
||||
" <td>None</td>\n",
|
||||
" </tr>\n",
|
||||
" <tr>\n",
|
||||
" <td>No evidence that androgen regulation of pulmonary TMPRSS2 explains sex-discordant COVID-19 outcomes</td>\n",
|
||||
" <td>2020-04-21 00:00:00</td>\n",
|
||||
" <td>https://doi.org/10.1101/2020.04.21.051201</td>\n",
|
||||
" <td>In addition to male sex, smoking is a risk factor for COVID-19 susceptibility and poor clinical outcomes .</td>\n",
|
||||
" <td>Higher morbidity and mortality</td>\n",
|
||||
" <td>None</td>\n",
|
||||
" </tr>\n",
|
||||
" <tr>\n",
|
||||
" <td>Current status of potential therapeutic candidates for the COVID-19 crisis</td>\n",
|
||||
" <td>2020-04-22 00:00:00</td>\n",
|
||||
" <td>https://doi.org/10.1016/j.bbi.2020.04.046</td>\n",
|
||||
" <td>There was no difference on 28-day mortality between heparin users and nonusers.</td>\n",
|
||||
" <td>elicited strong inflammatory responses are favorable or detrimental</td>\n",
|
||||
" <td>None</td>\n",
|
||||
" </tr>\n",
|
||||
" <tr>\n",
|
||||
" <td>COVID-19: what has been learned and to be learned about the novel coronavirus disease</td>\n",
|
||||
" <td>2020-03-15 00:00:00</td>\n",
|
||||
" <td>https://doi.org/10.7150/ijbs.45134</td>\n",
|
||||
" <td>• Three major risk factors for COVID-19 were sex (male), age (≥60), and severe pneumonia.</td>\n",
|
||||
" <td>sex (male), age (≥60), and severe pneumonia</td>\n",
|
||||
" <td>None</td>\n",
|
||||
" </tr>\n",
|
||||
" </tbody>\n",
|
||||
"</table>"
|
||||
],
|
||||
@@ -531,23 +496,11 @@
|
||||
{
|
||||
"cell_type": "markdown",
|
||||
"metadata": {
|
||||
"id": "ColTLy--rWfR",
|
||||
"colab_type": "text"
|
||||
"id": "ColTLy--rWfR"
|
||||
},
|
||||
"source": [
|
||||
"In the example above, the Embeddings index is used to find the top N results for a given query. On top of that, a question-answer extractor is used to derive additional columns based on a list of questions. In this case, the \"Risk Factors\" and \"Location\" columns were pulled from the document text."
|
||||
]
|
||||
},
|
||||
{
|
||||
"cell_type": "markdown",
|
||||
"metadata": {
|
||||
"id": "KWyoysauy7Pr",
|
||||
"colab_type": "text"
|
||||
},
|
||||
"source": [
|
||||
"# Next\n",
|
||||
"In part 4 of this series, we'll use combine the power of Elasticsearch with Extractive QA to build a large-scale, advanced search system.\n"
|
||||
]
|
||||
}
|
||||
]
|
||||
}
|
||||
@@ -0,0 +1,525 @@
|
||||
{
|
||||
"nbformat": 4,
|
||||
"nbformat_minor": 0,
|
||||
"metadata": {
|
||||
"accelerator": "GPU",
|
||||
"colab": {
|
||||
"name": "04 - Add semantic search to Elasticsearch",
|
||||
"provenance": [],
|
||||
"collapsed_sections": []
|
||||
},
|
||||
"kernelspec": {
|
||||
"display_name": "Python 3",
|
||||
"name": "python3"
|
||||
}
|
||||
},
|
||||
"cells": [
|
||||
{
|
||||
"cell_type": "markdown",
|
||||
"metadata": {
|
||||
"id": "zzZbP0LM6m5z"
|
||||
},
|
||||
"source": [
|
||||
"# Add semantic search to Elasticsearch\n",
|
||||
"\n",
|
||||
"Part 2 and Part 3 of this series showed how to index and search data in txtai. Part 2 indexed and searched a Hugging Face Dataset, Part 3 indexed and searched an external data source. \n",
|
||||
"\n",
|
||||
"txtai is modular in design, it's components can be individually used. txtai has a similarity function that works on lists of text. This method can be integrated with any external search service, such as a REST API, a SQL query or anything else that returns text search results. \n",
|
||||
"\n",
|
||||
"In this notebook, we'll take the same Hugging Face Dataset used in Part 2, index it in Elasticsearch and rank the search results using a semantic similarity function from txtai.\n",
|
||||
"\n",
|
||||
"**Make sure to select a GPU runtime when running this notebook**"
|
||||
]
|
||||
},
|
||||
{
|
||||
"cell_type": "markdown",
|
||||
"metadata": {
|
||||
"id": "xk7t5Jcd6reO"
|
||||
},
|
||||
"source": [
|
||||
"# Install dependencies\n",
|
||||
"\n",
|
||||
"Install `txtai`, `datasets` and `Elasticsearch`."
|
||||
]
|
||||
},
|
||||
{
|
||||
"cell_type": "code",
|
||||
"metadata": {
|
||||
"id": "0y1UA4-q-YdA"
|
||||
},
|
||||
"source": [
|
||||
"%%capture\n",
|
||||
"\n",
|
||||
"# Install txtai, datasets and elasticsearch python client\n",
|
||||
"!pip install git+https://github.com/neuml/txtai datasets elasticsearch\n",
|
||||
"\n",
|
||||
"# Download and extract elasticsearch\n",
|
||||
"!wget https://artifacts.elastic.co/downloads/elasticsearch/elasticsearch-7.10.1-linux-x86_64.tar.gz\n",
|
||||
"!tar -xzf elasticsearch-7.10.1-linux-x86_64.tar.gz\n",
|
||||
"!chown -R daemon:daemon elasticsearch-7.10.1"
|
||||
],
|
||||
"execution_count": null,
|
||||
"outputs": []
|
||||
},
|
||||
{
|
||||
"cell_type": "markdown",
|
||||
"metadata": {
|
||||
"id": "M5c_WxmxCShQ"
|
||||
},
|
||||
"source": [
|
||||
"Start an instance of Elasticsearch directly within this notebook."
|
||||
]
|
||||
},
|
||||
{
|
||||
"cell_type": "code",
|
||||
"metadata": {
|
||||
"id": "3ZfJeWbM6wmj"
|
||||
},
|
||||
"source": [
|
||||
"import os\n",
|
||||
"from subprocess import Popen, PIPE, STDOUT\n",
|
||||
"\n",
|
||||
"# If issues are encountered with this section, ES can be manually started as follows:\n",
|
||||
"# ./elasticsearch-7.10.1/bin/elasticsearch\n",
|
||||
"\n",
|
||||
"# Start and wait for server\n",
|
||||
"server = Popen(['elasticsearch-7.10.1/bin/elasticsearch'], stdout=PIPE, stderr=STDOUT, preexec_fn=lambda: os.setuid(1))\n",
|
||||
"!sleep 30"
|
||||
],
|
||||
"execution_count": null,
|
||||
"outputs": []
|
||||
},
|
||||
{
|
||||
"cell_type": "markdown",
|
||||
"metadata": {
|
||||
"id": "hSWFzkCn61tM"
|
||||
},
|
||||
"source": [
|
||||
"# Load data into Elasticsearch\n",
|
||||
"\n",
|
||||
"The following block loads the dataset into Elasticsearch."
|
||||
]
|
||||
},
|
||||
{
|
||||
"cell_type": "code",
|
||||
"metadata": {
|
||||
"colab": {
|
||||
"base_uri": "https://localhost:8080/"
|
||||
},
|
||||
"id": "So-OBvUT61QD",
|
||||
"outputId": "9dfae86a-e39a-4eaf-bea0-89c5869a1ce9"
|
||||
},
|
||||
"source": [
|
||||
"from datasets import load_dataset\n",
|
||||
"\n",
|
||||
"from elasticsearch import Elasticsearch, helpers\n",
|
||||
"\n",
|
||||
"# Connect to ES instance\n",
|
||||
"es = Elasticsearch(hosts=[\"http://localhost:9200\"], timeout=60, retry_on_timeout=True)\n",
|
||||
"\n",
|
||||
"# Load HF dataset\n",
|
||||
"dataset = load_dataset(\"ag_news\", split=\"train\")[\"text\"][:50000]\n",
|
||||
"\n",
|
||||
"# Elasticsearch bulk buffer\n",
|
||||
"buffer = []\n",
|
||||
"rows = 0\n",
|
||||
"\n",
|
||||
"for x, text in enumerate(dataset):\n",
|
||||
" # Article record\n",
|
||||
" article = {\"_id\": x, \"_index\": \"articles\", \"title\": text}\n",
|
||||
"\n",
|
||||
" # Buffer article\n",
|
||||
" buffer.append(article)\n",
|
||||
"\n",
|
||||
" # Increment number of articles processed\n",
|
||||
" rows += 1\n",
|
||||
"\n",
|
||||
" # Bulk load every 1000 records\n",
|
||||
" if rows % 1000 == 0:\n",
|
||||
" helpers.bulk(es, buffer)\n",
|
||||
" buffer = []\n",
|
||||
"\n",
|
||||
" print(\"Inserted {} articles\".format(rows), end=\"\\r\")\n",
|
||||
"\n",
|
||||
"if buffer:\n",
|
||||
" helpers.bulk(es, buffer)\n",
|
||||
"\n",
|
||||
"print(\"Total articles inserted: {}\".format(rows))"
|
||||
],
|
||||
"execution_count": null,
|
||||
"outputs": [
|
||||
{
|
||||
"output_type": "stream",
|
||||
"text": [
|
||||
"Using custom data configuration default\n",
|
||||
"Reusing dataset ag_news (/root/.cache/huggingface/datasets/ag_news/default/0.0.0/bc2bcb40336ace1a0374767fc29bb0296cdaf8a6da7298436239c54d79180548)\n"
|
||||
],
|
||||
"name": "stderr"
|
||||
},
|
||||
{
|
||||
"output_type": "stream",
|
||||
"text": [
|
||||
"Total articles inserted: 50000\n"
|
||||
],
|
||||
"name": "stdout"
|
||||
}
|
||||
]
|
||||
},
|
||||
{
|
||||
"cell_type": "markdown",
|
||||
"metadata": {
|
||||
"id": "X5RO-VNwzMAo"
|
||||
},
|
||||
"source": [
|
||||
"# Query data with Elasticsearch\n",
|
||||
"\n",
|
||||
"Elasticsearch is a token-based search system. Queries and documents are parsed into tokens and the most relevant query-document matches are calculated using a scoring algorithm. The default scoring algorithm is [BM25](https://www.elastic.co/blog/practical-bm25-part-2-the-bm25-algorithm-and-its-variables). Powerful queries can be built using a [rich query syntax](https://www.elastic.co/guide/en/elasticsearch/reference/current/query-dsl-query-string-query.html#query-string-syntax) and [Query DSL](https://www.elastic.co/guide/en/elasticsearch/reference/7.10/query-dsl.html). \n",
|
||||
"\n",
|
||||
"The following section runs a query against Elasticsearch, finds the top 5 matches and returns the corresponding documents associated with each match.\n"
|
||||
]
|
||||
},
|
||||
{
|
||||
"cell_type": "code",
|
||||
"metadata": {
|
||||
"colab": {
|
||||
"base_uri": "https://localhost:8080/",
|
||||
"height": 297
|
||||
},
|
||||
"id": "ucd9mwSfFTMm",
|
||||
"outputId": "7f411947-985a-4f89-ebde-0d3f297efd56"
|
||||
},
|
||||
"source": [
|
||||
"from IPython.display import display, HTML\n",
|
||||
"\n",
|
||||
"def table(category, query, rows):\n",
|
||||
" html = \"\"\"\n",
|
||||
" <style type='text/css'>\n",
|
||||
" @import url('https://fonts.googleapis.com/css?family=Oswald&display=swap');\n",
|
||||
" table {\n",
|
||||
" border-collapse: collapse;\n",
|
||||
" width: 900px;\n",
|
||||
" }\n",
|
||||
" th, td {\n",
|
||||
" border: 1px solid #9e9e9e;\n",
|
||||
" padding: 10px;\n",
|
||||
" font: 15px Oswald;\n",
|
||||
" }\n",
|
||||
" </style>\n",
|
||||
" \"\"\"\n",
|
||||
"\n",
|
||||
" html += \"<h3>[%s] %s</h3><table><thead><tr><th>Score</th><th>Text</th></tr></thead>\" % (category, query)\n",
|
||||
" for score, text in rows:\n",
|
||||
" html += \"<tr><td>%.4f</td><td>%s</td></tr>\" % (score, text)\n",
|
||||
" html += \"</table>\"\n",
|
||||
"\n",
|
||||
" display(HTML(html))\n",
|
||||
"\n",
|
||||
"def search(query, limit):\n",
|
||||
" query = {\n",
|
||||
" \"size\": limit,\n",
|
||||
" \"query\": {\n",
|
||||
" \"query_string\": {\"query\": query}\n",
|
||||
" }\n",
|
||||
" }\n",
|
||||
"\n",
|
||||
" results = []\n",
|
||||
" for result in es.search(index=\"articles\", body=query)[\"hits\"][\"hits\"]:\n",
|
||||
" source = result[\"_source\"]\n",
|
||||
" results.append((min(result[\"_score\"], 18) / 18, source[\"title\"]))\n",
|
||||
"\n",
|
||||
" return results\n",
|
||||
"\n",
|
||||
"limit = 3\n",
|
||||
"query= \"+yankees lose\"\n",
|
||||
"table(\"Elasticsearch\", query, search(query, limit))"
|
||||
],
|
||||
"execution_count": null,
|
||||
"outputs": [
|
||||
{
|
||||
"output_type": "display_data",
|
||||
"data": {
|
||||
"text/html": [
|
||||
"\n",
|
||||
" <style type='text/css'>\n",
|
||||
" @import url('https://fonts.googleapis.com/css?family=Oswald&display=swap');\n",
|
||||
" table {\n",
|
||||
" border-collapse: collapse;\n",
|
||||
" width: 900px;\n",
|
||||
" }\n",
|
||||
" th, td {\n",
|
||||
" border: 1px solid #9e9e9e;\n",
|
||||
" padding: 10px;\n",
|
||||
" font: 15px Oswald;\n",
|
||||
" }\n",
|
||||
" </style>\n",
|
||||
" <h3>[Elasticsearch] +yankees lose</h3><table><thead><tr><th>Score</th><th>Text</th></tr></thead><tr><td>0.5817</td><td>El Duque adds to gloomy NY forecast The Yankees #39; staff infection has spread to the one man the team can #39;t afford to lose. Orlando Hernandez was scratched from last night #39;s scheduled start because </td></tr><tr><td>0.5697</td><td>Rangers Derail Red Sox The Red Sox lose for the first time in 11 games, falling to the Rangers 8-6 Saturday and missing a chance to pull within 1 1/2 games of the Yankees in the AL East.</td></tr><tr><td>0.5069</td><td>Rout leaves Yanks #39; lead at 3 Royals gain control with 10-run 5th Against a nothing-to-lose team such as the Kansas City Royals, the Yankees #39; manager wanted his team to put down the hammer early and not let baseball #39;s second worst team believe it had a chance.</td></tr></table>"
|
||||
],
|
||||
"text/plain": [
|
||||
"<IPython.core.display.HTML object>"
|
||||
]
|
||||
},
|
||||
"metadata": {
|
||||
"tags": []
|
||||
}
|
||||
}
|
||||
]
|
||||
},
|
||||
{
|
||||
"cell_type": "markdown",
|
||||
"metadata": {
|
||||
"id": "W1DkpcIob5kt"
|
||||
},
|
||||
"source": [
|
||||
"The table above shows the results for the query `+yankees lose`. This query requires the token `yankees`. The search doesn't understand the semantic meaning of the query. It returns the most relevant results with those two tokens.\n",
|
||||
"\n",
|
||||
"We can see in this case, the results aren't capturing the meaning of the search. Let's try adding semantic similarity to the search!"
|
||||
]
|
||||
},
|
||||
{
|
||||
"cell_type": "markdown",
|
||||
"metadata": {
|
||||
"id": "hMro47KedzJq"
|
||||
},
|
||||
"source": [
|
||||
"# Ranking search results with txtai\n",
|
||||
"\n",
|
||||
"txtai has a similarity module that computes the similarity between a query and a list of strings. Of course, txtai can also build a full index as shown in the previous notebooks but in this case we'll just use the ad-hoc similarity function.\n",
|
||||
"\n",
|
||||
"The code below creates a Similarity instance and defines a ranking function to order search results based on the computed similarity.\n",
|
||||
"\n",
|
||||
"`ranksearch` queries Elasticsearch for a larger set of results, ranks the results using the similarity instance and returns the top n results. "
|
||||
]
|
||||
},
|
||||
{
|
||||
"cell_type": "code",
|
||||
"metadata": {
|
||||
"id": "RUOj5zhFFK8N"
|
||||
},
|
||||
"source": [
|
||||
"%%capture\n",
|
||||
"from txtai.pipeline import Similarity\n",
|
||||
"\n",
|
||||
"def ranksearch(query, limit):\n",
|
||||
" results = [text for _, text in search(query, limit * 10)]\n",
|
||||
" return [(score, results[x]) for x, score in similarity(query, results)][:limit]\n",
|
||||
"\n",
|
||||
"# Create similarity instance for re-ranking\n",
|
||||
"similarity = Similarity(\"valhalla/distilbart-mnli-12-3\")"
|
||||
],
|
||||
"execution_count": null,
|
||||
"outputs": []
|
||||
},
|
||||
{
|
||||
"cell_type": "markdown",
|
||||
"metadata": {
|
||||
"id": "UMFuv5-Hedfc"
|
||||
},
|
||||
"source": [
|
||||
"Now let's re-run the previous search."
|
||||
]
|
||||
},
|
||||
{
|
||||
"cell_type": "code",
|
||||
"metadata": {
|
||||
"colab": {
|
||||
"base_uri": "https://localhost:8080/",
|
||||
"height": 297
|
||||
},
|
||||
"id": "3jJI9OxU0dZk",
|
||||
"outputId": "5e415dad-3a40-4ec0-a9a0-a3628501fd26"
|
||||
},
|
||||
"source": [
|
||||
"# Run the search\n",
|
||||
"table(\"Elasticsearch + txtai\", query, ranksearch(query, limit))"
|
||||
],
|
||||
"execution_count": null,
|
||||
"outputs": [
|
||||
{
|
||||
"output_type": "display_data",
|
||||
"data": {
|
||||
"text/html": [
|
||||
"\n",
|
||||
" <style type='text/css'>\n",
|
||||
" @import url('https://fonts.googleapis.com/css?family=Oswald&display=swap');\n",
|
||||
" table {\n",
|
||||
" border-collapse: collapse;\n",
|
||||
" width: 900px;\n",
|
||||
" }\n",
|
||||
" th, td {\n",
|
||||
" border: 1px solid #9e9e9e;\n",
|
||||
" padding: 10px;\n",
|
||||
" font: 15px Oswald;\n",
|
||||
" }\n",
|
||||
" </style>\n",
|
||||
" <h3>[Elasticsearch + txtai] +yankees lose</h3><table><thead><tr><th>Score</th><th>Text</th></tr></thead><tr><td>0.9929</td><td>Ouch! Yankees hit new low INDIANS 22, YANKEES 0---At New York, Omar Vizquel went 6-for-7 to tie the American League record for hits as Cleveland handed the Yankees the largest loss in their history last night.</td></tr><tr><td>0.9874</td><td>Vazquez and Yankees Buckle Early Because Javier Vazquez fizzled while Brad Radke flourished, the Yankees sustained their first regular-season defeat by the Minnesota Twins since 2001.</td></tr><tr><td>0.9542</td><td>Slide of the Yankees: Pinstripes Punished George Steinbrenner watched from his box as his Yankees suffered the most one-sided loss in the franchise's long history.</td></tr></table>"
|
||||
],
|
||||
"text/plain": [
|
||||
"<IPython.core.display.HTML object>"
|
||||
]
|
||||
},
|
||||
"metadata": {
|
||||
"tags": []
|
||||
}
|
||||
}
|
||||
]
|
||||
},
|
||||
{
|
||||
"cell_type": "markdown",
|
||||
"metadata": {
|
||||
"id": "RXB2PaDZfd8o"
|
||||
},
|
||||
"source": [
|
||||
"The results above do a much better job of finding results semantically similar in meaning to the query. Instead of just finding matches with `yankees` and `lose`, it finds matches where the `yankees lose`. \n",
|
||||
"\n",
|
||||
"This combination is effective and powerful. It takes advantage of the high performance of Elasticsearch while adding a semantic search capability. We may already have a large Elasticsearch cluster with TBs (or PBs)+ of data and years of engineering investment that solves most use cases. Semantically ranking search results is a practical approach."
|
||||
]
|
||||
},
|
||||
{
|
||||
"cell_type": "markdown",
|
||||
"metadata": {
|
||||
"id": "XBVL56fsRI86"
|
||||
},
|
||||
"source": [
|
||||
"# More examples\n",
|
||||
"\n",
|
||||
"Now for some more examples comparing the results from Elasticsearch vs Elasticsearch + txtai."
|
||||
]
|
||||
},
|
||||
{
|
||||
"cell_type": "code",
|
||||
"metadata": {
|
||||
"id": "7IHS38SERRpQ",
|
||||
"colab": {
|
||||
"base_uri": "https://localhost:8080/",
|
||||
"height": 1000
|
||||
},
|
||||
"outputId": "e82d15ef-ed15-40f5-ed90-f4dd865b8b3c"
|
||||
},
|
||||
"source": [
|
||||
"for query in [\"good news +economy\", \"bad news +economy\"]:\n",
|
||||
" table(\"Elasticsearch\", query, search(query, limit))\n",
|
||||
" table(\"Elasticsearch + txtai\", query, ranksearch(query, limit))"
|
||||
],
|
||||
"execution_count": null,
|
||||
"outputs": [
|
||||
{
|
||||
"output_type": "display_data",
|
||||
"data": {
|
||||
"text/html": [
|
||||
"\n",
|
||||
" <style type='text/css'>\n",
|
||||
" @import url('https://fonts.googleapis.com/css?family=Oswald&display=swap');\n",
|
||||
" table {\n",
|
||||
" border-collapse: collapse;\n",
|
||||
" width: 900px;\n",
|
||||
" }\n",
|
||||
" th, td {\n",
|
||||
" border: 1px solid #9e9e9e;\n",
|
||||
" padding: 10px;\n",
|
||||
" font: 15px Oswald;\n",
|
||||
" }\n",
|
||||
" </style>\n",
|
||||
" <h3>[Elasticsearch] good news +economy</h3><table><thead><tr><th>Score</th><th>Text</th></tr></thead><tr><td>0.8756</td><td>Surprise drop US wholesale prices is mixed news for economy (AFP) AFP - A surprise drop in US wholesale prices in August showed inflation apparently in check, but analysts said this was good and bad news for the US economy.</td></tr><tr><td>0.7379</td><td>China investment slows Good news for officials who are trying to cool an overheated economy; austerity measures to remain. BEIJING (Reuters) - China reported a marked slowdown in investment and money supply growth Monday, but stubbornly </td></tr><tr><td>0.7145</td><td>Spending Rebounds, Good News for Growth WASHINGTON (Reuters) - U.S. consumer spending rebounded sharply July, government data showed on Monday, erasing the disappointment of June and bolstering hopes that the U.S. economy has recovered from its recent soft spot.</td></tr></table>"
|
||||
],
|
||||
"text/plain": [
|
||||
"<IPython.core.display.HTML object>"
|
||||
]
|
||||
},
|
||||
"metadata": {
|
||||
"tags": []
|
||||
}
|
||||
},
|
||||
{
|
||||
"output_type": "display_data",
|
||||
"data": {
|
||||
"text/html": [
|
||||
"\n",
|
||||
" <style type='text/css'>\n",
|
||||
" @import url('https://fonts.googleapis.com/css?family=Oswald&display=swap');\n",
|
||||
" table {\n",
|
||||
" border-collapse: collapse;\n",
|
||||
" width: 900px;\n",
|
||||
" }\n",
|
||||
" th, td {\n",
|
||||
" border: 1px solid #9e9e9e;\n",
|
||||
" padding: 10px;\n",
|
||||
" font: 15px Oswald;\n",
|
||||
" }\n",
|
||||
" </style>\n",
|
||||
" <h3>[Elasticsearch + txtai] good news +economy</h3><table><thead><tr><th>Score</th><th>Text</th></tr></thead><tr><td>0.9996</td><td>Spending Rebounds, Good News for Growth WASHINGTON (Reuters) - U.S. consumer spending rebounded sharply in July, the government said on Monday, erasing the disappointment of June and bolstering hopes that the U.S. economy has recovered from its recent soft spot.</td></tr><tr><td>0.9996</td><td>Spending Rebounds, Good News for Growth WASHINGTON (Reuters) - U.S. consumer spending rebounded sharply July, government data showed on Monday, erasing the disappointment of June and bolstering hopes that the U.S. economy has recovered from its recent soft spot.</td></tr><tr><td>0.9993</td><td>Home building surges Housing construction in August jumped to its highest level in five months, a dose of encouraging news for the economy #39;s expansion.</td></tr></table>"
|
||||
],
|
||||
"text/plain": [
|
||||
"<IPython.core.display.HTML object>"
|
||||
]
|
||||
},
|
||||
"metadata": {
|
||||
"tags": []
|
||||
}
|
||||
},
|
||||
{
|
||||
"output_type": "display_data",
|
||||
"data": {
|
||||
"text/html": [
|
||||
"\n",
|
||||
" <style type='text/css'>\n",
|
||||
" @import url('https://fonts.googleapis.com/css?family=Oswald&display=swap');\n",
|
||||
" table {\n",
|
||||
" border-collapse: collapse;\n",
|
||||
" width: 900px;\n",
|
||||
" }\n",
|
||||
" th, td {\n",
|
||||
" border: 1px solid #9e9e9e;\n",
|
||||
" padding: 10px;\n",
|
||||
" font: 15px Oswald;\n",
|
||||
" }\n",
|
||||
" </style>\n",
|
||||
" <h3>[Elasticsearch] bad news +economy</h3><table><thead><tr><th>Score</th><th>Text</th></tr></thead><tr><td>0.9228</td><td>Surprise drop US wholesale prices is mixed news for economy (AFP) AFP - A surprise drop in US wholesale prices in August showed inflation apparently in check, but analysts said this was good and bad news for the US economy.</td></tr><tr><td>0.6405</td><td>Field Poll: Californians liking economy Bee Staff Writer. Californians are slowly growing more optimistic about the health of the economy, but a majority still feels the state is in bad economic times, according to a new Field Poll.</td></tr><tr><td>0.6188</td><td>ADB says China should raise rates to cool economy China should raise interest rates to cool the economy and prevent a future buildup of bad loans in the banking system, the Asian Development Bank #39;s (ADB) Bei-jing representative Bruce Murray said.</td></tr></table>"
|
||||
],
|
||||
"text/plain": [
|
||||
"<IPython.core.display.HTML object>"
|
||||
]
|
||||
},
|
||||
"metadata": {
|
||||
"tags": []
|
||||
}
|
||||
},
|
||||
{
|
||||
"output_type": "display_data",
|
||||
"data": {
|
||||
"text/html": [
|
||||
"\n",
|
||||
" <style type='text/css'>\n",
|
||||
" @import url('https://fonts.googleapis.com/css?family=Oswald&display=swap');\n",
|
||||
" table {\n",
|
||||
" border-collapse: collapse;\n",
|
||||
" width: 900px;\n",
|
||||
" }\n",
|
||||
" th, td {\n",
|
||||
" border: 1px solid #9e9e9e;\n",
|
||||
" padding: 10px;\n",
|
||||
" font: 15px Oswald;\n",
|
||||
" }\n",
|
||||
" </style>\n",
|
||||
" <h3>[Elasticsearch + txtai] bad news +economy</h3><table><thead><tr><th>Score</th><th>Text</th></tr></thead><tr><td>0.9977</td><td>Aging society hits Japan #39;s economy Japan #39;s economy will be the most severely affected among industrialized nations by population aging, Kyodo News said Thursday.</td></tr><tr><td>0.9963</td><td>Funds: Fund Mergers Can Hurt Investors (Reuters) Reuters - Mergers and acquisitions have\\played an enormous role in the U.S. economy during the past\\several decades, but sometimes the results have been bad for\\consumers. Similarly, consolidation in the mutual fund\\business has sometimes hurt fund investors.</td></tr><tr><td>0.9958</td><td>Signs of listless economy persist In a sign of persistent weakness in the US economy, a widely watched measure of business activity declined in August for the third consecutive month.</td></tr></table>"
|
||||
],
|
||||
"text/plain": [
|
||||
"<IPython.core.display.HTML object>"
|
||||
]
|
||||
},
|
||||
"metadata": {
|
||||
"tags": []
|
||||
}
|
||||
}
|
||||
]
|
||||
},
|
||||
{
|
||||
"cell_type": "markdown",
|
||||
"metadata": {
|
||||
"id": "h-Bk3KLjZMpF"
|
||||
},
|
||||
"source": [
|
||||
"Once again while Elasticsearch usually returns quality results, occasionally it will match results that aren't semantically relevant. The power of semantic search is that not only will it find direct matches but matches with the same meaning. "
|
||||
]
|
||||
}
|
||||
]
|
||||
}
|
||||
+31
-53
@@ -3,8 +3,9 @@
|
||||
"nbformat_minor": 0,
|
||||
"metadata": {
|
||||
"colab": {
|
||||
"name": "02 - Extractive QA with txtai",
|
||||
"provenance": []
|
||||
"name": "05 - Extractive QA with txtai",
|
||||
"provenance": [],
|
||||
"collapsed_sections": []
|
||||
},
|
||||
"kernelspec": {
|
||||
"name": "python3",
|
||||
@@ -15,46 +16,41 @@
|
||||
{
|
||||
"cell_type": "markdown",
|
||||
"metadata": {
|
||||
"id": "vwELCooy4ljr",
|
||||
"colab_type": "text"
|
||||
"id": "vwELCooy4ljr"
|
||||
},
|
||||
"source": [
|
||||
"# Part 2: Extractive QA with txtai\n",
|
||||
"# Extractive QA with txtai\n",
|
||||
"\n",
|
||||
"In Part 1, we gave a general overview of txtai, the backing technology and examples of how to use it for similarity searches. This notebook builds on that and extends to building extractive question-answering systems."
|
||||
"In Parts 1 through 4, we gave a general overview of txtai, the backing technology and examples of how to use it for similarity searches. This notebook builds on that and extends to building extractive question-answering systems."
|
||||
]
|
||||
},
|
||||
{
|
||||
"cell_type": "markdown",
|
||||
"metadata": {
|
||||
"id": "ew7orE2O441o",
|
||||
"colab_type": "text"
|
||||
"id": "ew7orE2O441o"
|
||||
},
|
||||
"source": [
|
||||
"# Install dependencies\n",
|
||||
"\n",
|
||||
"Install txtai and all dependencies"
|
||||
"Install `txtai` and all dependencies."
|
||||
]
|
||||
},
|
||||
{
|
||||
"cell_type": "code",
|
||||
"metadata": {
|
||||
"id": "LPQTb25tASIG",
|
||||
"colab_type": "code",
|
||||
"colab": {}
|
||||
"id": "LPQTb25tASIG"
|
||||
},
|
||||
"source": [
|
||||
"%%capture\n",
|
||||
"!pip install git+https://github.com/neuml/txtai"
|
||||
],
|
||||
"execution_count": 1,
|
||||
"execution_count": null,
|
||||
"outputs": []
|
||||
},
|
||||
{
|
||||
"cell_type": "markdown",
|
||||
"metadata": {
|
||||
"id": "_YnqorRKAbLu",
|
||||
"colab_type": "text"
|
||||
"id": "_YnqorRKAbLu"
|
||||
},
|
||||
"source": [
|
||||
"# Create an Embeddings and Extractor instances\n",
|
||||
@@ -69,9 +65,7 @@
|
||||
{
|
||||
"cell_type": "code",
|
||||
"metadata": {
|
||||
"id": "OUc9gqTyAYnm",
|
||||
"colab_type": "code",
|
||||
"colab": {}
|
||||
"id": "OUc9gqTyAYnm"
|
||||
},
|
||||
"source": [
|
||||
"%%capture\n",
|
||||
@@ -80,45 +74,40 @@
|
||||
"from txtai.extractor import Extractor\n",
|
||||
"\n",
|
||||
"# Create embeddings model, backed by sentence-transformers & transformers\n",
|
||||
"embeddings = Embeddings({\"method\": \"transformers\", \"path\": \"sentence-transformers/bert-base-nli-mean-tokens\"})\n",
|
||||
"embeddings = Embeddings({\"path\": \"sentence-transformers/nli-mpnet-base-v2\"})\n",
|
||||
"\n",
|
||||
"# Create extractor instance\n",
|
||||
"extractor = Extractor(embeddings, \"distilbert-base-cased-distilled-squad\")"
|
||||
],
|
||||
"execution_count": 2,
|
||||
"execution_count": null,
|
||||
"outputs": []
|
||||
},
|
||||
{
|
||||
"cell_type": "code",
|
||||
"metadata": {
|
||||
"id": "4X5z3UjnAGe7",
|
||||
"colab_type": "code",
|
||||
"colab": {
|
||||
"base_uri": "https://localhost:8080/",
|
||||
"height": 330
|
||||
"base_uri": "https://localhost:8080/"
|
||||
},
|
||||
"outputId": "4e376662-57d1-4841-eeb5-622aaaf286c3"
|
||||
"outputId": "131cfed3-e6f0-4cee-dc66-f242cd1a5bf7"
|
||||
},
|
||||
"source": [
|
||||
"sections = [\"Giants hit 3 HRs to down Dodgers\",\n",
|
||||
" \"Giants 5 Dodgers 4 final\",\n",
|
||||
" \"Dodgers drop Game 2 against the Giants, 5-4\",\n",
|
||||
" \"Blue Jays 2 Red Sox 1 final\",\n",
|
||||
" \"Red Sox lost to the Blue Jays, 2-1\",\n",
|
||||
" \"Blue Jays at Red Sox is over. Score: 2-1\",\n",
|
||||
" \"Phillies win over the Braves, 5-0\",\n",
|
||||
" \"Phillies 5 Braves 0 final\",\n",
|
||||
" \"Final: Braves lose to the Phillies in the series opener, 5-0\",\n",
|
||||
" \"Final score: Flyers 4 Lightning 1\",\n",
|
||||
" \"Flyers 4 Lightning 1 final\",\n",
|
||||
" \"Flyers win 4-1\"]\n",
|
||||
"\n",
|
||||
"# Add unique id to each section to assist with qa extraction\n",
|
||||
"sections = [(uid, section) for uid, section in enumerate(sections)]\n",
|
||||
"data = [\"Giants hit 3 HRs to down Dodgers\",\n",
|
||||
" \"Giants 5 Dodgers 4 final\",\n",
|
||||
" \"Dodgers drop Game 2 against the Giants, 5-4\",\n",
|
||||
" \"Blue Jays beat Red Sox final score 2-1\",\n",
|
||||
" \"Red Sox lost to the Blue Jays, 2-1\",\n",
|
||||
" \"Blue Jays at Red Sox is over. Score: 2-1\",\n",
|
||||
" \"Phillies win over the Braves, 5-0\",\n",
|
||||
" \"Phillies 5 Braves 0 final\",\n",
|
||||
" \"Final: Braves lose to the Phillies in the series opener, 5-0\",\n",
|
||||
" \"Lightning goaltender pulled, lose to Flyers 4-1\",\n",
|
||||
" \"Flyers 4 Lightning 1 final\",\n",
|
||||
" \"Flyers win 4-1\"]\n",
|
||||
"\n",
|
||||
"questions = [\"What team won the game?\", \"What was score?\"]\n",
|
||||
"\n",
|
||||
"execute = lambda query: extractor(sections, [(question, query, question, False) for question in questions])\n",
|
||||
"execute = lambda query: extractor([(question, query, question, False) for question in questions], data)\n",
|
||||
"\n",
|
||||
"for query in [\"Red Sox - Blue Jays\", \"Phillies - Braves\", \"Dodgers - Giants\", \"Flyers - Lightning\"]:\n",
|
||||
" print(\"----\", query, \"----\")\n",
|
||||
@@ -130,9 +119,9 @@
|
||||
"question = \"What hockey team won?\"\n",
|
||||
"\n",
|
||||
"print(\"----\", question, \"----\")\n",
|
||||
"print(extractor(sections, [(question, question, question, False)]))"
|
||||
"print(extractor([(question, question, question, False)], data))"
|
||||
],
|
||||
"execution_count": 3,
|
||||
"execution_count": null,
|
||||
"outputs": [
|
||||
{
|
||||
"output_type": "stream",
|
||||
@@ -159,17 +148,6 @@
|
||||
"name": "stdout"
|
||||
}
|
||||
]
|
||||
},
|
||||
{
|
||||
"cell_type": "markdown",
|
||||
"metadata": {
|
||||
"id": "k-9gHzrp8ZXA",
|
||||
"colab_type": "text"
|
||||
},
|
||||
"source": [
|
||||
"# Next\n",
|
||||
"In part 3 of this series, we'll look at how to use txtai on larger datasets and explore using word embeddings vs transformer embeddings"
|
||||
]
|
||||
}
|
||||
]
|
||||
}
|
||||
+80
-99
@@ -3,8 +3,9 @@
|
||||
"nbformat_minor": 0,
|
||||
"metadata": {
|
||||
"colab": {
|
||||
"name": "04 - Extractive QA with Elasticsearch",
|
||||
"provenance": []
|
||||
"name": "06 - Extractive QA with Elasticsearch",
|
||||
"provenance": [],
|
||||
"collapsed_sections": []
|
||||
},
|
||||
"kernelspec": {
|
||||
"name": "python3",
|
||||
@@ -15,33 +16,29 @@
|
||||
{
|
||||
"cell_type": "markdown",
|
||||
"metadata": {
|
||||
"id": "zzZbP0LM6m5z",
|
||||
"colab_type": "text"
|
||||
"id": "zzZbP0LM6m5z"
|
||||
},
|
||||
"source": [
|
||||
"# Extractive QA with Elasticsearch\n",
|
||||
"\n",
|
||||
"txtai is datastore agnostic, the library analyzes sets of text. The following example shows how extractive question-answering can be added on top of an Elasticesearch system."
|
||||
"txtai is datastore agnostic, the library analyzes sets of text. The following example shows how extractive question-answering can be added on top of an Elasticsearch system."
|
||||
]
|
||||
},
|
||||
{
|
||||
"cell_type": "markdown",
|
||||
"metadata": {
|
||||
"id": "xk7t5Jcd6reO",
|
||||
"colab_type": "text"
|
||||
"id": "xk7t5Jcd6reO"
|
||||
},
|
||||
"source": [
|
||||
"# Install txtai and Elasticsearch\n",
|
||||
"# Install dependencies\n",
|
||||
"\n",
|
||||
"Install txtai and Elasticsearch. Start an instance of Elasticsearch directly within this notebook. "
|
||||
"Install `txtai` and `Elasticsearch`."
|
||||
]
|
||||
},
|
||||
{
|
||||
"cell_type": "code",
|
||||
"metadata": {
|
||||
"id": "0y1UA4-q-YdA",
|
||||
"colab_type": "code",
|
||||
"colab": {}
|
||||
"id": "0y1UA4-q-YdA"
|
||||
},
|
||||
"source": [
|
||||
"%%capture\n",
|
||||
@@ -50,92 +47,72 @@
|
||||
"!pip install git+https://github.com/neuml/txtai elasticsearch\n",
|
||||
"\n",
|
||||
"# Download and extract elasticsearch\n",
|
||||
"!wget https://artifacts.elastic.co/downloads/elasticsearch/elasticsearch-7.8.1-linux-x86_64.tar.gz\n",
|
||||
"!tar -xzf elasticsearch-7.8.1-linux-x86_64.tar.gz\n",
|
||||
"!chown -R daemon:daemon elasticsearch-7.8.1"
|
||||
"!wget https://artifacts.elastic.co/downloads/elasticsearch/elasticsearch-7.10.1-linux-x86_64.tar.gz\n",
|
||||
"!tar -xzf elasticsearch-7.10.1-linux-x86_64.tar.gz\n",
|
||||
"!chown -R daemon:daemon elasticsearch-7.10.1"
|
||||
],
|
||||
"execution_count": 1,
|
||||
"outputs": []
|
||||
},
|
||||
{
|
||||
"cell_type": "code",
|
||||
"metadata": {
|
||||
"id": "3ZfJeWbM6wmj",
|
||||
"colab_type": "code",
|
||||
"colab": {}
|
||||
},
|
||||
"source": [
|
||||
"import os\n",
|
||||
"from subprocess import Popen, PIPE, STDOUT\n",
|
||||
"\n",
|
||||
"# Start and wait for server\n",
|
||||
"server = Popen(['elasticsearch-7.8.1/bin/elasticsearch'], stdout=PIPE, stderr=STDOUT, preexec_fn=lambda: os.setuid(1))\n",
|
||||
"!sleep 30"
|
||||
],
|
||||
"execution_count": 2,
|
||||
"execution_count": null,
|
||||
"outputs": []
|
||||
},
|
||||
{
|
||||
"cell_type": "markdown",
|
||||
"metadata": {
|
||||
"id": "TWEn4w68-D1y",
|
||||
"colab_type": "text"
|
||||
"id": "nKWz-C5gCJy8"
|
||||
},
|
||||
"source": [
|
||||
"Start an instance of Elasticsearch directly within this notebook. "
|
||||
]
|
||||
},
|
||||
{
|
||||
"cell_type": "code",
|
||||
"metadata": {
|
||||
"id": "3ZfJeWbM6wmj"
|
||||
},
|
||||
"source": [
|
||||
"import os\n",
|
||||
"from subprocess import Popen, PIPE, STDOUT\n",
|
||||
"\n",
|
||||
"# If issues are encountered with this section, ES can be manually started as follows:\n",
|
||||
"# ./elasticsearch-7.10.1/bin/elasticsearch\n",
|
||||
"\n",
|
||||
"# Start and wait for server\n",
|
||||
"server = Popen(['elasticsearch-7.10.1/bin/elasticsearch'], stdout=PIPE, stderr=STDOUT, preexec_fn=lambda: os.setuid(1))\n",
|
||||
"!sleep 30"
|
||||
],
|
||||
"execution_count": null,
|
||||
"outputs": []
|
||||
},
|
||||
{
|
||||
"cell_type": "markdown",
|
||||
"metadata": {
|
||||
"id": "TWEn4w68-D1y"
|
||||
},
|
||||
"source": [
|
||||
"# Download data\n",
|
||||
"\n",
|
||||
"This example is going to work off a subset of the [CORD-19](https://www.semanticscholar.org/cord19) dataset. COVID-19 Open Research Dataset (CORD-19) is a free resource of scholarly articles, aggregated by a coalition of leading research groups, covering COVID-19 and the coronavirus family of viruses.\n",
|
||||
"\n",
|
||||
"The following download is SQLite database with a subject of CORD-19, generated from a [Kaggle notebook](https://www.kaggle.com/davidmezzetti/cord-19-slim/output). More information on this data format, can be found in the [CORD-19 Analysis](https://www.kaggle.com/davidmezzetti/cord-19-analysis-with-sentence-embeddings) notebook."
|
||||
"The following download is a SQLite database generated from a [Kaggle notebook](https://www.kaggle.com/davidmezzetti/cord-19-slim/output). More information on this data format, can be found in the [CORD-19 Analysis](https://www.kaggle.com/davidmezzetti/cord-19-analysis-with-sentence-embeddings) notebook."
|
||||
]
|
||||
},
|
||||
{
|
||||
"cell_type": "code",
|
||||
"metadata": {
|
||||
"id": "8tVrIqSq-KBa",
|
||||
"colab_type": "code",
|
||||
"colab": {
|
||||
"base_uri": "https://localhost:8080/",
|
||||
"height": 315
|
||||
},
|
||||
"outputId": "d4b8b54d-1ede-45c1-adef-94bfa9a104cf"
|
||||
"id": "8tVrIqSq-KBa"
|
||||
},
|
||||
"source": [
|
||||
"%%capture\n",
|
||||
"!wget https://github.com/neuml/txtai/releases/download/v1.1.0/tests.gz\n",
|
||||
"!gunzip tests.gz\n",
|
||||
"!mv tests articles.sqlite"
|
||||
],
|
||||
"execution_count": 3,
|
||||
"outputs": [
|
||||
{
|
||||
"output_type": "stream",
|
||||
"text": [
|
||||
"--2020-08-25 01:56:54-- https://github.com/neuml/txtai/releases/download/v1.1.0/tests.gz\n",
|
||||
"Resolving github.com (github.com)... 140.82.112.4\n",
|
||||
"Connecting to github.com (github.com)|140.82.112.4|:443... connected.\n",
|
||||
"HTTP request sent, awaiting response... 302 Found\n",
|
||||
"Location: https://github-production-release-asset-2e65be.s3.amazonaws.com/286301447/080d8800-e653-11ea-8d02-c0c858a09e7a?X-Amz-Algorithm=AWS4-HMAC-SHA256&X-Amz-Credential=AKIAIWNJYAX4CSVEH53A%2F20200825%2Fus-east-1%2Fs3%2Faws4_request&X-Amz-Date=20200825T015604Z&X-Amz-Expires=300&X-Amz-Signature=e135dc0b8f0d7774019d6525aad528b99160aff4007b2a539330c090c29ef9b5&X-Amz-SignedHeaders=host&actor_id=0&repo_id=286301447&response-content-disposition=attachment%3B%20filename%3Dtests.gz&response-content-type=application%2Foctet-stream [following]\n",
|
||||
"--2020-08-25 01:56:54-- https://github-production-release-asset-2e65be.s3.amazonaws.com/286301447/080d8800-e653-11ea-8d02-c0c858a09e7a?X-Amz-Algorithm=AWS4-HMAC-SHA256&X-Amz-Credential=AKIAIWNJYAX4CSVEH53A%2F20200825%2Fus-east-1%2Fs3%2Faws4_request&X-Amz-Date=20200825T015604Z&X-Amz-Expires=300&X-Amz-Signature=e135dc0b8f0d7774019d6525aad528b99160aff4007b2a539330c090c29ef9b5&X-Amz-SignedHeaders=host&actor_id=0&repo_id=286301447&response-content-disposition=attachment%3B%20filename%3Dtests.gz&response-content-type=application%2Foctet-stream\n",
|
||||
"Resolving github-production-release-asset-2e65be.s3.amazonaws.com (github-production-release-asset-2e65be.s3.amazonaws.com)... 52.216.140.68\n",
|
||||
"Connecting to github-production-release-asset-2e65be.s3.amazonaws.com (github-production-release-asset-2e65be.s3.amazonaws.com)|52.216.140.68|:443... connected.\n",
|
||||
"HTTP request sent, awaiting response... 200 OK\n",
|
||||
"Length: 2456199 (2.3M) [application/octet-stream]\n",
|
||||
"Saving to: ‘tests.gz’\n",
|
||||
"\n",
|
||||
"tests.gz 100%[===================>] 2.34M 11.2MB/s in 0.2s \n",
|
||||
"\n",
|
||||
"2020-08-25 01:56:55 (11.2 MB/s) - ‘tests.gz’ saved [2456199/2456199]\n",
|
||||
"\n"
|
||||
],
|
||||
"name": "stdout"
|
||||
}
|
||||
]
|
||||
"execution_count": null,
|
||||
"outputs": []
|
||||
},
|
||||
{
|
||||
"cell_type": "markdown",
|
||||
"metadata": {
|
||||
"id": "hSWFzkCn61tM",
|
||||
"colab_type": "text"
|
||||
"id": "hSWFzkCn61tM"
|
||||
},
|
||||
"source": [
|
||||
"# Load data into Elasticsearch\n",
|
||||
@@ -147,12 +124,10 @@
|
||||
"cell_type": "code",
|
||||
"metadata": {
|
||||
"id": "So-OBvUT61QD",
|
||||
"colab_type": "code",
|
||||
"colab": {
|
||||
"base_uri": "https://localhost:8080/",
|
||||
"height": 34
|
||||
"base_uri": "https://localhost:8080/"
|
||||
},
|
||||
"outputId": "c4d447fd-4103-4cb6-d16e-83c84fc1b689"
|
||||
"outputId": "c2968c65-3d8c-436d-9377-4ea44b28f512"
|
||||
},
|
||||
"source": [
|
||||
"import sqlite3\n",
|
||||
@@ -203,7 +178,7 @@
|
||||
"\n",
|
||||
"print(\"Total articles inserted: {}\".format(rows))\n"
|
||||
],
|
||||
"execution_count": 4,
|
||||
"execution_count": null,
|
||||
"outputs": [
|
||||
{
|
||||
"output_type": "stream",
|
||||
@@ -217,8 +192,7 @@
|
||||
{
|
||||
"cell_type": "markdown",
|
||||
"metadata": {
|
||||
"id": "X5RO-VNwzMAo",
|
||||
"colab_type": "text"
|
||||
"id": "X5RO-VNwzMAo"
|
||||
},
|
||||
"source": [
|
||||
"# Query data\n",
|
||||
@@ -231,12 +205,11 @@
|
||||
"cell_type": "code",
|
||||
"metadata": {
|
||||
"id": "ucd9mwSfFTMm",
|
||||
"colab_type": "code",
|
||||
"colab": {
|
||||
"base_uri": "https://localhost:8080/",
|
||||
"height": 293
|
||||
},
|
||||
"outputId": "582b3aa1-9eeb-431b-b7d1-509b7c3c28f2"
|
||||
"outputId": "93b9d0e5-3279-4710-c640-678b50f407e8"
|
||||
},
|
||||
"source": [
|
||||
"import pandas as pd\n",
|
||||
@@ -262,7 +235,7 @@
|
||||
"\n",
|
||||
"display(HTML(df.to_html(index=False)))"
|
||||
],
|
||||
"execution_count": 5,
|
||||
"execution_count": null,
|
||||
"outputs": [
|
||||
{
|
||||
"output_type": "display_data",
|
||||
@@ -321,12 +294,21 @@
|
||||
}
|
||||
]
|
||||
},
|
||||
{
|
||||
"cell_type": "markdown",
|
||||
"metadata": {
|
||||
"id": "ylxOKji1-9_K"
|
||||
},
|
||||
"source": [
|
||||
"# Derive columns with Extractive QA\n",
|
||||
"\n",
|
||||
"The next section uses Extractive QA to derive additional columns. For each article, the full text is retrieved and a series of questions are asked of the document. The answers are added as a derived column per article."
|
||||
]
|
||||
},
|
||||
{
|
||||
"cell_type": "code",
|
||||
"metadata": {
|
||||
"id": "mwBTrCkcOM_H",
|
||||
"colab_type": "code",
|
||||
"colab": {}
|
||||
"id": "mwBTrCkcOM_H"
|
||||
},
|
||||
"source": [
|
||||
"%%capture\n",
|
||||
@@ -334,24 +316,23 @@
|
||||
"from txtai.extractor import Extractor\n",
|
||||
"\n",
|
||||
"# Create embeddings model, backed by sentence-transformers & transformers\n",
|
||||
"embeddings = Embeddings({\"method\": \"transformers\", \"path\": \"sentence-transformers/bert-base-nli-stsb-mean-tokens\"})\n",
|
||||
"embeddings = Embeddings({\"path\": \"sentence-transformers/nli-mpnet-base-v2\"})\n",
|
||||
"\n",
|
||||
"# Create extractor instance using qa model designed for the CORD-19 dataset\n",
|
||||
"extractor = Extractor(embeddings, \"NeuML/bert-small-cord19qa\")"
|
||||
],
|
||||
"execution_count": 6,
|
||||
"execution_count": null,
|
||||
"outputs": []
|
||||
},
|
||||
{
|
||||
"cell_type": "code",
|
||||
"metadata": {
|
||||
"id": "Yv75Lh-cOpL9",
|
||||
"colab_type": "code",
|
||||
"colab": {
|
||||
"base_uri": "https://localhost:8080/",
|
||||
"height": 328
|
||||
},
|
||||
"outputId": "6d1c81fc-2da4-480c-9799-061297fca8a8"
|
||||
"outputId": "c286f687-dfdb-44c3-f317-6295e2da05b4"
|
||||
},
|
||||
"source": [
|
||||
"document = {\n",
|
||||
@@ -371,10 +352,10 @@
|
||||
"\n",
|
||||
" for result in es.search(index=\"articles\", body=search)[\"hits\"][\"hits\"]:\n",
|
||||
" source = result[\"_source\"]\n",
|
||||
" sid, name, text = source[\"id\"], source[\"name\"], source[\"text\"]\n",
|
||||
" name, text = source[\"name\"], source[\"text\"]\n",
|
||||
"\n",
|
||||
" if not name or not re.search(r\"background|(?<!.*?results.*?)discussion|introduction|reference\", name.lower()):\n",
|
||||
" rows.append((sid, text))\n",
|
||||
" rows.append(text)\n",
|
||||
" \n",
|
||||
" return rows\n",
|
||||
"\n",
|
||||
@@ -383,8 +364,8 @@
|
||||
" source = result[\"_source\"]\n",
|
||||
"\n",
|
||||
" # Use QA extractor to derive additional columns\n",
|
||||
" answers = extractor(sections(source[\"article\"]), [(\"Risk factors\", \"risk factor\", \"What are names of risk factors?\", False),\n",
|
||||
" (\"Locations\", \"city country state\", \"What are names of locations?\", False)])\n",
|
||||
" answers = extractor([(\"Risk factors\", \"risk factor\", \"What are names of risk factors?\", False),\n",
|
||||
" (\"Locations\", \"city country state\", \"What are names of locations?\", False)], sections(source[\"article\"]))\n",
|
||||
"\n",
|
||||
" results.append((source[\"title\"], source[\"published\"], source[\"reference\"], source[\"text\"]) + tuple([answer[1] for answer in answers]))\n",
|
||||
"\n",
|
||||
@@ -392,7 +373,7 @@
|
||||
"\n",
|
||||
"display(HTML(df.to_html(index=False)))"
|
||||
],
|
||||
"execution_count": 7,
|
||||
"execution_count": null,
|
||||
"outputs": [
|
||||
{
|
||||
"output_type": "display_data",
|
||||
@@ -415,23 +396,23 @@
|
||||
" <td>2020-05-21 00:00:00</td>\n",
|
||||
" <td>https://doi.org/10.1002/cpt.1910</td>\n",
|
||||
" <td>Indeed, risk factors are sex, obesity, genetic factors and mechanical factors (3) .</td>\n",
|
||||
" <td>Comorbidities</td>\n",
|
||||
" <td>extrapulmonary sites</td>\n",
|
||||
" <td>sex, obesity, genetic factors and mechanical factors</td>\n",
|
||||
" <td>None</td>\n",
|
||||
" </tr>\n",
|
||||
" <tr>\n",
|
||||
" <td>Prevalence and Impact of Myocardial Injury in Patients Hospitalized with COVID-19 Infection</td>\n",
|
||||
" <td>2020-04-24 00:00:00</td>\n",
|
||||
" <td>http://medrxiv.org/cgi/content/short/2020.04.20.20072702v1?rss=1</td>\n",
|
||||
" <td>This risk was consistent across patients stratified by history of CVD, risk factors but no CVD, and neither CVD nor risk factors.</td>\n",
|
||||
" <td>CVD, risk factors but no CVD, and neither CVD</td>\n",
|
||||
" <td>None</td>\n",
|
||||
" <td>Abbott, Abbott Park, Illinois</td>\n",
|
||||
" </tr>\n",
|
||||
" <tr>\n",
|
||||
" <td>Does apolipoprotein E genotype predict COVID-19 severity?</td>\n",
|
||||
" <td>2020-04-27 00:00:00</td>\n",
|
||||
" <td>https://doi.org/10.1093/qjmed/hcaa142</td>\n",
|
||||
" <td>Risk factors associated with subsequent death include older age, hypertension, diabetes, ischemic heart disease, obesity and chronic lung disease; however, sometimes there are no obvious risk factors .</td>\n",
|
||||
" <td>socioeconomic inequalities and risk factors</td>\n",
|
||||
" <td>None</td>\n",
|
||||
" <td>None</td>\n",
|
||||
" </tr>\n",
|
||||
" <tr>\n",
|
||||
@@ -440,14 +421,14 @@
|
||||
" <td>https://www.ncbi.nlm.nih.gov/pubmed/32705587/</td>\n",
|
||||
" <td>BACKGROUND: Frailty and multimorbidity have been suggested as risk factors for severe COVID-19 disease.</td>\n",
|
||||
" <td>Frailty and multimorbidity</td>\n",
|
||||
" <td>comorbidity groupings</td>\n",
|
||||
" <td>comorbidity groupings and the corresponding health conditions</td>\n",
|
||||
" </tr>\n",
|
||||
" <tr>\n",
|
||||
" <td>COVID-19: what has been learned and to be learned about the novel coronavirus disease</td>\n",
|
||||
" <td>2020-03-15 00:00:00</td>\n",
|
||||
" <td>https://doi.org/10.7150/ijbs.45134</td>\n",
|
||||
" <td>• Three major risk factors for COVID-19 were sex (male), age (≥60), and severe pneumonia.</td>\n",
|
||||
" <td>age and underlying disease are strongly correlated</td>\n",
|
||||
" <td>Mandatory contact tracing and quarantine</td>\n",
|
||||
" <td>cities, provinces, and countries</td>\n",
|
||||
" </tr>\n",
|
||||
" </tbody>\n",
|
||||
@@ -0,0 +1,209 @@
|
||||
{
|
||||
"nbformat": 4,
|
||||
"nbformat_minor": 0,
|
||||
"metadata": {
|
||||
"colab": {
|
||||
"name": "07 - Apply labels with zero-shot classification",
|
||||
"provenance": [],
|
||||
"collapsed_sections": []
|
||||
},
|
||||
"kernelspec": {
|
||||
"name": "python3",
|
||||
"display_name": "Python 3"
|
||||
}
|
||||
},
|
||||
"cells": [
|
||||
{
|
||||
"cell_type": "markdown",
|
||||
"metadata": {
|
||||
"id": "4Pjmz-RORV8E"
|
||||
},
|
||||
"source": [
|
||||
"# Apply labels with zero-shot classification\n",
|
||||
"\n",
|
||||
"This notebook shows how zero-shot classification can be used to perform text classification, labeling and topic modeling. txtai provides a light-weight wrapper around the zero-shot-classification pipeline in Hugging Face Transformers. This method works impressively well out of the box. Kudos to the Hugging Face team for the phenomenal work on zero-shot classification!\n",
|
||||
"\n",
|
||||
"The examples in this notebook pick the best matching label using a list of labels for a snippet of text.\n",
|
||||
"\n",
|
||||
"[tldrstory](https://github.com/neuml/tldrstory) has full-stack implementation of a zero-shot classification system using Streamlit, FastAPI and Hugging Face Transformers. There is also a [Medium article describing tldrstory](https://towardsdatascience.com/tldrstory-ai-powered-understanding-of-headlines-and-story-text-fc86abd702fc) and zero-shot classification. \n"
|
||||
]
|
||||
},
|
||||
{
|
||||
"cell_type": "markdown",
|
||||
"metadata": {
|
||||
"id": "Dk31rbYjSTYm"
|
||||
},
|
||||
"source": [
|
||||
"# Install dependencies\n",
|
||||
"\n",
|
||||
"Install `txtai` and all dependencies."
|
||||
]
|
||||
},
|
||||
{
|
||||
"cell_type": "code",
|
||||
"metadata": {
|
||||
"id": "XMQuuun2R06J"
|
||||
},
|
||||
"source": [
|
||||
"%%capture\n",
|
||||
"!pip install git+https://github.com/neuml/txtai"
|
||||
],
|
||||
"execution_count": null,
|
||||
"outputs": []
|
||||
},
|
||||
{
|
||||
"cell_type": "markdown",
|
||||
"metadata": {
|
||||
"id": "PNPJ95cdTKSS"
|
||||
},
|
||||
"source": [
|
||||
"# Create a Labels instance\n",
|
||||
"\n",
|
||||
"The Labels instance is the main entrypoint for zero-shot classification. This is a light-weight wrapper around the zero-shot-classification pipeline in Hugging Face Transformers.\n",
|
||||
"\n",
|
||||
"In addition to the default model, additional models can be found on the [Hugging Face model hub](https://huggingface.co/models?search=mnli).\n"
|
||||
]
|
||||
},
|
||||
{
|
||||
"cell_type": "code",
|
||||
"metadata": {
|
||||
"id": "nTDwXOUeTH2-"
|
||||
},
|
||||
"source": [
|
||||
"%%capture\n",
|
||||
"\n",
|
||||
"from txtai.pipeline import Labels\n",
|
||||
"\n",
|
||||
"# Create labels model\n",
|
||||
"labels = Labels()\n",
|
||||
"\n",
|
||||
"# Alternate models can be used via passing the model path as shown below\n",
|
||||
"# labels = Labels(\"roberta-large-mnli\")"
|
||||
],
|
||||
"execution_count": null,
|
||||
"outputs": []
|
||||
},
|
||||
{
|
||||
"cell_type": "markdown",
|
||||
"metadata": {
|
||||
"id": "-vGR_piwZZO6"
|
||||
},
|
||||
"source": [
|
||||
"# Applying labels to text\n",
|
||||
"\n",
|
||||
"The example below shows how a zero-shot classifier can be applied to arbitary text. The default model for the zero-shot classification pipeline is *bart-large-mnli*. \n",
|
||||
"\n",
|
||||
"Look at the results below. It's nothing short of amazing✨ how well it performs. These aren't all simple even for a human. For example, intercepted was purposely picked as that is more common in football than basketball. The amount of knowledge stored in larger Transformer models continues to impress me. "
|
||||
]
|
||||
},
|
||||
{
|
||||
"cell_type": "code",
|
||||
"metadata": {
|
||||
"colab": {
|
||||
"base_uri": "https://localhost:8080/"
|
||||
},
|
||||
"id": "-K2YJJzsVtfq",
|
||||
"outputId": "cd8d2e24-fbe7-4a8f-a947-c12b1d033e1d"
|
||||
},
|
||||
"source": [
|
||||
"data = [\"Dodgers lose again, give up 3 HRs in a loss to the Giants\",\n",
|
||||
" \"Giants 5 Cardinals 4 final in extra innings\",\n",
|
||||
" \"Dodgers drop Game 2 against the Giants, 5-4\",\n",
|
||||
" \"Flyers 4 Lightning 1 final. 45 saves for the Lightning.\",\n",
|
||||
" \"Slashing, penalty, 2 minute power play coming up\",\n",
|
||||
" \"What a stick save!\",\n",
|
||||
" \"Leads the NFL in sacks with 9.5\",\n",
|
||||
" \"UCF 38 Temple 13\",\n",
|
||||
" \"With the 30 yard completion, down to the 10 yard line\",\n",
|
||||
" \"Drains the 3pt shot!!, 0:15 remaining in the game\",\n",
|
||||
" \"Intercepted! Drives down the court and shoots for the win\",\n",
|
||||
" \"Massive dunk!!! they are now up by 15 with 2 minutes to go\"]\n",
|
||||
"\n",
|
||||
"# List of labels\n",
|
||||
"tags = [\"Baseball\", \"Football\", \"Hockey\", \"Basketball\"]\n",
|
||||
"\n",
|
||||
"print(\"%-75s %s\" % (\"Text\", \"Label\"))\n",
|
||||
"print(\"-\" * 100)\n",
|
||||
"\n",
|
||||
"for text in data:\n",
|
||||
" print(\"%-75s %s\" % (text, tags[labels(text, tags)[0][0]]))"
|
||||
],
|
||||
"execution_count": null,
|
||||
"outputs": [
|
||||
{
|
||||
"output_type": "stream",
|
||||
"text": [
|
||||
"Text Label\n",
|
||||
"----------------------------------------------------------------------------------------------------\n",
|
||||
"Dodgers lose again, give up 3 HRs in a loss to the Giants Baseball\n",
|
||||
"Giants 5 Cardinals 4 final in extra innings Baseball\n",
|
||||
"Dodgers drop Game 2 against the Giants, 5-4 Baseball\n",
|
||||
"Flyers 4 Lightning 1 final. 45 saves for the Lightning. Hockey\n",
|
||||
"Slashing, penalty, 2 minute power play coming up Hockey\n",
|
||||
"What a stick save! Hockey\n",
|
||||
"Leads the NFL in sacks with 9.5 Football\n",
|
||||
"UCF 38 Temple 13 Football\n",
|
||||
"With the 30 yard completion, down to the 10 yard line Football\n",
|
||||
"Drains the 3pt shot!!, 0:15 remaining in the game Basketball\n",
|
||||
"Intercepted! Drives down the court and shoots for the win Basketball\n",
|
||||
"Massive dunk!!! they are now up by 15 with 2 minutes to go Basketball\n"
|
||||
],
|
||||
"name": "stdout"
|
||||
}
|
||||
]
|
||||
},
|
||||
{
|
||||
"cell_type": "markdown",
|
||||
"metadata": {
|
||||
"id": "t-tGAzCxsHLy"
|
||||
},
|
||||
"source": [
|
||||
"# Let's try emoji 😀\n",
|
||||
"\n",
|
||||
"Does the model have knowledge of emoji? Check out the run below, sure looks like it does! Notice the labels are applied based on the perspective from which the information is presented. "
|
||||
]
|
||||
},
|
||||
{
|
||||
"cell_type": "code",
|
||||
"metadata": {
|
||||
"colab": {
|
||||
"base_uri": "https://localhost:8080/"
|
||||
},
|
||||
"id": "uIf064M9pbjn",
|
||||
"outputId": "f91e54d2-7c6a-4fee-882a-e4c873e719aa"
|
||||
},
|
||||
"source": [
|
||||
"tags = [\"😀\", \"😡\"]\n",
|
||||
"\n",
|
||||
"print(\"%-75s %s\" % (\"Text\", \"Label\"))\n",
|
||||
"print(\"-\" * 100)\n",
|
||||
"\n",
|
||||
"for text in data:\n",
|
||||
" print(\"%-75s %s\" % (text, tags[labels(text, tags)[0][0]]))"
|
||||
],
|
||||
"execution_count": null,
|
||||
"outputs": [
|
||||
{
|
||||
"output_type": "stream",
|
||||
"text": [
|
||||
"Text Label\n",
|
||||
"----------------------------------------------------------------------------------------------------\n",
|
||||
"Dodgers lose again, give up 3 HRs in a loss to the Giants 😡\n",
|
||||
"Giants 5 Cardinals 4 final in extra innings 😀\n",
|
||||
"Dodgers drop Game 2 against the Giants, 5-4 😡\n",
|
||||
"Flyers 4 Lightning 1 final. 45 saves for the Lightning. 😀\n",
|
||||
"Slashing, penalty, 2 minute power play coming up 😡\n",
|
||||
"What a stick save! 😀\n",
|
||||
"Leads the NFL in sacks with 9.5 😀\n",
|
||||
"UCF 38 Temple 13 😀\n",
|
||||
"With the 30 yard completion, down to the 10 yard line 😀\n",
|
||||
"Drains the 3pt shot!!, 0:15 remaining in the game 😀\n",
|
||||
"Intercepted! Drives down the court and shoots for the win 😀\n",
|
||||
"Massive dunk!!! they are now up by 15 with 2 minutes to go 😀\n"
|
||||
],
|
||||
"name": "stdout"
|
||||
}
|
||||
]
|
||||
}
|
||||
]
|
||||
}
|
||||
@@ -0,0 +1,840 @@
|
||||
{
|
||||
"nbformat": 4,
|
||||
"nbformat_minor": 0,
|
||||
"metadata": {
|
||||
"colab": {
|
||||
"name": "08 - API Gallery",
|
||||
"provenance": [],
|
||||
"collapsed_sections": []
|
||||
},
|
||||
"kernelspec": {
|
||||
"display_name": "Python 3",
|
||||
"name": "python3"
|
||||
}
|
||||
},
|
||||
"cells": [
|
||||
{
|
||||
"cell_type": "markdown",
|
||||
"metadata": {
|
||||
"id": "4Pjmz-RORV8E"
|
||||
},
|
||||
"source": [
|
||||
"# API Gallery\n",
|
||||
"\n",
|
||||
"The txtai API is a web-based service backed by [FastAPI](https://fastapi.tiangolo.com/). All txtai functionality including similarity search, extractive QA and zero-shot labeling is available via the API.\n",
|
||||
"\n",
|
||||
"This notebook installs the txtai API and shows an example using each of the supported language bindings for txtai."
|
||||
]
|
||||
},
|
||||
{
|
||||
"cell_type": "markdown",
|
||||
"metadata": {
|
||||
"id": "Dk31rbYjSTYm"
|
||||
},
|
||||
"source": [
|
||||
"# Install dependencies\n",
|
||||
"\n",
|
||||
"Install `txtai` and all dependencies. Since this notebook uses the API, we need to install the api extras package."
|
||||
]
|
||||
},
|
||||
{
|
||||
"cell_type": "code",
|
||||
"metadata": {
|
||||
"id": "XMQuuun2R06J"
|
||||
},
|
||||
"source": [
|
||||
"%%capture\n",
|
||||
"!pip install git+https://github.com/neuml/txtai#egg=txtai[api]"
|
||||
],
|
||||
"execution_count": null,
|
||||
"outputs": []
|
||||
},
|
||||
{
|
||||
"cell_type": "markdown",
|
||||
"metadata": {
|
||||
"id": "-vGR_piwZZO6"
|
||||
},
|
||||
"source": [
|
||||
"# Python\n",
|
||||
"\n",
|
||||
"The first method we'll try is direct access via Python. We'll use zero-shot labeling for all the examples here. See [this notebook](https://colab.research.google.com/github/neuml/txtai/blob/master/examples/07_Apply_labels_with_zero_shot_classification.ipynb) for more details on zero-shot classification. "
|
||||
]
|
||||
},
|
||||
{
|
||||
"cell_type": "markdown",
|
||||
"metadata": {
|
||||
"id": "P4q72tkRMMkR"
|
||||
},
|
||||
"source": [
|
||||
"## Configure Labels instance"
|
||||
]
|
||||
},
|
||||
{
|
||||
"cell_type": "code",
|
||||
"metadata": {
|
||||
"id": "8Dy_TJ0iM38Q"
|
||||
},
|
||||
"source": [
|
||||
"%%capture\n",
|
||||
"import os\n",
|
||||
"from IPython.core.display import display, HTML\n",
|
||||
"from txtai.pipeline import Labels\n",
|
||||
"\n",
|
||||
"def table(rows):\n",
|
||||
" html = \"\"\"\n",
|
||||
" <style type='text/css'>\n",
|
||||
" @import url('https://fonts.googleapis.com/css?family=Oswald&display=swap');\n",
|
||||
" table {\n",
|
||||
" border-collapse: collapse;\n",
|
||||
" width: 900px;\n",
|
||||
" }\n",
|
||||
" th, td {\n",
|
||||
" border: 1px solid #9e9e9e;\n",
|
||||
" padding: 10px;\n",
|
||||
" font: 20px Oswald;\n",
|
||||
" }\n",
|
||||
" </style>\n",
|
||||
" \"\"\"\n",
|
||||
"\n",
|
||||
" html += \"<table><thead><tr><th>Text</th><th>Label</th></tr></thead>\"\n",
|
||||
" for text, label in rows:\n",
|
||||
" html += \"<tr><td>%s</td><td>%s</td></tr>\" % (text, label)\n",
|
||||
" html += \"</table>\"\n",
|
||||
"\n",
|
||||
" display(HTML(html))\n",
|
||||
"\n",
|
||||
"# Create labels model\n",
|
||||
"labels = Labels()"
|
||||
],
|
||||
"execution_count": null,
|
||||
"outputs": []
|
||||
},
|
||||
{
|
||||
"cell_type": "markdown",
|
||||
"metadata": {
|
||||
"id": "L4B73tGkMT6Q"
|
||||
},
|
||||
"source": [
|
||||
"## Apply labels to text"
|
||||
]
|
||||
},
|
||||
{
|
||||
"cell_type": "code",
|
||||
"metadata": {
|
||||
"colab": {
|
||||
"base_uri": "https://localhost:8080/",
|
||||
"height": 324
|
||||
},
|
||||
"id": "-K2YJJzsVtfq",
|
||||
"outputId": "2b9f6cf9-73c7-4eed-961b-117f0f927296"
|
||||
},
|
||||
"source": [
|
||||
"data = [\"Wears a red suit and says ho ho\",\n",
|
||||
" \"Pulls a flying sleigh\",\n",
|
||||
" \"This is cut down and decorated\",\n",
|
||||
" \"Santa puts these under the tree\",\n",
|
||||
" \"Best way to spend the holidays\"]\n",
|
||||
"\n",
|
||||
"# List of labels\n",
|
||||
"tags = [\"🎅 Santa Clause\", \"🦌 Reindeer\", \"🍪 Cookies\", \"🎄 Christmas Tree\", \"🎁 Gifts\", \"👪 Family\"]\n",
|
||||
"\n",
|
||||
"# Render output to table\n",
|
||||
"table([(text, tags[labels(text, tags)[0][0]]) for text in data])"
|
||||
],
|
||||
"execution_count": null,
|
||||
"outputs": [
|
||||
{
|
||||
"output_type": "display_data",
|
||||
"data": {
|
||||
"text/html": [
|
||||
"\n",
|
||||
" <style type='text/css'>\n",
|
||||
" @import url('https://fonts.googleapis.com/css?family=Oswald&display=swap');\n",
|
||||
" table {\n",
|
||||
" border-collapse: collapse;\n",
|
||||
" width: 900px;\n",
|
||||
" }\n",
|
||||
" th, td {\n",
|
||||
" border: 1px solid #9e9e9e;\n",
|
||||
" padding: 10px;\n",
|
||||
" font: 20px Oswald;\n",
|
||||
" }\n",
|
||||
" </style>\n",
|
||||
" <table><thead><tr><th>Text</th><th>Label</th></tr></thead><tr><td>Wears a red suit and says ho ho</td><td>🎅 Santa Clause</td></tr><tr><td>Pulls a flying sleigh</td><td>🦌 Reindeer</td></tr><tr><td>This is cut down and decorated</td><td>🎄 Christmas Tree</td></tr><tr><td>Santa puts these under the tree</td><td>🎁 Gifts</td></tr><tr><td>Best way to spend the holidays</td><td>👪 Family</td></tr></table>"
|
||||
],
|
||||
"text/plain": [
|
||||
"<IPython.core.display.HTML object>"
|
||||
]
|
||||
},
|
||||
"metadata": {
|
||||
"tags": []
|
||||
}
|
||||
}
|
||||
]
|
||||
},
|
||||
{
|
||||
"cell_type": "markdown",
|
||||
"metadata": {
|
||||
"id": "UF_bImkLHTMs"
|
||||
},
|
||||
"source": [
|
||||
"Once again we see the power of zero-shot labeling. The model wasn't trained on any data specific to this example. Still amazed with how much knowledge is stored in large NLP models."
|
||||
]
|
||||
},
|
||||
{
|
||||
"cell_type": "markdown",
|
||||
"metadata": {
|
||||
"id": "PNPJ95cdTKSS"
|
||||
},
|
||||
"source": [
|
||||
"# Start an API instance\n",
|
||||
"\n",
|
||||
"Now we'll start an API instance to run the remaining examples. The API needs a configuration file to run. The example below is simplified to only include labeling. See [this link](https://github.com/neuml/txtai#api) for a more detailed configuration example.\n",
|
||||
"\n",
|
||||
"The API instance is started in the background.\n"
|
||||
]
|
||||
},
|
||||
{
|
||||
"cell_type": "code",
|
||||
"metadata": {
|
||||
"colab": {
|
||||
"base_uri": "https://localhost:8080/"
|
||||
},
|
||||
"id": "nTDwXOUeTH2-",
|
||||
"outputId": "c0f8532f-a993-4859-adc6-94e35c689eca"
|
||||
},
|
||||
"source": [
|
||||
"%%writefile index.yml\n",
|
||||
"\n",
|
||||
"# Labels settings\n",
|
||||
"labels:"
|
||||
],
|
||||
"execution_count": null,
|
||||
"outputs": [
|
||||
{
|
||||
"output_type": "stream",
|
||||
"text": [
|
||||
"Writing index.yml\n"
|
||||
],
|
||||
"name": "stdout"
|
||||
}
|
||||
]
|
||||
},
|
||||
{
|
||||
"cell_type": "code",
|
||||
"metadata": {
|
||||
"id": "nGITHxUyRzyp"
|
||||
},
|
||||
"source": [
|
||||
"!CONFIG=index.yml nohup uvicorn \"txtai.api:app\" &> api.log &\n",
|
||||
"!sleep 90"
|
||||
],
|
||||
"execution_count": null,
|
||||
"outputs": []
|
||||
},
|
||||
{
|
||||
"cell_type": "markdown",
|
||||
"metadata": {
|
||||
"id": "NHvBFZeSd9AG"
|
||||
},
|
||||
"source": [
|
||||
"# JavaScript\n",
|
||||
"\n",
|
||||
"txtai.js is available via NPM and can be installed as follows.\n",
|
||||
"\n",
|
||||
"```bash\n",
|
||||
"npm install txtai\n",
|
||||
"```\n",
|
||||
"\n",
|
||||
"For this example, we'll clone the txtai.js project to import the example build configuration."
|
||||
]
|
||||
},
|
||||
{
|
||||
"cell_type": "code",
|
||||
"metadata": {
|
||||
"id": "b52knObEdcCr"
|
||||
},
|
||||
"source": [
|
||||
"%%capture\n",
|
||||
"!git clone https://github.com/neuml/txtai.js"
|
||||
],
|
||||
"execution_count": null,
|
||||
"outputs": []
|
||||
},
|
||||
{
|
||||
"cell_type": "markdown",
|
||||
"metadata": {
|
||||
"id": "rUGS0t-JMsS9"
|
||||
},
|
||||
"source": [
|
||||
"## Create labels.js\n",
|
||||
"\n",
|
||||
"The following file is a JavaScript version of the labels example."
|
||||
]
|
||||
},
|
||||
{
|
||||
"cell_type": "code",
|
||||
"metadata": {
|
||||
"colab": {
|
||||
"base_uri": "https://localhost:8080/"
|
||||
},
|
||||
"id": "zJbKRTSJV-kd",
|
||||
"outputId": "84c6d08e-88fe-492a-8aa1-3a9a9e6364b2"
|
||||
},
|
||||
"source": [
|
||||
"%%writefile txtai.js/examples/node/src/labels.js\n",
|
||||
"import {Labels} from \"txtai\";\n",
|
||||
"import {sprintf} from \"sprintf-js\";\n",
|
||||
"\n",
|
||||
"const run = async () => {\n",
|
||||
" try {\n",
|
||||
" let labels = new Labels(\"http://localhost:8000\");\n",
|
||||
"\n",
|
||||
" let data = [\"Wears a red suit and says ho ho\",\n",
|
||||
" \"Pulls a flying sleigh\",\n",
|
||||
" \"This is cut down and decorated\",\n",
|
||||
" \"Santa puts these under the tree\",\n",
|
||||
" \"Best way to spend the holidays\"];\n",
|
||||
"\n",
|
||||
" // List of labels\n",
|
||||
" let tags = [\"🎅 Santa Clause\", \"🦌 Reindeer\", \"🍪 Cookies\", \"🎄 Christmas Tree\", \"🎁 Gifts\", \"👪 Family\"];\n",
|
||||
"\n",
|
||||
" console.log(sprintf(\"%-40s %s\", \"Text\", \"Label\"));\n",
|
||||
" console.log(\"-\".repeat(75))\n",
|
||||
"\n",
|
||||
" for (let text of data) {\n",
|
||||
" let label = await labels.label(text, tags);\n",
|
||||
" label = tags[label[0].id];\n",
|
||||
"\n",
|
||||
" console.log(sprintf(\"%-40s %s\", text, label));\n",
|
||||
" }\n",
|
||||
" }\n",
|
||||
" catch (e) {\n",
|
||||
" console.trace(e);\n",
|
||||
" }\n",
|
||||
"};\n",
|
||||
"\n",
|
||||
"run();\n"
|
||||
],
|
||||
"execution_count": null,
|
||||
"outputs": [
|
||||
{
|
||||
"output_type": "stream",
|
||||
"text": [
|
||||
"Overwriting txtai.js/examples/node/src/labels.js\n"
|
||||
],
|
||||
"name": "stdout"
|
||||
}
|
||||
]
|
||||
},
|
||||
{
|
||||
"cell_type": "markdown",
|
||||
"metadata": {
|
||||
"id": "nTBs11j-GtD-"
|
||||
},
|
||||
"source": [
|
||||
"## Build and run labels example\n",
|
||||
"\n",
|
||||
"\n",
|
||||
"\n"
|
||||
]
|
||||
},
|
||||
{
|
||||
"cell_type": "code",
|
||||
"metadata": {
|
||||
"id": "kC5Oub6wa1nK"
|
||||
},
|
||||
"source": [
|
||||
"%%capture\n",
|
||||
"os.chdir(\"txtai.js/examples/node\")\n",
|
||||
"!npm install\n",
|
||||
"!npm run build"
|
||||
],
|
||||
"execution_count": null,
|
||||
"outputs": []
|
||||
},
|
||||
{
|
||||
"cell_type": "code",
|
||||
"metadata": {
|
||||
"colab": {
|
||||
"base_uri": "https://localhost:8080/"
|
||||
},
|
||||
"id": "ckOHNqyaeL-B",
|
||||
"outputId": "fb95316b-6650-4edb-e4e4-0be4a6c7de9d"
|
||||
},
|
||||
"source": [
|
||||
"!node dist/labels.js"
|
||||
],
|
||||
"execution_count": null,
|
||||
"outputs": [
|
||||
{
|
||||
"output_type": "stream",
|
||||
"text": [
|
||||
"Text Label\n",
|
||||
"---------------------------------------------------------------------------\n",
|
||||
"Wears a red suit and says ho ho 🎅 Santa Clause\n",
|
||||
"Pulls a flying sleigh 🦌 Reindeer\n",
|
||||
"This is cut down and decorated 🎄 Christmas Tree\n",
|
||||
"Santa puts these under the tree 🎁 Gifts\n",
|
||||
"Best way to spend the holidays 👪 Family\n"
|
||||
],
|
||||
"name": "stdout"
|
||||
}
|
||||
]
|
||||
},
|
||||
{
|
||||
"cell_type": "markdown",
|
||||
"metadata": {
|
||||
"id": "1yukBIMYG5OE"
|
||||
},
|
||||
"source": [
|
||||
"The JavaScript program is showing the same results as when natively running through Python!"
|
||||
]
|
||||
},
|
||||
{
|
||||
"cell_type": "markdown",
|
||||
"metadata": {
|
||||
"id": "nNiMgvg0p2BG"
|
||||
},
|
||||
"source": [
|
||||
"# Java\n",
|
||||
"\n",
|
||||
"txtai.java integrates with standard Java build tools (Gradle, Maven, SBT). The following shows how to add txtai as a dependency to Gradle.\n",
|
||||
"\n",
|
||||
"```gradle\n",
|
||||
"implementation 'com.github.neuml:txtai.java:v3.0.0'\n",
|
||||
"```\n",
|
||||
"\n",
|
||||
"For this example, we'll clone the txtai.java project to import the example build configuration."
|
||||
]
|
||||
},
|
||||
{
|
||||
"cell_type": "code",
|
||||
"metadata": {
|
||||
"id": "qs2ai8lhqmga"
|
||||
},
|
||||
"source": [
|
||||
"%%capture\n",
|
||||
"os.chdir(\"/content\")\n",
|
||||
"!git clone https://github.com/neuml/txtai.java"
|
||||
],
|
||||
"execution_count": null,
|
||||
"outputs": []
|
||||
},
|
||||
{
|
||||
"cell_type": "markdown",
|
||||
"metadata": {
|
||||
"id": "o8QFvzXkNFgq"
|
||||
},
|
||||
"source": [
|
||||
"## Create LabelsDemo.java\n",
|
||||
"\n",
|
||||
"The following file is a Java version of the labels example."
|
||||
]
|
||||
},
|
||||
{
|
||||
"cell_type": "code",
|
||||
"metadata": {
|
||||
"colab": {
|
||||
"base_uri": "https://localhost:8080/"
|
||||
},
|
||||
"id": "v73L8Gw0p6fh",
|
||||
"outputId": "2c6b0cf4-00f0-436b-b472-07ecebd015da"
|
||||
},
|
||||
"source": [
|
||||
"%%writefile txtai.java/examples/src/main/java/LabelsDemo.java\n",
|
||||
"import java.util.Arrays;\n",
|
||||
"import java.util.ArrayList;\n",
|
||||
"import java.util.List;\n",
|
||||
"\n",
|
||||
"import txtai.API.IndexResult;\n",
|
||||
"import txtai.Labels;\n",
|
||||
"\n",
|
||||
"public class LabelsDemo {\n",
|
||||
" public static void main(String[] args) {\n",
|
||||
" try {\n",
|
||||
" Labels labels = new Labels(\"http://localhost:8000\");\n",
|
||||
"\n",
|
||||
" List <String> data = \n",
|
||||
" Arrays.asList(\"Wears a red suit and says ho ho\",\n",
|
||||
" \"Pulls a flying sleigh\",\n",
|
||||
" \"This is cut down and decorated\",\n",
|
||||
" \"Santa puts these under the tree\",\n",
|
||||
" \"Best way to spend the holidays\");\n",
|
||||
"\n",
|
||||
" // List of labels\n",
|
||||
" List<String> tags = Arrays.asList(\"🎅 Santa Clause\", \"🦌 Reindeer\", \"🍪 Cookies\", \"🎄 Christmas Tree\", \"🎁 Gifts\", \"👪 Family\");\n",
|
||||
"\n",
|
||||
" System.out.printf(\"%-40s %s%n\", \"Text\", \"Label\");\n",
|
||||
" System.out.println(new String(new char[75]).replace(\"\\0\", \"-\"));\n",
|
||||
"\n",
|
||||
" for (String text: data) {\n",
|
||||
" List<IndexResult> label = labels.label(text, tags);\n",
|
||||
" System.out.printf(\"%-40s %s%n\", text, tags.get(label.get(0).id));\n",
|
||||
" }\n",
|
||||
" }\n",
|
||||
" catch (Exception ex) {\n",
|
||||
" ex.printStackTrace();\n",
|
||||
" }\n",
|
||||
" }\n",
|
||||
"}\n"
|
||||
],
|
||||
"execution_count": null,
|
||||
"outputs": [
|
||||
{
|
||||
"output_type": "stream",
|
||||
"text": [
|
||||
"Overwriting txtai.java/examples/src/main/java/LabelsDemo.java\n"
|
||||
],
|
||||
"name": "stdout"
|
||||
}
|
||||
]
|
||||
},
|
||||
{
|
||||
"cell_type": "markdown",
|
||||
"metadata": {
|
||||
"id": "wZv7eMIOLnRC"
|
||||
},
|
||||
"source": [
|
||||
"## Build and run labels example"
|
||||
]
|
||||
},
|
||||
{
|
||||
"cell_type": "code",
|
||||
"metadata": {
|
||||
"colab": {
|
||||
"base_uri": "https://localhost:8080/"
|
||||
},
|
||||
"id": "N2Mm3Gl5sH1z",
|
||||
"outputId": "f0e6f8ec-1ca4-485d-fc7b-3e15be829b1c"
|
||||
},
|
||||
"source": [
|
||||
"os.chdir(\"txtai.java/examples\")\n",
|
||||
"!../gradlew -q --console=plain labels 2> /dev/null"
|
||||
],
|
||||
"execution_count": null,
|
||||
"outputs": [
|
||||
{
|
||||
"output_type": "stream",
|
||||
"text": [
|
||||
"Text Label\n",
|
||||
"---------------------------------------------------------------------------\n",
|
||||
"Wears a red suit and says ho ho 🎅 Santa Clause\n",
|
||||
"Pulls a flying sleigh 🦌 Reindeer\n",
|
||||
"This is cut down and decorated 🎄 Christmas Tree\n",
|
||||
"Santa puts these under the tree 🎁 Gifts\n",
|
||||
"Best way to spend the holidays 👪 Family\n",
|
||||
"\u001b[m"
|
||||
],
|
||||
"name": "stdout"
|
||||
}
|
||||
]
|
||||
},
|
||||
{
|
||||
"cell_type": "markdown",
|
||||
"metadata": {
|
||||
"id": "iHpQvUAgNp7j"
|
||||
},
|
||||
"source": [
|
||||
"The Java program is showing the same results as when natively running through Python!"
|
||||
]
|
||||
},
|
||||
{
|
||||
"cell_type": "markdown",
|
||||
"metadata": {
|
||||
"id": "zU6jK2UL7D5H"
|
||||
},
|
||||
"source": [
|
||||
"# Rust\n",
|
||||
"\n",
|
||||
"txtai.rs is available via crates.io and can be installed by adding the following to your cargo.toml file.\n",
|
||||
"\n",
|
||||
"```toml\n",
|
||||
"[dependencies]\n",
|
||||
"txtai = { version = \"3.0\" }\n",
|
||||
"tokio = { version = \"0.2\", features = [\"full\"] }\n",
|
||||
"```\n",
|
||||
"\n",
|
||||
"For this example, we'll clone the txtai.rs project to import the example build configuration. First we need to install Rust."
|
||||
]
|
||||
},
|
||||
{
|
||||
"cell_type": "code",
|
||||
"metadata": {
|
||||
"id": "Ob4aswkx7jRh"
|
||||
},
|
||||
"source": [
|
||||
"%%capture\n",
|
||||
"os.chdir(\"/content\")\n",
|
||||
"!apt-get install rustc\n",
|
||||
"!git clone https://github.com/neuml/txtai.rs"
|
||||
],
|
||||
"execution_count": null,
|
||||
"outputs": []
|
||||
},
|
||||
{
|
||||
"cell_type": "markdown",
|
||||
"metadata": {
|
||||
"id": "evEQQXBuObZn"
|
||||
},
|
||||
"source": [
|
||||
"## Create labels.rs\n",
|
||||
"\n",
|
||||
"The following file is a Rust version of the labels example."
|
||||
]
|
||||
},
|
||||
{
|
||||
"cell_type": "code",
|
||||
"metadata": {
|
||||
"colab": {
|
||||
"base_uri": "https://localhost:8080/"
|
||||
},
|
||||
"id": "jjggKnKQ7jQO",
|
||||
"outputId": "9fe46d74-8a42-4ccc-ef49-b005b02d90ad"
|
||||
},
|
||||
"source": [
|
||||
"%%writefile txtai.rs/examples/demo/src/labels.rs\n",
|
||||
"use std::error::Error;\n",
|
||||
"\n",
|
||||
"use txtai::labels::Labels;\n",
|
||||
"\n",
|
||||
"pub async fn labels() -> Result<(), Box<dyn Error>> {\n",
|
||||
" let labels = Labels::new(\"http://localhost:8000\");\n",
|
||||
"\n",
|
||||
" let data = [\"Wears a red suit and says ho ho\",\n",
|
||||
" \"Pulls a flying sleigh\",\n",
|
||||
" \"This is cut down and decorated\",\n",
|
||||
" \"Santa puts these under the tree\",\n",
|
||||
" \"Best way to spend the holidays\"];\n",
|
||||
"\n",
|
||||
" println!(\"{:<40} {}\", \"Text\", \"Label\");\n",
|
||||
" println!(\"{}\", \"-\".repeat(75));\n",
|
||||
"\n",
|
||||
" for text in data.iter() {\n",
|
||||
" let tags = vec![\"🎅 Santa Clause\", \"🦌 Reindeer\", \"🍪 Cookies\", \"🎄 Christmas Tree\", \"🎁 Gifts\", \"👪 Family\"];\n",
|
||||
" let label = labels.label(text, &tags).await?[0].id;\n",
|
||||
"\n",
|
||||
" println!(\"{:<40} {}\", text, tags[label]);\n",
|
||||
" }\n",
|
||||
"\n",
|
||||
" Ok(())\n",
|
||||
"}"
|
||||
],
|
||||
"execution_count": null,
|
||||
"outputs": [
|
||||
{
|
||||
"output_type": "stream",
|
||||
"text": [
|
||||
"Overwriting txtai.rs/examples/demo/src/labels.rs\n"
|
||||
],
|
||||
"name": "stdout"
|
||||
}
|
||||
]
|
||||
},
|
||||
{
|
||||
"cell_type": "markdown",
|
||||
"metadata": {
|
||||
"id": "gFFPZO8sQZC4"
|
||||
},
|
||||
"source": [
|
||||
"## Build and run labels example\n",
|
||||
"\n",
|
||||
"\n",
|
||||
"\n"
|
||||
]
|
||||
},
|
||||
{
|
||||
"cell_type": "code",
|
||||
"metadata": {
|
||||
"id": "wuoAidGz9T4g"
|
||||
},
|
||||
"source": [
|
||||
"%%capture\n",
|
||||
"os.chdir(\"txtai.rs/examples/demo\")\n",
|
||||
"!cargo build"
|
||||
],
|
||||
"execution_count": null,
|
||||
"outputs": []
|
||||
},
|
||||
{
|
||||
"cell_type": "code",
|
||||
"metadata": {
|
||||
"colab": {
|
||||
"base_uri": "https://localhost:8080/"
|
||||
},
|
||||
"id": "-_v_FbL0-yPk",
|
||||
"outputId": "6f121ca5-071a-43db-ec02-cde711c381dd"
|
||||
},
|
||||
"source": [
|
||||
"!cargo run labels"
|
||||
],
|
||||
"execution_count": null,
|
||||
"outputs": [
|
||||
{
|
||||
"output_type": "stream",
|
||||
"text": [
|
||||
"\u001b[0m\u001b[0m\u001b[1m\u001b[32m Finished\u001b[0m dev [unoptimized + debuginfo] target(s) in 0.10s\n",
|
||||
"\u001b[0m\u001b[0m\u001b[1m\u001b[32m Running\u001b[0m `target/debug/demo labels`\n",
|
||||
"Text Label\n",
|
||||
"---------------------------------------------------------------------------\n",
|
||||
"Wears a red suit and says ho ho 🎅 Santa Clause\n",
|
||||
"Pulls a flying sleigh 🦌 Reindeer\n",
|
||||
"This is cut down and decorated 🎄 Christmas Tree\n",
|
||||
"Santa puts these under the tree 🎁 Gifts\n",
|
||||
"Best way to spend the holidays 👪 Family\n"
|
||||
],
|
||||
"name": "stdout"
|
||||
}
|
||||
]
|
||||
},
|
||||
{
|
||||
"cell_type": "markdown",
|
||||
"metadata": {
|
||||
"id": "kDmS89TPS3kb"
|
||||
},
|
||||
"source": [
|
||||
"The Rust program is showing the same results as when natively running through Python!"
|
||||
]
|
||||
},
|
||||
{
|
||||
"cell_type": "markdown",
|
||||
"metadata": {
|
||||
"id": "ezznN4I8_CCQ"
|
||||
},
|
||||
"source": [
|
||||
"# Go\n",
|
||||
"\n",
|
||||
"txtai.go can be installed by adding the following import statement. When using modules, txtai.go will automatically be installed. Otherwise use `go get`.\n",
|
||||
"\n",
|
||||
"```golang\n",
|
||||
"import \"github.com/neuml/txtai.go\"\n",
|
||||
"```\n",
|
||||
"\n",
|
||||
"For this example, we'll create a standalone process for labeling. First we need to install Go."
|
||||
]
|
||||
},
|
||||
{
|
||||
"cell_type": "code",
|
||||
"metadata": {
|
||||
"id": "b-b6fhLQ_DpQ"
|
||||
},
|
||||
"source": [
|
||||
"%%capture\n",
|
||||
"os.chdir(\"/content\")\n",
|
||||
"!apt install golang-go\n",
|
||||
"!go get \"github.com/neuml/txtai.go\""
|
||||
],
|
||||
"execution_count": null,
|
||||
"outputs": []
|
||||
},
|
||||
{
|
||||
"cell_type": "markdown",
|
||||
"metadata": {
|
||||
"id": "Dw-I6jOGR6vA"
|
||||
},
|
||||
"source": [
|
||||
"## Create labels.go\n",
|
||||
"\n",
|
||||
"The following file is a Go version of the labels example."
|
||||
]
|
||||
},
|
||||
{
|
||||
"cell_type": "code",
|
||||
"metadata": {
|
||||
"id": "bLBJwkN4ANpi",
|
||||
"colab": {
|
||||
"base_uri": "https://localhost:8080/"
|
||||
},
|
||||
"outputId": "8108d8f4-a53a-4dda-cc41-f52d532eccee"
|
||||
},
|
||||
"source": [
|
||||
"%%writefile labels.go\n",
|
||||
"package main\n",
|
||||
"\n",
|
||||
"import (\n",
|
||||
"\t\"fmt\"\n",
|
||||
"\t\"strings\"\n",
|
||||
"\t\"github.com/neuml/txtai.go\"\n",
|
||||
")\n",
|
||||
"\n",
|
||||
"func main() {\n",
|
||||
"\tlabels := txtai.Labels(\"http://localhost:8000\")\n",
|
||||
"\n",
|
||||
"\tdata := []string{\"Wears a red suit and says ho ho\",\n",
|
||||
" \"Pulls a flying sleigh\",\n",
|
||||
" \"This is cut down and decorated\",\n",
|
||||
" \"Santa puts these under the tree\",\n",
|
||||
" \"Best way to spend the holidays\"}\n",
|
||||
"\n",
|
||||
"\t// List of labels\n",
|
||||
"\ttags := []string{\"🎅 Santa Clause\", \"🦌 Reindeer\", \"🍪 Cookies\", \"🎄 Christmas Tree\", \"🎁 Gifts\", \"👪 Family\"}\n",
|
||||
"\n",
|
||||
"\tfmt.Printf(\"%-40s %s\\n\", \"Text\", \"Label\")\n",
|
||||
"\tfmt.Println(strings.Repeat(\"-\", 75))\n",
|
||||
"\n",
|
||||
"\tfor _, text := range data {\n",
|
||||
"\t\tlabel := labels.Label(text, tags)\n",
|
||||
"\t\tfmt.Printf(\"%-40s %s\\n\", text, tags[label[0].Id])\n",
|
||||
"\t}\n",
|
||||
"}"
|
||||
],
|
||||
"execution_count": null,
|
||||
"outputs": [
|
||||
{
|
||||
"output_type": "stream",
|
||||
"text": [
|
||||
"Writing labels.go\n"
|
||||
],
|
||||
"name": "stdout"
|
||||
}
|
||||
]
|
||||
},
|
||||
{
|
||||
"cell_type": "markdown",
|
||||
"metadata": {
|
||||
"id": "PJ2XzzDbSeZh"
|
||||
},
|
||||
"source": [
|
||||
"## Build and run labels example\n"
|
||||
]
|
||||
},
|
||||
{
|
||||
"cell_type": "code",
|
||||
"metadata": {
|
||||
"id": "l1xnUbtdAy0p",
|
||||
"colab": {
|
||||
"base_uri": "https://localhost:8080/"
|
||||
},
|
||||
"outputId": "99586a0e-380c-4fee-99bb-339c9363c9ef"
|
||||
},
|
||||
"source": [
|
||||
"!go run labels.go"
|
||||
],
|
||||
"execution_count": null,
|
||||
"outputs": [
|
||||
{
|
||||
"output_type": "stream",
|
||||
"text": [
|
||||
"Text Label\n",
|
||||
"---------------------------------------------------------------------------\n",
|
||||
"Wears a red suit and says ho ho 🎅 Santa Clause\n",
|
||||
"Pulls a flying sleigh 🦌 Reindeer\n",
|
||||
"This is cut down and decorated 🎄 Christmas Tree\n",
|
||||
"Santa puts these under the tree 🎁 Gifts\n",
|
||||
"Best way to spend the holidays 👪 Family\n"
|
||||
],
|
||||
"name": "stdout"
|
||||
}
|
||||
]
|
||||
},
|
||||
{
|
||||
"cell_type": "markdown",
|
||||
"metadata": {
|
||||
"id": "oml43X5eS6YB"
|
||||
},
|
||||
"source": [
|
||||
"The Go program is showing the same results as when natively running through Python!"
|
||||
]
|
||||
}
|
||||
]
|
||||
}
|
||||
@@ -0,0 +1,203 @@
|
||||
{
|
||||
"nbformat": 4,
|
||||
"nbformat_minor": 0,
|
||||
"metadata": {
|
||||
"colab": {
|
||||
"name": "09 - Building abstractive text summaries",
|
||||
"provenance": [],
|
||||
"collapsed_sections": []
|
||||
},
|
||||
"kernelspec": {
|
||||
"name": "python3",
|
||||
"display_name": "Python 3"
|
||||
}
|
||||
},
|
||||
"cells": [
|
||||
{
|
||||
"cell_type": "markdown",
|
||||
"metadata": {
|
||||
"id": "4Pjmz-RORV8E"
|
||||
},
|
||||
"source": [
|
||||
"# Building abstractive text summaries\n",
|
||||
"\n",
|
||||
"In the field of text summarization, there are two primary categories of summarization, extractive and abstractive summarization.\n",
|
||||
"\n",
|
||||
"Extractive summarization takes subsections of the text and joins them together to form a summary. This is commonly backed by graph algorithms like TextRank to find the sections/sentences with the most commonality. These summaries can be highly effective but they are unable to transform text and don't have a contextual understanding.\n",
|
||||
"\n",
|
||||
"Abstractive summarization uses Natural Language Processing (NLP) models to build transformative summaries of text. This is similar to having a human read an article and asking what was it about. A human wouldn't just give a verbose reading of the text. This notebook shows how blocks of text can be summarized using an abstractive summarization pipeline. "
|
||||
]
|
||||
},
|
||||
{
|
||||
"cell_type": "markdown",
|
||||
"metadata": {
|
||||
"id": "Dk31rbYjSTYm"
|
||||
},
|
||||
"source": [
|
||||
"# Install dependencies\n",
|
||||
"\n",
|
||||
"Install `txtai` and all dependencies. Since this notebook is using optional pipelines, we need to install the pipeline extras package."
|
||||
]
|
||||
},
|
||||
{
|
||||
"cell_type": "code",
|
||||
"metadata": {
|
||||
"id": "XMQuuun2R06J"
|
||||
},
|
||||
"source": [
|
||||
"%%capture\n",
|
||||
"!pip install git+https://github.com/neuml/txtai#egg=txtai[pipeline]"
|
||||
],
|
||||
"execution_count": null,
|
||||
"outputs": []
|
||||
},
|
||||
{
|
||||
"cell_type": "markdown",
|
||||
"metadata": {
|
||||
"id": "PNPJ95cdTKSS"
|
||||
},
|
||||
"source": [
|
||||
"# Create a Summary instance\n",
|
||||
"\n",
|
||||
"The Summary instance is the main entrypoint for text summarization. This is a light-weight wrapper around the summarization pipeline in Hugging Face Transformers.\n",
|
||||
"\n",
|
||||
"In addition to the default model, additional models can be found on the [Hugging Face model hub](https://huggingface.co/models?pipeline_tag=summarization).\n"
|
||||
]
|
||||
},
|
||||
{
|
||||
"cell_type": "code",
|
||||
"metadata": {
|
||||
"id": "nTDwXOUeTH2-"
|
||||
},
|
||||
"source": [
|
||||
"%%capture\n",
|
||||
"\n",
|
||||
"from txtai.pipeline import Summary\n",
|
||||
"\n",
|
||||
"# Create summary model\n",
|
||||
"summary = Summary()"
|
||||
],
|
||||
"execution_count": null,
|
||||
"outputs": []
|
||||
},
|
||||
{
|
||||
"cell_type": "markdown",
|
||||
"metadata": {
|
||||
"id": "-vGR_piwZZO6"
|
||||
},
|
||||
"source": [
|
||||
"# Summarize text\n",
|
||||
"\n",
|
||||
"The example below shows how a large block of text can be distilled down into a smaller summary."
|
||||
]
|
||||
},
|
||||
{
|
||||
"cell_type": "code",
|
||||
"metadata": {
|
||||
"colab": {
|
||||
"base_uri": "https://localhost:8080/",
|
||||
"height": 36
|
||||
},
|
||||
"id": "-K2YJJzsVtfq",
|
||||
"outputId": "206ce562-d8e2-4777-a04c-f888e866e08c"
|
||||
},
|
||||
"source": [
|
||||
"text = (\"Search is the base of many applications. Once data starts to pile up, users want to be able to find it. It’s the foundation \"\n",
|
||||
" \"of the internet and an ever-growing challenge that is never solved or done. The field of Natural Language Processing (NLP) is \"\n",
|
||||
" \"rapidly evolving with a number of new developments. Large-scale general language models are an exciting new capability \"\n",
|
||||
" \"allowing us to add amazing functionality quickly with limited compute and people. Innovation continues with new models \"\n",
|
||||
" \"and advancements coming in at what seems a weekly basis. This article introduces txtai, an AI-powered search engine \"\n",
|
||||
" \"that enables Natural Language Understanding (NLU) based search in any application.\"\n",
|
||||
")\n",
|
||||
"\n",
|
||||
"summary(text, maxlength=10)"
|
||||
],
|
||||
"execution_count": null,
|
||||
"outputs": [
|
||||
{
|
||||
"output_type": "execute_result",
|
||||
"data": {
|
||||
"application/vnd.google.colaboratory.intrinsic+json": {
|
||||
"type": "string"
|
||||
},
|
||||
"text/plain": [
|
||||
"'Search is the foundation of the internet'"
|
||||
]
|
||||
},
|
||||
"metadata": {
|
||||
"tags": []
|
||||
},
|
||||
"execution_count": 7
|
||||
}
|
||||
]
|
||||
},
|
||||
{
|
||||
"cell_type": "markdown",
|
||||
"metadata": {
|
||||
"id": "n2jndgE-JyWX"
|
||||
},
|
||||
"source": [
|
||||
"Notice how the summarizer built a sentence using parts of the document above. It takes a basic understanding of language in order to understand the first two sentences and how to combine them into a single transformative sentence."
|
||||
]
|
||||
},
|
||||
{
|
||||
"cell_type": "markdown",
|
||||
"metadata": {
|
||||
"id": "27PneZxQx7NR"
|
||||
},
|
||||
"source": [
|
||||
"# Summarize a document\n",
|
||||
"\n",
|
||||
"The next section retrieves an article, extracts text from it (more to come on this topic) and summarizes that text."
|
||||
]
|
||||
},
|
||||
{
|
||||
"cell_type": "code",
|
||||
"metadata": {
|
||||
"colab": {
|
||||
"base_uri": "https://localhost:8080/",
|
||||
"height": 53
|
||||
},
|
||||
"id": "idPThgJGvIju",
|
||||
"outputId": "08fa324d-3be3-48f7-f3d1-531ca545299b"
|
||||
},
|
||||
"source": [
|
||||
"!wget -q \"https://medium.com/neuml/time-lapse-video-for-the-web-a7d8874ff397\"\n",
|
||||
"\n",
|
||||
"from txtai.pipeline import Textractor\n",
|
||||
"\n",
|
||||
"textractor = Textractor()\n",
|
||||
"text = textractor(\"time-lapse-video-for-the-web-a7d8874ff397\")\n",
|
||||
"\n",
|
||||
"summary(text)"
|
||||
],
|
||||
"execution_count": null,
|
||||
"outputs": [
|
||||
{
|
||||
"output_type": "execute_result",
|
||||
"data": {
|
||||
"application/vnd.google.colaboratory.intrinsic+json": {
|
||||
"type": "string"
|
||||
},
|
||||
"text/plain": [
|
||||
"'Time-lapse video is a popular way to show an area or event over a long period of time. The same concept can be applied to a dynamic real-time website with frequently updated data. webelapse is an open source project developed to provide this functionality. It can be used as is or modified for different use cases.'"
|
||||
]
|
||||
},
|
||||
"metadata": {
|
||||
"tags": []
|
||||
},
|
||||
"execution_count": 9
|
||||
}
|
||||
]
|
||||
},
|
||||
{
|
||||
"cell_type": "markdown",
|
||||
"metadata": {
|
||||
"id": "a63k89aDyKTW"
|
||||
},
|
||||
"source": [
|
||||
"Click through the link to see the full article. This summary does a pretty good job of covering what the article is about!"
|
||||
]
|
||||
}
|
||||
]
|
||||
}
|
||||
@@ -0,0 +1,255 @@
|
||||
{
|
||||
"nbformat": 4,
|
||||
"nbformat_minor": 0,
|
||||
"metadata": {
|
||||
"colab": {
|
||||
"name": "10 - Extract text from documents",
|
||||
"provenance": [],
|
||||
"collapsed_sections": []
|
||||
},
|
||||
"kernelspec": {
|
||||
"name": "python3",
|
||||
"display_name": "Python 3"
|
||||
}
|
||||
},
|
||||
"cells": [
|
||||
{
|
||||
"cell_type": "markdown",
|
||||
"metadata": {
|
||||
"id": "4Pjmz-RORV8E"
|
||||
},
|
||||
"source": [
|
||||
"# Extract text from documents\n",
|
||||
"\n",
|
||||
"Up to this point, all the examples have been working with sections of text, which have already been split through some other means. What happens if we're working with documents? First we need to get the text out of these documents, then figure out how to index to best support similarity search.\n",
|
||||
"\n",
|
||||
"This notebook shows how documents can have text extracted and segmented to support similarity search."
|
||||
]
|
||||
},
|
||||
{
|
||||
"cell_type": "markdown",
|
||||
"metadata": {
|
||||
"id": "Dk31rbYjSTYm"
|
||||
},
|
||||
"source": [
|
||||
"# Install dependencies\n",
|
||||
"\n",
|
||||
"Install `txtai` and all dependencies. Since this notebook is using optional pipelines, we need to install the pipeline extras package."
|
||||
]
|
||||
},
|
||||
{
|
||||
"cell_type": "code",
|
||||
"metadata": {
|
||||
"id": "XMQuuun2R06J"
|
||||
},
|
||||
"source": [
|
||||
"%%capture\n",
|
||||
"!pip install git+https://github.com/neuml/txtai#egg=txtai[pipeline]\n",
|
||||
"\n",
|
||||
"# Get test data\n",
|
||||
"!wget -N https://github.com/neuml/txtai/releases/download/v2.0.0/tests.tar.gz\n",
|
||||
"!tar -xvzf tests.tar.gz\n",
|
||||
"\n",
|
||||
"# Install NLTK\n",
|
||||
"import nltk\n",
|
||||
"nltk.download('punkt')"
|
||||
],
|
||||
"execution_count": null,
|
||||
"outputs": []
|
||||
},
|
||||
{
|
||||
"cell_type": "markdown",
|
||||
"metadata": {
|
||||
"id": "PNPJ95cdTKSS"
|
||||
},
|
||||
"source": [
|
||||
"# Create a Textractor instance\n",
|
||||
"\n",
|
||||
"The Textractor instance is the main entrypoint for extracting text. This method is backed by Apache Tika, a robust text extraction library written in Java. [Apache Tika](https://tika.apache.org/0.9/formats.html) has support for a large number of file formats: PDF, Word, Excel, HTML and others. The [Python Tika package](https://github.com/chrismattmann/tika-python) automatically installs Tika and starts a local REST API instance used to read extracted data.\n",
|
||||
"\n",
|
||||
"*Note: This requires Java to be installed locally.*"
|
||||
]
|
||||
},
|
||||
{
|
||||
"cell_type": "code",
|
||||
"metadata": {
|
||||
"id": "nTDwXOUeTH2-"
|
||||
},
|
||||
"source": [
|
||||
"%%capture\n",
|
||||
"\n",
|
||||
"from txtai.pipeline import Textractor\n",
|
||||
"\n",
|
||||
"# Create textractor model\n",
|
||||
"textractor = Textractor()"
|
||||
],
|
||||
"execution_count": null,
|
||||
"outputs": []
|
||||
},
|
||||
{
|
||||
"cell_type": "markdown",
|
||||
"metadata": {
|
||||
"id": "-vGR_piwZZO6"
|
||||
},
|
||||
"source": [
|
||||
"# Extract text\n",
|
||||
"\n",
|
||||
"The example below shows how to extract text from a file."
|
||||
]
|
||||
},
|
||||
{
|
||||
"cell_type": "code",
|
||||
"metadata": {
|
||||
"colab": {
|
||||
"base_uri": "https://localhost:8080/",
|
||||
"height": 106
|
||||
},
|
||||
"id": "-K2YJJzsVtfq",
|
||||
"outputId": "8fef4c23-2f11-49d8-febd-c12dfb872d65"
|
||||
},
|
||||
"source": [
|
||||
"textractor(\"txtai/article.pdf\")"
|
||||
],
|
||||
"execution_count": null,
|
||||
"outputs": [
|
||||
{
|
||||
"output_type": "execute_result",
|
||||
"data": {
|
||||
"application/vnd.google.colaboratory.intrinsic+json": {
|
||||
"type": "string"
|
||||
},
|
||||
"text/plain": [
|
||||
"'Introducing txtai, an AI-powered search engine built on Transformers Add Natural Language Understanding to any application Search is the base of many applications. Once data starts to pile up, users want to be able to find it. It’s the foundation of the internet and an ever-growing challenge that is never solved or done. The field of Natural Language Processing (NLP) is rapidly evolving with a number of new developments. Large-scale general language models are an exciting new capability allowing us to add amazing functionality quickly with limited compute and people. Innovation continues with new models and advancements coming in at what seems a weekly basis. This article introduces txtai, an AI-powered search engine that enables Natural Language Understanding (NLU) based search in any application. Introducing txtai txtai builds an AI-powered index over sections of text. txtai supports building text indices to perform similarity searches and create extractive question-answering based systems. txtai also has functionality for zero-shot classification. txtai is open source and available on GitHub. txtai and/or the concepts behind it has already been used to power the Natural Language Processing (NLP) applications listed below: • paperai — AI-powered literature discovery and review engine for medical/scientific papers • tldrstory — AI-powered understanding of headlines and story text • neuspo — Fact-driven, real-time sports event and news site • codequestion — Ask coding questions directly from the terminal Build an Embeddings index For small lists of texts, the method above works. But for larger repositories of documents, it doesn’t make sense to tokenize and convert all embeddings for each query. txtai supports building pre- computed indices which significantly improves performance. Building on the previous example, the following example runs an index method to build and store the text embeddings. In this case, only the query is converted to an embeddings vector each search. https://github.com/neuml/codequestion https://neuspo.com/ https://github.com/neuml/tldrstory https://github.com/neuml/paperai Introducing txtai, an AI-powered search engine built on Transformers Add Natural Language Understanding to any application Introducing txtai Build an Embeddings index'"
|
||||
]
|
||||
},
|
||||
"metadata": {
|
||||
"tags": []
|
||||
},
|
||||
"execution_count": 3
|
||||
}
|
||||
]
|
||||
},
|
||||
{
|
||||
"cell_type": "markdown",
|
||||
"metadata": {
|
||||
"id": "n2jndgE-JyWX"
|
||||
},
|
||||
"source": [
|
||||
"Note that the text from the article was extracted into a single string. Depending on the articles, this may be acceptable. For long articles, often you'll want to split the content into logical sections to build better downstream vectors."
|
||||
]
|
||||
},
|
||||
{
|
||||
"cell_type": "markdown",
|
||||
"metadata": {
|
||||
"id": "1w2bhBCPOUdu"
|
||||
},
|
||||
"source": [
|
||||
"# Extract sentences"
|
||||
]
|
||||
},
|
||||
{
|
||||
"cell_type": "code",
|
||||
"metadata": {
|
||||
"colab": {
|
||||
"base_uri": "https://localhost:8080/"
|
||||
},
|
||||
"id": "PKZVK5vuOTqB",
|
||||
"outputId": "a2ca70f6-791b-468e-f7f5-17cf1ddbfbf6"
|
||||
},
|
||||
"source": [
|
||||
"textractor = Textractor(sentences=True)\n",
|
||||
"textractor(\"txtai/article.pdf\")"
|
||||
],
|
||||
"execution_count": null,
|
||||
"outputs": [
|
||||
{
|
||||
"output_type": "execute_result",
|
||||
"data": {
|
||||
"text/plain": [
|
||||
"['Introducing txtai, an AI-powered search engine built on Transformers Add Natural Language Understanding to any application Search is the base of many applications.',\n",
|
||||
" 'Once data starts to pile up, users want to be able to find it.',\n",
|
||||
" 'It’s the foundation of the internet and an ever-growing challenge that is never solved or done.',\n",
|
||||
" 'The field of Natural Language Processing (NLP) is rapidly evolving with a number of new developments.',\n",
|
||||
" 'Large-scale general language models are an exciting new capability allowing us to add amazing functionality quickly with limited compute and people.',\n",
|
||||
" 'Innovation continues with new models and advancements coming in at what seems a weekly basis.',\n",
|
||||
" 'This article introduces txtai, an AI-powered search engine that enables Natural Language Understanding (NLU) based search in any application.',\n",
|
||||
" 'Introducing txtai txtai builds an AI-powered index over sections of text.',\n",
|
||||
" 'txtai supports building text indices to perform similarity searches and create extractive question-answering based systems.',\n",
|
||||
" 'txtai also has functionality for zero-shot classification.',\n",
|
||||
" 'txtai is open source and available on GitHub.',\n",
|
||||
" 'txtai and/or the concepts behind it has already been used to power the Natural Language Processing (NLP) applications listed below: • paperai — AI-powered literature discovery and review engine for medical/scientific papers • tldrstory — AI-powered understanding of headlines and story text • neuspo — Fact-driven, real-time sports event and news site • codequestion — Ask coding questions directly from the terminal Build an Embeddings index For small lists of texts, the method above works.',\n",
|
||||
" 'But for larger repositories of documents, it doesn’t make sense to tokenize and convert all embeddings for each query.',\n",
|
||||
" 'txtai supports building pre- computed indices which significantly improves performance.',\n",
|
||||
" 'Building on the previous example, the following example runs an index method to build and store the text embeddings.',\n",
|
||||
" 'In this case, only the query is converted to an embeddings vector each search.',\n",
|
||||
" 'https://github.com/neuml/codequestion https://neuspo.com/ https://github.com/neuml/tldrstory https://github.com/neuml/paperai Introducing txtai, an AI-powered search engine built on Transformers Add Natural Language Understanding to any application Introducing txtai Build an Embeddings index']"
|
||||
]
|
||||
},
|
||||
"metadata": {
|
||||
"tags": []
|
||||
},
|
||||
"execution_count": 4
|
||||
}
|
||||
]
|
||||
},
|
||||
{
|
||||
"cell_type": "markdown",
|
||||
"metadata": {
|
||||
"id": "vdVCCc9UOv5S"
|
||||
},
|
||||
"source": [
|
||||
"Now the document is split up at the sentence level. These sentences can be feed to a workflow that adds each sentence to an embeddings index. Depending on the task, this may work well. Alternatively, it may be even better to split at the paragraph level."
|
||||
]
|
||||
},
|
||||
{
|
||||
"cell_type": "markdown",
|
||||
"metadata": {
|
||||
"id": "z1H8XYkaSoP4"
|
||||
},
|
||||
"source": [
|
||||
"# Extract paragraphs"
|
||||
]
|
||||
},
|
||||
{
|
||||
"cell_type": "code",
|
||||
"metadata": {
|
||||
"colab": {
|
||||
"base_uri": "https://localhost:8080/"
|
||||
},
|
||||
"id": "9VUito4ISoAe",
|
||||
"outputId": "305200a6-a180-4e41-dae2-d46ce336c801"
|
||||
},
|
||||
"source": [
|
||||
"textractor = Textractor(paragraphs=True)\n",
|
||||
"textractor(\"txtai/article.pdf\")"
|
||||
],
|
||||
"execution_count": null,
|
||||
"outputs": [
|
||||
{
|
||||
"output_type": "execute_result",
|
||||
"data": {
|
||||
"text/plain": [
|
||||
"['Introducing txtai, an AI-powered search engine built on Transformers',\n",
|
||||
" 'Add Natural Language Understanding to any application',\n",
|
||||
" 'Search is the base of many applications. Once data starts to pile up, users want to be able to find it. It’s the foundation of the internet and an ever-growing challenge that is never solved or done.',\n",
|
||||
" 'The field of Natural Language Processing (NLP) is rapidly evolving with a number of new developments. Large-scale general language models are an exciting new capability allowing us to add amazing functionality quickly with limited compute and people. Innovation continues with new models and advancements coming in at what seems a weekly basis.',\n",
|
||||
" 'This article introduces txtai, an AI-powered search engine that enables Natural Language Understanding (NLU) based search in any application.',\n",
|
||||
" 'Introducing txtai txtai builds an AI-powered index over sections of text. txtai supports building text indices to perform similarity searches and create extractive question-answering based systems. txtai also has functionality for zero-shot classification. txtai is open source and available on GitHub.',\n",
|
||||
" 'txtai and/or the concepts behind it has already been used to power the Natural Language Processing (NLP) applications listed below:',\n",
|
||||
" '• paperai — AI-powered literature discovery and review engine for medical/scientific papers • tldrstory — AI-powered understanding of headlines and story text • neuspo — Fact-driven, real-time sports event and news site • codequestion — Ask coding questions directly from the terminal',\n",
|
||||
" 'Build an Embeddings index For small lists of texts, the method above works. But for larger repositories of documents, it doesn’t make sense to tokenize and convert all embeddings for each query. txtai supports building pre- computed indices which significantly improves performance.',\n",
|
||||
" 'Building on the previous example, the following example runs an index method to build and store the text embeddings. In this case, only the query is converted to an embeddings vector each search.',\n",
|
||||
" 'https://github.com/neuml/codequestion https://neuspo.com/ https://github.com/neuml/tldrstory https://github.com/neuml/paperai',\n",
|
||||
" 'Introducing txtai, an AI-powered search engine built on Transformers Add Natural Language Understanding to any application',\n",
|
||||
" 'Introducing txtai Build an Embeddings index']"
|
||||
]
|
||||
},
|
||||
"metadata": {
|
||||
"tags": []
|
||||
},
|
||||
"execution_count": 5
|
||||
}
|
||||
]
|
||||
}
|
||||
]
|
||||
}
|
||||
File diff suppressed because one or more lines are too long
@@ -0,0 +1,229 @@
|
||||
{
|
||||
"nbformat": 4,
|
||||
"nbformat_minor": 0,
|
||||
"metadata": {
|
||||
"colab": {
|
||||
"name": "12 - Translate text between languages",
|
||||
"provenance": [],
|
||||
"collapsed_sections": []
|
||||
},
|
||||
"kernelspec": {
|
||||
"display_name": "Python 3",
|
||||
"name": "python3"
|
||||
}
|
||||
},
|
||||
"cells": [
|
||||
{
|
||||
"cell_type": "markdown",
|
||||
"metadata": {
|
||||
"id": "4Pjmz-RORV8E"
|
||||
},
|
||||
"source": [
|
||||
"# Translate text between languages\n",
|
||||
"\n",
|
||||
"This notebook covers machine translation backed by Hugging Face models. The quality of machine translation via cloud services has come a very long way and produces high quality results. This notebook shows how the models from Hugging Face give developers a reasonable alternative for local machine translation."
|
||||
]
|
||||
},
|
||||
{
|
||||
"cell_type": "markdown",
|
||||
"metadata": {
|
||||
"id": "Dk31rbYjSTYm"
|
||||
},
|
||||
"source": [
|
||||
"# Install dependencies\n",
|
||||
"\n",
|
||||
"Install `txtai` and all dependencies. Since this notebook is using optional pipelines, we need to install the pipeline extras package."
|
||||
]
|
||||
},
|
||||
{
|
||||
"cell_type": "code",
|
||||
"metadata": {
|
||||
"id": "XMQuuun2R06J"
|
||||
},
|
||||
"source": [
|
||||
"%%capture\n",
|
||||
"!pip install git+https://github.com/neuml/txtai#egg=txtai[pipeline]"
|
||||
],
|
||||
"execution_count": null,
|
||||
"outputs": []
|
||||
},
|
||||
{
|
||||
"cell_type": "markdown",
|
||||
"metadata": {
|
||||
"id": "PNPJ95cdTKSS"
|
||||
},
|
||||
"source": [
|
||||
"# Create a Translation instance\n",
|
||||
"\n",
|
||||
"The Translation instance is the main entrypoint for translating text between languages. The pipeline abstracts translating text into a one line call! \n",
|
||||
"\n",
|
||||
"The pipeline has logic to detect the input language, load the relevant model that handles translating from source to target language and return results. The translation pipeline also has built-in logic to handle splitting large text blocks into smaller sections the models can handle.\n",
|
||||
"\n"
|
||||
]
|
||||
},
|
||||
{
|
||||
"cell_type": "code",
|
||||
"metadata": {
|
||||
"id": "nTDwXOUeTH2-"
|
||||
},
|
||||
"source": [
|
||||
"%%capture\n",
|
||||
"\n",
|
||||
"from txtai.pipeline import Translation\n",
|
||||
"\n",
|
||||
"# Create translation model\n",
|
||||
"translate = Translation()"
|
||||
],
|
||||
"execution_count": null,
|
||||
"outputs": []
|
||||
},
|
||||
{
|
||||
"cell_type": "markdown",
|
||||
"metadata": {
|
||||
"id": "-vGR_piwZZO6"
|
||||
},
|
||||
"source": [
|
||||
"# Translate text\n",
|
||||
"\n",
|
||||
"The example below shows how to translate text from English to Spanish. This text is then translated back to English."
|
||||
]
|
||||
},
|
||||
{
|
||||
"cell_type": "code",
|
||||
"metadata": {
|
||||
"colab": {
|
||||
"base_uri": "https://localhost:8080/",
|
||||
"height": 36
|
||||
},
|
||||
"id": "-K2YJJzsVtfq",
|
||||
"outputId": "3beede7b-0996-466b-e922-fc3da23e7eda"
|
||||
},
|
||||
"source": [
|
||||
"translation = translate(\"This is a test translation into Spanish\", \"es\")\n",
|
||||
"translation"
|
||||
],
|
||||
"execution_count": null,
|
||||
"outputs": [
|
||||
{
|
||||
"output_type": "execute_result",
|
||||
"data": {
|
||||
"application/vnd.google.colaboratory.intrinsic+json": {
|
||||
"type": "string"
|
||||
},
|
||||
"text/plain": [
|
||||
"'Esta es una traducción de prueba al español'"
|
||||
]
|
||||
},
|
||||
"metadata": {
|
||||
"tags": []
|
||||
},
|
||||
"execution_count": 8
|
||||
}
|
||||
]
|
||||
},
|
||||
{
|
||||
"cell_type": "code",
|
||||
"metadata": {
|
||||
"colab": {
|
||||
"base_uri": "https://localhost:8080/",
|
||||
"height": 36
|
||||
},
|
||||
"id": "K_UnAZQpetM8",
|
||||
"outputId": "ec3ec2ef-4f97-4529-aa08-863fdea07506"
|
||||
},
|
||||
"source": [
|
||||
"translate(translation, \"en\")"
|
||||
],
|
||||
"execution_count": null,
|
||||
"outputs": [
|
||||
{
|
||||
"output_type": "execute_result",
|
||||
"data": {
|
||||
"application/vnd.google.colaboratory.intrinsic+json": {
|
||||
"type": "string"
|
||||
},
|
||||
"text/plain": [
|
||||
"'This is a test translation into Spanish'"
|
||||
]
|
||||
},
|
||||
"metadata": {
|
||||
"tags": []
|
||||
},
|
||||
"execution_count": 9
|
||||
}
|
||||
]
|
||||
},
|
||||
{
|
||||
"cell_type": "markdown",
|
||||
"metadata": {
|
||||
"id": "4cSI8GdtjhEM"
|
||||
},
|
||||
"source": [
|
||||
"# Translating multiple languages in a single call\n",
|
||||
"\n",
|
||||
"The section below translates a single English sentence into 5 different languages. The results are then passed to a single translation call to translate back into English. The pipeline detects each input language and is able to load the relevant translation models."
|
||||
]
|
||||
},
|
||||
{
|
||||
"cell_type": "code",
|
||||
"metadata": {
|
||||
"id": "8jLxGtwNf0Aj",
|
||||
"colab": {
|
||||
"base_uri": "https://localhost:8080/"
|
||||
},
|
||||
"outputId": "68bd189a-36e6-4148-cc39-868a33e60c53"
|
||||
},
|
||||
"source": [
|
||||
"languages = [\"fr\", \"es\", \"de\", \"hi\", \"ja\"]\n",
|
||||
"\n",
|
||||
"translations = [translate(\"The sky is blue, the stars are far\", language) for language in languages]\n",
|
||||
"\n",
|
||||
"english = translate(translations, \"en\")\n",
|
||||
"\n",
|
||||
"for x, text in enumerate(translations):\n",
|
||||
" print(\"Original Language: %s\" % languages[x])\n",
|
||||
" print(\"Translation: %s\" % text)\n",
|
||||
" print(\"Back to English: %s\" % english[x])\n",
|
||||
" print()\n"
|
||||
],
|
||||
"execution_count": null,
|
||||
"outputs": [
|
||||
{
|
||||
"output_type": "stream",
|
||||
"text": [
|
||||
"Original Language: fr\n",
|
||||
"Translation: Le ciel est bleu, les étoiles sont loin\n",
|
||||
"Back to English: The sky is blue, the stars are far away\n",
|
||||
"\n",
|
||||
"Original Language: es\n",
|
||||
"Translation: El cielo es azul, las estrellas están lejos.\n",
|
||||
"Back to English: The sky is blue, the stars are far away.\n",
|
||||
"\n",
|
||||
"Original Language: de\n",
|
||||
"Translation: Der Himmel ist blau, die Sterne sind weit\n",
|
||||
"Back to English: The sky is blue, the stars are wide\n",
|
||||
"\n",
|
||||
"Original Language: hi\n",
|
||||
"Translation: आकाश नीला है, तारे दूर हैं\n",
|
||||
"Back to English: Sky is blue, stars are away\n",
|
||||
"\n",
|
||||
"Original Language: ja\n",
|
||||
"Translation: 天は青い、星は遠い。\n",
|
||||
"Back to English: The heavens are blue and the stars are far away.\n",
|
||||
"\n"
|
||||
],
|
||||
"name": "stdout"
|
||||
}
|
||||
]
|
||||
},
|
||||
{
|
||||
"cell_type": "markdown",
|
||||
"metadata": {
|
||||
"id": "Xn3SlVE1LYvm"
|
||||
},
|
||||
"source": [
|
||||
"The translation quality overall is very high. Machine translation has made giant leaps and strides the last couple of years. These models give developers a solid alternative to cloud translation services if translating on local servers is preferred."
|
||||
]
|
||||
}
|
||||
]
|
||||
}
|
||||
File diff suppressed because one or more lines are too long
File diff suppressed because one or more lines are too long
@@ -0,0 +1,522 @@
|
||||
{
|
||||
"nbformat": 4,
|
||||
"nbformat_minor": 0,
|
||||
"metadata": {
|
||||
"colab": {
|
||||
"name": "15 - Distributed embeddings cluster",
|
||||
"provenance": [],
|
||||
"collapsed_sections": []
|
||||
},
|
||||
"kernelspec": {
|
||||
"name": "python3",
|
||||
"display_name": "Python 3"
|
||||
}
|
||||
},
|
||||
"cells": [
|
||||
{
|
||||
"cell_type": "markdown",
|
||||
"metadata": {
|
||||
"id": "4Pjmz-RORV8E"
|
||||
},
|
||||
"source": [
|
||||
"# Distributed embeddings cluster\n",
|
||||
"\n",
|
||||
"The txtai API is a web-based service backed by [FastAPI](https://fastapi.tiangolo.com/). All txtai functionality is available via the API. The API can also cluster multiple embeddings indices into a single logical index to horizontally scale over multiple nodes. \n",
|
||||
"\n",
|
||||
"This notebook installs the txtai API and shows an example of building an embeddings cluster."
|
||||
]
|
||||
},
|
||||
{
|
||||
"cell_type": "markdown",
|
||||
"metadata": {
|
||||
"id": "Dk31rbYjSTYm"
|
||||
},
|
||||
"source": [
|
||||
"# Install dependencies\n",
|
||||
"\n",
|
||||
"Install `txtai` and all dependencies. Since this notebook uses the API, we need to install the api extras package."
|
||||
]
|
||||
},
|
||||
{
|
||||
"cell_type": "code",
|
||||
"metadata": {
|
||||
"id": "XMQuuun2R06J"
|
||||
},
|
||||
"source": [
|
||||
"%%capture\n",
|
||||
"!pip install git+https://github.com/neuml/txtai#egg=txtai[api]"
|
||||
],
|
||||
"execution_count": null,
|
||||
"outputs": []
|
||||
},
|
||||
{
|
||||
"cell_type": "markdown",
|
||||
"metadata": {
|
||||
"id": "PNPJ95cdTKSS"
|
||||
},
|
||||
"source": [
|
||||
"# Start distributed embeddings cluster\n",
|
||||
"\n",
|
||||
"First we'll start multiple API instances that will serve as embeddings index shards. Each shard stores a subset of the indexed data and these shards work in tandem to form a single logical index.\n",
|
||||
"\n",
|
||||
"Then we'll start the main API instance that clusters the shards together into a logical instance.\n",
|
||||
"\n",
|
||||
"The API instances are all started in the background.\n"
|
||||
]
|
||||
},
|
||||
{
|
||||
"cell_type": "code",
|
||||
"metadata": {
|
||||
"id": "USb4JXZHxqTA"
|
||||
},
|
||||
"source": [
|
||||
"import os\n",
|
||||
"os.chdir(\"/content\")"
|
||||
],
|
||||
"execution_count": null,
|
||||
"outputs": []
|
||||
},
|
||||
{
|
||||
"cell_type": "code",
|
||||
"metadata": {
|
||||
"id": "nTDwXOUeTH2-",
|
||||
"colab": {
|
||||
"base_uri": "https://localhost:8080/"
|
||||
},
|
||||
"outputId": "e558af81-3e1b-4ab9-d8ee-d69acca8a85a"
|
||||
},
|
||||
"source": [
|
||||
"%%writefile index.yml\n",
|
||||
"writable: true\n",
|
||||
"\n",
|
||||
"# Embeddings settings\n",
|
||||
"embeddings:\n",
|
||||
" path: sentence-transformers/nli-mpnet-base-v2"
|
||||
],
|
||||
"execution_count": null,
|
||||
"outputs": [
|
||||
{
|
||||
"output_type": "stream",
|
||||
"text": [
|
||||
"Writing index.yml\n"
|
||||
],
|
||||
"name": "stdout"
|
||||
}
|
||||
]
|
||||
},
|
||||
{
|
||||
"cell_type": "code",
|
||||
"metadata": {
|
||||
"colab": {
|
||||
"base_uri": "https://localhost:8080/"
|
||||
},
|
||||
"id": "iCdBh-JgfyBl",
|
||||
"outputId": "a829793a-9223-40f8-d1d2-286fbbc4f341"
|
||||
},
|
||||
"source": [
|
||||
"%%writefile cluster.yml\n",
|
||||
"# Embeddings cluster\n",
|
||||
"cluster:\n",
|
||||
" shards:\n",
|
||||
" - http://127.0.0.1:8001\n",
|
||||
" - http://127.0.0.1:8002"
|
||||
],
|
||||
"execution_count": null,
|
||||
"outputs": [
|
||||
{
|
||||
"output_type": "stream",
|
||||
"text": [
|
||||
"Writing cluster.yml\n"
|
||||
],
|
||||
"name": "stdout"
|
||||
}
|
||||
]
|
||||
},
|
||||
{
|
||||
"cell_type": "code",
|
||||
"metadata": {
|
||||
"id": "nGITHxUyRzyp"
|
||||
},
|
||||
"source": [
|
||||
"# Start embeddings shards\n",
|
||||
"!CONFIG=index.yml nohup uvicorn --port 8001 \"txtai.api:app\" &> shard-1.log &\n",
|
||||
"!CONFIG=index.yml nohup uvicorn --port 8002 \"txtai.api:app\" &> shard-2.log &\n",
|
||||
"\n",
|
||||
"# Start main instance\n",
|
||||
"!CONFIG=cluster.yml nohup uvicorn --port 8000 \"txtai.api:app\" &> main.log &\n",
|
||||
"\n",
|
||||
"# Wait for startup\n",
|
||||
"!sleep 90"
|
||||
],
|
||||
"execution_count": null,
|
||||
"outputs": []
|
||||
},
|
||||
{
|
||||
"cell_type": "markdown",
|
||||
"metadata": {
|
||||
"id": "lxkbVng3giWP"
|
||||
},
|
||||
"source": [
|
||||
"# Python\n",
|
||||
"\n",
|
||||
"Let's first try the cluster out directly in Python. The code below aggregates the two shards into a single cluster and executes actions against the cluster."
|
||||
]
|
||||
},
|
||||
{
|
||||
"cell_type": "code",
|
||||
"metadata": {
|
||||
"colab": {
|
||||
"base_uri": "https://localhost:8080/"
|
||||
},
|
||||
"id": "36HGAokoglfg",
|
||||
"outputId": "38c551dd-a51a-4093-e0d3-a733c11fc531"
|
||||
},
|
||||
"source": [
|
||||
"%%writefile run.py\n",
|
||||
"from txtai.api import Cluster\n",
|
||||
"\n",
|
||||
"cluster = Cluster({\"shards\": [\"http://127.0.0.1:8001\", \"http://127.0.0.1:8002\"]})\n",
|
||||
"\n",
|
||||
"data = [\n",
|
||||
" \"US tops 5 million confirmed virus cases\",\n",
|
||||
" \"Canada's last fully intact ice shelf has suddenly collapsed, forming a Manhattan-sized iceberg\",\n",
|
||||
" \"Beijing mobilises invasion craft along coast as Taiwan tensions escalate\",\n",
|
||||
" \"The National Park Service warns against sacrificing slower friends in a bear attack\",\n",
|
||||
" \"Maine man wins $1M from $25 lottery ticket\",\n",
|
||||
" \"Make huge profits without work, earn up to $100,000 a day\",\n",
|
||||
"]\n",
|
||||
"\n",
|
||||
"# Index data\n",
|
||||
"cluster.add([{\"id\": x, \"text\": row} for x, row in enumerate(data)])\n",
|
||||
"cluster.index()\n",
|
||||
"\n",
|
||||
"# Test search\n",
|
||||
"uid = cluster.search(\"feel good story\", 1)[0][\"id\"]\n",
|
||||
"print(\"Query: feel good story\\nResult:\", data[uid])"
|
||||
],
|
||||
"execution_count": null,
|
||||
"outputs": [
|
||||
{
|
||||
"output_type": "stream",
|
||||
"text": [
|
||||
"Writing run.py\n"
|
||||
],
|
||||
"name": "stdout"
|
||||
}
|
||||
]
|
||||
},
|
||||
{
|
||||
"cell_type": "code",
|
||||
"metadata": {
|
||||
"colab": {
|
||||
"base_uri": "https://localhost:8080/"
|
||||
},
|
||||
"id": "6dQOzcfEs2Pk",
|
||||
"outputId": "1a75935d-a8fc-4c32-c450-4bc826681f8f"
|
||||
},
|
||||
"source": [
|
||||
"!python run.py"
|
||||
],
|
||||
"execution_count": null,
|
||||
"outputs": [
|
||||
{
|
||||
"output_type": "stream",
|
||||
"text": [
|
||||
"Query: feel good story\n",
|
||||
"Result: Maine man wins $1M from $25 lottery ticket\n"
|
||||
],
|
||||
"name": "stdout"
|
||||
}
|
||||
]
|
||||
},
|
||||
{
|
||||
"cell_type": "markdown",
|
||||
"metadata": {
|
||||
"id": "NHvBFZeSd9AG"
|
||||
},
|
||||
"source": [
|
||||
"# JavaScript\n",
|
||||
"\n",
|
||||
"Next let's try to run the same code above via the API using JavaScript.\n",
|
||||
"\n",
|
||||
"```bash\n",
|
||||
"npm install txtai\n",
|
||||
"```\n",
|
||||
"\n",
|
||||
"For this example, we'll clone the txtai.js project to import the example build configuration."
|
||||
]
|
||||
},
|
||||
{
|
||||
"cell_type": "code",
|
||||
"metadata": {
|
||||
"id": "b52knObEdcCr"
|
||||
},
|
||||
"source": [
|
||||
"%%capture\n",
|
||||
"!git clone https://github.com/neuml/txtai.js"
|
||||
],
|
||||
"execution_count": null,
|
||||
"outputs": []
|
||||
},
|
||||
{
|
||||
"cell_type": "markdown",
|
||||
"metadata": {
|
||||
"id": "rUGS0t-JMsS9"
|
||||
},
|
||||
"source": [
|
||||
"## Run cluster.js\n",
|
||||
"\n",
|
||||
"The following script is a JavaScript version of the logic above"
|
||||
]
|
||||
},
|
||||
{
|
||||
"cell_type": "code",
|
||||
"metadata": {
|
||||
"colab": {
|
||||
"base_uri": "https://localhost:8080/"
|
||||
},
|
||||
"id": "bPQ40_xRyFmA",
|
||||
"outputId": "7f857818-9d33-425b-d530-24d1ca81d238"
|
||||
},
|
||||
"source": [
|
||||
"%%writefile txtai.js/examples/node/src/cluster.js\n",
|
||||
"import {Embeddings} from \"txtai\";\n",
|
||||
"import {sprintf} from \"sprintf-js\";\n",
|
||||
"\n",
|
||||
"const run = async () => {\n",
|
||||
" try {\n",
|
||||
" let embeddings = new Embeddings(process.argv[2]);\n",
|
||||
"\n",
|
||||
" let data = [\"US tops 5 million confirmed virus cases\",\n",
|
||||
" \"Canada's last fully intact ice shelf has suddenly collapsed, forming a Manhattan-sized iceberg\",\n",
|
||||
" \"Beijing mobilises invasion craft along coast as Taiwan tensions escalate\",\n",
|
||||
" \"The National Park Service warns against sacrificing slower friends in a bear attack\",\n",
|
||||
" \"Maine man wins $1M from $25 lottery ticket\",\n",
|
||||
" \"Make huge profits without work, earn up to $100,000 a day\"];\n",
|
||||
"\n",
|
||||
" console.log();\n",
|
||||
" console.log(\"Querying an Embeddings cluster\");\n",
|
||||
" console.log(sprintf(\"%-20s %s\", \"Query\", \"Best Match\"));\n",
|
||||
" console.log(\"-\".repeat(50));\n",
|
||||
"\n",
|
||||
" for (let query of [\"feel good story\", \"climate change\", \"public health story\", \"war\", \"wildlife\", \"asia\", \"lucky\", \"dishonest junk\"]) {\n",
|
||||
" let results = await embeddings.search(query, 1);\n",
|
||||
" let uid = results[0].id;\n",
|
||||
" console.log(sprintf(\"%-20s %s\", query, data[uid]))\n",
|
||||
" }\n",
|
||||
" }\n",
|
||||
" catch (e) {\n",
|
||||
" console.trace(e);\n",
|
||||
" }\n",
|
||||
"};\n",
|
||||
"\n",
|
||||
"run();"
|
||||
],
|
||||
"execution_count": null,
|
||||
"outputs": [
|
||||
{
|
||||
"output_type": "stream",
|
||||
"text": [
|
||||
"Writing txtai.js/examples/node/src/cluster.js\n"
|
||||
],
|
||||
"name": "stdout"
|
||||
}
|
||||
]
|
||||
},
|
||||
{
|
||||
"cell_type": "markdown",
|
||||
"metadata": {
|
||||
"id": "nTBs11j-GtD-"
|
||||
},
|
||||
"source": [
|
||||
"## Build and run cluster.js\n",
|
||||
"\n",
|
||||
"\n",
|
||||
"\n"
|
||||
]
|
||||
},
|
||||
{
|
||||
"cell_type": "code",
|
||||
"metadata": {
|
||||
"id": "kC5Oub6wa1nK"
|
||||
},
|
||||
"source": [
|
||||
"%%capture\n",
|
||||
"os.chdir(\"txtai.js/examples/node\")\n",
|
||||
"!npm install\n",
|
||||
"!npm run build"
|
||||
],
|
||||
"execution_count": null,
|
||||
"outputs": []
|
||||
},
|
||||
{
|
||||
"cell_type": "markdown",
|
||||
"metadata": {
|
||||
"id": "Xr5IlvqH8W77"
|
||||
},
|
||||
"source": [
|
||||
"Next lets run the code against the main cluster URL"
|
||||
]
|
||||
},
|
||||
{
|
||||
"cell_type": "code",
|
||||
"metadata": {
|
||||
"colab": {
|
||||
"base_uri": "https://localhost:8080/"
|
||||
},
|
||||
"id": "ckOHNqyaeL-B",
|
||||
"outputId": "4b985d2c-bf32-4ba4-bc2a-b21c80892c51"
|
||||
},
|
||||
"source": [
|
||||
"!node dist/cluster.js http://127.0.0.1:8000"
|
||||
],
|
||||
"execution_count": null,
|
||||
"outputs": [
|
||||
{
|
||||
"output_type": "stream",
|
||||
"text": [
|
||||
"\n",
|
||||
"Querying an Embeddings cluster\n",
|
||||
"Query Best Match\n",
|
||||
"--------------------------------------------------\n",
|
||||
"feel good story Maine man wins $1M from $25 lottery ticket\n",
|
||||
"climate change Canada's last fully intact ice shelf has suddenly collapsed, forming a Manhattan-sized iceberg\n",
|
||||
"public health story US tops 5 million confirmed virus cases\n",
|
||||
"war Beijing mobilises invasion craft along coast as Taiwan tensions escalate\n",
|
||||
"wildlife The National Park Service warns against sacrificing slower friends in a bear attack\n",
|
||||
"asia Beijing mobilises invasion craft along coast as Taiwan tensions escalate\n",
|
||||
"lucky Maine man wins $1M from $25 lottery ticket\n",
|
||||
"dishonest junk Make huge profits without work, earn up to $100,000 a day\n"
|
||||
],
|
||||
"name": "stdout"
|
||||
}
|
||||
]
|
||||
},
|
||||
{
|
||||
"cell_type": "markdown",
|
||||
"metadata": {
|
||||
"id": "1yukBIMYG5OE"
|
||||
},
|
||||
"source": [
|
||||
"The JavaScript program is showing the same results as the Python code above. This is running a clustered query against both nodes in the cluster and aggregating the results together.\n",
|
||||
"\n",
|
||||
"Queries can be run against each individual shard to see what the queries independently return."
|
||||
]
|
||||
},
|
||||
{
|
||||
"cell_type": "code",
|
||||
"metadata": {
|
||||
"colab": {
|
||||
"base_uri": "https://localhost:8080/"
|
||||
},
|
||||
"id": "73rZCo4O4IQR",
|
||||
"outputId": "4f5bb213-0ffe-4353-aa43-c60ec3e1c389"
|
||||
},
|
||||
"source": [
|
||||
"!node dist/cluster.js http://127.0.0.1:8001"
|
||||
],
|
||||
"execution_count": null,
|
||||
"outputs": [
|
||||
{
|
||||
"output_type": "stream",
|
||||
"text": [
|
||||
"\n",
|
||||
"Querying an Embeddings cluster\n",
|
||||
"Query Best Match\n",
|
||||
"--------------------------------------------------\n",
|
||||
"feel good story Maine man wins $1M from $25 lottery ticket\n",
|
||||
"climate change Beijing mobilises invasion craft along coast as Taiwan tensions escalate\n",
|
||||
"public health story US tops 5 million confirmed virus cases\n",
|
||||
"war Beijing mobilises invasion craft along coast as Taiwan tensions escalate\n",
|
||||
"wildlife Beijing mobilises invasion craft along coast as Taiwan tensions escalate\n",
|
||||
"asia Beijing mobilises invasion craft along coast as Taiwan tensions escalate\n",
|
||||
"lucky Maine man wins $1M from $25 lottery ticket\n",
|
||||
"dishonest junk US tops 5 million confirmed virus cases\n"
|
||||
],
|
||||
"name": "stdout"
|
||||
}
|
||||
]
|
||||
},
|
||||
{
|
||||
"cell_type": "code",
|
||||
"metadata": {
|
||||
"colab": {
|
||||
"base_uri": "https://localhost:8080/"
|
||||
},
|
||||
"id": "ZeVBLJyr4Knr",
|
||||
"outputId": "cfb1d31e-72d6-401f-c9f7-8f18aad01070"
|
||||
},
|
||||
"source": [
|
||||
"!node dist/cluster.js http://127.0.0.1:8002"
|
||||
],
|
||||
"execution_count": null,
|
||||
"outputs": [
|
||||
{
|
||||
"output_type": "stream",
|
||||
"text": [
|
||||
"\n",
|
||||
"Querying an Embeddings cluster\n",
|
||||
"Query Best Match\n",
|
||||
"--------------------------------------------------\n",
|
||||
"feel good story Make huge profits without work, earn up to $100,000 a day\n",
|
||||
"climate change Canada's last fully intact ice shelf has suddenly collapsed, forming a Manhattan-sized iceberg\n",
|
||||
"public health story The National Park Service warns against sacrificing slower friends in a bear attack\n",
|
||||
"war The National Park Service warns against sacrificing slower friends in a bear attack\n",
|
||||
"wildlife The National Park Service warns against sacrificing slower friends in a bear attack\n",
|
||||
"asia The National Park Service warns against sacrificing slower friends in a bear attack\n",
|
||||
"lucky The National Park Service warns against sacrificing slower friends in a bear attack\n",
|
||||
"dishonest junk Make huge profits without work, earn up to $100,000 a day\n"
|
||||
],
|
||||
"name": "stdout"
|
||||
}
|
||||
]
|
||||
},
|
||||
{
|
||||
"cell_type": "markdown",
|
||||
"metadata": {
|
||||
"id": "J2I_4hmZ8uXs"
|
||||
},
|
||||
"source": [
|
||||
"Note the differences. The section below runs a count against the full cluster and each shard to show the count of records in each."
|
||||
]
|
||||
},
|
||||
{
|
||||
"cell_type": "code",
|
||||
"metadata": {
|
||||
"colab": {
|
||||
"base_uri": "https://localhost:8080/"
|
||||
},
|
||||
"id": "BKm27yna4MWr",
|
||||
"outputId": "e3f24897-b043-461a-b9e3-b63677fa75f7"
|
||||
},
|
||||
"source": [
|
||||
"!curl http://127.0.0.1:8000/count\n",
|
||||
"!printf \"\\n\"\n",
|
||||
"!curl http://127.0.0.1:8001/count\n",
|
||||
"!printf \"\\n\"\n",
|
||||
"!curl http://127.0.0.1:8002/count"
|
||||
],
|
||||
"execution_count": null,
|
||||
"outputs": [
|
||||
{
|
||||
"output_type": "stream",
|
||||
"text": [
|
||||
"6\n",
|
||||
"3\n",
|
||||
"3"
|
||||
],
|
||||
"name": "stdout"
|
||||
}
|
||||
]
|
||||
},
|
||||
{
|
||||
"cell_type": "markdown",
|
||||
"metadata": {
|
||||
"id": "6rKj-I0djRQj"
|
||||
},
|
||||
"source": [
|
||||
"This notebook showed how a distributed embeddings cluster can be created with txtai. This example can be further scaled out on Kubernetes with StatefulSets, which will be covered in a future tutorial."
|
||||
]
|
||||
}
|
||||
]
|
||||
}
|
||||
@@ -0,0 +1,656 @@
|
||||
{
|
||||
"nbformat": 4,
|
||||
"nbformat_minor": 0,
|
||||
"metadata": {
|
||||
"colab": {
|
||||
"name": "16 - Train a text labeler",
|
||||
"provenance": [],
|
||||
"collapsed_sections": []
|
||||
},
|
||||
"kernelspec": {
|
||||
"name": "python3",
|
||||
"display_name": "Python 3"
|
||||
},
|
||||
"accelerator": "GPU"
|
||||
},
|
||||
"cells": [
|
||||
{
|
||||
"cell_type": "markdown",
|
||||
"metadata": {
|
||||
"id": "4Pjmz-RORV8E"
|
||||
},
|
||||
"source": [
|
||||
"# Train a text labeler\n",
|
||||
"\n",
|
||||
"The [Hugging Face Model Hub](https://huggingface.co/models) has a wide range of models that can handle many tasks. While these models perform well, the best performance often is found when fine-tuning a model with task-specific data. \n",
|
||||
"\n",
|
||||
"Hugging Face provides a [number of full-featured examples](https://github.com/huggingface/transformers/tree/master/examples) available to assist with training task-specific models. When building models from the command line, these scripts are a great way to get started.\n",
|
||||
"\n",
|
||||
"txtai provides a training pipeline that can be used to train new models programatically using the Transformers Trainer framework. The training pipeline supports the following:\n",
|
||||
"\n",
|
||||
"- Building transient models without requiring an output directory\n",
|
||||
"- Load training data from Hugging Face datasets, pandas DataFrames and list of dicts\n",
|
||||
"- Text sequence classification tasks (single/multi label classification and regression) including all GLUE tasks\n",
|
||||
"- All training arguments\n",
|
||||
"\n",
|
||||
"This notebook shows examples of how to use txtai to train/fine-tune new models."
|
||||
]
|
||||
},
|
||||
{
|
||||
"cell_type": "markdown",
|
||||
"metadata": {
|
||||
"id": "Dk31rbYjSTYm"
|
||||
},
|
||||
"source": [
|
||||
"# Install dependencies\n",
|
||||
"\n",
|
||||
"Install `txtai` and all dependencies."
|
||||
]
|
||||
},
|
||||
{
|
||||
"cell_type": "code",
|
||||
"metadata": {
|
||||
"id": "XMQuuun2R06J"
|
||||
},
|
||||
"source": [
|
||||
"%%capture\n",
|
||||
"!pip install git+https://github.com/neuml/txtai datasets pandas"
|
||||
],
|
||||
"execution_count": null,
|
||||
"outputs": []
|
||||
},
|
||||
{
|
||||
"cell_type": "markdown",
|
||||
"metadata": {
|
||||
"id": "PNPJ95cdTKSS"
|
||||
},
|
||||
"source": [
|
||||
"# Train a model\n",
|
||||
"\n",
|
||||
"Let's get right to it! The following example fine-tunes a tiny Bert model with the sst2 dataset.\n",
|
||||
"\n",
|
||||
"The trainer pipeline is basically a one-liner that fine-tunes any text classification/regression model available (locally and/or from the HF Hub). \n"
|
||||
]
|
||||
},
|
||||
{
|
||||
"cell_type": "code",
|
||||
"metadata": {
|
||||
"id": "USb4JXZHxqTA",
|
||||
"colab": {
|
||||
"base_uri": "https://localhost:8080/",
|
||||
"height": 1000
|
||||
},
|
||||
"outputId": "b251fdc6-a9c2-4a04-97fa-d0edd4bcec71"
|
||||
},
|
||||
"source": [
|
||||
"from datasets import load_dataset\n",
|
||||
"\n",
|
||||
"from txtai.pipeline import HFTrainer\n",
|
||||
"\n",
|
||||
"trainer = HFTrainer()\n",
|
||||
"\n",
|
||||
"# Hugging Face dataset\n",
|
||||
"ds = load_dataset(\"glue\", \"sst2\")\n",
|
||||
"model, tokenizer = trainer(\"google/bert_uncased_L-2_H-128_A-2\", ds[\"train\"], columns=(\"sentence\", \"label\"))"
|
||||
],
|
||||
"execution_count": null,
|
||||
"outputs": [
|
||||
{
|
||||
"output_type": "stream",
|
||||
"text": [
|
||||
"Reusing dataset glue (/root/.cache/huggingface/datasets/glue/sst2/1.0.0/dacbe3125aa31d7f70367a07a8a9e72a5a0bfeb5fc42e75c9db75b96da6053ad)\n",
|
||||
"Loading cached processed dataset at /root/.cache/huggingface/datasets/glue/sst2/1.0.0/dacbe3125aa31d7f70367a07a8a9e72a5a0bfeb5fc42e75c9db75b96da6053ad/cache-d5d88f7871fc59b7.arrow\n",
|
||||
"Some weights of the model checkpoint at google/bert_uncased_L-2_H-128_A-2 were not used when initializing BertForSequenceClassification: ['cls.predictions.bias', 'cls.predictions.decoder.weight', 'cls.predictions.decoder.bias', 'cls.predictions.transform.LayerNorm.weight', 'cls.seq_relationship.weight', 'cls.predictions.transform.dense.weight', 'cls.predictions.transform.dense.bias', 'cls.predictions.transform.LayerNorm.bias', 'cls.seq_relationship.bias']\n",
|
||||
"- This IS expected if you are initializing BertForSequenceClassification from the checkpoint of a model trained on another task or with another architecture (e.g. initializing a BertForSequenceClassification model from a BertForPreTraining model).\n",
|
||||
"- This IS NOT expected if you are initializing BertForSequenceClassification from the checkpoint of a model that you expect to be exactly identical (initializing a BertForSequenceClassification model from a BertForSequenceClassification model).\n",
|
||||
"Some weights of BertForSequenceClassification were not initialized from the model checkpoint at google/bert_uncased_L-2_H-128_A-2 and are newly initialized: ['classifier.weight', 'classifier.bias']\n",
|
||||
"You should probably TRAIN this model on a down-stream task to be able to use it for predictions and inference.\n"
|
||||
],
|
||||
"name": "stderr"
|
||||
},
|
||||
{
|
||||
"output_type": "display_data",
|
||||
"data": {
|
||||
"text/html": [
|
||||
"\n",
|
||||
" <div>\n",
|
||||
" \n",
|
||||
" <progress value='25257' max='25257' style='width:300px; height:20px; vertical-align: middle;'></progress>\n",
|
||||
" [25257/25257 06:56, Epoch 3/3]\n",
|
||||
" </div>\n",
|
||||
" <table border=\"1\" class=\"dataframe\">\n",
|
||||
" <thead>\n",
|
||||
" <tr style=\"text-align: left;\">\n",
|
||||
" <th>Step</th>\n",
|
||||
" <th>Training Loss</th>\n",
|
||||
" </tr>\n",
|
||||
" </thead>\n",
|
||||
" <tbody>\n",
|
||||
" <tr>\n",
|
||||
" <td>500</td>\n",
|
||||
" <td>0.611500</td>\n",
|
||||
" </tr>\n",
|
||||
" <tr>\n",
|
||||
" <td>1000</td>\n",
|
||||
" <td>0.474800</td>\n",
|
||||
" </tr>\n",
|
||||
" <tr>\n",
|
||||
" <td>1500</td>\n",
|
||||
" <td>0.440500</td>\n",
|
||||
" </tr>\n",
|
||||
" <tr>\n",
|
||||
" <td>2000</td>\n",
|
||||
" <td>0.407000</td>\n",
|
||||
" </tr>\n",
|
||||
" <tr>\n",
|
||||
" <td>2500</td>\n",
|
||||
" <td>0.401100</td>\n",
|
||||
" </tr>\n",
|
||||
" <tr>\n",
|
||||
" <td>3000</td>\n",
|
||||
" <td>0.398900</td>\n",
|
||||
" </tr>\n",
|
||||
" <tr>\n",
|
||||
" <td>3500</td>\n",
|
||||
" <td>0.375000</td>\n",
|
||||
" </tr>\n",
|
||||
" <tr>\n",
|
||||
" <td>4000</td>\n",
|
||||
" <td>0.363900</td>\n",
|
||||
" </tr>\n",
|
||||
" <tr>\n",
|
||||
" <td>4500</td>\n",
|
||||
" <td>0.352700</td>\n",
|
||||
" </tr>\n",
|
||||
" <tr>\n",
|
||||
" <td>5000</td>\n",
|
||||
" <td>0.380300</td>\n",
|
||||
" </tr>\n",
|
||||
" <tr>\n",
|
||||
" <td>5500</td>\n",
|
||||
" <td>0.342000</td>\n",
|
||||
" </tr>\n",
|
||||
" <tr>\n",
|
||||
" <td>6000</td>\n",
|
||||
" <td>0.333200</td>\n",
|
||||
" </tr>\n",
|
||||
" <tr>\n",
|
||||
" <td>6500</td>\n",
|
||||
" <td>0.363900</td>\n",
|
||||
" </tr>\n",
|
||||
" <tr>\n",
|
||||
" <td>7000</td>\n",
|
||||
" <td>0.344900</td>\n",
|
||||
" </tr>\n",
|
||||
" <tr>\n",
|
||||
" <td>7500</td>\n",
|
||||
" <td>0.345100</td>\n",
|
||||
" </tr>\n",
|
||||
" <tr>\n",
|
||||
" <td>8000</td>\n",
|
||||
" <td>0.330900</td>\n",
|
||||
" </tr>\n",
|
||||
" <tr>\n",
|
||||
" <td>8500</td>\n",
|
||||
" <td>0.324800</td>\n",
|
||||
" </tr>\n",
|
||||
" <tr>\n",
|
||||
" <td>9000</td>\n",
|
||||
" <td>0.285700</td>\n",
|
||||
" </tr>\n",
|
||||
" <tr>\n",
|
||||
" <td>9500</td>\n",
|
||||
" <td>0.290200</td>\n",
|
||||
" </tr>\n",
|
||||
" <tr>\n",
|
||||
" <td>10000</td>\n",
|
||||
" <td>0.301100</td>\n",
|
||||
" </tr>\n",
|
||||
" <tr>\n",
|
||||
" <td>10500</td>\n",
|
||||
" <td>0.304900</td>\n",
|
||||
" </tr>\n",
|
||||
" <tr>\n",
|
||||
" <td>11000</td>\n",
|
||||
" <td>0.287000</td>\n",
|
||||
" </tr>\n",
|
||||
" <tr>\n",
|
||||
" <td>11500</td>\n",
|
||||
" <td>0.315400</td>\n",
|
||||
" </tr>\n",
|
||||
" <tr>\n",
|
||||
" <td>12000</td>\n",
|
||||
" <td>0.296700</td>\n",
|
||||
" </tr>\n",
|
||||
" <tr>\n",
|
||||
" <td>12500</td>\n",
|
||||
" <td>0.301100</td>\n",
|
||||
" </tr>\n",
|
||||
" <tr>\n",
|
||||
" <td>13000</td>\n",
|
||||
" <td>0.292200</td>\n",
|
||||
" </tr>\n",
|
||||
" <tr>\n",
|
||||
" <td>13500</td>\n",
|
||||
" <td>0.310600</td>\n",
|
||||
" </tr>\n",
|
||||
" <tr>\n",
|
||||
" <td>14000</td>\n",
|
||||
" <td>0.286100</td>\n",
|
||||
" </tr>\n",
|
||||
" <tr>\n",
|
||||
" <td>14500</td>\n",
|
||||
" <td>0.286400</td>\n",
|
||||
" </tr>\n",
|
||||
" <tr>\n",
|
||||
" <td>15000</td>\n",
|
||||
" <td>0.263400</td>\n",
|
||||
" </tr>\n",
|
||||
" <tr>\n",
|
||||
" <td>15500</td>\n",
|
||||
" <td>0.274600</td>\n",
|
||||
" </tr>\n",
|
||||
" <tr>\n",
|
||||
" <td>16000</td>\n",
|
||||
" <td>0.274900</td>\n",
|
||||
" </tr>\n",
|
||||
" <tr>\n",
|
||||
" <td>16500</td>\n",
|
||||
" <td>0.257500</td>\n",
|
||||
" </tr>\n",
|
||||
" <tr>\n",
|
||||
" <td>17000</td>\n",
|
||||
" <td>0.269800</td>\n",
|
||||
" </tr>\n",
|
||||
" <tr>\n",
|
||||
" <td>17500</td>\n",
|
||||
" <td>0.254300</td>\n",
|
||||
" </tr>\n",
|
||||
" <tr>\n",
|
||||
" <td>18000</td>\n",
|
||||
" <td>0.259200</td>\n",
|
||||
" </tr>\n",
|
||||
" <tr>\n",
|
||||
" <td>18500</td>\n",
|
||||
" <td>0.257800</td>\n",
|
||||
" </tr>\n",
|
||||
" <tr>\n",
|
||||
" <td>19000</td>\n",
|
||||
" <td>0.247800</td>\n",
|
||||
" </tr>\n",
|
||||
" <tr>\n",
|
||||
" <td>19500</td>\n",
|
||||
" <td>0.264000</td>\n",
|
||||
" </tr>\n",
|
||||
" <tr>\n",
|
||||
" <td>20000</td>\n",
|
||||
" <td>0.247800</td>\n",
|
||||
" </tr>\n",
|
||||
" <tr>\n",
|
||||
" <td>20500</td>\n",
|
||||
" <td>0.261500</td>\n",
|
||||
" </tr>\n",
|
||||
" <tr>\n",
|
||||
" <td>21000</td>\n",
|
||||
" <td>0.257700</td>\n",
|
||||
" </tr>\n",
|
||||
" <tr>\n",
|
||||
" <td>21500</td>\n",
|
||||
" <td>0.252600</td>\n",
|
||||
" </tr>\n",
|
||||
" <tr>\n",
|
||||
" <td>22000</td>\n",
|
||||
" <td>0.254300</td>\n",
|
||||
" </tr>\n",
|
||||
" <tr>\n",
|
||||
" <td>22500</td>\n",
|
||||
" <td>0.255800</td>\n",
|
||||
" </tr>\n",
|
||||
" <tr>\n",
|
||||
" <td>23000</td>\n",
|
||||
" <td>0.256700</td>\n",
|
||||
" </tr>\n",
|
||||
" <tr>\n",
|
||||
" <td>23500</td>\n",
|
||||
" <td>0.260400</td>\n",
|
||||
" </tr>\n",
|
||||
" <tr>\n",
|
||||
" <td>24000</td>\n",
|
||||
" <td>0.250900</td>\n",
|
||||
" </tr>\n",
|
||||
" <tr>\n",
|
||||
" <td>24500</td>\n",
|
||||
" <td>0.244300</td>\n",
|
||||
" </tr>\n",
|
||||
" <tr>\n",
|
||||
" <td>25000</td>\n",
|
||||
" <td>0.256100</td>\n",
|
||||
" </tr>\n",
|
||||
" </tbody>\n",
|
||||
"</table><p>"
|
||||
],
|
||||
"text/plain": [
|
||||
"<IPython.core.display.HTML object>"
|
||||
]
|
||||
},
|
||||
"metadata": {
|
||||
"tags": []
|
||||
}
|
||||
}
|
||||
]
|
||||
},
|
||||
{
|
||||
"cell_type": "markdown",
|
||||
"metadata": {
|
||||
"id": "CubsNAbpEWQg"
|
||||
},
|
||||
"source": [
|
||||
"The default trainer pipeline functionality will not store any logs, checkpoints or models to disk. The trainer can take any of the standard TrainingArguments to enable persistent models.\n",
|
||||
"\n",
|
||||
"The next section creates a Labels pipeline using the newly built model and runs the model against the sst2 validation set. "
|
||||
]
|
||||
},
|
||||
{
|
||||
"cell_type": "code",
|
||||
"metadata": {
|
||||
"colab": {
|
||||
"base_uri": "https://localhost:8080/"
|
||||
},
|
||||
"id": "xw2y2C5Mg11_",
|
||||
"outputId": "b6254748-ae97-467a-83f4-b5a2debc56c2"
|
||||
},
|
||||
"source": [
|
||||
"from txtai.pipeline import Labels\n",
|
||||
"\n",
|
||||
"labels = Labels((model, tokenizer), dynamic=False)\n",
|
||||
"\n",
|
||||
"# Determine accuracy on validation set\n",
|
||||
"results = [row[\"label\"] == labels(row[\"sentence\"])[0][0] for row in ds[\"validation\"]]\n",
|
||||
"sum(results) / len(ds[\"validation\"])"
|
||||
],
|
||||
"execution_count": null,
|
||||
"outputs": [
|
||||
{
|
||||
"output_type": "execute_result",
|
||||
"data": {
|
||||
"text/plain": [
|
||||
"0.8188073394495413"
|
||||
]
|
||||
},
|
||||
"metadata": {
|
||||
"tags": []
|
||||
},
|
||||
"execution_count": 10
|
||||
}
|
||||
]
|
||||
},
|
||||
{
|
||||
"cell_type": "markdown",
|
||||
"metadata": {
|
||||
"id": "ZAHSwaB3Ex49"
|
||||
},
|
||||
"source": [
|
||||
"81.88% accuracy - not bad for a tiny Bert model. "
|
||||
]
|
||||
},
|
||||
{
|
||||
"cell_type": "markdown",
|
||||
"metadata": {
|
||||
"id": "f3GkY4JNEhhE"
|
||||
},
|
||||
"source": [
|
||||
"# Train a model with Lists\n",
|
||||
"\n",
|
||||
"As mentioned earlier, the trainer pipeline supports Hugging Face datasets, pandas DataFrames and lists of dicts. The example below trains a model using lists."
|
||||
]
|
||||
},
|
||||
{
|
||||
"cell_type": "code",
|
||||
"metadata": {
|
||||
"id": "QkApw1b2hfZq",
|
||||
"colab": {
|
||||
"base_uri": "https://localhost:8080/",
|
||||
"height": 182
|
||||
},
|
||||
"outputId": "9fc07884-47b7-4ef9-b6fa-4f6b34997e36"
|
||||
},
|
||||
"source": [
|
||||
"data = [{\"text\": \"This is a test sentence\", \"label\": 0}, {\"text\": \"This is not a test\", \"label\": 1}]\n",
|
||||
"\n",
|
||||
"model, tokenizer = trainer(\"google/bert_uncased_L-2_H-128_A-2\", data)"
|
||||
],
|
||||
"execution_count": null,
|
||||
"outputs": [
|
||||
{
|
||||
"output_type": "stream",
|
||||
"text": [
|
||||
"Some weights of the model checkpoint at google/bert_uncased_L-2_H-128_A-2 were not used when initializing BertForSequenceClassification: ['cls.predictions.bias', 'cls.predictions.decoder.weight', 'cls.predictions.decoder.bias', 'cls.predictions.transform.LayerNorm.weight', 'cls.seq_relationship.weight', 'cls.predictions.transform.dense.weight', 'cls.predictions.transform.dense.bias', 'cls.predictions.transform.LayerNorm.bias', 'cls.seq_relationship.bias']\n",
|
||||
"- This IS expected if you are initializing BertForSequenceClassification from the checkpoint of a model trained on another task or with another architecture (e.g. initializing a BertForSequenceClassification model from a BertForPreTraining model).\n",
|
||||
"- This IS NOT expected if you are initializing BertForSequenceClassification from the checkpoint of a model that you expect to be exactly identical (initializing a BertForSequenceClassification model from a BertForSequenceClassification model).\n",
|
||||
"Some weights of BertForSequenceClassification were not initialized from the model checkpoint at google/bert_uncased_L-2_H-128_A-2 and are newly initialized: ['classifier.weight', 'classifier.bias']\n",
|
||||
"You should probably TRAIN this model on a down-stream task to be able to use it for predictions and inference.\n"
|
||||
],
|
||||
"name": "stderr"
|
||||
},
|
||||
{
|
||||
"output_type": "display_data",
|
||||
"data": {
|
||||
"text/html": [
|
||||
"\n",
|
||||
" <div>\n",
|
||||
" \n",
|
||||
" <progress value='3' max='3' style='width:300px; height:20px; vertical-align: middle;'></progress>\n",
|
||||
" [3/3 00:00, Epoch 3/3]\n",
|
||||
" </div>\n",
|
||||
" <table border=\"1\" class=\"dataframe\">\n",
|
||||
" <thead>\n",
|
||||
" <tr style=\"text-align: left;\">\n",
|
||||
" <th>Step</th>\n",
|
||||
" <th>Training Loss</th>\n",
|
||||
" </tr>\n",
|
||||
" </thead>\n",
|
||||
" <tbody>\n",
|
||||
" </tbody>\n",
|
||||
"</table><p>"
|
||||
],
|
||||
"text/plain": [
|
||||
"<IPython.core.display.HTML object>"
|
||||
]
|
||||
},
|
||||
"metadata": {
|
||||
"tags": []
|
||||
}
|
||||
}
|
||||
]
|
||||
},
|
||||
{
|
||||
"cell_type": "markdown",
|
||||
"metadata": {
|
||||
"id": "cjYTxm7sFKyZ"
|
||||
},
|
||||
"source": [
|
||||
"# Train a model with DataFrames\n",
|
||||
"\n",
|
||||
"The next section builds a new model using data stored in a pandas DataFrame."
|
||||
]
|
||||
},
|
||||
{
|
||||
"cell_type": "code",
|
||||
"metadata": {
|
||||
"id": "0XaKKQ32wqbs",
|
||||
"colab": {
|
||||
"base_uri": "https://localhost:8080/",
|
||||
"height": 182
|
||||
},
|
||||
"outputId": "379dabea-062c-45d4-c422-224968493d74"
|
||||
},
|
||||
"source": [
|
||||
"import pandas as pd\n",
|
||||
"\n",
|
||||
"df = pd.DataFrame(data)\n",
|
||||
"\n",
|
||||
"model, tokenizer = trainer(\"google/bert_uncased_L-2_H-128_A-2\", data)"
|
||||
],
|
||||
"execution_count": null,
|
||||
"outputs": [
|
||||
{
|
||||
"output_type": "stream",
|
||||
"text": [
|
||||
"Some weights of the model checkpoint at google/bert_uncased_L-2_H-128_A-2 were not used when initializing BertForSequenceClassification: ['cls.predictions.bias', 'cls.predictions.decoder.weight', 'cls.predictions.decoder.bias', 'cls.predictions.transform.LayerNorm.weight', 'cls.seq_relationship.weight', 'cls.predictions.transform.dense.weight', 'cls.predictions.transform.dense.bias', 'cls.predictions.transform.LayerNorm.bias', 'cls.seq_relationship.bias']\n",
|
||||
"- This IS expected if you are initializing BertForSequenceClassification from the checkpoint of a model trained on another task or with another architecture (e.g. initializing a BertForSequenceClassification model from a BertForPreTraining model).\n",
|
||||
"- This IS NOT expected if you are initializing BertForSequenceClassification from the checkpoint of a model that you expect to be exactly identical (initializing a BertForSequenceClassification model from a BertForSequenceClassification model).\n",
|
||||
"Some weights of BertForSequenceClassification were not initialized from the model checkpoint at google/bert_uncased_L-2_H-128_A-2 and are newly initialized: ['classifier.weight', 'classifier.bias']\n",
|
||||
"You should probably TRAIN this model on a down-stream task to be able to use it for predictions and inference.\n"
|
||||
],
|
||||
"name": "stderr"
|
||||
},
|
||||
{
|
||||
"output_type": "display_data",
|
||||
"data": {
|
||||
"text/html": [
|
||||
"\n",
|
||||
" <div>\n",
|
||||
" \n",
|
||||
" <progress value='3' max='3' style='width:300px; height:20px; vertical-align: middle;'></progress>\n",
|
||||
" [3/3 00:00, Epoch 3/3]\n",
|
||||
" </div>\n",
|
||||
" <table border=\"1\" class=\"dataframe\">\n",
|
||||
" <thead>\n",
|
||||
" <tr style=\"text-align: left;\">\n",
|
||||
" <th>Step</th>\n",
|
||||
" <th>Training Loss</th>\n",
|
||||
" </tr>\n",
|
||||
" </thead>\n",
|
||||
" <tbody>\n",
|
||||
" </tbody>\n",
|
||||
"</table><p>"
|
||||
],
|
||||
"text/plain": [
|
||||
"<IPython.core.display.HTML object>"
|
||||
]
|
||||
},
|
||||
"metadata": {
|
||||
"tags": []
|
||||
}
|
||||
}
|
||||
]
|
||||
},
|
||||
{
|
||||
"cell_type": "markdown",
|
||||
"metadata": {
|
||||
"id": "QH3D8PQSFvQO"
|
||||
},
|
||||
"source": [
|
||||
"# Train a regression model\n",
|
||||
"\n",
|
||||
"The previous models were classification tasks. The following model trains a sentence similarity model with a regression output per sentence pair between 0 (dissimilar) and 1 (similar)."
|
||||
]
|
||||
},
|
||||
{
|
||||
"cell_type": "code",
|
||||
"metadata": {
|
||||
"colab": {
|
||||
"base_uri": "https://localhost:8080/",
|
||||
"height": 342
|
||||
},
|
||||
"id": "1rXuz4ncw9G-",
|
||||
"outputId": "e0084762-0029-4da2-c9c5-36a493be1f82"
|
||||
},
|
||||
"source": [
|
||||
"ds = load_dataset(\"glue\", \"stsb\")\n",
|
||||
"model, tokenizer = trainer(\"google/bert_uncased_L-2_H-128_A-2\", ds[\"train\"], columns=(\"sentence1\", \"sentence2\", \"label\"))"
|
||||
],
|
||||
"execution_count": null,
|
||||
"outputs": [
|
||||
{
|
||||
"output_type": "stream",
|
||||
"text": [
|
||||
"Reusing dataset glue (/root/.cache/huggingface/datasets/glue/stsb/1.0.0/dacbe3125aa31d7f70367a07a8a9e72a5a0bfeb5fc42e75c9db75b96da6053ad)\n",
|
||||
"Loading cached processed dataset at /root/.cache/huggingface/datasets/glue/stsb/1.0.0/dacbe3125aa31d7f70367a07a8a9e72a5a0bfeb5fc42e75c9db75b96da6053ad/cache-f34aa4f801bd41ea.arrow\n",
|
||||
"Some weights of the model checkpoint at google/bert_uncased_L-2_H-128_A-2 were not used when initializing BertForSequenceClassification: ['cls.predictions.bias', 'cls.predictions.decoder.weight', 'cls.predictions.decoder.bias', 'cls.predictions.transform.LayerNorm.weight', 'cls.seq_relationship.weight', 'cls.predictions.transform.dense.weight', 'cls.predictions.transform.dense.bias', 'cls.predictions.transform.LayerNorm.bias', 'cls.seq_relationship.bias']\n",
|
||||
"- This IS expected if you are initializing BertForSequenceClassification from the checkpoint of a model trained on another task or with another architecture (e.g. initializing a BertForSequenceClassification model from a BertForPreTraining model).\n",
|
||||
"- This IS NOT expected if you are initializing BertForSequenceClassification from the checkpoint of a model that you expect to be exactly identical (initializing a BertForSequenceClassification model from a BertForSequenceClassification model).\n",
|
||||
"Some weights of BertForSequenceClassification were not initialized from the model checkpoint at google/bert_uncased_L-2_H-128_A-2 and are newly initialized: ['classifier.weight', 'classifier.bias']\n",
|
||||
"You should probably TRAIN this model on a down-stream task to be able to use it for predictions and inference.\n"
|
||||
],
|
||||
"name": "stderr"
|
||||
},
|
||||
{
|
||||
"output_type": "display_data",
|
||||
"data": {
|
||||
"text/html": [
|
||||
"\n",
|
||||
" <div>\n",
|
||||
" \n",
|
||||
" <progress value='2157' max='2157' style='width:300px; height:20px; vertical-align: middle;'></progress>\n",
|
||||
" [2157/2157 00:36, Epoch 3/3]\n",
|
||||
" </div>\n",
|
||||
" <table border=\"1\" class=\"dataframe\">\n",
|
||||
" <thead>\n",
|
||||
" <tr style=\"text-align: left;\">\n",
|
||||
" <th>Step</th>\n",
|
||||
" <th>Training Loss</th>\n",
|
||||
" </tr>\n",
|
||||
" </thead>\n",
|
||||
" <tbody>\n",
|
||||
" <tr>\n",
|
||||
" <td>500</td>\n",
|
||||
" <td>2.836700</td>\n",
|
||||
" </tr>\n",
|
||||
" <tr>\n",
|
||||
" <td>1000</td>\n",
|
||||
" <td>1.055100</td>\n",
|
||||
" </tr>\n",
|
||||
" <tr>\n",
|
||||
" <td>1500</td>\n",
|
||||
" <td>0.920700</td>\n",
|
||||
" </tr>\n",
|
||||
" <tr>\n",
|
||||
" <td>2000</td>\n",
|
||||
" <td>0.847800</td>\n",
|
||||
" </tr>\n",
|
||||
" </tbody>\n",
|
||||
"</table><p>"
|
||||
],
|
||||
"text/plain": [
|
||||
"<IPython.core.display.HTML object>"
|
||||
]
|
||||
},
|
||||
"metadata": {
|
||||
"tags": []
|
||||
}
|
||||
}
|
||||
]
|
||||
},
|
||||
{
|
||||
"cell_type": "code",
|
||||
"metadata": {
|
||||
"colab": {
|
||||
"base_uri": "https://localhost:8080/"
|
||||
},
|
||||
"id": "fyvAslSP6j0F",
|
||||
"outputId": "5060b09b-4b81-40a0-9430-fbf9fc20eced"
|
||||
},
|
||||
"source": [
|
||||
"labels = Labels((model, tokenizer), dynamic=False)\n",
|
||||
"labels([(\"Sailing to the arctic\", \"Dogs and cats don't get along\"), \n",
|
||||
" (\"Walking down the road\", \"Walking down the street\")])"
|
||||
],
|
||||
"execution_count": null,
|
||||
"outputs": [
|
||||
{
|
||||
"output_type": "execute_result",
|
||||
"data": {
|
||||
"text/plain": [
|
||||
"[[(0, 0.551963746547699)], [(0, 0.9760823845863342)]]"
|
||||
]
|
||||
},
|
||||
"metadata": {
|
||||
"tags": []
|
||||
},
|
||||
"execution_count": 14
|
||||
}
|
||||
]
|
||||
}
|
||||
]
|
||||
}
|
||||
@@ -0,0 +1,320 @@
|
||||
{
|
||||
"nbformat": 4,
|
||||
"nbformat_minor": 0,
|
||||
"metadata": {
|
||||
"colab": {
|
||||
"name": "17 - Train without labels",
|
||||
"provenance": [],
|
||||
"collapsed_sections": []
|
||||
},
|
||||
"kernelspec": {
|
||||
"name": "python3",
|
||||
"display_name": "Python 3"
|
||||
},
|
||||
"accelerator": "GPU"
|
||||
},
|
||||
"cells": [
|
||||
{
|
||||
"cell_type": "markdown",
|
||||
"metadata": {
|
||||
"id": "4Pjmz-RORV8E"
|
||||
},
|
||||
"source": [
|
||||
"# Train without labels\n",
|
||||
"\n",
|
||||
"Almost all data available is unlabeled. Labeled data takes effort to manually review and/or takes time to collect. Zero-shot classification takes existing large language models and runs a similarity comparison between candidate text and a list of labels. This has been shown to perform surprisingly well.\n",
|
||||
"\n",
|
||||
"The problem with zero-shot classifiers is that they need to have a large number of parameters (400M+) to perform well against general tasks, which comes with sizable hardware requirements.\n",
|
||||
"\n",
|
||||
"This notebook explores using zero-shot classifiers to build training data for smaller models. A simple form of [knowledge distillation](https://en.wikipedia.org/wiki/Knowledge_distillation). "
|
||||
]
|
||||
},
|
||||
{
|
||||
"cell_type": "markdown",
|
||||
"metadata": {
|
||||
"id": "Dk31rbYjSTYm"
|
||||
},
|
||||
"source": [
|
||||
"# Install dependencies\n",
|
||||
"\n",
|
||||
"Install `txtai` and all dependencies."
|
||||
]
|
||||
},
|
||||
{
|
||||
"cell_type": "code",
|
||||
"metadata": {
|
||||
"id": "XMQuuun2R06J"
|
||||
},
|
||||
"source": [
|
||||
"%%capture\n",
|
||||
"!pip install git+https://github.com/neuml/txtai datasets pandas"
|
||||
],
|
||||
"execution_count": null,
|
||||
"outputs": []
|
||||
},
|
||||
{
|
||||
"cell_type": "markdown",
|
||||
"metadata": {
|
||||
"id": "3PUe1OW8IZR5"
|
||||
},
|
||||
"source": [
|
||||
"# Apply zero-shot classifier to unlabeled text\n",
|
||||
"\n",
|
||||
"The following section takes a small 1000 record random sample of the sst2 dataset and applies a zero-shot classifer to the text. The labels are ignored. This dataset was chosen only to be able to evaluate the accuracy at then end. "
|
||||
]
|
||||
},
|
||||
{
|
||||
"cell_type": "code",
|
||||
"metadata": {
|
||||
"colab": {
|
||||
"base_uri": "https://localhost:8080/"
|
||||
},
|
||||
"id": "GlrOnS4cmkih",
|
||||
"outputId": "880277f7-fa3b-4c8f-a7bb-e6c5dcc895f1"
|
||||
},
|
||||
"source": [
|
||||
"import random\n",
|
||||
"\n",
|
||||
"from datasets import load_dataset\n",
|
||||
"\n",
|
||||
"from txtai.pipeline import Labels\n",
|
||||
"\n",
|
||||
"def batch(texts, size):\n",
|
||||
" return [texts[x : x + size] for x in range(0, len(texts), size)]\n",
|
||||
"\n",
|
||||
"# Set random seed for repeatable sampling\n",
|
||||
"random.seed(42)\n",
|
||||
"\n",
|
||||
"ds = load_dataset(\"glue\", \"sst2\")\n",
|
||||
"\n",
|
||||
"sentences = random.sample(ds[\"train\"][\"sentence\"], 1000)\n",
|
||||
"\n",
|
||||
"# Load a zero shot classifier - txtai provides this through the Labels pipeline\n",
|
||||
"labels = Labels(\"microsoft/deberta-large-mnli\")\n",
|
||||
"\n",
|
||||
"train = []\n",
|
||||
"\n",
|
||||
"# Zero-shot prediction using [\"negative\", \"positive\"] labels\n",
|
||||
"for chunk in batch(sentences, 32):\n",
|
||||
" train.extend([{\"text\": chunk[x], \"label\": label[0][0]} for x, label in enumerate(labels(chunk, [\"negative\", \"positive\"]))])"
|
||||
],
|
||||
"execution_count": null,
|
||||
"outputs": [
|
||||
{
|
||||
"output_type": "stream",
|
||||
"text": [
|
||||
"Reusing dataset glue (/root/.cache/huggingface/datasets/glue/sst2/1.0.0/dacbe3125aa31d7f70367a07a8a9e72a5a0bfeb5fc42e75c9db75b96da6053ad)\n",
|
||||
"Some weights of the model checkpoint at microsoft/deberta-large-mnli were not used when initializing DebertaForSequenceClassification: ['config']\n",
|
||||
"- This IS expected if you are initializing DebertaForSequenceClassification from the checkpoint of a model trained on another task or with another architecture (e.g. initializing a BertForSequenceClassification model from a BertForPreTraining model).\n",
|
||||
"- This IS NOT expected if you are initializing DebertaForSequenceClassification from the checkpoint of a model that you expect to be exactly identical (initializing a BertForSequenceClassification model from a BertForSequenceClassification model).\n"
|
||||
],
|
||||
"name": "stderr"
|
||||
}
|
||||
]
|
||||
},
|
||||
{
|
||||
"cell_type": "markdown",
|
||||
"metadata": {
|
||||
"id": "TLsZmRpHJGav"
|
||||
},
|
||||
"source": [
|
||||
"Next, we'll use the training set we just built to train a smaller Electra model."
|
||||
]
|
||||
},
|
||||
{
|
||||
"cell_type": "code",
|
||||
"metadata": {
|
||||
"colab": {
|
||||
"base_uri": "https://localhost:8080/",
|
||||
"height": 214
|
||||
},
|
||||
"id": "nAt42TIHnfTN",
|
||||
"outputId": "24b0e1ad-f020-41bb-efb8-016a89baf80e"
|
||||
},
|
||||
"source": [
|
||||
"from txtai.pipeline import HFTrainer\n",
|
||||
"\n",
|
||||
"trainer = HFTrainer()\n",
|
||||
"model, tokenizer = trainer(\"google/electra-base-discriminator\", train, num_train_epochs=5)"
|
||||
],
|
||||
"execution_count": null,
|
||||
"outputs": [
|
||||
{
|
||||
"output_type": "stream",
|
||||
"text": [
|
||||
"Some weights of the model checkpoint at google/electra-base-discriminator were not used when initializing ElectraForSequenceClassification: ['discriminator_predictions.dense_prediction.weight', 'discriminator_predictions.dense_prediction.bias', 'discriminator_predictions.dense.weight', 'discriminator_predictions.dense.bias']\n",
|
||||
"- This IS expected if you are initializing ElectraForSequenceClassification from the checkpoint of a model trained on another task or with another architecture (e.g. initializing a BertForSequenceClassification model from a BertForPreTraining model).\n",
|
||||
"- This IS NOT expected if you are initializing ElectraForSequenceClassification from the checkpoint of a model that you expect to be exactly identical (initializing a BertForSequenceClassification model from a BertForSequenceClassification model).\n",
|
||||
"Some weights of ElectraForSequenceClassification were not initialized from the model checkpoint at google/electra-base-discriminator and are newly initialized: ['classifier.out_proj.weight', 'classifier.dense.bias', 'classifier.dense.weight', 'classifier.out_proj.bias']\n",
|
||||
"You should probably TRAIN this model on a down-stream task to be able to use it for predictions and inference.\n"
|
||||
],
|
||||
"name": "stderr"
|
||||
},
|
||||
{
|
||||
"output_type": "display_data",
|
||||
"data": {
|
||||
"text/html": [
|
||||
"\n",
|
||||
" <div>\n",
|
||||
" \n",
|
||||
" <progress value='625' max='625' style='width:300px; height:20px; vertical-align: middle;'></progress>\n",
|
||||
" [625/625 00:55, Epoch 5/5]\n",
|
||||
" </div>\n",
|
||||
" <table border=\"1\" class=\"dataframe\">\n",
|
||||
" <thead>\n",
|
||||
" <tr style=\"text-align: left;\">\n",
|
||||
" <th>Step</th>\n",
|
||||
" <th>Training Loss</th>\n",
|
||||
" </tr>\n",
|
||||
" </thead>\n",
|
||||
" <tbody>\n",
|
||||
" <tr>\n",
|
||||
" <td>500</td>\n",
|
||||
" <td>0.280500</td>\n",
|
||||
" </tr>\n",
|
||||
" </tbody>\n",
|
||||
"</table><p>"
|
||||
],
|
||||
"text/plain": [
|
||||
"<IPython.core.display.HTML object>"
|
||||
]
|
||||
},
|
||||
"metadata": {
|
||||
"tags": []
|
||||
}
|
||||
}
|
||||
]
|
||||
},
|
||||
{
|
||||
"cell_type": "markdown",
|
||||
"metadata": {
|
||||
"id": "J9pugqJSJRn6"
|
||||
},
|
||||
"source": [
|
||||
"# Evaluating accuracy\n",
|
||||
"\n",
|
||||
"Recall the training set is only 1000 records. To be clear, training an Electra model against the full sst2 dataset would perform better than below. But for this exercise, we're are not using the training labels and simulating labeled data not being available.\n",
|
||||
"\n",
|
||||
"First, lets see what the baseline accuracy for the zero-shot model would be against the sst2 evaluation set. Reminder that this has not seen any of the sst2 training data. \n"
|
||||
]
|
||||
},
|
||||
{
|
||||
"cell_type": "code",
|
||||
"metadata": {
|
||||
"colab": {
|
||||
"base_uri": "https://localhost:8080/"
|
||||
},
|
||||
"id": "RbgIrkgMvJS4",
|
||||
"outputId": "a4760822-ea25-4adb-cf69-4d288f641b37"
|
||||
},
|
||||
"source": [
|
||||
"labels = Labels(\"microsoft/deberta-large-mnli\")"
|
||||
],
|
||||
"execution_count": null,
|
||||
"outputs": [
|
||||
{
|
||||
"output_type": "stream",
|
||||
"text": [
|
||||
"Some weights of the model checkpoint at microsoft/deberta-large-mnli were not used when initializing DebertaForSequenceClassification: ['config']\n",
|
||||
"- This IS expected if you are initializing DebertaForSequenceClassification from the checkpoint of a model trained on another task or with another architecture (e.g. initializing a BertForSequenceClassification model from a BertForPreTraining model).\n",
|
||||
"- This IS NOT expected if you are initializing DebertaForSequenceClassification from the checkpoint of a model that you expect to be exactly identical (initializing a BertForSequenceClassification model from a BertForSequenceClassification model).\n"
|
||||
],
|
||||
"name": "stderr"
|
||||
}
|
||||
]
|
||||
},
|
||||
{
|
||||
"cell_type": "code",
|
||||
"metadata": {
|
||||
"colab": {
|
||||
"base_uri": "https://localhost:8080/"
|
||||
},
|
||||
"id": "-36UBMILpKYh",
|
||||
"outputId": "5594425d-d2aa-4006-97cb-3b70b3fc063c"
|
||||
},
|
||||
"source": [
|
||||
"results = [row[\"label\"] == labels(row[\"sentence\"], [\"negative\", \"positive\"])[0][0] for row in ds[\"validation\"]]\n",
|
||||
"sum(results) / len(ds[\"validation\"])"
|
||||
],
|
||||
"execution_count": null,
|
||||
"outputs": [
|
||||
{
|
||||
"output_type": "execute_result",
|
||||
"data": {
|
||||
"text/plain": [
|
||||
"0.8818807339449541"
|
||||
]
|
||||
},
|
||||
"metadata": {
|
||||
"tags": []
|
||||
},
|
||||
"execution_count": 11
|
||||
}
|
||||
]
|
||||
},
|
||||
{
|
||||
"cell_type": "markdown",
|
||||
"metadata": {
|
||||
"id": "uJVnWHZZKFIN"
|
||||
},
|
||||
"source": [
|
||||
"88.18% accuracy, not bad for a model that has not been trained on the dataset at all! Shows the power of zero-shot classification.\n",
|
||||
"\n",
|
||||
"Next, let's test our model trained on the 1000 zero-shot labeled records."
|
||||
]
|
||||
},
|
||||
{
|
||||
"cell_type": "code",
|
||||
"metadata": {
|
||||
"colab": {
|
||||
"base_uri": "https://localhost:8080/"
|
||||
},
|
||||
"id": "Kr5IZqZtvXlP",
|
||||
"outputId": "9a3c920d-5c5f-412b-ccbf-94ebf6f11913"
|
||||
},
|
||||
"source": [
|
||||
"labels = Labels((model, tokenizer), dynamic=False)\n",
|
||||
"\n",
|
||||
"results = [row[\"label\"] == labels(row[\"sentence\"])[0][0] for row in ds[\"validation\"]]\n",
|
||||
"sum(results) / len(ds[\"validation\"])"
|
||||
],
|
||||
"execution_count": null,
|
||||
"outputs": [
|
||||
{
|
||||
"output_type": "execute_result",
|
||||
"data": {
|
||||
"text/plain": [
|
||||
"0.8864678899082569"
|
||||
]
|
||||
},
|
||||
"metadata": {
|
||||
"tags": []
|
||||
},
|
||||
"execution_count": 12
|
||||
}
|
||||
]
|
||||
},
|
||||
{
|
||||
"cell_type": "markdown",
|
||||
"metadata": {
|
||||
"id": "sDw-Zh43KVdX"
|
||||
},
|
||||
"source": [
|
||||
"88.65% accuracy! Wouldn't get too carried away with the percentages but this at least meets the accuracy of the zero-shot classifier if not exceeds it. \n",
|
||||
"\n",
|
||||
"Now this model will be highly tuned for a specific task but it had the opportunity to learn from the combined 1000 records whereas the zero-shot classifier views each record independently. It's also much more performant. "
|
||||
]
|
||||
},
|
||||
{
|
||||
"cell_type": "markdown",
|
||||
"metadata": {
|
||||
"id": "QEAwki2lLM2A"
|
||||
},
|
||||
"source": [
|
||||
"# Conclusion\n",
|
||||
"\n",
|
||||
"This notebook explored a method of building trained text classifiers without training data being available. Given the amount of resources needed to run large-scale zero-shot classifiers, this method is a simple way to build smaller models tuned for specific tasks. In this example, the zero-shot classifier has 400M parameters and the trained text classifier has 110M. "
|
||||
]
|
||||
}
|
||||
]
|
||||
}
|
||||
File diff suppressed because it is too large
Load Diff
@@ -0,0 +1,297 @@
|
||||
{
|
||||
"nbformat": 4,
|
||||
"nbformat_minor": 0,
|
||||
"metadata": {
|
||||
"colab": {
|
||||
"name": "19 - Train a QA model",
|
||||
"provenance": [],
|
||||
"collapsed_sections": []
|
||||
},
|
||||
"kernelspec": {
|
||||
"name": "python3",
|
||||
"display_name": "Python 3"
|
||||
},
|
||||
"accelerator": "GPU"
|
||||
},
|
||||
"cells": [
|
||||
{
|
||||
"cell_type": "markdown",
|
||||
"metadata": {
|
||||
"id": "4Pjmz-RORV8E"
|
||||
},
|
||||
"source": [
|
||||
"# Train a QA model\n",
|
||||
"\n",
|
||||
"The [Hugging Face Model Hub](https://huggingface.co/models) has a wide range of models that can handle many tasks. While these models perform well, the best performance is often found when fine-tuning a model with task-specific data. \n",
|
||||
"\n",
|
||||
"Hugging Face provides a [number of full-featured examples](https://github.com/huggingface/transformers/tree/master/examples) to assist with training task-specific models. When building models from the command line, these scripts are a great way to get started.\n",
|
||||
"\n",
|
||||
"txtai provides a training pipeline that can be used to train new models programatically using the Transformers Trainer framework.\n",
|
||||
"\n",
|
||||
"This example trains a small QA model and then further fine-tunes it with a couple new examples (few-shot learning)."
|
||||
]
|
||||
},
|
||||
{
|
||||
"cell_type": "markdown",
|
||||
"metadata": {
|
||||
"id": "Dk31rbYjSTYm"
|
||||
},
|
||||
"source": [
|
||||
"# Install dependencies\n",
|
||||
"\n",
|
||||
"Install `txtai` and all dependencies."
|
||||
]
|
||||
},
|
||||
{
|
||||
"cell_type": "code",
|
||||
"metadata": {
|
||||
"id": "XMQuuun2R06J"
|
||||
},
|
||||
"source": [
|
||||
"%%capture\n",
|
||||
"!pip install git+https://github.com/neuml/txtai datasets pandas"
|
||||
],
|
||||
"execution_count": null,
|
||||
"outputs": []
|
||||
},
|
||||
{
|
||||
"cell_type": "markdown",
|
||||
"metadata": {
|
||||
"id": "r6nmtieHdMfr"
|
||||
},
|
||||
"source": [
|
||||
"# Train a SQuAD 2.0 Model\n",
|
||||
"\n",
|
||||
"The first step is training a SQuAD 2.0 model. SQuAD is a question-answer dataset that poses a question with a context along with the identified answer. It's also possible to not have an answer. See the [SQuAD dataset website](https://rajpurkar.github.io/SQuAD-explorer/) for more information.\n",
|
||||
"\n",
|
||||
"We'll use a tiny Bert model with a portion of SQuAD 2.0 for efficiency purposes."
|
||||
]
|
||||
},
|
||||
{
|
||||
"cell_type": "code",
|
||||
"metadata": {
|
||||
"colab": {
|
||||
"base_uri": "https://localhost:8080/",
|
||||
"height": 297
|
||||
},
|
||||
"id": "pg9-tUxEdRfk",
|
||||
"outputId": "06195c45-4b39-46e5-a462-af566f437ade"
|
||||
},
|
||||
"source": [
|
||||
"from datasets import load_dataset\n",
|
||||
"from txtai.pipeline import HFTrainer\n",
|
||||
"\n",
|
||||
"ds = load_dataset(\"squad_v2\")\n",
|
||||
"\n",
|
||||
"trainer = HFTrainer()\n",
|
||||
"trainer(\"google/bert_uncased_L-2_H-128_A-2\", ds[\"train\"].select(range(3000)), task=\"question-answering\", output_dir=\"bert-tiny-squadv2\")\n",
|
||||
"print(\"Training complete\")"
|
||||
],
|
||||
"execution_count": null,
|
||||
"outputs": [
|
||||
{
|
||||
"output_type": "stream",
|
||||
"name": "stderr",
|
||||
"text": [
|
||||
"Reusing dataset squad_v2 (/root/.cache/huggingface/datasets/squad_v2/squad_v2/2.0.0/09187c73c1b837c95d9a249cd97c2c3f1cebada06efe667b4427714b27639b1d)\n",
|
||||
"Loading cached processed dataset at /root/.cache/huggingface/datasets/squad_v2/squad_v2/2.0.0/09187c73c1b837c95d9a249cd97c2c3f1cebada06efe667b4427714b27639b1d/cache-73bbe029cf3366fc.arrow\n",
|
||||
"Some weights of the model checkpoint at google/bert_uncased_L-2_H-128_A-2 were not used when initializing BertForQuestionAnswering: ['cls.predictions.decoder.bias', 'cls.predictions.transform.dense.bias', 'cls.predictions.transform.LayerNorm.bias', 'cls.predictions.transform.LayerNorm.weight', 'cls.predictions.decoder.weight', 'cls.predictions.bias', 'cls.seq_relationship.bias', 'cls.predictions.transform.dense.weight', 'cls.seq_relationship.weight']\n",
|
||||
"- This IS expected if you are initializing BertForQuestionAnswering from the checkpoint of a model trained on another task or with another architecture (e.g. initializing a BertForSequenceClassification model from a BertForPreTraining model).\n",
|
||||
"- This IS NOT expected if you are initializing BertForQuestionAnswering from the checkpoint of a model that you expect to be exactly identical (initializing a BertForSequenceClassification model from a BertForSequenceClassification model).\n",
|
||||
"Some weights of BertForQuestionAnswering were not initialized from the model checkpoint at google/bert_uncased_L-2_H-128_A-2 and are newly initialized: ['qa_outputs.bias', 'qa_outputs.weight']\n",
|
||||
"You should probably TRAIN this model on a down-stream task to be able to use it for predictions and inference.\n"
|
||||
]
|
||||
},
|
||||
{
|
||||
"output_type": "display_data",
|
||||
"data": {
|
||||
"text/html": [
|
||||
"\n",
|
||||
" <div>\n",
|
||||
" \n",
|
||||
" <progress value='1131' max='1131' style='width:300px; height:20px; vertical-align: middle;'></progress>\n",
|
||||
" [1131/1131 00:50, Epoch 3/3]\n",
|
||||
" </div>\n",
|
||||
" <table border=\"1\" class=\"dataframe\">\n",
|
||||
" <thead>\n",
|
||||
" <tr style=\"text-align: left;\">\n",
|
||||
" <th>Step</th>\n",
|
||||
" <th>Training Loss</th>\n",
|
||||
" </tr>\n",
|
||||
" </thead>\n",
|
||||
" <tbody>\n",
|
||||
" <tr>\n",
|
||||
" <td>500</td>\n",
|
||||
" <td>4.501800</td>\n",
|
||||
" </tr>\n",
|
||||
" <tr>\n",
|
||||
" <td>1000</td>\n",
|
||||
" <td>3.875900</td>\n",
|
||||
" </tr>\n",
|
||||
" </tbody>\n",
|
||||
"</table><p>"
|
||||
],
|
||||
"text/plain": [
|
||||
"<IPython.core.display.HTML object>"
|
||||
]
|
||||
},
|
||||
"metadata": {}
|
||||
},
|
||||
{
|
||||
"output_type": "stream",
|
||||
"name": "stdout",
|
||||
"text": [
|
||||
"Training complete\n"
|
||||
]
|
||||
}
|
||||
]
|
||||
},
|
||||
{
|
||||
"cell_type": "markdown",
|
||||
"metadata": {
|
||||
"id": "zZtHxNSwFNGC"
|
||||
},
|
||||
"source": [
|
||||
"# Fine-tune with new data\n",
|
||||
"\n",
|
||||
"Next we'll add a few additional examples. Fine-tuning a QA model will help with framing a certain type of question or improve performance for a specific use-case. \n",
|
||||
"\n",
|
||||
"For smaller models with a narrow use case, this helps the model zero in on the types of questions that are to be asked. In this case, we want to tell the model exactly the types of information we're looking for when asking for ingredients. This will help improve confidence in the answers the model is generating.\n"
|
||||
]
|
||||
},
|
||||
{
|
||||
"cell_type": "code",
|
||||
"metadata": {
|
||||
"colab": {
|
||||
"base_uri": "https://localhost:8080/",
|
||||
"height": 75
|
||||
},
|
||||
"id": "JBeScS5dFNeW",
|
||||
"outputId": "13596524-b476-4f55-f430-d25eeda9301f"
|
||||
},
|
||||
"source": [
|
||||
"# Training data\n",
|
||||
"data = [\n",
|
||||
" {\"question\": \"What ingredient?\", \"context\": \"Pour 1 can whole tomatoes\", \"answers\": \"tomatoes\"},\n",
|
||||
" {\"question\": \"What ingredient?\", \"context\": \"Dice 1 yellow onion\", \"answers\": \"onion\"},\n",
|
||||
" {\"question\": \"What ingredient?\", \"context\": \"Cut 1 red pepper\", \"answers\": \"pepper\"},\n",
|
||||
" {\"question\": \"What ingredient?\", \"context\": \"Peel and dice 1 clove garlic\", \"answers\": \"garlic\"},\n",
|
||||
" {\"question\": \"What ingredient?\", \"context\": \"Put 1/2 lb beef\", \"answers\": \"beef\"},\n",
|
||||
"]\n",
|
||||
"\n",
|
||||
"model, tokenizer = trainer(\"bert-tiny-squadv2\", data, task=\"question-answering\", num_train_epochs=10)"
|
||||
],
|
||||
"execution_count": null,
|
||||
"outputs": [
|
||||
{
|
||||
"output_type": "display_data",
|
||||
"data": {
|
||||
"text/html": [
|
||||
"\n",
|
||||
" <div>\n",
|
||||
" \n",
|
||||
" <progress value='10' max='10' style='width:300px; height:20px; vertical-align: middle;'></progress>\n",
|
||||
" [10/10 00:00, Epoch 10/10]\n",
|
||||
" </div>\n",
|
||||
" <table border=\"1\" class=\"dataframe\">\n",
|
||||
" <thead>\n",
|
||||
" <tr style=\"text-align: left;\">\n",
|
||||
" <th>Step</th>\n",
|
||||
" <th>Training Loss</th>\n",
|
||||
" </tr>\n",
|
||||
" </thead>\n",
|
||||
" <tbody>\n",
|
||||
" </tbody>\n",
|
||||
"</table><p>"
|
||||
],
|
||||
"text/plain": [
|
||||
"<IPython.core.display.HTML object>"
|
||||
]
|
||||
},
|
||||
"metadata": {}
|
||||
}
|
||||
]
|
||||
},
|
||||
{
|
||||
"cell_type": "markdown",
|
||||
"metadata": {
|
||||
"id": "V7nAl3WtkBNK"
|
||||
},
|
||||
"source": [
|
||||
"# Test the model\n",
|
||||
"\n",
|
||||
"Now we're ready to test the results! The following sections run a question against the original model only trained with SQuAD 2.0 and the further fine-tuned model."
|
||||
]
|
||||
},
|
||||
{
|
||||
"cell_type": "code",
|
||||
"metadata": {
|
||||
"colab": {
|
||||
"base_uri": "https://localhost:8080/"
|
||||
},
|
||||
"id": "46fMiJrAIBu4",
|
||||
"outputId": "fb92ca0a-d433-486f-b61c-054f4e4a9b36"
|
||||
},
|
||||
"source": [
|
||||
"from transformers import pipeline\n",
|
||||
"\n",
|
||||
"questions = pipeline(\"question-answering\", model=\"bert-tiny-squadv2\")\n",
|
||||
"questions(\"What ingredient?\", \"Peel and dice 1 shallot\")"
|
||||
],
|
||||
"execution_count": null,
|
||||
"outputs": [
|
||||
{
|
||||
"output_type": "execute_result",
|
||||
"data": {
|
||||
"text/plain": [
|
||||
"{'answer': 'dice 1 shallot',\n",
|
||||
" 'end': 23,\n",
|
||||
" 'score': 0.05128436163067818,\n",
|
||||
" 'start': 9}"
|
||||
]
|
||||
},
|
||||
"metadata": {},
|
||||
"execution_count": 57
|
||||
}
|
||||
]
|
||||
},
|
||||
{
|
||||
"cell_type": "code",
|
||||
"metadata": {
|
||||
"colab": {
|
||||
"base_uri": "https://localhost:8080/"
|
||||
},
|
||||
"id": "nWQMRQm0NwdN",
|
||||
"outputId": "a1f15b5c-1cf8-4fe5-daa8-e19adc1700e1"
|
||||
},
|
||||
"source": [
|
||||
"from transformers import pipeline\n",
|
||||
"\n",
|
||||
"questions = pipeline(\"question-answering\", model=model.to(\"cpu\"), tokenizer=tokenizer)\n",
|
||||
"questions(\"What ingredient?\", \"Peel and dice 1 shallot\")"
|
||||
],
|
||||
"execution_count": null,
|
||||
"outputs": [
|
||||
{
|
||||
"output_type": "execute_result",
|
||||
"data": {
|
||||
"text/plain": [
|
||||
"{'answer': 'shallot', 'end': 23, 'score': 0.13187439739704132, 'start': 16}"
|
||||
]
|
||||
},
|
||||
"metadata": {},
|
||||
"execution_count": 58
|
||||
}
|
||||
]
|
||||
},
|
||||
{
|
||||
"cell_type": "markdown",
|
||||
"metadata": {
|
||||
"id": "wJoYksLbkZTJ"
|
||||
},
|
||||
"source": [
|
||||
"See how the results are more confident and have a better answer. This method allows using a smaller model with a narrow set of functionality with the upside of increased speed. Give it a try with your own data!"
|
||||
]
|
||||
}
|
||||
]
|
||||
}
|
||||
@@ -0,0 +1,186 @@
|
||||
"""
|
||||
Search application using Open Library book data. Requires the following steps to be run:
|
||||
|
||||
Install Streamlit
|
||||
pip install streamlit
|
||||
|
||||
Download and prepare data
|
||||
mkdir openlibrary && cd openlibrary
|
||||
wget -O works.txt.gz https://openlibrary.org/data/ol_dump_works_latest.txt.gz
|
||||
gunzip works.txt.gz
|
||||
grep "\"description\":" works.txt > filtered.txt
|
||||
|
||||
Build index
|
||||
python books.py openlibrary
|
||||
|
||||
Run application
|
||||
streamlit run books.py openlibrary
|
||||
"""
|
||||
|
||||
import json
|
||||
import os
|
||||
import sqlite3
|
||||
import sys
|
||||
|
||||
import pandas as pd
|
||||
import streamlit as st
|
||||
|
||||
from txtai.embeddings import Embeddings
|
||||
|
||||
|
||||
class Application:
|
||||
"""
|
||||
Main application.
|
||||
"""
|
||||
|
||||
def __init__(self, path):
|
||||
"""
|
||||
Creates a new application.
|
||||
|
||||
Args:
|
||||
path: root path to data
|
||||
"""
|
||||
|
||||
self.path = path
|
||||
self.dbpath = os.path.join(self.path, "books")
|
||||
|
||||
def rows(self, index):
|
||||
"""
|
||||
Iterates over dataset yielding each row.
|
||||
|
||||
Args:
|
||||
index: yields rows for embeddings indexing if True, otherwise yields database rows
|
||||
"""
|
||||
|
||||
with open(os.path.join(self.path, "filtered.txt")) as infile:
|
||||
for x, row in enumerate(infile):
|
||||
if x % 1000 == 0:
|
||||
print("Processed %d rows" % x, end="\r")
|
||||
|
||||
row = row.split("\t")
|
||||
uid, data = row[1], json.loads(row[4])
|
||||
|
||||
description = data["description"]
|
||||
if isinstance(description, dict):
|
||||
description = description["value"]
|
||||
|
||||
if "title" in data:
|
||||
if index:
|
||||
yield (uid, data["title"] + ". " + description, None)
|
||||
else:
|
||||
cover = "%d" % data["covers"][0] if "covers" in data and data["covers"] else None
|
||||
yield (uid, data["title"], description, cover)
|
||||
|
||||
def database(self):
|
||||
"""
|
||||
Builds a SQLite database.
|
||||
"""
|
||||
|
||||
# Database file path
|
||||
dbfile = os.path.join(self.dbpath, "books.sqlite")
|
||||
|
||||
# Delete existing file
|
||||
if os.path.exists(dbfile):
|
||||
os.remove(dbfile)
|
||||
|
||||
# Create output database
|
||||
db = sqlite3.connect(dbfile)
|
||||
|
||||
# Create database cursor
|
||||
cur = db.cursor()
|
||||
|
||||
cur.execute("CREATE TABLE books (Id TEXT PRIMARY KEY, Title TEXT, Description TEXT, Cover TEXT)")
|
||||
|
||||
for uid, title, description, cover in self.rows(False):
|
||||
cur.execute("INSERT INTO books (Id, Title, Description, Cover) VALUES (?, ?, ?, ?)", (uid, title, description, cover))
|
||||
|
||||
# Finish and close database
|
||||
db.commit()
|
||||
db.close()
|
||||
|
||||
def build(self):
|
||||
"""
|
||||
Builds an embeddings index and database.
|
||||
"""
|
||||
|
||||
# Build embeddings index
|
||||
embeddings = Embeddings({"path": "sentence-transformers/msmarco-distilbert-base-v4"})
|
||||
embeddings.index(self.rows(True))
|
||||
embeddings.save(self.dbpath)
|
||||
|
||||
# Build SQLite DB
|
||||
self.database()
|
||||
|
||||
@st.cache(allow_output_mutation=True)
|
||||
def load(self):
|
||||
"""
|
||||
Loads and caches embeddings index.
|
||||
|
||||
Returns:
|
||||
embeddings index
|
||||
"""
|
||||
|
||||
embeddings = Embeddings()
|
||||
embeddings.load(self.dbpath)
|
||||
|
||||
return embeddings
|
||||
|
||||
def run(self):
|
||||
"""
|
||||
Runs a Streamlit application.
|
||||
"""
|
||||
|
||||
# Build embeddings index
|
||||
embeddings = self.load()
|
||||
|
||||
db = sqlite3.connect(os.path.join(self.dbpath, "books.sqlite"))
|
||||
cur = db.cursor()
|
||||
|
||||
st.title("Book search")
|
||||
|
||||
st.markdown(
|
||||
"This application builds a local txtai index using book data from [openlibrary.org](https://openlibrary.org). "
|
||||
+ "Links to the Open Library pages and covers are shown in the application."
|
||||
)
|
||||
|
||||
query = st.text_input("Search query:")
|
||||
if query:
|
||||
ids = [uid for uid, score in embeddings.search(query, 10) if score >= 0.5]
|
||||
|
||||
results = []
|
||||
for uid in ids:
|
||||
cur.execute("SELECT Title, Description, Cover FROM books WHERE Id=?", (uid,))
|
||||
result = cur.fetchone()
|
||||
|
||||
if result:
|
||||
# Build cover image
|
||||
cover = (
|
||||
"<img src='http://covers.openlibrary.org/b/id/%s-M.jpg'/>" % result[2]
|
||||
if result[2]
|
||||
else "<img src='http://openlibrary.org/images/icons/avatar_book-lg.png'/>"
|
||||
)
|
||||
|
||||
# Append book link
|
||||
cover = "<a target='_blank' href='https://openlibrary.org/%s'>%s</a>" % (uid, cover)
|
||||
title = "<a target='_blank' href='https://openlibrary.org/%s'>%s</a>" % (uid, result[0])
|
||||
|
||||
results.append({"Cover": cover, "Title": title, "Description": result[1]})
|
||||
|
||||
st.write(pd.DataFrame(results).to_html(escape=False, index=False), unsafe_allow_html=True)
|
||||
|
||||
db.close()
|
||||
|
||||
|
||||
if __name__ == "__main__":
|
||||
os.environ["TOKENIZERS_PARALLELISM"] = "false"
|
||||
|
||||
# Application is used both to index and search
|
||||
app = Application(sys.argv[1])
|
||||
|
||||
# pylint: disable=W0212
|
||||
if st._is_running_with_streamlit:
|
||||
# Run application using existing index/db
|
||||
app.run()
|
||||
else:
|
||||
# Not running through streamlit, build database/index
|
||||
app.build()
|
||||
+16
-13
@@ -4,41 +4,43 @@ Demo shell
|
||||
|
||||
from cmd import Cmd
|
||||
|
||||
import numpy as np
|
||||
|
||||
from txtai.embeddings import Embeddings
|
||||
|
||||
|
||||
class Shell(Cmd):
|
||||
"""
|
||||
Query shell.
|
||||
"""
|
||||
|
||||
def __init__(self):
|
||||
super(Shell, self).__init__()
|
||||
super().__init__()
|
||||
|
||||
self.intro = "query shell"
|
||||
self.prompt = "(search) "
|
||||
|
||||
self.embeddings = None
|
||||
self.sections = None
|
||||
self.data = None
|
||||
|
||||
def preloop(self):
|
||||
# Create embeddings model, backed by sentence-transformers & transformers
|
||||
self.embeddings = Embeddings({"method": "transformers", "path": "sentence-transformers/bert-base-nli-mean-tokens"})
|
||||
self.embeddings = Embeddings({"path": "sentence-transformers/nli-mpnet-base-v2"})
|
||||
|
||||
self.sections = ["US tops 5 million confirmed virus cases",
|
||||
"Canada's last fully intact ice shelf has suddenly collapsed, forming a Manhattan-sized iceberg",
|
||||
"Beijing mobilises invasion craft along coast as Taiwan tensions escalate",
|
||||
"The National Park Service warns against sacrificing slower friends in a bear attack",
|
||||
"Maine man wins $1M from $25 lottery ticket",
|
||||
"Make huge profits without work, earn up to $100,000 a day"]
|
||||
self.data = [
|
||||
"US tops 5 million confirmed virus cases",
|
||||
"Canada's last fully intact ice shelf has suddenly collapsed, forming a Manhattan-sized iceberg",
|
||||
"Beijing mobilises invasion craft along coast as Taiwan tensions escalate",
|
||||
"The National Park Service warns against sacrificing slower friends in a bear attack",
|
||||
"Maine man wins $1M from $25 lottery ticket",
|
||||
"Make huge profits without work, earn up to $100,000 a day",
|
||||
]
|
||||
|
||||
def default(self, line):
|
||||
# Get index of best section that best matches query
|
||||
uid = np.argmax(self.embeddings.similarity(line, self.sections))
|
||||
print(self.sections[uid])
|
||||
uid = self.embeddings.similarity(line, self.data)[0][0]
|
||||
print(self.data[uid])
|
||||
print()
|
||||
|
||||
|
||||
def main():
|
||||
"""
|
||||
Shell execution loop.
|
||||
@@ -46,5 +48,6 @@ def main():
|
||||
|
||||
Shell().cmdloop()
|
||||
|
||||
|
||||
if __name__ == "__main__":
|
||||
main()
|
||||
|
||||
@@ -0,0 +1,82 @@
|
||||
"""
|
||||
Streamlit version of https://colab.research.google.com/github/neuml/txtai/blob/master/examples/13_Similarity_search_with_images.ipynb
|
||||
|
||||
Requires streamlit and torchvision to be installed.
|
||||
pip install streamlit torchvision
|
||||
"""
|
||||
|
||||
import glob
|
||||
import os
|
||||
import sys
|
||||
|
||||
import streamlit as st
|
||||
|
||||
from PIL import Image
|
||||
|
||||
from txtai.embeddings import Embeddings
|
||||
|
||||
|
||||
def images(directory):
|
||||
"""
|
||||
Generator that loops over each image in a directory.
|
||||
|
||||
Args:
|
||||
directory: directory with images
|
||||
"""
|
||||
|
||||
for path in glob.glob(directory + "/*jpg") + glob.glob(directory + "/*png"):
|
||||
yield (path, Image.open(path), None)
|
||||
|
||||
|
||||
@st.cache(allow_output_mutation=True)
|
||||
def build(directory):
|
||||
"""
|
||||
Builds an image embeddings index.
|
||||
|
||||
Args:
|
||||
directory: directory with images
|
||||
|
||||
Returns:
|
||||
Embeddings index
|
||||
"""
|
||||
|
||||
embeddings = Embeddings({"method": "sentence-transformers", "path": "clip-ViT-B-32"})
|
||||
embeddings.index(images(directory))
|
||||
|
||||
# Update model to support multilingual queries
|
||||
embeddings.config["path"] = "sentence-transformers/clip-ViT-B-32-multilingual-v1"
|
||||
embeddings.model = embeddings.loadVectors()
|
||||
|
||||
return embeddings
|
||||
|
||||
|
||||
def app(directory):
|
||||
"""
|
||||
Streamlit application that runs searches against an image embeddings index.
|
||||
|
||||
Args:
|
||||
directory: directory with images
|
||||
"""
|
||||
|
||||
# Build embeddings index
|
||||
embeddings = build(directory)
|
||||
|
||||
st.title("Image search")
|
||||
|
||||
st.markdown("This application shows how images and text can be embedded into the same space to support similarity search. ")
|
||||
st.markdown(
|
||||
"[sentence-transformers](https://github.com/UKPLab/sentence-transformers/tree/master/examples/applications/image-search) "
|
||||
+ "recently added support for the [OpenAI CLIP model](https://github.com/openai/CLIP). This model embeds text and images into "
|
||||
+ "the same space, enabling image similarity search. txtai can directly utilize these models."
|
||||
)
|
||||
|
||||
query = st.text_input("Search query:")
|
||||
if query:
|
||||
index, _ = embeddings.search(query, 1)[0]
|
||||
st.image(Image.open(index))
|
||||
|
||||
|
||||
if __name__ == "__main__":
|
||||
os.environ["TOKENIZERS_PARALLELISM"] = "false"
|
||||
|
||||
app(sys.argv[1])
|
||||
@@ -0,0 +1,76 @@
|
||||
"""
|
||||
Application that queries Wikipedia API and summarizes the top result.
|
||||
|
||||
Install Streamlit
|
||||
pip install streamlit
|
||||
|
||||
Run application
|
||||
streamlit run wiki.py
|
||||
"""
|
||||
|
||||
import os
|
||||
import urllib.parse
|
||||
|
||||
import requests
|
||||
import streamlit as st
|
||||
|
||||
from txtai.pipeline import Summary
|
||||
|
||||
|
||||
class Application:
|
||||
"""
|
||||
Main application.
|
||||
"""
|
||||
|
||||
SEARCH_TEMPLATE = "https://en.wikipedia.org/w/api.php?action=opensearch&search=%s&limit=1&namespace=0&format=json"
|
||||
CONTENT_TEMPLATE = "https://en.wikipedia.org/w/api.php?format=json&action=query&prop=extracts&exintro&explaintext&redirects=1&titles=%s"
|
||||
|
||||
def __init__(self):
|
||||
"""
|
||||
Creates a new application.
|
||||
"""
|
||||
|
||||
self.summary = Summary("sshleifer/distilbart-cnn-12-6")
|
||||
|
||||
def run(self):
|
||||
"""
|
||||
Runs a Streamlit application.
|
||||
"""
|
||||
|
||||
st.title("Wikipedia")
|
||||
st.markdown("This application queries the Wikipedia API and summarizes the top result.")
|
||||
|
||||
query = st.text_input("Query")
|
||||
|
||||
if query:
|
||||
query = urllib.parse.quote_plus(query)
|
||||
data = requests.get(Application.SEARCH_TEMPLATE % query).json()
|
||||
if data and data[1]:
|
||||
page = urllib.parse.quote_plus(data[1][0])
|
||||
content = requests.get(Application.CONTENT_TEMPLATE % page).json()
|
||||
content = list(content["query"]["pages"].values())[0]["extract"]
|
||||
|
||||
st.write(self.summary(content))
|
||||
st.markdown("*Source: " + data[3][0] + "*")
|
||||
else:
|
||||
st.markdown("*No results found*")
|
||||
|
||||
|
||||
@st.cache(allow_output_mutation=True)
|
||||
def create():
|
||||
"""
|
||||
Creates and caches a Streamlit application.
|
||||
|
||||
Returns:
|
||||
Application
|
||||
"""
|
||||
|
||||
return Application()
|
||||
|
||||
|
||||
if __name__ == "__main__":
|
||||
os.environ["TOKENIZERS_PARALLELISM"] = "false"
|
||||
|
||||
# Create and run application
|
||||
app = create()
|
||||
app.run()
|
||||
@@ -0,0 +1,248 @@
|
||||
"""
|
||||
Build txtai workflows.
|
||||
|
||||
Requires streamlit to be installed.
|
||||
pip install streamlit
|
||||
"""
|
||||
|
||||
import os
|
||||
|
||||
import pandas as pd
|
||||
import streamlit as st
|
||||
|
||||
from txtai.embeddings import Documents, Embeddings
|
||||
from txtai.pipeline import Segmentation, Summary, Textractor, Transcription, Translation
|
||||
from txtai.workflow import Workflow, Task, UrlTask
|
||||
|
||||
|
||||
class Application:
|
||||
"""
|
||||
Streamlit application.
|
||||
"""
|
||||
|
||||
def __init__(self):
|
||||
"""
|
||||
Creates a new Streamlit application.
|
||||
"""
|
||||
|
||||
# Component options
|
||||
self.components = {}
|
||||
|
||||
# Defined pipelines
|
||||
self.pipelines = {}
|
||||
|
||||
# Current workflow
|
||||
self.workflow = []
|
||||
|
||||
# Embeddings index params
|
||||
self.embeddings = None
|
||||
self.documents = None
|
||||
self.data = None
|
||||
|
||||
def number(self, label):
|
||||
"""
|
||||
Extracts a number from a text input field.
|
||||
|
||||
Args:
|
||||
label: label to use for text input field
|
||||
|
||||
Returns:
|
||||
numeric input
|
||||
"""
|
||||
|
||||
value = st.sidebar.text_input(label)
|
||||
return int(value) if value else None
|
||||
|
||||
def options(self, component):
|
||||
"""
|
||||
Extracts component settings into a component configuration dict.
|
||||
|
||||
Args:
|
||||
component: component type
|
||||
|
||||
Returns:
|
||||
dict with component settings
|
||||
"""
|
||||
|
||||
options = {"type": component}
|
||||
|
||||
st.sidebar.markdown("---")
|
||||
if component == "summary":
|
||||
st.sidebar.markdown("**Summary** \n*Abstractive text summarization*")
|
||||
options["path"] = st.sidebar.text_input("Model", value="sshleifer/distilbart-cnn-12-6")
|
||||
options["minlength"] = self.number("Min length")
|
||||
options["maxlength"] = self.number("Max length")
|
||||
|
||||
elif component in ("segment", "textract"):
|
||||
if component == "segment":
|
||||
st.sidebar.markdown("**Segment** \n*Split text into semantic units*")
|
||||
else:
|
||||
st.sidebar.markdown("**Textractor** \n*Extract text from documents*")
|
||||
|
||||
options["sentences"] = st.sidebar.checkbox("Split sentences")
|
||||
options["lines"] = st.sidebar.checkbox("Split lines")
|
||||
options["paragraphs"] = st.sidebar.checkbox("Split paragraphs")
|
||||
options["join"] = st.sidebar.checkbox("Join tokenized")
|
||||
options["minlength"] = self.number("Min section length")
|
||||
|
||||
elif component == "transcribe":
|
||||
st.sidebar.markdown("**Transcribe** \n*Transcribe audio to text*")
|
||||
options["path"] = st.sidebar.text_input("Model", value="facebook/wav2vec2-base-960h")
|
||||
|
||||
elif component == "translate":
|
||||
st.sidebar.markdown("**Translate** \n*Machine translation*")
|
||||
options["target"] = st.sidebar.text_input("Target language code", value="en")
|
||||
|
||||
elif component == "embeddings":
|
||||
st.sidebar.markdown("**Embeddings Index** \n*Index workflow output*")
|
||||
options["path"] = st.sidebar.text_area("Embeddings model path", value="sentence-transformers/nli-mpnet-base-v2")
|
||||
|
||||
return options
|
||||
|
||||
def build(self, components):
|
||||
"""
|
||||
Builds a workflow using components.
|
||||
|
||||
Args:
|
||||
components: list of components to add to workflow
|
||||
"""
|
||||
|
||||
# Clear application
|
||||
self.__init__()
|
||||
|
||||
# pylint: disable=W0108
|
||||
tasks = []
|
||||
for component in components:
|
||||
wtype = component.pop("type")
|
||||
self.components[wtype] = component
|
||||
|
||||
if wtype == "summary":
|
||||
self.pipelines[wtype] = Summary(component.pop("path"))
|
||||
tasks.append(Task(lambda x: self.pipelines["summary"](x, **self.components["summary"])))
|
||||
|
||||
elif wtype == "segment":
|
||||
self.pipelines[wtype] = Segmentation(**self.components["segment"])
|
||||
tasks.append(Task(self.pipelines["segment"]))
|
||||
|
||||
elif wtype == "textract":
|
||||
self.pipelines[wtype] = Textractor(**self.components["textract"])
|
||||
tasks.append(UrlTask(self.pipelines["textract"]))
|
||||
|
||||
elif wtype == "transcribe":
|
||||
self.pipelines[wtype] = Transcription(component.pop("path"))
|
||||
tasks.append(UrlTask(self.pipelines["transcribe"], r".\.wav$"))
|
||||
|
||||
elif wtype == "translate":
|
||||
self.pipelines[wtype] = Translation()
|
||||
tasks.append(Task(lambda x: self.pipelines["translate"](x, **self.components["translate"])))
|
||||
|
||||
elif wtype == "embeddings":
|
||||
self.embeddings = Embeddings({**component})
|
||||
self.documents = Documents()
|
||||
tasks.append(Task(self.documents.add, unpack=False))
|
||||
|
||||
self.workflow = Workflow(tasks)
|
||||
|
||||
def process(self, data):
|
||||
"""
|
||||
Processes the current application action.
|
||||
|
||||
Args:
|
||||
data: input data
|
||||
"""
|
||||
|
||||
if data and self.workflow:
|
||||
# Build tuples for embedding index
|
||||
if self.documents:
|
||||
data = [(x, element, None) for x, element in enumerate(data)]
|
||||
|
||||
# Process workflow
|
||||
for result in self.workflow(data):
|
||||
if not self.documents:
|
||||
st.write(result)
|
||||
|
||||
# Build embeddings index
|
||||
if self.documents:
|
||||
# Cache data
|
||||
self.data = [x[1] for x in self.documents]
|
||||
|
||||
with st.spinner("Building embedding index...."):
|
||||
self.embeddings.index(self.documents)
|
||||
self.documents.close()
|
||||
|
||||
# Clear workflow
|
||||
self.documents, self.pipelines, self.workflow = None, None, None
|
||||
|
||||
if self.embeddings and self.data:
|
||||
# Set query and limit
|
||||
query = st.text_input("Query")
|
||||
limit = min(5, len(self.data))
|
||||
|
||||
st.markdown(
|
||||
"""
|
||||
<style>
|
||||
table td:nth-child(1) {
|
||||
display: none
|
||||
}
|
||||
table th:nth-child(1) {
|
||||
display: none
|
||||
}
|
||||
table {text-align: left !important}
|
||||
</style>
|
||||
""",
|
||||
unsafe_allow_html=True,
|
||||
)
|
||||
|
||||
if query:
|
||||
df = pd.DataFrame([{"content": self.data[uid], "score": score} for uid, score in self.embeddings.search(query, limit)])
|
||||
st.table(df)
|
||||
|
||||
def run(self):
|
||||
"""
|
||||
Runs Streamlit application.
|
||||
"""
|
||||
|
||||
st.sidebar.image("https://github.com/neuml/txtai/raw/master/logo.png", width=256)
|
||||
st.sidebar.markdown("# Workflow builder \n*Build and apply workflows to data* ")
|
||||
|
||||
# Get selected components
|
||||
selected = st.sidebar.multiselect("Select components", ["embeddings", "segment", "summary", "textract", "transcribe", "translate"])
|
||||
|
||||
# Get selected options
|
||||
components = [self.options(component) for component in selected]
|
||||
st.sidebar.markdown("---")
|
||||
|
||||
# Build or re-build workflow when build button clicked
|
||||
build = st.sidebar.button("Build")
|
||||
if build:
|
||||
with st.spinner("Building workflow...."):
|
||||
self.build(components)
|
||||
|
||||
with st.beta_expander("Data", expanded=not self.data):
|
||||
data = st.text_area("Input", height=10)
|
||||
|
||||
# Parse text items
|
||||
data = [x for x in data.split("\n") if x] if "file://" in data else [data]
|
||||
|
||||
# Process current action
|
||||
self.process(data)
|
||||
|
||||
|
||||
@st.cache(allow_output_mutation=True)
|
||||
def create():
|
||||
"""
|
||||
Creates and caches a Streamlit application.
|
||||
|
||||
Returns:
|
||||
Application
|
||||
"""
|
||||
|
||||
return Application()
|
||||
|
||||
|
||||
if __name__ == "__main__":
|
||||
os.environ["TOKENIZERS_PARALLELISM"] = "false"
|
||||
|
||||
# Create and run application
|
||||
app = create()
|
||||
app.run()
|
||||

+48
@@ -0,0 +1,48 @@
|
||||
#
|
||||
# txtai Material for MkDocs configuration
|
||||
#
|
||||
|
||||
site_name: txtai
|
||||
repo_name: neuml/txtai
|
||||
repo_url: https://github.com/neuml/txtai
|
||||
copyright: © NeuML LLC, Apache-2.0 License
|
||||
theme:
|
||||
name: material
|
||||
logo: images/logo.png
|
||||
favicon: images/logo.png
|
||||
icon:
|
||||
repo: fontawesome/brands/github
|
||||
palette:
|
||||
primary: blue
|
||||
accent: blue
|
||||
plugins:
|
||||
- search
|
||||
- mkdocstrings:
|
||||
handlers:
|
||||
python:
|
||||
rendering:
|
||||
show_root_full_path: false
|
||||
show_root_heading: true
|
||||
show_root_toc_entry: false
|
||||
markdown_extensions:
|
||||
- pymdownx.highlight
|
||||
- pymdownx.superfences
|
||||
nav:
|
||||
- Home: index.md
|
||||
- Installation: install.md
|
||||
- Examples: examples.md
|
||||
- Embeddings: embeddings.md
|
||||
- Pipelines:
|
||||
- Overview: pipelines/overview.md
|
||||
- Extractor: pipelines/extractor.md
|
||||
- Labels: pipelines/labels.md
|
||||
- ONNX: pipelines/onnx.md
|
||||
- Segmentation: pipelines/segmentation.md
|
||||
- Similarity: pipelines/similarity.md
|
||||
- Summary: pipelines/summary.md
|
||||
- Textractor: pipelines/textractor.md
|
||||
- Trainer: pipelines/trainer.md
|
||||
- Transcription: pipelines/transcription.md
|
||||
- Translation: pipelines/translation.md
|
||||
- Workflows: workflows.md
|
||||
- API: api.md
|
||||
@@ -0,0 +1,2 @@
|
||||
[tool.black]
|
||||
line-length = 150
|
||||
@@ -1,47 +1,76 @@
|
||||
# pylint: disable = C0111
|
||||
from setuptools import find_packages, setup
|
||||
|
||||
with open("README.md", "r") as f:
|
||||
with open("README.md", "r", encoding="utf-8") as f:
|
||||
DESCRIPTION = f.read()
|
||||
|
||||
setup(name="txtai",
|
||||
version="1.2.0",
|
||||
author="NeuML",
|
||||
description="AI-powered search engine",
|
||||
long_description=DESCRIPTION,
|
||||
long_description_content_type="text/markdown",
|
||||
url="https://github.com/neuml/txtai",
|
||||
project_urls={
|
||||
"Documentation": "https://github.com/neuml/txtai",
|
||||
"Issue Tracker": "https://github.com/neuml/txtai/issues",
|
||||
"Source Code": "https://github.com/neuml/txtai",
|
||||
},
|
||||
license="Apache 2.0: http://www.apache.org/licenses/LICENSE-2.0",
|
||||
packages=find_packages(where="src/python"),
|
||||
package_dir={"": "src/python"},
|
||||
keywords="search embedding machine-learning nlp",
|
||||
python_requires=">=3.6",
|
||||
install_requires=[
|
||||
"annoy>=1.16.3",
|
||||
"faiss-cpu>=1.6.3; os_name != 'nt'",
|
||||
"fasttext>=0.9.2",
|
||||
"hnswlib>=0.4.0",
|
||||
"nltk>=3.5",
|
||||
"numpy>=1.18.4",
|
||||
"pymagnitude-lite>=0.1.43",
|
||||
"regex>=2020.5.14",
|
||||
"scikit-learn>=0.23.1",
|
||||
"torch>=1.4.0",
|
||||
"tqdm>=4.46.0",
|
||||
"sentence-transformers>=0.3.3",
|
||||
"transformers==3.0.2"
|
||||
],
|
||||
classifiers=[
|
||||
"License :: OSI Approved :: Apache Software License",
|
||||
"Operating System :: OS Independent",
|
||||
"Programming Language :: Python :: 3",
|
||||
"Topic :: Scientific/Engineering :: Artificial Intelligence",
|
||||
"Topic :: Software Development",
|
||||
"Topic :: Text Processing :: Indexing",
|
||||
"Topic :: Utilities"
|
||||
])
|
||||
# Required dependencies
|
||||
install = ["faiss-cpu>=1.7.1.post2", "numpy>=1.18.4", "torch>=1.6.0", "transformers>=4.10.2"]
|
||||
|
||||
# Optional dependencies
|
||||
extras = {}
|
||||
|
||||
extras["dev"] = ["black", "coverage", "pre-commit", "pylint"]
|
||||
|
||||
extras["api"] = [
|
||||
"aiohttp>=3.7.4",
|
||||
"fastapi>=0.61.1",
|
||||
"PyYAML>=5.3",
|
||||
"uvicorn>=0.12.1",
|
||||
]
|
||||
|
||||
extras["model"] = ["onnxruntime>=1.8.1"]
|
||||
|
||||
extras["pipeline"] = [
|
||||
"fasttext>=0.9.2",
|
||||
"nltk>=3.5",
|
||||
"onnx>=1.10.1",
|
||||
"onnxruntime>=1.8.1",
|
||||
"sentencepiece>=0.1.91",
|
||||
"soundfile>=0.10.3.post1",
|
||||
"tika>=1.24",
|
||||
]
|
||||
|
||||
extras["similarity"] = [
|
||||
"annoy>=1.16.3",
|
||||
"fasttext>=0.9.2",
|
||||
"hnswlib>=0.5.0",
|
||||
"pymagnitude-lite>=0.1.43",
|
||||
"scikit-learn>=0.23.1",
|
||||
"sentence-transformers>=2.0.0",
|
||||
]
|
||||
|
||||
extras["workflow"] = ["apache-libcloud>=3.3.1", "pillow>=7.2.0", "requests>=2.24.0"]
|
||||
|
||||
extras["all"] = extras["api"] + extras["model"] + extras["pipeline"] + extras["similarity"] + extras["workflow"]
|
||||
|
||||
setup(
|
||||
name="txtai",
|
||||
version="3.3.0",
|
||||
author="NeuML",
|
||||
description="Build AI-powered semantic search applications",
|
||||
long_description=DESCRIPTION,
|
||||
long_description_content_type="text/markdown",
|
||||
url="https://github.com/neuml/txtai",
|
||||
project_urls={
|
||||
"Documentation": "https://github.com/neuml/txtai",
|
||||
"Issue Tracker": "https://github.com/neuml/txtai/issues",
|
||||
"Source Code": "https://github.com/neuml/txtai",
|
||||
},
|
||||
license="Apache 2.0: http://www.apache.org/licenses/LICENSE-2.0",
|
||||
packages=find_packages(where="src/python"),
|
||||
package_dir={"": "src/python"},
|
||||
keywords="search embedding machine-learning nlp",
|
||||
python_requires=">=3.6",
|
||||
install_requires=install,
|
||||
extras_require=extras,
|
||||
classifiers=[
|
||||
"License :: OSI Approved :: Apache Software License",
|
||||
"Operating System :: OS Independent",
|
||||
"Programming Language :: Python :: 3",
|
||||
"Topic :: Scientific/Engineering :: Artificial Intelligence",
|
||||
"Topic :: Software Development",
|
||||
"Topic :: Text Processing :: Indexing",
|
||||
"Topic :: Utilities",
|
||||
],
|
||||
)
|
||||
|
||||
@@ -1,200 +0,0 @@
|
||||
"""
|
||||
ANN (Approximate Nearest Neighbors) module
|
||||
"""
|
||||
|
||||
import numpy as np
|
||||
|
||||
# pylint: disable=E0611
|
||||
from annoy import AnnoyIndex
|
||||
from hnswlib import Index
|
||||
|
||||
# Conditionally import Faiss as it's only supported on Linux/macOS
|
||||
try:
|
||||
import faiss
|
||||
FAISS = True
|
||||
except ImportError:
|
||||
FAISS = False
|
||||
|
||||
class ANN(object):
|
||||
"""
|
||||
Base class for ANN models.
|
||||
"""
|
||||
|
||||
@staticmethod
|
||||
def create(config):
|
||||
"""
|
||||
Create an ANN model.
|
||||
|
||||
Args:
|
||||
config: index configuration parameters
|
||||
|
||||
Returns:
|
||||
ANN
|
||||
"""
|
||||
|
||||
# ANN model
|
||||
model = None
|
||||
backend = config.get("backend")
|
||||
|
||||
# Default backend if not provided, based on available libraries
|
||||
if not backend:
|
||||
backend = "faiss" if FAISS else "annoy"
|
||||
|
||||
# Create ANN instance
|
||||
if backend == "annoy":
|
||||
model = Annoy(config)
|
||||
elif backend == "hnsw":
|
||||
model = HNSW(config)
|
||||
else:
|
||||
# Raise error if trying to create a Faiss index without Faiss installed
|
||||
if not FAISS:
|
||||
raise ImportError("Faiss library is not installed")
|
||||
|
||||
model = Faiss(config)
|
||||
|
||||
# Store config back
|
||||
config["backend"] = backend
|
||||
|
||||
return model
|
||||
|
||||
def __init__(self, config):
|
||||
"""
|
||||
Creates a new ANN model.
|
||||
"""
|
||||
|
||||
# ANN index
|
||||
self.model = None
|
||||
|
||||
# Model configuration
|
||||
self.config = config
|
||||
|
||||
def load(self, path):
|
||||
"""
|
||||
Loads an ANN model at path.
|
||||
"""
|
||||
|
||||
def index(self, embeddings):
|
||||
"""
|
||||
Builds an ANN model.
|
||||
|
||||
Args:
|
||||
embeddings: embeddings array
|
||||
"""
|
||||
|
||||
def search(self, query, limit):
|
||||
"""
|
||||
Searches ANN model for query. Returns topn results.
|
||||
|
||||
Args:
|
||||
query: query vector
|
||||
limit: maximum results
|
||||
"""
|
||||
|
||||
def save(self, path):
|
||||
"""
|
||||
Saves an ANN model at path.
|
||||
"""
|
||||
|
||||
class Annoy(ANN):
|
||||
"""
|
||||
Builds an ANN model using the Annoy library.
|
||||
"""
|
||||
|
||||
def load(self, path):
|
||||
# Load index
|
||||
self.model = AnnoyIndex(self.config["dimensions"], self.config["metric"])
|
||||
self.model.load(path)
|
||||
|
||||
def index(self, embeddings):
|
||||
# Inner product is equal to cosine similarity on normalized vectors
|
||||
self.config["metric"] = "dot"
|
||||
|
||||
# Create index
|
||||
self.model = AnnoyIndex(self.config["dimensions"], self.config["metric"])
|
||||
|
||||
# Add items
|
||||
for x in range(embeddings.shape[0]):
|
||||
self.model.add_item(x, embeddings[x])
|
||||
|
||||
# Build index
|
||||
self.model.build(10)
|
||||
|
||||
def search(self, query, limit):
|
||||
# Run the query
|
||||
ids, scores = self.model.get_nns_by_vector(query, n=limit, include_distances=True)
|
||||
|
||||
# Map results to [(id, score)]
|
||||
return list(zip(ids, scores))
|
||||
|
||||
def save(self, path):
|
||||
# Write index
|
||||
self.model.save(path)
|
||||
|
||||
class Faiss(ANN):
|
||||
"""
|
||||
Builds an ANN model using the Faiss library.
|
||||
"""
|
||||
|
||||
def load(self, path):
|
||||
# Load index
|
||||
self.model = faiss.read_index(path)
|
||||
|
||||
def index(self, embeddings):
|
||||
# Create embeddings index. Inner product is equal to cosine similarity on normalized vectors.
|
||||
if self.config.get("quantize"):
|
||||
params = "IVF100,SQ8" if embeddings.shape[0] >= 5000 else "IDMap,SQ8"
|
||||
else:
|
||||
params = "IVF100,Flat" if embeddings.shape[0] >= 5000 else "IDMap,Flat"
|
||||
|
||||
self.model = faiss.index_factory(embeddings.shape[1], params, faiss.METRIC_INNER_PRODUCT)
|
||||
|
||||
# Train model
|
||||
self.model.train(embeddings)
|
||||
self.model.add_with_ids(embeddings, np.array(range(embeddings.shape[0])))
|
||||
|
||||
def search(self, query, limit):
|
||||
# Run the query
|
||||
self.model.nprobe = 6
|
||||
scores, ids = self.model.search(query.reshape(1, -1), limit)
|
||||
|
||||
# Map results to [(id, score)]
|
||||
return list(zip(ids[0].tolist(), (scores[0]).tolist()))
|
||||
|
||||
def save(self, path):
|
||||
# Write index
|
||||
faiss.write_index(self.model, path)
|
||||
|
||||
class HNSW(ANN):
|
||||
"""
|
||||
Builds an ANN model using the hnswlib library.
|
||||
"""
|
||||
|
||||
def load(self, path):
|
||||
# Load index
|
||||
self.model = Index(dim=self.config["dimensions"], space=self.config["metric"])
|
||||
self.model.load_index(path)
|
||||
|
||||
def index(self, embeddings):
|
||||
# Inner product is equal to cosine similarity on normalized vectors
|
||||
self.config["metric"] = "ip"
|
||||
|
||||
# Create index
|
||||
self.model = Index(dim=self.config["dimensions"], space=self.config["metric"])
|
||||
self.model.init_index(max_elements=embeddings.shape[0])
|
||||
|
||||
# Add items
|
||||
self.model.add_items(embeddings, np.array(range(embeddings.shape[0])))
|
||||
|
||||
def search(self, query, limit):
|
||||
# Run the query
|
||||
ids, distances = self.model.knn_query(query.reshape(1, -1), k=limit)
|
||||
|
||||
# Convert distances to similarity scores
|
||||
scores = [1 - d for d in distances[0]]
|
||||
|
||||
# Map results to [(id, score)]
|
||||
return list(zip(ids[0], scores))
|
||||
|
||||
def save(self, path):
|
||||
# Write index
|
||||
self.model.save_index(path)
|
||||
@@ -0,0 +1,9 @@
|
||||
"""
|
||||
ANN imports
|
||||
"""
|
||||
|
||||
from .annoy import Annoy
|
||||
from .base import ANN
|
||||
from .factory import ANNFactory
|
||||
from .faiss import Faiss
|
||||
from .hnsw import HNSW
|
||||
@@ -0,0 +1,61 @@
|
||||
"""
|
||||
Annoy module
|
||||
"""
|
||||
|
||||
# Conditional import
|
||||
try:
|
||||
from annoy import AnnoyIndex
|
||||
|
||||
ANNOY = True
|
||||
except ImportError:
|
||||
ANNOY = False
|
||||
|
||||
from .base import ANN
|
||||
|
||||
# pylint: disable=W0223
|
||||
class Annoy(ANN):
|
||||
"""
|
||||
Builds an ANN model using the Annoy library.
|
||||
"""
|
||||
|
||||
def load(self, path):
|
||||
# Load index
|
||||
self.model = AnnoyIndex(self.config["dimensions"], self.config["metric"])
|
||||
self.model.load(path)
|
||||
|
||||
def index(self, embeddings):
|
||||
# Inner product is equal to cosine similarity on normalized vectors
|
||||
self.config["metric"] = "dot"
|
||||
|
||||
# Create index
|
||||
self.model = AnnoyIndex(self.config["dimensions"], self.config["metric"])
|
||||
|
||||
# Add items
|
||||
for x in range(embeddings.shape[0]):
|
||||
self.model.add_item(x, embeddings[x])
|
||||
|
||||
# Build index
|
||||
self.model.build(self.setting("ntrees", 10))
|
||||
|
||||
def search(self, queries, limit):
|
||||
# Lookup search k setting
|
||||
searchk = self.setting("searchk", -1)
|
||||
|
||||
# Annoy doesn't have a built in batch query method
|
||||
results = []
|
||||
for query in queries:
|
||||
# Run the query
|
||||
ids, scores = self.model.get_nns_by_vector(query, n=limit, search_k=searchk, include_distances=True)
|
||||
|
||||
# Map results to [(id, score)]
|
||||
results.append(list(zip(ids, scores)))
|
||||
|
||||
return results
|
||||
|
||||
def count(self):
|
||||
# Number of items in index
|
||||
return self.model.get_n_items()
|
||||
|
||||
def save(self, path):
|
||||
# Write index
|
||||
self.model.save(path)
|
||||
@@ -0,0 +1,107 @@
|
||||
"""
|
||||
ANN (Approximate Nearest Neighbors) module
|
||||
"""
|
||||
|
||||
|
||||
class ANN:
|
||||
"""
|
||||
Base class for ANN models.
|
||||
"""
|
||||
|
||||
def __init__(self, config):
|
||||
"""
|
||||
Creates a new ANN model.
|
||||
"""
|
||||
|
||||
# ANN index
|
||||
self.model = None
|
||||
|
||||
# Model configuration
|
||||
self.config = config
|
||||
|
||||
def load(self, path):
|
||||
"""
|
||||
Loads an ANN model at path.
|
||||
"""
|
||||
|
||||
raise NotImplementedError
|
||||
|
||||
def index(self, embeddings):
|
||||
"""
|
||||
Builds an ANN model.
|
||||
|
||||
Args:
|
||||
embeddings: embeddings array
|
||||
"""
|
||||
|
||||
raise NotImplementedError
|
||||
|
||||
def append(self, embeddings):
|
||||
"""
|
||||
Append elements to an existing model.
|
||||
|
||||
Args:
|
||||
embeddings: embeddings array
|
||||
"""
|
||||
|
||||
raise NotImplementedError
|
||||
|
||||
def delete(self, ids):
|
||||
"""
|
||||
Deletes elements from existing model.
|
||||
|
||||
Args:
|
||||
ids: ids to delete
|
||||
"""
|
||||
|
||||
raise NotImplementedError
|
||||
|
||||
def search(self, queries, limit):
|
||||
"""
|
||||
Searches ANN model for query. Returns topn results.
|
||||
|
||||
Args:
|
||||
queries: queries array
|
||||
limit: maximum results
|
||||
|
||||
Returns:
|
||||
query results
|
||||
"""
|
||||
|
||||
raise NotImplementedError
|
||||
|
||||
def count(self):
|
||||
"""
|
||||
Number of elements in the ANN model.
|
||||
|
||||
Returns:
|
||||
count
|
||||
"""
|
||||
|
||||
raise NotImplementedError
|
||||
|
||||
def save(self, path):
|
||||
"""
|
||||
Saves an ANN model at path.
|
||||
"""
|
||||
|
||||
raise NotImplementedError
|
||||
|
||||
def setting(self, name, default=None):
|
||||
"""
|
||||
Looks up backend specific setting.
|
||||
|
||||
Args:
|
||||
name: setting name
|
||||
default: default value when setting not found
|
||||
|
||||
Returns:
|
||||
setting value
|
||||
"""
|
||||
|
||||
# Get the backend-specific config object
|
||||
backend = self.config.get(self.config["backend"])
|
||||
|
||||
# Get setting value, set default value if not found
|
||||
setting = backend.get(name) if backend else None
|
||||
return setting if setting else default
|
||||
@@ -0,0 +1,48 @@
|
||||
"""
|
||||
Factory module
|
||||
"""
|
||||
|
||||
from .annoy import Annoy, ANNOY
|
||||
from .faiss import Faiss
|
||||
from .hnsw import HNSW, HNSWLIB
|
||||
|
||||
|
||||
class ANNFactory:
|
||||
"""
|
||||
Methods to create ANN models.
|
||||
"""
|
||||
|
||||
@staticmethod
|
||||
def create(config):
|
||||
"""
|
||||
Create an ANN model.
|
||||
|
||||
Args:
|
||||
config: index configuration parameters
|
||||
|
||||
Returns:
|
||||
ANN
|
||||
"""
|
||||
|
||||
# ANN model
|
||||
model = None
|
||||
backend = config.get("backend", "faiss")
|
||||
|
||||
# Create ANN instance
|
||||
if backend == "annoy":
|
||||
if not ANNOY:
|
||||
raise ImportError('annoy library is not available - install "similarity" extra to enable')
|
||||
|
||||
model = Annoy(config)
|
||||
elif backend == "hnsw":
|
||||
if not HNSWLIB:
|
||||
raise ImportError('hnswlib library is not available - install "similarity" extra to enable')
|
||||
|
||||
model = HNSW(config)
|
||||
else:
|
||||
model = Faiss(config)
|
||||
|
||||
# Store config back
|
||||
config["backend"] = backend
|
||||
|
||||
return model
|
||||
@@ -0,0 +1,72 @@
|
||||
"""
|
||||
Faiss module
|
||||
"""
|
||||
|
||||
import numpy as np
|
||||
|
||||
from faiss import index_factory, METRIC_INNER_PRODUCT, read_index, write_index
|
||||
|
||||
from .base import ANN
|
||||
|
||||
|
||||
class Faiss(ANN):
|
||||
"""
|
||||
Builds an ANN model using the Faiss library.
|
||||
"""
|
||||
|
||||
def load(self, path):
|
||||
# Load index
|
||||
self.model = read_index(path)
|
||||
|
||||
def index(self, embeddings):
|
||||
# Lookup components setting
|
||||
components = self.setting("components")
|
||||
|
||||
# Create embeddings index. Inner product is equal to cosine similarity on normalized vectors.
|
||||
if components:
|
||||
params = components
|
||||
elif self.config.get("quantize"):
|
||||
params = "IVF100,SQ8" if embeddings.shape[0] >= 5000 else "IDMap,SQ8"
|
||||
else:
|
||||
params = "IVF100,Flat" if embeddings.shape[0] >= 5000 else "IDMap,Flat"
|
||||
|
||||
self.model = index_factory(embeddings.shape[1], params, METRIC_INNER_PRODUCT)
|
||||
|
||||
# Train model
|
||||
self.model.train(embeddings)
|
||||
self.model.add_with_ids(embeddings, np.arange(embeddings.shape[0], dtype=np.int64))
|
||||
|
||||
# Update id offset
|
||||
self.config["offset"] = embeddings.shape[0]
|
||||
|
||||
def append(self, embeddings):
|
||||
new = embeddings.shape[0]
|
||||
|
||||
# Append new ids
|
||||
self.model.add_with_ids(embeddings, np.arange(self.config["offset"], self.config["offset"] + new, dtype=np.int64))
|
||||
|
||||
# Update id offset
|
||||
self.config["offset"] += new
|
||||
|
||||
def delete(self, ids):
|
||||
# Remove specified ids
|
||||
self.model.remove_ids(np.array(ids, dtype=np.int64))
|
||||
|
||||
def search(self, queries, limit):
|
||||
# Run the query
|
||||
self.model.nprobe = self.setting("nprobe", 6)
|
||||
scores, ids = self.model.search(queries, limit)
|
||||
|
||||
# Map results to [(id, score)]
|
||||
results = []
|
||||
for x, score in enumerate(scores):
|
||||
results.append(list(zip(ids[x].tolist(), score.tolist())))
|
||||
|
||||
return results
|
||||
|
||||
def count(self):
|
||||
return self.model.ntotal
|
||||
|
||||
def save(self, path):
|
||||
# Write index
|
||||
write_index(self.model, path)
|
||||
@@ -0,0 +1,95 @@
|
||||
"""
|
||||
HNSW module
|
||||
"""
|
||||
|
||||
import numpy as np
|
||||
|
||||
# Conditional import
|
||||
try:
|
||||
# pylint: disable=E0611
|
||||
from hnswlib import Index
|
||||
|
||||
HNSWLIB = True
|
||||
except ImportError:
|
||||
HNSWLIB = False
|
||||
|
||||
from .base import ANN
|
||||
|
||||
|
||||
class HNSW(ANN):
|
||||
"""
|
||||
Builds an ANN model using the hnswlib library.
|
||||
"""
|
||||
|
||||
def load(self, path):
|
||||
# Load index
|
||||
self.model = Index(dim=self.config["dimensions"], space=self.config["metric"])
|
||||
self.model.load_index(path)
|
||||
|
||||
def index(self, embeddings):
|
||||
# Inner product is equal to cosine similarity on normalized vectors
|
||||
self.config["metric"] = "ip"
|
||||
|
||||
# Lookup index settings
|
||||
efconstruction = self.setting("efconstruction", 200)
|
||||
m = self.setting("m", 16)
|
||||
seed = self.setting("randomseed", 100)
|
||||
|
||||
# Create index
|
||||
self.model = Index(dim=self.config["dimensions"], space=self.config["metric"])
|
||||
self.model.init_index(max_elements=embeddings.shape[0], ef_construction=efconstruction, M=m, random_seed=seed)
|
||||
|
||||
# Add items
|
||||
self.model.add_items(embeddings, np.arange(embeddings.shape[0]))
|
||||
|
||||
# Update id offset and set delete counter
|
||||
self.config["offset"] = embeddings.shape[0]
|
||||
self.config["deletes"] = 0
|
||||
|
||||
def append(self, embeddings):
|
||||
new = embeddings.shape[0]
|
||||
|
||||
# Resize index
|
||||
self.model.resize_index(self.config["offset"] + new)
|
||||
|
||||
# Append new ids
|
||||
self.model.add_items(embeddings, np.arange(self.config["offset"], self.config["offset"] + new))
|
||||
|
||||
# Update id offset
|
||||
self.config["offset"] += new
|
||||
|
||||
def delete(self, ids):
|
||||
# Mark elements as deleted to omit from search results
|
||||
for uid in ids:
|
||||
try:
|
||||
self.model.mark_deleted(uid)
|
||||
self.config["deletes"] += 1
|
||||
except RuntimeError:
|
||||
# Ignore label not found error
|
||||
continue
|
||||
|
||||
def search(self, queries, limit):
|
||||
# Set ef query param
|
||||
ef = self.setting("efsearch")
|
||||
if ef:
|
||||
self.model.set_ef(ef)
|
||||
|
||||
# Run the query
|
||||
ids, distances = self.model.knn_query(queries, k=limit)
|
||||
|
||||
# Map results to [(id, score)]
|
||||
results = []
|
||||
for x, distance in enumerate(distances):
|
||||
# Convert distances to similarity scores
|
||||
scores = [1 - d for d in distance]
|
||||
|
||||
results.append(list(zip(ids[x], scores)))
|
||||
|
||||
return results
|
||||
|
||||
def count(self):
|
||||
return self.model.get_current_count() - self.config["deletes"]
|
||||
|
||||
def save(self, path):
|
||||
# Write index
|
||||
self.model.save_index(path)
|
||||
@@ -0,0 +1,14 @@
|
||||
"""
|
||||
API imports
|
||||
"""
|
||||
|
||||
# Conditional import
|
||||
try:
|
||||
from .application import app, start
|
||||
from .base import API
|
||||
from .cluster import Cluster
|
||||
from .extension import Extension
|
||||
from .factory import Factory
|
||||
except ImportError as missing:
|
||||
# pylint: disable=W0707
|
||||
raise ImportError('API is not available - install "api" extra to enable') from missing
|
||||
@@ -0,0 +1,88 @@
|
||||
"""
|
||||
FastAPI application module
|
||||
"""
|
||||
|
||||
import os
|
||||
|
||||
import yaml
|
||||
|
||||
from fastapi import FastAPI
|
||||
|
||||
from .base import API
|
||||
from .factory import Factory
|
||||
|
||||
# pylint: disable=R0401
|
||||
from .routers import embeddings, extractor, labels, segmentation, similarity, summary, textractor, transcription, translation, workflow
|
||||
|
||||
# API instance
|
||||
app = FastAPI()
|
||||
|
||||
# Global API instance
|
||||
INSTANCE = None
|
||||
|
||||
|
||||
def get():
|
||||
"""
|
||||
Returns global API instance.
|
||||
|
||||
Returns:
|
||||
API instance
|
||||
"""
|
||||
|
||||
# pylint: disable=W0603
|
||||
global INSTANCE
|
||||
return INSTANCE
|
||||
|
||||
|
||||
@app.on_event("startup")
|
||||
def start():
|
||||
"""
|
||||
FastAPI startup event. Loads API instance.
|
||||
"""
|
||||
|
||||
# pylint: disable=W0603
|
||||
global INSTANCE
|
||||
|
||||
# Load YAML settings
|
||||
with open(os.getenv("CONFIG"), "r") as f:
|
||||
# Read configuration
|
||||
config = yaml.safe_load(f)
|
||||
|
||||
# Instantiate API instance
|
||||
api = os.getenv("API_CLASS")
|
||||
INSTANCE = Factory.create(config, api) if api else API(config)
|
||||
|
||||
# Router definitions
|
||||
routers = [
|
||||
("embeddings", embeddings.router),
|
||||
("extractor", extractor.router),
|
||||
("labels", labels.router),
|
||||
("segmentation", segmentation.router),
|
||||
("similarity", similarity.router),
|
||||
("summary", summary.router),
|
||||
("textractor", textractor.router),
|
||||
("transcription", transcription.router),
|
||||
("translation", translation.router),
|
||||
("workflow", workflow.router),
|
||||
]
|
||||
|
||||
# Conditionally add routes based on configuration
|
||||
for name, router in routers:
|
||||
if name in config:
|
||||
app.include_router(router)
|
||||
|
||||
# Special case for embeddings clusters
|
||||
if "cluster" in config and "embeddings" not in config:
|
||||
app.include_router(embeddings.router)
|
||||
|
||||
# Special case to add similarity instance for embeddings
|
||||
if "embeddings" in config and "similarity" not in config:
|
||||
app.include_router(similarity.router)
|
||||
|
||||
# Execute extensions if present
|
||||
extensions = os.getenv("EXTENSIONS")
|
||||
if extensions:
|
||||
for extension in extensions.split(","):
|
||||
# Create instance and execute extension
|
||||
extension = Factory.get(extension.strip())()
|
||||
extension(app)
|
||||
@@ -0,0 +1,399 @@
|
||||
"""
|
||||
API module
|
||||
"""
|
||||
|
||||
from .cluster import Cluster
|
||||
|
||||
from ..embeddings import Documents, Embeddings
|
||||
from ..pipeline import PipelineFactory
|
||||
from ..workflow import WorkflowFactory
|
||||
|
||||
|
||||
class API:
|
||||
"""
|
||||
Base API template. Downstream applications can extend this base template to add/modify functionality.
|
||||
"""
|
||||
|
||||
def __init__(self, config):
|
||||
"""
|
||||
Creates an embeddings index instance that is called by FastAPI.
|
||||
|
||||
Args:
|
||||
config: index configuration
|
||||
"""
|
||||
|
||||
# Initialize member variables
|
||||
self.config, self.documents, self.embeddings, self.cluster = config, None, None, None
|
||||
|
||||
# Local embeddings index
|
||||
if self.config.get("path") and Embeddings().exists(self.config["path"]):
|
||||
# Load existing index if available
|
||||
self.embeddings = Embeddings()
|
||||
self.embeddings.load(self.config["path"])
|
||||
elif self.config.get("embeddings"):
|
||||
# Initialize empty embeddings
|
||||
self.embeddings = Embeddings(self.config["embeddings"])
|
||||
|
||||
# Embeddings cluster
|
||||
if self.config.get("cluster"):
|
||||
self.cluster = Cluster(self.config["cluster"])
|
||||
|
||||
# Create pipelines
|
||||
self.pipes()
|
||||
|
||||
# Create workflows
|
||||
self.flows()
|
||||
|
||||
def pipes(self):
|
||||
"""
|
||||
Initialize pipelines.
|
||||
"""
|
||||
|
||||
# Pipeline definitions
|
||||
self.pipelines = {}
|
||||
|
||||
# Default pipelines
|
||||
pipelines = ["extractor", "labels", "segmentation", "similarity", "summary", "textractor", "transcription", "translation"]
|
||||
|
||||
# Add custom pipelines
|
||||
for key in self.config:
|
||||
if "." in key:
|
||||
pipelines.append(key)
|
||||
|
||||
# Create pipelines
|
||||
for pipeline in pipelines:
|
||||
if pipeline in self.config:
|
||||
config = self.config[pipeline] if self.config[pipeline] else {}
|
||||
|
||||
# Custom pipeline parameters
|
||||
if pipeline == "extractor":
|
||||
config["embeddings"] = self.embeddings
|
||||
elif pipeline == "similarity" and "path" not in config and "labels" in self.pipelines:
|
||||
config["model"] = self.pipelines["labels"]
|
||||
|
||||
self.pipelines[pipeline] = PipelineFactory.create(config, pipeline)
|
||||
|
||||
def flows(self):
|
||||
"""
|
||||
Initialize workflows.
|
||||
"""
|
||||
|
||||
self.workflows = {}
|
||||
|
||||
# Create workflows
|
||||
if "workflow" in self.config:
|
||||
for workflow, config in self.config["workflow"].items():
|
||||
for task in config["tasks"]:
|
||||
# Resolve pipeline action
|
||||
if "action" in task:
|
||||
task["action"] = self.pipelines[task["action"]]
|
||||
|
||||
self.workflows[workflow] = WorkflowFactory.create(config)
|
||||
|
||||
def limit(self, limit):
|
||||
"""
|
||||
Parses the number of results to return from the request. Allows range of 1-250, with a default of 10.
|
||||
|
||||
Args:
|
||||
limit: limit parameter
|
||||
|
||||
Returns:
|
||||
bounded limit
|
||||
"""
|
||||
|
||||
# Return between 1 and 250 results, defaults to 10
|
||||
return max(1, min(250, int(limit) if limit else 10))
|
||||
|
||||
def search(self, query, request):
|
||||
"""
|
||||
Finds documents in the embeddings model most similar to the input query. Returns
|
||||
a list of {id: value, score: value} sorted by highest score, where id is the
|
||||
document id in the embeddings model.
|
||||
|
||||
Downstream applications can override this method to provide enriched search results.
|
||||
|
||||
Args:
|
||||
query: query text
|
||||
request: FastAPI request
|
||||
|
||||
Returns:
|
||||
list of {id: value, score: value}
|
||||
"""
|
||||
|
||||
limit = self.limit(request.query_params.get("limit") if request else None)
|
||||
|
||||
if self.cluster:
|
||||
return self.cluster.search(query, limit)
|
||||
if self.embeddings:
|
||||
return [{"id": uid, "score": float(score)} for uid, score in self.embeddings.search(query, limit)]
|
||||
|
||||
return None
|
||||
|
||||
def batchsearch(self, queries, limit):
|
||||
"""
|
||||
Finds documents in the embeddings model most similar to the input queries. Returns
|
||||
a list of {id: value, score: value} sorted by highest score per query, where id is
|
||||
the document id in the embeddings model.
|
||||
|
||||
Args:
|
||||
queries: queries text
|
||||
limit: maximum results
|
||||
|
||||
Returns:
|
||||
list of {id: value, score: value} per query
|
||||
"""
|
||||
|
||||
if self.cluster:
|
||||
return self.cluster.batchsearch(queries, self.limit(limit))
|
||||
if self.embeddings:
|
||||
results = self.embeddings.batchsearch(queries, self.limit(limit))
|
||||
return [[{"id": uid, "score": float(score)} for uid, score in result] for result in results]
|
||||
|
||||
return None
|
||||
|
||||
def add(self, documents):
|
||||
"""
|
||||
Adds a batch of documents for indexing.
|
||||
|
||||
Downstream applications can override this method to also store full documents in an external system.
|
||||
|
||||
Args:
|
||||
documents: list of {id: value, text: value}
|
||||
"""
|
||||
|
||||
if self.cluster:
|
||||
self.cluster.add(documents)
|
||||
elif self.embeddings and self.config.get("writable"):
|
||||
# Only add batch if index is marked writable
|
||||
# Create documents file if not already open
|
||||
if not self.documents:
|
||||
self.documents = Documents()
|
||||
|
||||
# Add batch
|
||||
self.documents.add([(document["id"], document["text"], None) for document in documents])
|
||||
|
||||
def index(self):
|
||||
"""
|
||||
Builds an embeddings index for previously batched documents.
|
||||
"""
|
||||
|
||||
if self.cluster:
|
||||
self.cluster.index()
|
||||
elif self.embeddings and self.config.get("writable") and self.documents:
|
||||
# Build scoring index if scoring method provided
|
||||
if self.config.get("scoring"):
|
||||
self.embeddings.score(self.documents)
|
||||
|
||||
# Build embeddings index
|
||||
self.embeddings.index(self.documents)
|
||||
|
||||
# Save index if path available, otherwise this is an memory-only index
|
||||
if self.config.get("path"):
|
||||
self.embeddings.save(self.config["path"])
|
||||
|
||||
# Reset document stream
|
||||
self.documents.close()
|
||||
self.documents = None
|
||||
|
||||
def upsert(self):
|
||||
"""
|
||||
Runs an embeddings upsert operation for previously batched documents.
|
||||
"""
|
||||
|
||||
if self.cluster:
|
||||
self.cluster.upsert()
|
||||
elif self.embeddings and self.config.get("writable") and self.documents:
|
||||
# Run upsert
|
||||
self.embeddings.upsert(self.documents)
|
||||
|
||||
# Save index if path available, otherwise this is an memory-only index
|
||||
if self.config.get("path"):
|
||||
self.embeddings.save(self.config["path"])
|
||||
|
||||
# Reset document stream
|
||||
self.documents.close()
|
||||
self.documents = None
|
||||
|
||||
def delete(self, ids):
|
||||
"""
|
||||
Deletes from an embeddings index. Returns list of ids deleted.
|
||||
|
||||
Args:
|
||||
ids: list of ids to delete
|
||||
|
||||
Returns:
|
||||
ids deleted
|
||||
"""
|
||||
|
||||
if self.cluster:
|
||||
return self.cluster.delete(ids)
|
||||
if self.embeddings and self.config.get("writable"):
|
||||
return self.embeddings.delete(ids)
|
||||
|
||||
return None
|
||||
|
||||
def count(self):
|
||||
"""
|
||||
Total number of elements in this embeddings index.
|
||||
|
||||
Returns:
|
||||
number of elements in embeddings index
|
||||
"""
|
||||
|
||||
if self.cluster:
|
||||
return self.cluster.count()
|
||||
if self.embeddings:
|
||||
return self.embeddings.count()
|
||||
|
||||
return None
|
||||
|
||||
def similarity(self, query, texts):
|
||||
"""
|
||||
Computes the similarity between query and list of text. Returns a list of
|
||||
{id: value, score: value} sorted by highest score, where id is the index
|
||||
in texts.
|
||||
|
||||
Args:
|
||||
query: query text
|
||||
texts: list of text
|
||||
|
||||
Returns:
|
||||
list of {id: value, score: value}
|
||||
"""
|
||||
|
||||
# Use similarity instance if available otherwise fall back to embeddings model
|
||||
if "similarity" in self.pipelines:
|
||||
return [{"id": uid, "score": float(score)} for uid, score in self.pipelines["similarity"](query, texts)]
|
||||
if self.embeddings:
|
||||
return [{"id": uid, "score": float(score)} for uid, score in self.embeddings.similarity(query, texts)]
|
||||
|
||||
return None
|
||||
|
||||
def batchsimilarity(self, queries, texts):
|
||||
"""
|
||||
Computes the similarity between list of queries and list of text. Returns a list
|
||||
of {id: value, score: value} sorted by highest score per query, where id is the
|
||||
index in texts.
|
||||
|
||||
Args:
|
||||
queries: queries text
|
||||
texts: list of text
|
||||
|
||||
Returns:
|
||||
list of {id: value, score: value} per query
|
||||
"""
|
||||
|
||||
# Use similarity instance if available otherwise fall back to embeddings model
|
||||
if "similarity" in self.pipelines:
|
||||
return [[{"id": uid, "score": float(score)} for uid, score in r] for r in self.pipelines["similarity"](queries, texts)]
|
||||
if self.embeddings:
|
||||
return [[{"id": uid, "score": float(score)} for uid, score in r] for r in self.embeddings.batchsimilarity(queries, texts)]
|
||||
|
||||
return None
|
||||
|
||||
def transform(self, text):
|
||||
"""
|
||||
Transforms text into embeddings arrays.
|
||||
|
||||
Args:
|
||||
text: input text
|
||||
|
||||
Returns:
|
||||
embeddings array
|
||||
"""
|
||||
|
||||
if self.embeddings:
|
||||
return [float(x) for x in self.embeddings.transform((None, text, None))]
|
||||
|
||||
return None
|
||||
|
||||
def batchtransform(self, texts):
|
||||
"""
|
||||
Transforms list of text into embeddings arrays.
|
||||
|
||||
Args:
|
||||
texts: list of text
|
||||
|
||||
Returns:
|
||||
embeddings arrays
|
||||
"""
|
||||
|
||||
if self.embeddings:
|
||||
documents = [(None, text, None) for text in texts]
|
||||
return [[float(x) for x in result] for result in self.embeddings.batchtransform(documents)]
|
||||
|
||||
return None
|
||||
|
||||
def extract(self, queue, texts):
|
||||
"""
|
||||
Extracts answers to input questions.
|
||||
|
||||
Args:
|
||||
queue: list of {name: value, query: value, question: value, snippet: value}
|
||||
texts: list of text
|
||||
|
||||
Returns:
|
||||
list of {name: value, answer: value}
|
||||
"""
|
||||
|
||||
if self.embeddings and "extractor" in self.pipelines:
|
||||
# Convert queue to tuples
|
||||
queue = [(x["name"], x["query"], x.get("question"), x.get("snippet")) for x in queue]
|
||||
return [{"name": name, "answer": answer} for name, answer in self.pipelines["extractor"](queue, texts)]
|
||||
|
||||
return None
|
||||
|
||||
def label(self, text, labels):
|
||||
"""
|
||||
Applies a zero shot classifier to text using a list of labels. Returns a list of
|
||||
{id: value, score: value} sorted by highest score, where id is the index in labels.
|
||||
|
||||
Args:
|
||||
text: text|list
|
||||
labels: list of labels
|
||||
|
||||
Returns:
|
||||
list of {id: value, score: value} per text element
|
||||
"""
|
||||
|
||||
if "labels" in self.pipelines:
|
||||
# Text is a string
|
||||
if isinstance(text, str):
|
||||
return [{"id": uid, "score": float(score)} for uid, score in self.pipelines["labels"](text, labels)]
|
||||
|
||||
# Text is a list
|
||||
return [[{"id": uid, "score": float(score)} for uid, score in result] for result in self.pipelines["labels"](text, labels)]
|
||||
|
||||
return None
|
||||
|
||||
def pipeline(self, name, args):
|
||||
"""
|
||||
Generic pipeline execution method.
|
||||
|
||||
Args:
|
||||
name: pipeline name
|
||||
args: pipeline arguments
|
||||
"""
|
||||
|
||||
if name in self.pipelines:
|
||||
return self.pipelines[name](*args)
|
||||
|
||||
return None
|
||||
|
||||
def workflow(self, name, elements):
|
||||
"""
|
||||
Executes a workflow.
|
||||
|
||||
Args:
|
||||
name: workflow name
|
||||
elements: elements to process
|
||||
|
||||
Returns:
|
||||
processed elements
|
||||
"""
|
||||
|
||||
# Convert lists to tuples
|
||||
elements = [tuple(element) if isinstance(element, list) else element for element in elements]
|
||||
|
||||
# Execute workflow
|
||||
return self.workflows[name](elements)
|
||||
@@ -0,0 +1,248 @@
|
||||
"""
|
||||
Cluster module
|
||||
"""
|
||||
|
||||
import asyncio
|
||||
import zlib
|
||||
|
||||
import aiohttp
|
||||
|
||||
|
||||
class Cluster:
|
||||
"""
|
||||
Aggregates multiple embeddings shards into a single logical embeddings instance.
|
||||
"""
|
||||
|
||||
# pylint: disable = W0231
|
||||
def __init__(self, config=None):
|
||||
"""
|
||||
Creates a new Cluster.
|
||||
|
||||
Args:
|
||||
config: cluster configuration
|
||||
"""
|
||||
|
||||
# Configuration
|
||||
self.config = config
|
||||
|
||||
# Embeddings shard urls
|
||||
self.shards = None
|
||||
if "shards" in self.config:
|
||||
self.shards = self.config["shards"]
|
||||
|
||||
def search(self, query, limit=None):
|
||||
"""
|
||||
Finds documents in the embeddings cluster most similar to the input query. Returns
|
||||
a list of {id: value, score: value} sorted by highest score, where id is the
|
||||
document id in the embeddings model.
|
||||
|
||||
Args:
|
||||
query: query text
|
||||
limit: maximum results
|
||||
|
||||
Returns:
|
||||
list of {id: value, score: value}
|
||||
"""
|
||||
|
||||
# Build URL
|
||||
action = "search?query=%s" % query
|
||||
if limit:
|
||||
action += "&limit=%d" % limit
|
||||
|
||||
# Run query and flatten results into single results list
|
||||
results = []
|
||||
for result in self.execute("get", action):
|
||||
results.extend(result)
|
||||
|
||||
# Sort and limit results
|
||||
return sorted(results, key=lambda x: x["score"], reverse=True)[: (limit if limit else 10)]
|
||||
|
||||
def batchsearch(self, queries, limit=None):
|
||||
"""
|
||||
Finds documents in the embeddings cluster most similar to the input queries. Returns
|
||||
a list of {id: value, score: value} sorted by highest score per query, where id is
|
||||
the document id in the embeddings model.
|
||||
|
||||
Args:
|
||||
queries: queries text
|
||||
limit: maximum results
|
||||
|
||||
Returns:
|
||||
list of {id: value, score: value} per query
|
||||
"""
|
||||
|
||||
# POST parameters
|
||||
params = {"queries": queries}
|
||||
if limit:
|
||||
params["limit"] = limit
|
||||
|
||||
# Run query
|
||||
batch = self.execute("post", "batchsearch", [params] * len(self.shards))
|
||||
|
||||
# Combine results per query
|
||||
results = []
|
||||
for x in range(len(queries)):
|
||||
result = []
|
||||
for section in batch:
|
||||
result.extend(section[x])
|
||||
|
||||
# Sort and limit results
|
||||
results.append(sorted(result, key=lambda x: x["score"], reverse=True)[: (limit if limit else 10)])
|
||||
|
||||
return results
|
||||
|
||||
def add(self, documents):
|
||||
"""
|
||||
Adds a batch of documents for indexing.
|
||||
|
||||
Args:
|
||||
documents: list of {id: value, text: value}
|
||||
"""
|
||||
|
||||
self.execute("post", "add", self.shard(documents))
|
||||
|
||||
def index(self):
|
||||
"""
|
||||
Builds an embeddings index for previously batched documents.
|
||||
"""
|
||||
|
||||
self.execute("get", "index")
|
||||
|
||||
def upsert(self):
|
||||
"""
|
||||
Runs an embeddings upsert operation for previously batched documents.
|
||||
"""
|
||||
|
||||
self.execute("get", "upsert")
|
||||
|
||||
def delete(self, ids):
|
||||
"""
|
||||
Deletes from an embeddings cluster. Returns list of ids deleted.
|
||||
|
||||
Args:
|
||||
ids: list of ids to delete
|
||||
|
||||
Returns:
|
||||
ids deleted
|
||||
"""
|
||||
|
||||
return [uid for ids in self.execute("post", "delete", self.shard(ids)) for uid in ids]
|
||||
|
||||
def count(self):
|
||||
"""
|
||||
Total number of elements in this embeddings cluster.
|
||||
|
||||
Returns:
|
||||
number of elements in embeddings cluster
|
||||
"""
|
||||
|
||||
return sum(self.execute("get", "count"))
|
||||
|
||||
def shard(self, documents):
|
||||
"""
|
||||
Splits documents into equal sized shards.
|
||||
|
||||
Args:
|
||||
documents: input documents
|
||||
|
||||
Returns:
|
||||
list of evenly sized shards with the last shard having the remaining elements
|
||||
"""
|
||||
|
||||
shards = [[] for _ in range(len(self.shards))]
|
||||
for document in documents:
|
||||
uid = document["id"] if isinstance(document, dict) else document
|
||||
if isinstance(uid, str):
|
||||
# Quick int hash of string to help derive shard id
|
||||
uid = zlib.adler32(uid.encode("utf-8"))
|
||||
|
||||
shards[uid % len(self.shards)].append(document)
|
||||
|
||||
return shards
|
||||
|
||||
def execute(self, method, action, data=None):
|
||||
"""
|
||||
Executes a HTTP action asynchronously.
|
||||
|
||||
Args:
|
||||
method: get or post
|
||||
action: url action to perform
|
||||
data: post parameters
|
||||
|
||||
Returns:
|
||||
json results if any
|
||||
"""
|
||||
|
||||
# Get urls
|
||||
urls = ["%s/%s" % (shard, action) for shard in self.shards]
|
||||
close = False
|
||||
|
||||
# Use existing loop if available, otherwise create one
|
||||
try:
|
||||
loop = asyncio.get_event_loop()
|
||||
except RuntimeError:
|
||||
loop = asyncio.new_event_loop()
|
||||
close = True
|
||||
|
||||
try:
|
||||
return loop.run_until_complete(self.run(urls, method, data))
|
||||
finally:
|
||||
# Close loop if it was created in this method
|
||||
if close:
|
||||
loop.close()
|
||||
|
||||
async def run(self, urls, method, data):
|
||||
"""
|
||||
Runs an async action.
|
||||
|
||||
Args:
|
||||
urls: run against this list of urls
|
||||
method: get or post
|
||||
data: list of data for each url or None
|
||||
|
||||
Returns:
|
||||
json results if any
|
||||
"""
|
||||
|
||||
async with aiohttp.ClientSession() as session:
|
||||
tasks = []
|
||||
|
||||
for x, url in enumerate(urls):
|
||||
if method == "post":
|
||||
if not data or data[x]:
|
||||
tasks.append(asyncio.ensure_future(self.post(session, url, data[x] if data else None)))
|
||||
else:
|
||||
tasks.append(asyncio.ensure_future(self.get(session, url)))
|
||||
|
||||
return await asyncio.gather(*tasks)
|
||||
|
||||
async def get(self, session, url):
|
||||
"""
|
||||
Runs an async HTTP GET request.
|
||||
|
||||
Args:
|
||||
session: ClientSession
|
||||
url: url
|
||||
|
||||
Returns:
|
||||
json results if any
|
||||
"""
|
||||
|
||||
async with session.get(url) as resp:
|
||||
return await resp.json()
|
||||
|
||||
async def post(self, session, url, data):
|
||||
"""
|
||||
Runs an async HTTP POST request.
|
||||
|
||||
Args:
|
||||
session: ClientSession
|
||||
url: url
|
||||
data: data to POST
|
||||
|
||||
Returns:
|
||||
json results if any
|
||||
"""
|
||||
|
||||
async with session.post(url, json=data) as resp:
|
||||
return await resp.json()
|
||||
@@ -0,0 +1,19 @@
|
||||
"""
|
||||
Extension module
|
||||
"""
|
||||
|
||||
|
||||
class Extension:
|
||||
"""
|
||||
Defines an API extension. API extensions can expose custom pipelines or other custom logic.
|
||||
"""
|
||||
|
||||
def __call__(self, app):
|
||||
"""
|
||||
Hook to register custom routing logic and/or modify the FastAPI instance.
|
||||
|
||||
Args:
|
||||
app: FastAPI application instance
|
||||
"""
|
||||
|
||||
return
|
||||
@@ -0,0 +1,44 @@
|
||||
"""
|
||||
API factory module
|
||||
"""
|
||||
|
||||
|
||||
class Factory:
|
||||
"""
|
||||
API factory. Creates new API instances.
|
||||
"""
|
||||
|
||||
@staticmethod
|
||||
def get(api):
|
||||
"""
|
||||
Gets a new instance of api class.
|
||||
|
||||
Args:
|
||||
api: API instance class
|
||||
|
||||
Returns:
|
||||
API
|
||||
"""
|
||||
|
||||
parts = api.split(".")
|
||||
module = ".".join(parts[:-1])
|
||||
m = __import__(module)
|
||||
for comp in parts[1:]:
|
||||
m = getattr(m, comp)
|
||||
|
||||
return m
|
||||
|
||||
@staticmethod
|
||||
def create(config, api):
|
||||
"""
|
||||
Creates a new API instance.
|
||||
|
||||
Args:
|
||||
config: API configuration
|
||||
api: API instance class
|
||||
|
||||
Returns:
|
||||
API instance
|
||||
"""
|
||||
|
||||
return Factory.get(api)(config)
|
||||
@@ -0,0 +1,13 @@
|
||||
"""
|
||||
Router imports
|
||||
"""
|
||||
|
||||
from . import embeddings
|
||||
from . import extractor
|
||||
from . import segmentation
|
||||
from . import similarity
|
||||
from . import summary
|
||||
from . import textractor
|
||||
from . import transcription
|
||||
from . import translation
|
||||
from . import workflow
|
||||
@@ -0,0 +1,137 @@
|
||||
"""
|
||||
Defines API paths for embeddings endpoints.
|
||||
"""
|
||||
|
||||
from typing import List
|
||||
|
||||
from fastapi import APIRouter, Body, Request
|
||||
|
||||
from .. import application
|
||||
|
||||
router = APIRouter()
|
||||
|
||||
|
||||
@router.get("/search")
|
||||
def search(query: str, request: Request):
|
||||
"""
|
||||
Finds documents in the embeddings model most similar to the input query. Returns
|
||||
a list of {id: value, score: value} sorted by highest score, where id is the
|
||||
document id in the embeddings model.
|
||||
|
||||
Args:
|
||||
query: query text
|
||||
request: FastAPI request
|
||||
|
||||
Returns:
|
||||
list of {id: value, score: value}
|
||||
"""
|
||||
|
||||
return application.get().search(query, request)
|
||||
|
||||
|
||||
@router.post("/batchsearch")
|
||||
def batchsearch(queries: List[str] = Body(...), limit: int = Body(...)):
|
||||
"""
|
||||
Finds documents in the embeddings model most similar to the input queries. Returns
|
||||
a list of {id: value, score: value} sorted by highest score per query, where id is
|
||||
the document id in the embeddings model.
|
||||
|
||||
Args:
|
||||
queries: queries text
|
||||
limit: maximum results
|
||||
|
||||
Returns:
|
||||
list of {id: value, score: value} per query
|
||||
"""
|
||||
|
||||
return application.get().batchsearch(queries, limit)
|
||||
|
||||
|
||||
@router.post("/add")
|
||||
def add(documents: List[dict] = Body(...)):
|
||||
"""
|
||||
Adds a batch of documents for indexing.
|
||||
|
||||
Args:
|
||||
documents: list of {id: value, text: value}
|
||||
"""
|
||||
|
||||
application.get().add(documents)
|
||||
|
||||
|
||||
@router.get("/index")
|
||||
def index():
|
||||
"""
|
||||
Builds an embeddings index for previously batched documents.
|
||||
"""
|
||||
|
||||
application.get().index()
|
||||
|
||||
|
||||
@router.get("/upsert")
|
||||
def upsert():
|
||||
"""
|
||||
Runs an embeddings upsert operation for previously batched documents.
|
||||
"""
|
||||
|
||||
application.get().upsert()
|
||||
|
||||
|
||||
@router.post("/delete")
|
||||
def delete(ids: List = Body(...)):
|
||||
"""
|
||||
Deletes from an embeddings index. Returns list of ids deleted.
|
||||
|
||||
Args:
|
||||
ids: list of ids to delete
|
||||
|
||||
Returns:
|
||||
ids deleted
|
||||
"""
|
||||
|
||||
return application.get().delete(ids)
|
||||
|
||||
|
||||
@router.get("/count")
|
||||
def count():
|
||||
"""
|
||||
Deletes from an embeddings index. Returns list of ids deleted.
|
||||
|
||||
Args:
|
||||
ids: list of ids to delete
|
||||
|
||||
Returns:
|
||||
ids deleted
|
||||
"""
|
||||
|
||||
return application.get().count()
|
||||
|
||||
|
||||
@router.get("/transform")
|
||||
def transform(text: str):
|
||||
"""
|
||||
Transforms text into an embeddings array.
|
||||
|
||||
Args:
|
||||
text: input text
|
||||
|
||||
Returns:
|
||||
embeddings array
|
||||
"""
|
||||
|
||||
return application.get().transform(text)
|
||||
|
||||
|
||||
@router.post("/batchtransform")
|
||||
def batchtransform(texts: List[str] = Body(...)):
|
||||
"""
|
||||
Transforms list of text into embeddings arrays.
|
||||
|
||||
Args:
|
||||
texts: list of text
|
||||
|
||||
Returns:
|
||||
embeddings arrays
|
||||
"""
|
||||
|
||||
return application.get().batchtransform(texts)
|
||||
@@ -0,0 +1,27 @@
|
||||
"""
|
||||
Defines API paths for extractor endpoints.
|
||||
"""
|
||||
|
||||
from typing import List
|
||||
|
||||
from fastapi import APIRouter, Body
|
||||
|
||||
from .. import application
|
||||
|
||||
router = APIRouter()
|
||||
|
||||
|
||||
@router.post("/extract")
|
||||
def extract(queue: List[dict] = Body(...), texts: List[str] = Body(...)):
|
||||
"""
|
||||
Extracts answers to input questions.
|
||||
|
||||
Args:
|
||||
queue: list of {name: value, query: value, question: value, snippet: value}
|
||||
texts: list of text
|
||||
|
||||
Returns:
|
||||
list of {name: value, answer: value}
|
||||
"""
|
||||
|
||||
return application.get().extract(queue, texts)
|
||||
@@ -0,0 +1,46 @@
|
||||
"""
|
||||
Defines API paths for labels endpoints.
|
||||
"""
|
||||
|
||||
from typing import List
|
||||
|
||||
from fastapi import APIRouter, Body
|
||||
|
||||
from .. import application
|
||||
|
||||
router = APIRouter()
|
||||
|
||||
|
||||
@router.post("/label")
|
||||
def label(text: str = Body(...), labels: List[str] = Body(...)):
|
||||
"""
|
||||
Applies a zero shot classifier to text using a list of labels. Returns a list of
|
||||
{id: value, score: value} sorted by highest score, where id is the index in labels.
|
||||
|
||||
Args:
|
||||
text: input text
|
||||
labels: list of labels
|
||||
|
||||
Returns:
|
||||
list of {id: value, score: value} per text element
|
||||
"""
|
||||
|
||||
return application.get().label(text, labels)
|
||||
|
||||
|
||||
@router.post("/batchlabel")
|
||||
def batchlabel(texts: List[str] = Body(...), labels: List[str] = Body(...)):
|
||||
"""
|
||||
Applies a zero shot classifier to list of text using a list of labels. Returns a list of
|
||||
{id: value, score: value} sorted by highest score, where id is the index in labels per
|
||||
text element.
|
||||
|
||||
Args:
|
||||
texts: list of text
|
||||
labels: list of labels
|
||||
|
||||
Returns:
|
||||
list of {id: value score: value} per text element
|
||||
"""
|
||||
|
||||
return application.get().label(texts, labels)
|
||||
@@ -0,0 +1,41 @@
|
||||
"""
|
||||
Defines API paths for segmentation endpoints.
|
||||
"""
|
||||
|
||||
from typing import List
|
||||
|
||||
from fastapi import APIRouter, Body
|
||||
|
||||
from .. import application
|
||||
|
||||
router = APIRouter()
|
||||
|
||||
|
||||
@router.get("/segment")
|
||||
def segment(text: str):
|
||||
"""
|
||||
Segments text into semantic units.
|
||||
|
||||
Args:
|
||||
text: input text
|
||||
|
||||
Returns:
|
||||
segmented text
|
||||
"""
|
||||
|
||||
return application.get().pipeline("segmentation", (text,))
|
||||
|
||||
|
||||
@router.post("/batchsegment")
|
||||
def batchsegment(texts: List[str] = Body(...)):
|
||||
"""
|
||||
Segments text into semantic units.
|
||||
|
||||
Args:
|
||||
texts: list of texts to segment
|
||||
|
||||
Returns:
|
||||
list of segmented text
|
||||
"""
|
||||
|
||||
return application.get().pipeline("segmentation", (texts,))
|
||||
@@ -0,0 +1,47 @@
|
||||
"""
|
||||
Defines API paths for similarity endpoints.
|
||||
"""
|
||||
|
||||
from typing import List
|
||||
|
||||
from fastapi import APIRouter, Body
|
||||
|
||||
from .. import application
|
||||
|
||||
router = APIRouter()
|
||||
|
||||
|
||||
@router.post("/similarity")
|
||||
def similarity(query: str = Body(...), texts: List[str] = Body(...)):
|
||||
"""
|
||||
Computes the similarity between query and list of text. Returns a list of
|
||||
{id: value, score: value} sorted by highest score, where id is the index
|
||||
in texts.
|
||||
|
||||
Args:
|
||||
query: query text
|
||||
texts: list of text
|
||||
|
||||
Returns:
|
||||
list of {id: value, score: value}
|
||||
"""
|
||||
|
||||
return application.get().similarity(query, texts)
|
||||
|
||||
|
||||
@router.post("/batchsimilarity")
|
||||
def batchsimilarity(queries: List[str] = Body(...), texts: List[str] = Body(...)):
|
||||
"""
|
||||
Computes the similarity between list of queries and list of text. Returns a list
|
||||
of {id: value, score: value} sorted by highest score per query, where id is the
|
||||
index in texts.
|
||||
|
||||
Args:
|
||||
queries: queries text
|
||||
texts: list of text
|
||||
|
||||
Returns:
|
||||
list of {id: value, score: value} per query
|
||||
"""
|
||||
|
||||
return application.get().batchsimilarity(queries, texts)
|
||||
@@ -0,0 +1,45 @@
|
||||
"""
|
||||
Defines API paths for summary endpoints.
|
||||
"""
|
||||
|
||||
from typing import List, Optional
|
||||
|
||||
from fastapi import APIRouter, Body
|
||||
|
||||
from .. import application
|
||||
|
||||
router = APIRouter()
|
||||
|
||||
|
||||
@router.get("/summary")
|
||||
def summary(text: str, minlength: Optional[int] = None, maxlength: Optional[int] = None):
|
||||
"""
|
||||
Runs a summarization model against a block of text.
|
||||
|
||||
Args:
|
||||
text: text to summarize
|
||||
minlength: minimum length for summary
|
||||
maxlength: maximum length for summary
|
||||
|
||||
Returns:
|
||||
summary text
|
||||
"""
|
||||
|
||||
return application.get().pipeline("summary", (text, minlength, maxlength))
|
||||
|
||||
|
||||
@router.post("/batchsummary")
|
||||
def batchsummary(texts: List[str] = Body(...), minlength: Optional[int] = Body(default=None), maxlength: Optional[int] = Body(default=None)):
|
||||
"""
|
||||
Runs a summarization model against a block of text.
|
||||
|
||||
Args:
|
||||
texts: list of text to summarize
|
||||
minlength: minimum length for summary
|
||||
maxlength: maximum length for summary
|
||||
|
||||
Returns:
|
||||
list of summary text
|
||||
"""
|
||||
|
||||
return application.get().pipeline("summary", (texts, minlength, maxlength))
|
||||
@@ -0,0 +1,41 @@
|
||||
"""
|
||||
Defines API paths for textractor endpoints.
|
||||
"""
|
||||
|
||||
from typing import List
|
||||
|
||||
from fastapi import APIRouter, Body
|
||||
|
||||
from .. import application
|
||||
|
||||
router = APIRouter()
|
||||
|
||||
|
||||
@router.get("/textract")
|
||||
def textract(file: str):
|
||||
"""
|
||||
Extracts text from a file at path.
|
||||
|
||||
Args:
|
||||
file: file to extract text
|
||||
|
||||
Returns:
|
||||
extracted text
|
||||
"""
|
||||
|
||||
return application.get().pipeline("textractor", (file,))
|
||||
|
||||
|
||||
@router.post("/batchtextract")
|
||||
def batchtextract(files: List[str] = Body(...)):
|
||||
"""
|
||||
Extracts text from a file at path.
|
||||
|
||||
Args:
|
||||
files: list of files to extract text
|
||||
|
||||
Returns:
|
||||
list of extracted text
|
||||
"""
|
||||
|
||||
return application.get().pipeline("textractor", (files,))
|
||||
@@ -0,0 +1,41 @@
|
||||
"""
|
||||
Defines API paths for transcription endpoints.
|
||||
"""
|
||||
|
||||
from typing import List
|
||||
|
||||
from fastapi import APIRouter, Body
|
||||
|
||||
from .. import application
|
||||
|
||||
router = APIRouter()
|
||||
|
||||
|
||||
@router.get("/transcribe")
|
||||
def transcribe(file: str):
|
||||
"""
|
||||
Transcribes audio files to text.
|
||||
|
||||
Args:
|
||||
file: file to transcribe
|
||||
|
||||
Returns:
|
||||
transcribed text
|
||||
"""
|
||||
|
||||
return application.get().pipeline("transcription", (file,))
|
||||
|
||||
|
||||
@router.post("/batchtranscribe")
|
||||
def batchtranscribe(files: List[str] = Body(...)):
|
||||
"""
|
||||
Transcribes audio files to text.
|
||||
|
||||
Args:
|
||||
files: list of files to transcribe
|
||||
|
||||
Returns:
|
||||
list of transcribed text
|
||||
"""
|
||||
|
||||
return application.get().pipeline("transcription", (files,))
|
||||
@@ -0,0 +1,45 @@
|
||||
"""
|
||||
Defines API paths for translation endpoints.
|
||||
"""
|
||||
|
||||
from typing import List, Optional
|
||||
|
||||
from fastapi import APIRouter, Body
|
||||
|
||||
from .. import application
|
||||
|
||||
router = APIRouter()
|
||||
|
||||
|
||||
@router.get("/translate")
|
||||
def translate(text: str, target: Optional[str] = "en", source: Optional[int] = None):
|
||||
"""
|
||||
Translates text from source language into target language.
|
||||
|
||||
Args:
|
||||
text: text to translate
|
||||
target: target language code, defaults to "en"
|
||||
source: source language code, detects language if not provided
|
||||
|
||||
Returns:
|
||||
translated text
|
||||
"""
|
||||
|
||||
return application.get().pipeline("translation", (text, target, source))
|
||||
|
||||
|
||||
@router.post("/batchtranslate")
|
||||
def batchtranslate(texts: List[str] = Body(...), target: Optional[str] = Body(default="en"), source: Optional[str] = Body(default=None)):
|
||||
"""
|
||||
Translates text from source language into target language.
|
||||
|
||||
Args:
|
||||
texts: list of text to translate
|
||||
target: target language code, defaults to "en"
|
||||
source: source language code, detects language if not provided
|
||||
|
||||
Returns:
|
||||
list of translated text
|
||||
"""
|
||||
|
||||
return application.get().pipeline("translation", (texts, target, source))
|
||||
@@ -0,0 +1,27 @@
|
||||
"""
|
||||
Defines API paths for workflow endpoints.
|
||||
"""
|
||||
|
||||
from typing import List
|
||||
|
||||
from fastapi import APIRouter, Body
|
||||
|
||||
from .. import application
|
||||
|
||||
router = APIRouter()
|
||||
|
||||
|
||||
@router.post("/workflow")
|
||||
def workflow(name: str = Body(...), elements: List = Body(...)):
|
||||
"""
|
||||
Executes a named workflow using elements as input.
|
||||
|
||||
Args:
|
||||
name: workflow name
|
||||
elements: list of elements to run through workflow
|
||||
|
||||
Returns:
|
||||
list of processed elements
|
||||
"""
|
||||
|
||||
return application.get().workflow(name, elements)
|
||||
@@ -0,0 +1,8 @@
|
||||
"""
|
||||
Data imports
|
||||
"""
|
||||
|
||||
from .base import Data
|
||||
from .labels import Labels
|
||||
from .questions import Questions
|
||||
from .tokens import Tokens
|
||||
@@ -0,0 +1,111 @@
|
||||
"""
|
||||
Data module
|
||||
"""
|
||||
|
||||
from .tokens import Tokens
|
||||
|
||||
|
||||
class Data:
|
||||
"""
|
||||
Base data tokenization class.
|
||||
"""
|
||||
|
||||
def __init__(self, tokenizer, columns, maxlength):
|
||||
"""
|
||||
Creates new base instance for tokenizing data.
|
||||
|
||||
Args:
|
||||
tokenizer: model tokenizer
|
||||
columns: column names
|
||||
maxlength: maximum sequence length
|
||||
"""
|
||||
|
||||
self.tokenizer = tokenizer
|
||||
self.columns = columns
|
||||
self.maxlength = maxlength
|
||||
|
||||
def __call__(self, train, validation):
|
||||
"""
|
||||
Tokenizes training and validation data and returns processed datasets.
|
||||
|
||||
Args:
|
||||
train: training data
|
||||
validation: validation data
|
||||
|
||||
Returns:
|
||||
(train, validation)
|
||||
"""
|
||||
|
||||
return (self.prepare(train, self.process), self.prepare(validation, self.process) if validation else None)
|
||||
|
||||
def prepare(self, data, fn):
|
||||
"""
|
||||
Prepares and tokenizes data for training.
|
||||
|
||||
Args:
|
||||
data: input data
|
||||
fn: tokenize processing function to apply
|
||||
|
||||
Returns:
|
||||
tokens
|
||||
"""
|
||||
|
||||
if hasattr(data, "map"):
|
||||
# Hugging Face dataset
|
||||
tokens = data.map(fn, batched=True, remove_columns=data.column_names)
|
||||
else:
|
||||
# pandas DataFrame
|
||||
if hasattr(data, "to_dict"):
|
||||
data = data.to_dict("records")
|
||||
|
||||
# Re-orient data into columns for efficient batch tokenization
|
||||
columns = {}
|
||||
for row in data:
|
||||
for column in row.keys():
|
||||
if column not in columns:
|
||||
columns[column] = []
|
||||
|
||||
columns[column].append(row[column])
|
||||
|
||||
# Process column-oriented data
|
||||
tokens = Tokens(fn(columns))
|
||||
|
||||
return tokens
|
||||
|
||||
def labels(self, data):
|
||||
"""
|
||||
Extracts a list of unique labels from data.
|
||||
|
||||
Args:
|
||||
data: input data
|
||||
|
||||
Returns:
|
||||
list of unique labels
|
||||
"""
|
||||
|
||||
if hasattr(data, "map"):
|
||||
# Hugging Face dataset
|
||||
labels = sorted(data.unique(self.columns[-1]))
|
||||
else:
|
||||
# pandas DataFrame
|
||||
if hasattr(data, "to_dict"):
|
||||
data = data.to_dict("records")
|
||||
|
||||
# Process list of dicts
|
||||
labels = sorted({row[self.columns[-1]] for row in data})
|
||||
|
||||
# Determine number of labels, account for regression tasks
|
||||
return 1 if [x for x in labels if isinstance(x, float)] else len(labels)
|
||||
|
||||
def process(self, data):
|
||||
"""
|
||||
Tokenizes batch of input data
|
||||
|
||||
Args:
|
||||
data: input data batch
|
||||
|
||||
Returns:
|
||||
tokenized data
|
||||
"""
|
||||
|
||||
return data
|
||||
@@ -0,0 +1,42 @@
|
||||
"""
|
||||
Labels module
|
||||
"""
|
||||
|
||||
from .base import Data
|
||||
|
||||
|
||||
class Labels(Data):
|
||||
"""
|
||||
Tokenizes text-classification datasets used as input for training text-classification models.
|
||||
"""
|
||||
|
||||
def __init__(self, tokenizer, columns, maxlength):
|
||||
"""
|
||||
Creates a new instance for tokenizing Labels training data.
|
||||
|
||||
Args:
|
||||
tokenizer: model tokenizer
|
||||
columns: tuple of columns to use for text/label
|
||||
maxlength: maximum sequence length
|
||||
"""
|
||||
|
||||
super().__init__(tokenizer, columns, maxlength)
|
||||
|
||||
# Standardize columns
|
||||
if not self.columns:
|
||||
self.columns = ("text", None, "label")
|
||||
elif len(columns) < 3:
|
||||
self.columns = (self.columns[0], None, self.columns[-1])
|
||||
|
||||
def process(self, data):
|
||||
# Column keys
|
||||
text1, text2, label = self.columns
|
||||
|
||||
# Tokenizer inputs can be single string or string pair, depending on task
|
||||
text = (data[text1], data[text2]) if text2 else (data[text1],)
|
||||
|
||||
# Tokenize text and add label
|
||||
inputs = self.tokenizer(*text, max_length=self.maxlength, padding=True, truncation=True)
|
||||
inputs[label] = data[label]
|
||||
|
||||
return inputs
|
||||
@@ -0,0 +1,140 @@
|
||||
"""
|
||||
Questions module
|
||||
"""
|
||||
|
||||
from .base import Data
|
||||
|
||||
|
||||
class Questions(Data):
|
||||
"""
|
||||
Tokenizes question-answering datasets used as input for training question-answering models.
|
||||
"""
|
||||
|
||||
def __init__(self, tokenizer, columns, maxlength, stride):
|
||||
"""
|
||||
Creates a new instance for tokenizing Questions training data.
|
||||
|
||||
Args:
|
||||
tokenizer: model tokenizer
|
||||
columns: tuple of columns to use for question/context/answer
|
||||
maxlength: maximum sequence length
|
||||
stride: chunk size for splitting data for QA tasks
|
||||
"""
|
||||
|
||||
super().__init__(tokenizer, columns, maxlength)
|
||||
|
||||
if not self.columns:
|
||||
self.columns = ("question", "context", "answers")
|
||||
|
||||
self.question, self.context, self.answer = self.columns
|
||||
self.stride = stride
|
||||
self.rpad = tokenizer.padding_side == "right"
|
||||
|
||||
def process(self, data):
|
||||
# Tokenize data
|
||||
tokenized = self.tokenize(data)
|
||||
|
||||
# Get mapping of overflowing tokens and answer offsets
|
||||
samples = tokenized.pop("overflow_to_sample_mapping")
|
||||
offsets = tokenized.pop("offset_mapping")
|
||||
|
||||
# Start/end positions
|
||||
tokenized["start_positions"] = []
|
||||
tokenized["end_positions"] = []
|
||||
|
||||
for x, offset in enumerate(offsets):
|
||||
# Label NO ANSWER with CLS token
|
||||
inputids = tokenized["input_ids"][x]
|
||||
clstoken = inputids.index(self.tokenizer.cls_token_id)
|
||||
|
||||
# Sequence ids
|
||||
sequences = tokenized.sequence_ids(x)
|
||||
|
||||
# Get and format answer
|
||||
answers = self.answers(data, samples[x])
|
||||
|
||||
# If no answers are given, set cls token as answer.
|
||||
if len(answers["answer_start"]) == 0:
|
||||
tokenized["start_positions"].append(clstoken)
|
||||
tokenized["end_positions"].append(clstoken)
|
||||
else:
|
||||
# Start/end character index of the answer in the text.
|
||||
startchar = answers["answer_start"][0]
|
||||
endchar = startchar + len(answers["text"][0])
|
||||
|
||||
# Start token index of the current span in the text.
|
||||
start = 0
|
||||
while sequences[start] != (1 if self.rpad else 0):
|
||||
start += 1
|
||||
|
||||
# End token index of the current span in the text.
|
||||
end = len(inputids) - 1
|
||||
while sequences[end] != (1 if self.rpad else 0):
|
||||
end -= 1
|
||||
|
||||
# Label with CLS token if out of span
|
||||
if not (offset[start][0] <= startchar and offset[end][1] >= endchar):
|
||||
tokenized["start_positions"].append(clstoken)
|
||||
tokenized["end_positions"].append(clstoken)
|
||||
else:
|
||||
# Map start character and end character to matching token index
|
||||
while start < len(offset) and offset[start][0] <= startchar:
|
||||
start += 1
|
||||
tokenized["start_positions"].append(start - 1)
|
||||
|
||||
while offset[end][1] >= endchar:
|
||||
end -= 1
|
||||
tokenized["end_positions"].append(end + 1)
|
||||
|
||||
return tokenized
|
||||
|
||||
def tokenize(self, data):
|
||||
"""
|
||||
Tokenizes batch of data
|
||||
|
||||
Args:
|
||||
data: input data batch
|
||||
|
||||
Returns:
|
||||
tokenized data
|
||||
"""
|
||||
|
||||
# Trim question whitespace
|
||||
data[self.question] = [x.lstrip() for x in data[self.question]]
|
||||
|
||||
# Tokenize records
|
||||
return self.tokenizer(
|
||||
data[self.question if self.rpad else self.context],
|
||||
data[self.context if self.rpad else self.question],
|
||||
truncation="only_second" if self.rpad else "only_first",
|
||||
max_length=self.maxlength,
|
||||
stride=self.stride,
|
||||
return_overflowing_tokens=True,
|
||||
return_offsets_mapping=True,
|
||||
padding=True,
|
||||
)
|
||||
|
||||
def answers(self, data, index):
|
||||
"""
|
||||
Gets and formats an answer.
|
||||
|
||||
Args:
|
||||
data: input examples
|
||||
index: answer index to retrieve
|
||||
|
||||
Returns:
|
||||
answers dict
|
||||
"""
|
||||
|
||||
# Answer mappings
|
||||
answers = data[self.answer][index]
|
||||
context = data[self.context][index]
|
||||
|
||||
# Handle mapping string answers to dict
|
||||
if not isinstance(answers, dict):
|
||||
if not answers:
|
||||
answers = {"text": [], "answer_start": []}
|
||||
else:
|
||||
answers = {"text": [answers], "answer_start": [context.index(answers)]}
|
||||
|
||||
return answers
|
||||
@@ -0,0 +1,28 @@
|
||||
"""
|
||||
Tokens module
|
||||
"""
|
||||
|
||||
import torch
|
||||
|
||||
|
||||
class Tokens(torch.utils.data.Dataset):
|
||||
"""
|
||||
Default dataset used to hold tokenized data.
|
||||
"""
|
||||
|
||||
def __init__(self, columns):
|
||||
self.data = []
|
||||
|
||||
# Map column-oriented data to rows
|
||||
for column in columns:
|
||||
for x, value in enumerate(columns[column]):
|
||||
if len(self.data) <= x:
|
||||
self.data.append({})
|
||||
|
||||
self.data[x][column] = value
|
||||
|
||||
def __len__(self):
|
||||
return len(self.data)
|
||||
|
||||
def __getitem__(self, index):
|
||||
return self.data[index]
|
||||
@@ -1,306 +0,0 @@
|
||||
"""
|
||||
Embeddings module
|
||||
"""
|
||||
|
||||
import pickle
|
||||
import os
|
||||
import shutil
|
||||
|
||||
import numpy as np
|
||||
|
||||
from sklearn.decomposition import TruncatedSVD
|
||||
|
||||
from .ann import ANN
|
||||
from .scoring import Scoring
|
||||
from .vectors import Vectors
|
||||
|
||||
class Embeddings(object):
|
||||
"""
|
||||
Model that builds sentence embeddings from a list of tokens.
|
||||
|
||||
Optional scoring method can be created to weigh tokens when creating embeddings. Averaging used if no scoring method provided.
|
||||
|
||||
The model also applies principal component analysis using a LSA model. This reduces the noise of common but less
|
||||
relevant terms.
|
||||
"""
|
||||
|
||||
# pylint: disable = W0231
|
||||
def __init__(self, config=None):
|
||||
"""
|
||||
Creates a new Embeddings model.
|
||||
|
||||
Args:
|
||||
config: embeddings configuration
|
||||
"""
|
||||
|
||||
# Configuration
|
||||
self.config = config
|
||||
|
||||
# Embeddings model
|
||||
self.embeddings = None
|
||||
|
||||
# Dimensionality reduction model
|
||||
self.lsa = None
|
||||
|
||||
# Embedding scoring method - weighs each word in a sentence
|
||||
self.scoring = Scoring.create(self.config["scoring"]) if self.config and self.config.get("scoring") else None
|
||||
|
||||
# Sentence vectors model
|
||||
self.model = self.loadVectors() if self.config else None
|
||||
|
||||
def loadVectors(self):
|
||||
"""
|
||||
Loads a word vector model set in config.
|
||||
|
||||
Returns:
|
||||
vector model
|
||||
"""
|
||||
|
||||
return Vectors.create(self.config.get("method"), self.config["path"], True if not self.embeddings else False, self.scoring)
|
||||
|
||||
def score(self, documents):
|
||||
"""
|
||||
Builds a scoring index. Documents are tuples of (id, text|tokens, tags).
|
||||
|
||||
Args:
|
||||
documents: list of documents
|
||||
"""
|
||||
|
||||
if self.scoring:
|
||||
# Build scoring index over documents
|
||||
self.scoring.index(documents)
|
||||
|
||||
def index(self, documents):
|
||||
"""
|
||||
Builds an embeddings index. Documents are tuples of (id, text|tokens, tags).
|
||||
|
||||
Args:
|
||||
documents: list of documents
|
||||
"""
|
||||
|
||||
# Transform documents to embeddings vectors
|
||||
ids, dimensions, stream = self.model.index(documents)
|
||||
|
||||
# Load streamed embeddings back to memory
|
||||
embeddings = np.empty((len(ids), dimensions), dtype=np.float32)
|
||||
with open(stream, "rb") as queue:
|
||||
for x in range(embeddings.shape[0]):
|
||||
embeddings[x] = pickle.load(queue)
|
||||
|
||||
# Remove temporary file
|
||||
os.remove(stream)
|
||||
|
||||
# Build LSA model (if enabled). Remove principal components from embeddings.
|
||||
if self.config.get("pca"):
|
||||
self.lsa = self.buildLSA(embeddings, self.config["pca"])
|
||||
self.removePC(embeddings)
|
||||
|
||||
# Normalize embeddings
|
||||
self.normalize(embeddings)
|
||||
|
||||
# Save embeddings metadata
|
||||
self.config["ids"] = ids
|
||||
self.config["dimensions"] = dimensions
|
||||
|
||||
# Create embeddings index
|
||||
self.embeddings = ANN.create(self.config)
|
||||
|
||||
# Build the index
|
||||
self.embeddings.index(embeddings)
|
||||
|
||||
def buildLSA(self, embeddings, components):
|
||||
"""
|
||||
Builds a LSA model. This model is used to remove the principal component within embeddings. This helps to
|
||||
smooth out noisy embeddings (common words with less value).
|
||||
|
||||
Args:
|
||||
embeddings: input embeddings matrix
|
||||
components: number of model components
|
||||
|
||||
Returns:
|
||||
LSA model
|
||||
"""
|
||||
|
||||
svd = TruncatedSVD(n_components=components, random_state=0)
|
||||
svd.fit(embeddings)
|
||||
|
||||
return svd
|
||||
|
||||
def removePC(self, embeddings):
|
||||
"""
|
||||
Applies a LSA model to embeddings, removed the top n principal components. Operation applied
|
||||
directly on array.
|
||||
|
||||
Args:
|
||||
embeddings: input embeddings matrix
|
||||
"""
|
||||
|
||||
pc = self.lsa.components_
|
||||
factor = embeddings.dot(pc.transpose())
|
||||
|
||||
# Apply LSA model
|
||||
# Calculation is different if n_components = 1
|
||||
if pc.shape[0] == 1:
|
||||
embeddings -= factor * pc
|
||||
elif len(embeddings.shape) > 1:
|
||||
# Apply model on a row-wise basis to limit memory usage
|
||||
for x in range(embeddings.shape[0]):
|
||||
embeddings[x] -= factor[x].dot(pc)
|
||||
else:
|
||||
# Single embedding
|
||||
embeddings -= factor.dot(pc)
|
||||
|
||||
def normalize(self, embeddings):
|
||||
"""
|
||||
Normalizes embeddings using L2 normalization. Operation applied directly on array.
|
||||
|
||||
Args:
|
||||
embeddings: input embeddings matrix
|
||||
"""
|
||||
|
||||
# Calculation is different for matrices vs vectors
|
||||
if len(embeddings.shape) > 1:
|
||||
embeddings /= np.linalg.norm(embeddings, axis=1)[:, np.newaxis]
|
||||
else:
|
||||
embeddings /= np.linalg.norm(embeddings)
|
||||
|
||||
def transform(self, document):
|
||||
"""
|
||||
Transforms document into an embeddings vector. Document text will be tokenized if not pre-tokenized.
|
||||
|
||||
Args:
|
||||
document: (id, text|tokens, tags)
|
||||
|
||||
Returns:
|
||||
embeddings vector
|
||||
"""
|
||||
|
||||
# Convert document into sentence embedding
|
||||
embedding = self.model.transform(document)
|
||||
|
||||
# Reduce the dimensionality of the embeddings. Scale the embeddings using this
|
||||
# model to reduce the noise of common but less relevant terms.
|
||||
if self.lsa:
|
||||
self.removePC(embedding)
|
||||
|
||||
# Normalize embeddings
|
||||
self.normalize(embedding)
|
||||
|
||||
return embedding
|
||||
|
||||
def search(self, query, limit=3):
|
||||
"""
|
||||
Finds documents in the vector model most similar to the input document.
|
||||
|
||||
Args:
|
||||
query: query text|tokens
|
||||
limit: maximum results
|
||||
|
||||
Returns:
|
||||
list of topn matched (id, score)
|
||||
"""
|
||||
|
||||
# Convert tokens to embedding vector
|
||||
embedding = self.transform((None, query, None))
|
||||
|
||||
# Search embeddings index
|
||||
results = self.embeddings.search(embedding, limit)
|
||||
|
||||
# Map ids if id mapping available
|
||||
lookup = self.config.get("ids")
|
||||
if lookup:
|
||||
return [(lookup[i], score) for i, score in results]
|
||||
|
||||
return results
|
||||
|
||||
def similarity(self, query, documents):
|
||||
"""
|
||||
Computes the similarity between a query and a set of documents
|
||||
|
||||
Args:
|
||||
query: query text|tokens
|
||||
documents: document text|tokens
|
||||
|
||||
Returns:
|
||||
[computed similarity (0 - 1 with 1 being most similar)]
|
||||
"""
|
||||
|
||||
query = self.transform((None, query, None)).reshape(1, -1)
|
||||
documents = np.array([self.transform((None, text, None)) for text in documents])
|
||||
|
||||
# Dot product on normalized vectors is equal to cosine similarity
|
||||
return np.dot(query, documents.T)[0]
|
||||
|
||||
def load(self, path):
|
||||
"""
|
||||
Loads a pre-trained model.
|
||||
|
||||
Models have the following files:
|
||||
config - configuration
|
||||
embeddings - sentence embeddings index
|
||||
lsa - LSA model, used to remove the principal component(s)
|
||||
scoring - scoring model used to weigh word vectors
|
||||
vectors - word vectors model
|
||||
|
||||
Args:
|
||||
path: input directory path
|
||||
"""
|
||||
|
||||
# Index configuration
|
||||
with open("%s/config" % path, "rb") as handle:
|
||||
self.config = pickle.load(handle)
|
||||
|
||||
# Build full path to embedded vectors file
|
||||
if self.config.get("storevectors"):
|
||||
self.config["path"] = os.path.join(path, self.config["path"])
|
||||
|
||||
# Sentence embeddings index
|
||||
self.embeddings = ANN.create(self.config)
|
||||
self.embeddings.load("%s/embeddings" % path)
|
||||
|
||||
# Dimensionality reduction
|
||||
if self.config.get("pca"):
|
||||
with open("%s/lsa" % path, "rb") as handle:
|
||||
self.lsa = pickle.load(handle)
|
||||
|
||||
# Embedding scoring
|
||||
if self.config.get("scoring"):
|
||||
self.scoring = Scoring.create(self.config["scoring"])
|
||||
self.scoring.load(path)
|
||||
|
||||
# Sentence vectors model - transforms text into sentence embeddings
|
||||
self.model = self.loadVectors()
|
||||
|
||||
def save(self, path):
|
||||
"""
|
||||
Saves a model.
|
||||
|
||||
Args:
|
||||
path: output directory path
|
||||
"""
|
||||
|
||||
if self.config:
|
||||
# Create output directory, if necessary
|
||||
os.makedirs(path, exist_ok=True)
|
||||
|
||||
# Copy vectors file
|
||||
if self.config.get("storevectors"):
|
||||
shutil.copyfile(self.config["path"], os.path.join(path, os.path.basename(self.config["path"])))
|
||||
|
||||
self.config["path"] = os.path.basename(self.config["path"])
|
||||
|
||||
# Write index configuration
|
||||
with open("%s/config" % path, "wb") as handle:
|
||||
pickle.dump(self.config, handle, protocol=pickle.HIGHEST_PROTOCOL)
|
||||
|
||||
# Write sentence embeddings index
|
||||
self.embeddings.save("%s/embeddings" % path)
|
||||
|
||||
# Save dimensionality reduction
|
||||
if self.lsa:
|
||||
with open("%s/lsa" % path, "wb") as handle:
|
||||
pickle.dump(self.lsa, handle, protocol=pickle.HIGHEST_PROTOCOL)
|
||||
|
||||
# Save embedding scoring
|
||||
if self.scoring:
|
||||
self.scoring.save(path)
|
||||
@@ -0,0 +1,7 @@
|
||||
"""
|
||||
Embeddings imports
|
||||
"""
|
||||
|
||||
from .base import Embeddings
|
||||
from .documents import Documents
|
||||
from .reducer import Reducer
|
||||
@@ -0,0 +1,424 @@
|
||||
"""
|
||||
Embeddings module
|
||||
"""
|
||||
|
||||
import pickle
|
||||
import os
|
||||
import shutil
|
||||
|
||||
import numpy as np
|
||||
|
||||
from ..ann import ANNFactory
|
||||
from ..scoring import ScoringFactory
|
||||
from ..vectors import VectorsFactory
|
||||
|
||||
from .reducer import Reducer
|
||||
|
||||
|
||||
class Embeddings:
|
||||
"""
|
||||
Model that builds sentence embeddings from a list of tokens.
|
||||
|
||||
Optional scoring method can be created to weigh tokens when creating embeddings. Averaging used if no scoring method provided.
|
||||
|
||||
The model also applies principal component analysis using a LSA model. This reduces the noise of common but less
|
||||
relevant terms.
|
||||
"""
|
||||
|
||||
# pylint: disable = W0231
|
||||
def __init__(self, config=None):
|
||||
"""
|
||||
Creates a new Embeddings model.
|
||||
|
||||
Args:
|
||||
config: embeddings configuration
|
||||
"""
|
||||
|
||||
# Configuration
|
||||
self.config = config
|
||||
|
||||
# Embeddings model
|
||||
self.embeddings = None
|
||||
|
||||
if self.config and self.config.get("method") != "transformers":
|
||||
# Dimensionality reduction model
|
||||
self.reducer = None
|
||||
|
||||
# Embedding scoring method - weighs each word in a sentence
|
||||
self.scoring = ScoringFactory.create(self.config["scoring"]) if self.config and self.config.get("scoring") else None
|
||||
else:
|
||||
self.reducer, self.scoring = None, None
|
||||
|
||||
# Sentence vectors model
|
||||
self.model = self.loadVectors() if self.config else None
|
||||
|
||||
def score(self, documents):
|
||||
"""
|
||||
Builds a scoring index.
|
||||
|
||||
Args:
|
||||
documents: list of (id, text|tokens, tags)
|
||||
"""
|
||||
|
||||
if self.scoring:
|
||||
# Build scoring index over documents
|
||||
self.scoring.index(documents)
|
||||
|
||||
def index(self, documents):
|
||||
"""
|
||||
Builds an embeddings index. This method overwrites an existing index.
|
||||
|
||||
Args:
|
||||
documents: list of (id, text|tokens, tags)
|
||||
"""
|
||||
|
||||
# Transform documents to embeddings vectors
|
||||
ids, dimensions, embeddings = self.vectors(documents)
|
||||
|
||||
# Build LSA model (if enabled). Remove principal components from embeddings.
|
||||
if self.config.get("pca"):
|
||||
self.reducer = Reducer(embeddings, self.config["pca"])
|
||||
self.reducer(embeddings)
|
||||
|
||||
# Normalize embeddings
|
||||
self.normalize(embeddings)
|
||||
|
||||
# Save embeddings metadata
|
||||
self.config["ids"] = ids
|
||||
self.config["dimensions"] = dimensions
|
||||
|
||||
# Create embeddings index
|
||||
self.embeddings = ANNFactory.create(self.config)
|
||||
|
||||
# Build the index
|
||||
self.embeddings.index(embeddings)
|
||||
|
||||
def upsert(self, documents):
|
||||
"""
|
||||
Runs an embeddings index upsert operation. If the index exists, new
|
||||
data is appended to the index, existing data is updated. If the index
|
||||
doesn't exist, this method runs a standard index operation.
|
||||
|
||||
Args:
|
||||
documents: list of (id, text|tokens, tags)
|
||||
"""
|
||||
|
||||
# Run standard insert if index doesn't exist
|
||||
if not self.embeddings:
|
||||
self.index(documents)
|
||||
return
|
||||
|
||||
# Transform documents to embeddings vectors
|
||||
ids, _, embeddings = self.vectors(documents)
|
||||
|
||||
# Normalize embeddings
|
||||
self.normalize(embeddings)
|
||||
|
||||
# Delete existing elements
|
||||
self.delete(ids)
|
||||
|
||||
# Append elements the index
|
||||
self.embeddings.append(embeddings)
|
||||
|
||||
# Save embeddings metadata
|
||||
self.config["ids"] = self.config["ids"] + ids
|
||||
|
||||
def delete(self, ids):
|
||||
"""
|
||||
Deletes from an embeddings index. Returns list of ids deleted.
|
||||
|
||||
Args:
|
||||
ids: list of ids to delete
|
||||
|
||||
Returns:
|
||||
ids deleted
|
||||
"""
|
||||
|
||||
# List of internal indices for each candidate id to delete
|
||||
indices = []
|
||||
|
||||
# List of deleted ids
|
||||
deletes = []
|
||||
|
||||
# Get handle to config ids
|
||||
cids = self.config["ids"]
|
||||
|
||||
# Find existing ids
|
||||
for uid in ids:
|
||||
indices.extend([index for index, value in enumerate(cids) if uid == value])
|
||||
|
||||
# Delete any found from config ids and embeddings
|
||||
if indices:
|
||||
# Clear config ids
|
||||
for index in indices:
|
||||
deletes.append(cids[index])
|
||||
cids[index] = None
|
||||
|
||||
# Delete ids from index
|
||||
self.embeddings.delete(indices)
|
||||
|
||||
return deletes
|
||||
|
||||
def transform(self, document):
|
||||
"""
|
||||
Transforms document into an embeddings vector. Document text will be tokenized if not pre-tokenized.
|
||||
|
||||
Args:
|
||||
document: (id, text|tokens, tags)
|
||||
|
||||
Returns:
|
||||
embeddings vector
|
||||
"""
|
||||
|
||||
# Convert document into sentence embedding
|
||||
embedding = self.model.transform(document)
|
||||
|
||||
# Reduce the dimensionality of the embeddings. Scale the embeddings using this
|
||||
# model to reduce the noise of common but less relevant terms.
|
||||
if self.reducer:
|
||||
self.reducer(embedding)
|
||||
|
||||
# Normalize embeddings
|
||||
self.normalize(embedding)
|
||||
|
||||
return embedding
|
||||
|
||||
def batchtransform(self, documents):
|
||||
"""
|
||||
Transforms documents into embeddings vectors. Document text will be tokenized if not pre-tokenized.
|
||||
|
||||
Args:
|
||||
documents: list of (id, text|tokens, tags)
|
||||
|
||||
Returns:
|
||||
embeddings vectors
|
||||
"""
|
||||
|
||||
return [self.transform(document) for document in documents]
|
||||
|
||||
def count(self):
|
||||
"""
|
||||
Total number of elements in this embeddings index.
|
||||
|
||||
Returns:
|
||||
number of elements in embeddings index
|
||||
"""
|
||||
|
||||
return self.embeddings.count()
|
||||
|
||||
def search(self, query, limit=3):
|
||||
"""
|
||||
Finds documents in the embeddings model most similar to the input query. Returns
|
||||
a list of (id, score) sorted by highest score, where id is the document id in
|
||||
the embeddings model.
|
||||
|
||||
Args:
|
||||
query: query text|tokens
|
||||
limit: maximum results
|
||||
|
||||
Returns:
|
||||
list of (id, score)
|
||||
"""
|
||||
|
||||
return self.batchsearch([query], limit)[0]
|
||||
|
||||
def batchsearch(self, queries, limit=3):
|
||||
"""
|
||||
Finds documents in the embeddings model most similar to the input queries. Returns
|
||||
a list of (id, score) sorted by highest score per query, where id is the document id
|
||||
in the embeddings model.
|
||||
|
||||
Args:
|
||||
queries: queries text|tokens
|
||||
limit: maximum results
|
||||
|
||||
Returns:
|
||||
list of (id, score) per query
|
||||
"""
|
||||
|
||||
# Convert queries to embedding vectors
|
||||
embeddings = np.array([self.transform((None, query, None)) for query in queries])
|
||||
|
||||
# Search embeddings index
|
||||
results = self.embeddings.search(embeddings, limit)
|
||||
|
||||
# Map ids if id mapping available
|
||||
lookup = self.config.get("ids")
|
||||
if lookup:
|
||||
results = [[(lookup[i], score) for i, score in r] for r in results]
|
||||
|
||||
return results
|
||||
|
||||
def similarity(self, query, texts):
|
||||
"""
|
||||
Computes the similarity between query and list of text. Returns a list of
|
||||
(id, score) sorted by highest score, where id is the index in texts.
|
||||
|
||||
Args:
|
||||
query: query text|tokens
|
||||
texts: list of text|tokens
|
||||
|
||||
Returns:
|
||||
list of (id, score)
|
||||
"""
|
||||
|
||||
return self.batchsimilarity([query], texts)[0]
|
||||
|
||||
def batchsimilarity(self, queries, texts):
|
||||
"""
|
||||
Computes the similarity between list of queries and list of text. Returns a list
|
||||
of (id, score) sorted by highest score per query, where id is the index in texts.
|
||||
|
||||
Args:
|
||||
queries: queries text|tokens
|
||||
texts: list of text|tokens
|
||||
|
||||
Returns:
|
||||
list of (id, score) per query
|
||||
"""
|
||||
|
||||
# Convert queries to embedding vectors
|
||||
queries = np.array([self.transform((None, query, None)) for query in queries])
|
||||
texts = np.array([self.transform((None, text, None)) for text in texts])
|
||||
|
||||
# Dot product on normalized vectors is equal to cosine similarity
|
||||
scores = np.dot(queries, texts.T).tolist()
|
||||
|
||||
# Add index id and sort desc based on score
|
||||
return [sorted(enumerate(score), key=lambda x: x[1], reverse=True) for score in scores]
|
||||
|
||||
def load(self, path):
|
||||
"""
|
||||
Loads a pre-trained model.
|
||||
|
||||
Models have the following files:
|
||||
config - configuration
|
||||
embeddings - sentence embeddings index
|
||||
lsa - LSA model, used to remove the principal component(s)
|
||||
scoring - scoring model used to weigh word vectors
|
||||
vectors - vectors model
|
||||
|
||||
Args:
|
||||
path: input directory path
|
||||
"""
|
||||
|
||||
# Index configuration
|
||||
with open("%s/config" % path, "rb") as handle:
|
||||
self.config = pickle.load(handle)
|
||||
|
||||
# Build full path to embedding vectors file
|
||||
if self.config.get("storevectors"):
|
||||
self.config["path"] = os.path.join(path, self.config["path"])
|
||||
|
||||
# Sentence embeddings index
|
||||
self.embeddings = ANNFactory.create(self.config)
|
||||
self.embeddings.load("%s/embeddings" % path)
|
||||
|
||||
# Dimensionality reduction
|
||||
if self.config.get("pca"):
|
||||
with open("%s/lsa" % path, "rb") as handle:
|
||||
self.reducer = Reducer()
|
||||
self.reducer.load(path)
|
||||
|
||||
# Embedding scoring
|
||||
if self.config.get("scoring"):
|
||||
self.scoring = ScoringFactory.create(self.config["scoring"])
|
||||
self.scoring.load(path)
|
||||
|
||||
# Sentence vectors model - transforms text into sentence embeddings
|
||||
self.model = self.loadVectors()
|
||||
|
||||
def exists(self, path):
|
||||
"""
|
||||
Checks if an index exists at path.
|
||||
|
||||
Args:
|
||||
path: input directory path
|
||||
|
||||
Returns:
|
||||
true if index exists, false otherwise
|
||||
"""
|
||||
|
||||
return os.path.exists("%s/config" % path) and os.path.exists("%s/embeddings" % path)
|
||||
|
||||
def save(self, path):
|
||||
"""
|
||||
Saves a model.
|
||||
|
||||
Args:
|
||||
path: output directory path
|
||||
"""
|
||||
|
||||
if self.config:
|
||||
# Create output directory, if necessary
|
||||
os.makedirs(path, exist_ok=True)
|
||||
|
||||
# Copy vectors file
|
||||
if self.config.get("storevectors"):
|
||||
shutil.copyfile(self.config["path"], os.path.join(path, os.path.basename(self.config["path"])))
|
||||
|
||||
self.config["path"] = os.path.basename(self.config["path"])
|
||||
|
||||
# Write index configuration
|
||||
with open("%s/config" % path, "wb") as handle:
|
||||
pickle.dump(self.config, handle, protocol=pickle.HIGHEST_PROTOCOL)
|
||||
|
||||
# Write sentence embeddings index
|
||||
self.embeddings.save("%s/embeddings" % path)
|
||||
|
||||
# Save dimensionality reduction
|
||||
if self.reducer:
|
||||
self.reducer.save(path)
|
||||
|
||||
# Save embedding scoring
|
||||
if self.scoring:
|
||||
self.scoring.save(path)
|
||||
|
||||
def loadVectors(self):
|
||||
"""
|
||||
Loads a vector model set in config.
|
||||
|
||||
Returns:
|
||||
vector model
|
||||
"""
|
||||
|
||||
return VectorsFactory.create(self.config, self.scoring)
|
||||
|
||||
def vectors(self, documents):
|
||||
"""
|
||||
Transforms documents into embeddings vectors.
|
||||
|
||||
Args:
|
||||
documents: list of (id, text|tokens, tags)
|
||||
|
||||
Returns:
|
||||
tuple of document ids, dimensions and embeddings
|
||||
"""
|
||||
|
||||
# Transform documents to embeddings vectors
|
||||
ids, dimensions, stream = self.model.index(documents)
|
||||
|
||||
# Load streamed embeddings back to memory
|
||||
embeddings = np.empty((len(ids), dimensions), dtype=np.float32)
|
||||
with open(stream, "rb") as queue:
|
||||
for x in range(embeddings.shape[0]):
|
||||
embeddings[x] = pickle.load(queue)
|
||||
|
||||
# Remove temporary file
|
||||
os.remove(stream)
|
||||
|
||||
return (ids, dimensions, embeddings)
|
||||
|
||||
def normalize(self, embeddings):
|
||||
"""
|
||||
Normalizes embeddings using L2 normalization. Operation applied directly on array.
|
||||
|
||||
Args:
|
||||
embeddings: input embeddings matrix
|
||||
"""
|
||||
|
||||
# Calculation is different for matrices vs vectors
|
||||
if len(embeddings.shape) > 1:
|
||||
embeddings /= np.linalg.norm(embeddings, axis=1)[:, np.newaxis]
|
||||
else:
|
||||
embeddings /= np.linalg.norm(embeddings)
|
||||
@@ -0,0 +1,71 @@
|
||||
"""
|
||||
Stream module
|
||||
"""
|
||||
|
||||
import os
|
||||
import pickle
|
||||
import tempfile
|
||||
|
||||
|
||||
class Documents:
|
||||
"""
|
||||
Streams documents to temporary storage. Allows queuing large volumes of content for later indexing.
|
||||
"""
|
||||
|
||||
def __init__(self):
|
||||
"""
|
||||
Creates a new DocumentStream.
|
||||
"""
|
||||
|
||||
self.documents = None
|
||||
self.batch = 0
|
||||
|
||||
def __iter__(self):
|
||||
"""
|
||||
Streams all queued documents.
|
||||
"""
|
||||
|
||||
# Close streaming file
|
||||
self.documents.close()
|
||||
|
||||
# Open stream file
|
||||
with open(self.documents.name, "rb") as queue:
|
||||
# Read each batch
|
||||
for _ in range(self.batch):
|
||||
documents = pickle.load(queue)
|
||||
|
||||
# Yield each document
|
||||
yield from documents
|
||||
|
||||
def add(self, documents):
|
||||
"""
|
||||
Adds a batch of documents for indexing.
|
||||
|
||||
Args:
|
||||
documents: list of (id, data, tag) tuples
|
||||
|
||||
Returns:
|
||||
documents
|
||||
"""
|
||||
|
||||
# Create documents file if not already open
|
||||
if not self.documents:
|
||||
self.documents = tempfile.NamedTemporaryFile(mode="wb", suffix=".docs", delete=False)
|
||||
|
||||
# Add batch
|
||||
pickle.dump(documents, self.documents)
|
||||
self.batch += 1
|
||||
|
||||
return documents
|
||||
|
||||
def close(self):
|
||||
"""
|
||||
Closes and resets this instance. New sets of documents can be added with additional calls to add.
|
||||
"""
|
||||
|
||||
# Cleanup stream file
|
||||
os.remove(self.documents.name)
|
||||
|
||||
# Reset document parameters
|
||||
self.documents = None
|
||||
self.batch = 0
|
||||
@@ -0,0 +1,95 @@
|
||||
"""
|
||||
Reducer module
|
||||
"""
|
||||
|
||||
import pickle
|
||||
|
||||
# Conditionally import dimensionality reduction libraries as they aren't installed by default
|
||||
try:
|
||||
from sklearn.decomposition import TruncatedSVD
|
||||
|
||||
REDUCER = True
|
||||
except ImportError:
|
||||
REDUCER = False
|
||||
|
||||
|
||||
class Reducer:
|
||||
"""
|
||||
LSA dimensionality reduction model
|
||||
"""
|
||||
|
||||
def __init__(self, embeddings=None, components=None):
|
||||
"""
|
||||
Creates a dimensionality reduction model.
|
||||
|
||||
Args:
|
||||
embeddings: input embeddings matrix
|
||||
components: number of model components
|
||||
"""
|
||||
|
||||
self.model = self.build(embeddings, components) if embeddings is not None and components else None
|
||||
|
||||
def __call__(self, embeddings):
|
||||
"""
|
||||
Applies a dimensionality reduction model to embeddings, removed the top n principal components. Operation applied
|
||||
directly on array.
|
||||
|
||||
Args:
|
||||
embeddings: input embeddings matrix
|
||||
"""
|
||||
|
||||
pc = self.model.components_
|
||||
factor = embeddings.dot(pc.transpose())
|
||||
|
||||
# Apply LSA model
|
||||
# Calculation is different if n_components = 1
|
||||
if pc.shape[0] == 1:
|
||||
embeddings -= factor * pc
|
||||
elif len(embeddings.shape) > 1:
|
||||
# Apply model on a row-wise basis to limit memory usage
|
||||
for x in range(embeddings.shape[0]):
|
||||
embeddings[x] -= factor[x].dot(pc)
|
||||
else:
|
||||
# Single embedding
|
||||
embeddings -= factor.dot(pc)
|
||||
|
||||
def build(self, embeddings, components):
|
||||
"""
|
||||
Builds a LSA model. This model is used to remove the principal component within embeddings. This helps to
|
||||
smooth out noisy embeddings (common words with less value).
|
||||
|
||||
Args:
|
||||
embeddings: input embeddings matrix
|
||||
components: number of model components
|
||||
|
||||
Returns:
|
||||
LSA model
|
||||
"""
|
||||
|
||||
model = TruncatedSVD(n_components=components, random_state=0)
|
||||
model.fit(embeddings)
|
||||
|
||||
return model
|
||||
|
||||
def load(self, path):
|
||||
"""
|
||||
Loads a Reducer object from path.
|
||||
|
||||
Args:
|
||||
path: directory path to load model
|
||||
"""
|
||||
|
||||
# Dimensionality reduction
|
||||
with open("%s/lsa" % path, "rb") as handle:
|
||||
self.model = pickle.load(handle)
|
||||
|
||||
def save(self, path):
|
||||
"""
|
||||
Saves a Reducer object to path.
|
||||
|
||||
Args:
|
||||
path: directory path to save model
|
||||
"""
|
||||
|
||||
with open("%s/lsa" % path, "wb") as handle:
|
||||
pickle.dump(self.model, handle, protocol=pickle.HIGHEST_PROTOCOL)
|
||||
@@ -1,137 +0,0 @@
|
||||
"""
|
||||
Extractor module
|
||||
"""
|
||||
|
||||
from nltk.tokenize import sent_tokenize
|
||||
|
||||
from .pipeline import Pipeline
|
||||
from .tokenizer import Tokenizer
|
||||
|
||||
class Extractor(object):
|
||||
"""
|
||||
Class that uses an extractive question-answering model to extract content from a given text context.
|
||||
"""
|
||||
|
||||
def __init__(self, embeddings, path, quantize=False, tokenizer=None):
|
||||
"""
|
||||
Builds a new extractor.
|
||||
|
||||
Args:
|
||||
embeddings: embeddings model
|
||||
path: path to qa model
|
||||
quantize: True if model should be quantized before inference, False otherwise.
|
||||
tokenizer: Tokenizer class
|
||||
"""
|
||||
|
||||
# Embeddings model and open database cursor
|
||||
self.embeddings = embeddings
|
||||
|
||||
# QA Pipeline
|
||||
self.pipeline = Pipeline(path, quantize)
|
||||
|
||||
# Tokenizer class use default method if not set
|
||||
self.tokenizer = tokenizer if tokenizer else Tokenizer
|
||||
|
||||
def __call__(self, sections, queue):
|
||||
"""
|
||||
Extracts answers to input questions. This method runs queries against a list of text sections, finds the top n best matches
|
||||
and uses that as the question context. A question-answering model is then run against the context for the input question,
|
||||
with the answer returned.
|
||||
|
||||
Args:
|
||||
sections: list of (id, text) sections
|
||||
queue: input queue (name, query, question, snippet)
|
||||
|
||||
Returns:
|
||||
extracted answers
|
||||
"""
|
||||
|
||||
# Tokenize text
|
||||
segments, tokenlist = [], []
|
||||
for sid, text in sections:
|
||||
tokens = self.tokenizer.tokenize(text)
|
||||
if tokens:
|
||||
segments.append((sid, text))
|
||||
tokenlist.append(tokens)
|
||||
|
||||
# Build question-context pairs
|
||||
names, questions, contexts, snippets = [], [], [], []
|
||||
for name, query, question, snippet in queue:
|
||||
# Get list of required tokens
|
||||
must = [token.strip("+") for token in query.split() if token.startswith("+")]
|
||||
|
||||
# Tokenize search query
|
||||
query = self.tokenizer.tokenize(query)
|
||||
|
||||
# List of matches
|
||||
matches = []
|
||||
|
||||
scores = self.embeddings.similarity(query, tokenlist)
|
||||
for x, score in enumerate(scores):
|
||||
# Get segment text
|
||||
text = segments[x][1]
|
||||
|
||||
# Add result if all required tokens are present or there are not required tokens
|
||||
if not must or all([token.lower() in text.lower() for token in must]):
|
||||
matches.append(segments[x] + (score,))
|
||||
|
||||
# Build context using top n best matching segments
|
||||
topn = sorted(matches, key=lambda x: x[2], reverse=True)[:3]
|
||||
context = " ".join([text for _, text, _ in sorted(topn, key=lambda x: x[0])])
|
||||
|
||||
names.append(name)
|
||||
questions.append(question)
|
||||
contexts.append(context)
|
||||
snippets.append(snippet)
|
||||
|
||||
# Run qa pipeline and return answers
|
||||
return self.answers(names, questions, contexts, snippets)
|
||||
|
||||
def answers(self, names, questions, contexts, snippets):
|
||||
"""
|
||||
Executes QA pipeline and formats extracted answers.
|
||||
|
||||
Args:
|
||||
names: column names
|
||||
questions: questions
|
||||
contexts: question context
|
||||
snippets: flags to enable answer snippets per answer
|
||||
"""
|
||||
|
||||
results = []
|
||||
|
||||
# Run qa pipeline
|
||||
answers = self.pipeline(questions, contexts)
|
||||
|
||||
# Extract and format answer
|
||||
for x, answer in enumerate(answers):
|
||||
# Extract answer
|
||||
value = answer["answer"]
|
||||
|
||||
# Resolve snippet if necessary
|
||||
if answer and snippets[x]:
|
||||
value = self.snippet(contexts[x], value)
|
||||
|
||||
results.append((names[x], value))
|
||||
|
||||
return results
|
||||
|
||||
def snippet(self, context, answer):
|
||||
"""
|
||||
Extracts text surrounding the answer within context.
|
||||
|
||||
Args:
|
||||
context: full context
|
||||
answer: answer within context
|
||||
|
||||
Returns:
|
||||
text surrounding answer as a snippet
|
||||
"""
|
||||
|
||||
# Searches for first sentence to contain answer
|
||||
if answer:
|
||||
for x in sent_tokenize(context):
|
||||
if answer in x:
|
||||
return x
|
||||
|
||||
return answer
|
||||
@@ -0,0 +1,7 @@
|
||||
"""
|
||||
Models imports
|
||||
"""
|
||||
|
||||
from .models import Models
|
||||
from .onnx import OnnxModel
|
||||
from .pooling import MeanPooling, Pooling
|
||||
@@ -0,0 +1,122 @@
|
||||
"""
|
||||
Models module
|
||||
"""
|
||||
|
||||
import os
|
||||
|
||||
import torch
|
||||
|
||||
from transformers import AutoModel, AutoModelForQuestionAnswering, AutoModelForSeq2SeqLM, AutoModelForSequenceClassification
|
||||
|
||||
from .onnx import OnnxModel
|
||||
|
||||
|
||||
class Models:
|
||||
"""
|
||||
Utility methods for working with machine learning models
|
||||
"""
|
||||
|
||||
@staticmethod
|
||||
def checklength(config, tokenizer):
|
||||
"""
|
||||
Checks the length for a Hugging Face Transformers tokenizer using a Hugging Face Transformers config. Copies the
|
||||
max_position_embeddings parameter if the tokenizer has no max_length set. This helps with backwards compatibility
|
||||
with older tokenizers.
|
||||
|
||||
Args:
|
||||
config: Transformers config
|
||||
tokenizer: Transformers tokenizer
|
||||
"""
|
||||
|
||||
# Unpack nested config, handles passing model directly
|
||||
if hasattr(config, "config"):
|
||||
config = config.config
|
||||
|
||||
if hasattr(config, "max_position_embeddings") and tokenizer.model_max_length == int(1e30):
|
||||
tokenizer.model_max_length = config.max_position_embeddings
|
||||
|
||||
@staticmethod
|
||||
def deviceid(gpu):
|
||||
"""
|
||||
Translates a gpu flag into a device id.
|
||||
|
||||
Args:
|
||||
gpu: True/False if GPU should be enabled, also supports a GPU device id
|
||||
|
||||
Returns:
|
||||
device id
|
||||
"""
|
||||
|
||||
# Always return -1 if gpu is None or CUDA is unavailable
|
||||
if gpu is None or not torch.cuda.is_available():
|
||||
return -1
|
||||
|
||||
# Default to device 0 if gpu is True and not otherwise specified
|
||||
if isinstance(gpu, bool):
|
||||
return 0 if gpu else -1
|
||||
|
||||
# Return gpu as device id if gpu flag is an int
|
||||
return int(gpu)
|
||||
|
||||
@staticmethod
|
||||
def device(deviceid):
|
||||
"""
|
||||
Gets a tensor device.
|
||||
|
||||
Args:
|
||||
deviceid: device id
|
||||
|
||||
Returns:
|
||||
tensor device
|
||||
"""
|
||||
|
||||
# Torch device
|
||||
# pylint: disable=E1101
|
||||
return torch.device(Models.reference(deviceid))
|
||||
|
||||
@staticmethod
|
||||
def reference(deviceid):
|
||||
"""
|
||||
Gets a tensor device reference.
|
||||
|
||||
Args:
|
||||
deviceid: device id
|
||||
|
||||
Returns:
|
||||
device reference
|
||||
"""
|
||||
|
||||
return "cpu" if deviceid < 0 else "cuda:{}".format(deviceid)
|
||||
|
||||
@staticmethod
|
||||
def load(path, task="default"):
|
||||
"""
|
||||
Loads a machine learning model. Handles multiple model frameworks (ONNX, Transformers).
|
||||
|
||||
Args:
|
||||
path: path to model
|
||||
task: task name used to lookup model configuration
|
||||
|
||||
Returns:
|
||||
machine learning model
|
||||
"""
|
||||
|
||||
# Detect ONNX models
|
||||
if isinstance(path, bytes) or (isinstance(path, str) and os.path.isfile(path)):
|
||||
return OnnxModel(path)
|
||||
|
||||
# Return path, if path isn't a string
|
||||
if not isinstance(path, str):
|
||||
return path
|
||||
|
||||
# Transformer models
|
||||
config = {
|
||||
"default": AutoModel.from_pretrained,
|
||||
"question-answering": AutoModelForQuestionAnswering.from_pretrained,
|
||||
"summarization": AutoModelForSeq2SeqLM.from_pretrained,
|
||||
"text-classification": AutoModelForSequenceClassification.from_pretrained,
|
||||
"zero-shot-classification": AutoModelForSequenceClassification.from_pretrained,
|
||||
}
|
||||
|
||||
# Load model for supported tasks. Return path for unsupported tasks.
|
||||
return config[task](path) if task in config else path
|
||||
@@ -0,0 +1,130 @@
|
||||
"""
|
||||
ONNX module
|
||||
"""
|
||||
|
||||
from collections import namedtuple
|
||||
|
||||
# Conditional import
|
||||
try:
|
||||
from onnxruntime import InferenceSession, SessionOptions
|
||||
|
||||
ONNX_RUNTIME = True
|
||||
except ImportError:
|
||||
ONNX_RUNTIME = False
|
||||
|
||||
import numpy as np
|
||||
import torch
|
||||
|
||||
from transformers.configuration_utils import PretrainedConfig
|
||||
from transformers.models.auto.modeling_auto import (
|
||||
MODEL_MAPPING,
|
||||
MODEL_FOR_QUESTION_ANSWERING_MAPPING,
|
||||
MODEL_FOR_SEQUENCE_CLASSIFICATION_MAPPING,
|
||||
)
|
||||
from transformers.models.auto.tokenization_auto import TOKENIZER_MAPPING
|
||||
from transformers.modeling_utils import PreTrainedModel
|
||||
|
||||
# pylint: disable=W0223
|
||||
class OnnxModel(PreTrainedModel):
|
||||
"""
|
||||
Provides a Transformers/PyTorch compatible interface for ONNX models. Handles casting inputs
|
||||
and outputs with minimal to no copying of data.
|
||||
"""
|
||||
|
||||
def __init__(self, model):
|
||||
"""
|
||||
Creates a new OnnxModel.
|
||||
|
||||
Args:
|
||||
model: path to model or InferenceSession
|
||||
"""
|
||||
|
||||
if not ONNX_RUNTIME:
|
||||
raise ImportError('onnxruntime is not available - install "model" extra to enable')
|
||||
|
||||
super().__init__(OnnxConfig())
|
||||
|
||||
# Create ONNX session
|
||||
self.model = InferenceSession(model, SessionOptions())
|
||||
|
||||
# Add references for this class to supported AutoModel classes
|
||||
name = self.__class__.__name__
|
||||
if name not in MODEL_MAPPING:
|
||||
for mapping in [MODEL_MAPPING, MODEL_FOR_SEQUENCE_CLASSIFICATION_MAPPING, MODEL_FOR_QUESTION_ANSWERING_MAPPING]:
|
||||
self.autoadd(mapping, name, self.__class__)
|
||||
|
||||
# Add references for this class to support pipeline AutoTokenizers
|
||||
if type(self.config) not in TOKENIZER_MAPPING:
|
||||
self.autoadd(TOKENIZER_MAPPING, type(self.config), type(self.config).__name__)
|
||||
|
||||
def autoadd(self, mapping, key, value):
|
||||
"""
|
||||
Adds OnnxModel to auto model configuration to fully support pipelines.
|
||||
|
||||
Args:
|
||||
mapping: auto model mapping
|
||||
key: key to add
|
||||
value: value to add
|
||||
"""
|
||||
|
||||
# pylint: disable=W0212
|
||||
Params = namedtuple("Params", ["config", "model"])
|
||||
params = Params(key, value)
|
||||
|
||||
mapping._modules[key] = params
|
||||
mapping._config_mapping[key] = "config"
|
||||
mapping._reverse_config_mapping[value] = key
|
||||
mapping._model_mapping[key] = "model"
|
||||
|
||||
def forward(self, **inputs):
|
||||
"""
|
||||
Runs inputs through an ONNX model and returns outputs. This method handles casting inputs
|
||||
and outputs between torch tensors and numpy arrays as shared memory (no copy).
|
||||
|
||||
Args:
|
||||
inputs: model inputs
|
||||
|
||||
Returns:
|
||||
model outputs
|
||||
"""
|
||||
|
||||
inputs = self.parse(inputs)
|
||||
|
||||
# Run inputs through ONNX model
|
||||
results = self.model.run(None, inputs)
|
||||
|
||||
# pylint: disable=E1101
|
||||
return torch.from_numpy(np.array(results))
|
||||
|
||||
def parse(self, inputs):
|
||||
"""
|
||||
Parse model inputs and handle converting to ONNX compatible inputs.
|
||||
|
||||
Args:
|
||||
inputs: model inputs
|
||||
|
||||
Returns:
|
||||
ONNX compatible model inputs
|
||||
"""
|
||||
|
||||
features = {}
|
||||
|
||||
# Select features from inputs
|
||||
for key in ["input_ids", "attention_mask", "token_type_ids"]:
|
||||
if key in inputs:
|
||||
value = inputs[key]
|
||||
|
||||
# Cast torch tensors to numpy
|
||||
if hasattr(value, "cpu"):
|
||||
value = value.cpu().numpy()
|
||||
|
||||
# Cast to numpy array if not already one
|
||||
features[key] = np.asarray(value)
|
||||
|
||||
return features
|
||||
|
||||
|
||||
class OnnxConfig(PretrainedConfig):
|
||||
"""
|
||||
Configuration for ONNX models.
|
||||
"""
|
||||
@@ -0,0 +1,136 @@
|
||||
"""
|
||||
Pooling module
|
||||
"""
|
||||
|
||||
import numpy as np
|
||||
import torch
|
||||
|
||||
from torch import nn
|
||||
|
||||
from transformers import AutoTokenizer
|
||||
|
||||
from .models import Models
|
||||
|
||||
|
||||
class Pooling(nn.Module):
|
||||
"""
|
||||
Builds pooled vectors usings outputs from a transformers model.
|
||||
"""
|
||||
|
||||
def __init__(self, path, device, tokenizer=None, batch=32, maxlength=None):
|
||||
"""
|
||||
Creates a new Pooling model.
|
||||
|
||||
Args:
|
||||
path: path to model, accepts Hugging Face model hub id or local path
|
||||
device: tensor device id
|
||||
tokenizer: optional path to tokenizer
|
||||
batch: batch size
|
||||
maxlength: max sequence length
|
||||
"""
|
||||
|
||||
super().__init__()
|
||||
|
||||
self.model = Models.load(path)
|
||||
self.tokenizer = AutoTokenizer.from_pretrained(tokenizer if tokenizer else path)
|
||||
self.device = Models.device(device)
|
||||
|
||||
# Detect unbounded tokenizer typically found in older models
|
||||
Models.checklength(self.model, self.tokenizer)
|
||||
|
||||
# Set batch and max length
|
||||
self.batch = batch
|
||||
self.maxlength = maxlength if maxlength else self.tokenizer.model_max_length
|
||||
|
||||
# Move to device
|
||||
self.to(self.device)
|
||||
|
||||
def encode(self, documents):
|
||||
"""
|
||||
Builds an array of pooled embeddings for documents.
|
||||
|
||||
Args:
|
||||
documents: list of documents used to build embeddings
|
||||
|
||||
Returns:
|
||||
pooled embeddings
|
||||
"""
|
||||
|
||||
# Split documents into batches and process
|
||||
results = []
|
||||
|
||||
# Sort document indices from largest to smallest to enable efficient batching
|
||||
# This performance tweak matches logic in sentence-transformers
|
||||
lengths = np.argsort([-len(x) for x in documents])
|
||||
documents = [documents[x] for x in lengths]
|
||||
|
||||
for chunk in self.chunk(documents, self.batch):
|
||||
# Tokenize input
|
||||
inputs = self.tokenizer(chunk, padding=True, truncation="longest_first", return_tensors="pt", max_length=self.maxlength)
|
||||
|
||||
# Move inputs to device
|
||||
inputs = inputs.to(self.device)
|
||||
|
||||
# Run inputs through model
|
||||
with torch.no_grad():
|
||||
outputs = self.forward(**inputs)
|
||||
|
||||
# Add batch result
|
||||
results.extend(outputs.cpu().numpy())
|
||||
|
||||
# Restore original order and return array
|
||||
return np.asarray([results[x] for x in np.argsort(lengths)])
|
||||
|
||||
def chunk(self, texts, size):
|
||||
"""
|
||||
Splits texts into separate batch sizes specified by size.
|
||||
|
||||
Args:
|
||||
texts: text elements
|
||||
size: batch size
|
||||
|
||||
Returns:
|
||||
list of evenly sized batches with the last batch having the remaining elements
|
||||
"""
|
||||
|
||||
return [texts[x : x + size] for x in range(0, len(texts), size)]
|
||||
|
||||
def forward(self, **inputs):
|
||||
"""
|
||||
Runs inputs through transformers model and returns outputs.
|
||||
|
||||
Args:
|
||||
inputs: model inputs
|
||||
|
||||
Returns:
|
||||
model outputs
|
||||
"""
|
||||
|
||||
return self.model(**inputs)[0]
|
||||
|
||||
|
||||
class MeanPooling(Pooling):
|
||||
"""
|
||||
Builds mean pooled vectors usings outputs from a transformers model.
|
||||
"""
|
||||
|
||||
def forward(self, **inputs):
|
||||
"""
|
||||
Runs mean pooling on token embeddings taking the input mask into account.
|
||||
|
||||
Args:
|
||||
outputs: model outputs
|
||||
mask: input attention mask
|
||||
|
||||
Returns:
|
||||
mean pooled embeddings using output token embeddings (i.e. last hidden state)
|
||||
"""
|
||||
|
||||
# Run through transformers model
|
||||
tokens = super().forward(**inputs)
|
||||
mask = inputs["attention_mask"]
|
||||
|
||||
# Mean pooling
|
||||
# pylint: disable=E1101
|
||||
mask = mask.unsqueeze(-1).expand(tokens.size()).float()
|
||||
return torch.sum(tokens * mask, 1) / torch.clamp(mask.sum(1), min=1e-9)
|
||||
@@ -1,146 +0,0 @@
|
||||
"""
|
||||
Pipeline module
|
||||
"""
|
||||
|
||||
import numpy as np
|
||||
import regex as re
|
||||
import torch
|
||||
|
||||
from transformers import AutoModelForQuestionAnswering, AutoTokenizer
|
||||
|
||||
class Pipeline(object):
|
||||
"""
|
||||
Extractive question-answering model.
|
||||
|
||||
Logic based on HuggingFace's transformers QuestionAnswering pipeline.
|
||||
"""
|
||||
|
||||
def __init__(self, path, quantize):
|
||||
"""
|
||||
Loads a new pipeline model.
|
||||
|
||||
Args:
|
||||
path: path to model
|
||||
quantize: if model should be quantized
|
||||
"""
|
||||
|
||||
self.model = AutoModelForQuestionAnswering.from_pretrained(path)
|
||||
self.tokenizer = AutoTokenizer.from_pretrained(path)
|
||||
|
||||
if quantize:
|
||||
# pylint: disable=E1101
|
||||
self.model = torch.quantization.quantize_dynamic(self.model, {torch.nn.Linear}, dtype=torch.qint8)
|
||||
|
||||
def __call__(self, questions, contexts):
|
||||
"""
|
||||
Runs a extractive question-answering model against each question-context pair, finding the best answers.
|
||||
|
||||
Args:
|
||||
questions: list of questions
|
||||
contexts: list of contexts to pull answers from
|
||||
|
||||
Returns:
|
||||
list of answers
|
||||
"""
|
||||
|
||||
answers = []
|
||||
|
||||
for x, question in enumerate(questions):
|
||||
# Encode question and context using model tokenizer
|
||||
inputs = self.tokenizer.encode_plus(question, contexts[x], add_special_tokens=True, return_tensors="pt")
|
||||
input_ids = inputs["input_ids"].tolist()[0]
|
||||
|
||||
try:
|
||||
# Run the input against the model, get candidate start-end pairs
|
||||
start, end = self.model(**inputs)
|
||||
start, end = start.detach().numpy(), end.detach().numpy()
|
||||
|
||||
# Normalize start and end logits
|
||||
start = np.exp(start) / np.sum(np.exp(start))
|
||||
end = np.exp(end) / np.sum(np.exp(end))
|
||||
|
||||
# Tokenized questions for BERT models take the format:
|
||||
# [CLS] Question [SEP] Answer [SEP]
|
||||
# This logic prevents the answer coming from the question
|
||||
separator = input_ids.index(self.tokenizer.sep_token_id)
|
||||
pmask = np.array([1 if x <= separator else 0 for x in range(len(input_ids))])
|
||||
|
||||
# Mask the question tokens
|
||||
start, end = (start * np.abs(np.array(pmask) - 1), end * np.abs(np.array(pmask) - 1))
|
||||
|
||||
tokens, answer = [], None
|
||||
|
||||
start, end, score = self.score(start, end, 15)
|
||||
|
||||
# Require best score to be at least 0.05
|
||||
if score >= 0.05:
|
||||
# Get span tokens
|
||||
tokens = self.tokenizer.convert_ids_to_tokens(input_ids[start:(end + 1)], skip_special_tokens=True)
|
||||
|
||||
# Build regex to match original string
|
||||
answer = re.search(self.regex(tokens), contexts[x], re.IGNORECASE)
|
||||
answer = answer[0]
|
||||
|
||||
# Add answer
|
||||
answers.append({"answer": answer, "score": score})
|
||||
|
||||
# pylint: disable=W0702
|
||||
except:
|
||||
answers.append({"answer": None, "score": 0.0})
|
||||
|
||||
return answers
|
||||
|
||||
def score(self, start, end, maxlength):
|
||||
"""
|
||||
Scores all possible combinations of start and end index up to maxlength. Returns
|
||||
the best match.
|
||||
|
||||
Args:
|
||||
start: start index scores
|
||||
end: end index scores
|
||||
maxlength: max number of tokens to allow in a match
|
||||
|
||||
Returns:
|
||||
(start index, end index, score) of best scoring combination
|
||||
"""
|
||||
|
||||
# Score all possible combinations of start, end indices
|
||||
scores = np.matmul(np.expand_dims(start, -1), np.expand_dims(end, 1))
|
||||
|
||||
# Zero out candidates with end < start and end - start > maxlength
|
||||
candidates = np.tril(np.triu(scores), maxlength - 1)
|
||||
|
||||
# Get index of best rated combination
|
||||
# pylint: disable=E1101
|
||||
index = np.argmax(candidates.flatten())
|
||||
|
||||
# Get (start, end, score) of best rated combination
|
||||
# pylint: disable=E1126, W0632
|
||||
start, end = np.unravel_index(index, candidates.shape)[1:]
|
||||
return start, end, candidates[0, start, end]
|
||||
|
||||
def regex(self, tokens):
|
||||
"""
|
||||
Builds a regular expression from tokens.
|
||||
|
||||
Args:
|
||||
tokens: input tokens
|
||||
|
||||
Returns:
|
||||
regex to use to extract match in original text
|
||||
"""
|
||||
|
||||
regex = []
|
||||
|
||||
for token in tokens:
|
||||
# Escape regex characters
|
||||
token = re.escape(token)
|
||||
|
||||
# Handle subwords
|
||||
if token.startswith("\\#\\#"):
|
||||
token = re.sub(r"^\\#\\#", "", token)
|
||||
|
||||
regex.append(token)
|
||||
|
||||
# Build and return complete regular expression
|
||||
return "\\s?".join(regex)
|
||||
@@ -0,0 +1,21 @@
|
||||
"""
|
||||
Pipeline imports
|
||||
"""
|
||||
|
||||
from .base import Pipeline
|
||||
from .extractor import Extractor
|
||||
from .factory import PipelineFactory
|
||||
from .hfmodel import HFModel
|
||||
from .hfonnx import HFOnnx
|
||||
from .hfpipeline import HFPipeline
|
||||
from .hftrainer import HFTrainer
|
||||
from .labels import Labels
|
||||
from .questions import Questions
|
||||
from .segmentation import Segmentation
|
||||
from .similarity import Similarity
|
||||
from .summary import Summary
|
||||
from .tensors import Tensors
|
||||
from .textractor import Textractor
|
||||
from .tokenizer import Tokenizer
|
||||
from .transcription import Transcription
|
||||
from .translation import Translation
|
||||
@@ -0,0 +1,9 @@
|
||||
"""
|
||||
Pipeline module
|
||||
"""
|
||||
|
||||
|
||||
class Pipeline:
|
||||
"""
|
||||
Base class for all Pipelines. The only interface requirement is to define a __call___ method.
|
||||
"""
|
||||
@@ -0,0 +1,173 @@
|
||||
"""
|
||||
Extractor module
|
||||
"""
|
||||
|
||||
from .base import Pipeline
|
||||
from .questions import Questions
|
||||
from .tokenizer import Tokenizer
|
||||
|
||||
|
||||
class Extractor(Pipeline):
|
||||
"""
|
||||
Class that uses an extractive question-answering model to extract content from a given text context.
|
||||
"""
|
||||
|
||||
def __init__(self, embeddings, path, quantize=False, gpu=False, model=None, tokenizer=None):
|
||||
"""
|
||||
Builds a new extractor.
|
||||
|
||||
Args:
|
||||
embeddings: embeddings model
|
||||
path: path to qa model
|
||||
quantize: True if model should be quantized before inference, False otherwise.
|
||||
gpu: if gpu inference should be used (only works if GPUs are available)
|
||||
model: optional existing pipeline model to wrap
|
||||
tokenizer: Tokenizer class
|
||||
"""
|
||||
|
||||
# Embeddings model
|
||||
self.embeddings = embeddings
|
||||
|
||||
# QA Pipeline
|
||||
self.pipeline = Questions(path, quantize, gpu, model)
|
||||
|
||||
# Tokenizer class use default method if not set
|
||||
self.tokenizer = tokenizer if tokenizer else Tokenizer
|
||||
|
||||
def __call__(self, queue, texts):
|
||||
"""
|
||||
Extracts answers to input questions. This method runs queries against a list of text, finds the top n best matches
|
||||
and uses that as the question context. A question-answering model is then run against the context for the input question,
|
||||
with the answer returned.
|
||||
|
||||
Args:
|
||||
queue: input queue (name, query, question, snippet)
|
||||
texts: list of text
|
||||
|
||||
Returns:
|
||||
list of (name, answer)
|
||||
"""
|
||||
|
||||
# Execute embeddings query
|
||||
results = self.query([query for _, query, _, _ in queue], texts)
|
||||
|
||||
# Build question-context pairs
|
||||
names, questions, contexts, topns, snippets = [], [], [], [], []
|
||||
for x, (name, _, question, snippet) in enumerate(queue):
|
||||
# Build context using top n best matching segments
|
||||
topn = sorted(results[x], key=lambda y: y[2], reverse=True)[:3]
|
||||
context = " ".join([text for _, text, _ in sorted(topn, key=lambda y: y[0])])
|
||||
|
||||
names.append(name)
|
||||
questions.append(question)
|
||||
contexts.append(context)
|
||||
topns.append([text for _, text, _ in topn])
|
||||
snippets.append(snippet)
|
||||
|
||||
# Run qa pipeline and return answers
|
||||
return self.answers(names, questions, contexts, topns, snippets)
|
||||
|
||||
def query(self, queries, texts):
|
||||
"""
|
||||
Executes the extractor embeddings query. Returns results sorted by best match.
|
||||
|
||||
Args:
|
||||
queries: list of embedding queries to run
|
||||
texts: list of text
|
||||
|
||||
Returns:
|
||||
list of (id, text, score)
|
||||
"""
|
||||
|
||||
# Tokenize text
|
||||
segments, tokenlist = [], []
|
||||
for text in texts:
|
||||
tokens = self.tokenizer.tokenize(text)
|
||||
if tokens:
|
||||
segments.append(text)
|
||||
tokenlist.append(tokens)
|
||||
|
||||
# Add index id to segments to preserver ordering after filters
|
||||
segments = list(enumerate(segments))
|
||||
|
||||
# Build question-context pairs
|
||||
results = []
|
||||
for query in queries:
|
||||
# Get list of required and prohibited tokens
|
||||
must = [token.strip("+") for token in query.split() if token.startswith("+") and len(token) > 1]
|
||||
mnot = [token.strip("-") for token in query.split() if token.startswith("-") and len(token) > 1]
|
||||
|
||||
# Tokenize search query
|
||||
query = self.tokenizer.tokenize(query)
|
||||
|
||||
# List of matches
|
||||
matches = []
|
||||
|
||||
# Get list of (id, score) - sorted by highest score
|
||||
scores = self.embeddings.similarity(query, tokenlist)
|
||||
for x, score in scores:
|
||||
# Get segment text
|
||||
text = segments[x][1]
|
||||
|
||||
# Add result if:
|
||||
# - all required tokens are present or there are not required tokens AND
|
||||
# - all prohibited tokens are not present or there are not prohibited tokens
|
||||
if (not must or all([token.lower() in text.lower() for token in must])) and (
|
||||
not mnot or all([token.lower() not in text.lower() for token in mnot])
|
||||
):
|
||||
matches.append(segments[x] + (score,))
|
||||
|
||||
# Add query matches sorted by highest score
|
||||
results.append(matches)
|
||||
|
||||
return results
|
||||
|
||||
def answers(self, names, questions, contexts, topns, snippets):
|
||||
"""
|
||||
Executes QA pipeline and formats extracted answers.
|
||||
|
||||
Args:
|
||||
names: question identifiers/names
|
||||
questions: questions
|
||||
contexts: question context
|
||||
topns: same as question context but as a list with each candidate element
|
||||
snippets: flags to enable answer snippets per answer
|
||||
|
||||
Returns:
|
||||
list of (name, answer)
|
||||
"""
|
||||
|
||||
results = []
|
||||
|
||||
# Run qa pipeline
|
||||
answers = self.pipeline(questions, contexts)
|
||||
|
||||
# Extract and format answer
|
||||
for x, answer in enumerate(answers):
|
||||
# Resolve snippet if necessary
|
||||
if answer and snippets[x]:
|
||||
answer = self.snippet(topns[x], answer)
|
||||
|
||||
results.append((names[x], answer))
|
||||
|
||||
return results
|
||||
|
||||
def snippet(self, topn, answer):
|
||||
"""
|
||||
Extracts text surrounding the answer within context.
|
||||
|
||||
Args:
|
||||
topn: topn items used as a context
|
||||
answer: answer within context
|
||||
|
||||
Returns:
|
||||
text surrounding answer as a snippet
|
||||
"""
|
||||
|
||||
# Searches for first sentence to contain answer
|
||||
if answer:
|
||||
for x in topn:
|
||||
if answer in x:
|
||||
return x
|
||||
|
||||
return answer
|
||||
@@ -0,0 +1,50 @@
|
||||
"""
|
||||
Pipeline factory module
|
||||
"""
|
||||
|
||||
|
||||
class PipelineFactory:
|
||||
"""
|
||||
Pipeline factory. Creates new Pipeline instances.
|
||||
"""
|
||||
|
||||
@staticmethod
|
||||
def get(pipeline):
|
||||
"""
|
||||
Gets a new instance of pipeline class.
|
||||
|
||||
Args:
|
||||
pipeline: Pipeline instance class
|
||||
|
||||
Returns:
|
||||
Pipeline class
|
||||
"""
|
||||
|
||||
# Local pipeline if no package
|
||||
if "." not in pipeline:
|
||||
# Get parent package
|
||||
pipeline = ".".join(__name__.split(".")[:-1]) + "." + pipeline.capitalize()
|
||||
|
||||
parts = pipeline.split(".")
|
||||
module = ".".join(parts[:-1])
|
||||
m = __import__(module)
|
||||
for comp in parts[1:]:
|
||||
m = getattr(m, comp)
|
||||
|
||||
return m
|
||||
|
||||
@staticmethod
|
||||
def create(config, pipeline):
|
||||
"""
|
||||
Creates a new Pipeline instance.
|
||||
|
||||
Args:
|
||||
config: Pipeline configuration
|
||||
pipeline: Pipeline instance class
|
||||
|
||||
Returns:
|
||||
Pipeline
|
||||
"""
|
||||
|
||||
# Get Pipeline instance
|
||||
return PipelineFactory.get(pipeline)(**config)
|
||||
Some files were not shown because too many files have changed in this diff Show More
Reference in New Issue
Block a user