mirror of
https://github.com/rui314/mold.git
synced 2026-11-09 04:49:33 -10:00
Compare commits
241
Commits
linker-script
...
v2.42.1
| Author | SHA1 | Date | |
|---|---|---|---|
 Rui Ueyama |
9b376bc6a9 | ||
|
Rui Ueyama
|
af7d056853 | ||
|
Rui Ueyama
|
5bdd5e6284 | ||
|
Rui Ueyama
|
a4bcbb45ae | ||
|
Rui Ueyama
|
4a83b5d856 | ||
|
Rui Ueyama
|
20eb664a7e | ||
|
Rui Ueyama
|
c72d19dcca | ||
|
Rui Ueyama
|
dad2695f3e | ||
|
Rui Ueyama
|
fcd9dea78f | ||
|
Rui Ueyama
|
ff0cb501b0 | ||
|
Rui Ueyama
|
91252d8aa5 | ||
|
Rui Ueyama
|
4a11b7849d | ||
|
Rui Ueyama
|
53715c07ee | ||
|
Rui Ueyama
|
41d2f376c3 | ||
|
Rui Ueyama
|
3a58944ff9 | ||
|
Rui Ueyama
|
ec7c803207 | ||
|
Rui Ueyama
|
f9bdf4b4de | ||
|
Rui Ueyama
|
e9de4def18 | ||
|
Rui Ueyama
|
18d173697c | ||
|
Rui Ueyama
|
fa1e8edc39 | ||
|
Rui Ueyama
|
841880212f | ||
|
Rui Ueyama
|
f585fee6ca | ||
|
Rui Ueyama
|
95137b235e | ||
|
Rui Ueyama
|
95dbca6708 | ||
|
Rui Ueyama
|
f8cb3daf00 | ||
|
Rui Ueyama
|
0f582b0a23 | ||
|
Rui Ueyama
|
2c402f707f | ||
|
Rui Ueyama
|
046a644906 | ||
|
Rui Ueyama
|
8566358143 | ||
|
Rui Ueyama
|
477db5f372 | ||
|
Rui Ueyama
|
9887339f72 | ||
|
Rui Ueyama
|
0706198355 | ||
|
Rui Ueyama
|
cbcf79c0ef | ||
|
Rui Ueyama
|
6060657622 | ||
|
Rui UeyamaandClaude Fable 5.1
|
92eb17a07c | ||
|
Rui UeyamaandClaude Fable 5.1
|
450832db6b | ||
|
Rui UeyamaandClaude Fable 5.1
|
d3cf4a23e0 | ||
|
Rui UeyamaandClaude Fable 5
|
32626eba5d | ||
|
Rui Ueyama
|
046ca4fa79 | ||
|
Rui UeyamaandClaude Fable 5
|
adb411d475 | ||
|
Rui UeyamaandClaude Fable 5
|
878599b795 | ||
|
Rui UeyamaandClaude Fable 5
|
4ebc916bc9 | ||
|
Rui UeyamaandClaude Fable 5
|
a129618d11 | ||
|
Rui UeyamaandClaude Fable 5
|
a9af11f74a | ||
|
Rui UeyamaandClaude Fable 5
|
d55b408ff0 | ||
|
Rui UeyamaandClaude Fable 5
|
f3b74cbb6a | ||
|
Rui UeyamaandClaude Fable 5
|
1f56c36413 | ||
|
Rui UeyamaandClaude Fable 5
|
e2a28d61eb | ||
|
Rui UeyamaandClaude Fable 5
|
19e5360530 | ||
|
Rui UeyamaandClaude Fable 5
|
f68cb6fb18 | ||
|
Rui Ueyama
|
504249d994 | ||
|
Rui Ueyama
|
ecf335a4e1 | ||
|
Rui UeyamaandClaude Fable 5
|
fbaaa75f9f | ||
|
Rui UeyamaandClaude Fable 5
|
91cab12f9a | ||
|
jvoisin
|
3d4dc7291e | ||
|
Rui UeyamaandClaude Fable 5
|
e633272dc9 | ||
|
Rui UeyamaandClaude Fable 5
|
5dce8bb4fc | ||
|
Rui UeyamaandClaude Fable 5
|
28513b5882 | ||
|
Rui UeyamaandClaude Fable 5
|
df35e2ba4a | ||
|
Rui UeyamaandClaude Fable 5
|
72a956d56e | ||
|
Rui UeyamaandClaude Fable 5
|
32e7a1a111 | ||
|
Rui UeyamaandClaude Fable 5
|
64d7331cef | ||
|
Rui UeyamaandClaude Fable 5
|
1e5d6ba386 | ||
|
Rui Ueyama
|
04a455a416 | ||
|
Rui UeyamaandClaude Fable 5
|
d00482d2dd | ||
|
Rui UeyamaandClaude Fable 5
|
7279781fbd | ||
|
Rui Ueyama
|
f716fb62de | ||
|
Rui UeyamaandClaude Fable 5
|
d9c9b906ad | ||
|
Rui UeyamaandClaude Fable 5
|
364413c41b | ||
|
Rui UeyamaandClaude Fable 5
|
8d9cdfef3d | ||
|
Rui UeyamaandClaude Fable 5
|
21042fa988 | ||
|
Rui UeyamaandClaude Fable 5
|
00f3077dae | ||
|
Rui UeyamaandClaude Fable 5
|
97f9e8e416 | ||
|
Rui UeyamaandClaude Fable 5
|
8579808892 | ||
|
Rui UeyamaandClaude Fable 5
|
68fceadb7d | ||
|
Rui UeyamaandClaude Fable 5
|
29a43f104d | ||
|
Rui UeyamaandClaude Fable 5
|
38ec6e4ad3 | ||
|
Rui UeyamaandClaude Fable 5
|
4af8d3f8e9 | ||
|
Rui UeyamaandClaude Fable 5
|
e344452b1e | ||
|
Rui UeyamaandClaude Fable 5
|
e3ae2eb7ff | ||
|
Rui UeyamaandClaude Fable 5
|
6f0f855ce6 | ||
|
Rui UeyamaandClaude Fable 5
|
c2822be61a | ||
|
Rui Ueyama
|
0d3fe4ed34 | ||
|
Rui Ueyama
|
6b22256da3 | ||
|
Rui UeyamaandClaude Fable 5
|
0ddd5b0420 | ||
|
Rui Ueyama
|
02a4923ba2 | ||
|
Rui UeyamaandClaude Fable 5
|
8349c41980 | ||
|
Rui Ueyama
|
abd0a19cfb | ||
|
Rui Ueyama
|
e3e5fba05f | ||
|
Rui Ueyama
|
cb33534e38 | ||
|
Rui UeyamaandClaude Fable 5
|
c4c090bce7 | ||
|
Rui Ueyama
|
6e1d9b68a3 | ||
|
Rui Ueyama
|
7187b766f7 | ||
|
Rui Ueyama
|
ebb41cbd65 | ||
|
Rui Ueyama
|
30765e5020 | ||
|
Rui Ueyama
|
6a1b0f7924 | ||
|
Rui Ueyama
|
dd3cdb3c9d | ||
|
WaterWhisperer
|
5147fc580c | ||
|
Rui Ueyama
|
e04dded86e | ||
|
Rui UeyamaandClaude Fable 5
|
a718dbbcd5 | ||
|
Rui UeyamaandClaude Fable 5
|
a7504210dd | ||
|
Rui Ueyama
|
d8f4506ab5 | ||
|
Rui Ueyama
|
5ef9acad1f | ||
|
Rui Ueyama
|
3d16156250 | ||
|
Rui Ueyama
|
c340272e63 | ||
|
Rui Ueyama
|
635956d3b7 | ||
|
Rui Ueyama
|
5f71cbf988 | ||
|
Rui Ueyama
|
6157cc99f1 | ||
|
Rui Ueyama
|
441dc1d1fd | ||
|
Rui Ueyama
|
d12e0e4e9c | ||
|
Rui Ueyama
|
f76ea9442a | ||
|
Rui Ueyama
|
b9d57111ed | ||
|
Rui Ueyama
|
de35271267 | ||
|
Rui Ueyama
|
cf0e0f7996 | ||
|
Rui Ueyama
|
a94df206b6 | ||
|
Rui Ueyama
|
1ce5b39f7e | ||
|
Rui Ueyama
|
80af3a8138 | ||
|
Rui Ueyama
|
799b26f8e2 | ||
|
Rui Ueyama
|
a9dc01b477 | ||
|
Rui Ueyama
|
ac73431954 | ||
|
Rui UeyamaandClaude Fable 5
|
3eca43961d | ||
|
Rui Ueyama
|
4b56395f5e | ||
|
Rui Ueyama
|
cf0b26045f | ||
|
Rui UeyamaandClaude Fable 5
|
283238426e | ||
|
Rui Ueyama
|
8aa9429728 | ||
|
Rui Ueyama
|
cdbc8db1cb | ||
|
Rui UeyamaandClaude Fable 5
|
a7b79b2a52 | ||
|
Rui UeyamaandClaude Fable 5
|
ad038099a0 | ||
|
Rui UeyamaandClaude Fable 5
|
c30224584a | ||
|
Rui Ueyama
|
5b84f386ee | ||
|
Rui Ueyama
|
9b101aa9c7 | ||
|
Rui Ueyama
|
3ff882b02c | ||
|
Rui Ueyama
|
19ae69dd61 | ||
|
Rui UeyamaandClaude Fable 5
|
64b92151a0 | ||
|
Rui Ueyama
|
5e33441a0d | ||
|
Rui Ueyama
|
dd06a8969b | ||
|
Rui Ueyama
|
0a59e34909 | ||
|
Rui Ueyama
|
34a2edb995 | ||
|
Franciszek MaroszekandClaude Opus 5
|
5898fbcb6e | ||
|
Rui Ueyama
|
7324c2a006 | ||
|
Rui Ueyama
|
48cea99498 | ||
|
Rui Ueyama
|
755a39ed53 | ||
|
Rui Ueyama
|
bf19884539 | ||
|
Rui Ueyama
|
17abd5cdea | ||
|
Rui Ueyama
|
dfb03f26f8 | ||
|
Rui Ueyama
|
474d4ce4df | ||
|
Rui Ueyama
|
4cce716e72 | ||
|
Rui Ueyama
|
e4303913ee | ||
|
Rui Ueyama
|
efbba44cdc | ||
|
Rui Ueyama
|
6a9ecbad23 | ||
|
Rui Ueyama
|
046101eda3 | ||
|
Rui Ueyama
|
594b03674d | ||
|
Rui Ueyama
|
5f7764124c | ||
|
Rui Ueyama
|
fc7cbd5dad | ||
|
Rui Ueyama
|
1861e3c308 | ||
|
Rui Ueyama
|
1f77c59113 | ||
|
Rui Ueyama
|
fb80d619ae | ||
|
Rui Ueyama
|
f554cfef24 | ||
|
Rui Ueyama
|
d9137264f6 | ||
|
Rui Ueyama
|
7887246f23 | ||
|
Rui Ueyama
|
a222bda697 | ||
|
Rui Ueyama
|
63d88b5e46 | ||
|
Rui Ueyama
|
eb615efc16 | ||
|
Rui Ueyama
|
3af5464546 | ||
|
Rui Ueyama
|
50f68848d5 | ||
|
Rui Ueyama
|
e1f1ba00e0 | ||
|
Rui Ueyama
|
7813baa40f | ||
|
Rui Ueyama
|
ac7334246c | ||
|
Rui Ueyama
|
9cb33a0e7d | ||
|
Rui UeyamaandClaude Fable 5
|
5157cef1fc | ||
|
Rui UeyamaandClaude Fable 5
|
35f4a334a0 | ||
|
Rui UeyamaandClaude Fable 5
|
fba0a2185d | ||
|
Rui UeyamaandClaude Fable 5
|
1fb2901b19 | ||
|
Rui UeyamaandClaude Fable 5
|
2b605279fe | ||
|
Rui UeyamaandClaude Fable 5
|
00a27307f8 | ||
|
Rui UeyamaandClaude Fable 5
|
920a516125 | ||
|
Rui Ueyama
|
4b00446c59 | ||
|
Rui UeyamaandClaude Fable 5
|
1d306dc0ac | ||
|
Rui UeyamaandClaude Fable 5
|
383ff33215 | ||
|
Rui UeyamaandClaude Fable 5
|
4ea8cb996f | ||
|
Rui UeyamaandClaude Fable 5
|
2d09378cfd | ||
|
Rui UeyamaandClaude Fable 5
|
a8fbf52ef1 | ||
|
Rui Ueyama
|
848135170a | ||
|
Rui UeyamaandClaude Fable 5
|
1c11d94c02 | ||
|
Rui UeyamaandClaude Fable 5
|
45dea59990 | ||
|
Rui UeyamaandClaude Fable 5
|
9b7c526704 | ||
|
Rui UeyamaandClaude Fable 5
|
a30c483ffa | ||
|
Rui UeyamaandClaude Fable 5
|
d444584f2b | ||
|
Rui UeyamaandClaude Fable 5
|
c8d44d73ce | ||
|
Rui UeyamaandClaude Fable 5
|
97867c5354 | ||
|
Rui UeyamaandClaude Fable 5
|
e2190e9a60 | ||
|
Rui UeyamaandClaude Fable 5
|
0a5bd29b56 | ||
|
Rui UeyamaandClaude Fable 5
|
be3d214c47 | ||
|
Rui UeyamaandClaude Fable 5
|
4ef13c9609 | ||
|
Rui UeyamaandClaude Fable 5
|
3699cc68e2 | ||
|
Rui Ueyama
|
bfa7117757 | ||
|
git-staus
|
9bf01c1f1d | ||
|
Rui UeyamaandClaude Fable 5
|
5ba31dc3ea | ||
|
Rui UeyamaandClaude Fable 5
|
86b42639cc | ||
|
Rui UeyamaandClaude Fable 5
|
a06b6234c9 | ||
|
Rui UeyamaandClaude Fable 5
|
6b5df4d6cf | ||
|
Rui UeyamaandClaude Fable 5
|
3e62b432a5 | ||
|
Rui UeyamaandClaude Fable 5
|
f478001cc0 | ||
|
Rui UeyamaandClaude Fable 5
|
7172b136c9 | ||
|
Rui UeyamaandClaude Fable 5
|
c6f436690b | ||
|
Rui UeyamaandClaude Fable 5
|
923df2f0d6 | ||
|
Rui UeyamaandClaude Fable 5
|
b922536782 | ||
|
Rui UeyamaandClaude Fable 5
|
22a8d49788 | ||
|
Rui Ueyama
|
1ef1ea49ed | ||
|
Rui Ueyama
|
0a04fb22ad | ||
|
Rui UeyamaandClaude Fable 5
|
5f2d627597 | ||
|
Rui Ueyama
|
f485f44d06 | ||
|
Rui Ueyama
|
a708f03e9a | ||
|
Rui UeyamaandClaude Fable 5
|
b126f83271 | ||
|
Rui UeyamaandClaude Fable 5
|
0086e97e8d | ||
|
Rui UeyamaandClaude Fable 5
|
e57c733e74 | ||
|
Rui Ueyama
|
1adc707d49 | ||
|
Rui Ueyama
|
2ad8219352 | ||
|
Rui Ueyama
|
c0b29dc05e | ||
|
Rui Ueyama
|
2b340d400b | ||
|
Rui Ueyama
|
7f75a1adde | ||
|
Rui Ueyama
|
930bb45339 | ||
|
Rui Ueyama
|
36e80ccea5 | ||
|
Rui Ueyama
|
0ddff68d52 | ||
|
Andrew Grieve
|
3d546cd068 | ||
|
Rui Ueyama
|
f5fd48874a | ||
|
Rui Ueyama
|
6b7e8d86e2 | ||
|
Rui Ueyama
|
aa50e9f88d | ||
|
Rui Ueyama
|
26ccd7aecc | ||
|
Rui Ueyama
|
6b1914d062 | ||
|
Rui Ueyama
|
3bb16732ae | ||
|
Rui Ueyama
|
81ccee4446 | ||
|
Martin Liska
|
dc5c6c5fa4 | ||
|
Ehren Bendler
|
f07bf7352f | ||
|
Ehren Bendler
|
2ec5e72691 | ||
|
Rui Ueyama
|
f4a62c7503 | ||
|
Rui Ueyama
|
075c63861d | ||
|
Rui Ueyama
|
94c259a89a | ||
|
Rui Ueyama
|
8b79fbbf02 | ||
|
Rui UeyamaandClaude Opus 4.8
|
ad4c489fff | ||
|
Sun Yuechi
|
71cbd79f8c |
No files matched your search
@@ -79,7 +79,7 @@ jobs:
|
||||
distro:
|
||||
- alpine
|
||||
- archlinux
|
||||
- debian:11 # GCC 10 and CMake 3.18 - the minimum supported by mold
|
||||
- debian:12
|
||||
- fedora
|
||||
- gentoo/stage3
|
||||
- opensuse/tumbleweed
|
||||
|
||||
+16
-5
@@ -44,7 +44,7 @@
|
||||
# features and behave exactly the same.
|
||||
|
||||
cmake_minimum_required(VERSION 3.14)
|
||||
project(mold VERSION 2.41.0)
|
||||
project(mold VERSION 2.42.1)
|
||||
|
||||
include(CMakeDependentOption)
|
||||
include(CheckSymbolExists)
|
||||
@@ -149,10 +149,9 @@ find_package(ZLIB QUIET)
|
||||
if(ZLIB_FOUND AND NOT MOLD_MOSTLY_STATIC)
|
||||
target_link_libraries(mold PRIVATE ZLIB::ZLIB)
|
||||
else()
|
||||
set(ZLIB_BUILD_EXAMPLES OFF CACHE INTERNAL "")
|
||||
set(ZLIB_BUILD_SHARED OFF CACHE INTERNAL "")
|
||||
set(ZLIB_BUILD_TESTING OFF CACHE INTERNAL "")
|
||||
add_subdirectory(third-party/zlib EXCLUDE_FROM_ALL)
|
||||
target_include_directories(zlibstatic INTERFACE third-party/zlib
|
||||
$<TARGET_PROPERTY:zlibstatic,BINARY_DIR>)
|
||||
target_link_libraries(mold PRIVATE zlibstatic)
|
||||
endif()
|
||||
|
||||
@@ -209,9 +208,13 @@ cmake_dependent_option(
|
||||
# By default, we build a bundled mimalloc and statically-link it to
|
||||
# mold. If you want to dynamically link to the system's
|
||||
# libmimalloc.so, pass -DMOLD_USE_SYSTEM_MIMALLOC=ON.
|
||||
#
|
||||
# We require mimalloc v3 or newer. mimalloc v2 doesn't use transparent
|
||||
# huge pages for the allocation path that serves mold's largest data
|
||||
# structures, which makes linking large programs significantly slower.
|
||||
if(MOLD_USE_MIMALLOC)
|
||||
if(MOLD_USE_SYSTEM_MIMALLOC)
|
||||
find_package(mimalloc REQUIRED)
|
||||
find_package(mimalloc 3 REQUIRED)
|
||||
target_link_libraries(mold PRIVATE mimalloc)
|
||||
else()
|
||||
function(mold_add_mimalloc)
|
||||
@@ -306,6 +309,13 @@ endif()
|
||||
check_symbol_exists(madvise sys/mman.h HAVE_MADVISE)
|
||||
check_symbol_exists(uname sys/utsname.h HAVE_UNAME)
|
||||
|
||||
# glibc declares fallocate only under _GNU_SOURCE. C++ compilers
|
||||
# predefine it on Linux, but this check runs the C compiler, which
|
||||
# does not.
|
||||
set(CMAKE_REQUIRED_DEFINITIONS -D_GNU_SOURCE)
|
||||
check_symbol_exists(fallocate fcntl.h HAVE_FALLOCATE)
|
||||
unset(CMAKE_REQUIRED_DEFINITIONS)
|
||||
|
||||
# Create a .cc file containing the current git hash for `mold --version`.
|
||||
add_custom_target(git_hash
|
||||
COMMAND ${CMAKE_COMMAND}
|
||||
@@ -414,6 +424,7 @@ endforeach()
|
||||
# Add other non-template source files.
|
||||
target_sources(mold PRIVATE
|
||||
lib/aho-corasick.cc
|
||||
lib/arena.cc
|
||||
lib/compress.cc
|
||||
lib/crc32.cc
|
||||
lib/demangle.cc
|
||||
|
||||
@@ -1,30 +1,21 @@
|
||||
# mold: A Modern Linker
|
||||
|
||||
mold is a faster drop-in replacement for existing Unix linkers. It is several
|
||||
times quicker than the LLVM lld linker, the second-fastest open-source linker,
|
||||
which I initially developed a few years ago. mold aims to enhance developer
|
||||
productivity by minimizing build time, particularly in rapid
|
||||
debug-edit-rebuild cycles.
|
||||
mold is a high-performance drop-in replacement for existing Unix linkers,
|
||||
designed to speed up builds. In our August 2026 benchmarks, it links 4.9x
|
||||
faster than [LLVM lld](https://lld.llvm.org) and 1.9x faster than
|
||||
[wild](https://github.com/wild-linker/wild) at the median; see
|
||||
[Benchmark](#benchmark) for the full results.
|
||||
|
||||
Here is a performance comparison of GNU ld, GNU gold, LLVM lld, and
|
||||
mold when linking final debuginfo-enabled executables for major large
|
||||
programs on a simulated 16-core, 32-thread machine.
|
||||
mold is written by the original developer of LLVM lld, the linker that
|
||||
Android, Chrome, FreeBSD, PlayStation, Nintendo Switch, and other production
|
||||
systems are built with. mold started as an effort to build an even faster
|
||||
linker from scratch, free of the architectural limits its author had run into
|
||||
while optimizing lld. It has been in production use since 2021, and today it
|
||||
is the default linker of many large open-source projects and is used
|
||||
internally by many companies.
|
||||
|
||||

|
||||
|
||||
| Program (linker output size) | GNU ld | GNU gold | LLVM lld | mold
|
||||
|-------------------------------|--------|----------|----------|------
|
||||
| MySQL 8.3 (0.47 GiB) | 10.84s | 7.47s | 1.64s | 0.46s
|
||||
| Clang 19 (1.56 GiB) | 42.07s | 33.13s | 5.20s | 1.35s
|
||||
| Chromium 124 (1.35 GiB) | N/A | 27.40s | 6.10s | 1.52s
|
||||
|
||||
mold is so fast that it is only 2x _slower_ than the `cp` command on the same
|
||||
machine. If you find that mold is not faster than other linkers, feel
|
||||
free to [file a bug report](https://github.com/rui314/mold/issues).
|
||||
|
||||
mold supports x86-64, i386, ARM64, ARM32, 64-bit/32-bit little/big-endian
|
||||
RISC-V, 32-bit PowerPC, 64-bit big-endian PowerPC ELFv1, 64-bit little-endian
|
||||
PowerPC ELFv2, s390x, 64-bit/32-bit LoongArch, SPARC64, m68k, and SH-4.
|
||||
mold supports x86-64, i386, ARM 32/64, RISC-V 32/64, PowerPC 32/64, s390x,
|
||||
LoongArch 32/64, SPARC64, m68k, and SH-4.
|
||||
|
||||
## Why does linking speed matter?
|
||||
|
||||
@@ -38,12 +29,106 @@ speed up this process, saving you time and preventing distractions while
|
||||
waiting for a lengthy build to finish. The difference is most noticeable
|
||||
during rapid debug-edit-rebuild cycles.
|
||||
|
||||
## Benchmark
|
||||
|
||||
Here is a performance comparison of lld, wild, and mold when linking nine
|
||||
large programs on two machines:
|
||||
|
||||
- AMD Ryzen Threadripper 7980X (64 cores) running Ubuntu 24.04
|
||||
- Apple M1 Ultra (16 performance cores and 4 efficiency cores) running Fedora
|
||||
Asahi Remix 42; the benchmark is restricted to the performance cores
|
||||
|
||||
The Threadripper represents many-core workstation and server processors, and
|
||||
the M1 Ultra represents high-performance desktop processors.
|
||||
|
||||
All three linkers were built from source in release configuration as of
|
||||
2026-08-28 and ran with their default options. Times are wall-clock times as
|
||||
seen by the caller, the median of three runs after a warm-up. The ARM64 rows
|
||||
are the ARM64 builds of the same programs. The benchmark suite, including all
|
||||
linker inputs, is available on [Zenodo](https://zenodo.org/records/21882261).
|
||||
|
||||
**AMD Ryzen Threadripper 7980X, debug builds**
|
||||
|
||||
| Program (output size) | lld | wild | mold | wild/mold | lld/mold
|
||||
|-----------------------------------|--------|-------|-------|-----------|---------
|
||||
| Blender 5.2 (2.46 GiB) | 4.72s | 1.98s | 0.86s | 2.3x | 5.5x
|
||||
| Chromium 145 (4.51 GiB) | 16.64s | 3.98s | 1.65s | 2.4x | 10.1x
|
||||
| Chromium 145 ARM64 (4.76 GiB) | 20.91s | N/A | 1.83s | N/A | 11.4x
|
||||
| Clang 21 (4.19 GiB) | 6.19s | 3.71s | 1.34s | 2.8x | 4.6x
|
||||
| ClickHouse 26.1 (5.58 GiB) | 6.62s | 4.40s | 0.98s | 4.5x | 6.7x
|
||||
| Firefox 149 (2.37 GiB) | 5.11s | N/A | 0.78s | N/A | 6.5x
|
||||
| Firefox 149 ARM64 (2.43 GiB) | 6.40s | N/A | 0.93s | N/A | 6.9x
|
||||
| Godot 4.6 (1.01 GiB) | 1.77s | 1.08s | 0.46s | 2.3x | 3.8x
|
||||
| LibreOffice 26.2 (0.98 GiB) | 3.46s | 1.41s | 0.44s | 3.2x | 7.9x
|
||||
| PyTorch 2.9 (3.51 GiB) | 4.35s | 2.48s | 0.80s | 3.1x | 5.4x
|
||||
| TensorFlow 2.21 (9.55 GiB) | 50.73s | N/A | 3.15s | N/A | 16.1x
|
||||
|
||||
**AMD Ryzen Threadripper 7980X, release builds**
|
||||
|
||||
| Program (output size) | lld | wild | mold | wild/mold | lld/mold
|
||||
|-----------------------------------|-------|-------|-------|-----------|---------
|
||||
| Blender 5.2 (0.24 GiB) | 0.85s | 0.30s | 0.20s | 1.5x | 4.2x
|
||||
| Chromium 145 (0.58 GiB) | 6.48s | N/A | 0.64s | N/A | 10.2x
|
||||
| Chromium 145 ARM64 (0.60 GiB) | 7.91s | N/A | 0.73s | N/A | 10.8x
|
||||
| Clang 21 (0.21 GiB) | 0.53s | 0.23s | 0.11s | 2.2x | 5.0x
|
||||
| ClickHouse 26.1 (1.23 GiB) | 3.18s | 2.07s | 0.41s | 5.0x | 7.7x
|
||||
| Firefox 149 (0.22 GiB) | 1.01s | 0.41s | 0.21s | 2.0x | 4.9x
|
||||
| Godot 4.6 (0.15 GiB) | 0.44s | 0.21s | 0.08s | 2.7x | 5.8x
|
||||
| LibreOffice 26.2 (0.19 GiB) | 1.13s | 0.57s | 0.19s | 3.0x | 6.0x
|
||||
| PyTorch 2.9 (0.31 GiB) | 0.68s | 0.32s | 0.15s | 2.2x | 4.7x
|
||||
| TensorFlow 2.21 (0.73 GiB) | 9.62s | N/A | 0.70s | N/A | 13.7x
|
||||
|
||||
**Apple M1 Ultra, debug builds**
|
||||
|
||||
| Program (output size) | lld | wild | mold | wild/mold | lld/mold
|
||||
|-----------------------------------|--------|-------|-------|-----------|---------
|
||||
| Blender 5.2 (2.46 GiB) | 3.21s | 1.81s | 1.56s | 1.2x | 2.1x
|
||||
| Chromium 145 (4.51 GiB) | 9.54s | 3.49s | 2.22s | 1.6x | 4.3x
|
||||
| Chromium 145 ARM64 (4.76 GiB) | 12.67s | N/A | 2.31s | N/A | 5.5x
|
||||
| Clang 21 (4.19 GiB) | 4.40s | 2.78s | 2.96s | 0.9x | 1.5x
|
||||
| ClickHouse 26.1 (5.58 GiB) | 4.92s | 3.50s | 1.71s | 2.1x | 2.9x
|
||||
| Firefox 149 (2.37 GiB) | 3.21s | N/A | 1.12s | N/A | 2.9x
|
||||
| Firefox 149 ARM64 (2.43 GiB) | 4.13s | N/A | 1.12s | N/A | 3.7x
|
||||
| Godot 4.6 (1.01 GiB) | 1.12s | 0.81s | 0.62s | 1.3x | 1.8x
|
||||
| LibreOffice 26.2 (0.98 GiB) | 2.08s | 0.94s | 0.63s | 1.5x | 3.3x
|
||||
| PyTorch 2.9 (3.51 GiB) | 3.07s | 2.10s | 1.45s | 1.4x | 2.1x
|
||||
| TensorFlow 2.21 (9.55 GiB) | 43.68s | N/A | 4.43s | N/A | 9.9x
|
||||
|
||||
**Apple M1 Ultra, release builds**
|
||||
|
||||
| Program (output size) | lld | wild | mold | wild/mold | lld/mold
|
||||
|-----------------------------------|-------|-------|-------|-----------|---------
|
||||
| Blender 5.2 (0.24 GiB) | 0.56s | 0.20s | 0.25s | 0.8x | 2.3x
|
||||
| Chromium 145 (0.58 GiB) | 4.25s | N/A | 0.78s | N/A | 5.5x
|
||||
| Chromium 145 ARM64 (0.60 GiB) | 5.17s | N/A | 0.91s | N/A | 5.7x
|
||||
| Clang 21 (0.21 GiB) | 0.30s | 0.15s | 0.14s | 1.0x | 2.1x
|
||||
| ClickHouse 26.1 (1.23 GiB) | 1.94s | 0.95s | 0.55s | 1.7x | 3.5x
|
||||
| Firefox 149 (0.22 GiB) | 0.56s | 0.23s | 0.20s | 1.1x | 2.7x
|
||||
| Godot 4.6 (0.15 GiB) | 0.26s | 0.11s | 0.11s | 1.0x | 2.3x
|
||||
| LibreOffice 26.2 (0.19 GiB) | 0.62s | 0.30s | 0.23s | 1.3x | 2.7x
|
||||
| PyTorch 2.9 (0.31 GiB) | 0.43s | 0.22s | 0.17s | 1.3x | 2.5x
|
||||
| TensorFlow 2.21 (0.73 GiB) | 8.07s | N/A | 0.68s | N/A | 11.9x
|
||||
|
||||
N/A indicates that the linker cannot link that program. wild's Chromium
|
||||
release links are also marked N/A because wild does not implement `--icf=all`
|
||||
and links without identical code folding.
|
||||
|
||||
## Why is mold so fast?
|
||||
|
||||
mold owes its speed to pervasive parallelism and to efficient data structures
|
||||
and algorithms. For details, read our paper "mold: A Massively Parallel
|
||||
Linker" (ASPLOS 2027), available at https://arxiv.org/abs/2608.23228.
|
||||
|
||||
## Installation
|
||||
|
||||
Binary packages for the following systems are currently available:
|
||||
|
||||
[](https://repology.org/project/mold/versions)
|
||||
|
||||
Prebuilt binaries for Linux on x86-64, ARM64, ARM32, RISC-V, PPC64LE, s390x,
|
||||
and LoongArch are also attached to each
|
||||
[GitHub release](https://github.com/rui314/mold/releases).
|
||||
|
||||
## How to Build
|
||||
|
||||
mold is written in C++20, so if you build mold yourself, you will need a
|
||||
@@ -54,14 +139,14 @@ recent version of a C++ compiler and a C++ standard library. We recommend GCC
|
||||
|
||||
To install build dependencies, run `./install-build-deps.sh` in this
|
||||
directory. It will detect your Linux distribution and attempt to install the
|
||||
necessary packages. You may need to run it as root.
|
||||
necessary packages.
|
||||
|
||||
### Compile mold
|
||||
|
||||
```shell
|
||||
git clone --branch stable https://github.com/rui314/mold.git
|
||||
cd mold
|
||||
./install-build-deps.sh
|
||||
sudo ./install-build-deps.sh
|
||||
cmake -DCMAKE_BUILD_TYPE=Release -DCMAKE_CXX_COMPILER=c++ -B build
|
||||
cmake --build build -j$(nproc)
|
||||
sudo cmake --build build --target install
|
||||
@@ -219,39 +304,26 @@ is available online. You can read the same manual by running `man mold`.
|
||||
|
||||
</details>
|
||||
|
||||
## Why is mold so fast?
|
||||
## Stability
|
||||
|
||||
One reason is that it utilizes faster algorithms and more efficient data
|
||||
structures compared to other linkers. Another reason is that mold is highly
|
||||
parallelized.
|
||||
|
||||
Here is a side-by-side comparison of per-core CPU usage for lld (left) and
|
||||
mold (right), linking the same program, a Chromium executable.
|
||||
|
||||

|
||||
|
||||
As you can see, mold uses all available cores throughout its execution and
|
||||
finishes quickly. In contrast, lld fails to utilize available cores most of
|
||||
the time. In this demo, the maximum parallelism is artificially capped at 16,
|
||||
so that the bars fit in the GIF.
|
||||
|
||||
For details, please see the [design notes](docs/design.md).
|
||||
mold has been developed in the open since 2020 and has more than 140
|
||||
contributors. Its test suite, which covers every linker feature, runs in CI for
|
||||
all supported target CPU architectures, natively or under QEMU, and under ASAN
|
||||
and TSAN. Before each release, we try to build all of Gentoo Linux's roughly
|
||||
19,000 packages with mold, using GNU ld as a control, to find regressions before
|
||||
they reach a release.
|
||||
|
||||
## Sponsors
|
||||
|
||||
It is taken for granted nowadays that compiler toolchains can be easily
|
||||
installed and used for free, and people may not think too much about the
|
||||
individuals behind these "free tools". mold supports many projects, but it
|
||||
is essentially a one-person project. This situation is similar to the one
|
||||
depicted in the following xkcd illustration.
|
||||
mold is free to use, but keeping it maintained is continuous work: supporting
|
||||
new architectures and toolchain features, keeping up with the projects that
|
||||
depend on it, and making it faster. That work is funded by sponsors. If mold
|
||||
saves you or your company time, please consider becoming a
|
||||
[GitHub sponsor](https://github.com/sponsors/rui314).
|
||||
|
||||
[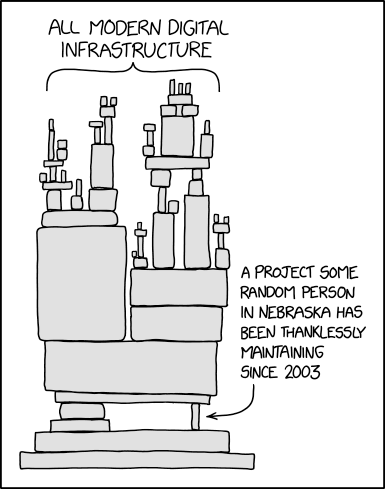](https://xkcd.com/2347)
|
||||
|
||||
If you think that the "Nebraska guy" should be rewarded, please consider
|
||||
becoming our [GitHub sponsor](https://github.com/sponsors/rui314)!
|
||||
|
||||
We thank everyone who sponsors our project. In particular, we'd like to acknowledge
|
||||
the following people and organizations who have sponsored $128/month or more:
|
||||
We thank everyone who sponsors the project. In particular, we'd like to
|
||||
acknowledge the following people and organizations who have sponsored
|
||||
$128/month or more:
|
||||
|
||||
### Corporate sponsors
|
||||
|
||||
|
||||
@@ -86,22 +86,27 @@ x86_64)
|
||||
# The toolchain in Debian 9 is too old to build mold, so we rebuild it
|
||||
# from source. We download source archives from official sites and build
|
||||
# them locally, rather than downloading pre-built binaries from somewhere
|
||||
# else, to avoid relying on unverifiable third-party binary blobs. Podman
|
||||
# caches the result of each RUN command, so rebuilding is done only once
|
||||
# per host.
|
||||
# else, to avoid relying on unverifiable third-party binary blobs. Each
|
||||
# archive is checked against the SHA-256 hash recorded below before it is
|
||||
# unpacked, so this git commit alone determines every input of the build.
|
||||
# A compromised network or mirror can only make the build fail, never
|
||||
# change its output. Podman caches the result of each RUN command, so
|
||||
# rebuilding is done only once per host.
|
||||
cat <<EOF | $image_build
|
||||
FROM mirror.gcr.io/library/debian:stretch@sha256:c5c5200ff1e9c73ffbf188b4a67eb1c91531b644856b4aefe86a58d2f0cb05be
|
||||
ENV DEBIAN_FRONTEND=noninteractive TZ=UTC
|
||||
RUN sed -i -e '/^deb/d' -e 's/^# deb /deb /g' /etc/apt/sources.list && \
|
||||
echo 'Acquire::Retries "10"; Acquire::http::timeout "10"; Acquire::Check-Valid-Until "false";' > /etc/apt/apt.conf.d/80-retries && \
|
||||
apt-get update && \
|
||||
apt-get install -y --no-install-recommends wget file make gcc g++ zlib1g-dev libssl-dev ca-certificates && \
|
||||
apt-get install -y --no-install-recommends wget xz-utils file make gcc g++ git zlib1g-dev libssl-dev ca-certificates && \
|
||||
rm -rf /var/lib/apt/lists
|
||||
|
||||
# Build CMake 3.27
|
||||
RUN mkdir /build && \
|
||||
cd /build && \
|
||||
wget -O- --progress=dot:mega https://cmake.org/files/v3.27/cmake-3.27.7.tar.gz | tar xzf - --strip-components=1 && \
|
||||
wget --progress=dot:mega https://cmake.org/files/v3.27/cmake-3.27.7.tar.gz && \
|
||||
echo '08f71a106036bf051f692760ef9558c0577c42ac39e96ba097e7662bd4158d8e cmake-3.27.7.tar.gz' | sha256sum -c && \
|
||||
tar xf cmake-3.27.7.tar.gz --strip-components=1 && \
|
||||
./bootstrap --parallel=\$(nproc) && \
|
||||
make -j\$(nproc) && \
|
||||
make install && \
|
||||
@@ -110,11 +115,19 @@ RUN mkdir /build && \
|
||||
# Build GCC 14
|
||||
RUN mkdir /build && \
|
||||
cd /build && \
|
||||
wget -O- --progress=dot:mega https://ftpmirror.gnu.org/gcc/gcc-14.2.0/gcc-14.2.0.tar.gz | tar xzf - --strip-components=1 && \
|
||||
wget --progress=dot:mega https://ftp.gnu.org/gnu/gcc/gcc-14.2.0/gcc-14.2.0.tar.xz && \
|
||||
echo 'a7b39bc69cbf9e25826c5a60ab26477001f7c08d85cec04bc0e29cabed6f3cc9 gcc-14.2.0.tar.xz' | sha256sum -c && \
|
||||
tar xf gcc-14.2.0.tar.xz --strip-components=1 && \
|
||||
mkdir gmp mpc mpfr && \
|
||||
wget -O- --progress=dot:mega https://ftpmirror.gnu.org/gmp/gmp-6.3.0.tar.gz | tar xzf - --strip-components=1 -C gmp && \
|
||||
wget -O- --progress=dot:mega https://ftpmirror.gnu.org/mpc/mpc-1.3.1.tar.gz | tar xzf - --strip-components=1 -C mpc && \
|
||||
wget -O- --progress=dot:mega https://ftpmirror.gnu.org/mpfr/mpfr-4.2.1.tar.gz | tar xzf - --strip-components=1 -C mpfr && \
|
||||
wget --progress=dot:mega https://ftp.gnu.org/gnu/gmp/gmp-6.3.0.tar.xz && \
|
||||
echo 'a3c2b80201b89e68616f4ad30bc66aee4927c3ce50e33929ca819d5c43538898 gmp-6.3.0.tar.xz' | sha256sum -c && \
|
||||
tar xf gmp-6.3.0.tar.xz --strip-components=1 -C gmp && \
|
||||
wget --progress=dot:mega https://ftp.gnu.org/gnu/mpc/mpc-1.3.1.tar.gz && \
|
||||
echo 'ab642492f5cf882b74aa0cb730cd410a81edcdbec895183ce930e706c1c759b8 mpc-1.3.1.tar.gz' | sha256sum -c && \
|
||||
tar xf mpc-1.3.1.tar.gz --strip-components=1 -C mpc && \
|
||||
wget --progress=dot:mega https://ftp.gnu.org/gnu/mpfr/mpfr-4.2.1.tar.xz && \
|
||||
echo '277807353a6726978996945af13e52829e3abd7a9a5b7fb2793894e18f1fcbb2 mpfr-4.2.1.tar.xz' | sha256sum -c && \
|
||||
tar xf mpfr-4.2.1.tar.xz --strip-components=1 -C mpfr && \
|
||||
./configure --prefix=/usr --enable-languages=c,c++ --disable-bootstrap --disable-multilib && \
|
||||
make -j\$(nproc) && \
|
||||
make install && \
|
||||
@@ -124,7 +137,9 @@ RUN mkdir /build && \
|
||||
# Build GNU binutils 2.43
|
||||
RUN mkdir /build && \
|
||||
cd /build && \
|
||||
wget -O- --progress=dot:mega https://ftpmirror.gnu.org/binutils/binutils-2.43.tar.gz | tar xzf - --strip-components=1 && \
|
||||
wget --progress=dot:mega https://ftp.gnu.org/gnu/binutils/binutils-2.43.tar.xz && \
|
||||
echo 'b53606f443ac8f01d1d5fc9c39497f2af322d99e14cea5c0b4b124d630379365 binutils-2.43.tar.xz' | sha256sum -c && \
|
||||
tar xf binutils-2.43.tar.xz --strip-components=1 && \
|
||||
./configure --prefix=/usr && \
|
||||
make -j\$(nproc) && \
|
||||
make install && \
|
||||
@@ -133,7 +148,9 @@ RUN mkdir /build && \
|
||||
# Build Python 3.12.7
|
||||
RUN mkdir /build && \
|
||||
cd /build && \
|
||||
wget -O- --progress=dot:mega https://www.python.org/ftp/python/3.12.7/Python-3.12.7.tgz | tar xzf - --strip-components=1 && \
|
||||
wget --progress=dot:mega https://www.python.org/ftp/python/3.12.7/Python-3.12.7.tar.xz && \
|
||||
echo '24887b92e2afd4a2ac602419ad4b596372f67ac9b077190f459aba390faf5550 Python-3.12.7.tar.xz' | sha256sum -c && \
|
||||
tar xf Python-3.12.7.tar.xz --strip-components=1 && \
|
||||
./configure && \
|
||||
make -j\$(nproc) && \
|
||||
make install && \
|
||||
@@ -142,7 +159,9 @@ RUN mkdir /build && \
|
||||
# Build LLVM 20
|
||||
RUN mkdir /build && \
|
||||
cd /build && \
|
||||
wget -O- --progress=dot:mega https://github.com/llvm/llvm-project/archive/refs/tags/llvmorg-20.1.3.tar.gz | tar xzf - --strip-components=1 && \
|
||||
wget --progress=dot:mega https://github.com/llvm/llvm-project/releases/download/llvmorg-20.1.3/llvm-project-20.1.3.src.tar.xz && \
|
||||
echo 'b6183c41281ee3f23da7fda790c6d4f5877aed103d1e759763b1008bdd0e2c50 llvm-project-20.1.3.src.tar.xz' | sha256sum -c && \
|
||||
tar xf llvm-project-20.1.3.src.tar.xz --strip-components=1 && \
|
||||
mkdir b && \
|
||||
cd b && \
|
||||
cmake -DCMAKE_BUILD_TYPE=Release -DLLVM_ENABLE_PROJECTS=clang ../llvm && \
|
||||
@@ -163,7 +182,7 @@ ENV DEBIAN_FRONTEND=noninteractive TZ=UTC
|
||||
RUN sed -i -e '/^deb/d' -e 's/^# deb /deb /g' /etc/apt/sources.list && \
|
||||
echo 'Acquire::Retries "10"; Acquire::http::timeout "10"; Acquire::Check-Valid-Until "false";' > /etc/apt/apt.conf.d/80-retries && \
|
||||
apt-get update && \
|
||||
apt-get install -y --no-install-recommends build-essential gcc-10 g++-10 clang-16 cmake && \
|
||||
apt-get install -y --no-install-recommends build-essential gcc-10 g++-10 clang-16 cmake git && \
|
||||
ln -sf /usr/bin/clang-16 /usr/bin/clang && \
|
||||
ln -sf /usr/bin/clang++-16 /usr/bin/clang++ && \
|
||||
rm -rf /var/lib/apt/lists
|
||||
@@ -176,7 +195,7 @@ ENV DEBIAN_FRONTEND=noninteractive TZ=UTC
|
||||
RUN sed -i -e '/^URIs/d' -e 's/^# http/URIs: http/' /etc/apt/sources.list.d/debian.sources && \
|
||||
echo 'Acquire::Retries "10"; Acquire::http::timeout "10"; Acquire::Check-Valid-Until "false";' > /etc/apt/apt.conf.d/80-retries && \
|
||||
apt-get update && \
|
||||
apt-get install -y --no-install-recommends build-essential gcc-14 g++-14 clang-18 cmake && \
|
||||
apt-get install -y --no-install-recommends build-essential gcc-14 g++-14 clang-18 cmake git && \
|
||||
ln -sf /usr/bin/clang-18 /usr/bin/clang && \
|
||||
ln -sf /usr/bin/clang++-18 /usr/bin/clang++ && \
|
||||
rm -rf /var/lib/apt/lists
|
||||
@@ -186,10 +205,10 @@ loongarch64)
|
||||
cat <<EOF | $image_build
|
||||
FROM mirror.gcr.io/loongarch64/debian:sid@sha256:0356df4e494bbb86bb469377a00789a5b42bbf67d5ff649a3f9721b745cbef77
|
||||
ENV DEBIAN_FRONTEND=noninteractive TZ=UTC
|
||||
RUN sed -i -e 's!http[^ ]*!http://snapshot.debian.org/archive/debian-ports/20250620T014755Z!g' /etc/apt/sources.list && \
|
||||
RUN echo 'deb http://deb.debian.org/debian sid main' > /etc/apt/sources.list && \
|
||||
echo 'Acquire::Retries "10"; Acquire::http::timeout "10"; Acquire::Check-Valid-Until "false";' > /etc/apt/apt.conf.d/80-retries && \
|
||||
apt-get update && \
|
||||
apt-get install -y --no-install-recommends build-essential gcc-14 g++-14 clang-19 cmake && \
|
||||
apt-get install -y --no-install-recommends build-essential gcc-14 g++-14 clang-19 cmake git && \
|
||||
ln -sf /usr/bin/clang-19 /usr/bin/clang && \
|
||||
ln -sf /usr/bin/clang++-19 /usr/bin/clang++ && \
|
||||
rm -rf /var/lib/apt/lists
|
||||
|
||||

@@ -1 +0,0 @@
|
||||
<svg version="1.1" viewBox="0.0 0.0 600.0 371.0" fill="none" stroke="none" stroke-linecap="square" stroke-miterlimit="10" width="600" height="371" xmlns:xlink="http://www.w3.org/1999/xlink" xmlns="http://www.w3.org/2000/svg"><path fill="#ffffff" d="M0 0L600.0 0L600.0 371.0L0 371.0L0 0Z" fill-rule="nonzero"/><path stroke="#333333" stroke-width="1.0" stroke-linecap="butt" d="M82.5 275.5L581.5 275.5" fill-rule="nonzero"/><path stroke="#cccccc" stroke-width="1.0" stroke-linecap="butt" d="M82.5 231.5L581.5 231.5" fill-rule="nonzero"/><path stroke="#cccccc" stroke-width="1.0" stroke-linecap="butt" d="M82.5 186.5L581.5 186.5" fill-rule="nonzero"/><path stroke="#cccccc" stroke-width="1.0" stroke-linecap="butt" d="M82.5 142.5L581.5 142.5" fill-rule="nonzero"/><path stroke="#cccccc" stroke-width="1.0" stroke-linecap="butt" d="M82.5 98.5L581.5 98.5" fill-rule="nonzero"/><path stroke="#cccccc" stroke-width="1.0" stroke-linecap="butt" d="M82.5 53.5L581.5 53.5" fill-rule="nonzero"/><clipPath id="id_0"><path d="M82.55 53.916668L581.45 53.916668L581.45 275.45L82.55 275.45L82.55 53.916668Z" clip-rule="nonzero"/></clipPath><path stroke="#000000" stroke-width="2.0" stroke-linecap="butt" stroke-opacity="0.0" clip-path="url(#id_0)" d="M158.0 275.0L136.0 275.0L136.0 229.0C136.0 227.89543 136.89543 227.0 138.0 227.0L156.0 227.0C157.10457 227.0 158.0 227.89543 158.0 229.0Z" fill-rule="nonzero"/><path fill="#4285f4" clip-path="url(#id_0)" d="M158.0 275.0L136.0 275.0L136.0 229.0C136.0 227.89543 136.89543 227.0 138.0 227.0L156.0 227.0C157.10457 227.0 158.0 227.89543 158.0 229.0Z" fill-rule="nonzero"/><path stroke="#000000" stroke-width="2.0" stroke-linecap="butt" stroke-opacity="0.0" clip-path="url(#id_0)" d="M307.0 275.0L285.0 275.0L285.0 91.0C285.0 89.89543 285.89542 89.0 287.0 89.0L305.0 89.0C306.10458 89.0 307.0 89.89543 307.0 91.0Z" fill-rule="nonzero"/><path fill="#4285f4" clip-path="url(#id_0)" d="M307.0 275.0L285.0 275.0L285.0 91.0C285.0 89.89543 285.89542 89.0 287.0 89.0L305.0 89.0C306.10458 89.0 307.0 89.89543 307.0 91.0Z" fill-rule="nonzero"/><path stroke="#000000" stroke-width="2.0" stroke-linecap="butt" stroke-opacity="0.0" clip-path="url(#id_0)" d="M182.0 275.0L160.0 275.0L160.0 244.0C160.0 242.89543 160.89543 242.0 162.0 242.0L180.0 242.0C181.10457 242.0 182.0 242.89543 182.0 244.0Z" fill-rule="nonzero"/><path fill="#ea4335" clip-path="url(#id_0)" d="M182.0 275.0L160.0 275.0L160.0 244.0C160.0 242.89543 160.89543 242.0 162.0 242.0L180.0 242.0C181.10457 242.0 182.0 242.89543 182.0 244.0Z" fill-rule="nonzero"/><path stroke="#000000" stroke-width="2.0" stroke-linecap="butt" stroke-opacity="0.0" clip-path="url(#id_0)" d="M331.0 275.0L309.0 275.0L309.0 131.0C309.0 129.89543 309.89542 129.0 311.0 129.0L329.0 129.0C330.10458 129.0 331.0 129.89543 331.0 131.0Z" fill-rule="nonzero"/><path fill="#ea4335" clip-path="url(#id_0)" d="M331.0 275.0L309.0 275.0L309.0 131.0C309.0 129.89543 309.89542 129.0 311.0 129.0L329.0 129.0C330.10458 129.0 331.0 129.89543 331.0 131.0Z" fill-rule="nonzero"/><path stroke="#000000" stroke-width="2.0" stroke-linecap="butt" stroke-opacity="0.0" clip-path="url(#id_0)" d="M480.0 275.0L458.0 275.0L458.0 156.0C458.0 154.89543 458.89542 154.0 460.0 154.0L478.0 154.0C479.10458 154.0 480.0 154.89543 480.0 156.0Z" fill-rule="nonzero"/><path fill="#ea4335" clip-path="url(#id_0)" d="M480.0 275.0L458.0 275.0L458.0 156.0C458.0 154.89543 458.89542 154.0 460.0 154.0L478.0 154.0C479.10458 154.0 480.0 154.89543 480.0 156.0Z" fill-rule="nonzero"/><path stroke="#000000" stroke-width="2.0" stroke-linecap="butt" stroke-opacity="0.0" clip-path="url(#id_0)" d="M206.0 275.0L184.0 275.0L184.0 270.0C184.0 268.89542 184.89543 268.0 186.0 268.0L204.0 268.0C205.10457 268.0 206.0 268.89542 206.0 270.0Z" fill-rule="nonzero"/><path fill="#fbbc04" clip-path="url(#id_0)" d="M206.0 275.0L184.0 275.0L184.0 270.0C184.0 268.89542 184.89543 268.0 186.0 268.0L204.0 268.0C205.10457 268.0 206.0 268.89542 206.0 270.0Z" fill-rule="nonzero"/><path stroke="#000000" stroke-width="2.0" stroke-linecap="butt" stroke-opacity="0.0" clip-path="url(#id_0)" d="M355.0 275.0L333.0 275.0L333.0 254.0C333.0 252.89543 333.89542 252.0 335.0 252.0L353.0 252.0C354.10458 252.0 355.0 252.89543 355.0 254.0Z" fill-rule="nonzero"/><path fill="#fbbc04" clip-path="url(#id_0)" d="M355.0 275.0L333.0 275.0L333.0 254.0C333.0 252.89543 333.89542 252.0 335.0 252.0L353.0 252.0C354.10458 252.0 355.0 252.89543 355.0 254.0Z" fill-rule="nonzero"/><path stroke="#000000" stroke-width="2.0" stroke-linecap="butt" stroke-opacity="0.0" clip-path="url(#id_0)" d="M504.0 275.0L482.0 275.0L482.0 250.0C482.0 248.89543 482.89542 248.0 484.0 248.0L502.0 248.0C503.10458 248.0 504.0 248.89543 504.0 250.0Z" fill-rule="nonzero"/><path fill="#fbbc04" clip-path="url(#id_0)" d="M504.0 275.0L482.0 275.0L482.0 250.0C482.0 248.89543 482.89542 248.0 484.0 248.0L502.0 248.0C503.10458 248.0 504.0 248.89543 504.0 250.0Z" fill-rule="nonzero"/><path stroke="#000000" stroke-width="2.0" stroke-linecap="butt" stroLine truncated
|
||||
|
Before Width: | Height: | Size: 99 KiB |

Binary file not shown.
|
Before Width: | Height: | Size: 596 KiB |
+11
-3
@@ -1,6 +1,6 @@
|
||||
.\" generated with Ronn-NG/v0.9.1
|
||||
.\" http://github.com/apjanke/ronn-ng/tree/0.9.1
|
||||
.TH "MOLD" "1" "May 2026" ""
|
||||
.TH "MOLD" "1" "August 2026" ""
|
||||
.SH "NAME"
|
||||
\fBmold\fR \- a modern linker
|
||||
.SH "SYNOPSIS"
|
||||
@@ -152,7 +152,9 @@ By default, the compiler always emits a landing pad at the beginning of each glo
|
||||
.IP
|
||||
If \fB\-\-rewrite\-endbr\fR is given, mold conducts a whole program analysis to identify functions whose addresses are actually taken and rewrites landing pads with no\-ops for non\-address\-taken functions, reducing the attack surface\.
|
||||
.IP
|
||||
This feature is currently available only on x86\-64\.
|
||||
This feature is currently available only on x86\-64 and arm64\.
|
||||
.IP
|
||||
On arm64, the landing pad is \fBbti c\fR\. Note that code compiled with \fB\-mbranch\-protection=standard\fR (BTI + pointer authentication) starts functions with \fBpaciasp\fR, which doubles as a landing pad, so there is no separate \fBbti c\fR to rewrite and this option has no effect on such code\.
|
||||
.SH "GNU\-COMPATIBLE OPTIONS"
|
||||
.TP
|
||||
\fB\-\-help\fR
|
||||
@@ -193,7 +195,10 @@ Omit \fB\.debug_*\fR sections from the output file\.
|
||||
Read linker script from \fIfile\fR\.
|
||||
.TP
|
||||
\fB\-X\fR, \fB\-\-discard\-locals\fR
|
||||
Discard temporary local symbols to reduce the sizes of the symbol table and the string table\. Temporary local symbols are local symbols starting with \fB\.L\fR\. Compilers usually generate such symbols for unnamed program elements such as string literals or floating\-point literals\.
|
||||
Discard temporary local symbols to reduce the sizes of the symbol table and the string table\. Temporary local symbols are local symbols starting with \fB\.L\fR\. Compilers usually generate such symbols for unnamed program elements such as string literals or floating\-point literals\. This is the default; use \fB\-\-discard\-none\fR to keep temporary local symbols\.
|
||||
.TP
|
||||
\fB\-\-discard\-none\fR
|
||||
Keep all local symbols in the symbol table, including temporary ones starting with \fB\.L\fR, except ones in mergeable sections\. This restores the default behavior of GNU ld\. \fBmold\fR and \fBld\.lld\fR discard temporary local symbols by default\.
|
||||
.TP
|
||||
\fB\-e\fR \fIsymbol\fR, \fB\-\-entry\fR=\fIsymbol\fR:
|
||||
|
||||
@@ -258,6 +263,9 @@ Alias for \fB\-\-section\-start=\.data=\fR\fIaddress\fR\.
|
||||
\fB\-\-Ttext\fR=\fIaddress\fR
|
||||
Alias for \fB\-\-section\-start=\.text=\fR\fIaddress\fR\.
|
||||
.TP
|
||||
\fB\-\-Ttext\-segment\fR=\fIaddress\fR
|
||||
Set the address of the first byte of the text segment\.
|
||||
.TP
|
||||
\fB\-\-allow\-multiple\-definition\fR
|
||||
Normally, the linker reports an error if there are more than one definition of a symbol\. This option changes the default behavior so that it doesn't report an error for duplicate definitions and instead use the first definition\.
|
||||
.TP
|
||||
|
||||
+17
-2
@@ -318,7 +318,12 @@ but as `-o magic`.
|
||||
landing pads with no-ops for non-address-taken functions, reducing the
|
||||
attack surface.
|
||||
|
||||
This feature is currently available only on x86-64.
|
||||
This feature is currently available only on x86-64 and arm64.
|
||||
|
||||
On arm64, the landing pad is `bti c`. Note that code compiled with
|
||||
`-mbranch-protection=standard` (BTI + pointer authentication) starts
|
||||
functions with `paciasp`, which doubles as a landing pad, so there is no
|
||||
separate `bti c` to rewrite and this option has no effect on such code.
|
||||
|
||||
## GNU-COMPATIBLE OPTIONS
|
||||
|
||||
@@ -375,7 +380,14 @@ but as `-o magic`.
|
||||
Discard temporary local symbols to reduce the sizes of the symbol table and
|
||||
the string table. Temporary local symbols are local symbols starting with
|
||||
`.L`. Compilers usually generate such symbols for unnamed program elements
|
||||
such as string literals or floating-point literals.
|
||||
such as string literals or floating-point literals. This is the default;
|
||||
use `--discard-none` to keep temporary local symbols.
|
||||
|
||||
* `--discard-none`:
|
||||
Keep all local symbols in the symbol table, including temporary ones
|
||||
starting with `.L`, except ones in mergeable sections. This restores the
|
||||
default behavior of GNU ld. `mold` and `ld.lld` discard temporary local
|
||||
symbols by default.
|
||||
|
||||
* `-e` _symbol_, `--entry`=_symbol_:
|
||||
|
||||
@@ -458,6 +470,9 @@ but as `-o magic`.
|
||||
* `--Ttext`=_address_:
|
||||
Alias for `--section-start=.text=`_address_.
|
||||
|
||||
* `--Ttext-segment`=_address_:
|
||||
Set the address of the first byte of the text segment.
|
||||
|
||||
* `--allow-multiple-definition`:
|
||||
Normally, the linker reports an error if there are more than one definition
|
||||
of a symbol. This option changes the default behavior so that it doesn't
|
||||
|
||||
+65
-51
@@ -26,20 +26,45 @@ bool AhoCorasick::can_handle(std::string_view pat) {
|
||||
pat.remove_prefix(1);
|
||||
if (pat.ends_with('*'))
|
||||
pat.remove_suffix(1);
|
||||
return pat.find_first_of("*?[") == pat.npos;
|
||||
return !pat.empty() && pat.find_first_of("*?[\\") == pat.npos;
|
||||
}
|
||||
|
||||
i32 AhoCorasick::find_child(i32 node, u8 ch) const {
|
||||
if (node == 0)
|
||||
return root_children[ch];
|
||||
|
||||
for (i32 i = nodes[node].first_child; i != -1; i = nodes[i].next_sibling)
|
||||
if (nodes[i].ch == ch)
|
||||
return i;
|
||||
return -1;
|
||||
}
|
||||
|
||||
i32 AhoCorasick::add_child(i32 node, u8 ch) {
|
||||
if (i32 child = find_child(node, ch); child != -1)
|
||||
return child;
|
||||
|
||||
i32 child = nodes.size();
|
||||
i32 sibling = nodes[node].first_child;
|
||||
nodes.emplace_back();
|
||||
nodes[child].next_sibling = sibling;
|
||||
nodes[child].ch = ch;
|
||||
nodes[node].first_child = child;
|
||||
|
||||
if (node == 0)
|
||||
root_children[ch] = child;
|
||||
return child;
|
||||
}
|
||||
|
||||
i64 AhoCorasick::find(std::string_view str) {
|
||||
if (nodes.empty())
|
||||
return -1;
|
||||
|
||||
i64 idx = 0;
|
||||
i32 idx = 0;
|
||||
i64 val = -1;
|
||||
|
||||
auto walk = [&](u8 c) {
|
||||
for (i64 j = idx; j != -1; j = nodes[j].suffix_link) {
|
||||
i64 child = nodes[j].children[c];
|
||||
if (child != -1) {
|
||||
for (i32 j = idx; j != -1; j = nodes[j].suffix_link) {
|
||||
if (i32 child = find_child(j, c); child != -1) {
|
||||
idx = child;
|
||||
val = std::max(val, nodes[child].value);
|
||||
return;
|
||||
@@ -49,25 +74,25 @@ i64 AhoCorasick::find(std::string_view str) {
|
||||
};
|
||||
|
||||
walk('\0');
|
||||
for (u8 c : str)
|
||||
for (u8 c : str) {
|
||||
walk(c);
|
||||
if (val == max_value)
|
||||
return val;
|
||||
}
|
||||
walk('\0');
|
||||
return val;
|
||||
}
|
||||
|
||||
bool AhoCorasick::add(std::string_view pat, i64 val) {
|
||||
assert(can_handle(pat));
|
||||
if (nodes.empty())
|
||||
nodes.resize(1);
|
||||
i64 idx = 0;
|
||||
max_value = std::max(max_value, val);
|
||||
if (nodes.empty()) {
|
||||
root_children.fill(-1);
|
||||
nodes.emplace_back();
|
||||
}
|
||||
i32 idx = 0;
|
||||
|
||||
auto walk = [&](u8 c) {
|
||||
if (nodes[idx].children[c] == -1) {
|
||||
nodes[idx].children[c] = nodes.size();
|
||||
nodes.resize(nodes.size() + 1);
|
||||
}
|
||||
idx = nodes[idx].children[c];
|
||||
};
|
||||
auto walk = [&](u8 c) { idx = add_child(idx, c); };
|
||||
|
||||
// We handle "foo" as if "\0foo\0", "*foo" as if "foo\0", "foo*" as
|
||||
// if "\0foo", and "*foo*" as if "foo". Aho-Corasick can do only
|
||||
@@ -88,45 +113,34 @@ bool AhoCorasick::add(std::string_view pat, i64 val) {
|
||||
void AhoCorasick::compile() {
|
||||
if (nodes.empty())
|
||||
return;
|
||||
fix_suffix_links(0);
|
||||
fix_values();
|
||||
}
|
||||
|
||||
void AhoCorasick::fix_suffix_links(i64 idx) {
|
||||
for (i64 i = 0; i < 256; i++) {
|
||||
i64 child = nodes[idx].children[i];
|
||||
if (child == -1)
|
||||
continue;
|
||||
// A failure link may refer to any node at the previous depth, so failure
|
||||
// links must be constructed breadth-first.
|
||||
std::queue<i32> queue;
|
||||
for (i32 child = nodes[0].first_child; child != -1;
|
||||
child = nodes[child].next_sibling) {
|
||||
nodes[child].suffix_link = 0;
|
||||
queue.push(child);
|
||||
}
|
||||
|
||||
i64 j = nodes[idx].suffix_link;
|
||||
for (; j != -1; j = nodes[j].suffix_link) {
|
||||
if (nodes[j].children[i] != -1) {
|
||||
nodes[child].suffix_link = j;
|
||||
break;
|
||||
}
|
||||
while (!queue.empty()) {
|
||||
i32 idx = queue.front();
|
||||
queue.pop();
|
||||
|
||||
for (i32 child = nodes[idx].first_child; child != -1;
|
||||
child = nodes[child].next_sibling) {
|
||||
i32 suffix = nodes[idx].suffix_link;
|
||||
while (suffix != 0 && find_child(suffix, nodes[child].ch) == -1)
|
||||
suffix = nodes[suffix].suffix_link;
|
||||
|
||||
if (i32 next = find_child(suffix, nodes[child].ch); next != -1)
|
||||
suffix = next;
|
||||
|
||||
nodes[child].suffix_link = suffix;
|
||||
nodes[child].value = std::max(nodes[child].value, nodes[suffix].value);
|
||||
queue.push(child);
|
||||
}
|
||||
if (j == -1)
|
||||
nodes[child].suffix_link = 0;
|
||||
fix_suffix_links(child);
|
||||
}
|
||||
}
|
||||
|
||||
void AhoCorasick::fix_values() {
|
||||
std::queue<i64> queue;
|
||||
queue.push(0);
|
||||
|
||||
do {
|
||||
i64 idx = queue.front();
|
||||
queue.pop();
|
||||
|
||||
for (i64 child : nodes[idx].children) {
|
||||
if (child != -1) {
|
||||
i64 suffix = nodes[child].suffix_link;
|
||||
nodes[child].value = std::max(nodes[child].value, nodes[suffix].value);
|
||||
queue.push(child);
|
||||
}
|
||||
}
|
||||
} while (!queue.empty());
|
||||
}
|
||||
|
||||
} // namespace mold
|
||||
+134
@@ -0,0 +1,134 @@
|
||||
#include "lib.h"
|
||||
|
||||
#ifdef _WIN32
|
||||
# include <windows.h>
|
||||
#endif
|
||||
|
||||
namespace mold {
|
||||
|
||||
static constexpr u32 BLOCK_SIZE = 1024 * 1024;
|
||||
static constexpr u32 BLOCK_ALIGNMENT = 64;
|
||||
static constexpr u32 MAX_LOCAL_ALLOC = BLOCK_SIZE / 4;
|
||||
static constexpr u32 NUM_ARENA_SLOTS = 10;
|
||||
|
||||
// Reserved address space is made accessible in chunks of this size.
|
||||
static constexpr u64 COMMIT_CHUNK = 64 * 1024 * 1024;
|
||||
|
||||
static std::atomic<u32> next_arena_slot;
|
||||
static thread_local u32 positions[NUM_ARENA_SLOTS];
|
||||
static thread_local u32 ends[NUM_ARENA_SLOTS];
|
||||
|
||||
[[noreturn]]
|
||||
static void memory_error(std::string_view action, u64 size) {
|
||||
std::cerr << "mold: cannot " << action << ' ' << size
|
||||
<< " bytes of virtual memory\n";
|
||||
std::exit(1);
|
||||
}
|
||||
|
||||
ArenaResource::ArenaResource() : arena_slot(next_arena_slot++) {
|
||||
assert(arena_slot < NUM_ARENA_SLOTS);
|
||||
|
||||
// Reserve address space without making it accessible. An inaccessible
|
||||
// mapping is not charged against the system's commit limit even where
|
||||
// overcommit is disabled, and fork() does not charge it either. Pages
|
||||
// are made accessible by commit() as the arena grows.
|
||||
#ifdef _WIN32
|
||||
data = (u8 *)VirtualAlloc(nullptr, (SIZE_T)SIZE, MEM_RESERVE, PAGE_NOACCESS);
|
||||
if (!data)
|
||||
memory_error("reserve", SIZE);
|
||||
#else
|
||||
data = (u8 *)mmap(nullptr, SIZE, PROT_NONE, MAP_ANONYMOUS | MAP_PRIVATE, -1, 0);
|
||||
if (data == MAP_FAILED)
|
||||
memory_error("reserve", SIZE);
|
||||
#endif
|
||||
|
||||
#ifdef MADV_HUGEPAGE
|
||||
// Large links fill the beginning of the arena densely. Transparent huge
|
||||
// pages reduce address-translation overhead without populating unused pages.
|
||||
madvise(data, SIZE, MADV_HUGEPAGE);
|
||||
#endif
|
||||
}
|
||||
|
||||
ArenaResource::~ArenaResource() {
|
||||
#ifdef _WIN32
|
||||
VirtualFree(data, 0, MEM_RELEASE);
|
||||
#else
|
||||
munmap(data, SIZE);
|
||||
#endif
|
||||
}
|
||||
|
||||
// Makes the reserved range up to `end` accessible. Memory is committed in
|
||||
// whole chunks so that the arena grows with few system calls.
|
||||
void ArenaResource::commit(u64 end) {
|
||||
std::scoped_lock lock(commit_mu);
|
||||
u64 cur = committed.load(std::memory_order_relaxed);
|
||||
if (end <= cur)
|
||||
return;
|
||||
|
||||
u64 next = align_to(end, COMMIT_CHUNK);
|
||||
#ifdef _WIN32
|
||||
if (!VirtualAlloc(data + cur, (SIZE_T)(next - cur), MEM_COMMIT, PAGE_READWRITE))
|
||||
memory_error("commit", next - cur);
|
||||
#else
|
||||
if (mprotect(data + cur, next - cur, PROT_READ | PROT_WRITE) == -1)
|
||||
memory_error("commit", next - cur);
|
||||
#endif
|
||||
committed.store(next, std::memory_order_release);
|
||||
}
|
||||
|
||||
void *ArenaResource::allocate(u64 size, u64 alignment) {
|
||||
assert(std::has_single_bit(alignment));
|
||||
|
||||
// ArenaPtr and base-relative indices both encode offsets in four-byte units.
|
||||
alignment = std::max<u64>(alignment, 4);
|
||||
|
||||
// Standard containers make many small allocations. Reserve them from a
|
||||
// thread-local block to avoid contending on the global bump pointer.
|
||||
if (size <= MAX_LOCAL_ALLOC && alignment <= BLOCK_ALIGNMENT) {
|
||||
// Offsets are from the beginning of the arena in four-byte units.
|
||||
u32 &pos = positions[arena_slot];
|
||||
u32 &end = ends[arena_slot];
|
||||
u32 size4 = align_to(size, 4) / 4;
|
||||
|
||||
if (pos) {
|
||||
u32 begin = align_to(pos, alignment / 4);
|
||||
if (begin <= end && size4 <= end - begin) {
|
||||
pos = begin + size4;
|
||||
return data + (u64)begin * 4;
|
||||
}
|
||||
}
|
||||
|
||||
u8 *begin = (u8 *)allocate_global(BLOCK_SIZE, BLOCK_ALIGNMENT);
|
||||
u32 begin4 = (begin - data) / 4;
|
||||
pos = begin4 + size4;
|
||||
end = begin4 + BLOCK_SIZE / 4;
|
||||
return begin;
|
||||
}
|
||||
|
||||
return allocate_global(size, alignment);
|
||||
}
|
||||
|
||||
void *ArenaResource::allocate_global(u64 size, u64 alignment) {
|
||||
u64 old = offset.load(std::memory_order_relaxed);
|
||||
u64 begin, end;
|
||||
|
||||
for (;;) {
|
||||
u64 padding = -old & (alignment - 1);
|
||||
if (old > SIZE || padding > SIZE - old || size > SIZE - old - padding) {
|
||||
std::cerr << "mold: cannot allocate more than " << SIZE
|
||||
<< " bytes for linker data structures on this host\n";
|
||||
std::exit(1);
|
||||
}
|
||||
|
||||
begin = old + padding;
|
||||
end = begin + size;
|
||||
if (offset.compare_exchange_weak(old, end, std::memory_order_relaxed))
|
||||
break;
|
||||
}
|
||||
|
||||
if (end > committed.load(std::memory_order_acquire))
|
||||
commit(end);
|
||||
return data + begin;
|
||||
}
|
||||
|
||||
} // namespace mold
|
||||
+15
-1
@@ -32,7 +32,21 @@ struct Atomic : std::atomic<T> {
|
||||
}
|
||||
|
||||
T exchange(T val) { return std::atomic<T>::exchange(val, relaxed); }
|
||||
T operator|=(T val) { return std::atomic<T>::fetch_or(val, relaxed); }
|
||||
|
||||
T fetch_or(T val, std::memory_order order = relaxed) {
|
||||
return std::atomic<T>::fetch_or(val, order);
|
||||
}
|
||||
|
||||
T fetch_and(T val, std::memory_order order = relaxed) {
|
||||
return std::atomic<T>::fetch_and(val, order);
|
||||
}
|
||||
|
||||
T operator|=(T val) {
|
||||
// Avoid exclusive cache-line ownership if all requested bits are set.
|
||||
T old = load();
|
||||
return (old & val) == val ? old : fetch_or(val);
|
||||
}
|
||||
|
||||
T operator++() { return std::atomic<T>::fetch_add(1, relaxed) + 1; }
|
||||
T operator--() { return std::atomic<T>::fetch_sub(1, relaxed) - 1; }
|
||||
T operator++(int) { return std::atomic<T>::fetch_add(1, relaxed); }
|
||||
|
||||
@@ -1,78 +0,0 @@
|
||||
#pragma once
|
||||
|
||||
#include "integers.h"
|
||||
|
||||
#include <cassert>
|
||||
#include <vector>
|
||||
|
||||
namespace mold {
|
||||
|
||||
class BitvectorProxy {
|
||||
public:
|
||||
BitvectorProxy(u64 &word, size_t pos)
|
||||
: word(word), mask(1ULL << pos) {}
|
||||
|
||||
BitvectorProxy &operator=(bool val) {
|
||||
if (val)
|
||||
word |= mask;
|
||||
else
|
||||
word &= ~mask;
|
||||
return *this;
|
||||
}
|
||||
|
||||
BitvectorProxy &operator=(const BitvectorProxy &other) {
|
||||
return *this = (bool)other;
|
||||
}
|
||||
|
||||
operator bool() const {
|
||||
return word & mask;
|
||||
}
|
||||
|
||||
private:
|
||||
u64 &word;
|
||||
u64 mask;
|
||||
};
|
||||
|
||||
class Bitvector {
|
||||
public:
|
||||
Bitvector() = default;
|
||||
Bitvector(i64 n) : size(n), words((n + 63) / 64) {}
|
||||
|
||||
void resize(i64 n) {
|
||||
words.clear();
|
||||
words.resize((n + 63) / 64);
|
||||
size = n;
|
||||
}
|
||||
|
||||
Bitvector &operator|=(const Bitvector &x) {
|
||||
assert(size == x.size);
|
||||
for (i64 i = 0; i < words.size(); i++)
|
||||
words[i] |= x.words[i];
|
||||
return *this;
|
||||
}
|
||||
|
||||
Bitvector &operator&=(const Bitvector &x) {
|
||||
assert(size == x.size);
|
||||
for (i64 i = 0; i < words.size(); i++)
|
||||
words[i] &= x.words[i];
|
||||
return *this;
|
||||
}
|
||||
|
||||
Bitvector &operator<<=(size_t n) {
|
||||
assert(n == 1);
|
||||
for (i64 i = words.size() - 1; i > 0; i--)
|
||||
words[i] = (words[i] << 1) | (words[i - 1] >> 63);
|
||||
words[0] <<= 1;
|
||||
return *this;
|
||||
}
|
||||
|
||||
BitvectorProxy operator[](size_t pos) {
|
||||
assert(pos < size);
|
||||
return {words[pos / 64], pos % 64};
|
||||
}
|
||||
|
||||
i64 size = 0;
|
||||
std::vector<u64> words;
|
||||
};
|
||||
|
||||
} // namespace mold
|
||||
@@ -2,6 +2,7 @@
|
||||
#define MOLD_LIBDIR "@CMAKE_INSTALL_FULL_LIBDIR@"
|
||||
#define MOLD_FIRST_TARGET @MOLD_FIRST_TARGET@
|
||||
|
||||
#cmakedefine01 HAVE_FALLOCATE
|
||||
#cmakedefine01 HAVE_MADVISE
|
||||
#cmakedefine01 HAVE_UNAME
|
||||
#cmakedefine01 MOLD_USE_MIMALLOC
|
||||
|
||||
@@ -0,0 +1,50 @@
|
||||
#!/usr/bin/env python3
|
||||
# Work around a deadlock in portage's binary package extraction.
|
||||
#
|
||||
# tar_stream_reader.close() joins its stdin-feeder thread and then waits
|
||||
# for the external decompressor to exit without draining the
|
||||
# decompressor's remaining stdout. tarfile stops reading at the tar
|
||||
# end-of-archive marker, so trailing archive padding is left in the
|
||||
# pipe. If that residue exceeds the pipe buffer, the decompressor
|
||||
# blocks writing forever and close() never returns, freezing the whole
|
||||
# emerge. Small pipe buffers make this reachable in practice: the
|
||||
# kernel shrinks new pipes to one page once a user exceeds
|
||||
# fs.pipe-user-pages-soft, which our 80 parallel containers do.
|
||||
#
|
||||
# The fix is to drain the decompressor's stdout to EOF before joining
|
||||
# and waiting. This script patches the installed gpkg.py at container
|
||||
# image build time and fails loudly if the code no longer matches, so
|
||||
# a portage upgrade that changes (or fixes) this code is noticed.
|
||||
|
||||
import sys
|
||||
import portage.gpkg
|
||||
|
||||
path = portage.gpkg.__file__
|
||||
src = open(path).read()
|
||||
|
||||
old = """ if self.proc is not None:
|
||||
self.thread.join()
|
||||
"""
|
||||
|
||||
new = """ if self.proc is not None:
|
||||
# Drain remaining decompressor output before joining and
|
||||
# waiting; otherwise the decompressor can block forever on
|
||||
# a full stdout pipe. Injected by mold's lib/gentoo-test.sh.
|
||||
try:
|
||||
while self.read_io.read(65536):
|
||||
pass
|
||||
except Exception:
|
||||
pass
|
||||
self.thread.join()
|
||||
"""
|
||||
|
||||
if src.count(old) != 1:
|
||||
sys.exit(f"gpkg workaround: expected pattern not found in {path}; "
|
||||
"portage changed, update lib/gentoo-gpkg-workaround.py")
|
||||
|
||||
with open(path, "w") as f:
|
||||
f.write(src.replace(old, new))
|
||||
|
||||
import py_compile
|
||||
py_compile.compile(path, doraise=True)
|
||||
print(f"gpkg deadlock workaround applied to {path}")
|
||||
+145
-28
@@ -2,10 +2,25 @@
|
||||
#
|
||||
# This test script takes a Gentoo package name and tries to build it
|
||||
# using mold in a Podman environment. We chose Gentoo Linux as a test
|
||||
# target, because its source-based package allows us to build programs
|
||||
# target, because its source-based packages allow us to build programs
|
||||
# locally and run their test suites without any hassle.
|
||||
#
|
||||
# You can get a complete list of Gentoo packages availalbe for testing
|
||||
# We first build a package with mold acting as /usr/bin/ld. Only if
|
||||
# that fails, we build the same package again with GNU ld to tell
|
||||
# whether the failure is mold's fault. The package's own test suite
|
||||
# runs in both cases; FEATURES=test is scoped to just the package
|
||||
# under test via package.env, because applying it to the entire
|
||||
# dependency graph makes a large fraction of the tree unresolvable.
|
||||
# Results are classified into three directories:
|
||||
#
|
||||
# success: the package built fine with mold (or, for a control
|
||||
# build, with GNU ld)
|
||||
# failure: the package built with GNU ld but not with mold, which
|
||||
# means it hit a mold bug
|
||||
# broken: the package didn't build even with GNU ld, so the
|
||||
# failure is not mold's fault
|
||||
#
|
||||
# You can get a complete list of Gentoo packages available for testing
|
||||
# with the following command:
|
||||
#
|
||||
# podman run --rm mold-gentoo emerge --color n -s '' | \
|
||||
@@ -20,50 +35,152 @@ fi
|
||||
|
||||
set -x
|
||||
|
||||
# Create a Podman image
|
||||
if ! podman image ls mold-gentoo | grep -q mold-gentoo; then
|
||||
set -e
|
||||
cat <<EOF | podman build -t mold-gentoo -
|
||||
FROM docker.io/gentoo/stage3
|
||||
RUN emerge-webrsync
|
||||
RUN echo 'USE="X ssl elogind -systemd corefonts truetype jpeg jpeg2k tiff zstd static-libs binary -perl"' >> /etc/portage/make.conf && \
|
||||
echo 'ACCEPT_KEYWORDS="~amd64"' >> /etc/portage/make.conf && \
|
||||
echo 'ACCEPT_LICENSE="* -@EULA"' >> /etc/portage/make.conf && \
|
||||
echo 'FEATURES="\${FEATURE} noclean nostrip ccache -ipc-sandbox -network-sandbox -pid-sandbox -sandbox"' >> /etc/portage/make.conf && \
|
||||
echo 'CCACHE_DIR="/ccache"' >> /etc/portage/make.conf && \
|
||||
FEATURES='getbinpkg binpkg-request-signature' emerge gdb lld llvm-core/clang vim emacs strace ccache xeyes dev-build/cmake dev-vcs/git && \
|
||||
rm -rf /var/tmp/portage
|
||||
EOF
|
||||
set +e
|
||||
# Test results are keyed by the commit hash embedded in the mold
|
||||
# binary, so refuse to run with a binary that doesn't have one.
|
||||
git_hash=$(./dist/mold --version | perl -ne '/\(([0-9a-f]{40})\b/ and print $1;')
|
||||
|
||||
if [ "$git_hash" = "" ]; then
|
||||
echo "Cannot get a git hash from ./dist/mold --version. Run this script at the mold source root, with dist/mold built from a git checkout."
|
||||
exit 1
|
||||
fi
|
||||
|
||||
git_hash=$(./dist/mold --version | perl -ne '/\((\w+)/; print $1;')
|
||||
cache_dir=/var/cache/mold-gentoo
|
||||
|
||||
# Create a Podman image. The lock prevents parallel invocations of
|
||||
# this script from racing to build the same image.
|
||||
#
|
||||
# A few notes on the container configuration:
|
||||
#
|
||||
# - We accept ~amd64 (testing) packages to test the newest version of
|
||||
# everything. The stage3 image is built for the stable profile, so
|
||||
# we update the whole system to ~amd64 once here; without that,
|
||||
# half-upgraded packages (e.g. perl and its virtuals) cause
|
||||
# unsolvable dependency conflicts in every container.
|
||||
#
|
||||
# - EMERGE_DEFAULT_OPTS makes emerge automatically apply the USE flag
|
||||
# adjustments it would otherwise just print and give up on. An
|
||||
# ephemeral container has no /etc/portage/package.use accumulated by
|
||||
# an administrator, so without this, thousands of packages are
|
||||
# unbuildable out of the box.
|
||||
#
|
||||
# - freetype and harfbuzz mutually depend on each other, so we
|
||||
# pre-install them with the documented two-step bootstrap. During
|
||||
# that step, pillow is built without truetype support to break
|
||||
# another dependency cycle (docutils -> pillow -> harfbuzz -> glib
|
||||
# -> docutils). The override is removed afterwards; once the cycle
|
||||
# participants are installed, they satisfy buildtime dependencies
|
||||
# and the cycle can no longer form.
|
||||
#
|
||||
# - qtbase's test suite requires icu (REQUIRED_USE), which autounmask
|
||||
# doesn't resolve on its own, hence the package.use entry.
|
||||
#
|
||||
# - gcc doesn't auto-select a newly installed major version, so we
|
||||
# switch to the newest slot explicitly after the world update.
|
||||
#
|
||||
# - lib/gentoo-gpkg-workaround.py patches a deadlock in portage's
|
||||
# binary package extraction. See that file for details.
|
||||
#
|
||||
# - static-libs is not in USE because it contradicts REQUIRED_USE
|
||||
# constraints in some packages (e.g. lvm2 forbids static-libs with
|
||||
# udev), and building static archives doesn't exercise the linker
|
||||
# anyway. Where a dependency genuinely needs it, emerge re-enables
|
||||
# it per package via autounmask.
|
||||
#
|
||||
# - /etc/portage/env/test.conf allows marking a single package for
|
||||
# FEATURES=test through package.env, which is how we scope test
|
||||
# suites to just the package under test.
|
||||
#
|
||||
# - The image build compiles a couple hundred packages from source,
|
||||
# because the Gentoo binhost only carries stable versions built with
|
||||
# default USE flags, which rarely match our ~amd64/USE combination.
|
||||
# To pay that cost only once, the build publishes what it compiles
|
||||
# to the GNU ld binary package pool and reuses it, so a rebuilt
|
||||
# image only compiles packages whose version has changed since the
|
||||
# last build. The toolchain step still uses the binhost, where our
|
||||
# configuration does match (e.g. clang). Since it verifies binhost
|
||||
# package signatures and our own pool is unsigned, it runs with a
|
||||
# private PKGDIR so the two never mix.
|
||||
(
|
||||
flock 9
|
||||
if ! podman image exists mold-gentoo; then
|
||||
cat <<EOF | podman build -v $cache_dir/distfiles:/var/cache/distfiles -v $cache_dir/ccache:/ccache -v $cache_dir/binpkgs-ld:/var/cache/binpkgs -v `pwd`/lib:/mold-lib:ro -t mold-gentoo - || exit 1
|
||||
FROM docker.io/gentoo/stage3
|
||||
RUN emerge-webrsync
|
||||
RUN echo 'USE="X ssl elogind -systemd truetype jpeg jpeg2k tiff zstd -perl udev lcms alsa"' >> /etc/portage/make.conf && \
|
||||
echo 'ACCEPT_KEYWORDS="~amd64"' >> /etc/portage/make.conf && \
|
||||
echo 'ACCEPT_LICENSE="* -@EULA"' >> /etc/portage/make.conf && \
|
||||
echo 'FEATURES="nostrip ccache binpkg-multi-instance -ipc-sandbox -network-sandbox -pid-sandbox -sandbox"' >> /etc/portage/make.conf && \
|
||||
echo 'CCACHE_DIR="/ccache"' >> /etc/portage/make.conf && \
|
||||
echo 'MAKEOPTS="-j$(nproc) --load-average=100"' >> /etc/portage/make.conf && \
|
||||
echo 'EMERGE_DEFAULT_OPTS="--autounmask-continue=y --autounmask-license=n --autounmask-backtrack=y --backtrack=100 --jobs=16 --load-average=100"' >> /etc/portage/make.conf && \
|
||||
mkdir -p /etc/portage/env /etc/portage/package.use && \
|
||||
echo 'FEATURES="test"' > /etc/portage/env/test.conf && \
|
||||
printf 'media-libs/freetype harfbuzz\ndev-qt/qtbase icu\n' > /etc/portage/package.use/mold && \
|
||||
echo 'dev-python/pillow -truetype' > /etc/portage/package.use/cycle-break && \
|
||||
FEATURES=buildpkg emerge --usepkg --update --deep --newuse @world && \
|
||||
gcc-config \$(gcc-config -l | tail -n 1 | awk '{print \$2}') && env-update && \
|
||||
USE=-harfbuzz FEATURES=buildpkg emerge --oneshot media-libs/freetype && \
|
||||
FEATURES=buildpkg emerge --usepkg --oneshot media-libs/freetype media-libs/harfbuzz && \
|
||||
rm /etc/portage/package.use/cycle-break && \
|
||||
PKGDIR=/var/tmp/binpkgs FEATURES='getbinpkg binpkg-request-signature' emerge gdb lld llvm-core/clang vim emacs strace ccache dev-build/cmake dev-vcs/git && \
|
||||
rm -rf /var/tmp/portage /var/tmp/binpkgs
|
||||
RUN python3 /mold-lib/gentoo-gpkg-workaround.py
|
||||
EOF
|
||||
fi
|
||||
) 9> /tmp/mold-gentoo-image.lock || exit 1
|
||||
|
||||
if [ "$package" = dev-libs/concurrencykit ]; then
|
||||
echo "Skipping known broken package: $package"
|
||||
exit 0
|
||||
fi
|
||||
|
||||
# Build a given package in Podman
|
||||
# Build a given package in Podman.
|
||||
#
|
||||
# Build artifacts are shared between containers through host
|
||||
# directories bind-mounted into every container:
|
||||
#
|
||||
# /var/cache/mold-gentoo/ccache: compiler cache
|
||||
# /var/cache/mold-gentoo/distfiles: source tarballs, so that each
|
||||
# distfile is downloaded only once across all containers and runs
|
||||
# /var/cache/mold-gentoo/binpkgs-{mold,ld}: binary packages, so that each
|
||||
# dependency is built only once instead of once per container that
|
||||
# needs it
|
||||
#
|
||||
# Every emerge runs with FEATURES=buildpkg to publish what it built to
|
||||
# the binary package pool, and dependencies are installed with
|
||||
# --usepkg from the pool when an exact version and USE match exists.
|
||||
# The package under test itself is always built from source. In the
|
||||
# mold run, dependencies are still linked with mold and their binaries
|
||||
# are still exercised by the test suites of everything built on top of
|
||||
# them; the pool just memoizes that work across containers. The mold
|
||||
# and GNU ld runs use separate pools so that a control build can never
|
||||
# install mold-linked binaries.
|
||||
cmd1='(cd /usr/bin; ln -sf /mold/dist/mold $(realpath ld))'
|
||||
cmd2="MAKEOPTS=-'j$(nproc) --load-average=100' emerge --onlydeps $package"
|
||||
cmd3="MAKEOPTS='-j$(nproc) --load-average=100' FEATURES=test emerge $package"
|
||||
cmd2="echo '$package test.conf' > /etc/portage/package.env"
|
||||
cmd3="FEATURES=buildpkg emerge --usepkg --onlydeps $package"
|
||||
cmd4="FEATURES=buildpkg emerge $package"
|
||||
filename=`echo "$package" | sed 's!/!_!g'`
|
||||
podman="podman run --rm --pids-limit=-1 --cap-add=SYS_PTRACE -v `pwd`:/mold:ro -v /var/cache/ccache-gentoo:/ccache mold-gentoo timeout -v -k 15s 3h"
|
||||
podman="podman run --rm --pids-limit=-1 --cap-add=SYS_PTRACE -v `pwd`:/mold:ro -v $cache_dir/ccache:/ccache -v $cache_dir/distfiles:/var/cache/distfiles"
|
||||
run="mold-gentoo timeout -v -k 15s 3h chrt --idle 0 nice -n 19 bash -c"
|
||||
dir=gentoo/$git_hash
|
||||
|
||||
mkdir -p "$dir"/success "$dir"/failure
|
||||
mkdir -p "$dir"/success "$dir"/failure "$dir"/broken
|
||||
|
||||
$podman chrt --idle 0 nice -n 19 bash -c "$cmd1 && $cmd2 && $cmd3" >& "$dir"/"$filename".mold
|
||||
# Build the package with mold. If this succeeds, we don't need a
|
||||
# control build.
|
||||
$podman -v $cache_dir/binpkgs-mold:/var/cache/binpkgs $run "$cmd1 && $cmd2 && $cmd3 && $cmd4" >& "$dir"/"$filename".mold
|
||||
if [ $? = 0 ]; then
|
||||
mv "$dir"/"$filename".mold "$dir"/success
|
||||
else
|
||||
mv "$dir"/"$filename".mold "$dir"/failure
|
||||
exit 0
|
||||
fi
|
||||
|
||||
$podman chrt --idle 0 nice -n 19 bash -c "$cmd2 && $cmd3" >& "$dir"/"$filename".ld
|
||||
# Build the package again with GNU ld to tell whether the failure is
|
||||
# mold's fault.
|
||||
$podman -v $cache_dir/binpkgs-ld:/var/cache/binpkgs $run "$cmd2 && $cmd3 && $cmd4" >& "$dir"/"$filename".ld
|
||||
if [ $? = 0 ]; then
|
||||
mv "$dir"/"$filename".mold "$dir"/failure
|
||||
mv "$dir"/"$filename".ld "$dir"/success
|
||||
else
|
||||
mv "$dir"/"$filename".ld "$dir"/failure
|
||||
mv "$dir"/"$filename".mold "$dir"/broken
|
||||
mv "$dir"/"$filename".ld "$dir"/broken
|
||||
fi
|
||||
+257
-146
@@ -1,94 +1,23 @@
|
||||
// This file implements a glob matcher that can run multiple glob patterns
|
||||
// against an input string. mold uses the glob matcher for symbol name
|
||||
// patterns in a version script or a dynamic list file. Since we may need to
|
||||
// match hundreds of glob patterns against millions of symbol names, the
|
||||
// speed of the matcher is very important.
|
||||
//
|
||||
// The pattern match implemented in this file is NFA-based, although the
|
||||
// cost of the function is O(n*m), where n is the number of NFA states and m
|
||||
// is the length of the input string. We do not use recursion or
|
||||
// backtracking, unlike a generic NFA-based regular expression matcher. This
|
||||
// is doable because glob patterns are very limited subsets of regexes.
|
||||
//
|
||||
// Here is the explanation of the algorithm. Observe that the only "tricky"
|
||||
// meta-character in a glob pattern is "*", which matches zero or more
|
||||
// characters. Other characters and meta-characters always match a single
|
||||
// input character. So the key of the algorithm is to handle "*" efficiently.
|
||||
//
|
||||
// We can represent a glob pattern "a*b*" with three NFA states: q_start, q1
|
||||
// and q_accept, with the following transition functions:
|
||||
//
|
||||
// δ(q_start, "a") = q1
|
||||
// δ(q1, <any character>) = q1
|
||||
// δ(q1, "b") = q_accept
|
||||
// δ(q_accept, <any character>) = q_accept
|
||||
//
|
||||
// We can construct such an NFA in a straightforward manner. We maintain NFA
|
||||
// states as a list, with the initial contents being the start state. Each
|
||||
// character except for "*" creates a new NFA state, adds a transition from
|
||||
// the last state in the list to the new one, and appends the new state at
|
||||
// the end of the list. "*" sets the "is_star" flag on the last NFA state.
|
||||
// The flag indicates that the state machine can remain in the state for any
|
||||
// input character.
|
||||
//
|
||||
// An NFA constructed this way doesn't have any complicated loops,
|
||||
// ε-transitions, or anything like that. Each state has only one incoming
|
||||
// edge. The only loops in the state transition are the self-loops on states
|
||||
// followed by a "*". Aside from that, the state machine progresses linearly
|
||||
// from the start state to the accept state.
|
||||
//
|
||||
// Each state of an NFA can be represented by a single bit. If a bit is 1,
|
||||
// the non-deterministic state machine is in that state. Otherwise, it's
|
||||
// not. Observe that a state with the "is_star" flag will continued to be 1
|
||||
// once it becomes 1, since the state machine can loop over the state on any
|
||||
// input character.
|
||||
//
|
||||
// With that observation, we can represent an NFA with a bit vector of N
|
||||
// bits, where N is the number of NFA states. For each input character, bit
|
||||
// M becomes 1 if
|
||||
//
|
||||
// - bit M-1 is 1 and there's a transition from state_{M-1} to state_M
|
||||
// with the given character, or
|
||||
// - bit M is 1 and state_M's "is_star" flag is 1.
|
||||
//
|
||||
// Initially, the 0th bit is 1 for the start state. At each step, the bits
|
||||
// propagate from least significant to most significant positions, at most
|
||||
// one bit at a time. If the most significant bit is 1 after the entire
|
||||
// input has been processed, the string matches.
|
||||
//
|
||||
// This propagation can be implemented with bitwise OR, bitwise AND, and a
|
||||
// one-bit bit shift on the bit vector. All these operations are very cheap.
|
||||
//
|
||||
// We can combine multiple glob matchers into a single matcher by simply
|
||||
// concatenating the bit vectors of their state machines.
|
||||
// This file implements the glob matcher used for symbol name patterns.
|
||||
// Exact, prefix and suffix patterns are matched directly, and simple
|
||||
// substring patterns are combined into an Aho-Corasick matcher. The
|
||||
// remaining patterns are matched with the non-recursive algorithm described
|
||||
// at https://research.swtch.com/glob. If there are many such patterns, a
|
||||
// bit-parallel NFA matches them together.
|
||||
|
||||
#include "lib.h"
|
||||
|
||||
#include <cstring>
|
||||
|
||||
namespace mold {
|
||||
|
||||
static std::vector<MultiGlob::State> parse_glob(std::string_view pat) {
|
||||
std::vector<MultiGlob::State> vec(1);
|
||||
std::optional<Glob::Pattern> Glob::Pattern::compile(std::string_view pat,
|
||||
i64 value) {
|
||||
std::vector<Token> tokens;
|
||||
|
||||
while (!pat.empty()) {
|
||||
u8 c = pat[0];
|
||||
pat = pat.substr(1);
|
||||
std::bitset<256> chars;
|
||||
pat.remove_prefix(1);
|
||||
|
||||
switch (c) {
|
||||
case '*':
|
||||
vec.back().is_star = true;
|
||||
continue;
|
||||
case '?':
|
||||
chars.set();
|
||||
break;
|
||||
case '\\':
|
||||
if (pat.empty())
|
||||
return {};
|
||||
chars[pat[0]] = true;
|
||||
pat = pat.substr(1);
|
||||
break;
|
||||
case '[': {
|
||||
// Here are a few bracket pattern examples:
|
||||
//
|
||||
@@ -100,23 +29,25 @@ static std::vector<MultiGlob::State> parse_glob(std::string_view pat) {
|
||||
// Both `!` and `^` are accepted as negation markers. `!` is the
|
||||
// POSIX/shell convention used by other linkers. `^` was mold's
|
||||
// original syntax and is kept for backward compatibility.
|
||||
tokens.emplace_back(BRACKET);
|
||||
std::bitset<256> &chars = tokens.back().chars;
|
||||
bool negate = false;
|
||||
bool closed = false;
|
||||
|
||||
if (!pat.empty() && (pat[0] == '!' || pat[0] == '^')) {
|
||||
negate = true;
|
||||
pat = pat.substr(1);
|
||||
pat.remove_prefix(1);
|
||||
}
|
||||
|
||||
while (!pat.empty()) {
|
||||
if (pat[0] == ']') {
|
||||
pat = pat.substr(1);
|
||||
pat.remove_prefix(1);
|
||||
closed = true;
|
||||
break;
|
||||
}
|
||||
|
||||
if (pat[0] == '\\') {
|
||||
pat = pat.substr(1);
|
||||
pat.remove_prefix(1);
|
||||
if (pat.empty())
|
||||
return {};
|
||||
}
|
||||
@@ -124,13 +55,13 @@ static std::vector<MultiGlob::State> parse_glob(std::string_view pat) {
|
||||
if (pat.size() >= 3 && pat[1] == '-') {
|
||||
u8 start = pat[0];
|
||||
u8 end = pat[2];
|
||||
pat = pat.substr(3);
|
||||
pat.remove_prefix(3);
|
||||
|
||||
if (end == '\\') {
|
||||
if (pat.empty())
|
||||
return {};
|
||||
end = pat[0];
|
||||
pat = pat.substr(1);
|
||||
pat.remove_prefix(1);
|
||||
}
|
||||
|
||||
if (end < start)
|
||||
@@ -139,8 +70,8 @@ static std::vector<MultiGlob::State> parse_glob(std::string_view pat) {
|
||||
for (i64 i = start; i <= end; i++)
|
||||
chars[i] = true;
|
||||
} else {
|
||||
chars[pat[0]] = true;
|
||||
pat = pat.substr(1);
|
||||
chars[(u8)pat[0]] = true;
|
||||
pat.remove_prefix(1);
|
||||
}
|
||||
}
|
||||
|
||||
@@ -151,106 +82,286 @@ static std::vector<MultiGlob::State> parse_glob(std::string_view pat) {
|
||||
chars.flip();
|
||||
break;
|
||||
}
|
||||
case '?':
|
||||
tokens.emplace_back(QUESTION);
|
||||
break;
|
||||
case '*':
|
||||
if (tokens.empty() || tokens.back().kind != STAR)
|
||||
tokens.emplace_back(STAR);
|
||||
break;
|
||||
case '\\':
|
||||
if (pat.empty())
|
||||
return {};
|
||||
if (tokens.empty() || tokens.back().kind != STRING)
|
||||
tokens.emplace_back(STRING);
|
||||
tokens.back().str += pat[0];
|
||||
pat.remove_prefix(1);
|
||||
break;
|
||||
default:
|
||||
chars[c] = true;
|
||||
if (tokens.empty() || tokens.back().kind != STRING)
|
||||
tokens.emplace_back(STRING);
|
||||
tokens.back().str += c;
|
||||
break;
|
||||
}
|
||||
|
||||
vec.push_back({chars, false});
|
||||
}
|
||||
return vec;
|
||||
return Pattern(std::move(tokens), value);
|
||||
}
|
||||
|
||||
// Instead of returning just a match/no match boolean value, our glob
|
||||
// matcher returns an integer value associated with each given pattern.
|
||||
// If multiple patterns match at the same time, the largest associated
|
||||
// value will be returned by find().
|
||||
bool MultiGlob::add(std::string_view pat, i64 val) {
|
||||
std::vector<State> vec = parse_glob(pat);
|
||||
if (vec.empty())
|
||||
bool Glob::Pattern::match(std::string_view str) const {
|
||||
if (!tokens.empty() && tokens.back().kind == STRING &&
|
||||
!str.ends_with(tokens.back().str))
|
||||
return false;
|
||||
patterns.push_back({std::move(vec), val});
|
||||
|
||||
i64 x = 0;
|
||||
i64 y = 0;
|
||||
i64 next_x = -1;
|
||||
i64 next_y = -1;
|
||||
|
||||
while (x < str.size() || y < tokens.size()) {
|
||||
if (y < tokens.size()) {
|
||||
const Token &tok = tokens[y];
|
||||
|
||||
switch (tok.kind) {
|
||||
case STRING:
|
||||
if (str.substr(x).starts_with(tok.str)) {
|
||||
x += tok.str.size();
|
||||
y++;
|
||||
continue;
|
||||
}
|
||||
break;
|
||||
case STAR:
|
||||
next_y = y++;
|
||||
next_x = x + 1;
|
||||
|
||||
if (y < tokens.size() && tokens[y].kind == STRING) {
|
||||
const std::string &s = tokens[y].str;
|
||||
i64 pos = str.find(s, x);
|
||||
if (pos == str.npos)
|
||||
return false;
|
||||
next_x = pos + 1;
|
||||
x = pos + s.size();
|
||||
y++;
|
||||
}
|
||||
continue;
|
||||
case QUESTION:
|
||||
if (x < str.size()) {
|
||||
x++;
|
||||
y++;
|
||||
continue;
|
||||
}
|
||||
break;
|
||||
case BRACKET:
|
||||
if (x < str.size() && tok.chars[(u8)str[x]]) {
|
||||
x++;
|
||||
y++;
|
||||
continue;
|
||||
}
|
||||
break;
|
||||
}
|
||||
}
|
||||
|
||||
// Retry the last star after assigning one more input byte to it.
|
||||
if (next_x != -1 && next_x <= str.size()) {
|
||||
x = next_x;
|
||||
y = next_y;
|
||||
continue;
|
||||
}
|
||||
return false;
|
||||
}
|
||||
return true;
|
||||
}
|
||||
|
||||
void MultiGlob::compile() {
|
||||
if (patterns.empty())
|
||||
return;
|
||||
void Glob::Nfa::compile(std::span<const Pattern> patterns) {
|
||||
i64 num_states = 0;
|
||||
|
||||
ranges::stable_sort(patterns, ranges::greater(), &GlobPattern::value);
|
||||
for (const Pattern &pattern : patterns) {
|
||||
num_states++;
|
||||
|
||||
std::vector<State> states;
|
||||
for (GlobPattern &p : patterns)
|
||||
append(states, p.states);
|
||||
i64 sz = states.size();
|
||||
|
||||
start_states.resize(sz);
|
||||
for (i64 pos = 0; GlobPattern &p : patterns) {
|
||||
start_states[pos] = true;
|
||||
pos += p.states.size();
|
||||
for (const Pattern::Token &tok : pattern.tokens) {
|
||||
if (tok.kind == Pattern::STRING)
|
||||
num_states += tok.str.size();
|
||||
else if (tok.kind != Pattern::STAR)
|
||||
num_states++;
|
||||
}
|
||||
}
|
||||
|
||||
star_mask.resize(sz);
|
||||
for (i64 i = 0; i < sz; i++)
|
||||
if (states[i].is_star)
|
||||
star_mask[i] = true;
|
||||
i64 num_words = (num_states + 63) / 64;
|
||||
initial_states.resize(num_words);
|
||||
star_states.resize(num_words);
|
||||
accept_states.resize(num_words);
|
||||
char_masks.resize(256 * num_words);
|
||||
values.resize(num_states, -1);
|
||||
|
||||
for (i64 i = 0; i < 256; i++) {
|
||||
char_mask[i].resize(sz);
|
||||
for (i64 j = 0; j < sz; j++)
|
||||
if (states[j].incoming_edge[i])
|
||||
char_mask[i][j] = true;
|
||||
auto set_bit = [](std::vector<u64> &vec, i64 pos) {
|
||||
vec[pos / 64] |= 1ULL << (pos % 64);
|
||||
};
|
||||
|
||||
i64 state = 0;
|
||||
|
||||
for (const Pattern &pattern : patterns) {
|
||||
set_bit(initial_states, state);
|
||||
|
||||
for (const Pattern::Token &tok : pattern.tokens) {
|
||||
switch (tok.kind) {
|
||||
case Pattern::STRING:
|
||||
for (u8 c : tok.str) {
|
||||
state++;
|
||||
char_masks[c * num_words + state / 64] |= 1ULL << (state % 64);
|
||||
}
|
||||
break;
|
||||
case Pattern::STAR:
|
||||
set_bit(star_states, state);
|
||||
break;
|
||||
case Pattern::QUESTION:
|
||||
state++;
|
||||
for (i64 c = 0; c < 256; c++)
|
||||
char_masks[c * num_words + state / 64] |= 1ULL << (state % 64);
|
||||
break;
|
||||
case Pattern::BRACKET:
|
||||
state++;
|
||||
for (i64 c = 0; c < 256; c++)
|
||||
if (tok.chars[c])
|
||||
char_masks[c * num_words + state / 64] |= 1ULL << (state % 64);
|
||||
break;
|
||||
}
|
||||
}
|
||||
|
||||
set_bit(accept_states, state);
|
||||
values[state] = pattern.value;
|
||||
state++;
|
||||
}
|
||||
}
|
||||
|
||||
i64 MultiGlob::find(std::string_view str) {
|
||||
if (patterns.empty())
|
||||
return -1;
|
||||
i64 Glob::Nfa::match(std::string_view str) const {
|
||||
static thread_local std::vector<u64> states;
|
||||
states.assign(initial_states.begin(), initial_states.end());
|
||||
|
||||
Bitvector bits = start_states;
|
||||
Bitvector tmp;
|
||||
i64 num_words = states.size();
|
||||
|
||||
for (u8 c : str) {
|
||||
// This is equivalent to
|
||||
//
|
||||
// bits = (bits & star_mask) | ((bits << 1) & char_mask[c])
|
||||
//
|
||||
// but we update the existing objects in place to avoid allocating
|
||||
// temporary objects.
|
||||
tmp = bits;
|
||||
tmp &= star_mask;
|
||||
bits <<= 1;
|
||||
bits &= char_mask[c];
|
||||
bits |= tmp;
|
||||
const u64 *mask = char_masks.data() + c * num_words;
|
||||
u64 carry = 0;
|
||||
|
||||
for (i64 i = 0; i < num_words; i++) {
|
||||
u64 old = states[i];
|
||||
u64 next = (old << 1) | carry;
|
||||
states[i] = (old & star_states[i]) | (next & mask[i]);
|
||||
carry = old >> 63;
|
||||
}
|
||||
}
|
||||
|
||||
for (i64 pos = 0; GlobPattern &p : patterns) {
|
||||
pos += p.states.size();
|
||||
if (bits[pos - 1])
|
||||
return p.value;
|
||||
i64 value = -1;
|
||||
|
||||
for (i64 i = 0; i < num_words; i++) {
|
||||
u64 word = states[i] & accept_states[i];
|
||||
|
||||
while (word) {
|
||||
i64 bit = std::countr_zero(word);
|
||||
value = std::max(value, values[i * 64 + bit]);
|
||||
word &= word - 1;
|
||||
}
|
||||
}
|
||||
return -1;
|
||||
return value;
|
||||
}
|
||||
|
||||
static bool is_literal(std::string_view pat) {
|
||||
return pat.find_first_of("*?[\\") == pat.npos;
|
||||
}
|
||||
|
||||
bool Glob::add(std::string_view pat, i64 val) {
|
||||
assert(val >= 0);
|
||||
assert(!is_compiled);
|
||||
is_empty = false;
|
||||
max_value = std::max(max_value, val);
|
||||
|
||||
// Match-all, exact, prefix and suffix patterns are handled with
|
||||
// plain string comparisons instead of the matchers below, which
|
||||
// have to scan the entire input string on every query.
|
||||
if (pat == "*") {
|
||||
match_all = std::max(match_all, val);
|
||||
return true;
|
||||
}
|
||||
|
||||
if (is_literal(pat)) {
|
||||
exacts.push_back({std::string(pat), val});
|
||||
return true;
|
||||
}
|
||||
|
||||
if (pat.ends_with('*') && is_literal(pat.substr(0, pat.size() - 1))) {
|
||||
prefixes.push_back({std::string(pat.substr(0, pat.size() - 1)), val});
|
||||
return true;
|
||||
}
|
||||
|
||||
if (pat.starts_with('*') && is_literal(pat.substr(1))) {
|
||||
suffixes.push_back({std::string(pat.substr(1)), val});
|
||||
return true;
|
||||
}
|
||||
|
||||
// If the pattern requires only a single substring search, the
|
||||
// Aho-Corasick algorithm is even faster than our glob matcher.
|
||||
if (aho_corasick.can_handle(pat))
|
||||
return aho_corasick.add(pat, val);
|
||||
return multi_glob.add(pat, val);
|
||||
|
||||
if (std::optional<Pattern> pattern = Pattern::compile(pat, val)) {
|
||||
patterns.push_back(std::move(*pattern));
|
||||
return true;
|
||||
}
|
||||
return false;
|
||||
}
|
||||
|
||||
i64 Glob::find(std::string_view str) {
|
||||
std::call_once(once, [&] {
|
||||
multi_glob.compile();
|
||||
// If the same name was added more than once, keep only the entry
|
||||
// with the largest value, as find() returns the largest match.
|
||||
// Sorting by (name, negated value) places that entry first in
|
||||
// each run of duplicates, which is the one unique() keeps.
|
||||
ranges::sort(exacts, {}, [](const LiteralPattern &p) {
|
||||
return std::pair<std::string_view, i64>(p.pat, -p.value);
|
||||
});
|
||||
|
||||
auto dup = ranges::unique(exacts, {}, &LiteralPattern::pat);
|
||||
exacts.erase(dup.begin(), dup.end());
|
||||
|
||||
if (patterns.size() >= 64) {
|
||||
nfa.compile(patterns);
|
||||
patterns.clear();
|
||||
}
|
||||
|
||||
aho_corasick.compile();
|
||||
is_compiled = true;
|
||||
});
|
||||
|
||||
return std::max(multi_glob.find(str), aho_corasick.find(str));
|
||||
i64 val = match_all;
|
||||
if (val == max_value)
|
||||
return val;
|
||||
|
||||
auto it = ranges::lower_bound(exacts, str, {}, &LiteralPattern::pat);
|
||||
if (it != exacts.end() && it->pat == str)
|
||||
val = std::max(val, it->value);
|
||||
|
||||
for (const LiteralPattern &p : prefixes)
|
||||
if (val < p.value && str.starts_with(p.pat))
|
||||
val = p.value;
|
||||
|
||||
for (const LiteralPattern &p : suffixes)
|
||||
if (val < p.value && str.ends_with(p.pat))
|
||||
val = p.value;
|
||||
|
||||
if (val == max_value)
|
||||
return val;
|
||||
|
||||
val = std::max(val, aho_corasick.find(str));
|
||||
if (val == max_value)
|
||||
return val;
|
||||
|
||||
if (!nfa.empty())
|
||||
val = std::max(val, nfa.match(str));
|
||||
|
||||
for (const Pattern &p : patterns)
|
||||
if (val < p.value && p.match(str))
|
||||
val = p.value;
|
||||
|
||||
return val;
|
||||
}
|
||||
|
||||
} // namespace mold
|
||||
@@ -11,6 +11,11 @@
|
||||
namespace mold {
|
||||
|
||||
i64 HyperLogLog::get_cardinality() const {
|
||||
u8 buckets[NBUCKETS] = {};
|
||||
for (const Sketch &sketch : sketches)
|
||||
for (i64 i = 0; i < NBUCKETS; i++)
|
||||
buckets[i] = std::max(buckets[i], sketch.buckets[i]);
|
||||
|
||||
double z = 0;
|
||||
for (i64 val : buckets)
|
||||
z += std::ldexp(1.0, -val);
|
||||
|
||||
+6
-6
@@ -59,15 +59,15 @@ public:
|
||||
}
|
||||
|
||||
operator T() const {
|
||||
if (size == 3) {
|
||||
if (is_le)
|
||||
if constexpr (size == 3) {
|
||||
if constexpr (is_le)
|
||||
return buf[2] << 16 | buf[1] << 8 | buf[0];
|
||||
return buf[0] << 16 | buf[1] << 8 | buf[2];
|
||||
} else {
|
||||
T v;
|
||||
memcpy(&v, buf, size);
|
||||
return is_native ? v : bswap(v);
|
||||
}
|
||||
|
||||
T v;
|
||||
memcpy(&v, buf, size);
|
||||
return is_native ? v : bswap(v);
|
||||
}
|
||||
|
||||
Integer &operator=(T v) { new (this) Integer(v); return *this; }
|
||||
|
||||
@@ -2,8 +2,8 @@
|
||||
|
||||
#include "atomics.h"
|
||||
#include "integers.h"
|
||||
#include "bitvector.h"
|
||||
|
||||
#include <algorithm>
|
||||
#include <array>
|
||||
#include <atomic>
|
||||
#include <bit>
|
||||
@@ -14,7 +14,9 @@
|
||||
#include <cstring>
|
||||
#include <fcntl.h>
|
||||
#include <filesystem>
|
||||
#include <functional>
|
||||
#include <iostream>
|
||||
#include <memory>
|
||||
#include <mutex>
|
||||
#include <optional>
|
||||
#include <span>
|
||||
@@ -23,9 +25,12 @@
|
||||
#include <string_view>
|
||||
#include <sys/stat.h>
|
||||
#include <sys/types.h>
|
||||
#include <tbb/blocked_range.h>
|
||||
#include <tbb/concurrent_vector.h>
|
||||
#include <tbb/enumerable_thread_specific.h>
|
||||
#include <tbb/parallel_for.h>
|
||||
#include <tbb/parallel_reduce.h>
|
||||
#include <tbb/parallel_scan.h>
|
||||
#include <vector>
|
||||
|
||||
#ifdef _WIN32
|
||||
@@ -69,6 +74,57 @@ inline u64 combine_hash(u64 a, u64 b) {
|
||||
return a ^ (b + 0x9e3779b9 + (a << 6) + (a >> 2));
|
||||
}
|
||||
|
||||
// TaggedPtr stores one of several pointer types and uses the low pointer bits
|
||||
// to record which type it contains.
|
||||
template <typename... Ts>
|
||||
class TaggedPtr {
|
||||
public:
|
||||
static_assert(sizeof...(Ts) > 0);
|
||||
|
||||
TaggedPtr() = default;
|
||||
|
||||
template <typename T> requires (std::is_same_v<T, Ts> || ...)
|
||||
TaggedPtr(T *ptr) {
|
||||
*this = ptr;
|
||||
}
|
||||
|
||||
template <typename T> requires (std::is_same_v<T, Ts> || ...)
|
||||
TaggedPtr &operator=(T *ptr) {
|
||||
static_assert(alignof(T) >= 1ULL << TAG_BITS);
|
||||
value = (uintptr_t)ptr;
|
||||
if (ptr)
|
||||
value |= get_tag<T>();
|
||||
return *this;
|
||||
}
|
||||
|
||||
TaggedPtr &operator=(std::nullptr_t) {
|
||||
value = 0;
|
||||
return *this;
|
||||
}
|
||||
|
||||
template <typename T> requires (std::is_same_v<T, Ts> || ...)
|
||||
T *get() const {
|
||||
if (!value || (value & TAG_MASK) != get_tag<T>())
|
||||
return nullptr;
|
||||
return (T *)(value & ~TAG_MASK);
|
||||
}
|
||||
|
||||
private:
|
||||
template <typename T>
|
||||
static consteval uintptr_t get_tag() {
|
||||
bool matches[] = {std::is_same_v<T, Ts>...};
|
||||
for (i64 i = 0; i < sizeof...(Ts); i++)
|
||||
if (matches[i])
|
||||
return i;
|
||||
return 0;
|
||||
}
|
||||
|
||||
static constexpr i64 TAG_BITS = std::bit_width((u64)sizeof...(Ts) - 1);
|
||||
static constexpr uintptr_t TAG_MASK = (1ULL << TAG_BITS) - 1;
|
||||
|
||||
uintptr_t value = 0;
|
||||
};
|
||||
|
||||
//
|
||||
// perf.cc
|
||||
//
|
||||
@@ -164,6 +220,41 @@ inline u64 bit_ceil(u64 val) {
|
||||
return 1LL << (64 - std::countl_zero(val));
|
||||
}
|
||||
|
||||
// ExactArray owns a fixed-size array without value-initializing trivial
|
||||
// elements that the caller is about to overwrite.
|
||||
template <typename T>
|
||||
class ExactArray {
|
||||
public:
|
||||
ExactArray() = default;
|
||||
|
||||
explicit ExactArray(i64 sz)
|
||||
: ptr(new T[sz]), size_(sz) {}
|
||||
|
||||
T &operator[](i64 i) {
|
||||
return ptr[i];
|
||||
}
|
||||
|
||||
const T &operator[](i64 i) const {
|
||||
return ptr[i];
|
||||
}
|
||||
|
||||
T *data() {
|
||||
return ptr.get();
|
||||
}
|
||||
|
||||
const T *data() const {
|
||||
return ptr.get();
|
||||
}
|
||||
|
||||
i64 size() const {
|
||||
return size_;
|
||||
}
|
||||
|
||||
private:
|
||||
std::unique_ptr<T[]> ptr;
|
||||
i64 size_ = 0;
|
||||
};
|
||||
|
||||
inline u64 align_to(u64 val, u64 align) {
|
||||
if (align == 0)
|
||||
return val;
|
||||
@@ -246,6 +337,60 @@ inline void write_vector(void *buf, const std::vector<T> &vec) {
|
||||
memcpy(buf, vec.data(), vec.size() * sizeof(T));
|
||||
}
|
||||
|
||||
// Return the suffix that doesn't satisfy pred, preserving both groups' order.
|
||||
// A prefix sum gives each element a destination without a serial merge.
|
||||
template <typename T, typename Pred>
|
||||
std::span<T> parallel_stable_partition(std::span<T> span, Pred pred) {
|
||||
if (span.size() <= 16384) {
|
||||
auto tail = ranges::stable_partition(span, pred);
|
||||
return {tail.begin(), tail.end()};
|
||||
}
|
||||
|
||||
tbb::blocked_range<i64> range(0, span.size(), 16384);
|
||||
ExactArray<u8> matches(span.size());
|
||||
i64 num_matches = tbb::parallel_reduce(range, (i64)0,
|
||||
[&](const auto &r, i64 count) {
|
||||
for (i64 i = r.begin(); i < r.end(); i++) {
|
||||
matches[i] = bool(pred(span[i]));
|
||||
count += matches[i];
|
||||
}
|
||||
return count;
|
||||
}, std::plus());
|
||||
|
||||
if (num_matches == 0 || num_matches == span.size())
|
||||
return span.subspan(num_matches);
|
||||
|
||||
ExactArray<T> buf(span.size());
|
||||
tbb::parallel_scan(range, (i64)0,
|
||||
[&](const auto &r, i64 count, bool is_final) {
|
||||
for (i64 i = r.begin(); i < r.end(); i++) {
|
||||
if (is_final) {
|
||||
// count matches and i - count non-matches precede this element.
|
||||
i64 dst = matches[i] ? count : num_matches + i - count;
|
||||
buf[dst] = std::move(span[i]);
|
||||
}
|
||||
count += matches[i];
|
||||
}
|
||||
return count;
|
||||
}, std::plus());
|
||||
|
||||
tbb::parallel_for(range, [&](const auto &r) {
|
||||
std::move(buf.data() + r.begin(), buf.data() + r.end(),
|
||||
span.begin() + r.begin());
|
||||
});
|
||||
return span.subspan(num_matches);
|
||||
}
|
||||
|
||||
inline void parallel_memcpy(void *dst, const void *src, i64 size) {
|
||||
constexpr i64 BLOCK_SIZE = 2 * 1024 * 1024;
|
||||
|
||||
tbb::parallel_for(tbb::blocked_range<i64>(0, size, BLOCK_SIZE),
|
||||
[&](const tbb::blocked_range<i64> &range) {
|
||||
memcpy((u8 *)dst + range.begin(),
|
||||
(const u8 *)src + range.begin(), range.size());
|
||||
});
|
||||
}
|
||||
|
||||
inline void encode_uleb(std::vector<u8> &vec, u64 val) {
|
||||
do {
|
||||
u8 byte = val & 0x7f;
|
||||
@@ -325,13 +470,6 @@ inline u64 read_uleb(std::string_view str) {
|
||||
return read_uleb(&tmp);
|
||||
}
|
||||
|
||||
inline i64 uleb_size(u64 val) {
|
||||
for (int i = 1; i < 9; i++)
|
||||
if (val < (1LL << (7 * i)))
|
||||
return i;
|
||||
return 9;
|
||||
}
|
||||
|
||||
inline void overwrite_uleb(u8 *loc, u64 val) {
|
||||
while (*loc & 0b1000'0000) {
|
||||
*loc++ = 0b1000'0000 | (val & 0b0111'1111);
|
||||
@@ -395,68 +533,37 @@ public:
|
||||
this->nbuckets = std::max<i64>(MIN_NBUCKETS, bit_ceil(nbuckets));
|
||||
i64 bufsize = sizeof(Entry) * this->nbuckets;
|
||||
|
||||
// Allocate a zero-initialized buffer. mmap() is faster than
|
||||
// malloc()+memset(), and MAP_POPULATE pre-faults pages here to
|
||||
// avoid CoW faults and TLB shootdowns under concurrent inserts.
|
||||
// Allocate a zero-initialized buffer. mmap is faster than
|
||||
// malloc + memset.
|
||||
#ifdef _WIN32
|
||||
entries = (Entry *)_aligned_malloc(bufsize, alignof(Entry));
|
||||
memset((void *)entries, 0, bufsize);
|
||||
#elif MAP_POPULATE
|
||||
entries = (Entry *)mmap(nullptr, bufsize, PROT_READ | PROT_WRITE,
|
||||
MAP_ANONYMOUS | MAP_PRIVATE | MAP_POPULATE, -1, 0);
|
||||
#else
|
||||
entries = (Entry *)mmap(nullptr, bufsize, PROT_READ | PROT_WRITE,
|
||||
MAP_ANONYMOUS | MAP_PRIVATE, -1, 0);
|
||||
#endif
|
||||
|
||||
#ifdef MADV_HUGEPAGE
|
||||
madvise((void *)entries, bufsize, MADV_HUGEPAGE);
|
||||
#endif
|
||||
}
|
||||
|
||||
std::pair<T *, bool> insert(std::string_view key, u64 hash, const T &val) {
|
||||
assert(has_single_bit(nbuckets));
|
||||
return insert_entry(key.data(), hash, val,
|
||||
[&](const char *ptr, u32 len) {
|
||||
return key == std::string_view(ptr, len);
|
||||
},
|
||||
[&](T &) { return (u32)key.size(); });
|
||||
}
|
||||
|
||||
u64 begin = hash & (nbuckets - 1);
|
||||
u64 mask = nbuckets / NUM_SHARDS - 1;
|
||||
|
||||
for (i64 i = 0; i < MAX_RETRY; i++) {
|
||||
u64 idx = (begin & ~mask) | ((begin + i) & mask);
|
||||
Entry &ent = entries[idx];
|
||||
|
||||
// It seems avoiding compare-and-swap is faster overall at least
|
||||
// on my Zen4 machine, so do it.
|
||||
if (const char *ptr = ent.key.load(std::memory_order_acquire);
|
||||
ptr != nullptr && ptr != (char *)-1) {
|
||||
if (key == std::string_view(ptr, ent.keylen))
|
||||
return {&ent.value, false};
|
||||
continue;
|
||||
}
|
||||
|
||||
// Otherwise, use CAS to atomically claim the ownership of the slot.
|
||||
const char *ptr = nullptr;
|
||||
bool claimed = ent.key.compare_exchange_strong(ptr, (char *)-1,
|
||||
std::memory_order_acquire);
|
||||
|
||||
// If we successfully claimed the ownership of the slot,
|
||||
// copy values to it.
|
||||
if (claimed) {
|
||||
new (&ent.value) T(val);
|
||||
ent.keylen = key.size();
|
||||
ent.key.store(key.data(), std::memory_order_release);
|
||||
return {&ent.value, true};
|
||||
}
|
||||
|
||||
// If someone is copying values to the slot, do busy wait.
|
||||
while (ptr == (char *)-1) {
|
||||
pause();
|
||||
ptr = ent.key.load(std::memory_order_acquire);
|
||||
}
|
||||
|
||||
// If the same key is already present, this is the slot we are
|
||||
// looking for.
|
||||
if (key == std::string_view(ptr, ent.keylen))
|
||||
return {&ent.value, false};
|
||||
}
|
||||
|
||||
std::cerr << "ConcurrentMap is full\n";
|
||||
abort();
|
||||
std::pair<T *, bool> insert_cstr(const char *key, u64 hash, const T &val,
|
||||
auto initialize) {
|
||||
// This variant avoids storing a length alongside every caller-side key.
|
||||
// Only a newly inserted key needs its length computed by `initialize`.
|
||||
return insert_entry(
|
||||
key, hash, val,
|
||||
[&](const char *ptr, u32) { return !strcmp(key, ptr); },
|
||||
[&](T &value) { return initialize(value, key); });
|
||||
}
|
||||
|
||||
i64 get_idx(T *value) const {
|
||||
@@ -464,6 +571,16 @@ public:
|
||||
return (Entry *)addr - entries;
|
||||
}
|
||||
|
||||
// Prefetch the bucket where a key with the given hash would be
|
||||
// probed first. Useful when a caller knows the hashes of upcoming
|
||||
// insertions, as probes into a large table miss the cache almost
|
||||
// every time.
|
||||
void prefetch(u64 hash) const {
|
||||
#ifdef __GNUC__
|
||||
__builtin_prefetch(entries + (hash & (nbuckets - 1)));
|
||||
#endif
|
||||
}
|
||||
|
||||
// Return a list of map entries sorted in a deterministic order.
|
||||
std::vector<Entry *> get_sorted_entries(i64 shard_idx) {
|
||||
if (nbuckets == 0)
|
||||
@@ -514,12 +631,435 @@ public:
|
||||
return flatten(vec);
|
||||
}
|
||||
|
||||
static constexpr i64 MIN_NBUCKETS = 4096;
|
||||
static constexpr i64 NUM_SHARDS = 16;
|
||||
// MIN_NBUCKETS is chosen so that even the smallest map has
|
||||
// MAX_RETRY buckets per shard; probing is confined to a shard, and
|
||||
// a probe that visits MAX_RETRY distinct occupied slots aborts.
|
||||
static constexpr i64 MIN_NBUCKETS = 16384;
|
||||
static constexpr i64 NUM_SHARDS = 64;
|
||||
static constexpr i64 MAX_RETRY = 256;
|
||||
|
||||
Entry *entries = nullptr;
|
||||
u64 nbuckets = 0;
|
||||
|
||||
private:
|
||||
std::pair<T *, bool> insert_entry(const char *key, u64 hash, const T &val,
|
||||
auto equals, auto initialize) {
|
||||
assert(has_single_bit(nbuckets));
|
||||
|
||||
u64 begin = hash & (nbuckets - 1);
|
||||
u64 mask = nbuckets / NUM_SHARDS - 1;
|
||||
|
||||
for (i64 i = 0; i < MAX_RETRY; i++) {
|
||||
u64 idx = (begin & ~mask) | ((begin + i) & mask);
|
||||
Entry &ent = entries[idx];
|
||||
|
||||
// Avoid an atomic update when the slot is already occupied.
|
||||
if (const char *ptr = ent.key.load(std::memory_order_acquire);
|
||||
ptr != nullptr && ptr != (char *)-1) {
|
||||
if (equals(ptr, ent.keylen))
|
||||
return {&ent.value, false};
|
||||
continue;
|
||||
}
|
||||
|
||||
const char *ptr = nullptr;
|
||||
bool claimed = ent.key.compare_exchange_strong(ptr, (char *)-1,
|
||||
std::memory_order_acquire);
|
||||
|
||||
// -1 marks the slot as claimed until its value has been initialized.
|
||||
if (claimed) {
|
||||
new (&ent.value) T(val);
|
||||
ent.keylen = initialize(ent.value);
|
||||
ent.key.store(key, std::memory_order_release);
|
||||
return {&ent.value, true};
|
||||
}
|
||||
|
||||
// Wait for the thread that claimed the slot to publish its key.
|
||||
while (ptr == (char *)-1) {
|
||||
pause();
|
||||
ptr = ent.key.load(std::memory_order_acquire);
|
||||
}
|
||||
|
||||
if (equals(ptr, ent.keylen))
|
||||
return {&ent.value, false};
|
||||
}
|
||||
|
||||
std::cerr << "ConcurrentMap is full\n";
|
||||
abort();
|
||||
}
|
||||
};
|
||||
|
||||
static_assert(sizeof(void *) == 4 || sizeof(void *) == 8);
|
||||
|
||||
// ArenaResource owns a sparsely-backed address range for symbols, input files,
|
||||
// and related linker data structures. Allocation is thread-safe and monotonic;
|
||||
// individual allocations are not freed. Keeping related objects in this range
|
||||
// lets ArenaPtr represent references between them as 32-bit self-relative
|
||||
// offsets.
|
||||
class ArenaResource {
|
||||
public:
|
||||
// An 8 GiB arena ensures that the distance between any two allocations fits
|
||||
// in ArenaPtr's signed 32-bit offset. A smaller reservation is used on
|
||||
// 32-bit hosts, where address space is more limited.
|
||||
static constexpr u64 SIZE = sizeof(void *) == 8 ? 1ULL << 33 : 1ULL << 28;
|
||||
|
||||
ArenaResource();
|
||||
~ArenaResource();
|
||||
ArenaResource(const ArenaResource &) = delete;
|
||||
ArenaResource &operator=(const ArenaResource &) = delete;
|
||||
|
||||
void *allocate(u64 size, u64 alignment);
|
||||
|
||||
template <typename T>
|
||||
T *allocate(i64 count) {
|
||||
if (count < 0 || (u64)count > SIZE / sizeof(T)) {
|
||||
std::cerr << "mold: cannot allocate more than " << SIZE
|
||||
<< " bytes for linker data structures on this host\n";
|
||||
std::exit(1);
|
||||
}
|
||||
return (T *)allocate(sizeof(T) * (u64)count, alignof(T));
|
||||
}
|
||||
|
||||
template <typename T, typename... Args>
|
||||
T *make(Args &&...args) {
|
||||
return std::construct_at(allocate<T>(1), std::forward<Args>(args)...);
|
||||
}
|
||||
|
||||
// ArenaPtr works only if the pointer field itself is within 8 GiB of its
|
||||
// target. Records stored outside the arena instead use an index from the
|
||||
// beginning of the arena. Indices count four-byte slots, and zero represents
|
||||
// a null pointer.
|
||||
u32 get_index(const void *ptr) const {
|
||||
uintptr_t addr = (uintptr_t)ptr;
|
||||
uintptr_t begin = (uintptr_t)data;
|
||||
assert(begin < addr && addr < begin + SIZE);
|
||||
assert((addr - begin) % 4 == 0);
|
||||
return (addr - begin) / 4;
|
||||
}
|
||||
|
||||
template <typename T>
|
||||
T *get_pointer(u32 idx) const {
|
||||
assert(0 < idx && (u64)idx * 4 < SIZE);
|
||||
return (T *)(data + (u64)idx * 4);
|
||||
}
|
||||
|
||||
private:
|
||||
void *allocate_global(u64 size, u64 alignment);
|
||||
void commit(u64 end);
|
||||
|
||||
u8 *data;
|
||||
|
||||
// The reserved range is made accessible in chunks as allocations advance.
|
||||
// Bytes below `committed` are accessible.
|
||||
std::atomic<u64> committed = 0;
|
||||
std::mutex commit_mu;
|
||||
|
||||
// Index into the per-thread array of allocation blocks. Slots are never
|
||||
// reused, so a new arena cannot inherit stale pointers from an old one.
|
||||
u32 arena_slot;
|
||||
|
||||
// Leave the first slots unused so that a base-relative index is never zero.
|
||||
std::atomic<u64> offset = 8;
|
||||
};
|
||||
|
||||
// ArenaAllocator adapts ArenaResource to the standard allocator interface so
|
||||
// containers can place their backing storage in the resource's address range.
|
||||
// It does not own the resource, and deallocation is deferred until the
|
||||
// resource itself is destroyed.
|
||||
template <typename T>
|
||||
class ArenaAllocator {
|
||||
public:
|
||||
using value_type = T;
|
||||
|
||||
ArenaAllocator(ArenaResource &arena) : arena(arena) {}
|
||||
|
||||
template <typename U>
|
||||
ArenaAllocator(const ArenaAllocator<U> &other) : arena(other.arena) {}
|
||||
|
||||
T *allocate(i64 count) {
|
||||
return arena.template allocate<T>(count);
|
||||
}
|
||||
|
||||
void deallocate(T *, i64) {}
|
||||
|
||||
template <typename U>
|
||||
bool operator==(const ArenaAllocator<U> &other) const {
|
||||
return &arena == &other.arena;
|
||||
}
|
||||
|
||||
private:
|
||||
template <typename U> friend class ArenaAllocator;
|
||||
|
||||
ArenaResource &arena;
|
||||
};
|
||||
|
||||
// ArenaPtr stores a pointer as a signed 32-bit offset from itself, in units of
|
||||
// four bytes. It is used for references between objects in an ArenaResource;
|
||||
// the ArenaPtr and its target must be four-byte aligned and less than 8 GiB
|
||||
// apart. An offset of zero represents a null pointer.
|
||||
template <typename T>
|
||||
class alignas(4) ArenaPtr {
|
||||
public:
|
||||
ArenaPtr() = default;
|
||||
ArenaPtr(std::nullptr_t) {}
|
||||
ArenaPtr(T *ptr) { *this = ptr; }
|
||||
|
||||
// The offset is relative to this ArenaPtr, so copying it verbatim would
|
||||
// make it point somewhere else.
|
||||
ArenaPtr(const ArenaPtr &other) { *this = (T *)other; }
|
||||
ArenaPtr(ArenaPtr &&other) { *this = (T *)other; }
|
||||
|
||||
ArenaPtr &operator=(T *ptr) {
|
||||
if (!ptr) {
|
||||
offset = 0;
|
||||
return *this;
|
||||
}
|
||||
|
||||
i64 byte_offset = (intptr_t)ptr - (intptr_t)this;
|
||||
assert(byte_offset % 4 == 0);
|
||||
assert(is_int(byte_offset / 4, 32));
|
||||
offset = byte_offset / 4;
|
||||
assert(offset != 0);
|
||||
return *this;
|
||||
}
|
||||
|
||||
ArenaPtr &operator=(const ArenaPtr &other) {
|
||||
return *this = (T *)other;
|
||||
}
|
||||
|
||||
ArenaPtr &operator=(ArenaPtr &&other) {
|
||||
return *this = (T *)other;
|
||||
}
|
||||
|
||||
operator T *() const {
|
||||
return offset ? (T *)((intptr_t)this + (i64)offset * 4) : nullptr;
|
||||
}
|
||||
|
||||
T *operator->() const {
|
||||
return (T *)*this;
|
||||
}
|
||||
|
||||
T &operator*() const {
|
||||
return *(T *)*this;
|
||||
}
|
||||
|
||||
friend void swap(ArenaPtr &x, ArenaPtr &y) {
|
||||
T *tmp = x;
|
||||
x = (T *)y;
|
||||
y = tmp;
|
||||
}
|
||||
|
||||
private:
|
||||
i32 offset = 0;
|
||||
};
|
||||
|
||||
static_assert(sizeof(ArenaPtr<u64>) == 4);
|
||||
|
||||
// ArenaObjectDeleter runs an arena object's destructor without freeing its
|
||||
// storage. ArenaObjectPtr uses it to retain normal unique_ptr ownership
|
||||
// semantics for objects whose storage belongs to ArenaResource.
|
||||
template <typename T>
|
||||
struct ArenaObjectDeleter {
|
||||
void operator()(T *ptr) const {
|
||||
std::destroy_at(ptr);
|
||||
}
|
||||
};
|
||||
|
||||
template <typename T>
|
||||
using ArenaObjectPtr = std::unique_ptr<T, ArenaObjectDeleter<T>>;
|
||||
|
||||
template <typename T>
|
||||
struct ShardedMapEntry : T {
|
||||
ShardedMapEntry(std::string_view key) : key(key) {}
|
||||
|
||||
// Keeping the key outside T means that values not stored in a map do not
|
||||
// pay for it. A mapped T is the base subobject of this entry.
|
||||
std::string_view key;
|
||||
};
|
||||
|
||||
template <typename T>
|
||||
std::string_view get_sharded_map_key(const T &object) {
|
||||
return static_cast<const ShardedMapEntry<T> &>(object).key;
|
||||
}
|
||||
|
||||
// ShardedMap is a map from strings to values of type T, built in two phases.
|
||||
// In the first phase, which may run in parallel, add() records a key and an
|
||||
// ArenaPtr<T> slot that needs the key's value. gather() then deduplicates the
|
||||
// keys, finds or creates one value for each key, and writes its address to
|
||||
// every recorded slot. The slots must remain at stable addresses until
|
||||
// gather().
|
||||
//
|
||||
// Keys whose hashes fall into different shards never interact, and
|
||||
// each shard is processed by exactly one thread during gather(), so
|
||||
// unlike with a concurrent hash table, no synchronization is needed,
|
||||
// and each key is hashed only once, in add().
|
||||
//
|
||||
// If a value needs to be initialized from its key, pass an
|
||||
// `on_create(key, value)` callback to gather() or insert(). It is called
|
||||
// exactly once when a value is created.
|
||||
//
|
||||
// insert() handles keys that arrive outside the two-phase pattern under a
|
||||
// shard mutex. All values live in stable arena blocks.
|
||||
template <typename T>
|
||||
class ShardedMap {
|
||||
public:
|
||||
static constexpr i64 NUM_SHARDS = 64;
|
||||
|
||||
// A key recorded by add() with the slot that receives its value's address.
|
||||
struct Pending {
|
||||
std::string_view key;
|
||||
u64 hash;
|
||||
ArenaPtr<T> *slot;
|
||||
};
|
||||
|
||||
// A thread's recorded keys, grouped by shard.
|
||||
using Bin = std::array<std::vector<Pending>, NUM_SHARDS>;
|
||||
|
||||
explicit ShardedMap(ArenaResource &arena) {
|
||||
for (Shard &shard : shards)
|
||||
shard.arena = &arena;
|
||||
}
|
||||
|
||||
// Records a key and the slot to receive its value's address. A caller
|
||||
// adding many keys should fetch its thread's bin once with get_bin(),
|
||||
// as the thread-local lookup costs more than the record itself.
|
||||
void add(std::string_view key, ArenaPtr<T> &slot) {
|
||||
add(get_bin(), key, slot);
|
||||
}
|
||||
|
||||
Bin &get_bin() { return bins.local(); }
|
||||
|
||||
void add(Bin &bin, std::string_view key, ArenaPtr<T> &slot) {
|
||||
u64 hash = hash_string(key);
|
||||
bin[hash % NUM_SHARDS].push_back({key, hash, &slot});
|
||||
}
|
||||
|
||||
T *insert(std::string_view key, auto on_create) {
|
||||
u64 hash = hash_string(key);
|
||||
Shard &shard = shards[hash % NUM_SHARDS];
|
||||
std::scoped_lock lock(shard.mu);
|
||||
return shard.insert(key, hash, on_create);
|
||||
}
|
||||
|
||||
void gather(auto on_create) {
|
||||
tbb::parallel_for((i64)0, NUM_SHARDS, [&](i64 i) {
|
||||
Shard &shard = shards[i];
|
||||
|
||||
i64 count = 0;
|
||||
for (Bin &bin : bins)
|
||||
count += bin[i].size();
|
||||
if (count == 0)
|
||||
return;
|
||||
|
||||
shard.reserve(count);
|
||||
|
||||
for (Bin &bin : bins)
|
||||
for (Pending &p : bin[i])
|
||||
*p.slot = shard.insert(p.key, p.hash, on_create);
|
||||
});
|
||||
|
||||
bins.clear();
|
||||
}
|
||||
|
||||
void parallel_for_each(auto fn) {
|
||||
tbb::parallel_for((i64)0, NUM_SHARDS, [&](i64 i) {
|
||||
Shard &shard = shards[i];
|
||||
for (Block &block : shard.blocks)
|
||||
for (i64 j = 0; j < block.size; j++)
|
||||
fn(block.data[j]);
|
||||
});
|
||||
}
|
||||
|
||||
private:
|
||||
using Entry = ShardedMapEntry<T>;
|
||||
static_assert(std::is_trivially_destructible_v<Entry>);
|
||||
|
||||
struct Block {
|
||||
Entry *data;
|
||||
i64 size;
|
||||
i64 capacity;
|
||||
};
|
||||
|
||||
// Shards are built by one thread at a time. Keep only a cached hash and
|
||||
// an entry pointer in each bucket; keys and values remain in the arena.
|
||||
struct Slot {
|
||||
u64 hash = 0;
|
||||
Entry *entry = nullptr;
|
||||
};
|
||||
|
||||
struct Shard {
|
||||
Shard() = default;
|
||||
Shard(const Shard &) = delete;
|
||||
Shard &operator=(const Shard &) = delete;
|
||||
|
||||
T *insert(std::string_view key, u64 hash, auto on_create) {
|
||||
if (size * 4 >= slots.size() * 3)
|
||||
rehash(std::max<i64>(16, slots.size() * 2));
|
||||
|
||||
u64 mask = slots.size() - 1;
|
||||
// The low hash bits already selected the shard.
|
||||
u64 idx = (hash / NUM_SHARDS) & mask;
|
||||
while (slots[idx].entry) {
|
||||
Slot &slot = slots[idx];
|
||||
if (slot.hash == hash && slot.entry->key == key)
|
||||
return slot.entry;
|
||||
idx = (idx + 1) & mask;
|
||||
}
|
||||
|
||||
if (blocks.empty() || blocks.back().size == blocks.back().capacity)
|
||||
add_block(INSERT_BLOCK_SIZE);
|
||||
|
||||
Entry *entry = emplace(blocks.back(), key);
|
||||
slots[idx] = {hash, entry};
|
||||
size++;
|
||||
on_create(key, *entry);
|
||||
return entry;
|
||||
}
|
||||
|
||||
void reserve(i64 count) {
|
||||
i64 capacity = std::max<i64>(16, bit_ceil((size + count) * 4 / 3 + 1));
|
||||
if (slots.size() < capacity)
|
||||
rehash(capacity);
|
||||
if (blocks.empty() ||
|
||||
blocks.back().capacity - blocks.back().size < count)
|
||||
add_block(std::max<i64>(INSERT_BLOCK_SIZE, count));
|
||||
}
|
||||
|
||||
void rehash(i64 capacity) {
|
||||
std::vector<Slot> vec(capacity);
|
||||
u64 mask = capacity - 1;
|
||||
for (Slot slot : slots) {
|
||||
if (!slot.entry)
|
||||
continue;
|
||||
u64 idx = (slot.hash / NUM_SHARDS) & mask;
|
||||
while (vec[idx].entry)
|
||||
idx = (idx + 1) & mask;
|
||||
vec[idx] = slot;
|
||||
}
|
||||
slots = std::move(vec);
|
||||
}
|
||||
|
||||
static constexpr i64 INSERT_BLOCK_SIZE = 256;
|
||||
|
||||
void add_block(i64 capacity) {
|
||||
Entry *data = arena->allocate<Entry>(capacity);
|
||||
blocks.push_back({data, 0, capacity});
|
||||
}
|
||||
|
||||
Entry *emplace(Block &block, std::string_view key) {
|
||||
assert(block.size < block.capacity);
|
||||
Entry *entry = block.data + block.size++;
|
||||
return std::construct_at(entry, key);
|
||||
}
|
||||
|
||||
std::mutex mu;
|
||||
ArenaResource *arena = nullptr;
|
||||
std::vector<Block> blocks;
|
||||
std::vector<Slot> slots;
|
||||
i64 size = 0;
|
||||
};
|
||||
|
||||
Shard shards[NUM_SHARDS];
|
||||
tbb::enumerable_thread_specific<Bin> bins;
|
||||
};
|
||||
|
||||
//
|
||||
@@ -533,23 +1073,31 @@ void get_random_bytes(u8 *buf, i64 size);
|
||||
//
|
||||
|
||||
class HyperLogLog {
|
||||
public:
|
||||
void insert(u64 hash) {
|
||||
update_maximum(buckets[hash & (NBUCKETS - 1)], std::countl_zero(hash) + 1);
|
||||
}
|
||||
|
||||
i64 get_cardinality() const;
|
||||
|
||||
void merge(const HyperLogLog &other) {
|
||||
for (i64 i = 0; i < NBUCKETS; i++)
|
||||
update_maximum(buckets[i], other.buckets[i]);
|
||||
}
|
||||
|
||||
private:
|
||||
static constexpr i64 NBUCKETS = 2048;
|
||||
static constexpr double ALPHA = 0.79402;
|
||||
|
||||
Atomic<u8> buckets[NBUCKETS];
|
||||
public:
|
||||
class Sketch {
|
||||
public:
|
||||
void insert(u64 hash) {
|
||||
u8 &val = buckets[hash & (NBUCKETS - 1)];
|
||||
val = std::max<u8>(val, std::countl_zero(hash) + 1);
|
||||
}
|
||||
|
||||
private:
|
||||
friend class HyperLogLog;
|
||||
u8 buckets[NBUCKETS] = {};
|
||||
};
|
||||
|
||||
Sketch &local() {
|
||||
return sketches.local();
|
||||
}
|
||||
|
||||
i64 get_cardinality() const;
|
||||
|
||||
private:
|
||||
tbb::enumerable_thread_specific<Sketch> sketches;
|
||||
};
|
||||
|
||||
//
|
||||
@@ -567,57 +1115,88 @@ public:
|
||||
|
||||
private:
|
||||
struct TrieNode {
|
||||
TrieNode() { children.fill(-1); }
|
||||
i64 value = -1;
|
||||
i32 suffix_link = -1;
|
||||
std::array<i32, 256> children;
|
||||
i32 first_child = -1;
|
||||
i32 next_sibling = -1;
|
||||
u8 ch = 0;
|
||||
};
|
||||
|
||||
void fix_suffix_links(i64 idx);
|
||||
void fix_values();
|
||||
i32 find_child(i32 node, u8 ch) const;
|
||||
i32 add_child(i32 node, u8 ch);
|
||||
|
||||
// Most trie nodes have only one child. The root uses a dense table because
|
||||
// it is visited for almost every input byte; other edges are stored sparsely.
|
||||
std::array<i32, 256> root_children;
|
||||
std::vector<TrieNode> nodes;
|
||||
};
|
||||
|
||||
//
|
||||
// glob.cc
|
||||
//
|
||||
|
||||
class MultiGlob {
|
||||
public:
|
||||
bool add(std::string_view pat, i64 val);
|
||||
bool empty() const { return patterns.empty(); }
|
||||
void compile();
|
||||
i64 find(std::string_view str);
|
||||
|
||||
struct State {
|
||||
std::bitset<256> incoming_edge;
|
||||
bool is_star = false;
|
||||
};
|
||||
|
||||
struct GlobPattern {
|
||||
std::vector<State> states;
|
||||
i64 value = -1;
|
||||
};
|
||||
|
||||
private:
|
||||
std::vector<GlobPattern> patterns;
|
||||
Bitvector start_states;
|
||||
Bitvector star_mask;
|
||||
Bitvector char_mask[256];
|
||||
i64 max_value = -1;
|
||||
};
|
||||
|
||||
class Glob {
|
||||
public:
|
||||
bool add(std::string_view pat, i64 val);
|
||||
bool empty() const { return multi_glob.empty() && aho_corasick.empty(); }
|
||||
bool empty() const { return is_empty; }
|
||||
i64 find(std::string_view str);
|
||||
|
||||
private:
|
||||
std::once_flag once;
|
||||
bool is_empty = true;
|
||||
bool is_compiled = false;
|
||||
i64 max_value = -1;
|
||||
|
||||
MultiGlob multi_glob;
|
||||
// Patterns that need only a literal string comparison are kept out
|
||||
// of the automaton-based matchers below, which scan the entire input
|
||||
// string per query. Real version scripts consist almost entirely of
|
||||
// such patterns (e.g. `local: *;` or `v8dbg_*;`), and we match them
|
||||
// against every defined symbol name.
|
||||
struct LiteralPattern {
|
||||
std::string pat;
|
||||
i64 value;
|
||||
};
|
||||
|
||||
struct Pattern {
|
||||
enum Kind { STRING, STAR, QUESTION, BRACKET };
|
||||
|
||||
struct Token {
|
||||
Token(Kind kind) : kind(kind) {}
|
||||
|
||||
Kind kind;
|
||||
std::string str;
|
||||
std::bitset<256> chars;
|
||||
};
|
||||
|
||||
Pattern(std::vector<Token> &&tokens, i64 value)
|
||||
: tokens(std::move(tokens)), value(value) {}
|
||||
|
||||
static std::optional<Pattern> compile(std::string_view pat, i64 value);
|
||||
bool match(std::string_view str) const;
|
||||
|
||||
std::vector<Token> tokens;
|
||||
i64 value;
|
||||
};
|
||||
|
||||
// Nfa matches many glob patterns in parallel by representing each state
|
||||
// with one bit. It is used only for large pattern sets; matching individual
|
||||
// patterns is faster when there are only a few of them.
|
||||
struct Nfa {
|
||||
void compile(std::span<const Pattern> patterns);
|
||||
i64 match(std::string_view str) const;
|
||||
bool empty() const { return initial_states.empty(); }
|
||||
|
||||
std::vector<u64> initial_states;
|
||||
std::vector<u64> star_states;
|
||||
std::vector<u64> accept_states;
|
||||
std::vector<u64> char_masks;
|
||||
std::vector<i64> values;
|
||||
};
|
||||
|
||||
i64 match_all = -1; // "*"
|
||||
std::vector<LiteralPattern> exacts; // "foo"
|
||||
std::vector<LiteralPattern> prefixes; // "foo*"
|
||||
std::vector<LiteralPattern> suffixes; // "*foo"
|
||||
std::vector<Pattern> patterns; // "foo*bar"
|
||||
|
||||
Nfa nfa;
|
||||
AhoCorasick aho_corasick;
|
||||
};
|
||||
|
||||
|
||||
+13
-14
@@ -1,18 +1,17 @@
|
||||
# Get a git hash value. We do not want to use git command here
|
||||
# because we don't want to make git a build-time dependency.
|
||||
if(EXISTS "${SOURCE_DIR}/.git/HEAD")
|
||||
file(READ "${SOURCE_DIR}/.git/HEAD" HASH)
|
||||
string(STRIP "${HASH}" HASH)
|
||||
# Embed the current git commit hash into the mold executable. We ask git
|
||||
# instead of parsing files under .git because the repository format varies
|
||||
# (e.g. packed refs, reftable). When building from a source tarball, there's
|
||||
# no .git, and the hash is simply omitted.
|
||||
if(EXISTS "${SOURCE_DIR}/.git")
|
||||
execute_process(
|
||||
COMMAND git -C "${SOURCE_DIR}" rev-parse HEAD
|
||||
OUTPUT_VARIABLE HASH
|
||||
OUTPUT_STRIP_TRAILING_WHITESPACE
|
||||
ERROR_QUIET
|
||||
RESULT_VARIABLE EXIT_CODE)
|
||||
|
||||
if(HASH MATCHES "^ref: (.*)")
|
||||
set(HEAD "${CMAKE_MATCH_1}")
|
||||
if(EXISTS "${SOURCE_DIR}/.git/${HEAD}")
|
||||
file(READ "${SOURCE_DIR}/.git/${HEAD}" HASH)
|
||||
string(STRIP "${HASH}" HASH)
|
||||
else()
|
||||
file(READ "${SOURCE_DIR}/.git/packed-refs" PACKED_REFS)
|
||||
string(REGEX REPLACE ".*\n([0-9a-f]+) ${HEAD}\n.*" "\\1" HASH "\n${PACKED_REFS}")
|
||||
endif()
|
||||
if(NOT EXIT_CODE EQUAL 0)
|
||||
set(HASH "")
|
||||
endif()
|
||||
endif()
|
||||
|
||||
|
||||
+20
-19
@@ -262,8 +262,8 @@ void write_pltgot_entry(Context<E> &ctx, u8 *buf, Symbol<E> &sym) {
|
||||
}
|
||||
|
||||
template <>
|
||||
void EhFrameSection<E>::apply_eh_reloc(Context<E> &ctx, const ElfRel<E> &rel,
|
||||
u64 offset, u64 val) {
|
||||
void EhFrameSection<E>::apply_eh_reloc(Context<E> &ctx, InputSection<E> &isec,
|
||||
const ElfRel<E> &rel, u64 offset, u64 val) {
|
||||
u8 *loc = ctx.buf + this->shdr.sh_offset + offset;
|
||||
|
||||
switch (rel.r_type) {
|
||||
@@ -289,13 +289,16 @@ void InputSection<E>::apply_reloc_alloc(Context<E> &ctx, u8 *base) {
|
||||
if (rel.r_type == R_NONE || rel.r_type == R_ARM_V4BX)
|
||||
continue;
|
||||
|
||||
Symbol<E> &sym = *file.symbols[rel.r_sym];
|
||||
Symbol<E> &sym = *file->symbols[rel.r_sym];
|
||||
if (sym.get_type() == STT_TLS && sym.is_remaining_undef_weak())
|
||||
continue;
|
||||
|
||||
u8 *loc = base + rel.r_offset;
|
||||
|
||||
u64 S = sym.get_addr(ctx);
|
||||
u64 A = get_addend(*this, rel);
|
||||
u64 P = get_addr() + rel.r_offset;
|
||||
u64 T = S & 1;
|
||||
u64 T = is_thumb_func(ctx, sym);
|
||||
u64 G = sym.get_got_idx(ctx) * sizeof(Word<E>);
|
||||
u64 GOT = ctx.got->shdr.sh_addr;
|
||||
|
||||
@@ -330,15 +333,16 @@ void InputSection<E>::apply_reloc_alloc(Context<E> &ctx, u8 *base) {
|
||||
}
|
||||
|
||||
// THM_CALL relocation refers to either BL or BLX instruction.
|
||||
// They are different in only one bit. We need to use BL if
|
||||
// the jump target is Thumb. Otherwise, use BLX.
|
||||
// They are different in only one bit. We need to use BLX if the
|
||||
// jump target is an ARM function. Otherwise, use BL.
|
||||
i64 val1 = S + A - P;
|
||||
i64 val2 = align_to(S + A - P, 4);
|
||||
bool arm = is_arm_func(ctx, sym);
|
||||
|
||||
if (T && is_int(val1, 25)) {
|
||||
if (!arm && is_int(val1, 25)) {
|
||||
*(U16<E> *)(loc + 2) |= 0x1000; // BL
|
||||
write_thm_b25(loc, val1);
|
||||
} else if (!T && is_int(val2, 25)) {
|
||||
} else if (arm && is_int(val2, 25)) {
|
||||
*(U16<E> *)(loc + 2) &= ~0x1000; // BLX
|
||||
write_thm_b25(loc, val2);
|
||||
} else {
|
||||
@@ -437,7 +441,7 @@ void InputSection<E>::apply_reloc_alloc(Context<E> &ctx, u8 *base) {
|
||||
// Just like R_ARM_JUMP24, we need to jump to a thunk if we need to
|
||||
// switch processor mode.
|
||||
i64 val = S + A - P;
|
||||
if (!T || !is_int(val, 25))
|
||||
if (is_arm_func(ctx, sym) || !is_int(val, 25))
|
||||
val = get_thumb_thunk_addr() + A - P;
|
||||
write_thm_b25(loc, val);
|
||||
break;
|
||||
@@ -552,14 +556,11 @@ void InputSection<E>::apply_reloc_alloc(Context<E> &ctx, u8 *base) {
|
||||
|
||||
template <>
|
||||
void InputSection<E>::apply_reloc_nonalloc(Context<E> &ctx, u8 *base) {
|
||||
std::span<const ElfRel<E>> rels = get_rels(ctx);
|
||||
|
||||
for (i64 i = 0; i < rels.size(); i++) {
|
||||
const ElfRel<E> &rel = rels[i];
|
||||
for_each_reloc(ctx, [&](const ElfRel<E> &rel, i64) ALWAYS_INLINE {
|
||||
if (rel.r_type == R_NONE || record_undef_error(ctx, rel))
|
||||
continue;
|
||||
return;
|
||||
|
||||
Symbol<E> &sym = *file.symbols[rel.r_sym];
|
||||
Symbol<E> &sym = *file->symbols[rel.r_sym];
|
||||
u8 *loc = base + rel.r_offset;
|
||||
|
||||
SectionFragment<E> *frag;
|
||||
@@ -587,7 +588,7 @@ void InputSection<E>::apply_reloc_nonalloc(Context<E> &ctx, u8 *base) {
|
||||
<< rel;
|
||||
break;
|
||||
}
|
||||
}
|
||||
});
|
||||
}
|
||||
|
||||
template <>
|
||||
@@ -601,7 +602,7 @@ void InputSection<E>::scan_relocations(Context<E> &ctx) {
|
||||
if (rel.r_type == R_NONE || record_undef_error(ctx, rel))
|
||||
continue;
|
||||
|
||||
Symbol<E> &sym = *file.symbols[rel.r_sym];
|
||||
Symbol<E> &sym = *file->symbols[rel.r_sym];
|
||||
|
||||
if (sym.is_ifunc())
|
||||
sym.flags |= NEEDS_GOT | NEEDS_PLT;
|
||||
@@ -726,7 +727,7 @@ void create_arm_exidx_section<E>(Context<E> &ctx) {
|
||||
ctx.chunk_pool.emplace_back(sec);
|
||||
|
||||
for (InputSection<E> *isec : osec->members)
|
||||
isec->is_alive = false;
|
||||
isec->kill();
|
||||
break;
|
||||
}
|
||||
}
|
||||
@@ -875,7 +876,7 @@ void arm32be_swap_bytes(Context<E> &ctx) {
|
||||
|
||||
for (Symbol<E> *sym : file->get_local_syms())
|
||||
if (InputSection<E> *isec = sym->get_input_section())
|
||||
if (isec->is_alive && (isec->shdr().sh_flags & SHF_EXECINSTR))
|
||||
if (isec->is_alive() && (isec->shdr().sh_flags & SHF_EXECINSTR))
|
||||
if (std::string_view x = sym->name();
|
||||
x == "$a" || x.starts_with("$a.") ||
|
||||
x == "$t" || x.starts_with("$t.") ||
|
||||
|
||||
+50
-24
@@ -104,9 +104,14 @@ void write_pltgot_entry(Context<E> &ctx, u8 *buf, Symbol<E> &sym) {
|
||||
}
|
||||
|
||||
template <>
|
||||
void EhFrameSection<E>::apply_eh_reloc(Context<E> &ctx, const ElfRel<E> &rel,
|
||||
u64 offset, u64 val) {
|
||||
void EhFrameSection<E>::apply_eh_reloc(Context<E> &ctx, InputSection<E> &isec,
|
||||
const ElfRel<E> &rel, u64 offset, u64 val) {
|
||||
u8 *loc = ctx.buf + this->shdr.sh_offset + offset;
|
||||
u64 P = this->shdr.sh_addr + offset;
|
||||
|
||||
auto check = [&](i64 val, i64 lo, i64 hi) {
|
||||
check_range(ctx, isec, rel, val, lo, hi);
|
||||
};
|
||||
|
||||
switch (rel.r_type) {
|
||||
case R_NONE:
|
||||
@@ -115,10 +120,11 @@ void EhFrameSection<E>::apply_eh_reloc(Context<E> &ctx, const ElfRel<E> &rel,
|
||||
*(U64<E> *)loc = val;
|
||||
break;
|
||||
case R_AARCH64_PREL32:
|
||||
*(U32<E> *)loc = val - this->shdr.sh_addr - offset;
|
||||
check(val - P, -(1LL << 31), 1LL << 31);
|
||||
*(U32<E> *)loc = val - P;
|
||||
break;
|
||||
case R_AARCH64_PREL64:
|
||||
*(U64<E> *)loc = val - this->shdr.sh_addr - offset;
|
||||
*(U64<E> *)loc = val - P;
|
||||
break;
|
||||
default:
|
||||
Fatal(ctx) << "unsupported relocation in .eh_frame: " << rel;
|
||||
@@ -145,14 +151,17 @@ static bool is_add(u8 *loc) {
|
||||
|
||||
template <>
|
||||
void InputSection<E>::apply_reloc_alloc(Context<E> &ctx, u8 *base) {
|
||||
std::span<const ElfRel<E>> rels = get_rels(ctx);
|
||||
std::span<ElfRel<E>> rels = get_rels(ctx);
|
||||
|
||||
for (i64 i = 0; i < rels.size(); i++) {
|
||||
const ElfRel<E> &rel = rels[i];
|
||||
ElfRel<E> &rel = rels[i];
|
||||
if (rel.r_type == R_NONE)
|
||||
continue;
|
||||
|
||||
Symbol<E> &sym = *file.symbols[rel.r_sym];
|
||||
Symbol<E> &sym = *file->symbols[rel.r_sym];
|
||||
if (sym.get_type() == STT_TLS && sym.is_remaining_undef_weak())
|
||||
continue;
|
||||
|
||||
u8 *loc = base + rel.r_offset;
|
||||
|
||||
u64 S = sym.get_addr(ctx);
|
||||
@@ -165,6 +174,11 @@ void InputSection<E>::apply_reloc_alloc(Context<E> &ctx, u8 *base) {
|
||||
check_range(ctx, i, val, lo, hi);
|
||||
};
|
||||
|
||||
auto rewrite = [&](i64 idx, u32 ty) {
|
||||
if (ctx.arg.emit_relocs)
|
||||
rels[idx].r_type = ty;
|
||||
};
|
||||
|
||||
switch (rel.r_type) {
|
||||
case R_AARCH64_ABS64:
|
||||
break;
|
||||
@@ -246,6 +260,9 @@ void InputSection<E>::apply_reloc_alloc(Context<E> &ctx, u8 *base) {
|
||||
u32 reg = bits(*(ul32 *)loc, 4, 0);
|
||||
*(ul32 *)(loc + 4) = 0x9100'0000 | (reg << 5) | reg; // ADD
|
||||
*(ul32 *)(loc + 4) |= bits(S + A, 11, 0) << 10;
|
||||
|
||||
rewrite(i, R_AARCH64_ADR_PREL_PG_HI21);
|
||||
rewrite(i + 1, R_AARCH64_ADD_ABS_LO12_NC);
|
||||
i++;
|
||||
}
|
||||
break;
|
||||
@@ -272,6 +289,8 @@ void InputSection<E>::apply_reloc_alloc(Context<E> &ctx, u8 *base) {
|
||||
*(ul32 *)loc = 0xd503'201f; // nop
|
||||
*(ul32 *)(loc + 4) = 0x1000'0000 | reg1; // adr
|
||||
write_adr(loc + 4, val);
|
||||
rewrite(i, R_NONE);
|
||||
rewrite(i + 1, R_AARCH64_ADR_PREL_LO21);
|
||||
i++;
|
||||
break;
|
||||
}
|
||||
@@ -425,13 +444,16 @@ void InputSection<E>::apply_reloc_alloc(Context<E> &ctx, u8 *base) {
|
||||
write_adrp(loc, val);
|
||||
} else {
|
||||
*(ul32 *)loc = 0xd503'201f; // nop
|
||||
rewrite(i, R_NONE);
|
||||
}
|
||||
break;
|
||||
case R_AARCH64_TLSDESC_LD64_LO12:
|
||||
if (sym.has_tlsdesc(ctx))
|
||||
if (sym.has_tlsdesc(ctx)) {
|
||||
*(ul32 *)loc |= bits(sym.get_tlsdesc_addr(ctx) + A, 11, 3) << 10;
|
||||
else
|
||||
} else {
|
||||
*(ul32 *)loc = 0xd503'201f; // nop
|
||||
rewrite(i, R_NONE);
|
||||
}
|
||||
break;
|
||||
case R_AARCH64_TLSDESC_ADD_LO12:
|
||||
if (sym.has_tlsdesc(ctx)) {
|
||||
@@ -439,9 +461,11 @@ void InputSection<E>::apply_reloc_alloc(Context<E> &ctx, u8 *base) {
|
||||
} else if (sym.has_gottp(ctx)) {
|
||||
*(ul32 *)loc = 0x9000'0000; // adrp x0, 0
|
||||
write_adrp(loc, page(sym.get_gottp_addr(ctx) + A) - page(P));
|
||||
rewrite(i, R_AARCH64_TLSIE_ADR_GOTTPREL_PAGE21);
|
||||
} else {
|
||||
*(ul32 *)loc = 0xd2a0'0000; // movz x0, 0, lsl #16
|
||||
*(ul32 *)loc |= bits(S + A - ctx.tp_addr, 32, 16) << 5;
|
||||
rewrite(i, R_AARCH64_TLSLE_MOVW_TPREL_G1);
|
||||
}
|
||||
break;
|
||||
case R_AARCH64_TLSDESC_CALL:
|
||||
@@ -450,9 +474,11 @@ void InputSection<E>::apply_reloc_alloc(Context<E> &ctx, u8 *base) {
|
||||
} else if (sym.has_gottp(ctx)) {
|
||||
*(ul32 *)loc = 0xf940'0000; // ldr x0, [x0, 0]
|
||||
*(ul32 *)loc |= bits(sym.get_gottp_addr(ctx) + A, 11, 3) << 10;
|
||||
rewrite(i, R_AARCH64_TLSIE_LD64_GOTTPREL_LO12_NC);
|
||||
} else {
|
||||
*(ul32 *)loc = 0xf280'0000; // movk x0, 0
|
||||
*(ul32 *)loc |= bits(S + A - ctx.tp_addr, 15, 0) << 5;
|
||||
rewrite(i, R_AARCH64_TLSLE_MOVW_TPREL_G0_NC);
|
||||
}
|
||||
break;
|
||||
default:
|
||||
@@ -463,14 +489,11 @@ void InputSection<E>::apply_reloc_alloc(Context<E> &ctx, u8 *base) {
|
||||
|
||||
template <>
|
||||
void InputSection<E>::apply_reloc_nonalloc(Context<E> &ctx, u8 *base) {
|
||||
std::span<const ElfRel<E>> rels = get_rels(ctx);
|
||||
|
||||
for (i64 i = 0; i < rels.size(); i++) {
|
||||
const ElfRel<E> &rel = rels[i];
|
||||
for_each_reloc(ctx, [&](const ElfRel<E> &rel, i64 i) ALWAYS_INLINE {
|
||||
if (rel.r_type == R_NONE || record_undef_error(ctx, rel))
|
||||
continue;
|
||||
return;
|
||||
|
||||
Symbol<E> &sym = *file.symbols[rel.r_sym];
|
||||
Symbol<E> &sym = *file->symbols[rel.r_sym];
|
||||
u8 *loc = base + rel.r_offset;
|
||||
|
||||
SectionFragment<E> *frag;
|
||||
@@ -481,7 +504,7 @@ void InputSection<E>::apply_reloc_nonalloc(Context<E> &ctx, u8 *base) {
|
||||
u64 A = frag ? frag_addend : (i64)rel.r_addend;
|
||||
|
||||
auto check = [&](i64 val, i64 lo, i64 hi) {
|
||||
check_range(ctx, val, i, lo, hi);
|
||||
check_range(ctx, i, val, lo, hi);
|
||||
};
|
||||
|
||||
switch (rel.r_type) {
|
||||
@@ -495,12 +518,18 @@ void InputSection<E>::apply_reloc_nonalloc(Context<E> &ctx, u8 *base) {
|
||||
check(S + A, 0, 1LL << 32);
|
||||
*(U32<E> *)loc = S + A;
|
||||
break;
|
||||
case R_AARCH64_TLS_DTPREL64:
|
||||
if (std::optional<u64> val = get_tombstone(sym, frag))
|
||||
*(U64<E> *)loc = *val;
|
||||
else
|
||||
*(U64<E> *)loc = S + A - ctx.dtp_addr;
|
||||
break;
|
||||
default:
|
||||
Fatal(ctx) << *this << ": invalid relocation for non-allocated sections: "
|
||||
<< rel;
|
||||
break;
|
||||
}
|
||||
}
|
||||
});
|
||||
}
|
||||
|
||||
template <>
|
||||
@@ -514,8 +543,8 @@ void InputSection<E>::scan_relocations(Context<E> &ctx) {
|
||||
if (rel.r_type == R_NONE || record_undef_error(ctx, rel))
|
||||
continue;
|
||||
|
||||
Symbol<E> &sym = *file.symbols[rel.r_sym];
|
||||
u8 *loc = (u8 *)(contents.data() + rel.r_offset);
|
||||
Symbol<E> &sym = *file->symbols[rel.r_sym];
|
||||
u8 *loc = contents + rel.r_offset;
|
||||
|
||||
if (sym.is_ifunc())
|
||||
sym.flags |= NEEDS_GOT | NEEDS_PLT;
|
||||
@@ -646,7 +675,7 @@ void Thunk<E>::shrink_size(Context<E> &ctx) {
|
||||
u64 S = sym->get_addr(ctx);
|
||||
u64 P = get_addr() + off;
|
||||
i64 prel = page(S) - page(P);
|
||||
off += is_small(prel) ? 16 : 32;
|
||||
off += is_small(prel) ? 12 : 24;
|
||||
offsets.push_back(off);
|
||||
}
|
||||
}
|
||||
@@ -658,7 +687,6 @@ void Thunk<E>::copy_buf(Context<E> &ctx) {
|
||||
0x9000'0010, // adrp x16, 0
|
||||
0x9100'0210, // add x16, x16
|
||||
0xd61f'0200, // br x16
|
||||
0xd420'7d00, // brk
|
||||
};
|
||||
|
||||
// Long thunk with a 64 bit displacement
|
||||
@@ -669,8 +697,6 @@ void Thunk<E>::copy_buf(Context<E> &ctx) {
|
||||
0xf2e0'0011, // movk x17, 0, lsl #48
|
||||
0x8b11'0210, // add x16, x16, x17
|
||||
0xd61f'0200, // br x16
|
||||
0xd420'7d00, // brk
|
||||
0xd420'7d00, // brk
|
||||
};
|
||||
|
||||
u8 *base = ctx.buf + output_section.shdr.sh_offset + offset;
|
||||
@@ -680,7 +706,7 @@ void Thunk<E>::copy_buf(Context<E> &ctx) {
|
||||
u64 P = get_addr() + offsets[i];
|
||||
u8 *buf = base + offsets[i];
|
||||
|
||||
if (offsets[i + 1] - offsets[i] == 16) {
|
||||
if (offsets[i + 1] - offsets[i] == sizeof(insn1)) {
|
||||
i64 prel = page(S) - page(P);
|
||||
assert(is_int(prel, 33));
|
||||
memcpy(buf, insn1, sizeof(insn1));
|
||||
|
||||
+17
-15
@@ -174,8 +174,8 @@ void write_pltgot_entry(Context<E> &ctx, u8 *buf, Symbol<E> &sym) {
|
||||
}
|
||||
|
||||
template <>
|
||||
void EhFrameSection<E>::apply_eh_reloc(Context<E> &ctx, const ElfRel<E> &rel,
|
||||
u64 offset, u64 val) {
|
||||
void EhFrameSection<E>::apply_eh_reloc(Context<E> &ctx, InputSection<E> &isec,
|
||||
const ElfRel<E> &rel, u64 offset, u64 val) {
|
||||
u8 *loc = ctx.buf + this->shdr.sh_offset + offset;
|
||||
|
||||
switch (rel.r_type) {
|
||||
@@ -280,14 +280,17 @@ static u32 relax_tlsdesc_to_le(u8 *loc) {
|
||||
|
||||
template <>
|
||||
void InputSection<E>::apply_reloc_alloc(Context<E> &ctx, u8 *base) {
|
||||
std::span<const ElfRel<E>> rels = get_rels(ctx);
|
||||
std::span<ElfRel<E>> rels = get_rels(ctx);
|
||||
|
||||
for (i64 i = 0; i < rels.size(); i++) {
|
||||
const ElfRel<E> &rel = rels[i];
|
||||
ElfRel<E> &rel = rels[i];
|
||||
if (rel.r_type == R_NONE)
|
||||
continue;
|
||||
|
||||
Symbol<E> &sym = *file.symbols[rel.r_sym];
|
||||
Symbol<E> &sym = *file->symbols[rel.r_sym];
|
||||
if (sym.get_type() == STT_TLS && sym.is_remaining_undef_weak())
|
||||
continue;
|
||||
|
||||
u8 *loc = base + rel.r_offset;
|
||||
|
||||
u64 S = sym.get_addr(ctx);
|
||||
@@ -335,6 +338,8 @@ void InputSection<E>::apply_reloc_alloc(Context<E> &ctx, u8 *base) {
|
||||
loc[-2] = insn >> 8;
|
||||
loc[-1] = insn;
|
||||
*(ul32 *)loc = S + A - GOT;
|
||||
if (ctx.arg.emit_relocs)
|
||||
rel.r_type = R_386_GOTOFF;
|
||||
}
|
||||
break;
|
||||
case R_386_GOTOFF:
|
||||
@@ -436,14 +441,11 @@ void InputSection<E>::apply_reloc_alloc(Context<E> &ctx, u8 *base) {
|
||||
|
||||
template <>
|
||||
void InputSection<E>::apply_reloc_nonalloc(Context<E> &ctx, u8 *base) {
|
||||
std::span<const ElfRel<E>> rels = get_rels(ctx);
|
||||
|
||||
for (i64 i = 0; i < rels.size(); i++) {
|
||||
const ElfRel<E> &rel = rels[i];
|
||||
for_each_reloc(ctx, [&](const ElfRel<E> &rel, i64 i) ALWAYS_INLINE {
|
||||
if (rel.r_type == R_NONE || record_undef_error(ctx, rel))
|
||||
continue;
|
||||
return;
|
||||
|
||||
Symbol<E> &sym = *file.symbols[rel.r_sym];
|
||||
Symbol<E> &sym = *file->symbols[rel.r_sym];
|
||||
u8 *loc = base + rel.r_offset;
|
||||
|
||||
SectionFragment<E> *frag;
|
||||
@@ -455,7 +457,7 @@ void InputSection<E>::apply_reloc_nonalloc(Context<E> &ctx, u8 *base) {
|
||||
u64 GOT = ctx.got->shdr.sh_addr;
|
||||
|
||||
auto check = [&](i64 val, i64 lo, i64 hi) {
|
||||
check_range(ctx, val, i, lo, hi);
|
||||
check_range(ctx, i, val, lo, hi);
|
||||
};
|
||||
|
||||
switch (rel.r_type) {
|
||||
@@ -502,7 +504,7 @@ void InputSection<E>::apply_reloc_nonalloc(Context<E> &ctx, u8 *base) {
|
||||
default:
|
||||
unreachable();
|
||||
}
|
||||
}
|
||||
});
|
||||
}
|
||||
|
||||
template <>
|
||||
@@ -516,8 +518,8 @@ void InputSection<E>::scan_relocations(Context<E> &ctx) {
|
||||
if (rel.r_type == R_NONE || record_undef_error(ctx, rel))
|
||||
continue;
|
||||
|
||||
Symbol<E> &sym = *file.symbols[rel.r_sym];
|
||||
u8 *loc = (u8 *)(contents.data() + rel.r_offset);
|
||||
Symbol<E> &sym = *file->symbols[rel.r_sym];
|
||||
u8 *loc = contents + rel.r_offset;
|
||||
|
||||
if (sym.is_ifunc())
|
||||
sym.flags |= NEEDS_GOT | NEEDS_PLT;
|
||||
|
||||
+92
-117
@@ -132,8 +132,8 @@ static void set_rj(u8 *loc, u32 rj) {
|
||||
// ld.d $t0, $t0, 0 # R_LARCH_GOT_PC_LO12, R_LARCH_RELAX
|
||||
static bool is_relaxable_got_load(Context<E> &ctx, InputSection<E> &isec, i64 i) {
|
||||
std::span<const ElfRel<E>> rels = isec.get_rels(ctx);
|
||||
Symbol<E> &sym = *isec.file.symbols[rels[i].r_sym];
|
||||
u8 *buf = (u8 *)isec.contents.data();
|
||||
Symbol<E> &sym = *isec.file->symbols[rels[i].r_sym];
|
||||
u8 *buf = isec.contents;
|
||||
|
||||
if (ctx.arg.relax &&
|
||||
sym.is_pcrel_linktime_const(ctx) &&
|
||||
@@ -219,9 +219,14 @@ void write_pltgot_entry<E>(Context<E> &ctx, u8 *buf, Symbol<E> &sym) {
|
||||
}
|
||||
|
||||
template <>
|
||||
void EhFrameSection<E>::apply_eh_reloc(Context<E> &ctx, const ElfRel<E> &rel,
|
||||
u64 offset, u64 val) {
|
||||
void EhFrameSection<E>::apply_eh_reloc(Context<E> &ctx, InputSection<E> &isec,
|
||||
const ElfRel<E> &rel, u64 offset, u64 val) {
|
||||
u8 *loc = ctx.buf + this->shdr.sh_offset + offset;
|
||||
u64 P = this->shdr.sh_addr + offset;
|
||||
|
||||
auto check = [&](i64 val, i64 lo, i64 hi) {
|
||||
check_range(ctx, isec, rel, val, lo, hi);
|
||||
};
|
||||
|
||||
switch (rel.r_type) {
|
||||
case R_NONE:
|
||||
@@ -257,7 +262,8 @@ void EhFrameSection<E>::apply_eh_reloc(Context<E> &ctx, const ElfRel<E> &rel,
|
||||
*(ul64 *)loc -= val;
|
||||
break;
|
||||
case R_LARCH_32_PCREL:
|
||||
*(ul32 *)loc = val - this->shdr.sh_addr - offset;
|
||||
check(val - P, -(1LL << 31), 1LL << 31);
|
||||
*(ul32 *)loc = val - P;
|
||||
break;
|
||||
case R_LARCH_64_PCREL:
|
||||
*(ul64 *)loc = val - this->shdr.sh_addr - offset;
|
||||
@@ -269,13 +275,13 @@ void EhFrameSection<E>::apply_eh_reloc(Context<E> &ctx, const ElfRel<E> &rel,
|
||||
|
||||
template <>
|
||||
void InputSection<E>::apply_reloc_alloc(Context<E> &ctx, u8 *base) {
|
||||
std::span<const ElfRel<E>> rels = get_rels(ctx);
|
||||
std::span<ElfRel<E>> rels = get_rels(ctx);
|
||||
std::span<RelocDelta> deltas = extra.r_deltas;
|
||||
i64 k = 0;
|
||||
u8 *buf = (u8 *)contents.data();
|
||||
u8 *buf = contents;
|
||||
|
||||
for (i64 i = 0; i < rels.size(); i++) {
|
||||
const ElfRel<E> &rel = rels[i];
|
||||
ElfRel<E> &rel = rels[i];
|
||||
|
||||
if (rel.r_type == R_NONE || rel.r_type == R_LARCH_RELAX ||
|
||||
rel.r_type == R_LARCH_MARK_LA || rel.r_type == R_LARCH_MARK_PCREL ||
|
||||
@@ -294,7 +300,10 @@ void InputSection<E>::apply_reloc_alloc(Context<E> &ctx, u8 *base) {
|
||||
r_delta = deltas[k - 1].delta;
|
||||
}
|
||||
|
||||
Symbol<E> &sym = *file.symbols[rel.r_sym];
|
||||
Symbol<E> &sym = *file->symbols[rel.r_sym];
|
||||
if (sym.get_type() == STT_TLS && sym.is_remaining_undef_weak())
|
||||
continue;
|
||||
|
||||
i64 r_offset = rel.r_offset - r_delta;
|
||||
u8 *loc = base + r_offset;
|
||||
|
||||
@@ -332,6 +341,11 @@ void InputSection<E>::apply_reloc_alloc(Context<E> &ctx, u8 *base) {
|
||||
<< " for relocation " << rel;
|
||||
};
|
||||
|
||||
auto rewrite = [&](i64 idx, u32 ty) {
|
||||
if (ctx.arg.emit_relocs)
|
||||
rels[idx].r_type = ty;
|
||||
};
|
||||
|
||||
switch (rel.r_type) {
|
||||
case R_LARCH_32:
|
||||
assert(E::is_64);
|
||||
@@ -346,7 +360,8 @@ void InputSection<E>::apply_reloc_alloc(Context<E> &ctx, u8 *base) {
|
||||
write_d5k16(loc, (S + A - P) >> 2);
|
||||
break;
|
||||
case R_LARCH_B26:
|
||||
check_branch(S + A - P, -(1 << 27), 1 << 27);
|
||||
if (!sym.is_remaining_undef_weak())
|
||||
check_branch(S + A - P, -(1 << 27), 1 << 27);
|
||||
write_d10k16(loc, (S + A - P) >> 2);
|
||||
break;
|
||||
case R_LARCH_ABS_LO12:
|
||||
@@ -375,10 +390,13 @@ void InputSection<E>::apply_reloc_alloc(Context<E> &ctx, u8 *base) {
|
||||
if (removed_bytes == 0) {
|
||||
write_j20(loc, hi20(S + A, P));
|
||||
} else {
|
||||
// Rewrite pcalau12i + addi.d with pcaddi
|
||||
// Rewrite pcalau12i + addi.d with pcaddi. The high part vanishes and
|
||||
// the low part becomes the pcaddi's PC-relative relocation.
|
||||
assert(removed_bytes == 4);
|
||||
*(ul32 *)loc = 0x1800'0000 | get_rd(*(ul32 *)loc); // pcaddi
|
||||
write_j20(loc, (S + A - P) >> 2);
|
||||
rewrite(i, R_NONE);
|
||||
rewrite(i + 2, R_LARCH_PCREL20_S2);
|
||||
i += 3;
|
||||
}
|
||||
break;
|
||||
@@ -417,10 +435,13 @@ void InputSection<E>::apply_reloc_alloc(Context<E> &ctx, u8 *base) {
|
||||
}
|
||||
write_j20(loc, hi20(GOT + G + A, P));
|
||||
} else {
|
||||
// Rewrite pcalau12i + ld.d with pcaddi
|
||||
// Rewrite pcalau12i + ld.d with pcaddi. The high part vanishes and the
|
||||
// low part becomes the pcaddi's PC-relative relocation.
|
||||
assert(removed_bytes == 4);
|
||||
*(ul32 *)loc = 0x1800'0000 | get_rd(*(ul32 *)loc); // pcaddi
|
||||
write_j20(loc, (S + A - P) >> 2);
|
||||
rewrite(i, R_NONE);
|
||||
rewrite(i + 2, R_LARCH_PCREL20_S2);
|
||||
i += 3;
|
||||
}
|
||||
break;
|
||||
@@ -527,7 +548,8 @@ void InputSection<E>::apply_reloc_alloc(Context<E> &ctx, u8 *base) {
|
||||
case R_LARCH_CALL36:
|
||||
if (removed_bytes == 0) {
|
||||
i64 val = S + A - P;
|
||||
check_branch(val, -(1LL << 37) - 0x20000, (1LL << 37) - 0x20000);
|
||||
if (!sym.is_remaining_undef_weak())
|
||||
check_branch(val, -(1LL << 37) - 0x20000, (1LL << 37) - 0x20000);
|
||||
write_j20(loc, (val + 0x20000) >> 18);
|
||||
write_k16(loc + 4, val >> 2);
|
||||
} else {
|
||||
@@ -538,6 +560,7 @@ void InputSection<E>::apply_reloc_alloc(Context<E> &ctx, u8 *base) {
|
||||
else
|
||||
*(ul32 *)loc = 0x5400'0000; // BL
|
||||
write_d10k16(loc, (S + A - P) >> 2);
|
||||
rewrite(i, R_LARCH_B26);
|
||||
}
|
||||
break;
|
||||
case R_LARCH_ADD_ULEB128:
|
||||
@@ -591,30 +614,49 @@ void InputSection<E>::apply_reloc_alloc(Context<E> &ctx, u8 *base) {
|
||||
// jirl $ra, $ra, 0
|
||||
if (sym.has_tlsdesc(ctx) && removed_bytes == 0)
|
||||
write_j20(loc, hi20(sym.get_tlsdesc_addr(ctx) + A, P));
|
||||
|
||||
// pcalau12i + addi.d => pcaddi when TLSDESC is kept; both deleted when it
|
||||
// is relaxed to IE/LE. Either way the high part loses its relocation.
|
||||
// The folded pcaddi's relocation is emitted from the LO12 slot below.
|
||||
if (!sym.has_tlsdesc(ctx) || removed_bytes)
|
||||
rewrite(i, R_NONE);
|
||||
break;
|
||||
case R_LARCH_TLS_DESC_PC_LO12:
|
||||
if (sym.has_tlsdesc(ctx) && removed_bytes == 0) {
|
||||
i64 dist = sym.get_tlsdesc_addr(ctx) + A - P;
|
||||
if (is_int(dist, 22)) {
|
||||
*(ul32 *)loc = 0x1800'0000 | get_rd(*(ul32 *)loc); // pcaddi
|
||||
write_j20(loc, dist >> 2);
|
||||
} else {
|
||||
write_k12(loc, sym.get_tlsdesc_addr(ctx) + A);
|
||||
if (sym.has_tlsdesc(ctx)) {
|
||||
if (removed_bytes == 0) {
|
||||
i64 dist = sym.get_tlsdesc_addr(ctx) + A - P;
|
||||
if (is_int(dist, 22)) {
|
||||
*(ul32 *)loc = 0x1800'0000 | get_rd(*(ul32 *)loc); // pcaddi
|
||||
write_j20(loc, dist >> 2);
|
||||
rewrite(i, R_LARCH_TLS_DESC_PCREL20_S2);
|
||||
} else {
|
||||
write_k12(loc, sym.get_tlsdesc_addr(ctx) + A);
|
||||
}
|
||||
}
|
||||
} else {
|
||||
rewrite(i, R_NONE);
|
||||
}
|
||||
break;
|
||||
case R_LARCH_TLS_DESC_LD:
|
||||
if (sym.has_tlsdesc(ctx) || removed_bytes == 4) {
|
||||
// Do nothing
|
||||
// TLSDESC is relaxed to IE or LE. The ld.d slot holds the first
|
||||
// instruction of the resulting sequence.
|
||||
if (sym.has_tlsdesc(ctx)) {
|
||||
// Do nothing (TLSDESC kept)
|
||||
} else if (removed_bytes == 4) {
|
||||
// Small TP offset: the instruction was deleted.
|
||||
rewrite(i, R_NONE);
|
||||
} else if (sym.has_gottp(ctx)) {
|
||||
*(ul32 *)loc = 0x1a00'0004; // pcalau12i $a0, 0
|
||||
write_j20(loc, hi20(sym.get_gottp_addr(ctx) + A, P));
|
||||
rewrite(i, R_LARCH_TLS_IE_PC_HI20);
|
||||
} else {
|
||||
*(ul32 *)loc = 0x1400'0004; // lu12i.w $a0, 0
|
||||
write_j20(loc, (S + A + 0x800 - ctx.tp_addr) >> 12);
|
||||
rewrite(i, R_LARCH_TLS_LE_HI20);
|
||||
}
|
||||
break;
|
||||
case R_LARCH_TLS_DESC_CALL:
|
||||
// The jirl slot holds the second instruction of the IE or LE sequence.
|
||||
if (sym.has_tlsdesc(ctx)) {
|
||||
// Do nothing
|
||||
} else if (sym.has_gottp(ctx)) {
|
||||
@@ -623,6 +665,7 @@ void InputSection<E>::apply_reloc_alloc(Context<E> &ctx, u8 *base) {
|
||||
else
|
||||
*(ul32 *)loc = 0x2880'0084; // ld.w $a0, $a0, 0
|
||||
write_k12(loc, sym.get_gottp_addr(ctx) + A);
|
||||
rewrite(i, R_LARCH_TLS_IE_PC_LO12);
|
||||
} else {
|
||||
i64 val = S + A - ctx.tp_addr;
|
||||
if (0 <= val && val < 0x1000)
|
||||
@@ -630,11 +673,16 @@ void InputSection<E>::apply_reloc_alloc(Context<E> &ctx, u8 *base) {
|
||||
else
|
||||
*(ul32 *)loc = 0x0280'0084; // addi.w $a0, $a0, 0
|
||||
write_k12(loc, val);
|
||||
rewrite(i, R_LARCH_TLS_LE_LO12);
|
||||
}
|
||||
break;
|
||||
case R_LARCH_TLS_LE_HI20_R:
|
||||
// lu12i.w + add.d + addi.d => addi.d when the variable is within 2 KiB
|
||||
// of TP, in which case the lu12i.w loses its relocation.
|
||||
if (removed_bytes == 0)
|
||||
write_j20(loc, (S + A + 0x800 - ctx.tp_addr) >> 12);
|
||||
else
|
||||
rewrite(i, R_NONE);
|
||||
break;
|
||||
case R_LARCH_TLS_LE_LO12_R: {
|
||||
i64 val = S + A - ctx.tp_addr;
|
||||
@@ -646,8 +694,13 @@ void InputSection<E>::apply_reloc_alloc(Context<E> &ctx, u8 *base) {
|
||||
set_rj(loc, 2);
|
||||
break;
|
||||
}
|
||||
case R_LARCH_64:
|
||||
case R_LARCH_TLS_LE_ADD_R:
|
||||
// add.d that materializes TP + offset; removed together with the
|
||||
// lu12i.w when the variable is within 2 KiB of TP.
|
||||
if (removed_bytes)
|
||||
rewrite(i, R_NONE);
|
||||
break;
|
||||
case R_LARCH_64:
|
||||
break;
|
||||
default:
|
||||
unreachable();
|
||||
@@ -657,19 +710,16 @@ void InputSection<E>::apply_reloc_alloc(Context<E> &ctx, u8 *base) {
|
||||
|
||||
template <>
|
||||
void InputSection<E>::apply_reloc_nonalloc(Context<E> &ctx, u8 *base) {
|
||||
std::span<const ElfRel<E>> rels = get_rels(ctx);
|
||||
|
||||
for (i64 i = 0; i < rels.size(); i++) {
|
||||
const ElfRel<E> &rel = rels[i];
|
||||
for_each_reloc(ctx, [&](const ElfRel<E> &rel, i64) ALWAYS_INLINE {
|
||||
if (rel.r_type == R_NONE)
|
||||
continue;
|
||||
return;
|
||||
|
||||
Symbol<E> &sym = *file.symbols[rel.r_sym];
|
||||
Symbol<E> &sym = *file->symbols[rel.r_sym];
|
||||
u8 *loc = base + rel.r_offset;
|
||||
|
||||
if (!sym.file) {
|
||||
if (!sym.file && &sym != discarded_comdat_sym<E>) {
|
||||
record_undef_error(ctx, rel);
|
||||
continue;
|
||||
return;
|
||||
}
|
||||
|
||||
SectionFragment<E> *frag;
|
||||
@@ -742,7 +792,7 @@ void InputSection<E>::apply_reloc_nonalloc(Context<E> &ctx, u8 *base) {
|
||||
<< rel;
|
||||
break;
|
||||
}
|
||||
}
|
||||
});
|
||||
}
|
||||
|
||||
template <>
|
||||
@@ -762,7 +812,7 @@ void InputSection<E>::scan_relocations(Context<E> &ctx) {
|
||||
if (record_undef_error(ctx, rel))
|
||||
continue;
|
||||
|
||||
Symbol<E> &sym = *file.symbols[rel.r_sym];
|
||||
Symbol<E> &sym = *file->symbols[rel.r_sym];
|
||||
|
||||
if (sym.is_ifunc())
|
||||
sym.flags |= NEEDS_GOT | NEEDS_PLT;
|
||||
@@ -855,13 +905,13 @@ void InputSection<E>::scan_relocations(Context<E> &ctx) {
|
||||
template <>
|
||||
void shrink_section(Context<E> &ctx, InputSection<E> &isec) {
|
||||
std::span<const ElfRel<E>> rels = isec.get_rels(ctx);
|
||||
std::vector<RelocDelta> &deltas = isec.extra.r_deltas;
|
||||
std::vector<RelocDelta> deltas;
|
||||
i64 r_delta = 0;
|
||||
u8 *buf = (u8 *)isec.contents.data();
|
||||
u8 *buf = isec.contents;
|
||||
|
||||
for (i64 i = 0; i < rels.size(); i++) {
|
||||
const ElfRel<E> &r = rels[i];
|
||||
Symbol<E> &sym = *isec.file.symbols[r.r_sym];
|
||||
Symbol<E> &sym = *isec.file->symbols[r.r_sym];
|
||||
|
||||
auto remove = [&](i64 d) {
|
||||
r_delta += d;
|
||||
@@ -1007,90 +1057,15 @@ void shrink_section(Context<E> &ctx, InputSection<E> &isec) {
|
||||
}
|
||||
}
|
||||
|
||||
if (deltas.empty())
|
||||
return;
|
||||
|
||||
RelocDelta *p = ctx.arena.template allocate<RelocDelta>(deltas.size());
|
||||
ranges::copy(deltas, p);
|
||||
isec.extra.r_deltas = {p, deltas.size()};
|
||||
isec.sh_size -= r_delta;
|
||||
}
|
||||
|
||||
// With --emit-relocs, rewrite the emitted relocations to match the
|
||||
// instructions that relaxation produced. The logic parallels apply_reloc_alloc.
|
||||
template <>
|
||||
void rewrite_reloc_types(Context<E> &ctx, InputSection<E> &isec, ElfRel<E> *buf) {
|
||||
std::span<const ElfRel<E>> rels = isec.get_rels(ctx);
|
||||
std::span<RelocDelta> deltas = isec.extra.r_deltas;
|
||||
i64 k = 0;
|
||||
|
||||
for (i64 i = 0; i < rels.size(); i++) {
|
||||
const ElfRel<E> &rel = rels[i];
|
||||
Symbol<E> &sym = *isec.file.symbols[rel.r_sym];
|
||||
|
||||
i64 removed_bytes = 0;
|
||||
if (!deltas.empty()) {
|
||||
while (k < deltas.size() && deltas[k].offset < rel.r_offset)
|
||||
k++;
|
||||
if (k < deltas.size() && deltas[k].offset == rel.r_offset)
|
||||
removed_bytes = get_removed_bytes(deltas, k);
|
||||
}
|
||||
|
||||
switch (rel.r_type) {
|
||||
case R_LARCH_TLS_LE_HI20_R:
|
||||
case R_LARCH_TLS_LE_ADD_R:
|
||||
// lu12i.w + add.d + addi.d => addi.d
|
||||
if (removed_bytes)
|
||||
buf[i].r_type = R_LARCH_NONE;
|
||||
break;
|
||||
case R_LARCH_PCALA_HI20:
|
||||
case R_LARCH_GOT_PC_HI20:
|
||||
// pcalau12i + addi.d/ld.d => pcaddi. The high part vanishes and the low
|
||||
// part becomes the pcaddi's PC-relative relocation.
|
||||
if (removed_bytes) {
|
||||
buf[i].r_type = R_LARCH_NONE;
|
||||
buf[i + 2].r_type = R_LARCH_PCREL20_S2;
|
||||
i += 3;
|
||||
}
|
||||
break;
|
||||
case R_LARCH_CALL36:
|
||||
// pcaddu18i + jirl => b or bl
|
||||
if (removed_bytes)
|
||||
buf[i].r_type = R_LARCH_B26;
|
||||
break;
|
||||
case R_LARCH_TLS_DESC_PC_HI20:
|
||||
// pcalau12i + addi.d => pcaddi when TLSDESC is kept; both deleted when it
|
||||
// is relaxed to IE/LE.
|
||||
if (!sym.has_tlsdesc(ctx)) {
|
||||
buf[i].r_type = R_LARCH_NONE;
|
||||
} else if (removed_bytes) {
|
||||
buf[i].r_type = R_LARCH_NONE;
|
||||
buf[i + 2].r_type = R_LARCH_TLS_DESC_PCREL20_S2;
|
||||
}
|
||||
break;
|
||||
case R_LARCH_TLS_DESC_PC_LO12:
|
||||
if (!sym.has_tlsdesc(ctx))
|
||||
buf[i].r_type = R_LARCH_NONE;
|
||||
break;
|
||||
case R_LARCH_TLS_DESC_LD:
|
||||
// TLSDESC is relaxed to IE or LE. The ld.d slot holds the first
|
||||
// instruction of the resulting sequence.
|
||||
if (sym.has_tlsdesc(ctx))
|
||||
break;
|
||||
if (sym.has_gottp(ctx))
|
||||
buf[i].r_type = R_LARCH_TLS_IE_PC_HI20; // pcalau12i
|
||||
else if (removed_bytes)
|
||||
buf[i].r_type = R_LARCH_NONE; // small TP offset (deleted)
|
||||
else
|
||||
buf[i].r_type = R_LARCH_TLS_LE_HI20; // large TP offset (lu12i.w)
|
||||
break;
|
||||
case R_LARCH_TLS_DESC_CALL:
|
||||
// The jirl slot holds the second instruction of the IE or LE sequence.
|
||||
if (sym.has_tlsdesc(ctx))
|
||||
break;
|
||||
if (sym.has_gottp(ctx))
|
||||
buf[i].r_type = R_LARCH_TLS_IE_PC_LO12; // ld.d
|
||||
else
|
||||
buf[i].r_type = R_LARCH_TLS_LE_LO12; // ori or addi.w
|
||||
break;
|
||||
}
|
||||
}
|
||||
}
|
||||
|
||||
} // namespace mold
|
||||
|
||||
#endif
|
||||
+17
-11
@@ -58,8 +58,8 @@ void write_pltgot_entry(Context<E> &ctx, u8 *buf, Symbol<E> &sym) {
|
||||
}
|
||||
|
||||
template <>
|
||||
void EhFrameSection<E>::apply_eh_reloc(Context<E> &ctx, const ElfRel<E> &rel,
|
||||
u64 offset, u64 val) {
|
||||
void EhFrameSection<E>::apply_eh_reloc(Context<E> &ctx, InputSection<E> &isec,
|
||||
const ElfRel<E> &rel, u64 offset, u64 val) {
|
||||
u8 *loc = ctx.buf + this->shdr.sh_offset + offset;
|
||||
|
||||
switch (rel.r_type) {
|
||||
@@ -85,7 +85,10 @@ void InputSection<E>::apply_reloc_alloc(Context<E> &ctx, u8 *base) {
|
||||
if (rel.r_type == R_NONE)
|
||||
continue;
|
||||
|
||||
Symbol<E> &sym = *file.symbols[rel.r_sym];
|
||||
Symbol<E> &sym = *file->symbols[rel.r_sym];
|
||||
if (sym.get_type() == STT_TLS && sym.is_remaining_undef_weak())
|
||||
continue;
|
||||
|
||||
u8 *loc = base + rel.r_offset;
|
||||
|
||||
u64 S = sym.get_addr(ctx);
|
||||
@@ -210,14 +213,11 @@ void InputSection<E>::apply_reloc_alloc(Context<E> &ctx, u8 *base) {
|
||||
|
||||
template <>
|
||||
void InputSection<E>::apply_reloc_nonalloc(Context<E> &ctx, u8 *base) {
|
||||
std::span<const ElfRel<E>> rels = get_rels(ctx);
|
||||
|
||||
for (i64 i = 0; i < rels.size(); i++) {
|
||||
const ElfRel<E> &rel = rels[i];
|
||||
for_each_reloc(ctx, [&](const ElfRel<E> &rel, i64) ALWAYS_INLINE {
|
||||
if (rel.r_type == R_NONE || record_undef_error(ctx, rel))
|
||||
continue;
|
||||
return;
|
||||
|
||||
Symbol<E> &sym = *file.symbols[rel.r_sym];
|
||||
Symbol<E> &sym = *file->symbols[rel.r_sym];
|
||||
u8 *loc = base + rel.r_offset;
|
||||
|
||||
SectionFragment<E> *frag;
|
||||
@@ -234,11 +234,17 @@ void InputSection<E>::apply_reloc_nonalloc(Context<E> &ctx, u8 *base) {
|
||||
else
|
||||
*(ub32 *)loc = S + A;
|
||||
break;
|
||||
case R_68K_TLS_LDO32:
|
||||
if (std::optional<u64> val = get_tombstone(sym, frag))
|
||||
*(ub32 *)loc = *val;
|
||||
else
|
||||
*(ub32 *)loc = S + A - ctx.dtp_addr;
|
||||
break;
|
||||
default:
|
||||
Fatal(ctx) << *this << ": invalid relocation for non-allocated sections: "
|
||||
<< rel;
|
||||
}
|
||||
}
|
||||
});
|
||||
}
|
||||
|
||||
template <>
|
||||
@@ -251,7 +257,7 @@ void InputSection<E>::scan_relocations(Context<E> &ctx) {
|
||||
if (rel.r_type == R_NONE || record_undef_error(ctx, rel))
|
||||
continue;
|
||||
|
||||
Symbol<E> &sym = *file.symbols[rel.r_sym];
|
||||
Symbol<E> &sym = *file->symbols[rel.r_sym];
|
||||
|
||||
if (sym.is_ifunc())
|
||||
Error(ctx) << sym << ": GNU ifunc symbol is not supported on m68k";
|
||||
|
||||
+12
-12
@@ -128,8 +128,8 @@ void write_pltgot_entry(Context<E> &ctx, u8 *buf, Symbol<E> &sym) {
|
||||
}
|
||||
|
||||
template <>
|
||||
void EhFrameSection<E>::apply_eh_reloc(Context<E> &ctx, const ElfRel<E> &rel,
|
||||
u64 offset, u64 val) {
|
||||
void EhFrameSection<E>::apply_eh_reloc(Context<E> &ctx, InputSection<E> &isec,
|
||||
const ElfRel<E> &rel, u64 offset, u64 val) {
|
||||
u8 *loc = ctx.buf + this->shdr.sh_offset + offset;
|
||||
|
||||
switch (rel.r_type) {
|
||||
@@ -150,14 +150,17 @@ template <>
|
||||
void InputSection<E>::apply_reloc_alloc(Context<E> &ctx, u8 *base) {
|
||||
std::span<const ElfRel<E>> rels = get_rels(ctx);
|
||||
|
||||
u64 GOT2 = file.extra.got2 ? file.extra.got2->get_addr() : 0;
|
||||
u64 GOT2 = file->extra.got2 ? file->extra.got2->get_addr() : 0;
|
||||
|
||||
for (i64 i = 0; i < rels.size(); i++) {
|
||||
const ElfRel<E> &rel = rels[i];
|
||||
if (rel.r_type == R_NONE)
|
||||
continue;
|
||||
|
||||
Symbol<E> &sym = *file.symbols[rel.r_sym];
|
||||
Symbol<E> &sym = *file->symbols[rel.r_sym];
|
||||
if (sym.get_type() == STT_TLS && sym.is_remaining_undef_weak())
|
||||
continue;
|
||||
|
||||
u8 *loc = base + rel.r_offset;
|
||||
|
||||
u64 S = sym.get_addr(ctx);
|
||||
@@ -284,14 +287,11 @@ void InputSection<E>::apply_reloc_alloc(Context<E> &ctx, u8 *base) {
|
||||
|
||||
template <>
|
||||
void InputSection<E>::apply_reloc_nonalloc(Context<E> &ctx, u8 *base) {
|
||||
std::span<const ElfRel<E>> rels = get_rels(ctx);
|
||||
|
||||
for (i64 i = 0; i < rels.size(); i++) {
|
||||
const ElfRel<E> &rel = rels[i];
|
||||
for_each_reloc(ctx, [&](const ElfRel<E> &rel, i64) ALWAYS_INLINE {
|
||||
if (rel.r_type == R_NONE || record_undef_error(ctx, rel))
|
||||
continue;
|
||||
return;
|
||||
|
||||
Symbol<E> &sym = *file.symbols[rel.r_sym];
|
||||
Symbol<E> &sym = *file->symbols[rel.r_sym];
|
||||
u8 *loc = base + rel.r_offset;
|
||||
|
||||
SectionFragment<E> *frag;
|
||||
@@ -318,7 +318,7 @@ void InputSection<E>::apply_reloc_nonalloc(Context<E> &ctx, u8 *base) {
|
||||
Fatal(ctx) << *this << ": invalid relocation for non-allocated sections: "
|
||||
<< rel;
|
||||
}
|
||||
}
|
||||
});
|
||||
}
|
||||
|
||||
template <>
|
||||
@@ -332,7 +332,7 @@ void InputSection<E>::scan_relocations(Context<E> &ctx) {
|
||||
if (rel.r_type == R_NONE || record_undef_error(ctx, rel))
|
||||
continue;
|
||||
|
||||
Symbol<E> &sym = *file.symbols[rel.r_sym];
|
||||
Symbol<E> &sym = *file->symbols[rel.r_sym];
|
||||
|
||||
if (sym.is_ifunc())
|
||||
sym.flags |= NEEDS_GOT | NEEDS_PLT;
|
||||
|
||||
+55
-31
@@ -131,9 +131,14 @@ template <>
|
||||
void write_pltgot_entry(Context<E> &ctx, u8 *buf, Symbol<E> &sym) {}
|
||||
|
||||
template <>
|
||||
void EhFrameSection<E>::apply_eh_reloc(Context<E> &ctx, const ElfRel<E> &rel,
|
||||
u64 offset, u64 val) {
|
||||
void EhFrameSection<E>::apply_eh_reloc(Context<E> &ctx, InputSection<E> &isec,
|
||||
const ElfRel<E> &rel, u64 offset, u64 val) {
|
||||
u8 *loc = ctx.buf + this->shdr.sh_offset + offset;
|
||||
u64 P = this->shdr.sh_addr + offset;
|
||||
|
||||
auto check = [&](i64 val, i64 lo, i64 hi) {
|
||||
check_range(ctx, isec, rel, val, lo, hi);
|
||||
};
|
||||
|
||||
switch (rel.r_type) {
|
||||
case R_NONE:
|
||||
@@ -142,10 +147,11 @@ void EhFrameSection<E>::apply_eh_reloc(Context<E> &ctx, const ElfRel<E> &rel,
|
||||
*(ub64 *)loc = val;
|
||||
break;
|
||||
case R_PPC64_REL32:
|
||||
*(ub32 *)loc = val - this->shdr.sh_addr - offset;
|
||||
check(val - P, -(1LL << 31), 1LL << 31);
|
||||
*(ub32 *)loc = val - P;
|
||||
break;
|
||||
case R_PPC64_REL64:
|
||||
*(ub64 *)loc = val - this->shdr.sh_addr - offset;
|
||||
*(ub64 *)loc = val - P;
|
||||
break;
|
||||
default:
|
||||
Fatal(ctx) << "unsupported relocation in .eh_frame: " << rel;
|
||||
@@ -161,7 +167,10 @@ void InputSection<E>::apply_reloc_alloc(Context<E> &ctx, u8 *base) {
|
||||
if (rel.r_type == R_NONE)
|
||||
continue;
|
||||
|
||||
Symbol<E> &sym = *file.symbols[rel.r_sym];
|
||||
Symbol<E> &sym = *file->symbols[rel.r_sym];
|
||||
if (sym.get_type() == STT_TLS && sym.is_remaining_undef_weak())
|
||||
continue;
|
||||
|
||||
u8 *loc = base + rel.r_offset;
|
||||
|
||||
u64 S = sym.get_addr(ctx);
|
||||
@@ -285,14 +294,11 @@ void InputSection<E>::apply_reloc_alloc(Context<E> &ctx, u8 *base) {
|
||||
|
||||
template <>
|
||||
void InputSection<E>::apply_reloc_nonalloc(Context<E> &ctx, u8 *base) {
|
||||
std::span<const ElfRel<E>> rels = get_rels(ctx);
|
||||
|
||||
for (i64 i = 0; i < rels.size(); i++) {
|
||||
const ElfRel<E> &rel = rels[i];
|
||||
for_each_reloc(ctx, [&](const ElfRel<E> &rel, i64 i) ALWAYS_INLINE {
|
||||
if (rel.r_type == R_NONE || record_undef_error(ctx, rel))
|
||||
continue;
|
||||
return;
|
||||
|
||||
Symbol<E> &sym = *file.symbols[rel.r_sym];
|
||||
Symbol<E> &sym = *file->symbols[rel.r_sym];
|
||||
u8 *loc = base + rel.r_offset;
|
||||
|
||||
SectionFragment<E> *frag;
|
||||
@@ -303,7 +309,7 @@ void InputSection<E>::apply_reloc_nonalloc(Context<E> &ctx, u8 *base) {
|
||||
u64 A = frag ? frag_addend : (i64)rel.r_addend;
|
||||
|
||||
auto check = [&](i64 val, i64 lo, i64 hi) {
|
||||
check_range(ctx, val, i, lo, hi);
|
||||
check_range(ctx, i, val, lo, hi);
|
||||
};
|
||||
|
||||
switch (rel.r_type) {
|
||||
@@ -324,7 +330,7 @@ void InputSection<E>::apply_reloc_nonalloc(Context<E> &ctx, u8 *base) {
|
||||
Fatal(ctx) << *this << ": invalid relocation for non-allocated sections: "
|
||||
<< rel;
|
||||
}
|
||||
}
|
||||
});
|
||||
}
|
||||
|
||||
template <>
|
||||
@@ -338,7 +344,7 @@ void InputSection<E>::scan_relocations(Context<E> &ctx) {
|
||||
if (rel.r_type == R_NONE || record_undef_error(ctx, rel))
|
||||
continue;
|
||||
|
||||
Symbol<E> &sym = *file.symbols[rel.r_sym];
|
||||
Symbol<E> &sym = *file->symbols[rel.r_sym];
|
||||
|
||||
if (sym.is_ifunc())
|
||||
sym.flags |= NEEDS_GOT | NEEDS_PLT | NEEDS_PPC_OPD;
|
||||
@@ -485,9 +491,9 @@ void Thunk<E>::copy_buf(Context<E> &ctx) {
|
||||
}
|
||||
|
||||
static InputSection<E> *get_opd_section(ObjectFile<E> &file) {
|
||||
for (std::unique_ptr<InputSection<E>> &isec : file.sections)
|
||||
if (isec && isec->name == ".opd")
|
||||
return isec.get();
|
||||
for (InputSection<E> *isec : file.sections)
|
||||
if (isec && isec->name() == ".opd")
|
||||
return isec;
|
||||
return nullptr;
|
||||
}
|
||||
|
||||
@@ -563,7 +569,7 @@ void ppc64v1_rewrite_opd(Context<E> &ctx) {
|
||||
InputSection<E> *opd = get_opd_section(*file);
|
||||
if (!opd)
|
||||
return;
|
||||
opd->is_alive = false;
|
||||
opd->kill();
|
||||
|
||||
// Move symbols from .opd to .text.
|
||||
std::vector<OpdSymbol> opd_syms;
|
||||
@@ -594,8 +600,8 @@ void ppc64v1_rewrite_opd(Context<E> &ctx) {
|
||||
ranges::stable_sort(opd_syms, {}, &OpdSymbol::r_offset);
|
||||
|
||||
// Rewrite relocations so that they directly refer to .opd.
|
||||
for (std::unique_ptr<InputSection<E>> &isec : file->sections) {
|
||||
if (!isec || !isec->is_alive || isec.get() == opd)
|
||||
for (InputSection<E> *isec : file->sections) {
|
||||
if (!isec || !isec->is_alive() || isec == opd)
|
||||
continue;
|
||||
|
||||
for (ElfRel<E> &r : isec->get_rels(ctx)) {
|
||||
@@ -619,11 +625,10 @@ void ppc64v1_rewrite_opd(Context<E> &ctx) {
|
||||
// refers to the function's .opd entry. This function marks such symbols
|
||||
// with NEEDS_PPC_OPD.
|
||||
void ppc64v1_scan_symbols(Context<E> &ctx) {
|
||||
tbb::parallel_for_each(ctx.objs, [&](ObjectFile<E> *file) {
|
||||
for (Symbol<E> *sym : file->symbols)
|
||||
if (sym->file == file && sym->is_exported)
|
||||
if (u32 ty = sym->get_type(); ty == STT_FUNC || ty == STT_GNU_IFUNC)
|
||||
sym->flags |= NEEDS_PPC_OPD;
|
||||
ctx.symbol_map.parallel_for_each([](Symbol<E> &sym) {
|
||||
if (sym.file && !sym.file->is_dso && sym.is_exported)
|
||||
if (u32 ty = sym.get_type(); ty == STT_FUNC || ty == STT_GNU_IFUNC)
|
||||
sym.flags |= NEEDS_PPC_OPD;
|
||||
});
|
||||
|
||||
// Functions referenced by the ELF header also have to have .opd entries.
|
||||
@@ -638,23 +643,42 @@ void ppc64v1_scan_symbols(Context<E> &ctx) {
|
||||
}
|
||||
|
||||
void PPC64OpdSection::add_symbol(Context<E> &ctx, Symbol<E> *sym) {
|
||||
sym->set_opd_idx(ctx, symbols.size());
|
||||
sym->aux->opd_idx = symbols.size();
|
||||
symbols.push_back(sym);
|
||||
this->shdr.sh_size += ENTRY_SIZE;
|
||||
}
|
||||
|
||||
std::vector<ElfRel<E>> PPC64OpdSection::collect_dynrels(Context<E> &ctx) const {
|
||||
i64 PPC64OpdSection::get_num_dynrels(Context<E> &ctx) const {
|
||||
return ctx.arg.pic ? symbols.size() * 2 : 0;
|
||||
}
|
||||
|
||||
std::vector<u64> PPC64OpdSection::get_relr_offsets(Context<E> &ctx) {
|
||||
if (!ctx.arg.pic)
|
||||
return {};
|
||||
|
||||
std::vector<ElfRel<E>> rels;
|
||||
std::vector<u64> offsets;
|
||||
offsets.reserve(symbols.size() * 2);
|
||||
for (Symbol<E> *sym : symbols) {
|
||||
u64 loc = sym->get_opd_addr(ctx) - this->shdr.sh_addr;
|
||||
offsets.push_back(loc);
|
||||
offsets.push_back(loc + 8);
|
||||
}
|
||||
return offsets;
|
||||
}
|
||||
|
||||
void PPC64OpdSection::write_dynrels(Context<E> &ctx, ElfRel<E> *buf) const {
|
||||
if (!ctx.arg.pic)
|
||||
return;
|
||||
|
||||
for (Symbol<E> *sym : symbols) {
|
||||
u64 loc = sym->get_opd_addr(ctx);
|
||||
rels.emplace_back(loc, E::R_RELATIVE, 0, sym->get_addr(ctx, NO_PLT | NO_OPD));
|
||||
rels.emplace_back(loc + 8, E::R_RELATIVE, 0, ctx.extra.TOC->value);
|
||||
if (!ctx.arg.pack_dyn_relocs_relr || !this->num_relrs ||
|
||||
loc % sizeof(Word<E>) != 0)
|
||||
*buf++ = ElfRel<E>(loc, E::R_RELATIVE, 0, sym->get_addr(ctx, NO_PLT | NO_OPD));
|
||||
if (!ctx.arg.pack_dyn_relocs_relr || !this->num_relrs ||
|
||||
(loc + 8) % sizeof(Word<E>) != 0)
|
||||
*buf++ = ElfRel<E>(loc + 8, E::R_RELATIVE, 0, ctx.extra.TOC->value);
|
||||
}
|
||||
return rels;
|
||||
}
|
||||
|
||||
void PPC64OpdSection::copy_buf(Context<E> &ctx) {
|
||||
|
||||
+129
-15
@@ -152,9 +152,14 @@ template <>
|
||||
void write_pltgot_entry(Context<E> &ctx, u8 *buf, Symbol<E> &sym) {}
|
||||
|
||||
template <>
|
||||
void EhFrameSection<E>::apply_eh_reloc(Context<E> &ctx, const ElfRel<E> &rel,
|
||||
u64 offset, u64 val) {
|
||||
void EhFrameSection<E>::apply_eh_reloc(Context<E> &ctx, InputSection<E> &isec,
|
||||
const ElfRel<E> &rel, u64 offset, u64 val) {
|
||||
u8 *loc = ctx.buf + this->shdr.sh_offset + offset;
|
||||
u64 P = this->shdr.sh_addr + offset;
|
||||
|
||||
auto check = [&](i64 val, i64 lo, i64 hi) {
|
||||
check_range(ctx, isec, rel, val, lo, hi);
|
||||
};
|
||||
|
||||
switch (rel.r_type) {
|
||||
case R_NONE:
|
||||
@@ -163,10 +168,11 @@ void EhFrameSection<E>::apply_eh_reloc(Context<E> &ctx, const ElfRel<E> &rel,
|
||||
*(ul64 *)loc = val;
|
||||
break;
|
||||
case R_PPC64_REL32:
|
||||
*(ul32 *)loc = val - this->shdr.sh_addr - offset;
|
||||
check(val - P, -(1LL << 31), 1LL << 31);
|
||||
*(ul32 *)loc = val - P;
|
||||
break;
|
||||
case R_PPC64_REL64:
|
||||
*(ul64 *)loc = val - this->shdr.sh_addr - offset;
|
||||
*(ul64 *)loc = val - P;
|
||||
break;
|
||||
default:
|
||||
Fatal(ctx) << "unsupported relocation in .eh_frame: " << rel;
|
||||
@@ -193,7 +199,10 @@ void InputSection<E>::apply_reloc_alloc(Context<E> &ctx, u8 *base) {
|
||||
if (rel.r_type == R_NONE)
|
||||
continue;
|
||||
|
||||
Symbol<E> &sym = *file.symbols[rel.r_sym];
|
||||
Symbol<E> &sym = *file->symbols[rel.r_sym];
|
||||
if (sym.get_type() == STT_TLS && sym.is_remaining_undef_weak())
|
||||
continue;
|
||||
|
||||
u8 *loc = base + rel.r_offset;
|
||||
|
||||
u64 S = sym.get_addr(ctx);
|
||||
@@ -206,6 +215,10 @@ void InputSection<E>::apply_reloc_alloc(Context<E> &ctx, u8 *base) {
|
||||
auto r2save_thunk_addr = [&] { return sym.get_thunk_addr(ctx, P); };
|
||||
auto no_r2save_thunk_addr = [&] { return sym.get_thunk_addr(ctx, P) + 8; };
|
||||
|
||||
auto check = [&](i64 val, i64 lo, i64 hi) {
|
||||
check_range(ctx, i, val, lo, hi);
|
||||
};
|
||||
|
||||
switch (rel.r_type) {
|
||||
case R_PPC64_TOC16_HA:
|
||||
*(ul16 *)loc = ha(S + A - TOC);
|
||||
@@ -214,6 +227,9 @@ void InputSection<E>::apply_reloc_alloc(Context<E> &ctx, u8 *base) {
|
||||
*(ul16 *)loc = lo(S + A - TOC);
|
||||
break;
|
||||
case R_PPC64_TOC16_DS:
|
||||
check(S + A - TOC, -(1 << 15), 1 << 15);
|
||||
*(ul16 *)loc |= (S + A - TOC) & 0xfffc;
|
||||
break;
|
||||
case R_PPC64_TOC16_LO_DS:
|
||||
*(ul16 *)loc |= (S + A - TOC) & 0xfffc;
|
||||
break;
|
||||
@@ -361,14 +377,11 @@ void InputSection<E>::apply_reloc_alloc(Context<E> &ctx, u8 *base) {
|
||||
|
||||
template <>
|
||||
void InputSection<E>::apply_reloc_nonalloc(Context<E> &ctx, u8 *base) {
|
||||
std::span<const ElfRel<E>> rels = get_rels(ctx);
|
||||
|
||||
for (i64 i = 0; i < rels.size(); i++) {
|
||||
const ElfRel<E> &rel = rels[i];
|
||||
for_each_reloc(ctx, [&](const ElfRel<E> &rel, i64 i) ALWAYS_INLINE {
|
||||
if (rel.r_type == R_NONE || record_undef_error(ctx, rel))
|
||||
continue;
|
||||
return;
|
||||
|
||||
Symbol<E> &sym = *file.symbols[rel.r_sym];
|
||||
Symbol<E> &sym = *file->symbols[rel.r_sym];
|
||||
u8 *loc = base + rel.r_offset;
|
||||
|
||||
SectionFragment<E> *frag;
|
||||
@@ -400,7 +413,7 @@ void InputSection<E>::apply_reloc_nonalloc(Context<E> &ctx, u8 *base) {
|
||||
Fatal(ctx) << *this << ": invalid relocation for non-allocated sections: "
|
||||
<< rel;
|
||||
}
|
||||
}
|
||||
});
|
||||
}
|
||||
|
||||
template <>
|
||||
@@ -414,7 +427,7 @@ void InputSection<E>::scan_relocations(Context<E> &ctx) {
|
||||
if (rel.r_type == R_NONE || record_undef_error(ctx, rel))
|
||||
continue;
|
||||
|
||||
Symbol<E> &sym = *file.symbols[rel.r_sym];
|
||||
Symbol<E> &sym = *file->symbols[rel.r_sym];
|
||||
|
||||
if (sym.is_ifunc())
|
||||
sym.flags |= NEEDS_GOT | NEEDS_PLT;
|
||||
@@ -573,8 +586,9 @@ void Thunk<E>::copy_buf(Context<E> &ctx) {
|
||||
}
|
||||
|
||||
// GCC may emit references to the following functions in function prologue
|
||||
// and epiilogue if -Os is specified. For some reason, these functions are
|
||||
// not in libgcc.a and expected to be synthesized by the linker.
|
||||
// and epilogue if -Os is specified. For some reason, these functions are
|
||||
// not in libgcc.a and expected to be synthesized by the linker. There are
|
||||
// variants for general-purpose, floating-point and vector registers.
|
||||
const std::vector<std::pair<std::string_view, u32>>
|
||||
ppc64_save_restore_insns = {
|
||||
{ "_savegpr0_14", 0xf9c1ff70 }, // std r14,-144(r1)
|
||||
@@ -664,6 +678,106 @@ ppc64_save_restore_insns = {
|
||||
{ "_restgpr1_30", 0xebccfff0 }, // ld r30,-16(r12)
|
||||
{ "_restgpr1_31", 0xebecfff8 }, // ld r31,-8(r12)
|
||||
{ "", 0x4e800020 }, // blr
|
||||
|
||||
{ "_savefpr_14", 0xd9c1ff70 }, // stfd f14,-144(r1)
|
||||
{ "_savefpr_15", 0xd9e1ff78 }, // stfd f15,-136(r1)
|
||||
{ "_savefpr_16", 0xda01ff80 }, // stfd f16,-128(r1)
|
||||
{ "_savefpr_17", 0xda21ff88 }, // stfd f17,-120(r1)
|
||||
{ "_savefpr_18", 0xda41ff90 }, // stfd f18,-112(r1)
|
||||
{ "_savefpr_19", 0xda61ff98 }, // stfd f19,-104(r1)
|
||||
{ "_savefpr_20", 0xda81ffa0 }, // stfd f20,-96(r1)
|
||||
{ "_savefpr_21", 0xdaa1ffa8 }, // stfd f21,-88(r1)
|
||||
{ "_savefpr_22", 0xdac1ffb0 }, // stfd f22,-80(r1)
|
||||
{ "_savefpr_23", 0xdae1ffb8 }, // stfd f23,-72(r1)
|
||||
{ "_savefpr_24", 0xdb01ffc0 }, // stfd f24,-64(r1)
|
||||
{ "_savefpr_25", 0xdb21ffc8 }, // stfd f25,-56(r1)
|
||||
{ "_savefpr_26", 0xdb41ffd0 }, // stfd f26,-48(r1)
|
||||
{ "_savefpr_27", 0xdb61ffd8 }, // stfd f27,-40(r1)
|
||||
{ "_savefpr_28", 0xdb81ffe0 }, // stfd f28,-32(r1)
|
||||
{ "_savefpr_29", 0xdba1ffe8 }, // stfd f29,-24(r1)
|
||||
{ "_savefpr_30", 0xdbc1fff0 }, // stfd f30,-16(r1)
|
||||
{ "_savefpr_31", 0xdbe1fff8 }, // stfd f31,-8(r1)
|
||||
{ "", 0xf8010010 }, // std r0,16(r1)
|
||||
{ "", 0x4e800020 }, // blr
|
||||
|
||||
{ "_restfpr_14", 0xc9c1ff70 }, // lfd f14,-144(r1)
|
||||
{ "_restfpr_15", 0xc9e1ff78 }, // lfd f15,-136(r1)
|
||||
{ "_restfpr_16", 0xca01ff80 }, // lfd f16,-128(r1)
|
||||
{ "_restfpr_17", 0xca21ff88 }, // lfd f17,-120(r1)
|
||||
{ "_restfpr_18", 0xca41ff90 }, // lfd f18,-112(r1)
|
||||
{ "_restfpr_19", 0xca61ff98 }, // lfd f19,-104(r1)
|
||||
{ "_restfpr_20", 0xca81ffa0 }, // lfd f20,-96(r1)
|
||||
{ "_restfpr_21", 0xcaa1ffa8 }, // lfd f21,-88(r1)
|
||||
{ "_restfpr_22", 0xcac1ffb0 }, // lfd f22,-80(r1)
|
||||
{ "_restfpr_23", 0xcae1ffb8 }, // lfd f23,-72(r1)
|
||||
{ "_restfpr_24", 0xcb01ffc0 }, // lfd f24,-64(r1)
|
||||
{ "_restfpr_25", 0xcb21ffc8 }, // lfd f25,-56(r1)
|
||||
{ "_restfpr_26", 0xcb41ffd0 }, // lfd f26,-48(r1)
|
||||
{ "_restfpr_27", 0xcb61ffd8 }, // lfd f27,-40(r1)
|
||||
{ "_restfpr_28", 0xcb81ffe0 }, // lfd f28,-32(r1)
|
||||
{ "_restfpr_29", 0xe8010010 }, // ld r0,16(r1)
|
||||
{ "", 0xcba1ffe8 }, // lfd f29,-24(r1)
|
||||
{ "", 0x7c0803a6 }, // mtlr r0
|
||||
{ "", 0xcbc1fff0 }, // lfd f30,-16(r1)
|
||||
{ "", 0xcbe1fff8 }, // lfd f31,-8(r1)
|
||||
{ "", 0x4e800020 }, // blr
|
||||
{ "_restfpr_30", 0xcbc1fff0 }, // lfd f30,-16(r1)
|
||||
{ "_restfpr_31", 0xe8010010 }, // ld r0,16(r1)
|
||||
{ "", 0xcbe1fff8 }, // lfd f31,-8(r1)
|
||||
{ "", 0x7c0803a6 }, // mtlr r0
|
||||
{ "", 0x4e800020 }, // blr
|
||||
|
||||
{ "_savevr_20", 0x3980ff40 }, // li r12,-192
|
||||
{ "", 0x7e8c01ce }, // stvx v20,r12,r0
|
||||
{ "_savevr_21", 0x3980ff50 }, // li r12,-176
|
||||
{ "", 0x7eac01ce }, // stvx v21,r12,r0
|
||||
{ "_savevr_22", 0x3980ff60 }, // li r12,-160
|
||||
{ "", 0x7ecc01ce }, // stvx v22,r12,r0
|
||||
{ "_savevr_23", 0x3980ff70 }, // li r12,-144
|
||||
{ "", 0x7eec01ce }, // stvx v23,r12,r0
|
||||
{ "_savevr_24", 0x3980ff80 }, // li r12,-128
|
||||
{ "", 0x7f0c01ce }, // stvx v24,r12,r0
|
||||
{ "_savevr_25", 0x3980ff90 }, // li r12,-112
|
||||
{ "", 0x7f2c01ce }, // stvx v25,r12,r0
|
||||
{ "_savevr_26", 0x3980ffa0 }, // li r12,-96
|
||||
{ "", 0x7f4c01ce }, // stvx v26,r12,r0
|
||||
{ "_savevr_27", 0x3980ffb0 }, // li r12,-80
|
||||
{ "", 0x7f6c01ce }, // stvx v27,r12,r0
|
||||
{ "_savevr_28", 0x3980ffc0 }, // li r12,-64
|
||||
{ "", 0x7f8c01ce }, // stvx v28,r12,r0
|
||||
{ "_savevr_29", 0x3980ffd0 }, // li r12,-48
|
||||
{ "", 0x7fac01ce }, // stvx v29,r12,r0
|
||||
{ "_savevr_30", 0x3980ffe0 }, // li r12,-32
|
||||
{ "", 0x7fcc01ce }, // stvx v30,r12,r0
|
||||
{ "_savevr_31", 0x3980fff0 }, // li r12,-16
|
||||
{ "", 0x7fec01ce }, // stvx v31,r12,r0
|
||||
{ "", 0x4e800020 }, // blr
|
||||
|
||||
{ "_restvr_20", 0x3980ff40 }, // li r12,-192
|
||||
{ "", 0x7e8c00ce }, // lvx v20,r12,r0
|
||||
{ "_restvr_21", 0x3980ff50 }, // li r12,-176
|
||||
{ "", 0x7eac00ce }, // lvx v21,r12,r0
|
||||
{ "_restvr_22", 0x3980ff60 }, // li r12,-160
|
||||
{ "", 0x7ecc00ce }, // lvx v22,r12,r0
|
||||
{ "_restvr_23", 0x3980ff70 }, // li r12,-144
|
||||
{ "", 0x7eec00ce }, // lvx v23,r12,r0
|
||||
{ "_restvr_24", 0x3980ff80 }, // li r12,-128
|
||||
{ "", 0x7f0c00ce }, // lvx v24,r12,r0
|
||||
{ "_restvr_25", 0x3980ff90 }, // li r12,-112
|
||||
{ "", 0x7f2c00ce }, // lvx v25,r12,r0
|
||||
{ "_restvr_26", 0x3980ffa0 }, // li r12,-96
|
||||
{ "", 0x7f4c00ce }, // lvx v26,r12,r0
|
||||
{ "_restvr_27", 0x3980ffb0 }, // li r12,-80
|
||||
{ "", 0x7f6c00ce }, // lvx v27,r12,r0
|
||||
{ "_restvr_28", 0x3980ffc0 }, // li r12,-64
|
||||
{ "", 0x7f8c00ce }, // lvx v28,r12,r0
|
||||
{ "_restvr_29", 0x3980ffd0 }, // li r12,-48
|
||||
{ "", 0x7fac00ce }, // lvx v29,r12,r0
|
||||
{ "_restvr_30", 0x3980ffe0 }, // li r12,-32
|
||||
{ "", 0x7fcc00ce }, // lvx v30,r12,r0
|
||||
{ "_restvr_31", 0x3980fff0 }, // li r12,-16
|
||||
{ "", 0x7fec00ce }, // lvx v31,r12,r0
|
||||
{ "", 0x4e800020 }, // blr
|
||||
};
|
||||
|
||||
void PPC64SaveRestoreSection::copy_buf(Context<E> &ctx) {
|
||||
|
||||
+95
-99
@@ -158,9 +158,14 @@ void write_pltgot_entry<E>(Context<E> &ctx, u8 *buf, Symbol<E> &sym) {
|
||||
}
|
||||
|
||||
template <>
|
||||
void EhFrameSection<E>::apply_eh_reloc(Context<E> &ctx, const ElfRel<E> &rel,
|
||||
u64 offset, u64 val) {
|
||||
void EhFrameSection<E>::apply_eh_reloc(Context<E> &ctx, InputSection<E> &isec,
|
||||
const ElfRel<E> &rel, u64 offset, u64 val) {
|
||||
u8 *loc = ctx.buf + this->shdr.sh_offset + offset;
|
||||
u64 P = this->shdr.sh_addr + offset;
|
||||
|
||||
auto check = [&](i64 val, i64 lo, i64 hi) {
|
||||
check_range(ctx, isec, rel, val, lo, hi);
|
||||
};
|
||||
|
||||
switch (rel.r_type) {
|
||||
case R_NONE:
|
||||
@@ -193,7 +198,8 @@ void EhFrameSection<E>::apply_eh_reloc(Context<E> &ctx, const ElfRel<E> &rel,
|
||||
*(U32<E> *)loc = val;
|
||||
break;
|
||||
case R_RISCV_32_PCREL:
|
||||
*(U32<E> *)loc = val - this->shdr.sh_addr - offset;
|
||||
check(val - P, -(1LL << 31), 1LL << 31);
|
||||
*(U32<E> *)loc = val - P;
|
||||
break;
|
||||
default:
|
||||
Fatal(ctx) << "unsupported relocation in .eh_frame: " << rel;
|
||||
@@ -252,26 +258,26 @@ find_paired_reloc(Context<E> &ctx, InputSection<E> &isec,
|
||||
// ld t0, 0(t0) # R_RISCV_PCREL_LO12_I(.L0), R_RISCV_RELAX
|
||||
static bool is_got_load_pair(Context<E> &ctx, InputSection<E> &isec,
|
||||
std::span<const ElfRel<E>> rels, i64 i) {
|
||||
u8 *buf = (u8 *)isec.contents.data();
|
||||
u8 *buf = isec.contents;
|
||||
return i + 3 < rels.size() &&
|
||||
rels[i].r_type == R_RISCV_GOT_HI20 &&
|
||||
rels[i + 1].r_type == R_RISCV_RELAX &&
|
||||
rels[i + 2].r_type == R_RISCV_PCREL_LO12_I &&
|
||||
rels[i + 3].r_type == R_RISCV_RELAX &&
|
||||
rels[i].r_offset == rels[i + 2].r_offset - 4 &&
|
||||
rels[i].r_offset == isec.file.symbols[rels[i + 2].r_sym]->value &&
|
||||
rels[i].r_offset == isec.file->symbols[rels[i + 2].r_sym]->value &&
|
||||
get_rd(buf + rels[i].r_offset) == get_rd(buf + rels[i + 2].r_offset);
|
||||
}
|
||||
|
||||
template <>
|
||||
void InputSection<E>::apply_reloc_alloc(Context<E> &ctx, u8 *base) {
|
||||
std::span<const ElfRel<E>> rels = get_rels(ctx);
|
||||
std::span<ElfRel<E>> rels = get_rels(ctx);
|
||||
std::span<RelocDelta> deltas = extra.r_deltas;
|
||||
i64 k = 0;
|
||||
u8 *buf = (u8 *)contents.data();
|
||||
u8 *buf = contents;
|
||||
|
||||
for (i64 i = 0; i < rels.size(); i++) {
|
||||
const ElfRel<E> &rel = rels[i];
|
||||
ElfRel<E> &rel = rels[i];
|
||||
if (rel.r_type == R_NONE || rel.r_type == R_RISCV_RELAX)
|
||||
continue;
|
||||
|
||||
@@ -287,7 +293,10 @@ void InputSection<E>::apply_reloc_alloc(Context<E> &ctx, u8 *base) {
|
||||
r_delta = deltas[k - 1].delta;
|
||||
}
|
||||
|
||||
Symbol<E> &sym = *file.symbols[rel.r_sym];
|
||||
Symbol<E> &sym = *file->symbols[rel.r_sym];
|
||||
if (sym.get_type() == STT_TLS && sym.is_remaining_undef_weak())
|
||||
continue;
|
||||
|
||||
i64 r_offset = rel.r_offset - r_delta;
|
||||
u8 *loc = base + r_offset;
|
||||
|
||||
@@ -306,6 +315,11 @@ void InputSection<E>::apply_reloc_alloc(Context<E> &ctx, u8 *base) {
|
||||
write_utype(loc, val);
|
||||
};
|
||||
|
||||
auto rewrite = [&](i64 idx, u32 ty) {
|
||||
if (ctx.arg.emit_relocs)
|
||||
rels[idx].r_type = ty;
|
||||
};
|
||||
|
||||
switch (rel.r_type) {
|
||||
case R_RISCV_32:
|
||||
if (E::is_64)
|
||||
@@ -330,18 +344,23 @@ void InputSection<E>::apply_reloc_alloc(Context<E> &ctx, u8 *base) {
|
||||
// auipc + jalr -> jal
|
||||
*(ul32 *)loc = (rd << 7) | 0b1101111;
|
||||
write_jtype(loc, val);
|
||||
rewrite(i, R_RISCV_JAL);
|
||||
} else if (removed_bytes == 6 && rd == 0) {
|
||||
// auipc + jalr -> c.j
|
||||
*(ul16 *)loc = 0b101'00000000000'01;
|
||||
write_cjtype(loc, val);
|
||||
rewrite(i, R_RISCV_RVC_JUMP);
|
||||
} else if (removed_bytes == 6 && rd == 1) {
|
||||
// auipc + jalr -> c.jal
|
||||
assert(!E::is_64);
|
||||
*(ul16 *)loc = 0b001'00000000000'01;
|
||||
write_cjtype(loc, val);
|
||||
rewrite(i, R_RISCV_RVC_JUMP);
|
||||
} else {
|
||||
assert(removed_bytes == 0);
|
||||
utype(val);
|
||||
if (!sym.is_remaining_undef_weak())
|
||||
check(val, -(1LL << 31) - 0x800, (1LL << 31) - 0x800);
|
||||
write_utype(loc, val);
|
||||
write_itype(loc + 4, val);
|
||||
}
|
||||
break;
|
||||
@@ -357,11 +376,17 @@ void InputSection<E>::apply_reloc_alloc(Context<E> &ctx, u8 *base) {
|
||||
// c.li <rd>, val
|
||||
*(ul16 *)loc = 0b010'0'00000'00000'01 | (rd << 7);
|
||||
write_citype(loc, sym.get_addr(ctx));
|
||||
// The value is materialized directly, so neither this nor the paired
|
||||
// PCREL_LO12 (the load) needs a relocation anymore.
|
||||
rewrite(i, R_NONE);
|
||||
rewrite(i + 2, R_NONE);
|
||||
i += 3;
|
||||
} else if (removed_bytes == 4) {
|
||||
// addi <rd>, zero, val
|
||||
*(ul32 *)loc = 0b0010011 | (rd << 7);
|
||||
write_itype(loc, sym.get_addr(ctx));
|
||||
rewrite(i, R_NONE);
|
||||
rewrite(i + 2, R_NONE);
|
||||
i += 3;
|
||||
} else {
|
||||
assert(removed_bytes == 0);
|
||||
@@ -394,7 +419,7 @@ void InputSection<E>::apply_reloc_alloc(Context<E> &ctx, u8 *base) {
|
||||
case R_RISCV_PCREL_LO12_I:
|
||||
case R_RISCV_PCREL_LO12_S: {
|
||||
const ElfRel<E> &rel2 = find_paired_reloc(ctx, *this, rels, sym, i);
|
||||
Symbol<E> &sym2 = *file.symbols[rel2.r_sym];
|
||||
Symbol<E> &sym2 = *file->symbols[rel2.r_sym];
|
||||
|
||||
auto write =
|
||||
(rel.r_type == R_RISCV_PCREL_LO12_I) ? write_itype : write_stype;
|
||||
@@ -421,6 +446,9 @@ void InputSection<E>::apply_reloc_alloc(Context<E> &ctx, u8 *base) {
|
||||
break;
|
||||
}
|
||||
case R_RISCV_HI20:
|
||||
// lui (+ addi) => an instruction holding a link-time constant. The lui
|
||||
// may be compressed to c.lui (removed 2 bytes) or deleted outright
|
||||
// (removed 4 bytes); either way it no longer needs a relocation.
|
||||
if (removed_bytes == 2) {
|
||||
// Rewrite LUI with C.LUI
|
||||
i64 rd = get_rd(buf + rel.r_offset);
|
||||
@@ -429,6 +457,8 @@ void InputSection<E>::apply_reloc_alloc(Context<E> &ctx, u8 *base) {
|
||||
} else if (removed_bytes == 0) {
|
||||
utype(S + A);
|
||||
}
|
||||
if (removed_bytes)
|
||||
rewrite(i, R_NONE);
|
||||
break;
|
||||
case R_RISCV_LO12_I:
|
||||
case R_RISCV_LO12_S:
|
||||
@@ -445,14 +475,19 @@ void InputSection<E>::apply_reloc_alloc(Context<E> &ctx, u8 *base) {
|
||||
break;
|
||||
case R_RISCV_TPREL_HI20:
|
||||
assert(removed_bytes == 0 || removed_bytes == 4);
|
||||
// lui + add => deleted; the variable is accessed relative to tp directly.
|
||||
if (removed_bytes == 0)
|
||||
utype(S + A - ctx.tp_addr);
|
||||
else
|
||||
rewrite(i, R_NONE);
|
||||
break;
|
||||
case R_RISCV_TPREL_ADD:
|
||||
// This relocation just annotates an ADD instruction that can be
|
||||
// removed when a TPREL is relaxed. No value is needed to be
|
||||
// written.
|
||||
assert(removed_bytes == 0 || removed_bytes == 4);
|
||||
if (removed_bytes)
|
||||
rewrite(i, R_NONE);
|
||||
break;
|
||||
case R_RISCV_TPREL_LO12_I:
|
||||
case R_RISCV_TPREL_LO12_S: {
|
||||
@@ -507,18 +542,25 @@ void InputSection<E>::apply_reloc_alloc(Context<E> &ctx, u8 *base) {
|
||||
// If the code-shrinking relaxation is disabled, we may leave
|
||||
// original useless instructions instead of deleting them, but we
|
||||
// accept that because relaxations are enabled by default.
|
||||
if (sym.has_tlsdesc(ctx) && removed_bytes == 0)
|
||||
utype(sym.get_tlsdesc_addr(ctx) + A - P);
|
||||
if (sym.has_tlsdesc(ctx)) {
|
||||
if (removed_bytes == 0)
|
||||
utype(sym.get_tlsdesc_addr(ctx) + A - P);
|
||||
} else {
|
||||
rewrite(i, R_NONE);
|
||||
}
|
||||
break;
|
||||
case R_RISCV_TLSDESC_LOAD_LO12:
|
||||
case R_RISCV_TLSDESC_ADD_LO12:
|
||||
case R_RISCV_TLSDESC_CALL: {
|
||||
const ElfRel<E> &rel2 = find_paired_reloc(ctx, *this, rels, sym, i);
|
||||
Symbol<E> &sym2 = *file->symbols[rel2.r_sym];
|
||||
|
||||
if (!sym2.has_tlsdesc(ctx))
|
||||
rewrite(i, R_NONE);
|
||||
|
||||
if (removed_bytes == 4)
|
||||
break;
|
||||
|
||||
const ElfRel<E> &rel2 = find_paired_reloc(ctx, *this, rels, sym, i);
|
||||
Symbol<E> &sym2 = *file.symbols[rel2.r_sym];
|
||||
|
||||
u64 S = sym2.get_addr(ctx);
|
||||
u64 A = rel2.r_addend;
|
||||
u64 P = get_addr() + rel2.r_offset - get_r_delta(*this, rel2.r_offset);
|
||||
@@ -561,7 +603,7 @@ void InputSection<E>::apply_reloc_alloc(Context<E> &ctx, u8 *base) {
|
||||
break;
|
||||
}
|
||||
case R_RISCV_ADD8:
|
||||
loc += S + A;
|
||||
*loc += S + A;
|
||||
break;
|
||||
case R_RISCV_ADD16:
|
||||
*(U16<E> *)loc += S + A;
|
||||
@@ -573,7 +615,7 @@ void InputSection<E>::apply_reloc_alloc(Context<E> &ctx, u8 *base) {
|
||||
*(U64<E> *)loc += S + A;
|
||||
break;
|
||||
case R_RISCV_SUB8:
|
||||
loc -= S + A;
|
||||
*loc -= S + A;
|
||||
break;
|
||||
case R_RISCV_SUB16:
|
||||
*(U16<E> *)loc -= S + A;
|
||||
@@ -646,14 +688,11 @@ void InputSection<E>::apply_reloc_alloc(Context<E> &ctx, u8 *base) {
|
||||
|
||||
template <>
|
||||
void InputSection<E>::apply_reloc_nonalloc(Context<E> &ctx, u8 *base) {
|
||||
std::span<const ElfRel<E>> rels = get_rels(ctx);
|
||||
|
||||
for (i64 i = 0; i < rels.size(); i++) {
|
||||
const ElfRel<E> &rel = rels[i];
|
||||
for_each_reloc(ctx, [&](const ElfRel<E> &rel, i64) ALWAYS_INLINE {
|
||||
if (rel.r_type == R_NONE || record_undef_error(ctx, rel))
|
||||
continue;
|
||||
return;
|
||||
|
||||
Symbol<E> &sym = *file.symbols[rel.r_sym];
|
||||
Symbol<E> &sym = *file->symbols[rel.r_sym];
|
||||
u8 *loc = base + rel.r_offset;
|
||||
|
||||
SectionFragment<E> *frag;
|
||||
@@ -673,6 +712,18 @@ void InputSection<E>::apply_reloc_nonalloc(Context<E> &ctx, u8 *base) {
|
||||
else
|
||||
*(U64<E> *)loc = S + A;
|
||||
break;
|
||||
case R_RISCV_TLS_DTPREL32:
|
||||
if (std::optional<u64> val = get_tombstone(sym, frag))
|
||||
*(U32<E> *)loc = *val;
|
||||
else
|
||||
*(U32<E> *)loc = S + A - ctx.dtp_addr;
|
||||
break;
|
||||
case R_RISCV_TLS_DTPREL64:
|
||||
if (std::optional<u64> val = get_tombstone(sym, frag))
|
||||
*(U64<E> *)loc = *val;
|
||||
else
|
||||
*(U64<E> *)loc = S + A - ctx.dtp_addr;
|
||||
break;
|
||||
case R_RISCV_ADD8:
|
||||
*loc += S + A;
|
||||
break;
|
||||
@@ -723,7 +774,7 @@ void InputSection<E>::apply_reloc_nonalloc(Context<E> &ctx, u8 *base) {
|
||||
<< rel;
|
||||
break;
|
||||
}
|
||||
}
|
||||
});
|
||||
}
|
||||
|
||||
template <>
|
||||
@@ -737,7 +788,7 @@ void InputSection<E>::scan_relocations(Context<E> &ctx) {
|
||||
if (rel.r_type == R_NONE || record_undef_error(ctx, rel))
|
||||
continue;
|
||||
|
||||
Symbol<E> &sym = *file.symbols[rel.r_sym];
|
||||
Symbol<E> &sym = *file->symbols[rel.r_sym];
|
||||
|
||||
if (sym.is_ifunc())
|
||||
sym.flags |= NEEDS_GOT | NEEDS_PLT;
|
||||
@@ -844,17 +895,17 @@ u64 get_eflags(Context<E> &ctx) {
|
||||
template <>
|
||||
void shrink_section(Context<E> &ctx, InputSection<E> &isec) {
|
||||
std::span<const ElfRel<E>> rels = isec.get_rels(ctx);
|
||||
std::vector<RelocDelta> &deltas = isec.extra.r_deltas;
|
||||
std::vector<RelocDelta> deltas;
|
||||
i64 r_delta = 0;
|
||||
u8 *buf = (u8 *)isec.contents.data();
|
||||
u8 *buf = isec.contents;
|
||||
|
||||
// True if we can use 2-byte instructions. This is usually true on
|
||||
// Unix because RV64GC is generally considered the baseline hardware.
|
||||
bool use_rvc = isec.file.get_eflags() & EF_RISCV_RVC;
|
||||
bool use_rvc = isec.file->get_eflags() & EF_RISCV_RVC;
|
||||
|
||||
for (i64 i = 0; i < rels.size(); i++) {
|
||||
const ElfRel<E> &r = rels[i];
|
||||
Symbol<E> &sym = *isec.file.symbols[r.r_sym];
|
||||
Symbol<E> &sym = *isec.file->symbols[r.r_sym];
|
||||
|
||||
auto remove = [&](i64 d) {
|
||||
r_delta += d;
|
||||
@@ -868,9 +919,14 @@ void shrink_section(Context<E> &ctx, InputSection<E> &isec) {
|
||||
// follows the NOPs is aligned to a specified alignment boundary.
|
||||
if (r.r_type == R_RISCV_ALIGN) {
|
||||
// The total bytes of NOPs is stored to r_addend, so the next
|
||||
// instruction is r_addend away.
|
||||
// instruction is r_addend away. The alignment itself is not recorded
|
||||
// anywhere; it is the smallest power of two greater than r_addend,
|
||||
// because the assembler emits as many NOP bytes as the worst case
|
||||
// requires, which is the alignment minus the minimum instruction
|
||||
// size. For example, `.balign 4` yields r_addend 2 in RVC code and
|
||||
// `.balign 8` yields 4 in non-RVC code.
|
||||
u64 P = isec.get_addr() + r.r_offset - r_delta;
|
||||
u64 desired = align_to(P, bit_ceil(r.r_addend));
|
||||
u64 desired = align_to(P, bit_ceil(r.r_addend + 1));
|
||||
u64 actual = P + r.r_addend;
|
||||
if (desired != actual)
|
||||
remove(actual - desired);
|
||||
@@ -980,7 +1036,7 @@ void shrink_section(Context<E> &ctx, InputSection<E> &isec) {
|
||||
case R_RISCV_TLSDESC_LOAD_LO12:
|
||||
case R_RISCV_TLSDESC_ADD_LO12: {
|
||||
const ElfRel<E> &rel2 = find_paired_reloc(ctx, isec, rels, sym, i);
|
||||
Symbol<E> &sym2 = *isec.file.symbols[rel2.r_sym];
|
||||
Symbol<E> &sym2 = *isec.file->symbols[rel2.r_sym];
|
||||
|
||||
if (r.r_type == R_RISCV_TLSDESC_LOAD_LO12) {
|
||||
if (!sym2.has_tlsdesc(ctx))
|
||||
@@ -997,75 +1053,15 @@ void shrink_section(Context<E> &ctx, InputSection<E> &isec) {
|
||||
}
|
||||
}
|
||||
|
||||
if (deltas.empty())
|
||||
return;
|
||||
|
||||
RelocDelta *p = ctx.arena.template allocate<RelocDelta>(deltas.size());
|
||||
ranges::copy(deltas, p);
|
||||
isec.extra.r_deltas = {p, deltas.size()};
|
||||
isec.sh_size -= r_delta;
|
||||
}
|
||||
|
||||
// With --emit-relocs, rewrite the emitted relocations to match the
|
||||
// instructions that relaxation produced. The logic parallels apply_reloc_alloc.
|
||||
template <>
|
||||
void rewrite_reloc_types(Context<E> &ctx, InputSection<E> &isec, ElfRel<E> *buf) {
|
||||
std::span<const ElfRel<E>> rels = isec.get_rels(ctx);
|
||||
std::span<RelocDelta> deltas = isec.extra.r_deltas;
|
||||
i64 k = 0;
|
||||
|
||||
for (i64 i = 0; i < rels.size(); i++) {
|
||||
const ElfRel<E> &rel = rels[i];
|
||||
Symbol<E> &sym = *isec.file.symbols[rel.r_sym];
|
||||
|
||||
i64 removed_bytes = 0;
|
||||
if (!deltas.empty()) {
|
||||
while (k < deltas.size() && deltas[k].offset < rel.r_offset)
|
||||
k++;
|
||||
if (k < deltas.size() && deltas[k].offset == rel.r_offset)
|
||||
removed_bytes = get_removed_bytes(deltas, k);
|
||||
}
|
||||
|
||||
switch (rel.r_type) {
|
||||
case R_RISCV_CALL:
|
||||
case R_RISCV_CALL_PLT:
|
||||
// auipc + jalr => jal, or c.j/c.jal
|
||||
if (removed_bytes == 4)
|
||||
buf[i].r_type = R_RISCV_JAL;
|
||||
else if (removed_bytes == 6)
|
||||
buf[i].r_type = R_RISCV_RVC_JUMP;
|
||||
break;
|
||||
case R_RISCV_GOT_HI20:
|
||||
// auipc + l[dw] GOT load => the value is materialized directly, so both
|
||||
// this and the paired PCREL_LO12 (the load) no longer need a relocation.
|
||||
if (removed_bytes) {
|
||||
buf[i].r_type = R_RISCV_NONE;
|
||||
buf[i + 2].r_type = R_RISCV_NONE;
|
||||
i += 3;
|
||||
}
|
||||
break;
|
||||
case R_RISCV_HI20:
|
||||
// lui (+ addi) => an instruction holding a link-time constant.
|
||||
if (removed_bytes)
|
||||
buf[i].r_type = R_RISCV_NONE;
|
||||
break;
|
||||
case R_RISCV_TPREL_HI20:
|
||||
case R_RISCV_TPREL_ADD:
|
||||
// lui + add => deleted; the variable is accessed relative to tp directly.
|
||||
if (removed_bytes)
|
||||
buf[i].r_type = R_RISCV_NONE;
|
||||
break;
|
||||
case R_RISCV_TLSDESC_HI20:
|
||||
if (!sym.has_tlsdesc(ctx))
|
||||
buf[i].r_type = R_RISCV_NONE;
|
||||
break;
|
||||
case R_RISCV_TLSDESC_LOAD_LO12:
|
||||
case R_RISCV_TLSDESC_ADD_LO12:
|
||||
case R_RISCV_TLSDESC_CALL: {
|
||||
Symbol<E> &sym2 =
|
||||
*isec.file.symbols[find_paired_reloc(ctx, isec, rels, sym, i).r_sym];
|
||||
if (!sym2.has_tlsdesc(ctx))
|
||||
buf[i].r_type = R_RISCV_NONE;
|
||||
break;
|
||||
}
|
||||
}
|
||||
}
|
||||
}
|
||||
|
||||
// ISA name handlers
|
||||
//
|
||||
// An example of ISA name is "rv64i2p1_m2p0_a2p1_f2p2_d2p2_c2p0_zicsr2p0".
|
||||
|
||||
+31
-19
@@ -102,15 +102,21 @@ void write_pltgot_entry(Context<E> &ctx, u8 *buf, Symbol<E> &sym) {
|
||||
}
|
||||
|
||||
template <>
|
||||
void EhFrameSection<E>::apply_eh_reloc(Context<E> &ctx, const ElfRel<E> &rel,
|
||||
u64 offset, u64 val) {
|
||||
void EhFrameSection<E>::apply_eh_reloc(Context<E> &ctx, InputSection<E> &isec,
|
||||
const ElfRel<E> &rel, u64 offset, u64 val) {
|
||||
u8 *loc = ctx.buf + this->shdr.sh_offset + offset;
|
||||
u64 P = this->shdr.sh_addr + offset;
|
||||
|
||||
auto check = [&](i64 val, i64 lo, i64 hi) {
|
||||
check_range(ctx, isec, rel, val, lo, hi);
|
||||
};
|
||||
|
||||
switch (rel.r_type) {
|
||||
case R_NONE:
|
||||
break;
|
||||
case R_390_PC32:
|
||||
*(ub32 *)loc = val - this->shdr.sh_addr - offset;
|
||||
check(val - P, -(1LL << 31), 1LL << 31);
|
||||
*(ub32 *)loc = val - P;
|
||||
break;
|
||||
case R_390_64:
|
||||
*(ub64 *)loc = val;
|
||||
@@ -122,14 +128,17 @@ void EhFrameSection<E>::apply_eh_reloc(Context<E> &ctx, const ElfRel<E> &rel,
|
||||
|
||||
template <>
|
||||
void InputSection<E>::apply_reloc_alloc(Context<E> &ctx, u8 *base) {
|
||||
std::span<const ElfRel<E>> rels = get_rels(ctx);
|
||||
std::span<ElfRel<E>> rels = get_rels(ctx);
|
||||
|
||||
for (i64 i = 0; i < rels.size(); i++) {
|
||||
const ElfRel<E> &rel = rels[i];
|
||||
ElfRel<E> &rel = rels[i];
|
||||
if (rel.r_type == R_NONE)
|
||||
continue;
|
||||
|
||||
Symbol<E> &sym = *file.symbols[rel.r_sym];
|
||||
Symbol<E> &sym = *file->symbols[rel.r_sym];
|
||||
if (sym.get_type() == STT_TLS && sym.is_remaining_undef_weak())
|
||||
continue;
|
||||
|
||||
u8 *loc = base + rel.r_offset;
|
||||
|
||||
u64 S = sym.get_addr(ctx);
|
||||
@@ -159,7 +168,7 @@ void InputSection<E>::apply_reloc_alloc(Context<E> &ctx, u8 *base) {
|
||||
break;
|
||||
case R_390_12:
|
||||
check(S + A, 0, 1 << 12);
|
||||
*(ul16 *)loc |= bits(S + A, 11, 0);
|
||||
*(ub16 *)loc |= bits(S + A, 11, 0);
|
||||
break;
|
||||
case R_390_16:
|
||||
check(S + A, 0, 1 << 16);
|
||||
@@ -177,7 +186,7 @@ void InputSection<E>::apply_reloc_alloc(Context<E> &ctx, u8 *base) {
|
||||
case R_390_PC12DBL:
|
||||
case R_390_PLT12DBL:
|
||||
check_dbl(S + A - P, -(1 << 12), 1 << 12);
|
||||
*(ul16 *)loc |= bits(S + A - P, 12, 1);
|
||||
*(ub16 *)loc |= bits(S + A - P, 12, 1);
|
||||
break;
|
||||
case R_390_PC16:
|
||||
check(S + A - P, -(1 << 15), 1 << 15);
|
||||
@@ -202,14 +211,18 @@ void InputSection<E>::apply_reloc_alloc(Context<E> &ctx, u8 *base) {
|
||||
*(ub32 *)loc |= bits(S + A - P, 24, 1);
|
||||
break;
|
||||
case R_390_PC32DBL:
|
||||
case R_390_PLT32DBL:
|
||||
check_dbl(S + A - P, -(1LL << 32), 1LL << 32);
|
||||
*(ub32 *)loc = (S + A - P) >> 1;
|
||||
break;
|
||||
case R_390_PLT32DBL:
|
||||
if (!sym.is_remaining_undef_weak())
|
||||
check_dbl(S + A - P, -(1LL << 32), 1LL << 32);
|
||||
*(ub32 *)loc = (S + A - P) >> 1;
|
||||
break;
|
||||
case R_390_GOT12:
|
||||
case R_390_GOTPLT12:
|
||||
check(G + A, 0, 1 << 12);
|
||||
*(ul16 *)loc |= bits(G + A, 11, 0);
|
||||
*(ub16 *)loc |= bits(G + A, 11, 0);
|
||||
break;
|
||||
case R_390_GOT16:
|
||||
case R_390_GOTPLT16:
|
||||
@@ -262,6 +275,8 @@ void InputSection<E>::apply_reloc_alloc(Context<E> &ctx, u8 *base) {
|
||||
is_int(val, 33)) {
|
||||
*(ub16 *)(loc - 2) = 0xc000 | (op & 0x00f0);
|
||||
*(ub32 *)loc = val >> 1;
|
||||
if (ctx.arg.emit_relocs)
|
||||
rel.r_type = R_390_PC32DBL;
|
||||
break;
|
||||
}
|
||||
}
|
||||
@@ -342,14 +357,11 @@ void InputSection<E>::apply_reloc_alloc(Context<E> &ctx, u8 *base) {
|
||||
|
||||
template <>
|
||||
void InputSection<E>::apply_reloc_nonalloc(Context<E> &ctx, u8 *base) {
|
||||
std::span<const ElfRel<E>> rels = get_rels(ctx);
|
||||
|
||||
for (i64 i = 0; i < rels.size(); i++) {
|
||||
const ElfRel<E> &rel = rels[i];
|
||||
for_each_reloc(ctx, [&](const ElfRel<E> &rel, i64 i) ALWAYS_INLINE {
|
||||
if (rel.r_type == R_NONE || record_undef_error(ctx, rel))
|
||||
continue;
|
||||
return;
|
||||
|
||||
Symbol<E> &sym = *file.symbols[rel.r_sym];
|
||||
Symbol<E> &sym = *file->symbols[rel.r_sym];
|
||||
u8 *loc = base + rel.r_offset;
|
||||
|
||||
SectionFragment<E> *frag;
|
||||
@@ -360,7 +372,7 @@ void InputSection<E>::apply_reloc_nonalloc(Context<E> &ctx, u8 *base) {
|
||||
u64 A = frag ? frag_addend : (i64)rel.r_addend;
|
||||
|
||||
auto check = [&](i64 val, i64 lo, i64 hi) {
|
||||
check_range(ctx, val, i, lo, hi);
|
||||
check_range(ctx, i, val, lo, hi);
|
||||
};
|
||||
|
||||
switch (rel.r_type) {
|
||||
@@ -383,7 +395,7 @@ void InputSection<E>::apply_reloc_nonalloc(Context<E> &ctx, u8 *base) {
|
||||
default:
|
||||
Fatal(ctx) << *this << ": apply_reloc_nonalloc: " << rel;
|
||||
}
|
||||
}
|
||||
});
|
||||
}
|
||||
|
||||
template <>
|
||||
@@ -397,7 +409,7 @@ void InputSection<E>::scan_relocations(Context<E> &ctx) {
|
||||
if (rel.r_type == R_NONE || record_undef_error(ctx, rel))
|
||||
continue;
|
||||
|
||||
Symbol<E> &sym = *file.symbols[rel.r_sym];
|
||||
Symbol<E> &sym = *file->symbols[rel.r_sym];
|
||||
|
||||
if (sym.is_ifunc())
|
||||
sym.flags |= NEEDS_GOT | NEEDS_PLT;
|
||||
|
||||
+35
-24
@@ -47,9 +47,10 @@
|
||||
// with a piece of code to store the address of .got to %r12.
|
||||
// We can use the register in our PLT for position-independent output.
|
||||
//
|
||||
// - Even though it uses the RELA-type relocations, relocation addends
|
||||
// are stored not to the r_addend field but to the relocated section
|
||||
// contents for some reason. Therefore, it's effectively REL.
|
||||
// - Even though it uses RELA-type relocations, object files store
|
||||
// addends not in the r_addend field but in the relocated section
|
||||
// contents. Dynamic relocations, however, follow the usual RELA
|
||||
// convention.
|
||||
//
|
||||
// - It looks like the ecosystem has bit-rotted. Some tests, especially
|
||||
// one using C++ exceptions, don't pass even with GNU ld.
|
||||
@@ -66,8 +67,8 @@ namespace mold {
|
||||
|
||||
using E = MOLD_TARGET;
|
||||
|
||||
// Even though SH-4 uses RELA-type relocations, addends are stored to
|
||||
// relocated places for some reason.
|
||||
// Even though SH-4 uses RELA-type relocations, addends are stored in
|
||||
// the relocated places for some reason.
|
||||
template <>
|
||||
i64 get_addend(u8 *loc, const ElfRel<E> &rel) {
|
||||
switch (rel.r_type) {
|
||||
@@ -151,32 +152,36 @@ template <>
|
||||
void write_plt_entry(Context<E> &ctx, u8 *buf, Symbol<E> &sym) {
|
||||
if (ctx.arg.pic) {
|
||||
constexpr U16<E> insn[] = {
|
||||
0xd001, // mov.l 1f, r0
|
||||
0xd002, // mov.l 1f, r0
|
||||
0x00ce, // mov.l @(r0, r12), r0
|
||||
0xd102, // mov.l 2f, r1
|
||||
0x402b, // jmp @r0
|
||||
0xd101, // mov.l 2f, r1
|
||||
0x0009, // nop
|
||||
0x0009, // nop
|
||||
0, 0, // 1: .long GOTPLT_ENTRY
|
||||
0, 0, // 2: .long INDEX_IN_RELPLT
|
||||
};
|
||||
|
||||
static_assert(sizeof(insn) == E::plt_size);
|
||||
memcpy(buf, insn, sizeof(insn));
|
||||
*(U32<E> *)(buf + 8) = sym.get_gotplt_addr(ctx) - ctx.got->shdr.sh_addr;
|
||||
*(U32<E> *)(buf + 12) = sym.get_plt_idx(ctx) * sizeof(ElfRel<E>);
|
||||
*(U32<E> *)(buf + 12) = sym.get_gotplt_addr(ctx) - ctx.got->shdr.sh_addr;
|
||||
*(U32<E> *)(buf + 16) = sym.get_plt_idx(ctx) * sizeof(ElfRel<E>);
|
||||
} else {
|
||||
constexpr U16<E> insn[] = {
|
||||
0xd001, // mov.l 1f, r0
|
||||
0xd002, // mov.l 1f, r0
|
||||
0x6002, // mov.l @r0, r0
|
||||
0xd102, // mov.l 2f, r1
|
||||
0x402b, // jmp @r0
|
||||
0xd101, // mov.l 2f, r1
|
||||
0x0009, // nop
|
||||
0x0009, // nop
|
||||
0, 0, // 1: .long GOTPLT_ENTRY
|
||||
0, 0, // 2: .long INDEX_IN_RELPLT
|
||||
};
|
||||
|
||||
static_assert(sizeof(insn) == E::plt_size);
|
||||
memcpy(buf, insn, sizeof(insn));
|
||||
*(U32<E> *)(buf + 8) = sym.get_gotplt_addr(ctx);
|
||||
*(U32<E> *)(buf + 12) = sym.get_plt_idx(ctx) * sizeof(ElfRel<E>);
|
||||
*(U32<E> *)(buf + 12) = sym.get_gotplt_addr(ctx);
|
||||
*(U32<E> *)(buf + 16) = sym.get_plt_idx(ctx) * sizeof(ElfRel<E>);
|
||||
}
|
||||
}
|
||||
|
||||
@@ -210,8 +215,8 @@ void write_pltgot_entry(Context<E> &ctx, u8 *buf, Symbol<E> &sym) {
|
||||
}
|
||||
|
||||
template <>
|
||||
void EhFrameSection<E>::apply_eh_reloc(Context<E> &ctx, const ElfRel<E> &rel,
|
||||
u64 offset, u64 val) {
|
||||
void EhFrameSection<E>::apply_eh_reloc(Context<E> &ctx, InputSection<E> &isec,
|
||||
const ElfRel<E> &rel, u64 offset, u64 val) {
|
||||
u8 *loc = ctx.buf + this->shdr.sh_offset + offset;
|
||||
|
||||
switch (rel.r_type) {
|
||||
@@ -237,7 +242,10 @@ void InputSection<E>::apply_reloc_alloc(Context<E> &ctx, u8 *base) {
|
||||
if (rel.r_type == R_NONE)
|
||||
continue;
|
||||
|
||||
Symbol<E> &sym = *file.symbols[rel.r_sym];
|
||||
Symbol<E> &sym = *file->symbols[rel.r_sym];
|
||||
if (sym.get_type() == STT_TLS && sym.is_remaining_undef_weak())
|
||||
continue;
|
||||
|
||||
u8 *loc = base + rel.r_offset;
|
||||
|
||||
u64 S = sym.get_addr(ctx);
|
||||
@@ -285,14 +293,11 @@ void InputSection<E>::apply_reloc_alloc(Context<E> &ctx, u8 *base) {
|
||||
|
||||
template <>
|
||||
void InputSection<E>::apply_reloc_nonalloc(Context<E> &ctx, u8 *base) {
|
||||
std::span<const ElfRel<E>> rels = get_rels(ctx);
|
||||
|
||||
for (i64 i = 0; i < rels.size(); i++) {
|
||||
const ElfRel<E> &rel = rels[i];
|
||||
for_each_reloc(ctx, [&](const ElfRel<E> &rel, i64) ALWAYS_INLINE {
|
||||
if (rel.r_type == R_NONE || record_undef_error(ctx, rel))
|
||||
continue;
|
||||
return;
|
||||
|
||||
Symbol<E> &sym = *file.symbols[rel.r_sym];
|
||||
Symbol<E> &sym = *file->symbols[rel.r_sym];
|
||||
u8 *loc = base + rel.r_offset;
|
||||
|
||||
SectionFragment<E> *frag;
|
||||
@@ -309,11 +314,17 @@ void InputSection<E>::apply_reloc_nonalloc(Context<E> &ctx, u8 *base) {
|
||||
else
|
||||
*(U32<E> *)loc = S + A;
|
||||
break;
|
||||
case R_SH_TLS_LDO_32:
|
||||
if (std::optional<u64> val = get_tombstone(sym, frag))
|
||||
*(U32<E> *)loc = *val;
|
||||
else
|
||||
*(U32<E> *)loc = S + A - ctx.dtp_addr;
|
||||
break;
|
||||
default:
|
||||
Fatal(ctx) << *this << ": invalid relocation for non-allocated sections: "
|
||||
<< rel;
|
||||
}
|
||||
}
|
||||
});
|
||||
}
|
||||
|
||||
template <>
|
||||
@@ -326,7 +337,7 @@ void InputSection<E>::scan_relocations(Context<E> &ctx) {
|
||||
if (rel.r_type == R_NONE || record_undef_error(ctx, rel))
|
||||
continue;
|
||||
|
||||
Symbol<E> &sym = *file.symbols[rel.r_sym];
|
||||
Symbol<E> &sym = *file->symbols[rel.r_sym];
|
||||
|
||||
if (sym.is_ifunc())
|
||||
Error(ctx) << sym << ": GNU ifunc symbol is not supported on sh4";
|
||||
|
||||
+21
-14
@@ -169,9 +169,14 @@ void write_pltgot_entry(Context<E> &ctx, u8 *buf, Symbol<E> &sym) {
|
||||
}
|
||||
|
||||
template <>
|
||||
void EhFrameSection<E>::apply_eh_reloc(Context<E> &ctx, const ElfRel<E> &rel,
|
||||
u64 offset, u64 val) {
|
||||
void EhFrameSection<E>::apply_eh_reloc(Context<E> &ctx, InputSection<E> &isec,
|
||||
const ElfRel<E> &rel, u64 offset, u64 val) {
|
||||
u8 *loc = ctx.buf + this->shdr.sh_offset + offset;
|
||||
u64 P = this->shdr.sh_addr + offset;
|
||||
|
||||
auto check = [&](i64 val, i64 lo, i64 hi) {
|
||||
check_range(ctx, isec, rel, val, lo, hi);
|
||||
};
|
||||
|
||||
switch (rel.r_type) {
|
||||
case R_NONE:
|
||||
@@ -181,7 +186,8 @@ void EhFrameSection<E>::apply_eh_reloc(Context<E> &ctx, const ElfRel<E> &rel,
|
||||
*(ub64 *)loc = val;
|
||||
break;
|
||||
case R_SPARC_DISP32:
|
||||
*(ub32 *)loc = val - this->shdr.sh_addr - offset;
|
||||
check(val - P, -(1LL << 31), 1LL << 31);
|
||||
*(ub32 *)loc = val - P;
|
||||
break;
|
||||
default:
|
||||
Fatal(ctx) << "unsupported relocation in .eh_frame: " << rel;
|
||||
@@ -199,7 +205,10 @@ void InputSection<E>::apply_reloc_alloc(Context<E> &ctx, u8 *base) {
|
||||
if (rel.r_type == R_NONE)
|
||||
continue;
|
||||
|
||||
Symbol<E> &sym = *file.symbols[rel.r_sym];
|
||||
Symbol<E> &sym = *file->symbols[rel.r_sym];
|
||||
if (sym.get_type() == STT_TLS && sym.is_remaining_undef_weak())
|
||||
continue;
|
||||
|
||||
u8 *loc = base + rel.r_offset;
|
||||
|
||||
u64 S = sym.get_addr(ctx);
|
||||
@@ -300,7 +309,8 @@ void InputSection<E>::apply_reloc_alloc(Context<E> &ctx, u8 *base) {
|
||||
break;
|
||||
case R_SPARC_WDISP30:
|
||||
case R_SPARC_WPLT30:
|
||||
check(S + A - P, -(1LL << 31), 1LL << 31);
|
||||
if (!sym.is_remaining_undef_weak())
|
||||
check(S + A - P, -(1LL << 31), 1LL << 31);
|
||||
*(ub32 *)loc |= bits(S + A - P, 31, 2);
|
||||
break;
|
||||
case R_SPARC_HI22:
|
||||
@@ -512,14 +522,11 @@ void InputSection<E>::apply_reloc_alloc(Context<E> &ctx, u8 *base) {
|
||||
|
||||
template <>
|
||||
void InputSection<E>::apply_reloc_nonalloc(Context<E> &ctx, u8 *base) {
|
||||
std::span<const ElfRel<E>> rels = get_rels(ctx);
|
||||
|
||||
for (i64 i = 0; i < rels.size(); i++) {
|
||||
const ElfRel<E> &rel = rels[i];
|
||||
for_each_reloc(ctx, [&](const ElfRel<E> &rel, i64 i) ALWAYS_INLINE {
|
||||
if (rel.r_type == R_NONE || record_undef_error(ctx, rel))
|
||||
continue;
|
||||
return;
|
||||
|
||||
Symbol<E> &sym = *file.symbols[rel.r_sym];
|
||||
Symbol<E> &sym = *file->symbols[rel.r_sym];
|
||||
u8 *loc = base + rel.r_offset;
|
||||
|
||||
SectionFragment<E> *frag;
|
||||
@@ -530,7 +537,7 @@ void InputSection<E>::apply_reloc_nonalloc(Context<E> &ctx, u8 *base) {
|
||||
u64 A = frag ? frag_addend : (i64)rel.r_addend;
|
||||
|
||||
auto check = [&](i64 val, i64 lo, i64 hi) {
|
||||
check_range(ctx, val, i, lo, hi);
|
||||
check_range(ctx, i, val, lo, hi);
|
||||
};
|
||||
|
||||
switch (rel.r_type) {
|
||||
@@ -555,7 +562,7 @@ void InputSection<E>::apply_reloc_nonalloc(Context<E> &ctx, u8 *base) {
|
||||
default:
|
||||
Fatal(ctx) << *this << ": apply_reloc_nonalloc: " << rel;
|
||||
}
|
||||
}
|
||||
});
|
||||
}
|
||||
|
||||
template <>
|
||||
@@ -570,7 +577,7 @@ void InputSection<E>::scan_relocations(Context<E> &ctx) {
|
||||
if (rel.r_type == R_NONE || record_undef_error(ctx, rel))
|
||||
continue;
|
||||
|
||||
Symbol<E> &sym = *file.symbols[rel.r_sym];
|
||||
Symbol<E> &sym = *file->symbols[rel.r_sym];
|
||||
|
||||
if (sym.is_ifunc())
|
||||
sym.flags |= NEEDS_GOT | NEEDS_PLT;
|
||||
|
||||
+30
-108
@@ -104,24 +104,31 @@ void write_pltgot_entry(Context<E> &ctx, u8 *buf, Symbol<E> &sym) {
|
||||
}
|
||||
|
||||
template <>
|
||||
void EhFrameSection<E>::apply_eh_reloc(Context<E> &ctx, const ElfRel<E> &rel,
|
||||
u64 offset, u64 val) {
|
||||
void EhFrameSection<E>::apply_eh_reloc(Context<E> &ctx, InputSection<E> &isec,
|
||||
const ElfRel<E> &rel, u64 offset, u64 val) {
|
||||
u8 *loc = ctx.buf + this->shdr.sh_offset + offset;
|
||||
u64 P = this->shdr.sh_addr + offset;
|
||||
|
||||
auto check = [&](i64 val, i64 lo, i64 hi) {
|
||||
check_range(ctx, isec, rel, val, lo, hi);
|
||||
};
|
||||
|
||||
switch (rel.r_type) {
|
||||
case R_NONE:
|
||||
break;
|
||||
case R_X86_64_32:
|
||||
check(val, 0, 1LL << 32);
|
||||
*(ul32 *)loc = val;
|
||||
break;
|
||||
case R_X86_64_64:
|
||||
*(ul64 *)loc = val;
|
||||
break;
|
||||
case R_X86_64_PC32:
|
||||
*(ul32 *)loc = val - this->shdr.sh_addr - offset;
|
||||
check(val - P, -(1LL << 31), 1LL << 31);
|
||||
*(ul32 *)loc = val - P;
|
||||
break;
|
||||
case R_X86_64_PC64:
|
||||
*(ul64 *)loc = val - this->shdr.sh_addr - offset;
|
||||
*(ul64 *)loc = val - P;
|
||||
break;
|
||||
default:
|
||||
Fatal(ctx) << "unsupported relocation in .eh_frame: " << rel;
|
||||
@@ -433,14 +440,17 @@ static void relax_ld_to_le(u8 *loc, const ElfRel<E> &rel, i64 tls_size) {
|
||||
// scan_relocations().
|
||||
template <>
|
||||
void InputSection<E>::apply_reloc_alloc(Context<E> &ctx, u8 *base) {
|
||||
std::span<const ElfRel<E>> rels = get_rels(ctx);
|
||||
std::span<ElfRel<E>> rels = get_rels(ctx);
|
||||
|
||||
for (i64 i = 0; i < rels.size(); i++) {
|
||||
const ElfRel<E> &rel = rels[i];
|
||||
ElfRel<E> &rel = rels[i];
|
||||
if (rel.r_type == R_NONE)
|
||||
continue;
|
||||
|
||||
Symbol<E> &sym = *file.symbols[rel.r_sym];
|
||||
Symbol<E> &sym = *file->symbols[rel.r_sym];
|
||||
if (sym.get_type() == STT_TLS && sym.is_remaining_undef_weak())
|
||||
continue;
|
||||
|
||||
u8 *loc = base + rel.r_offset;
|
||||
|
||||
u64 S = sym.get_addr(ctx);
|
||||
@@ -489,9 +499,13 @@ void InputSection<E>::apply_reloc_alloc(Context<E> &ctx, u8 *base) {
|
||||
*(ul16 *)loc = S + A - P;
|
||||
break;
|
||||
case R_X86_64_PC32:
|
||||
case R_X86_64_PLT32:
|
||||
write32s(S + A - P);
|
||||
break;
|
||||
case R_X86_64_PLT32:
|
||||
if (!sym.is_remaining_undef_weak())
|
||||
check(S + A - P, -(1LL << 31), 1LL << 31);
|
||||
*(ul32 *)loc = S + A - P;
|
||||
break;
|
||||
case R_X86_64_PC64:
|
||||
*(ul64 *)loc = S + A - P;
|
||||
break;
|
||||
@@ -528,6 +542,8 @@ void InputSection<E>::apply_reloc_alloc(Context<E> &ctx, u8 *base) {
|
||||
loc[-2] = insn >> 8;
|
||||
loc[-1] = insn;
|
||||
*(ul32 *)loc = S + A - P;
|
||||
if (ctx.arg.emit_relocs)
|
||||
rel.r_type = R_X86_64_PC32;
|
||||
break;
|
||||
}
|
||||
}
|
||||
@@ -657,14 +673,11 @@ void InputSection<E>::apply_reloc_alloc(Context<E> &ctx, u8 *base) {
|
||||
// scan_relocations.
|
||||
template <>
|
||||
void InputSection<E>::apply_reloc_nonalloc(Context<E> &ctx, u8 *base) {
|
||||
std::span<const ElfRel<E>> rels = get_rels(ctx);
|
||||
|
||||
for (i64 i = 0; i < rels.size(); i++) {
|
||||
const ElfRel<E> &rel = rels[i];
|
||||
for_each_reloc(ctx, [&](const ElfRel<E> &rel, i64 i) ALWAYS_INLINE {
|
||||
if (rel.r_type == R_NONE || record_undef_error(ctx, rel))
|
||||
continue;
|
||||
return;
|
||||
|
||||
Symbol<E> &sym = *file.symbols[rel.r_sym];
|
||||
Symbol<E> &sym = *file->symbols[rel.r_sym];
|
||||
u8 *loc = base + rel.r_offset;
|
||||
|
||||
SectionFragment<E> *frag;
|
||||
@@ -741,7 +754,7 @@ void InputSection<E>::apply_reloc_nonalloc(Context<E> &ctx, u8 *base) {
|
||||
<< rel;
|
||||
break;
|
||||
}
|
||||
}
|
||||
});
|
||||
}
|
||||
|
||||
// Linker has to create data structures in an output file to apply
|
||||
@@ -760,8 +773,8 @@ void InputSection<E>::scan_relocations(Context<E> &ctx) {
|
||||
if (rel.r_type == R_NONE || record_undef_error(ctx, rel))
|
||||
continue;
|
||||
|
||||
Symbol<E> &sym = *file.symbols[rel.r_sym];
|
||||
u8 *loc = (u8 *)(contents.data() + rel.r_offset);
|
||||
Symbol<E> &sym = *file->symbols[rel.r_sym];
|
||||
u8 *loc = contents + rel.r_offset;
|
||||
|
||||
if (sym.is_ifunc())
|
||||
sym.flags |= NEEDS_GOT | NEEDS_PLT;
|
||||
@@ -859,97 +872,6 @@ void InputSection<E>::scan_relocations(Context<E> &ctx) {
|
||||
}
|
||||
}
|
||||
|
||||
// Intel CET is a relatively new CPU feature to enhance security by
|
||||
// protecting control flow integrity. If the feature is enabled, indirect
|
||||
// branches (i.e. branch instructions that take a register instead of an
|
||||
// immediate) must land on a "landing pad" instruction, or a CPU-level fault
|
||||
// will raise. That prevents an attacker to branch to a middle of a random
|
||||
// function, making ROP or JOP much harder to conduct.
|
||||
//
|
||||
// On x86-64, the landing pad instruction is ENDBR64. That is actually a
|
||||
// repurposed NOP instruction to provide binary compatibility with older
|
||||
// hardware that doesn't support CET.
|
||||
//
|
||||
// The problem here is that the compiler always emits a landing pad at the
|
||||
// beginning fo a global function because it doesn't know whether or not the
|
||||
// function's address is taken in other translation units. As a result, the
|
||||
// resulting binary contains more landing pads than necessary.
|
||||
//
|
||||
// This function rewrites a landing pad with a nop if the function's address
|
||||
// was not actually taken. We can do what the compiler cannot because we
|
||||
// know about all translation units.
|
||||
void rewrite_endbr(Context<E> &ctx) {
|
||||
Timer t(ctx, "rewrite_endbr");
|
||||
|
||||
constexpr u8 endbr64[] = {0xf3, 0x0f, 0x1e, 0xfa};
|
||||
constexpr u8 nop[] = {0x0f, 0x1f, 0x40, 0x00};
|
||||
|
||||
// Rewrite all endbr64 instructions referred to by function symbols with
|
||||
// NOPs. We handle only global symbols because the compiler doesn't emit
|
||||
// an endbr64 for a file-scoped function in the first place if its address
|
||||
// is not taken within the file.
|
||||
tbb::parallel_for_each(ctx.objs, [&](ObjectFile<E> *file) {
|
||||
for (Symbol<E> *sym : file->get_global_syms()) {
|
||||
if (sym->file == file && sym->esym().st_type == STT_FUNC) {
|
||||
if (InputSection<E> *isec = sym->get_input_section();
|
||||
isec && (isec->shdr().sh_flags & SHF_EXECINSTR)) {
|
||||
if (OutputSection<E> *osec = isec->output_section) {
|
||||
u8 *buf = ctx.buf + osec->shdr.sh_offset + isec->offset + sym->value;
|
||||
if (memcmp(buf, endbr64, 4) == 0)
|
||||
memcpy(buf, nop, 4);
|
||||
}
|
||||
}
|
||||
}
|
||||
}
|
||||
});
|
||||
|
||||
auto write_back = [&](InputSection<E> *isec, i64 offset) {
|
||||
// If isec has an endbr64 at a given offset, copy that instruction to
|
||||
// the output buffer, possibly overwriting a nop written in the above
|
||||
// loop.
|
||||
if (isec && isec->output_section &&
|
||||
(isec->shdr().sh_flags & SHF_EXECINSTR) &&
|
||||
0 <= offset && offset <= isec->contents.size() - 4 &&
|
||||
memcmp(isec->contents.data() + offset, endbr64, 4) == 0)
|
||||
memcpy(ctx.buf + isec->output_section->shdr.sh_offset + isec->offset + offset,
|
||||
endbr64, 4);
|
||||
};
|
||||
|
||||
// Write back endbr64 instructions if they are referred to by address-taking
|
||||
// relocations.
|
||||
tbb::parallel_for_each(ctx.objs, [&](ObjectFile<E> *file) {
|
||||
for (std::unique_ptr<InputSection<E>> &isec : file->sections) {
|
||||
if (isec && isec->is_alive && (isec->shdr().sh_flags & SHF_ALLOC)) {
|
||||
for (const ElfRel<E> &rel : isec->get_rels(ctx)) {
|
||||
if (!is_func_call_rel(rel)) {
|
||||
Symbol<E> *sym = file->symbols[rel.r_sym];
|
||||
if (sym->esym().st_type == STT_SECTION)
|
||||
write_back(sym->get_input_section(), rel.r_addend);
|
||||
else
|
||||
write_back(sym->get_input_section(), sym->value);
|
||||
}
|
||||
}
|
||||
}
|
||||
}
|
||||
});
|
||||
|
||||
// We record addresses of some symbols in the ELF header, .dynamic or in
|
||||
// .dynsym. We need to retain endbr64s for such symbols.
|
||||
auto keep = [&](Symbol<E> *sym) {
|
||||
if (sym)
|
||||
write_back(sym->get_input_section(), sym->value);
|
||||
};
|
||||
|
||||
keep(ctx.arg.entry);
|
||||
keep(ctx.arg.init);
|
||||
keep(ctx.arg.fini);
|
||||
|
||||
if (ctx.dynsym)
|
||||
for (Symbol<E> *sym : ctx.dynsym->symbols)
|
||||
if (sym && sym->is_exported)
|
||||
keep(sym);
|
||||
}
|
||||
|
||||
} // namespace mold
|
||||
|
||||
#endif
|
||||
+25
-7
@@ -75,12 +75,14 @@ struct ArHdr {
|
||||
};
|
||||
}
|
||||
|
||||
// Returns the paths of the members of a thin archive, which are stored
|
||||
// outside of the archive file, without opening them.
|
||||
template <typename E>
|
||||
std::vector<MappedFile *>
|
||||
read_thin_archive_members(Context<E> &ctx, MappedFile *mf) {
|
||||
std::vector<std::string>
|
||||
get_thin_archive_member_paths(Context<E> &ctx, MappedFile *mf) {
|
||||
u8 *begin = mf->data;
|
||||
u8 *data = begin + 8;
|
||||
std::vector<MappedFile *> vec;
|
||||
std::vector<std::string> vec;
|
||||
std::string_view strtab;
|
||||
|
||||
while (data < begin + mf->size) {
|
||||
@@ -111,14 +113,27 @@ read_thin_archive_members(Context<E> &ctx, MappedFile *mf) {
|
||||
std::string name = hdr.read_name(strtab, body);
|
||||
|
||||
// Skip if symbol table
|
||||
if (name == "__.SYMDEF" || name == "__.SYMDEF SORTED")
|
||||
if (name == "__.SYMDEF" || name == "__.SYMDEF SORTED") {
|
||||
data = body + size;
|
||||
continue;
|
||||
}
|
||||
|
||||
std::string path = name.starts_with('/') ?
|
||||
name : (path_dirname(mf->name) / name).string();
|
||||
if (name.starts_with('/'))
|
||||
vec.push_back(name);
|
||||
else
|
||||
vec.push_back((path_dirname(mf->name) / name).string());
|
||||
data = body;
|
||||
}
|
||||
return vec;
|
||||
}
|
||||
|
||||
template <typename E>
|
||||
std::vector<MappedFile *>
|
||||
read_thin_archive_members(Context<E> &ctx, MappedFile *mf) {
|
||||
std::vector<MappedFile *> vec;
|
||||
for (std::string &path : get_thin_archive_member_paths(ctx, mf)) {
|
||||
vec.push_back(must_open_file(ctx, path));
|
||||
vec.back()->thin_parent = mf;
|
||||
data = body;
|
||||
}
|
||||
return vec;
|
||||
}
|
||||
@@ -176,6 +191,9 @@ read_archive_members(Context<E> &ctx, MappedFile *mf) {
|
||||
|
||||
using E = MOLD_TARGET;
|
||||
|
||||
template std::vector<std::string>
|
||||
get_thin_archive_member_paths(Context<E> &, MappedFile *);
|
||||
|
||||
template std::vector<MappedFile *>
|
||||
read_thin_archive_members(Context<E> &, MappedFile *);
|
||||
|
||||
|
||||
+216
-158
@@ -47,7 +47,7 @@ Options:
|
||||
Set DT_DEPAUDIT to the specified value
|
||||
-S, --strip-debug Strip .debug_* sections
|
||||
-T FILE, --script FILE Read linker script
|
||||
-X, --discard-locals Discard temporary local symbols
|
||||
-X, --discard-locals Discard temporary local symbols (default)
|
||||
-e SYMBOL, --entry SYMBOL Set program entry point
|
||||
-f SHLIB, --auxiliary SHLIB Set DT_AUXILIARY to the specified value
|
||||
-h LIBNAME, --soname LIBNAME
|
||||
@@ -76,6 +76,7 @@ Options:
|
||||
--Tbss=ADDR Set address to .bss
|
||||
--Tdata=ADDR Set address to .data
|
||||
--Ttext=ADDR Set address to .text
|
||||
--Ttext-segment=ADDR Set address of text segment
|
||||
--allow-multiple-definition Allow multiple definitions
|
||||
--apply-dynamic-relocs Apply link-time values for dynamic relocations (default)
|
||||
--no-apply-dynamic-relocs
|
||||
@@ -98,6 +99,7 @@ Options:
|
||||
--no-demangle
|
||||
--detach Create separate debug info file in the background (default)
|
||||
--no-detach
|
||||
--discard-none Keep all local symbols in the symbol table
|
||||
--enable-new-dtags Emit DT_RUNPATH for --rpath (default)
|
||||
--disable-new-dtags Emit DT_RPATH for --rpath
|
||||
--execute-only Make executable segments unreadable
|
||||
@@ -237,6 +239,24 @@ Options:
|
||||
mold: supported targets: elf32-i386 elf64-x86-64 elf32-littlearm elf64-littleaarch64 elf64-bigaarch64 elf32-littleriscv elf32-bigriscv elf64-littleriscv elf64-bigriscv elf32-powerpc elf64-powerpc elf64-powerpc elf64-powerpcle elf64-s390 elf64-sparc elf32-m68k elf32-sh-linux elf64-loongarch elf32-loongarch
|
||||
mold: supported emulations: elf_i386 elf_x86_64 armelf_linux_eabi aarch64elf aarch64linux aarch64elfb aarch64linuxb elf32lriscv elf32briscv elf64lriscv elf64briscv elf32ppc elf32ppclinux elf64ppc elf64lppc elf64_s390 elf64_sparc m68kelf shlelf_linux shelf_linux elf64loongarch elf32loongarch)";
|
||||
|
||||
// Same as isspace() in the C locale, without the function call that the
|
||||
// tokenizer below would otherwise make for every byte of a response file.
|
||||
static constexpr std::array<bool, 256> is_space = [] {
|
||||
std::array<bool, 256> x = {};
|
||||
for (u8 c : {' ', '\t', '\n', '\v', '\f', '\r'})
|
||||
x[c] = true;
|
||||
return x;
|
||||
}();
|
||||
|
||||
// True for the characters that end or alter a token: whitespace, quotes
|
||||
// and backslash. A table keeps the tokenizer's scan loop tight.
|
||||
static constexpr std::array<bool, 256> is_token_boundary = [] {
|
||||
std::array<bool, 256> x = {};
|
||||
for (u8 c : {' ', '\t', '\n', '\v', '\f', '\r', '\\', '\'', '"'})
|
||||
x[c] = true;
|
||||
return x;
|
||||
}();
|
||||
|
||||
// If a command line argument is in the form of `@path/to/some/file` (i.e.
|
||||
// it starts with an atsign), the linker reads the given file and
|
||||
// interprets its contents as a list of command line arguments. A file
|
||||
@@ -256,91 +276,64 @@ read_response_file(Context<E> &ctx, std::string_view path, i64 depth) {
|
||||
MappedFile *mf = must_open_file(ctx, std::string(path));
|
||||
mf->is_dependency = false;
|
||||
|
||||
std::vector<std::string> vec;
|
||||
std::ostringstream os;
|
||||
char quote = 0;
|
||||
std::string_view data((char *)mf->data, mf->size);
|
||||
std::vector<std::string_view> vec;
|
||||
|
||||
// Each state represents the type of characters currently being read.
|
||||
// SPACE indicates blank characters between tokens, BARE indicates an
|
||||
// unquoted token, and QUOTED indicates a quoted token.
|
||||
enum { SPACE, BARE, QUOTED } state = SPACE;
|
||||
|
||||
for (i64 i = 0; i <= mf->size; i++) {
|
||||
char c = (i < mf->size) ? mf->data[i] : 0;
|
||||
char c2 = (i + 1 < mf->size) ? mf->data[i + 1] : 0;
|
||||
|
||||
if (c == '\\' && c2 == 0)
|
||||
Fatal(ctx) << path << ": premature end of input";
|
||||
|
||||
switch (state) {
|
||||
case SPACE:
|
||||
if (c == 0 || isspace(c))
|
||||
break;
|
||||
|
||||
if (c == '\\') {
|
||||
os << c2;
|
||||
state = BARE;
|
||||
i++;
|
||||
break;
|
||||
}
|
||||
|
||||
if (c == '\'' || c == '"') {
|
||||
quote = c;
|
||||
state = QUOTED;
|
||||
break;
|
||||
}
|
||||
|
||||
os << c;
|
||||
state = BARE;
|
||||
break;
|
||||
case BARE:
|
||||
if (c == 0 || isspace(c)) {
|
||||
vec.push_back(os.str());
|
||||
os = {};
|
||||
state = SPACE;
|
||||
break;
|
||||
}
|
||||
|
||||
if (c == '\\') {
|
||||
os << c2;
|
||||
i++;
|
||||
break;
|
||||
}
|
||||
|
||||
if (c == '\'' || c == '"') {
|
||||
quote = c;
|
||||
state = QUOTED;
|
||||
break;
|
||||
}
|
||||
|
||||
os << c;
|
||||
break;
|
||||
case QUOTED:
|
||||
if (c == 0)
|
||||
Fatal(ctx) << path << ": premature end of input";
|
||||
|
||||
if (c == '\\') {
|
||||
os << c2;
|
||||
i++;
|
||||
break;
|
||||
}
|
||||
|
||||
if (c == quote) {
|
||||
state = BARE;
|
||||
break;
|
||||
}
|
||||
|
||||
os << c;
|
||||
break;
|
||||
for (i64 i = 0; i < data.size();) {
|
||||
if (is_space[(u8)data[i]]) {
|
||||
i++;
|
||||
continue;
|
||||
}
|
||||
|
||||
// A token containing no quotes or backslashes, which is by far the
|
||||
// common case, is returned as a substring of the file.
|
||||
i64 end = i;
|
||||
while (end < data.size() && !is_token_boundary[(u8)data[end]])
|
||||
end++;
|
||||
|
||||
if (end == data.size() || is_space[(u8)data[end]]) {
|
||||
vec.push_back(data.substr(i, end - i));
|
||||
i = end;
|
||||
continue;
|
||||
}
|
||||
|
||||
// Otherwise, copy the token, removing quotes and backslashes. A
|
||||
// backslash escapes the next character, and a quoted part may be
|
||||
// followed by more characters of the same token.
|
||||
std::string tok(data.substr(i, end - i));
|
||||
char quote = 0;
|
||||
|
||||
for (i = end; i < data.size(); i++) {
|
||||
char c = data[i];
|
||||
if (c == '\\') {
|
||||
if (i + 1 == data.size())
|
||||
Fatal(ctx) << path << ": premature end of input";
|
||||
tok += data[++i];
|
||||
} else if (quote) {
|
||||
if (c == quote)
|
||||
quote = 0;
|
||||
else
|
||||
tok += c;
|
||||
} else if (c == '\'' || c == '"') {
|
||||
quote = c;
|
||||
} else if (is_space[(u8)c]) {
|
||||
break;
|
||||
} else {
|
||||
tok += c;
|
||||
}
|
||||
}
|
||||
|
||||
if (quote)
|
||||
Fatal(ctx) << path << ": premature end of input";
|
||||
vec.push_back(save_string(ctx, tok));
|
||||
}
|
||||
|
||||
std::vector<std::string_view> vec2;
|
||||
for (std::string &tok : vec) {
|
||||
for (std::string_view tok : vec) {
|
||||
if (tok.starts_with('@'))
|
||||
append(vec2, read_response_file(ctx, tok.substr(1), depth + 1));
|
||||
else
|
||||
vec2.push_back(save_string(ctx, tok));
|
||||
vec2.push_back(tok);
|
||||
}
|
||||
return vec2;
|
||||
}
|
||||
@@ -371,19 +364,40 @@ static std::string_view string_trim(std::string_view str) {
|
||||
return str.substr(0, pos + 1);
|
||||
}
|
||||
|
||||
static std::vector<std::string> add_dashes(std::string name) {
|
||||
// Single-letter option
|
||||
if (name.size() == 1)
|
||||
return {"-" + name};
|
||||
// This function matches a command line argument against an option
|
||||
// name and, on success, returns the remainder of the argument. For
|
||||
// example, matching "--foo=bar" against "foo" yields "=bar", and
|
||||
// matching "--foo" against "foo" yields an empty string. On
|
||||
// mismatch, it returns std::nullopt.
|
||||
//
|
||||
// Multi-letter option names can be preceded by either a single dash
|
||||
// or double dashes except ones starting with "o", which must be
|
||||
// preceded by double dashes. For example, "-omagic" is interpreted
|
||||
// as "-o magic". If you really want to specify the "omagic" option,
|
||||
// you have to pass "--omagic". Single-letter option names take a
|
||||
// single dash.
|
||||
static std::optional<std::string_view>
|
||||
match_option(std::string_view arg, std::string_view name) {
|
||||
assert(arg.starts_with('-'));
|
||||
arg.remove_prefix(1);
|
||||
|
||||
// Multi-letter linker options can be preceded by either a single
|
||||
// dash or double dashes except ones starting with "o", which must
|
||||
// be preceded by double dashes. For example, "-omagic" is
|
||||
// interpreted as "-o magic". If you really want to specify the
|
||||
// "omagic" option, you have to pass "--omagic".
|
||||
if (name[0] == 'o')
|
||||
return {"--" + name};
|
||||
return {"-" + name, "--" + name};
|
||||
// Single-letter option
|
||||
if (name.size() == 1) {
|
||||
if (arg.starts_with(name))
|
||||
return arg.substr(1);
|
||||
return {};
|
||||
}
|
||||
|
||||
// Options beginning with "o" require double dashes
|
||||
if (name[0] == 'o' && !arg.starts_with('-'))
|
||||
return {};
|
||||
|
||||
if (arg.starts_with('-'))
|
||||
arg.remove_prefix(1);
|
||||
|
||||
if (arg.starts_with(name))
|
||||
return arg.substr(name.size());
|
||||
return {};
|
||||
}
|
||||
|
||||
template <typename E>
|
||||
@@ -571,7 +585,7 @@ parse_defsym_value(Context<E> &ctx, std::string_view s) {
|
||||
size_t nread;
|
||||
u64 addr = std::stoull(std::string(s), &nread, 16);
|
||||
if (s.size() != nread)
|
||||
return {};
|
||||
Fatal(ctx) << "-defsym: not a number: " << s;
|
||||
return addr;
|
||||
}
|
||||
|
||||
@@ -608,11 +622,18 @@ static bool returns_etxtbsy() {
|
||||
}
|
||||
|
||||
template <typename E>
|
||||
std::vector<std::string> parse_nonpositional_args(Context<E> &ctx) {
|
||||
std::vector<ReaderJob> parse_nonpositional_args(Context<E> &ctx) {
|
||||
std::span<std::string_view> args = ctx.cmdline_args;
|
||||
args = args.subspan(1);
|
||||
|
||||
std::vector<std::string> remaining;
|
||||
// Input file arguments are turned into ReaderJobs for
|
||||
// read_input_files(). rctx tracks the reader state options, such as
|
||||
// --as-needed, that apply to the files after them; each job gets a
|
||||
// snapshot of the state at its position.
|
||||
std::vector<ReaderJob> jobs;
|
||||
ReaderContext rctx;
|
||||
std::vector<ReaderContext> rctx_stack;
|
||||
std::unordered_set<std::string_view> visited_libs;
|
||||
std::string_view arg;
|
||||
|
||||
ctx.arg.color_diagnostics = isatty(STDERR_FILENO);
|
||||
@@ -638,11 +659,6 @@ std::vector<std::string> parse_nonpositional_args(Context<E> &ctx) {
|
||||
}
|
||||
};
|
||||
|
||||
// RISC-V and LoongArch object files contains lots of local symbols,
|
||||
// so by default we discard them. This is compatible with GNU ld.
|
||||
if constexpr (is_riscv<E> || is_loongarch<E>)
|
||||
ctx.arg.discard_locals = true;
|
||||
|
||||
// We generally don't need to write addends to relocated places if the
|
||||
// relocation type is RELA because RELA records contain addends.
|
||||
// However, there are too much code that wrongly assumes that addends
|
||||
@@ -657,76 +673,95 @@ std::vector<std::string> parse_nonpositional_args(Context<E> &ctx) {
|
||||
// we write addends to relocated places.
|
||||
ctx.arg.apply_dynamic_relocs = !is_sparc<E> && !is_riscv<E>;
|
||||
|
||||
auto read_arg = [&](std::string name) {
|
||||
for (const std::string &opt : add_dashes(name)) {
|
||||
if (args[0] == opt) {
|
||||
if (args.size() == 1)
|
||||
Fatal(ctx) << "option -" << name << ": argument missing";
|
||||
arg = args[1];
|
||||
args = args.subspan(2);
|
||||
return true;
|
||||
}
|
||||
auto read_arg = [&](std::string_view name) {
|
||||
std::optional<std::string_view> rest = match_option(args[0], name);
|
||||
if (!rest)
|
||||
return false;
|
||||
|
||||
std::string prefix = (name.size() == 1) ? opt : opt + "=";
|
||||
if (args[0].starts_with(prefix)) {
|
||||
arg = args[0].substr(prefix.size());
|
||||
args = args.subspan(1);
|
||||
return true;
|
||||
}
|
||||
// An option and its argument are either separate command line
|
||||
// arguments or a single one, as in "-o foo" vs. "-ofoo" or
|
||||
// "--output foo" vs. "--output=foo".
|
||||
if (rest->empty()) {
|
||||
if (args.size() == 1)
|
||||
Fatal(ctx) << "option -" << name << ": argument missing";
|
||||
arg = args[1];
|
||||
args = args.subspan(2);
|
||||
return true;
|
||||
}
|
||||
|
||||
if (name.size() == 1) {
|
||||
arg = *rest;
|
||||
args = args.subspan(1);
|
||||
return true;
|
||||
}
|
||||
|
||||
if (rest->starts_with('=')) {
|
||||
arg = rest->substr(1);
|
||||
args = args.subspan(1);
|
||||
return true;
|
||||
}
|
||||
return false;
|
||||
};
|
||||
|
||||
auto read_eq = [&](std::string name) {
|
||||
for (const std::string &opt : add_dashes(name)) {
|
||||
if (args[0].starts_with(opt + "=")) {
|
||||
arg = args[0].substr(opt.size() + 1);
|
||||
args = args.subspan(1);
|
||||
return true;
|
||||
}
|
||||
auto read_eq = [&](std::string_view name) {
|
||||
std::optional<std::string_view> rest = match_option(args[0], name);
|
||||
if (rest && rest->starts_with('=')) {
|
||||
arg = rest->substr(1);
|
||||
args = args.subspan(1);
|
||||
return true;
|
||||
}
|
||||
return false;
|
||||
};
|
||||
|
||||
auto read_flag = [&](std::string name) {
|
||||
for (const std::string &opt : add_dashes(name)) {
|
||||
if (args[0] == opt) {
|
||||
args = args.subspan(1);
|
||||
return true;
|
||||
}
|
||||
auto read_flag = [&](std::string_view name) {
|
||||
if (match_option(args[0], name) == "") {
|
||||
args = args.subspan(1);
|
||||
return true;
|
||||
}
|
||||
return false;
|
||||
};
|
||||
|
||||
auto read_z_flag = [&](std::string name) {
|
||||
auto read_z_flag = [&](std::string_view name) {
|
||||
if (args.size() >= 2 && args[0] == "-z" && args[1] == name) {
|
||||
args = args.subspan(2);
|
||||
return true;
|
||||
}
|
||||
|
||||
if (!args.empty() && args[0] == "-z" + name) {
|
||||
if (args[0].starts_with("-z") && args[0].substr(2) == name) {
|
||||
args = args.subspan(1);
|
||||
return true;
|
||||
}
|
||||
return false;
|
||||
};
|
||||
|
||||
auto read_z_arg = [&](std::string name) {
|
||||
if (args.size() >= 2 && args[0] == "-z" && args[1].starts_with(name + "=")) {
|
||||
auto read_z_arg = [&](std::string_view name) {
|
||||
if (args.size() >= 2 && args[0] == "-z" && args[1].starts_with(name) &&
|
||||
args[1].substr(name.size()).starts_with('=')) {
|
||||
arg = args[1].substr(name.size() + 1);
|
||||
args = args.subspan(2);
|
||||
return true;
|
||||
}
|
||||
|
||||
if (!args.empty() && args[0].starts_with("-z" + name + "=")) {
|
||||
arg = args[0].substr(name.size() + 3);
|
||||
args = args.subspan(1);
|
||||
return true;
|
||||
if (args[0].starts_with("-z")) {
|
||||
std::string_view s = args[0].substr(2);
|
||||
if (s.starts_with(name) && s.substr(name.size()).starts_with('=')) {
|
||||
arg = s.substr(name.size() + 1);
|
||||
args = args.subspan(1);
|
||||
return true;
|
||||
}
|
||||
}
|
||||
return false;
|
||||
};
|
||||
|
||||
while (!args.empty()) {
|
||||
if (!args[0].starts_with('-')) {
|
||||
ReaderJob job = {rctx, std::string(args[0])};
|
||||
job.rctx.pos = {(u32)jobs.size()};
|
||||
jobs.push_back(std::move(job));
|
||||
args = args.subspan(1);
|
||||
continue;
|
||||
}
|
||||
|
||||
if (read_flag("help")) {
|
||||
Out(ctx) << "Usage: " << ctx.cmdline_args[0]
|
||||
<< " [options] file...\n" << helpmsg;
|
||||
@@ -828,7 +863,7 @@ std::vector<std::string> parse_nonpositional_args(Context<E> &ctx) {
|
||||
Fatal(ctx) << "unknown -m argument: " << arg;
|
||||
}
|
||||
} else if (read_flag("end-lib")) {
|
||||
remaining.emplace_back("--end-lib");
|
||||
rctx.in_lib = false;
|
||||
} else if (read_flag("export-dynamic") || read_flag("E")) {
|
||||
ctx.arg.export_dynamic = true;
|
||||
} else if (read_flag("no-export-dynamic")) {
|
||||
@@ -859,9 +894,9 @@ std::vector<std::string> parse_nonpositional_args(Context<E> &ctx) {
|
||||
} else if (read_flag("print-map") || read_flag("M")) {
|
||||
ctx.arg.print_map = true;
|
||||
} else if (read_flag("Bstatic") || read_flag("dn") || read_flag("static")) {
|
||||
remaining.emplace_back("--Bstatic");
|
||||
rctx.static_ = true;
|
||||
} else if (read_flag("Bdynamic") || read_flag("dy")) {
|
||||
remaining.emplace_back("--Bdynamic");
|
||||
rctx.static_ = false;
|
||||
} else if (read_flag("shared") || read_flag("Bshareable")) {
|
||||
ctx.arg.shared = true;
|
||||
} else if (read_arg("spare-dynamic-tags")) {
|
||||
@@ -870,7 +905,7 @@ std::vector<std::string> parse_nonpositional_args(Context<E> &ctx) {
|
||||
ctx.arg.spare_program_headers
|
||||
= parse_number(ctx, "spare-program-headers", arg);
|
||||
} else if (read_flag("start-lib")) {
|
||||
remaining.emplace_back("--start-lib");
|
||||
rctx.in_lib = true;
|
||||
} else if (read_flag("start-stop")) {
|
||||
ctx.arg.start_stop = true;
|
||||
} else if (read_arg("dependency-file")) {
|
||||
@@ -1080,7 +1115,7 @@ std::vector<std::string> parse_nonpositional_args(Context<E> &ctx) {
|
||||
ctx.arg.wrap.insert(arg);
|
||||
} else if (read_flag("omagic") || read_flag("N")) {
|
||||
ctx.arg.omagic = true;
|
||||
remaining.emplace_back("--Bstatic");
|
||||
rctx.static_ = true;
|
||||
} else if (read_flag("no-omagic")) {
|
||||
ctx.arg.omagic = false;
|
||||
} else if (read_arg("oformat")) {
|
||||
@@ -1111,6 +1146,8 @@ std::vector<std::string> parse_nonpositional_args(Context<E> &ctx) {
|
||||
ctx.arg.section_start[".data"] = parse_hex(ctx, "Tdata", arg);
|
||||
} else if (read_arg("Ttext")) {
|
||||
ctx.arg.section_start[".text"] = parse_hex(ctx, "Ttext", arg);
|
||||
} else if (read_arg("Ttext-segment")) {
|
||||
ctx.arg.ttext_segment = parse_number(ctx, "Ttext-segment", arg);
|
||||
} else if (read_flag("repro")) {
|
||||
ctx.arg.repro = true;
|
||||
} else if (read_z_flag("now")) {
|
||||
@@ -1207,8 +1244,8 @@ std::vector<std::string> parse_nonpositional_args(Context<E> &ctx) {
|
||||
} else if (read_z_flag("x86-64-v4")) {
|
||||
ctx.arg.z_x86_64_isa_level |= GNU_PROPERTY_X86_ISA_1_V4;
|
||||
} else if (read_z_flag("rewrite-endbr")) {
|
||||
if constexpr (!is_x86_64<E>)
|
||||
Fatal(ctx) << "-z rewrite-endbr is supported only on x86-64";
|
||||
if constexpr (!is_x86_64<E> && !is_arm64<E>)
|
||||
Fatal(ctx) << "-z rewrite-endbr is supported only on x86-64 and arm64";
|
||||
ctx.arg.z_rewrite_endbr = true;
|
||||
} else if (read_z_flag("norewrite-endbr")) {
|
||||
ctx.arg.z_rewrite_endbr = false;
|
||||
@@ -1300,7 +1337,7 @@ std::vector<std::string> parse_nonpositional_args(Context<E> &ctx) {
|
||||
std::string(arg));
|
||||
} else if (read_arg("opt-remarks-passes")) {
|
||||
ctx.arg.plugin_opt.push_back("opt-remarks-passes=" + std::string(arg));
|
||||
} else if (read_flag("opt-remarks-with_hotness")) {
|
||||
} else if (read_flag("opt-remarks-with-hotness")) {
|
||||
ctx.arg.plugin_opt.emplace_back("opt-remarks-with-hotness");
|
||||
} else if (args[0].starts_with("-lto-O")) {
|
||||
ctx.arg.plugin_opt.push_back("O" + std::string(args[0].substr(6)));
|
||||
@@ -1344,6 +1381,9 @@ std::vector<std::string> parse_nonpositional_args(Context<E> &ctx) {
|
||||
ctx.arg.discard_all = true;
|
||||
} else if (read_flag("discard-locals") || read_flag("X")) {
|
||||
ctx.arg.discard_locals = true;
|
||||
} else if (read_flag("discard-none")) {
|
||||
ctx.arg.discard_all = false;
|
||||
ctx.arg.discard_locals = false;
|
||||
} else if (read_flag("strip-all") || read_flag("s")) {
|
||||
ctx.arg.strip_all = true;
|
||||
} else if (read_flag("strip-debug") || read_flag("S")) {
|
||||
@@ -1462,21 +1502,31 @@ std::vector<std::string> parse_nonpositional_args(Context<E> &ctx) {
|
||||
} else if (read_arg("export-dynamic-symbol-list")) {
|
||||
append(ctx.dynamic_list_patterns, parse_dynamic_list(ctx, arg));
|
||||
} else if (read_flag("as-needed")) {
|
||||
remaining.emplace_back("--as-needed");
|
||||
rctx.as_needed = true;
|
||||
} else if (read_flag("no-as-needed")) {
|
||||
remaining.emplace_back("--no-as-needed");
|
||||
rctx.as_needed = false;
|
||||
} else if (read_flag("whole-archive")) {
|
||||
remaining.emplace_back("--whole-archive");
|
||||
rctx.whole_archive = true;
|
||||
} else if (read_flag("no-whole-archive")) {
|
||||
remaining.emplace_back("--no-whole-archive");
|
||||
rctx.whole_archive = false;
|
||||
} else if (read_arg("l") || read_arg("library")) {
|
||||
remaining.push_back("-l" + std::string(arg));
|
||||
if (visited_libs.insert(arg).second) {
|
||||
ReaderJob job = {rctx, std::string(arg)};
|
||||
job.is_lib = true;
|
||||
job.rctx.pos = {(u32)jobs.size()};
|
||||
jobs.push_back(std::move(job));
|
||||
}
|
||||
} else if (read_arg("script") || read_arg("T")) {
|
||||
remaining.emplace_back(arg);
|
||||
ReaderJob job = {rctx, std::string(arg)};
|
||||
job.rctx.pos = {(u32)jobs.size()};
|
||||
jobs.push_back(std::move(job));
|
||||
} else if (read_flag("push-state")) {
|
||||
remaining.emplace_back("--push-state");
|
||||
rctx_stack.push_back(rctx);
|
||||
} else if (read_flag("pop-state")) {
|
||||
remaining.emplace_back("--pop-state");
|
||||
if (rctx_stack.empty())
|
||||
Fatal(ctx) << "no state pushed before popping";
|
||||
rctx = rctx_stack.back();
|
||||
rctx_stack.pop_back();
|
||||
} else if (args[0].starts_with("-z") && args[0].size() > 2) {
|
||||
Warn(ctx) << "unknown command line option: " << args[0];
|
||||
args = args.subspan(1);
|
||||
@@ -1487,10 +1537,7 @@ std::vector<std::string> parse_nonpositional_args(Context<E> &ctx) {
|
||||
Fatal(ctx) << "unknown command line option: -dynamic; -dynamic is a "
|
||||
<< "macOS linker's option. mold does not support macOS.";
|
||||
} else {
|
||||
if (args[0].starts_with('-'))
|
||||
Fatal(ctx) << "unknown command line option: " << args[0];
|
||||
remaining.emplace_back(args[0]);
|
||||
args = args.subspan(1);
|
||||
Fatal(ctx) << "unknown command line option: " << args[0];
|
||||
}
|
||||
}
|
||||
|
||||
@@ -1527,8 +1574,14 @@ std::vector<std::string> parse_nonpositional_args(Context<E> &ctx) {
|
||||
if (ctx.arg.shared)
|
||||
ctx.arg.pic = true;
|
||||
|
||||
if (ctx.arg.pic)
|
||||
if (ctx.arg.ttext_segment) {
|
||||
u64 val = *ctx.arg.ttext_segment;
|
||||
if (val % ctx.page_size)
|
||||
Warn(ctx) << "-Ttext-segment is not a multiple of page size: " << val;
|
||||
ctx.arg.image_base = align_down(val, ctx.page_size);
|
||||
} else if (ctx.arg.pic) {
|
||||
ctx.arg.image_base = 0;
|
||||
}
|
||||
|
||||
// A shared library is loaded by the dynamic linker, so it doesn't need
|
||||
// PT_INTERP. (-pie makes the output an executable even with -shared.)
|
||||
@@ -1685,14 +1738,19 @@ std::vector<std::string> parse_nonpositional_args(Context<E> &ctx) {
|
||||
sym->gc_root = true;
|
||||
ctx.arg.entry->gc_root = true;
|
||||
|
||||
if (version_shown && remaining.empty())
|
||||
if (version_shown && jobs.empty())
|
||||
exit(0);
|
||||
return remaining;
|
||||
|
||||
if (rctx.static_ || ctx.arg.relocatable) {
|
||||
ctx.arg.static_ = true;
|
||||
ctx.arg.dynamic_linker = "";
|
||||
}
|
||||
return jobs;
|
||||
}
|
||||
|
||||
using E = MOLD_TARGET;
|
||||
|
||||
template std::vector<std::string_view> expand_response_files(Context<E> &, char **);
|
||||
template std::vector<std::string> parse_nonpositional_args(Context<E> &ctx);
|
||||
template std::vector<ReaderJob> parse_nonpositional_args(Context<E> &ctx);
|
||||
|
||||
} // namespace mold
|
||||
@@ -395,6 +395,7 @@ std::string rel_to_string<RV64LE>(u32 r_type) {
|
||||
CASE(R_RISCV_TLS_DTPREL64);
|
||||
CASE(R_RISCV_TLS_TPREL32);
|
||||
CASE(R_RISCV_TLS_TPREL64);
|
||||
CASE(R_RISCV_TLSDESC);
|
||||
CASE(R_RISCV_BRANCH);
|
||||
CASE(R_RISCV_JAL);
|
||||
CASE(R_RISCV_CALL);
|
||||
@@ -429,6 +430,7 @@ std::string rel_to_string<RV64LE>(u32 r_type) {
|
||||
CASE(R_RISCV_SET8);
|
||||
CASE(R_RISCV_SET16);
|
||||
CASE(R_RISCV_SET32);
|
||||
CASE(R_RISCV_GOT32_PCREL);
|
||||
CASE(R_RISCV_32_PCREL);
|
||||
CASE(R_RISCV_IRELATIVE);
|
||||
CASE(R_RISCV_PLT32);
|
||||
@@ -751,6 +753,8 @@ std::string rel_to_string<SPARC64>(u32 r_type) {
|
||||
CASE(R_SPARC_GOTDATA_OP_HIX22);
|
||||
CASE(R_SPARC_GOTDATA_OP_LOX10);
|
||||
CASE(R_SPARC_GOTDATA_OP);
|
||||
CASE(R_SPARC_SIZE32);
|
||||
CASE(R_SPARC_JMP_IREL);
|
||||
CASE(R_SPARC_IRELATIVE);
|
||||
}
|
||||
return unknown_type(r_type);
|
||||
|
||||
@@ -170,6 +170,7 @@ enum : u32 {
|
||||
VER_NDX_GLOBAL = 1,
|
||||
VER_NDX_LAST_RESERVED = 1,
|
||||
VER_NDX_UNSPECIFIED = 0xffff,
|
||||
VERSYM_HIDDEN = 0x8000,
|
||||
};
|
||||
|
||||
enum : u32 {
|
||||
@@ -178,10 +179,6 @@ enum : u32 {
|
||||
VER_FLG_INFO = 4,
|
||||
};
|
||||
|
||||
enum : u32 {
|
||||
VERSYM_HIDDEN = 0x8000,
|
||||
};
|
||||
|
||||
enum : u32 {
|
||||
PT_NULL = 0,
|
||||
PT_LOAD = 1,
|
||||
@@ -377,6 +374,10 @@ enum : u32 {
|
||||
EF_ARM_EABI_VER5 = 0x5000000,
|
||||
};
|
||||
|
||||
enum : u32 {
|
||||
EF_PPC64_ABI = 3,
|
||||
};
|
||||
|
||||
enum : u32 {
|
||||
EF_RISCV_RVC = 1,
|
||||
EF_RISCV_FLOAT_ABI = 6,
|
||||
@@ -1428,9 +1429,11 @@ enum : u32 {
|
||||
|
||||
enum : u32 {
|
||||
DW_UT_compile = 0x01,
|
||||
DW_UT_type = 0x02,
|
||||
DW_UT_partial = 0x03,
|
||||
DW_UT_skeleton = 0x04,
|
||||
DW_UT_split_compile = 0x05,
|
||||
DW_UT_split_type = 0x06,
|
||||
};
|
||||
|
||||
enum : u32 {
|
||||
@@ -1833,34 +1836,6 @@ struct ElfRel<SPARC64> {
|
||||
ib64 r_addend;
|
||||
};
|
||||
|
||||
template <>
|
||||
struct ElfRel<SH4LE> {
|
||||
ElfRel() = default;
|
||||
|
||||
// Addend is ignored except for base relocations because even though
|
||||
// SH4 is RELA, r_addend is ignored in most cases and works as if it
|
||||
// were REL.
|
||||
ElfRel(u64 offset, u32 type, u32 sym, i64 addend)
|
||||
: r_offset(offset), r_type(type), r_sym(sym), r_addend(sym ? 0 : addend) {}
|
||||
|
||||
ul32 r_offset;
|
||||
u8 r_type;
|
||||
ul24 r_sym;
|
||||
il32 r_addend;
|
||||
};
|
||||
|
||||
template <>
|
||||
struct ElfRel<SH4BE> {
|
||||
ElfRel() = default;
|
||||
ElfRel(u64 offset, u32 type, u32 sym, i64 addend)
|
||||
: r_offset(offset), r_sym(sym), r_type(type), r_addend(sym ? 0 : addend) {}
|
||||
|
||||
ub32 r_offset;
|
||||
ub24 r_sym;
|
||||
u8 r_type;
|
||||
ib32 r_addend;
|
||||
};
|
||||
|
||||
//
|
||||
// Machine descriptions
|
||||
//
|
||||
@@ -1968,7 +1943,7 @@ struct ARM64LE {
|
||||
static constexpr u32 plt_size = 16;
|
||||
static constexpr u32 pltgot_size = 16;
|
||||
static constexpr u32 thunk_hdr_size = 0;
|
||||
static constexpr u32 thunk_size = 32;
|
||||
static constexpr u32 thunk_size = 24;
|
||||
static constexpr u8 trap[] = { 0x00, 0x7d, 0x20, 0xd4 }; // brk
|
||||
|
||||
static constexpr u32 R_COPY = R_AARCH64_COPY;
|
||||
@@ -2235,7 +2210,7 @@ struct SH4LE {
|
||||
static constexpr u32 page_size = 4096;
|
||||
static constexpr u32 e_machine = EM_SH;
|
||||
static constexpr u32 plt_hdr_size = 16;
|
||||
static constexpr u32 plt_size = 16;
|
||||
static constexpr u32 plt_size = 20;
|
||||
static constexpr u32 pltgot_size = 12;
|
||||
static constexpr u8 trap[] = { 0xfd, 0xff }; // illegal
|
||||
|
||||
|
||||
@@ -14,6 +14,10 @@
|
||||
# include <mimalloc-new-delete.h>
|
||||
#endif
|
||||
|
||||
#ifdef __linux__
|
||||
# include <sys/prctl.h>
|
||||
#endif
|
||||
|
||||
std::string mold::mold_version =
|
||||
#ifdef MOLD_GIT_HASH
|
||||
"mold " MOLD_VERSION " (" MOLD_GIT_HASH "; compatible with GNU ld)";
|
||||
@@ -28,5 +32,12 @@ int main(int argc, char **argv) {
|
||||
mi_option_disable(mi_option_show_errors);
|
||||
#endif
|
||||
|
||||
#if defined(__linux__) && defined(PR_SET_THP_DISABLE)
|
||||
// A parent process may have disabled transparent huge pages, and the
|
||||
// flag is inherited. Huge pages make mold considerably faster on
|
||||
// large links, so re-enable them for this process.
|
||||
prctl(PR_SET_THP_DISABLE, 0, 0, 0, 0);
|
||||
#endif
|
||||
|
||||
return mold::mold_main<mold::MOLD_FIRST_TARGET>(argc, argv);
|
||||
}
|
||||
+21
-5
@@ -17,7 +17,12 @@ static bool is_gcc_lto_obj(MappedFile *mf, bool has_gcc_plugin) {
|
||||
const char *data = mf->get_contents().data();
|
||||
ElfEhdr<E> &ehdr = *(ElfEhdr<E> *)data;
|
||||
ElfShdr<E> *sh_begin = (ElfShdr<E> *)(data + ehdr.e_shoff);
|
||||
std::span<ElfShdr<E>> shdrs{(ElfShdr<E> *)(data + ehdr.e_shoff), ehdr.e_shnum};
|
||||
|
||||
// e_shnum is a 16-bit field. If an object file contains more than 65279
|
||||
// sections, e_shnum is zero and the actual number is stored to the first
|
||||
// section header's sh_size field.
|
||||
i64 num_sections = (ehdr.e_shnum == 0) ? sh_begin->sh_size : ehdr.e_shnum;
|
||||
std::span<ElfShdr<E>> shdrs{sh_begin, (size_t)num_sections};
|
||||
|
||||
// e_shstrndx is a 16-bit field. If .shstrtab's section index is
|
||||
// too large, the actual number is stored to sh_link field.
|
||||
@@ -133,10 +138,10 @@ static std::string_view get_elf_type(u8 *buf) {
|
||||
bool is_le = (buf[EI_DATA] == ELFDATA2LSB);
|
||||
bool is_64 = (buf[EI_CLASS] == ELFCLASS64);
|
||||
|
||||
auto *ehdr_le = (ElfEhdr<I386> *)buf;
|
||||
auto *ehdr_be = (ElfEhdr<M68K> *)buf;
|
||||
auto *ehdr64_le = (ElfEhdr<ARM64LE> *)buf;
|
||||
auto *ehdr64_be = (ElfEhdr<ARM64BE> *)buf;
|
||||
|
||||
switch (is_le ? ehdr_le->e_machine : ehdr_be->e_machine) {
|
||||
switch (is_le ? ehdr64_le->e_machine : ehdr64_be->e_machine) {
|
||||
case EM_386:
|
||||
return I386::name;
|
||||
case EM_X86_64:
|
||||
@@ -152,7 +157,18 @@ static std::string_view get_elf_type(u8 *buf) {
|
||||
case EM_PPC:
|
||||
return PPC32::name;
|
||||
case EM_PPC64:
|
||||
return is_le ? PPC64V2::name : PPC64V1::name;
|
||||
// ELFv1 is big-endian and ELFv2 is little-endian by convention, but
|
||||
// the correspondence is not a rule; musl for example uses ELFv2 on
|
||||
// big-endian too. We support only the usual combinations, so treat
|
||||
// the others as unrecognizable rather than silently linking them
|
||||
// against the wrong ABI.
|
||||
if (!is_le)
|
||||
if (u32 abi = (ehdr64_be->e_flags & EF_PPC64_ABI); abi == 0 || abi == 1)
|
||||
return PPC64V1::name;
|
||||
if (is_le)
|
||||
if (u32 abi = (ehdr64_le->e_flags & EF_PPC64_ABI); abi == 0 || abi == 2)
|
||||
return PPC64V2::name;
|
||||
return "";
|
||||
case EM_S390X:
|
||||
return S390X::name;
|
||||
case EM_SPARC64:
|
||||
|
||||
+74
-35
@@ -15,8 +15,10 @@ template <typename E>
|
||||
static bool should_keep(const InputSection<E> &isec) {
|
||||
u32 type = isec.shdr().sh_type;
|
||||
u32 flags = isec.shdr().sh_flags;
|
||||
std::string_view name = isec.name();
|
||||
|
||||
if constexpr (is_ppc32<E>)
|
||||
if (isec.name == ".got2")
|
||||
if (name == ".got2")
|
||||
return true;
|
||||
|
||||
return (flags & SHF_GNU_RETAIN) ||
|
||||
@@ -24,10 +26,10 @@ static bool should_keep(const InputSection<E> &isec) {
|
||||
type == SHT_INIT_ARRAY ||
|
||||
type == SHT_FINI_ARRAY ||
|
||||
type == SHT_PREINIT_ARRAY ||
|
||||
isec.name.starts_with(".ctors") ||
|
||||
isec.name.starts_with(".dtors") ||
|
||||
isec.name.starts_with(".init") ||
|
||||
isec.name.starts_with(".fini");
|
||||
name.starts_with(".ctors") ||
|
||||
name.starts_with(".dtors") ||
|
||||
name.starts_with(".init") ||
|
||||
name.starts_with(".fini");
|
||||
}
|
||||
|
||||
// Sections whose names are valid C identifiers can be referenced via
|
||||
@@ -37,34 +39,36 @@ static bool should_keep(const InputSection<E> &isec) {
|
||||
// of a given name when we encounter such a reference during marking.
|
||||
template <typename E>
|
||||
using StartStopMap =
|
||||
tbb::concurrent_unordered_multimap<std::string_view, InputSection<E> *>;
|
||||
tbb::concurrent_unordered_map<std::string_view,
|
||||
tbb::concurrent_vector<InputSection<E> *>>;
|
||||
|
||||
template <typename E>
|
||||
static StartStopMap<E> build_start_stop_map(Context<E> &ctx) {
|
||||
StartStopMap<E> map;
|
||||
tbb::parallel_for_each(ctx.objs, [&](ObjectFile<E> *file) {
|
||||
for (std::unique_ptr<InputSection<E>> &isec : file->sections)
|
||||
if (isec && isec->is_alive && (isec->shdr().sh_flags & SHF_ALLOC) &&
|
||||
is_c_identifier(isec->name))
|
||||
map.insert({isec->name, isec.get()});
|
||||
for (InputSection<E> *isec : file->sections)
|
||||
if (isec && isec->is_alive() && (isec->shdr().sh_flags & SHF_ALLOC))
|
||||
if (std::string_view name = isec->name();
|
||||
is_c_identifier(name))
|
||||
map[name].push_back(isec);
|
||||
});
|
||||
return map;
|
||||
}
|
||||
|
||||
template <typename E>
|
||||
static bool mark_section(InputSection<E> *isec) {
|
||||
return isec && isec->is_alive && !isec->is_visited.test_and_set();
|
||||
return isec && isec->is_alive() && isec->visit();
|
||||
}
|
||||
|
||||
template <typename E>
|
||||
static tbb::concurrent_vector<InputSection<E> *>
|
||||
static std::vector<InputSection<E> *>
|
||||
collect_root_set(Context<E> &ctx) {
|
||||
Timer t(ctx, "collect_root_set");
|
||||
tbb::concurrent_vector<InputSection<E> *> rootset;
|
||||
tbb::enumerable_thread_specific<std::vector<InputSection<E> *>> rootset;
|
||||
|
||||
auto enqueue_section = [&](InputSection<E> *isec) {
|
||||
if (mark_section(isec))
|
||||
rootset.push_back(isec);
|
||||
rootset.local().push_back(isec);
|
||||
};
|
||||
|
||||
auto enqueue_symbol = [&](Symbol<E> *sym) {
|
||||
@@ -78,8 +82,8 @@ collect_root_set(Context<E> &ctx) {
|
||||
|
||||
// Add sections that are not subject to garbage collection.
|
||||
tbb::parallel_for_each(ctx.objs, [&](ObjectFile<E> *file) {
|
||||
for (std::unique_ptr<InputSection<E>> &isec : file->sections) {
|
||||
if (!isec || !isec->is_alive)
|
||||
for (InputSection<E> *isec : file->sections) {
|
||||
if (!isec || !isec->is_alive())
|
||||
continue;
|
||||
|
||||
// --gc-sections discards only SHF_ALLOC sections. If you want to
|
||||
@@ -87,12 +91,12 @@ collect_root_set(Context<E> &ctx) {
|
||||
// use `strip` command, compile without debug info or use
|
||||
// --strip-all linker option.
|
||||
if (!(isec->shdr().sh_flags & SHF_ALLOC)) {
|
||||
isec->is_visited = true;
|
||||
isec->set_visited();
|
||||
continue;
|
||||
}
|
||||
|
||||
if (should_keep(*isec))
|
||||
enqueue_section(isec.get());
|
||||
enqueue_section(isec);
|
||||
}
|
||||
});
|
||||
|
||||
@@ -112,7 +116,10 @@ collect_root_set(Context<E> &ctx) {
|
||||
enqueue_symbol(file->symbols[rel.r_sym]);
|
||||
});
|
||||
|
||||
return rootset;
|
||||
std::vector<std::vector<InputSection<E> *>> vec;
|
||||
for (std::vector<InputSection<E> *> &v : rootset)
|
||||
vec.push_back(std::move(v));
|
||||
return flatten(vec);
|
||||
}
|
||||
|
||||
static std::string_view start_stop_name(std::string_view sym) {
|
||||
@@ -127,7 +134,7 @@ template <typename E>
|
||||
static void visit_section(Context<E> &ctx, InputSection<E> *isec,
|
||||
tbb::feeder<InputSection<E> *> &feeder, i64 depth,
|
||||
const StartStopMap<E> &start_stop_map) {
|
||||
assert(isec->is_visited);
|
||||
assert(isec->is_visited());
|
||||
|
||||
// Mark a section alive. For better performacne, we don't call
|
||||
// `feeder.add` too often.
|
||||
@@ -144,13 +151,19 @@ static void visit_section(Context<E> &ctx, InputSection<E> *isec,
|
||||
// describing how to handle exceptions for that function.
|
||||
// We want to keep associated .eh_frame records.
|
||||
for (FdeRecord<E> &fde : isec->get_fdes())
|
||||
for (const ElfRel<E> &rel : fde.get_rels(isec->file).subspan(1))
|
||||
if (Symbol<E> *sym = isec->file.symbols[rel.r_sym])
|
||||
for (const ElfRel<E> &rel : fde.get_rels(*isec->file).subspan(1))
|
||||
if (Symbol<E> *sym = isec->file->symbols[rel.r_sym])
|
||||
mark(sym->get_input_section());
|
||||
|
||||
for (const ElfRel<E> &rel : isec->get_rels(ctx)) {
|
||||
// Symbol can refer to either a section fragment or an input section.
|
||||
Symbol<E> &sym = *isec->file.symbols[rel.r_sym];
|
||||
Symbol<E> &sym = *isec->file->symbols[rel.r_sym];
|
||||
|
||||
if (sym.file && sym.file->is_dso) {
|
||||
sym.file->is_reachable.test_and_set();
|
||||
continue;
|
||||
}
|
||||
|
||||
if (SectionFragment<E> *frag = sym.get_frag()) {
|
||||
frag->is_alive = true;
|
||||
continue;
|
||||
@@ -158,13 +171,24 @@ static void visit_section(Context<E> &ctx, InputSection<E> *isec,
|
||||
|
||||
mark(sym.get_input_section());
|
||||
|
||||
// A reference to __start_<name> or __stop_<name> keeps every section
|
||||
// named <name> alive, mirroring how those symbols are defined.
|
||||
if (std::string_view sec = start_stop_name(sym.name());
|
||||
!sec.empty()) {
|
||||
auto [i, end] = start_stop_map.equal_range(sec);
|
||||
for (; i != end; ++i)
|
||||
mark(i->second);
|
||||
// A reference to __start_<name> or __stop_<name> keeps every
|
||||
// section named <name> alive, mirroring how those symbols are
|
||||
// defined. A single such reference can keep an enormous number of
|
||||
// sections alive, so we spread the fanout over threads instead
|
||||
// of marking the sections one by one.
|
||||
if (std::string_view name = start_stop_name(sym.name());
|
||||
!name.empty()) {
|
||||
if (auto it = start_stop_map.find(name);
|
||||
it != start_stop_map.end()) {
|
||||
// Mark and visit the sections with a nested parallel loop.
|
||||
// As in mark() below, a section added to a feeder has
|
||||
// already been marked, so a feeder's loop body must visit
|
||||
// it unconditionally.
|
||||
tbb::parallel_for_each(it->second, [&](InputSection<E> *isec) {
|
||||
if (mark_section(isec))
|
||||
visit_section(ctx, isec, feeder, 0, start_stop_map);
|
||||
});
|
||||
}
|
||||
}
|
||||
}
|
||||
|
||||
@@ -175,7 +199,7 @@ static void visit_section(Context<E> &ctx, InputSection<E> *isec,
|
||||
// Mark all reachable sections
|
||||
template <typename E>
|
||||
static void mark(Context<E> &ctx,
|
||||
tbb::concurrent_vector<InputSection<E> *> &rootset,
|
||||
std::vector<InputSection<E> *> &rootset,
|
||||
const StartStopMap<E> &start_stop_map) {
|
||||
Timer t(ctx, "mark");
|
||||
|
||||
@@ -195,10 +219,10 @@ static void sweep(Context<E> &ctx) {
|
||||
tbb::parallel_for((i64)0, (i64)ctx.objs.size(), [&](i64 i) {
|
||||
ObjectFile<E> &file = *ctx.objs[i];
|
||||
|
||||
for (std::unique_ptr<InputSection<E>> &isec : file.sections) {
|
||||
if (isec && isec->is_alive && !isec->is_visited) {
|
||||
for (InputSection<E> *isec : file.sections) {
|
||||
if (isec && isec->is_alive() && !isec->is_visited()) {
|
||||
isec->kill();
|
||||
sections[i].push_back(isec.get());
|
||||
sections[i].push_back(isec);
|
||||
}
|
||||
}
|
||||
});
|
||||
@@ -229,10 +253,25 @@ static void sweep(Context<E> &ctx) {
|
||||
template <typename E>
|
||||
void gc_sections(Context<E> &ctx) {
|
||||
Timer t(ctx, "gc");
|
||||
tbb::concurrent_vector<InputSection<E> *> rootset = collect_root_set(ctx);
|
||||
|
||||
for (SharedFile<E> *file : ctx.dsos)
|
||||
if (file->as_needed)
|
||||
file->is_reachable = false;
|
||||
|
||||
for (Symbol<E> *sym : ctx.arg.undefined)
|
||||
if (sym->file && sym->file->is_dso)
|
||||
sym->file->is_reachable = true;
|
||||
|
||||
for (Symbol<E> *sym : ctx.arg.require_defined)
|
||||
if (sym->file && sym->file->is_dso)
|
||||
sym->file->is_reachable = true;
|
||||
|
||||
std::vector<InputSection<E> *> rootset = collect_root_set(ctx);
|
||||
StartStopMap<E> start_stop_map = build_start_stop_map(ctx);
|
||||
mark(ctx, rootset, start_stop_map);
|
||||
sweep(ctx);
|
||||
|
||||
std::erase_if(ctx.dsos, [](SharedFile<E> *file) { return !file->is_reachable; });
|
||||
}
|
||||
|
||||
using E = MOLD_TARGET;
|
||||
|
||||
+684
-317
File diff suppressed because it is too large.
Load diff
+293
-318
@@ -67,8 +67,6 @@
|
||||
#include "mold.h"
|
||||
#include "../lib/siphash.h"
|
||||
|
||||
#include <array>
|
||||
#include <cstdio>
|
||||
#include <fstream>
|
||||
#include <tbb/concurrent_unordered_map.h>
|
||||
#include <tbb/concurrent_vector.h>
|
||||
@@ -77,24 +75,14 @@
|
||||
#include <tbb/parallel_for_each.h>
|
||||
#include <tbb/parallel_sort.h>
|
||||
|
||||
static constexpr int64_t HASH_SIZE = 16;
|
||||
|
||||
using Digest = std::array<uint8_t, HASH_SIZE>;
|
||||
|
||||
namespace std {
|
||||
template <> struct hash<Digest> {
|
||||
size_t operator()(const Digest &k) const {
|
||||
static_assert(sizeof(size_t) <= HASH_SIZE);
|
||||
size_t val;
|
||||
memcpy(&val, k.data(), sizeof(size_t));
|
||||
return val;
|
||||
}
|
||||
};
|
||||
}
|
||||
|
||||
namespace mold {
|
||||
|
||||
static u8 hmac_key[16];
|
||||
struct Digest {
|
||||
u64 hi;
|
||||
u64 lo;
|
||||
};
|
||||
|
||||
static u8 siphash_key[16];
|
||||
|
||||
template <typename E>
|
||||
static void uniquify_cies(Context<E> &ctx) {
|
||||
@@ -123,125 +111,32 @@ static void uniquify_cies(Context<E> &ctx) {
|
||||
template <typename E>
|
||||
static bool is_eligible(Context<E> &ctx, InputSection<E> &isec) {
|
||||
const ElfShdr<E> &shdr = isec.shdr();
|
||||
std::string_view name = isec.name();
|
||||
|
||||
if (shdr.sh_size == 0 || !(shdr.sh_flags & SHF_ALLOC) ||
|
||||
shdr.sh_type == SHT_NOBITS || is_c_identifier(isec.name))
|
||||
shdr.sh_type == SHT_NOBITS || is_c_identifier(name))
|
||||
return false;
|
||||
|
||||
if (shdr.sh_flags & SHF_EXECINSTR)
|
||||
return (ctx.arg.icf_all || !isec.address_taken) &&
|
||||
isec.name != ".init" && isec.name != ".fini";
|
||||
return (ctx.arg.icf_all || !isec.is_address_taken()) &&
|
||||
name != ".init" && name != ".fini";
|
||||
|
||||
// .gcc_except_table contains a compiler-generated table. Pointer
|
||||
// equality for the section is not significant because only the C++
|
||||
// exception handling code will use the table at runtime.
|
||||
if (isec.name == ".gcc_except_table" ||
|
||||
isec.name.starts_with(".gcc_except_table."))
|
||||
if (name == ".gcc_except_table" ||
|
||||
name.starts_with(".gcc_except_table."))
|
||||
return true;
|
||||
|
||||
bool is_readonly = !(shdr.sh_flags & SHF_WRITE);
|
||||
bool is_relro = isec.name.starts_with(".data.rel.ro");
|
||||
return (ctx.arg.ignore_data_address_equality || !isec.address_taken) &&
|
||||
bool is_relro = name.starts_with(".data.rel.ro");
|
||||
return (ctx.arg.ignore_data_address_equality || !isec.is_address_taken()) &&
|
||||
(is_readonly || is_relro);
|
||||
}
|
||||
|
||||
template <typename E>
|
||||
static bool is_leaf(Context<E> &ctx, InputSection<E> &isec) {
|
||||
if (!isec.get_rels(ctx).empty())
|
||||
return false;
|
||||
|
||||
for (FdeRecord<E> &fde : isec.get_fdes())
|
||||
if (fde.get_rels(isec.file).size() > 1)
|
||||
return false;
|
||||
|
||||
return true;
|
||||
}
|
||||
|
||||
template <typename E>
|
||||
struct LeafHasher {
|
||||
size_t operator()(InputSection<E> *isec) const {
|
||||
u64 h = hash_string(isec->contents);
|
||||
for (FdeRecord<E> &fde : isec->get_fdes()) {
|
||||
u64 h2 = hash_string(fde.get_contents(isec->file).substr(8));
|
||||
h = combine_hash(h, h2);
|
||||
}
|
||||
return h;
|
||||
}
|
||||
};
|
||||
|
||||
template <typename E>
|
||||
struct LeafEq {
|
||||
bool operator()(InputSection<E> *a, InputSection<E> *b) const {
|
||||
if (a->contents != b->contents)
|
||||
return false;
|
||||
|
||||
std::span<FdeRecord<E>> x = a->get_fdes();
|
||||
std::span<FdeRecord<E>> y = b->get_fdes();
|
||||
|
||||
if (x.size() != y.size())
|
||||
return false;
|
||||
|
||||
for (i64 i = 0; i < x.size(); i++)
|
||||
if (x[i].get_contents(a->file).substr(8) !=
|
||||
y[i].get_contents(b->file).substr(8))
|
||||
return false;
|
||||
return true;
|
||||
}
|
||||
};
|
||||
|
||||
// Early merge of leaf nodes, which can be processed without constructing the
|
||||
// entire graph. This reduces the vertex count and improves memory efficiency.
|
||||
template <typename E>
|
||||
static void merge_leaf_nodes(Context<E> &ctx) {
|
||||
Timer t(ctx, "merge_leaf_nodes");
|
||||
|
||||
static Counter eligible("icf_eligibles");
|
||||
static Counter non_eligible("icf_non_eligibles");
|
||||
static Counter leaf("icf_leaf_nodes");
|
||||
|
||||
tbb::concurrent_unordered_map<InputSection<E> *, Atomic<InputSection<E> *>,
|
||||
LeafHasher<E>, LeafEq<E>> map;
|
||||
|
||||
tbb::parallel_for((i64)0, (i64)ctx.objs.size(), [&](i64 i) {
|
||||
for (std::unique_ptr<InputSection<E>> &isec : ctx.objs[i]->sections) {
|
||||
if (!isec || !isec->is_alive)
|
||||
continue;
|
||||
|
||||
if (!is_eligible(ctx, *isec)) {
|
||||
non_eligible++;
|
||||
continue;
|
||||
}
|
||||
|
||||
if (is_leaf(ctx, *isec)) {
|
||||
leaf++;
|
||||
isec->icf_leaf = true;
|
||||
auto [it, inserted] = map.insert({isec.get(), isec.get()});
|
||||
if (!inserted) {
|
||||
InputSection<E> *isec2 = it->second.load();
|
||||
while (isec->get_priority() < isec2->get_priority() &&
|
||||
!it->second.compare_exchange_strong(isec2, isec.get()));
|
||||
}
|
||||
} else {
|
||||
eligible++;
|
||||
isec->icf_eligible = true;
|
||||
}
|
||||
}
|
||||
});
|
||||
|
||||
tbb::parallel_for((i64)0, (i64)ctx.objs.size(), [&](i64 i) {
|
||||
for (std::unique_ptr<InputSection<E>> &isec : ctx.objs[i]->sections) {
|
||||
if (isec && isec->is_alive && isec->icf_leaf) {
|
||||
auto it = map.find(isec.get());
|
||||
assert(it != map.end());
|
||||
isec->leader = it->second;
|
||||
}
|
||||
}
|
||||
});
|
||||
}
|
||||
|
||||
template <typename E>
|
||||
static Digest compute_digest(Context<E> &ctx, InputSection<E> &isec) {
|
||||
SipHash13_128 hasher(hmac_key);
|
||||
SipHash13_128 hasher(siphash_key);
|
||||
|
||||
auto hash = [&](auto val) {
|
||||
hasher.update((u8 *)&val, sizeof(val));
|
||||
@@ -263,83 +158,207 @@ static Digest compute_digest(Context<E> &ctx, InputSection<E> &isec) {
|
||||
hash((u64)frag);
|
||||
} else if (!isec) {
|
||||
hash('3');
|
||||
} else if (isec->leader) {
|
||||
} else if (isec->icf_idx != -1) {
|
||||
hash('4');
|
||||
hash((u64)isec->leader);
|
||||
} else if (isec->icf_eligible) {
|
||||
hash('5');
|
||||
} else {
|
||||
hash('6');
|
||||
hash('5');
|
||||
hash((u64)isec);
|
||||
}
|
||||
hash(sym.value);
|
||||
};
|
||||
|
||||
hash_string(isec.contents);
|
||||
hash_string(isec.get_contents());
|
||||
hash(isec.shdr().sh_flags);
|
||||
hash(isec.get_fdes().size());
|
||||
std::span<FdeRecord<E>> fdes = isec.get_fdes();
|
||||
hash(fdes.size());
|
||||
hash(isec.get_rels(ctx).size());
|
||||
|
||||
for (FdeRecord<E> &fde : isec.get_fdes()) {
|
||||
hash(isec.file.cies[fde.cie_idx].icf_idx);
|
||||
for (FdeRecord<E> &fde : fdes) {
|
||||
hash(isec.file->cies[fde.cie_idx].icf_idx);
|
||||
|
||||
// Bytes 0 to 4 contain the length of this record, and
|
||||
// bytes 4 to 8 contain an offset to CIE.
|
||||
hash_string(fde.get_contents(isec.file).substr(8));
|
||||
hash_string(fde.get_contents(*isec.file).substr(8));
|
||||
|
||||
hash(fde.get_rels(isec.file).size());
|
||||
hash(fde.get_rels(*isec.file).size());
|
||||
|
||||
for (const ElfRel<E> &rel : fde.get_rels(isec.file).subspan(1)) {
|
||||
hash_symbol(*isec.file.symbols[rel.r_sym]);
|
||||
for (const ElfRel<E> &rel : fde.get_rels(*isec.file).subspan(1)) {
|
||||
hash_symbol(*isec.file->symbols[rel.r_sym]);
|
||||
hash(rel.r_type);
|
||||
hash(rel.r_offset - fde.input_offset);
|
||||
hash(get_addend(isec.file.cies[fde.cie_idx].input_section, rel));
|
||||
hash(get_addend(isec.file->cies[fde.cie_idx].input_section, rel));
|
||||
}
|
||||
}
|
||||
|
||||
for (i64 i = 0; i < isec.get_rels(ctx).size(); i++) {
|
||||
const ElfRel<E> &rel = isec.get_rels(ctx)[i];
|
||||
for (const ElfRel<E> &rel : isec.get_rels(ctx)) {
|
||||
hash(rel.r_offset);
|
||||
hash(rel.r_type);
|
||||
hash(get_addend(isec, rel));
|
||||
hash_symbol(*isec.file.symbols[rel.r_sym]);
|
||||
hash_symbol(*isec.file->symbols[rel.r_sym]);
|
||||
}
|
||||
|
||||
Digest digest;
|
||||
hasher.finish(digest.data());
|
||||
hasher.finish(&digest);
|
||||
return digest;
|
||||
}
|
||||
|
||||
// A concurrent hash map from digest to section. We use it to count the
|
||||
// number of distinct digests and to elect the leader section of each
|
||||
// digest's equivalence class.
|
||||
//
|
||||
// The number of distinct digests cannot exceed the number of digests,
|
||||
// so we can allocate a large enough table upfront and never need to
|
||||
// grow it.
|
||||
//
|
||||
// The map is reused across propagation rounds. Instead of clearing the
|
||||
// table at the start of each round, we stamp each slot with the round
|
||||
// number in which it was written; a slot stamped with an earlier round
|
||||
// is treated as vacant.
|
||||
//
|
||||
// Each slot consists of two 64-bit words and a section pointer. The
|
||||
// first word packs the round number, a busy bit, and 48 bits of the
|
||||
// digest; the second word holds another 64 bits. An inserter claims a
|
||||
// vacant slot by installing the first word with compare-and-swap with
|
||||
// the busy bit set, writes the second word and the pointer, and then
|
||||
// rewrites the first word with the busy bit cleared to publish the
|
||||
// slot. Since the slot index is derived from digest bits that the
|
||||
// first word doesn't contain, a successful match effectively compares
|
||||
// an entire 128-bit digest, so the map is exact under the same
|
||||
// hash-collision assumption the surrounding algorithm is built on.
|
||||
//
|
||||
// Of all sections inserted with the same digest in the same round, the
|
||||
// slot ends up pointing to the one with the lowest priority, which ICF
|
||||
// uses as the leader of the digest's equivalence class.
|
||||
template <typename E>
|
||||
class DigestMap {
|
||||
public:
|
||||
DigestMap(i64 n) :
|
||||
mask(bit_ceil(n * 2) - 1),
|
||||
slots(mask + 1) {}
|
||||
|
||||
void next_round() {
|
||||
if (++round == 1 << 15) {
|
||||
// The round number wrapped around, making stale slot stamps
|
||||
// ambiguous, so reset the table. In practice, ICF converges long
|
||||
// before this point.
|
||||
for (Slot &slot : slots)
|
||||
slot.hi = 0;
|
||||
round = 1;
|
||||
}
|
||||
}
|
||||
|
||||
// Returns true if the digest was not in the table.
|
||||
bool insert(const Digest &digest, InputSection<E> *isec) {
|
||||
constexpr u64 busy_bit = 1LL << 48;
|
||||
u64 tag = digest.hi >> 16;
|
||||
u64 value = (round << 49) | tag;
|
||||
|
||||
for (i64 i = digest.hi & mask;; i = (i + 1) & mask) {
|
||||
Slot &slot = slots[i];
|
||||
u64 x = slot.hi.load(std::memory_order_acquire);
|
||||
|
||||
// If the slot was last written in an earlier round, it's vacant;
|
||||
// try to claim it.
|
||||
while ((x >> 49) != round) {
|
||||
if (slot.hi.compare_exchange_weak(x, value | busy_bit,
|
||||
std::memory_order_acquire)) {
|
||||
slot.lo = digest.lo;
|
||||
slot.leader = isec;
|
||||
slot.hi.store(value, std::memory_order_release);
|
||||
return true;
|
||||
}
|
||||
}
|
||||
|
||||
// The slot is occupied. If it holds a different digest, try the
|
||||
// next slot.
|
||||
if ((x & 0xffff'ffff'ffff) != tag)
|
||||
continue;
|
||||
|
||||
// The tags match; compare the digest bits in the second word,
|
||||
// waiting for the writer to publish them if the slot is still
|
||||
// being claimed.
|
||||
while (x & busy_bit)
|
||||
x = slot.hi.load(std::memory_order_acquire);
|
||||
if (slot.lo != digest.lo)
|
||||
continue;
|
||||
|
||||
// The digest is already in the table; keep the slot pointing to
|
||||
// the lowest-priority section.
|
||||
InputSection<E> *cur = slot.leader;
|
||||
while (isec->get_priority() < cur->get_priority() &&
|
||||
!slot.leader.compare_exchange_strong(cur, isec));
|
||||
return false;
|
||||
}
|
||||
}
|
||||
|
||||
// Returns the section associated with a digest. The digest must have
|
||||
// been inserted in the current round, and no insertion may be running
|
||||
// concurrently.
|
||||
InputSection<E> *find(const Digest &digest) {
|
||||
u64 value = (round << 49) | (digest.hi >> 16);
|
||||
for (i64 i = digest.hi & mask;; i = (i + 1) & mask)
|
||||
if (slots[i].hi == value && slots[i].lo == digest.lo)
|
||||
return slots[i].leader;
|
||||
}
|
||||
|
||||
private:
|
||||
struct Slot {
|
||||
Atomic<u64> hi;
|
||||
Atomic<u64> lo;
|
||||
Atomic<InputSection<E> *> leader;
|
||||
};
|
||||
|
||||
// Time begins in round 1 so that all-zero slots, the initial state
|
||||
// of the table, read as vacant.
|
||||
u64 round = 1;
|
||||
u64 mask;
|
||||
std::vector<Slot> slots;
|
||||
};
|
||||
|
||||
template <typename E>
|
||||
static std::vector<InputSection<E> *> gather_sections(Context<E> &ctx) {
|
||||
Timer t(ctx, "gather_sections");
|
||||
|
||||
// Count the number of input sections for each input file.
|
||||
std::vector<i64> num_sections(ctx.objs.size());
|
||||
static Counter eligible("icf_eligibles");
|
||||
static Counter non_eligible("icf_non_eligibles");
|
||||
|
||||
// Count the number of eligible input sections for each input file
|
||||
// and turn the counts into starting indices with a prefix sum.
|
||||
std::vector<i64> indices(ctx.objs.size() + 1);
|
||||
|
||||
tbb::parallel_for((i64)0, (i64)ctx.objs.size(), [&](i64 i) {
|
||||
for (std::unique_ptr<InputSection<E>> &isec : ctx.objs[i]->sections)
|
||||
if (isec && isec->is_alive && isec->icf_eligible)
|
||||
num_sections[i]++;
|
||||
for (InputSection<E> *isec : ctx.objs[i]->sections) {
|
||||
if (!isec)
|
||||
continue;
|
||||
|
||||
assert(isec->icf_idx == -1);
|
||||
if (!isec->is_alive())
|
||||
continue;
|
||||
|
||||
if (is_eligible(ctx, *isec)) {
|
||||
eligible++;
|
||||
isec->icf_idx = 0;
|
||||
indices[i + 1]++;
|
||||
} else {
|
||||
non_eligible++;
|
||||
}
|
||||
}
|
||||
});
|
||||
|
||||
std::vector<i64> section_indices(ctx.objs.size());
|
||||
for (i64 i = 0; i < ctx.objs.size() - 1; i++)
|
||||
section_indices[i + 1] = section_indices[i] + num_sections[i];
|
||||
for (i64 i = 1; i < indices.size(); i++)
|
||||
indices[i] += indices[i - 1];
|
||||
|
||||
std::vector<InputSection<E> *> sections(
|
||||
section_indices.back() + num_sections.back());
|
||||
std::vector<InputSection<E> *> sections(indices.back());
|
||||
|
||||
// Fill `sections` contents.
|
||||
tbb::parallel_for((i64)0, (i64)ctx.objs.size(), [&](i64 i) {
|
||||
i64 idx = section_indices[i];
|
||||
for (std::unique_ptr<InputSection<E>> &isec : ctx.objs[i]->sections)
|
||||
if (isec && isec->is_alive && isec->icf_eligible)
|
||||
sections[idx++] = isec.get();
|
||||
});
|
||||
|
||||
tbb::parallel_for((i64)0, (i64)sections.size(), [&](i64 i) {
|
||||
sections[i]->icf_idx = i;
|
||||
i64 idx = indices[i];
|
||||
for (InputSection<E> *isec : ctx.objs[i]->sections) {
|
||||
if (isec && isec->icf_idx != -1) {
|
||||
isec->icf_idx = idx;
|
||||
sections[idx++] = isec;
|
||||
}
|
||||
}
|
||||
});
|
||||
|
||||
return sections;
|
||||
@@ -360,6 +379,13 @@ compute_digests(Context<E> &ctx, std::span<InputSection<E> *> sections) {
|
||||
// Build a graph, treating every function as a vertex and every function call
|
||||
// as an edge. See the description at the top for a more detailed formulation.
|
||||
// We use u32 indices here to improve cache locality.
|
||||
//
|
||||
// Relocations in a section's FDEs are edges too, because compute_digest
|
||||
// hashes eligible relocation targets without identity, and every such
|
||||
// target must be represented as an edge to remain distinguishable. In
|
||||
// particular, an FDE's reference to an LSDA is an edge; without it, two
|
||||
// identical functions whose exception tables catch different types would
|
||||
// be folded into one.
|
||||
template <typename E>
|
||||
static void gather_edges(Context<E> &ctx,
|
||||
std::span<InputSection<E> *> sections,
|
||||
@@ -367,114 +393,104 @@ static void gather_edges(Context<E> &ctx,
|
||||
std::vector<u32> &edge_indices) {
|
||||
Timer t(ctx, "gather_edges");
|
||||
|
||||
if (sections.empty())
|
||||
return;
|
||||
|
||||
std::vector<i64> num_edges(sections.size());
|
||||
edge_indices.resize(sections.size());
|
||||
// Count the number of outgoing edges for each vertex and turn the
|
||||
// counts into starting indices with a prefix sum. The extra entry at
|
||||
// the end makes edge_indices[i + 1] valid for every vertex, so that
|
||||
// vertex i's edges are edge_indices[i] to edge_indices[i + 1].
|
||||
edge_indices.resize(sections.size() + 1);
|
||||
|
||||
tbb::parallel_for((i64)0, (i64)sections.size(), [&](i64 i) {
|
||||
InputSection<E> &isec = *sections[i];
|
||||
assert(isec.icf_eligible);
|
||||
assert(isec.icf_idx != -1);
|
||||
|
||||
for (i64 j = 0; j < isec.get_rels(ctx).size(); j++) {
|
||||
const ElfRel<E> &rel = isec.get_rels(ctx)[j];
|
||||
Symbol<E> &sym = *isec.file.symbols[rel.r_sym];
|
||||
if (!sym.get_frag())
|
||||
if (InputSection<E> *isec = sym.get_input_section())
|
||||
if (isec->icf_eligible)
|
||||
num_edges[i]++;
|
||||
}
|
||||
for (FdeRecord<E> &fde : isec.get_fdes())
|
||||
for (const ElfRel<E> &rel : fde.get_rels(*isec.file).subspan(1))
|
||||
if (Symbol<E> &sym = *isec.file->symbols[rel.r_sym];
|
||||
InputSection<E> *isec = sym.get_input_section())
|
||||
if (isec->icf_idx != -1)
|
||||
edge_indices[i + 1]++;
|
||||
|
||||
for (const ElfRel<E> &rel : isec.get_rels(ctx))
|
||||
if (Symbol<E> &sym = *isec.file->symbols[rel.r_sym];
|
||||
InputSection<E> *isec = sym.get_input_section())
|
||||
if (isec->icf_idx != -1)
|
||||
edge_indices[i + 1]++;
|
||||
});
|
||||
|
||||
for (i64 i = 0; i < num_edges.size() - 1; i++)
|
||||
edge_indices[i + 1] = edge_indices[i] + num_edges[i];
|
||||
for (i64 i = 1; i < edge_indices.size(); i++)
|
||||
edge_indices[i] += edge_indices[i - 1];
|
||||
|
||||
edges.resize(edge_indices.back() + num_edges.back());
|
||||
edges.resize(edge_indices.back());
|
||||
|
||||
tbb::parallel_for((i64)0, (i64)num_edges.size(), [&](i64 i) {
|
||||
tbb::parallel_for((i64)0, (i64)sections.size(), [&](i64 i) {
|
||||
InputSection<E> &isec = *sections[i];
|
||||
i64 idx = edge_indices[i];
|
||||
|
||||
for (ElfRel<E> &rel : isec.get_rels(ctx)) {
|
||||
Symbol<E> &sym = *isec.file.symbols[rel.r_sym];
|
||||
if (InputSection<E> *isec = sym.get_input_section())
|
||||
if (isec->icf_eligible)
|
||||
for (FdeRecord<E> &fde : isec.get_fdes())
|
||||
for (const ElfRel<E> &rel : fde.get_rels(*isec.file).subspan(1))
|
||||
if (Symbol<E> &sym = *isec.file->symbols[rel.r_sym];
|
||||
InputSection<E> *isec = sym.get_input_section())
|
||||
if (isec->icf_idx != -1)
|
||||
edges[idx++] = isec->icf_idx;
|
||||
|
||||
for (const ElfRel<E> &rel : isec.get_rels(ctx))
|
||||
if (Symbol<E> &sym = *isec.file->symbols[rel.r_sym];
|
||||
InputSection<E> *isec = sym.get_input_section())
|
||||
if (isec->icf_idx != -1)
|
||||
edges[idx++] = isec->icf_idx;
|
||||
}
|
||||
});
|
||||
}
|
||||
|
||||
template <typename E>
|
||||
static i64 propagate(std::span<std::vector<Digest>> digests,
|
||||
std::span<u32> edges, std::span<u32> edge_indices,
|
||||
bool &slot, std::span<u8> converged,
|
||||
tbb::affinity_partitioner &ap) {
|
||||
static Counter round("icf_round");
|
||||
round++;
|
||||
|
||||
i64 num_digests = digests[0].size();
|
||||
tbb::enumerable_thread_specific<i64> changed;
|
||||
|
||||
tbb::parallel_for((i64)0, num_digests, [&](i64 i) {
|
||||
if (converged[i])
|
||||
return;
|
||||
|
||||
SipHash13_128 hasher(hmac_key);
|
||||
hasher.update(digests[2][i].data(), HASH_SIZE);
|
||||
// Compute the next-round digest of each vertex by hashing its current
|
||||
// digest and the current digests of the vertices it refers to. A
|
||||
// vertex's digest after the nth round is therefore a hash of its
|
||||
// unfolding into a tree of depth n.
|
||||
static void propagate(std::vector<Digest> &cur, std::vector<Digest> &next,
|
||||
std::span<u32> edges, std::span<u32> edge_indices) {
|
||||
tbb::parallel_for((i64)0, (i64)cur.size(), [&](i64 i) {
|
||||
SipHash13_128 hasher(siphash_key);
|
||||
hasher.update(&cur[i], sizeof(Digest));
|
||||
|
||||
i64 begin = edge_indices[i];
|
||||
i64 end = (i + 1 == num_digests) ? edges.size() : edge_indices[i + 1];
|
||||
|
||||
i64 end = edge_indices[i + 1];
|
||||
for (i64 j : edges.subspan(begin, end - begin))
|
||||
hasher.update(digests[slot][j].data(), HASH_SIZE);
|
||||
|
||||
hasher.finish(digests[!slot][i].data());
|
||||
|
||||
if (digests[slot][i] == digests[!slot][i]) {
|
||||
// This node has converged. Skip further iterations as it will
|
||||
// yield the same hash.
|
||||
converged[i] = true;
|
||||
} else {
|
||||
changed.local()++;
|
||||
}
|
||||
}, ap);
|
||||
|
||||
slot = !slot;
|
||||
return changed.combine(std::plus());
|
||||
hasher.update(&cur[j], sizeof(Digest));
|
||||
hasher.finish(&next[i]);
|
||||
});
|
||||
std::swap(cur, next);
|
||||
}
|
||||
|
||||
template <typename E>
|
||||
static i64 count_num_classes(std::span<Digest> digests,
|
||||
tbb::affinity_partitioner &ap) {
|
||||
std::vector<Digest> vec(digests.begin(), digests.end());
|
||||
tbb::parallel_sort(vec);
|
||||
std::span<InputSection<E> *> sections,
|
||||
DigestMap<E> &map) {
|
||||
map.next_round();
|
||||
|
||||
tbb::enumerable_thread_specific<i64> num_classes;
|
||||
tbb::parallel_for((i64)0, (i64)vec.size() - 1, [&](i64 i) {
|
||||
if (vec[i] != vec[i + 1])
|
||||
tbb::parallel_for((i64)0, (i64)digests.size(), [&](i64 i) {
|
||||
if (map.insert(digests[i], sections[i]))
|
||||
num_classes.local()++;
|
||||
}, ap);
|
||||
});
|
||||
|
||||
static Counter counter("icf_round");
|
||||
counter++;
|
||||
return num_classes.combine(std::plus());
|
||||
}
|
||||
|
||||
template <typename E>
|
||||
static void print_icf_sections(Context<E> &ctx) {
|
||||
tbb::concurrent_vector<InputSection<E> *> leaders;
|
||||
static void
|
||||
print_icf_sections(Context<E> &ctx, std::span<InputSection<E> *> sections) {
|
||||
tbb::concurrent_vector<InputSection<E> *> leader_sections;
|
||||
tbb::concurrent_unordered_multimap<InputSection<E> *, InputSection<E> *> map;
|
||||
|
||||
tbb::parallel_for_each(ctx.objs, [&](ObjectFile<E> *file) {
|
||||
for (std::unique_ptr<InputSection<E>> &isec : file->sections) {
|
||||
if (isec && isec->is_alive && isec->leader) {
|
||||
if (isec.get() == isec->leader)
|
||||
leaders.push_back(isec.get());
|
||||
else
|
||||
map.insert({isec->leader, isec.get()});
|
||||
}
|
||||
}
|
||||
tbb::parallel_for_each(sections, [&](InputSection<E> *isec) {
|
||||
if (isec == isec->icf_leader)
|
||||
leader_sections.push_back(isec);
|
||||
else
|
||||
map.insert({isec->icf_leader, isec});
|
||||
});
|
||||
|
||||
tbb::parallel_sort(leaders.begin(), leaders.end(),
|
||||
tbb::parallel_sort(leader_sections.begin(), leader_sections.end(),
|
||||
[](InputSection<E> *a, InputSection<E> *b) {
|
||||
return a->get_priority() < b->get_priority();
|
||||
});
|
||||
@@ -493,13 +509,13 @@ static void print_icf_sections(Context<E> &ctx) {
|
||||
|
||||
i64 saved_bytes = 0;
|
||||
|
||||
for (InputSection<E> *leader : leaders) {
|
||||
for (InputSection<E> *leader : leader_sections) {
|
||||
auto [begin, end] = map.equal_range(leader);
|
||||
if (begin != end) {
|
||||
*out << "selected section " << *leader << '\n';
|
||||
for (auto it = begin; it != end; it++) {
|
||||
*out << " removing identical section " << *it->second << '\n';
|
||||
saved_bytes += leader->contents.size();
|
||||
saved_bytes += leader->get_contents().size();
|
||||
}
|
||||
}
|
||||
}
|
||||
@@ -513,116 +529,74 @@ void icf_sections(Context<E> &ctx) {
|
||||
if (ctx.objs.empty())
|
||||
return;
|
||||
|
||||
get_random_bytes(hmac_key, sizeof(hmac_key));
|
||||
|
||||
get_random_bytes(siphash_key, sizeof(siphash_key));
|
||||
uniquify_cies(ctx);
|
||||
merge_leaf_nodes(ctx);
|
||||
|
||||
// Prepare for the propagation rounds.
|
||||
std::vector<InputSection<E> *> sections = gather_sections(ctx);
|
||||
|
||||
// We allocate 3 arrays to store hashes for each vertex.
|
||||
//
|
||||
// Index 0 and 1 are used for tree hashes from the previous
|
||||
// iteration and the current iteration. They switch roles every
|
||||
// iteration. See `slot` below.
|
||||
//
|
||||
// Index 2 stores the initial, single-vertex hash. This is combined
|
||||
// with hashes from the connected vertices to form the tree hash
|
||||
// described above.
|
||||
std::vector<std::vector<Digest>> digests(3);
|
||||
digests[0] = compute_digests<E>(ctx, sections);
|
||||
digests[1].resize(digests[0].size());
|
||||
digests[2] = digests[0];
|
||||
// `digests` holds the current digest of each vertex
|
||||
std::vector<Digest> digests = compute_digests<E>(ctx, sections);
|
||||
|
||||
std::vector<u32> edges;
|
||||
std::vector<u32> edge_indices;
|
||||
gather_edges<E>(ctx, sections, edges, edge_indices);
|
||||
|
||||
std::vector<u8> converged(digests[0].size());
|
||||
bool slot = 0;
|
||||
// The digest map is used to count the number of distinct digests in
|
||||
// the loop below. As a side effect, it records the lowest-priority
|
||||
// section for each digest, which the grouping step after the loop
|
||||
// uses as the leader of each equivalence class.
|
||||
DigestMap<E> map(digests.size());
|
||||
|
||||
// Execute the propagation rounds until convergence is obtained.
|
||||
//
|
||||
// The number of distinct digests can only monotonically increase as
|
||||
// the rounds hash ever-deeper trees, so once two consecutive rounds
|
||||
// yield the same count, the partition of sections into equivalence
|
||||
// classes has stopped changing and will remain unchanged for further
|
||||
// iterations (proof omitted for brevity). Note that individual
|
||||
// digests may well still be changing at that point; sections that
|
||||
// have a cycle in downstream (i.e. recursive functions and functions
|
||||
// that call them) never settle on a digest. That doesn't matter
|
||||
// because sections in the same class change their digests in
|
||||
// lockstep, keeping the partition intact.
|
||||
{
|
||||
Timer t(ctx, "propagate");
|
||||
tbb::affinity_partitioner ap;
|
||||
|
||||
// A cheap test that the graph hasn't converged yet.
|
||||
// The loop after this one uses a strict condition, but it's expensive
|
||||
// as it requires sorting the entire hash collection.
|
||||
//
|
||||
// For nodes that have a cycle in downstream (i.e. recursive
|
||||
// functions and functions that calls recursive functions) will always
|
||||
// change with the iterations. Nodes that doesn't (i.e. non-recursive
|
||||
// functions) will stop changing as soon as the propagation depth reaches
|
||||
// the call tree depth.
|
||||
// Here, we test whether we have reached sufficient depth for the latter,
|
||||
// which is a necessary (but not sufficient) condition for convergence.
|
||||
i64 num_changed = -1;
|
||||
for (;;) {
|
||||
i64 n = propagate<E>(digests, edges, edge_indices, slot, converged, ap);
|
||||
if (n == num_changed)
|
||||
break;
|
||||
num_changed = n;
|
||||
}
|
||||
|
||||
// Run the pass until the unique number of hashes stop increasing, at which
|
||||
// point we have achieved convergence (proof omitted for brevity).
|
||||
i64 num_classes = -1;
|
||||
for (;;) {
|
||||
// count_num_classes requires sorting which is O(n log n), so do a little
|
||||
// more work beforehand to amortize that log factor.
|
||||
for (i64 i = 0; i < 10; i++)
|
||||
propagate<E>(digests, edges, edge_indices, slot, converged, ap);
|
||||
std::vector<Digest> scratch(digests.size());
|
||||
|
||||
i64 n = count_num_classes<E>(digests[slot], ap);
|
||||
if (n == num_classes)
|
||||
for (;;) {
|
||||
// count_num_classes is as expensive as propagate, so we propagate
|
||||
// a few times before counting the number of distinct groups.
|
||||
propagate(digests, scratch, edges, edge_indices);
|
||||
propagate(digests, scratch, edges, edge_indices);
|
||||
propagate(digests, scratch, edges, edge_indices);
|
||||
|
||||
i64 m = count_num_classes<E>(digests, sections, map);
|
||||
if (m == num_classes)
|
||||
break;
|
||||
num_classes = n;
|
||||
num_classes = m;
|
||||
}
|
||||
}
|
||||
|
||||
// Group sections by hash values.
|
||||
// Group sections by digest. The final counting round has already
|
||||
// elected a leader for each digest; look it up.
|
||||
{
|
||||
Timer t(ctx, "group");
|
||||
|
||||
auto *map =
|
||||
new tbb::concurrent_unordered_map<Digest, Atomic<InputSection<E> *>>;
|
||||
|
||||
std::span<Digest> digest = digests[slot];
|
||||
|
||||
tbb::parallel_for((i64)0, (i64)sections.size(), [&](i64 i) {
|
||||
InputSection<E> *isec = sections[i];
|
||||
auto [it, inserted] = map->insert({digest[i], isec});
|
||||
if (!inserted) {
|
||||
InputSection<E> *isec2 = it->second.load();
|
||||
while (isec->get_priority() < isec2->get_priority() &&
|
||||
!it->second.compare_exchange_strong(isec2, isec));
|
||||
}
|
||||
sections[i]->icf_leader = map.find(digests[i]);
|
||||
});
|
||||
|
||||
tbb::parallel_for((i64)0, (i64)sections.size(), [&](i64 i) {
|
||||
auto it = map->find(digest[i]);
|
||||
assert(it != map->end());
|
||||
sections[i]->leader = it->second;
|
||||
});
|
||||
|
||||
// Since free'ing the map is slow, postpone it.
|
||||
ctx.on_exit.push_back([=] { delete map; });
|
||||
}
|
||||
|
||||
if (!ctx.arg.print_icf_sections.empty())
|
||||
print_icf_sections(ctx);
|
||||
print_icf_sections<E>(ctx, sections);
|
||||
|
||||
// Update alignment of leaders.
|
||||
{
|
||||
Timer t(ctx, "update_alignment");
|
||||
tbb::parallel_for_each(ctx.objs, [](ObjectFile<E> *file) {
|
||||
for (std::unique_ptr<InputSection<E>> &isec : file->sections) {
|
||||
if (isec && isec->is_alive && isec->leader && isec->leader != isec.get()) {
|
||||
update_maximum(isec->leader->p2align, isec->p2align);
|
||||
}
|
||||
}
|
||||
tbb::parallel_for_each(sections, [&](InputSection<E> *isec) {
|
||||
if (isec != isec->icf_leader)
|
||||
update_maximum(isec->icf_leader->p2align, isec->p2align);
|
||||
});
|
||||
}
|
||||
|
||||
@@ -632,12 +606,13 @@ void icf_sections(Context<E> &ctx) {
|
||||
{
|
||||
Timer t(ctx, "sweep");
|
||||
static Counter eliminated("icf_eliminated");
|
||||
tbb::parallel_for_each(ctx.objs, [](ObjectFile<E> *file) {
|
||||
for (std::unique_ptr<InputSection<E>> &isec : file->sections) {
|
||||
if (isec && isec->is_alive && isec->icf_removed()) {
|
||||
isec->kill();
|
||||
eliminated++;
|
||||
}
|
||||
tbb::parallel_for_each(sections, [&](InputSection<E> *isec) {
|
||||
if (isec != isec->icf_leader) {
|
||||
isec->set_icf_removed();
|
||||
isec->kill();
|
||||
eliminated++;
|
||||
} else {
|
||||
isec->offset = -1;
|
||||
}
|
||||
});
|
||||
}
|
||||
|
||||
+463
-254
File diff suppressed because it is too large.
Load diff
+108
-67
@@ -31,17 +31,20 @@ bool cie_equals(const CieRecord<E> &a, const CieRecord<E> &b) {
|
||||
}
|
||||
|
||||
template <typename E>
|
||||
InputSection<E>::InputSection(Context<E> &ctx, ObjectFile<E> &file, i64 shndx)
|
||||
: file(file), shndx(shndx) {
|
||||
InputSection<E>::InputSection(Context<E> &ctx, ObjectFile<E> &file, i64 shndx,
|
||||
std::string_view section_name)
|
||||
: file(&file), shndx(shndx) {
|
||||
if (shndx < file.elf_sections.size()) {
|
||||
name = file.shstrtab.data() + file.elf_sections[shndx].sh_name;
|
||||
contents = {(char *)file.mf->data + shdr().sh_offset, (size_t)shdr().sh_size};
|
||||
} else {
|
||||
name = (shdr().sh_flags & SHF_TLS) ? ".tls_common" : ".common";
|
||||
std::string_view name = section_name;
|
||||
if (name.empty())
|
||||
name = file.shstrtab.data() + file.elf_sections[shndx].sh_name;
|
||||
namelen = std::min<i64>(name.size(), UINT16_MAX);
|
||||
|
||||
contents = file.mf->data + shdr().sh_offset;
|
||||
}
|
||||
|
||||
if (shdr().sh_flags & SHF_COMPRESSED) {
|
||||
ElfChdr<E> &chdr = *(ElfChdr<E> *)&contents[0];
|
||||
ElfChdr<E> &chdr = *(ElfChdr<E> *)contents;
|
||||
sh_size = chdr.ch_size;
|
||||
p2align = to_p2align(chdr.ch_addralign);
|
||||
} else {
|
||||
@@ -63,28 +66,29 @@ InputSection<E>::InputSection(Context<E> &ctx, ObjectFile<E> &file, i64 shndx)
|
||||
|
||||
template <typename E>
|
||||
void InputSection<E>::uncompress(Context<E> &ctx) {
|
||||
if (!(shdr().sh_flags & SHF_COMPRESSED) || uncompressed)
|
||||
if (!(shdr().sh_flags & SHF_COMPRESSED) || is_uncompressed())
|
||||
return;
|
||||
|
||||
u8 *buf = new u8[sh_size];
|
||||
copy_contents_to(ctx, buf, sh_size);
|
||||
contents = std::string_view((char *)buf, sh_size);
|
||||
contents = buf;
|
||||
ctx.string_pool.emplace_back(buf);
|
||||
uncompressed = true;
|
||||
set_uncompressed();
|
||||
}
|
||||
|
||||
template <typename E>
|
||||
void InputSection<E>::copy_contents_to(Context<E> &ctx, u8 *buf, i64 sz) {
|
||||
if (!(shdr().sh_flags & SHF_COMPRESSED) || uncompressed) {
|
||||
memcpy(buf, contents.data(), sz);
|
||||
if (!(shdr().sh_flags & SHF_COMPRESSED) || is_uncompressed()) {
|
||||
memcpy(buf, contents, sz);
|
||||
return;
|
||||
}
|
||||
|
||||
if (contents.size() < sizeof(ElfChdr<E>))
|
||||
std::string_view view = get_contents();
|
||||
if (view.size() < sizeof(ElfChdr<E>))
|
||||
Fatal(ctx) << *this << ": corrupted compressed section";
|
||||
|
||||
ElfChdr<E> &hdr = *(ElfChdr<E> *)&contents[0];
|
||||
std::string_view data = contents.substr(sizeof(ElfChdr<E>));
|
||||
ElfChdr<E> &hdr = *(ElfChdr<E> *)contents;
|
||||
std::string_view data = view.substr(sizeof(ElfChdr<E>));
|
||||
|
||||
switch (hdr.ch_type) {
|
||||
case ELFCOMPRESS_ZLIB: {
|
||||
@@ -128,7 +132,7 @@ void InputSection<E>::copy_contents_to(Context<E> &ctx, u8 *buf, i64 sz) {
|
||||
// wingdi.h defines ERROR as a macro, so undefine it before use
|
||||
#undef ERROR
|
||||
|
||||
typedef enum : u8 { NONE, ERROR, COPYREL, PLT, CPLT } Action;
|
||||
typedef enum : u8 { NONE, ERROR, CANONICAL, PLT } Action;
|
||||
|
||||
template <typename E>
|
||||
static void do_action(Context<E> &ctx, Action action, InputSection<E> &isec,
|
||||
@@ -141,17 +145,13 @@ static void do_action(Context<E> &ctx, Action action, InputSection<E> &isec,
|
||||
<< std::hex << rel.r_offset << " against symbol `"
|
||||
<< sym << "' can not be used; recompile with -fPIC";
|
||||
break;
|
||||
case COPYREL:
|
||||
sym.flags |= NEEDS_COPYREL;
|
||||
case CANONICAL:
|
||||
sym.flags |= NEEDS_CANONICAL;
|
||||
break;
|
||||
case PLT:
|
||||
// Create a PLT entry
|
||||
sym.flags |= NEEDS_PLT;
|
||||
break;
|
||||
case CPLT:
|
||||
// Create a canonical PLT entry
|
||||
sym.flags |= NEEDS_CPLT;
|
||||
break;
|
||||
}
|
||||
}
|
||||
|
||||
@@ -183,9 +183,9 @@ void InputSection<E>::scan_pcrel(Context<E> &ctx, Symbol<E> &sym,
|
||||
// linker generally does not support PC-relative relocations.
|
||||
static Action table[][4] = {
|
||||
// Absolute Local Imported data Imported code
|
||||
{ ERROR, NONE, ERROR, PLT }, // Shared object
|
||||
{ ERROR, NONE, COPYREL, CPLT }, // Position-independent exec
|
||||
{ NONE, NONE, COPYREL, CPLT }, // Position-dependent exec
|
||||
{ ERROR, NONE, ERROR, PLT }, // Shared object
|
||||
{ ERROR, NONE, CANONICAL, CANONICAL }, // Position-independent exec
|
||||
{ NONE, NONE, CANONICAL, CANONICAL }, // Position-dependent exec
|
||||
};
|
||||
|
||||
Action action = table[get_output_type(ctx)][get_sym_type(sym)];
|
||||
@@ -202,9 +202,9 @@ void InputSection<E>::scan_absrel(Context<E> &ctx, Symbol<E> &sym,
|
||||
// resolved at link-time.
|
||||
static Action table[][4] = {
|
||||
// Absolute Local Imported data Imported code
|
||||
{ NONE, ERROR, ERROR, ERROR }, // Shared object
|
||||
{ NONE, ERROR, ERROR, ERROR }, // Position-independent exec
|
||||
{ NONE, NONE, COPYREL, CPLT }, // Position-dependent exec
|
||||
{ NONE, ERROR, ERROR, ERROR }, // Shared object
|
||||
{ NONE, ERROR, ERROR, ERROR }, // Position-independent exec
|
||||
{ NONE, NONE, CANONICAL, CANONICAL }, // Position-dependent exec
|
||||
};
|
||||
|
||||
Action action = table[get_output_type(ctx)][get_sym_type(sym)];
|
||||
@@ -259,15 +259,18 @@ void InputSection<E>::write_to(Context<E> &ctx, u8 *buf) {
|
||||
copy_contents_to(ctx, buf, sh_size);
|
||||
} else {
|
||||
// A relaxed section is copied piece-wise.
|
||||
memcpy(buf, contents.data(), deltas[0].offset);
|
||||
memcpy(buf, contents, deltas[0].offset);
|
||||
|
||||
i64 input_size = get_contents().size();
|
||||
for (i64 i = 0; i < deltas.size(); i++) {
|
||||
i64 offset = deltas[i].offset;
|
||||
i64 delta = deltas[i].delta;
|
||||
i64 end = (i + 1 == deltas.size()) ? contents.size() : deltas[i + 1].offset;
|
||||
i64 end = input_size;
|
||||
if (i + 1 < deltas.size())
|
||||
end = deltas[i + 1].offset;
|
||||
i64 removed_bytes = get_removed_bytes(deltas, i);
|
||||
memcpy(buf + offset + removed_bytes - delta,
|
||||
contents.data() + offset + removed_bytes,
|
||||
contents + offset + removed_bytes,
|
||||
end - offset - removed_bytes);
|
||||
}
|
||||
}
|
||||
@@ -288,8 +291,8 @@ void InputSection<E>::write_to(Context<E> &ctx, u8 *buf) {
|
||||
template <typename E>
|
||||
std::string_view
|
||||
InputSection<E>::get_func_name(Context<E> &ctx, i64 offset) const {
|
||||
for (Symbol<E> *sym : file.symbols)
|
||||
if (sym->file == &file)
|
||||
for (Symbol<E> *sym : file->symbols)
|
||||
if (sym->file == file)
|
||||
if (const ElfSym<E> &esym = sym->esym();
|
||||
esym.st_shndx == shndx && esym.st_type == STT_FUNC &&
|
||||
esym.st_value <= offset && offset < esym.st_value + esym.st_size)
|
||||
@@ -297,35 +300,63 @@ InputSection<E>::get_func_name(Context<E> &ctx, i64 offset) const {
|
||||
return "";
|
||||
}
|
||||
|
||||
// Find the prevailing group having the same signature as the discarded group
|
||||
// that contains esym. This is called only on an error path, so a linear scan is
|
||||
// sufficient.
|
||||
template <typename E>
|
||||
static ObjectFile<E> *
|
||||
find_comdat_owner(Context<E> &ctx, ObjectFile<E> &file, const ElfSym<E> &esym) {
|
||||
if (esym.is_undef() || esym.is_abs() || esym.is_common())
|
||||
return nullptr;
|
||||
|
||||
i64 shndx = file.get_shndx(esym);
|
||||
for (ComdatGroupRef<E> &ref : file.comdat_groups) {
|
||||
if (ref.is_owner ||
|
||||
!ranges::any_of(ref.members(file), [&](u32 x) { return x == shndx; }))
|
||||
continue;
|
||||
|
||||
Symbol<E> *sig = ref.signature(ctx);
|
||||
for (ObjectFile<E> *file : ctx.objs)
|
||||
for (ComdatGroupRef<E> &ref : file->comdat_groups)
|
||||
if (ref.is_owner && ref.signature(ctx) == sig)
|
||||
return file;
|
||||
}
|
||||
return nullptr;
|
||||
}
|
||||
|
||||
// Test if the symbol a given relocation refers to has already been resolved.
|
||||
// If not, record that error and returns true.
|
||||
template <typename E>
|
||||
bool InputSection<E>::record_undef_error(Context<E> &ctx, const ElfRel<E> &rel) {
|
||||
// If a relocation refers to a linker-synthesized symbol for a
|
||||
// section fragment, it's always been resolved.
|
||||
if (file.elf_syms.size() <= rel.r_sym)
|
||||
if (file->elf_syms.size() <= rel.r_sym)
|
||||
return false;
|
||||
|
||||
Symbol<E> &sym = *file.symbols[rel.r_sym];
|
||||
const ElfSym<E> &esym = file.elf_syms[rel.r_sym];
|
||||
Symbol<E> &sym = *file->symbols[rel.r_sym];
|
||||
const ElfSym<E> &esym = file->elf_syms[rel.r_sym];
|
||||
|
||||
// If a symbol is defined in a comdat group, and the comdat group is
|
||||
// discarded, the symbol may not have an owner. It is technically an
|
||||
// violation of the One Definition Rule, so it is a programmer's fault.
|
||||
if (!sym.file) {
|
||||
Error(ctx) << *this << ": " << sym << " refers to a discarded COMDAT section"
|
||||
<< " probably due to an ODR violation";
|
||||
// A global symbol in a discarded COMDAT group should resolve to the
|
||||
// corresponding symbol in the prevailing group. If it does not, the
|
||||
// object files violate the One Definition Rule.
|
||||
if (!sym.file && &sym != discarded_comdat_sym<E>) {
|
||||
std::stringstream ss;
|
||||
ss << *this << ": " << sym << " refers to a discarded COMDAT section"
|
||||
<< " probably due to an ODR violation";
|
||||
if (ObjectFile<E> *owner = find_comdat_owner(ctx, *file, esym))
|
||||
ss << '\n' << ">>> prevailing definition is in " << *owner;
|
||||
Error(ctx) << ss.str();
|
||||
return true;
|
||||
}
|
||||
|
||||
auto record = [&] {
|
||||
std::stringstream ss;
|
||||
if (std::string_view source = file.get_source_name(); !source.empty())
|
||||
if (std::string_view source = file->get_source_name(); !source.empty())
|
||||
ss << ">>> referenced by " << source << "\n";
|
||||
else
|
||||
ss << ">>> referenced by " << *this << "\n";
|
||||
|
||||
ss << ">>> " << file;
|
||||
ss << ">>> " << *file;
|
||||
if (std::string_view func = get_func_name(ctx, rel.r_offset); !func.empty())
|
||||
ss << ":(" << func << ")";
|
||||
ss << '\n';
|
||||
@@ -359,12 +390,9 @@ bool InputSection<E>::record_undef_error(Context<E> &ctx, const ElfRel<E> &rel)
|
||||
|
||||
template <typename E>
|
||||
MergeableSection<E>::MergeableSection(Context<E> &ctx, MergedSection<E> &parent,
|
||||
std::unique_ptr<InputSection<E>> &isec)
|
||||
: parent(parent), p2align(isec->p2align), input_section(std::move(isec)) {
|
||||
InputSection<E> *isec)
|
||||
: parent(parent), p2align(isec->p2align), input_section(isec) {
|
||||
input_section->uncompress(ctx);
|
||||
|
||||
std::scoped_lock lock(parent.mu);
|
||||
parent.members.push_back(this);
|
||||
}
|
||||
|
||||
static size_t find_null(std::string_view data, i64 pos, i64 entsize) {
|
||||
@@ -397,19 +425,27 @@ static size_t find_null(std::string_view data, i64 pos, i64 entsize) {
|
||||
// We do not support mergeable sections that have relocations.
|
||||
template <typename E>
|
||||
void MergeableSection<E>::split_contents(Context<E> &ctx) {
|
||||
std::string_view data = input_section->contents;
|
||||
std::string_view data = input_section->get_contents();
|
||||
if (data.size() > UINT32_MAX)
|
||||
Fatal(ctx) << *input_section << ": mergeable section too large";
|
||||
|
||||
i64 entsize = parent.shdr.sh_entsize;
|
||||
HyperLogLog::Sketch &sketch = parent.estimator.local();
|
||||
|
||||
// Split sections
|
||||
auto add_fragment = [&](i64 pos, i64 size) {
|
||||
frag_offsets.push_back(pos);
|
||||
u64 hash = hash_string(data.substr(pos, size));
|
||||
hashes.push_back(hash);
|
||||
sketch.insert(hash);
|
||||
};
|
||||
|
||||
// Hash each fragment while its contents are still in the cache.
|
||||
if (parent.shdr.sh_flags & SHF_STRINGS) {
|
||||
for (i64 pos = 0; pos < data.size();) {
|
||||
frag_offsets.push_back(pos);
|
||||
size_t end = find_null(data, pos, entsize);
|
||||
if (end == data.npos)
|
||||
Fatal(ctx) << *input_section << ": string is not null terminated";
|
||||
add_fragment(pos, end + entsize - pos);
|
||||
pos = end + entsize;
|
||||
}
|
||||
} else {
|
||||
@@ -417,23 +453,12 @@ void MergeableSection<E>::split_contents(Context<E> &ctx) {
|
||||
Fatal(ctx) << *input_section
|
||||
<< ": section size is not multiple of sh_entsize";
|
||||
frag_offsets.reserve(data.size() / entsize);
|
||||
hashes.reserve(data.size() / entsize);
|
||||
|
||||
for (i64 pos = 0; pos < data.size(); pos += entsize)
|
||||
frag_offsets.push_back(pos);
|
||||
add_fragment(pos, entsize);
|
||||
}
|
||||
|
||||
// Compute hashes for section pieces
|
||||
HyperLogLog estimator;
|
||||
hashes.reserve(frag_offsets.size());
|
||||
|
||||
for (i64 i = 0; i < frag_offsets.size(); i++) {
|
||||
u64 hash = hash_string(get_contents(i));
|
||||
hashes.push_back(hash);
|
||||
estimator.insert(hash);
|
||||
}
|
||||
|
||||
parent.estimator.merge(estimator);
|
||||
|
||||
static Counter counter("string_fragments");
|
||||
counter += frag_offsets.size();
|
||||
}
|
||||
@@ -441,8 +466,20 @@ void MergeableSection<E>::split_contents(Context<E> &ctx) {
|
||||
template <typename E>
|
||||
void MergeableSection<E>::resolve_contents(Context<E> &ctx) {
|
||||
fragments.reserve(frag_offsets.size());
|
||||
for (i64 i = 0; i < frag_offsets.size(); i++)
|
||||
fragments.push_back(parent.insert(ctx, get_contents(i), hashes[i], p2align));
|
||||
|
||||
// The hash table is typically much larger than the cache, so each
|
||||
// insertion stalls on a cache miss for its first probe. We know all
|
||||
// hashes upfront, so prefetch the bucket a few insertions ahead.
|
||||
constexpr i64 lookahead = 8;
|
||||
|
||||
for (i64 i = 0; i < frag_offsets.size(); i++) {
|
||||
if (i + lookahead < frag_offsets.size())
|
||||
parent.map.prefetch(hashes[i + lookahead]);
|
||||
|
||||
SectionFragment<E> *frag =
|
||||
parent.insert(ctx, get_contents(i), hashes[i], p2align);
|
||||
fragments.push_back(parent.map.get_idx(frag));
|
||||
}
|
||||
|
||||
// Reclaim memory as we'll never use this vector again
|
||||
hashes.clear();
|
||||
@@ -451,6 +488,10 @@ void MergeableSection<E>::resolve_contents(Context<E> &ctx) {
|
||||
|
||||
using E = MOLD_TARGET;
|
||||
|
||||
// InputSections are allocated from the arena, which does not run
|
||||
// destructors, so the class must stay trivially destructible.
|
||||
static_assert(std::is_trivially_destructible_v<InputSection<E>>);
|
||||
|
||||
template bool cie_equals(const CieRecord<E> &, const CieRecord<E> &);
|
||||
template class InputSection<E>;
|
||||
template class MergeableSection<E>;
|
||||
|
||||
+35
-6
@@ -111,6 +111,27 @@ static std::string_view unquote(std::string_view s) {
|
||||
return s;
|
||||
}
|
||||
|
||||
// Version scripts and dynamic lists take a quoted name literally, while
|
||||
// an unquoted one is a glob pattern. We escape glob metacharacters in a
|
||||
// quoted name so that the pattern matcher treats them as literals.
|
||||
template <typename E>
|
||||
std::string_view Script<E>::unquote_pattern(std::string_view tok) {
|
||||
if (!tok.starts_with('"'))
|
||||
return tok;
|
||||
|
||||
std::string_view str = unquote(tok);
|
||||
if (str.find_first_of("*?[\\") == str.npos)
|
||||
return str;
|
||||
|
||||
std::string out;
|
||||
for (char c : str) {
|
||||
if (c == '*' || c == '?' || c == '[' || c == '\\')
|
||||
out += '\\';
|
||||
out += c;
|
||||
}
|
||||
return save_string(ctx, out);
|
||||
}
|
||||
|
||||
template <typename E>
|
||||
std::span<std::string_view>
|
||||
Script<E>::read_output_format(std::span<std::string_view> tok) {
|
||||
@@ -200,7 +221,8 @@ Script<E>::read_group(std::span<std::string_view> tok) {
|
||||
}
|
||||
|
||||
MappedFile *mf = resolve_path(tok[0], true);
|
||||
read_file(ctx, rctx, mf);
|
||||
ReaderContext rctx2 = rctx.next_child();
|
||||
read_file(ctx, rctx2, mf);
|
||||
tok = tok.subspan(1);
|
||||
}
|
||||
|
||||
@@ -268,6 +290,13 @@ static bool read_label(std::span<std::string_view> &tok, std::string label) {
|
||||
tok = tok.subspan(2);
|
||||
return true;
|
||||
}
|
||||
|
||||
// The tokenizer keeps a colon in a token because of the C++ scope
|
||||
// operator, so `local:*` is a single token. Split the pattern off.
|
||||
if (tok.size() >= 1 && tok[0].starts_with(label + ":")) {
|
||||
tok[0] = tok[0].substr(label.size() + 1);
|
||||
return true;
|
||||
}
|
||||
return false;
|
||||
}
|
||||
|
||||
@@ -308,11 +337,11 @@ Script<E>::read_version_script_commands(std::span<std::string_view> tok,
|
||||
if (tok[0] == "*") {
|
||||
ctx.default_version = (is_global ? ver_idx : (u32)VER_NDX_LOCAL);
|
||||
} else if (is_global) {
|
||||
ctx.version_patterns.push_back({unquote(tok[0]), mf->name, ver_str,
|
||||
ver_idx, is_cpp});
|
||||
ctx.version_patterns.push_back({unquote_pattern(tok[0]), mf->name,
|
||||
ver_str, ver_idx, is_cpp});
|
||||
} else {
|
||||
ctx.version_patterns.push_back({unquote(tok[0]), mf->name, ver_str,
|
||||
VER_NDX_LOCAL, is_cpp});
|
||||
ctx.version_patterns.push_back({unquote_pattern(tok[0]), mf->name,
|
||||
ver_str, VER_NDX_LOCAL, is_cpp});
|
||||
}
|
||||
|
||||
tok = tok.subspan(1);
|
||||
@@ -386,7 +415,7 @@ Script<E>::read_dynamic_list_commands(std::span<std::string_view> tok,
|
||||
continue;
|
||||
}
|
||||
|
||||
result.push_back({unquote(tok[0]), "", is_cpp});
|
||||
result.push_back({unquote_pattern(tok[0]), "", is_cpp});
|
||||
tok = skip(tok.subspan(1), ";");
|
||||
}
|
||||
return tok;
|
||||
|
||||
+82
-83
@@ -179,13 +179,18 @@ static PluginStatus add_input_file(const char *path) {
|
||||
MappedFile *mf = must_open_file(ctx, path);
|
||||
mf->is_dependency = false;
|
||||
|
||||
ObjectFile<E> *file = new ObjectFile<E>(ctx, mf, "");
|
||||
ObjectFile<E> *file = ctx.arena.template make<ObjectFile<E>>(ctx, mf, "");
|
||||
ctx.obj_pool.emplace_back(file);
|
||||
lto_objects<E>.push_back(file);
|
||||
|
||||
file->priority = file_priority++;
|
||||
file->is_lto_output = true;
|
||||
file->is_reachable = true;
|
||||
file->parse(ctx);
|
||||
file->parse_symbols(ctx);
|
||||
|
||||
// parse_symbols() only registers global symbols. Create their shared
|
||||
// Symbol objects and fill in the file's pointers before resolving.
|
||||
gather_symbols(ctx);
|
||||
file->resolve_symbols(ctx);
|
||||
return LDPS_OK;
|
||||
}
|
||||
@@ -280,7 +285,7 @@ template <typename E>
|
||||
static PluginStatus
|
||||
get_symbols(const void *handle, int nsyms, PluginSymbol *psyms, bool is_v2) {
|
||||
ObjectFile<E> &file = *(ObjectFile<E> *)handle;
|
||||
assert(file.is_lto_obj);
|
||||
assert(file.is_lto_input);
|
||||
|
||||
// If file is an archive member which was not chose to be included in
|
||||
// to the final result, we need to make the plugin to ignore all
|
||||
@@ -307,7 +312,7 @@ get_symbols(const void *handle, int nsyms, PluginSymbol *psyms, bool is_v2) {
|
||||
if (sym.file->is_dso)
|
||||
return LDPR_RESOLVED_DYN;
|
||||
|
||||
if (((ObjectFile<E> *)sym.file)->is_lto_obj && !sym.is_wrapped)
|
||||
if (sym.file->to_obj()->is_lto_input && !sym.is_wrapped)
|
||||
return esym.is_undef() ? LDPR_RESOLVED_IR : LDPR_PREEMPTED_IR;
|
||||
return esym.is_undef() ? LDPR_RESOLVED_EXEC : LDPR_PREEMPTED_REG;
|
||||
};
|
||||
@@ -342,8 +347,8 @@ static void restart_process(Context<E> &ctx) {
|
||||
for (std::string_view arg : ctx.cmdline_args)
|
||||
args.push_back(strdup(std::string(arg).c_str()));
|
||||
|
||||
for (std::unique_ptr<ObjectFile<E>> &file : ctx.obj_pool)
|
||||
if (file->is_lto_obj && !file->is_reachable)
|
||||
for (ArenaObjectPtr<ObjectFile<E>> &file : ctx.obj_pool)
|
||||
if (file->is_lto_input && !file->is_reachable)
|
||||
args.push_back(strdup(("--:ignore-ir-file=" +
|
||||
file->mf->get_identifier()).c_str()));
|
||||
|
||||
@@ -425,7 +430,8 @@ get_api_version(const char *plugin_identifier,
|
||||
if (LAPI_V1 < minimal_api_supported)
|
||||
Fatal(*gctx<E>) << "LTO plugin does not support V0 or V1 API";
|
||||
|
||||
std::string version = mold_version + "\0"s;
|
||||
// The plugin reads the string after this function has returned
|
||||
static std::string version = mold_version + "\0"s;
|
||||
|
||||
*linker_identifier = "mold";
|
||||
*linker_version = version.data();
|
||||
@@ -440,74 +446,71 @@ get_api_version(const char *plugin_identifier,
|
||||
// dlopen the linker plugin file
|
||||
template <typename E>
|
||||
static void load_lto_plugin(Context<E> &ctx) {
|
||||
static std::once_flag flag;
|
||||
if (phase != 0)
|
||||
return;
|
||||
phase = 1;
|
||||
gctx<E> = &ctx;
|
||||
|
||||
std::call_once(flag, [&] {
|
||||
assert(phase == 0);
|
||||
phase = 1;
|
||||
gctx<E> = &ctx;
|
||||
void *handle = dlopen(ctx.arg.plugin.c_str(), RTLD_NOW | RTLD_LOCAL);
|
||||
if (!handle)
|
||||
Fatal(ctx) << "could not open plugin file: " << dlerror();
|
||||
|
||||
void *handle = dlopen(ctx.arg.plugin.c_str(), RTLD_NOW | RTLD_LOCAL);
|
||||
if (!handle)
|
||||
Fatal(ctx) << "could not open plugin file: " << dlerror();
|
||||
OnloadFn *onload = (OnloadFn *)dlsym(handle, "onload");
|
||||
if (!onload)
|
||||
Fatal(ctx) << "failed to load plugin " << ctx.arg.plugin << ": "
|
||||
<< dlerror();
|
||||
|
||||
OnloadFn *onload = (OnloadFn *)dlsym(handle, "onload");
|
||||
if (!onload)
|
||||
Fatal(ctx) << "failed to load plugin " << ctx.arg.plugin << ": "
|
||||
<< dlerror();
|
||||
auto save = [&](std::string_view str) {
|
||||
return save_string(ctx, std::string(str).c_str()).data();
|
||||
};
|
||||
|
||||
auto save = [&](std::string_view str) {
|
||||
return save_string(ctx, std::string(str).c_str()).data();
|
||||
};
|
||||
std::vector<PluginTagValue> tv;
|
||||
tv.emplace_back(LDPT_MESSAGE, message<E>);
|
||||
|
||||
std::vector<PluginTagValue> tv;
|
||||
tv.emplace_back(LDPT_MESSAGE, message<E>);
|
||||
if (ctx.arg.shared)
|
||||
tv.emplace_back(LDPT_LINKER_OUTPUT, LDPO_DYN);
|
||||
else if (ctx.arg.pie)
|
||||
tv.emplace_back(LDPT_LINKER_OUTPUT, LDPO_PIE);
|
||||
else
|
||||
tv.emplace_back(LDPT_LINKER_OUTPUT, LDPO_EXEC);
|
||||
|
||||
if (ctx.arg.shared)
|
||||
tv.emplace_back(LDPT_LINKER_OUTPUT, LDPO_DYN);
|
||||
else if (ctx.arg.pie)
|
||||
tv.emplace_back(LDPT_LINKER_OUTPUT, LDPO_PIE);
|
||||
else
|
||||
tv.emplace_back(LDPT_LINKER_OUTPUT, LDPO_EXEC);
|
||||
for (std::string_view opt : ctx.arg.plugin_opt)
|
||||
tv.emplace_back(LDPT_OPTION, save(opt));
|
||||
|
||||
for (std::string_view opt : ctx.arg.plugin_opt)
|
||||
tv.emplace_back(LDPT_OPTION, save(opt));
|
||||
tv.emplace_back(LDPT_REGISTER_CLAIM_FILE_HOOK, register_claim_file_hook<E>);
|
||||
tv.emplace_back(LDPT_REGISTER_ALL_SYMBOLS_READ_HOOK,
|
||||
register_all_symbols_read_hook<E>);
|
||||
tv.emplace_back(LDPT_REGISTER_CLEANUP_HOOK, register_cleanup_hook<E>);
|
||||
tv.emplace_back(LDPT_ADD_SYMBOLS, add_symbols);
|
||||
tv.emplace_back(LDPT_GET_SYMBOLS, get_symbols_v1);
|
||||
tv.emplace_back(LDPT_ADD_INPUT_FILE, add_input_file<E>);
|
||||
tv.emplace_back(LDPT_GET_INPUT_FILE, get_input_file);
|
||||
tv.emplace_back(LDPT_RELEASE_INPUT_FILE, release_input_file<E>);
|
||||
tv.emplace_back(LDPT_ADD_INPUT_LIBRARY, add_input_library);
|
||||
tv.emplace_back(LDPT_OUTPUT_NAME, save(ctx.arg.output));
|
||||
tv.emplace_back(LDPT_SET_EXTRA_LIBRARY_PATH, set_extra_library_path);
|
||||
tv.emplace_back(LDPT_GET_VIEW, get_view<E>);
|
||||
tv.emplace_back(LDPT_GET_INPUT_SECTION_COUNT, get_input_section_count);
|
||||
tv.emplace_back(LDPT_GET_INPUT_SECTION_TYPE, get_input_section_type);
|
||||
tv.emplace_back(LDPT_GET_INPUT_SECTION_NAME, get_input_section_name);
|
||||
tv.emplace_back(LDPT_GET_INPUT_SECTION_CONTENTS, get_input_section_contents);
|
||||
tv.emplace_back(LDPT_UPDATE_SECTION_ORDER, update_section_order);
|
||||
tv.emplace_back(LDPT_ALLOW_SECTION_ORDERING, allow_section_ordering);
|
||||
tv.emplace_back(LDPT_ADD_SYMBOLS_V2, add_symbols);
|
||||
tv.emplace_back(LDPT_GET_SYMBOLS_V2, get_symbols_v2<E>);
|
||||
tv.emplace_back(LDPT_ALLOW_UNIQUE_SEGMENT_FOR_SECTIONS,
|
||||
allow_unique_segment_for_sections);
|
||||
tv.emplace_back(LDPT_UNIQUE_SEGMENT_FOR_SECTIONS, unique_segment_for_sections);
|
||||
tv.emplace_back(LDPT_GET_SYMBOLS_V3, get_symbols_v3<E>);
|
||||
tv.emplace_back(LDPT_GET_INPUT_SECTION_ALIGNMENT, get_input_section_alignment);
|
||||
tv.emplace_back(LDPT_GET_INPUT_SECTION_SIZE, get_input_section_size);
|
||||
tv.emplace_back(LDPT_REGISTER_NEW_INPUT_HOOK, register_new_input_hook<E>);
|
||||
tv.emplace_back(LDPT_GET_WRAP_SYMBOLS, get_wrap_symbols);
|
||||
tv.emplace_back(LDPT_GET_API_VERSION, get_api_version<E>);
|
||||
tv.emplace_back(LDPT_NULL, 0);
|
||||
|
||||
tv.emplace_back(LDPT_REGISTER_CLAIM_FILE_HOOK, register_claim_file_hook<E>);
|
||||
tv.emplace_back(LDPT_REGISTER_ALL_SYMBOLS_READ_HOOK,
|
||||
register_all_symbols_read_hook<E>);
|
||||
tv.emplace_back(LDPT_REGISTER_CLEANUP_HOOK, register_cleanup_hook<E>);
|
||||
tv.emplace_back(LDPT_ADD_SYMBOLS, add_symbols);
|
||||
tv.emplace_back(LDPT_GET_SYMBOLS, get_symbols_v1);
|
||||
tv.emplace_back(LDPT_ADD_INPUT_FILE, add_input_file<E>);
|
||||
tv.emplace_back(LDPT_GET_INPUT_FILE, get_input_file);
|
||||
tv.emplace_back(LDPT_RELEASE_INPUT_FILE, release_input_file<E>);
|
||||
tv.emplace_back(LDPT_ADD_INPUT_LIBRARY, add_input_library);
|
||||
tv.emplace_back(LDPT_OUTPUT_NAME, save(ctx.arg.output));
|
||||
tv.emplace_back(LDPT_SET_EXTRA_LIBRARY_PATH, set_extra_library_path);
|
||||
tv.emplace_back(LDPT_GET_VIEW, get_view<E>);
|
||||
tv.emplace_back(LDPT_GET_INPUT_SECTION_COUNT, get_input_section_count);
|
||||
tv.emplace_back(LDPT_GET_INPUT_SECTION_TYPE, get_input_section_type);
|
||||
tv.emplace_back(LDPT_GET_INPUT_SECTION_NAME, get_input_section_name);
|
||||
tv.emplace_back(LDPT_GET_INPUT_SECTION_CONTENTS, get_input_section_contents);
|
||||
tv.emplace_back(LDPT_UPDATE_SECTION_ORDER, update_section_order);
|
||||
tv.emplace_back(LDPT_ALLOW_SECTION_ORDERING, allow_section_ordering);
|
||||
tv.emplace_back(LDPT_ADD_SYMBOLS_V2, add_symbols);
|
||||
tv.emplace_back(LDPT_GET_SYMBOLS_V2, get_symbols_v2<E>);
|
||||
tv.emplace_back(LDPT_ALLOW_UNIQUE_SEGMENT_FOR_SECTIONS,
|
||||
allow_unique_segment_for_sections);
|
||||
tv.emplace_back(LDPT_UNIQUE_SEGMENT_FOR_SECTIONS, unique_segment_for_sections);
|
||||
tv.emplace_back(LDPT_GET_SYMBOLS_V3, get_symbols_v3<E>);
|
||||
tv.emplace_back(LDPT_GET_INPUT_SECTION_ALIGNMENT, get_input_section_alignment);
|
||||
tv.emplace_back(LDPT_GET_INPUT_SECTION_SIZE, get_input_section_size);
|
||||
tv.emplace_back(LDPT_REGISTER_NEW_INPUT_HOOK, register_new_input_hook<E>);
|
||||
tv.emplace_back(LDPT_GET_WRAP_SYMBOLS, get_wrap_symbols);
|
||||
tv.emplace_back(LDPT_GET_API_VERSION, get_api_version<E>);
|
||||
tv.emplace_back(LDPT_NULL, 0);
|
||||
|
||||
[[maybe_unused]] PluginStatus status = onload(tv.data());
|
||||
assert(status == LDPS_OK);
|
||||
});
|
||||
[[maybe_unused]] PluginStatus status = onload(tv.data());
|
||||
assert(status == LDPS_OK);
|
||||
}
|
||||
|
||||
template <typename E>
|
||||
@@ -603,20 +606,16 @@ ObjectFile<E> *read_lto_object(Context<E> &ctx, MappedFile *mf) {
|
||||
|
||||
load_lto_plugin(ctx);
|
||||
|
||||
// V0 API's claim_file is not thread-safe.
|
||||
static std::mutex mu;
|
||||
std::unique_lock lock(mu, std::defer_lock);
|
||||
if (!is_gcc_linker_api_v1)
|
||||
lock.lock();
|
||||
|
||||
// Create mold's object instance
|
||||
ObjectFile<E> *obj = new ObjectFile<E>;
|
||||
ObjectFile<E> *obj =
|
||||
ctx.arena.template make<ObjectFile<E>>(ctx);
|
||||
ctx.obj_pool.emplace_back(obj);
|
||||
|
||||
obj->filename = mf->name;
|
||||
obj->symbols.push_back(new Symbol<E>);
|
||||
Symbol<E> *dummy = ctx.arena.template make<Symbol<E>>();
|
||||
obj->symbols.emplace_back(dummy);
|
||||
obj->first_global = 1;
|
||||
obj->is_lto_obj = true;
|
||||
obj->is_lto_input = true;
|
||||
obj->mf = mf;
|
||||
obj->archive_name = mf->parent ? mf->parent->name : "";
|
||||
|
||||
@@ -651,7 +650,8 @@ ObjectFile<E> *read_lto_object(Context<E> &ctx, MappedFile *mf) {
|
||||
|
||||
// Initialize esyms
|
||||
obj->lto_elf_syms.resize(plugin_symbols.size() + 1);
|
||||
obj->lto_comdat_groups.resize(plugin_symbols.size() + 1);
|
||||
obj->lto_comdat_signatures.resize(plugin_symbols.size() + 1);
|
||||
obj->lto_comdat_discarded.resize(plugin_symbols.size() + 1);
|
||||
i64 strtab_offset = 1;
|
||||
|
||||
for (i64 i = 0; i < plugin_symbols.size(); i++) {
|
||||
@@ -669,14 +669,13 @@ ObjectFile<E> *read_lto_object(Context<E> &ctx, MappedFile *mf) {
|
||||
// have input sections.
|
||||
if (psym.comdat_key) {
|
||||
std::string_view key = save_string(ctx, psym.comdat_key);
|
||||
obj->lto_comdat_groups[i + 1] = insert_comdat_group(ctx, key);
|
||||
obj->lto_comdat_signatures[i + 1] = get_symbol(ctx, key);
|
||||
}
|
||||
}
|
||||
|
||||
obj->symbol_strtab = save_string(ctx, strtab);
|
||||
obj->elf_syms = obj->lto_elf_syms;
|
||||
obj->populate_symbol_names();
|
||||
obj->initialize_symbols(ctx);
|
||||
obj->register_global_symbols(ctx);
|
||||
plugin_symbols.clear();
|
||||
return obj;
|
||||
}
|
||||
@@ -695,10 +694,10 @@ std::vector<ObjectFile<E> *> run_lto_plugin(Context<E> &ctx) {
|
||||
|
||||
// Set `referenced_by_regular_obj` bit.
|
||||
tbb::parallel_for_each(ctx.objs, [](ObjectFile<E> *file) {
|
||||
if (!file->is_lto_obj) {
|
||||
if (!file->is_lto_input) {
|
||||
for (Symbol<E> *sym : file->get_global_syms()) {
|
||||
if (sym->file && !sym->file->is_dso &&
|
||||
((ObjectFile<E> *)sym->file)->is_lto_obj) {
|
||||
sym->file->to_obj()->is_lto_input) {
|
||||
std::scoped_lock lock(sym->mu);
|
||||
sym->referenced_by_regular_obj = true;
|
||||
}
|
||||
@@ -726,7 +725,7 @@ std::vector<ObjectFile<E> *> run_lto_plugin(Context<E> &ctx) {
|
||||
// given to the LTO backend. Such sections contains code and data for
|
||||
// peripherails (typically GPUs).
|
||||
for (ObjectFile<E> *file : ctx.objs) {
|
||||
if (file->is_reachable && !file->is_lto_obj && file->is_gcc_offload_obj) {
|
||||
if (file->is_reachable && !file->is_lto_input && file->is_gcc_offload_obj) {
|
||||
PluginInputFile pfile = create_plugin_input_file(ctx, file->mf);
|
||||
int claimed = false;
|
||||
claim_file_hook(&pfile, &claimed);
|
||||
|
||||
+296
-132
@@ -6,6 +6,8 @@
|
||||
#include <functional>
|
||||
#include <sys/stat.h>
|
||||
#include <sys/types.h>
|
||||
#include <tbb/parallel_for_each.h>
|
||||
#include <tbb/parallel_sort.h>
|
||||
#include <unordered_set>
|
||||
|
||||
namespace mold {
|
||||
@@ -14,98 +16,126 @@ template <typename E>
|
||||
static void
|
||||
check_file_compatibility(Context<E> &ctx, ReaderContext &rctx, MappedFile *mf) {
|
||||
std::string_view target = get_machine_type(ctx, rctx, mf);
|
||||
if (target.empty())
|
||||
Fatal(ctx) << mf->name << ": unknown machine type";
|
||||
if (target != ctx.arg.emulation)
|
||||
Fatal(ctx) << mf->name << ": incompatible file type: "
|
||||
<< ctx.arg.emulation << " is expected but got " << target;
|
||||
}
|
||||
|
||||
template <typename E>
|
||||
static ObjectFile<E> *new_object_file(Context<E> &ctx, ReaderContext &rctx,
|
||||
MappedFile *mf, std::string archive_name) {
|
||||
static void new_object_file(Context<E> &ctx, ReaderContext &rctx,
|
||||
MappedFile *mf, std::string archive_name) {
|
||||
static Counter count("parsed_objs");
|
||||
count++;
|
||||
|
||||
check_file_compatibility(ctx, rctx, mf);
|
||||
|
||||
ObjectFile<E> *file = new ObjectFile<E>(ctx, mf, archive_name);
|
||||
ObjectFile<E> *file =
|
||||
ctx.arena.template make<ObjectFile<E>>(ctx, mf, archive_name);
|
||||
ctx.obj_pool.emplace_back(file);
|
||||
file->priority = ctx.file_priority++;
|
||||
file->as_needed =
|
||||
rctx.in_lib || (!archive_name.empty() && !rctx.whole_archive);
|
||||
file->is_reachable = !file->as_needed;
|
||||
|
||||
rctx.tg->run([file, &ctx] { file->parse(ctx); });
|
||||
if (ctx.arg.trace)
|
||||
Out(ctx) << "trace: " << *file;
|
||||
return file;
|
||||
file->parse_symbols(ctx);
|
||||
ctx.unsorted_input_files.push_back({rctx.pos, file});
|
||||
}
|
||||
|
||||
// IR files for LTO are not read in place. We only record them here,
|
||||
// and read_input_files() hands them to the LTO plugin once all input
|
||||
// files have been found. We do this because LTO object file reading
|
||||
// is order-dependent.
|
||||
template <typename E>
|
||||
static void defer_lto_obj(Context<E> &ctx, ReaderContext &rctx,
|
||||
MappedFile *mf, std::string archive_name) {
|
||||
ReaderJob job;
|
||||
job.rctx = rctx;
|
||||
job.mf = mf;
|
||||
job.archive_name = archive_name;
|
||||
ctx.lto_jobs.push_back(std::move(job));
|
||||
}
|
||||
|
||||
template <typename E>
|
||||
static ObjectFile<E> *new_lto_obj(Context<E> &ctx, ReaderContext &rctx,
|
||||
MappedFile *mf, std::string archive_name) {
|
||||
static void new_lto_obj(Context<E> &ctx, ReaderContext &rctx,
|
||||
MappedFile *mf, std::string archive_name) {
|
||||
static Counter count("parsed_lto_objs");
|
||||
count++;
|
||||
|
||||
if (ctx.arg.ignore_ir_file.count(mf->get_identifier()))
|
||||
return nullptr;
|
||||
return;
|
||||
|
||||
ObjectFile<E> *file = read_lto_object(ctx, mf);
|
||||
if (!file)
|
||||
return nullptr;
|
||||
return;
|
||||
|
||||
file->priority = ctx.file_priority++;
|
||||
file->archive_name = archive_name;
|
||||
file->as_needed =
|
||||
rctx.in_lib || (!archive_name.empty() && !rctx.whole_archive);
|
||||
file->is_reachable = !file->as_needed;
|
||||
|
||||
if (ctx.arg.trace)
|
||||
Out(ctx) << "trace: " << *file;
|
||||
return file;
|
||||
ctx.unsorted_input_files.push_back({rctx.pos, file});
|
||||
}
|
||||
|
||||
template <typename E>
|
||||
static SharedFile<E> *
|
||||
new_shared_file(Context<E> &ctx, ReaderContext &rctx, MappedFile *mf) {
|
||||
static void new_shared_file(Context<E> &ctx, ReaderContext &rctx,
|
||||
MappedFile *mf) {
|
||||
if (rctx.static_)
|
||||
Fatal(ctx) << mf->name << ": attempted static link of a dynamic object";
|
||||
|
||||
check_file_compatibility(ctx, rctx, mf);
|
||||
|
||||
SharedFile<E> *file = new SharedFile<E>(ctx, mf);
|
||||
SharedFile<E> *file = ctx.arena.template make<SharedFile<E>>(ctx, mf);
|
||||
ctx.dso_pool.emplace_back(file);
|
||||
file->priority = ctx.file_priority++;
|
||||
file->as_needed = rctx.as_needed;
|
||||
file->is_reachable = !file->as_needed;
|
||||
|
||||
rctx.tg->run([file, &ctx] { file->parse(ctx); });
|
||||
if (ctx.arg.trace)
|
||||
Out(ctx) << "trace: " << *file;
|
||||
return file;
|
||||
file->parse(ctx);
|
||||
ctx.unsorted_input_files.push_back({rctx.pos, file});
|
||||
}
|
||||
|
||||
// Reads a file inside an archive.
|
||||
template <typename E>
|
||||
static void read_archive_member(Context<E> &ctx, ReaderContext &rctx,
|
||||
MappedFile *mf, std::string archive_name) {
|
||||
switch (get_file_type(ctx, mf)) {
|
||||
case FileType::ELF_OBJ:
|
||||
new_object_file(ctx, rctx, mf, archive_name);
|
||||
break;
|
||||
case FileType::GCC_LTO_OBJ:
|
||||
case FileType::LLVM_BITCODE:
|
||||
defer_lto_obj(ctx, rctx, mf, archive_name);
|
||||
break;
|
||||
case FileType::ELF_DSO:
|
||||
Warn(ctx) << archive_name << "(" << mf->name
|
||||
<< "): shared object file in an archive is ignored";
|
||||
break;
|
||||
default:
|
||||
break;
|
||||
}
|
||||
}
|
||||
|
||||
// Reads the given file, which is located at rctx.pos in the command
|
||||
// line. If the file is a container, i.e. an archive file or a linker
|
||||
// script, the files in it are read in place, recursively. IR files
|
||||
// for LTO are only recorded; see defer_lto_obj().
|
||||
//
|
||||
// read_input_files() reads top-level files with this function too but
|
||||
// overrides the container cases to read archive members in parallel.
|
||||
template <typename E>
|
||||
void read_file(Context<E> &ctx, ReaderContext &rctx, MappedFile *mf) {
|
||||
switch (get_file_type(ctx, mf)) {
|
||||
case FileType::ELF_OBJ:
|
||||
ctx.objs.push_back(new_object_file(ctx, rctx, mf, ""));
|
||||
new_object_file(ctx, rctx, mf, "");
|
||||
return;
|
||||
case FileType::ELF_DSO:
|
||||
ctx.dsos.push_back(new_shared_file(ctx, rctx, mf));
|
||||
new_shared_file(ctx, rctx, mf);
|
||||
return;
|
||||
case FileType::AR:
|
||||
case FileType::THIN_AR:
|
||||
for (MappedFile *child : read_archive_members(ctx, mf)) {
|
||||
switch (get_file_type(ctx, child)) {
|
||||
case FileType::ELF_OBJ:
|
||||
ctx.objs.push_back(new_object_file(ctx, rctx, child, mf->name));
|
||||
break;
|
||||
case FileType::GCC_LTO_OBJ:
|
||||
case FileType::LLVM_BITCODE:
|
||||
if (ObjectFile<E> *file = new_lto_obj(ctx, rctx, child, mf->name))
|
||||
ctx.objs.push_back(file);
|
||||
break;
|
||||
case FileType::ELF_DSO:
|
||||
Warn(ctx) << mf->name << "(" << child->name
|
||||
<< "): shared object file in an archive is ignored";
|
||||
break;
|
||||
default:
|
||||
break;
|
||||
}
|
||||
ReaderContext rctx2 = rctx.next_child();
|
||||
read_archive_member(ctx, rctx2, child, mf->name);
|
||||
}
|
||||
return;
|
||||
case FileType::TEXT:
|
||||
@@ -113,8 +143,7 @@ void read_file(Context<E> &ctx, ReaderContext &rctx, MappedFile *mf) {
|
||||
return;
|
||||
case FileType::GCC_LTO_OBJ:
|
||||
case FileType::LLVM_BITCODE:
|
||||
if (ObjectFile<E> *file = new_lto_obj(ctx, rctx, mf, ""))
|
||||
ctx.objs.push_back(file);
|
||||
defer_lto_obj(ctx, rctx, mf, "");
|
||||
return;
|
||||
default:
|
||||
Fatal(ctx) << mf->name << ": unknown file type";
|
||||
@@ -123,35 +152,23 @@ void read_file(Context<E> &ctx, ReaderContext &rctx, MappedFile *mf) {
|
||||
|
||||
template <typename E>
|
||||
static std::string_view
|
||||
detect_machine_type(Context<E> &ctx, std::vector<std::string> args) {
|
||||
for (ReaderContext rctx; const std::string &arg : args) {
|
||||
if (arg == "--Bstatic") {
|
||||
rctx.static_ = true;
|
||||
} else if (arg == "--Bdynamic") {
|
||||
rctx.static_ = false;
|
||||
} else if (!arg.starts_with('-')) {
|
||||
if (MappedFile *mf = open_file(ctx, arg))
|
||||
detect_machine_type(Context<E> &ctx, std::span<ReaderJob> jobs) {
|
||||
for (ReaderJob &job : jobs)
|
||||
if (!job.is_lib)
|
||||
if (MappedFile *mf = open_file(ctx, job.name))
|
||||
if (get_file_type(ctx, mf) != FileType::TEXT)
|
||||
if (std::string_view target = get_machine_type(ctx, rctx, mf);
|
||||
if (std::string_view target = get_machine_type(ctx, job.rctx, mf);
|
||||
!target.empty())
|
||||
return target;
|
||||
}
|
||||
}
|
||||
|
||||
for (ReaderContext rctx; const std::string &arg : args) {
|
||||
if (arg == "--Bstatic") {
|
||||
rctx.static_ = true;
|
||||
} else if (arg == "--Bdynamic") {
|
||||
rctx.static_ = false;
|
||||
} else if (!arg.starts_with('-')) {
|
||||
if (MappedFile *mf = open_file(ctx, arg))
|
||||
for (ReaderJob &job : jobs)
|
||||
if (!job.is_lib)
|
||||
if (MappedFile *mf = open_file(ctx, job.name))
|
||||
if (get_file_type(ctx, mf) == FileType::TEXT)
|
||||
if (std::string_view target =
|
||||
Script(ctx, rctx, mf).get_script_output_type();
|
||||
Script(ctx, job.rctx, mf).get_script_output_type();
|
||||
!target.empty())
|
||||
return target;
|
||||
}
|
||||
}
|
||||
|
||||
Fatal(ctx) << "-m option is missing";
|
||||
}
|
||||
@@ -193,73 +210,154 @@ MappedFile *find_library(Context<E> &ctx, ReaderContext &rctx, std::string name)
|
||||
Fatal(ctx) << "library not found: " << name;
|
||||
}
|
||||
|
||||
// Reads all input files.
|
||||
//
|
||||
// Reading input files is I/O- and CPU-intensive, and a large program
|
||||
// can easily consist of tens of thousands of them, so we want to read
|
||||
// files in parallel. The command line, on the other hand, is
|
||||
// inherently sequential: options such as --as-needed or
|
||||
// --whole-archive apply to the files after them, and a file's
|
||||
// priority for symbol resolution is its position in the command line.
|
||||
//
|
||||
// We reconcile the two as follows: the command line parser has
|
||||
// already recorded the reader state and the position for each file
|
||||
// argument in its ReaderJob. We open and read files in parallel and
|
||||
// then sort the files we've found back into the command line order to
|
||||
// assign priorities.
|
||||
template <typename E>
|
||||
static void read_input_files(Context<E> &ctx, std::span<std::string> args) {
|
||||
static void read_input_files(Context<E> &ctx, std::vector<ReaderJob> &jobs) {
|
||||
Timer t(ctx, "read_input_files");
|
||||
|
||||
ReaderContext rctx;
|
||||
std::vector<ReaderContext> stack;
|
||||
std::unordered_set<std::string_view> visited;
|
||||
// Open and read files in parallel. Archive files are expanded into
|
||||
// one job per member so that members are read in parallel too.
|
||||
//
|
||||
// Linker scripts are one exception to the parallelism: they can
|
||||
// modify the context, e.g. by defining symbol versions, so we only
|
||||
// collect them here and parse them after this loop, one at a time
|
||||
// and in the command line order, to keep their effects
|
||||
// deterministic. Scripts given as input files are rare and small,
|
||||
// such as the GROUP file that glibc installs as libc.so, so the
|
||||
// lost parallelism doesn't matter.
|
||||
//
|
||||
// IR files for LTO are the other exception. This loop only records
|
||||
// them, and we hand them to the LTO plugin after the scripts have
|
||||
// been parsed, also in the command line order.
|
||||
//
|
||||
// Parsing scripts late assumes that no script directive affects how
|
||||
// command line arguments after the script are read. That holds for
|
||||
// the directives we currently support: a script can only add input
|
||||
// files, whose positions order them correctly, and define symbol
|
||||
// versions or symbols, which are not used until after this
|
||||
// function. If we add a directive that doesn't satisfy this, such
|
||||
// as SEARCH_DIR, which affects how -l arguments after it are
|
||||
// resolved, this scheme needs to be revisited.
|
||||
tbb::concurrent_vector<ReaderJob> scripts;
|
||||
|
||||
tbb::task_group tg;
|
||||
rctx.tg = &tg;
|
||||
tbb::parallel_for_each(jobs, [&](ReaderJob &job,
|
||||
tbb::feeder<ReaderJob> &feeder) {
|
||||
ReaderContext &rctx = job.rctx;
|
||||
|
||||
while (!args.empty()) {
|
||||
std::string_view arg = args[0];
|
||||
args = args.subspan(1);
|
||||
|
||||
if (arg == "--as-needed") {
|
||||
rctx.as_needed = true;
|
||||
} else if (arg == "--no-as-needed") {
|
||||
rctx.as_needed = false;
|
||||
} else if (arg == "--whole-archive") {
|
||||
rctx.whole_archive = true;
|
||||
} else if (arg == "--no-whole-archive") {
|
||||
rctx.whole_archive = false;
|
||||
} else if (arg == "--Bstatic") {
|
||||
rctx.static_ = true;
|
||||
} else if (arg == "--Bdynamic") {
|
||||
rctx.static_ = false;
|
||||
} else if (arg == "--start-lib") {
|
||||
rctx.in_lib = true;
|
||||
} else if (arg == "--end-lib") {
|
||||
rctx.in_lib = false;
|
||||
} else if (arg == "--push-state") {
|
||||
stack.push_back(rctx);
|
||||
} else if (arg == "--pop-state") {
|
||||
if (stack.empty())
|
||||
Fatal(ctx) << "no state pushed before popping";
|
||||
rctx = stack.back();
|
||||
stack.pop_back();
|
||||
} else if (arg.starts_with("-l")) {
|
||||
arg = arg.substr(2);
|
||||
if (visited.contains(arg))
|
||||
continue;
|
||||
visited.insert(arg);
|
||||
|
||||
MappedFile *mf = find_library(ctx, rctx, std::string(arg));
|
||||
mf->given_fullpath = false;
|
||||
read_file(ctx, rctx, mf);
|
||||
} else {
|
||||
read_file(ctx, rctx, must_open_file(ctx, std::string(arg)));
|
||||
// An archive member is enqueued by the job that read its archive
|
||||
// file. A thin archive's members are opened here rather than by
|
||||
// that job, so that the files of a large archive are opened in
|
||||
// parallel.
|
||||
if (!job.archive_name.empty()) {
|
||||
MappedFile *mf = job.mf;
|
||||
if (!mf) {
|
||||
mf = must_open_file(ctx, job.name);
|
||||
mf->thin_parent = job.thin_parent;
|
||||
}
|
||||
read_archive_member(ctx, rctx, mf, job.archive_name);
|
||||
return;
|
||||
}
|
||||
|
||||
// Everything else is a command line argument that we need to open.
|
||||
MappedFile *mf;
|
||||
if (job.is_lib) {
|
||||
mf = find_library(ctx, rctx, job.name);
|
||||
mf->given_fullpath = false;
|
||||
} else {
|
||||
mf = must_open_file(ctx, job.name);
|
||||
}
|
||||
|
||||
switch (get_file_type(ctx, mf)) {
|
||||
case FileType::AR:
|
||||
for (MappedFile *child : read_fat_archive_members(ctx, mf)) {
|
||||
ReaderJob job2;
|
||||
job2.rctx = rctx.next_child();
|
||||
job2.mf = child;
|
||||
job2.archive_name = mf->name;
|
||||
feeder.add(std::move(job2));
|
||||
}
|
||||
break;
|
||||
case FileType::THIN_AR:
|
||||
for (std::string &path : get_thin_archive_member_paths(ctx, mf)) {
|
||||
ReaderJob job2;
|
||||
job2.rctx = rctx.next_child();
|
||||
job2.name = std::move(path);
|
||||
job2.archive_name = mf->name;
|
||||
job2.thin_parent = mf;
|
||||
feeder.add(std::move(job2));
|
||||
}
|
||||
break;
|
||||
case FileType::TEXT:
|
||||
job.mf = mf;
|
||||
scripts.push_back(std::move(job));
|
||||
break;
|
||||
default:
|
||||
read_file(ctx, rctx, mf);
|
||||
}
|
||||
});
|
||||
|
||||
// Parse linker scripts and read the files they name.
|
||||
ranges::sort(scripts, {}, [](const ReaderJob &job) {
|
||||
return job.rctx.pos;
|
||||
});
|
||||
|
||||
for (ReaderJob &job : scripts)
|
||||
Script(ctx, job.rctx, job.mf).parse_linker_script();
|
||||
|
||||
// Hand IR files to the LTO plugin, in the command line order. The
|
||||
// plugin keeps global state, so claims can't run in parallel anyway,
|
||||
// and LLVM's LTO assumes that the module holding the prevailing copy
|
||||
// of a COMDAT group arrives before the modules holding the other
|
||||
// copies, as it does with a serial linker. Otherwise the losing
|
||||
// copies' internal symbols become undefined references in the LTO
|
||||
// result.
|
||||
ranges::sort(ctx.lto_jobs, {}, [](const ReaderJob &job) {
|
||||
return job.rctx.pos;
|
||||
});
|
||||
|
||||
for (ReaderJob &job : ctx.lto_jobs)
|
||||
new_lto_obj(ctx, job.rctx, job.mf, job.archive_name);
|
||||
|
||||
// Sort the files into the command line order and assign priorities.
|
||||
tbb::parallel_sort(ctx.unsorted_input_files, [](auto &a, auto &b) {
|
||||
return a.first < b.first;
|
||||
});
|
||||
|
||||
for (auto &pair : ctx.unsorted_input_files) {
|
||||
InputFile<E> *file = pair.second;
|
||||
file->priority = ctx.file_priority++;
|
||||
if (ctx.arg.trace)
|
||||
Out(ctx) << "trace: " << *file;
|
||||
|
||||
if (file->is_dso)
|
||||
ctx.dsos.push_back(file->to_dso());
|
||||
else
|
||||
ctx.objs.push_back(file->to_obj());
|
||||
}
|
||||
|
||||
ctx.unsorted_input_files.clear();
|
||||
|
||||
if (ctx.objs.empty() && ctx.dsos.empty())
|
||||
Fatal(ctx) << "no input files";
|
||||
|
||||
if (rctx.static_ || ctx.arg.relocatable) {
|
||||
ctx.arg.static_ = true;
|
||||
ctx.arg.dynamic_linker = "";
|
||||
}
|
||||
|
||||
tg.wait();
|
||||
}
|
||||
|
||||
template <typename E>
|
||||
static bool has_lto_obj(Context<E> &ctx) {
|
||||
for (ObjectFile<E> *file : ctx.objs)
|
||||
if (file->is_reachable && (file->is_lto_obj || file->is_gcc_offload_obj))
|
||||
if (file->is_reachable && (file->is_lto_input || file->is_gcc_offload_obj))
|
||||
return true;
|
||||
return false;
|
||||
}
|
||||
@@ -291,11 +389,11 @@ int mold_main(int argc, char **argv) {
|
||||
|
||||
// Parse non-positional command line options
|
||||
ctx.cmdline_args = expand_response_files(ctx, argv);
|
||||
std::vector<std::string> file_args = parse_nonpositional_args(ctx);
|
||||
std::vector<ReaderJob> jobs = parse_nonpositional_args(ctx);
|
||||
|
||||
// If no -m option is given, deduce it from input files.
|
||||
if (ctx.arg.emulation.empty())
|
||||
ctx.arg.emulation = detect_machine_type(ctx, file_args);
|
||||
ctx.arg.emulation = detect_machine_type(ctx, jobs);
|
||||
|
||||
// Redo if -m does not match with our speculation.
|
||||
if (ctx.arg.emulation != E::name) {
|
||||
@@ -330,7 +428,7 @@ int mold_main(int argc, char **argv) {
|
||||
get_symbol(ctx, arg)->is_traced = true;
|
||||
|
||||
// Parse input files
|
||||
read_input_files(ctx, file_args);
|
||||
read_input_files(ctx, jobs);
|
||||
|
||||
// Uniquify shared object files by soname
|
||||
{
|
||||
@@ -368,6 +466,19 @@ int mold_main(int argc, char **argv) {
|
||||
std::erase_if(ctx.objs, [](InputFile<E> *file) { return !file->is_reachable; });
|
||||
std::erase_if(ctx.dsos, [](InputFile<E> *file) { return !file->is_reachable; });
|
||||
|
||||
// Building .gdb_index is split into three stages because the required data
|
||||
// becomes available at different points in the link. Compilation units and
|
||||
// public names depend only on input sections, so read them now in a
|
||||
// low-priority arena while foreground passes continue.
|
||||
bool create_gdb_index = ctx.arg.gdb_index && !ctx.arg.relocatable;
|
||||
tbb::task_arena gdb_input_arena(tbb::task_arena::automatic, 1,
|
||||
tbb::task_arena::priority::low);
|
||||
tbb::task_group gdb_task;
|
||||
if (create_gdb_index)
|
||||
gdb_input_arena.execute([&] {
|
||||
gdb_task.run([&] { read_gdb_index_inputs(ctx); });
|
||||
});
|
||||
|
||||
// Parse .eh_frame section contents.
|
||||
parse_eh_frame_sections(ctx);
|
||||
|
||||
@@ -385,6 +496,21 @@ int mold_main(int argc, char **argv) {
|
||||
return 0;
|
||||
}
|
||||
|
||||
// Non-allocated merged sections are independent of symbol and relocation
|
||||
// processing. Resolve them while the remaining foreground passes run.
|
||||
tbb::task_arena merge_arena(tbb::task_arena::automatic, 1,
|
||||
tbb::task_arena::priority::low);
|
||||
tbb::task_group merge_task;
|
||||
merge_arena.execute([&] {
|
||||
merge_task.run([&] {
|
||||
tbb::parallel_for_each(ctx.merged_sections,
|
||||
[&](ArenaObjectPtr<MergedSection<E>> &sec) {
|
||||
if (!(sec->shdr.sh_flags & SHF_ALLOC))
|
||||
sec->resolve(ctx);
|
||||
});
|
||||
});
|
||||
});
|
||||
|
||||
// Create .bss sections for common symbols.
|
||||
convert_common_symbols(ctx);
|
||||
|
||||
@@ -505,8 +631,11 @@ int mold_main(int argc, char **argv) {
|
||||
// .got.plt, .dynsym, .dynstr, etc.
|
||||
scan_relocations(ctx);
|
||||
|
||||
// Compute the is_weak bit for each imported symbol.
|
||||
compute_imported_symbol_weakness(ctx);
|
||||
// Now that we know all exported symbols, make sure that no versioned
|
||||
// name is defined twice.
|
||||
check_symbol_version_conflicts(ctx);
|
||||
|
||||
merge_arena.execute([&] { merge_task.wait(); });
|
||||
|
||||
// Sort sections by section attributes so that we'll have to
|
||||
// create as few segments as possible.
|
||||
@@ -520,15 +649,37 @@ int mold_main(int argc, char **argv) {
|
||||
// within an output section to input sections.
|
||||
compute_section_sizes(ctx);
|
||||
|
||||
// RELR is encoded independently for each output chunk using offsets
|
||||
// relative to that chunk.
|
||||
if (ctx.arg.pack_dyn_relocs_relr)
|
||||
ctx.reldyn->construct_relr(ctx);
|
||||
|
||||
// Reserve a space for dynamic symbol strings in .dynstr and sort
|
||||
// .dynsym contents if necessary. Beyond this point, no symbol will
|
||||
// be added to .dynsym.
|
||||
sort_dynsyms(ctx);
|
||||
|
||||
// sort_debug_info_sections may uncompress the same .debug_info sections.
|
||||
if (create_gdb_index)
|
||||
gdb_input_arena.execute([&] { gdb_task.wait(); });
|
||||
|
||||
// Sort .debug_info contents so that DWARF32 debug info precedes that of
|
||||
// DWARF64. This is to mitigate the possibility of a relocation overflow.
|
||||
sort_debug_info_sections(ctx);
|
||||
|
||||
// Type vectors identify compilation units by their order in the output
|
||||
// .debug_info section. That order is now fixed, so build the table while the
|
||||
// remaining layout passes continue. This stage stops scaling after about 12
|
||||
// workers, so limit its arena to avoid competing with foreground work.
|
||||
i64 gdb_table_workers =
|
||||
std::clamp<i64>(get_thread_count(ctx) * 3 / 8, 1, 12);
|
||||
tbb::task_arena gdb_table_arena(gdb_table_workers, 1,
|
||||
tbb::task_arena::priority::low);
|
||||
if (ctx.gdb_index && !ctx.gnu_debuglink)
|
||||
gdb_table_arena.execute([&] {
|
||||
gdb_task.run([&] { build_gdb_index_tables(ctx); });
|
||||
});
|
||||
|
||||
// Print reports about undefined symbols, if needed.
|
||||
if (ctx.arg.unresolved_symbols == UNRESOLVED_ERROR)
|
||||
report_undef_errors(ctx);
|
||||
@@ -611,9 +762,12 @@ int mold_main(int argc, char **argv) {
|
||||
|
||||
// Re-finalize layout. fix_synthetic_symbols above may have changed
|
||||
// addends for dynamic relocations referencing synthetic symbols, which
|
||||
// can shift the encoded size of .rela.dyn under --pack-dyn-relocs=android.
|
||||
// For other modes this is a cheap no-op convergence.
|
||||
filesize = set_osec_offsets(ctx);
|
||||
// can shift the encoded size of .rela.dyn under --pack-dyn-relocs=android
|
||||
// because Android's packed format encodes addends in variable-length
|
||||
// SLEB128. Other modes, including ordinary RELR, encode nothing whose
|
||||
// size depends on addends, so they do not need this pass.
|
||||
if (ctx.arg.pack_dyn_relocs_android)
|
||||
filesize = set_osec_offsets(ctx);
|
||||
|
||||
// At this point, both memory and file layouts are fixed.
|
||||
|
||||
@@ -633,7 +787,7 @@ int mold_main(int argc, char **argv) {
|
||||
if constexpr (is_arm32be<E>)
|
||||
arm32be_swap_bytes(ctx);
|
||||
|
||||
if constexpr (is_x86_64<E>)
|
||||
if constexpr (is_x86_64<E> || is_arm64<E>)
|
||||
if (ctx.arg.z_rewrite_endbr)
|
||||
rewrite_endbr(ctx);
|
||||
|
||||
@@ -641,11 +795,12 @@ int mold_main(int argc, char **argv) {
|
||||
// so we sort them.
|
||||
sort_reldyn(ctx);
|
||||
|
||||
// .gdb_index's contents cannot be constructed before applying
|
||||
// relocations to other debug sections. We have relocated debug
|
||||
// sections now, so write the .gdb_index section.
|
||||
if (ctx.gdb_index && !ctx.gnu_debuglink)
|
||||
// The final stage reads address ranges, which requires relocated debug
|
||||
// sections. We have applied the relocations now, so finish the index.
|
||||
if (ctx.gdb_index && !ctx.gnu_debuglink) {
|
||||
gdb_table_arena.execute([&] { gdb_task.wait(); });
|
||||
write_gdb_index(ctx);
|
||||
}
|
||||
|
||||
// .note.gnu.build-id section contains a cryptographic hash of the
|
||||
// entire output file. Now that we wrote everything except build-id,
|
||||
@@ -690,11 +845,19 @@ int mold_main(int argc, char **argv) {
|
||||
notify_parent<E>();
|
||||
release_global_lock();
|
||||
|
||||
#if HAVE_MADVISE
|
||||
// Dropping page table entries here in parallel makes process exit
|
||||
// faster, as the kernel otherwise reclaims them in a single thread
|
||||
// on exit. File contents stay in the page cache.
|
||||
tbb::parallel_for_each(ctx.mf_pool, [](std::unique_ptr<MappedFile> &mf) {
|
||||
if (mf->is_mmapped && !mf->parent && mf->data && mf->size)
|
||||
madvise(mf->data, mf->size, MADV_DONTNEED);
|
||||
});
|
||||
#endif
|
||||
|
||||
if (ctx.arg.quick_exit)
|
||||
_exit(0);
|
||||
|
||||
for (std::function<void()> &fn : ctx.on_exit)
|
||||
fn();
|
||||
ctx.checkpoint();
|
||||
return 0;
|
||||
}
|
||||
@@ -702,5 +865,6 @@ int mold_main(int argc, char **argv) {
|
||||
using E = MOLD_TARGET;
|
||||
|
||||
template int mold_main<E>(int, char **);
|
||||
template void read_file(Context<E> &, ReaderContext &, MappedFile *);
|
||||
|
||||
} // namespace mold
|
||||
+1
-1
@@ -71,7 +71,7 @@ void print_map(Context<E> &ctx) {
|
||||
if (!osec)
|
||||
continue;
|
||||
|
||||
std::span<InputSection<E> *> members = osec->members;
|
||||
std::span<ArenaPtr<InputSection<E>>> members = osec->members;
|
||||
std::vector<std::string> bufs(members.size());
|
||||
|
||||
tbb::parallel_for((i64)0, (i64)members.size(), [&](i64 i) {
|
||||
|
||||
+34
-2
@@ -2,6 +2,19 @@
|
||||
|
||||
namespace mold {
|
||||
|
||||
// Files up to this size are read into malloc'ed memory rather than
|
||||
// mmap'ed. mmap(2) takes the process's address space lock, so with tens
|
||||
// of thousands of input files, the calls serialize at a few microseconds
|
||||
// each no matter how many threads make them. read(2) takes no such lock,
|
||||
// but copying costs memory bandwidth in proportion to the file size, so
|
||||
// large files are still mmap'ed. On a Chromium link, files below this
|
||||
// threshold are 64% of the inputs by count but 16% by size.
|
||||
//
|
||||
// The buffers add up to hundreds of megabytes on such a link, so they
|
||||
// need to be backed by huge pages; with 4 KiB pages, faulting them in
|
||||
// costs more than the mmap calls did. mimalloc does that by default.
|
||||
static constexpr i64 READ_THRESHOLD = 32 * 1024;
|
||||
|
||||
MappedFile *open_file_impl(const std::string &path, std::string &error) {
|
||||
i64 fd = ::open(path.c_str(), O_RDONLY);
|
||||
if (fd == -1) {
|
||||
@@ -18,11 +31,27 @@ MappedFile *open_file_impl(const std::string &path, std::string &error) {
|
||||
mf->name = path;
|
||||
mf->size = st.st_size;
|
||||
|
||||
if (st.st_size > 0) {
|
||||
if (st.st_size > 0 && st.st_size <= READ_THRESHOLD && S_ISREG(st.st_mode)) {
|
||||
u8 *buf = (u8 *)malloc(st.st_size);
|
||||
for (i64 pos = 0; pos < st.st_size;) {
|
||||
i64 n = pread(fd, buf + pos, st.st_size - pos, pos);
|
||||
if (n > 0) {
|
||||
pos += n;
|
||||
} else if (n == 0) {
|
||||
error = path + ": file is shorter than its reported size";
|
||||
break;
|
||||
} else if (errno != EINTR) {
|
||||
error = path + ": read failed: " + errno_string();
|
||||
break;
|
||||
}
|
||||
}
|
||||
mf->data = buf;
|
||||
} else if (st.st_size > 0) {
|
||||
mf->data = (u8 *)mmap(nullptr, st.st_size, PROT_READ | PROT_WRITE,
|
||||
MAP_PRIVATE, fd, 0);
|
||||
if (mf->data == MAP_FAILED)
|
||||
error = path + ": mmap failed: " + errno_string();
|
||||
mf->is_mmapped = true;
|
||||
}
|
||||
|
||||
close(fd);
|
||||
@@ -32,7 +61,10 @@ MappedFile *open_file_impl(const std::string &path, std::string &error) {
|
||||
void MappedFile::unmap() {
|
||||
if (size == 0 || parent || !data)
|
||||
return;
|
||||
munmap(data, size);
|
||||
if (is_mmapped)
|
||||
munmap(data, size);
|
||||
else
|
||||
free(data);
|
||||
data = nullptr;
|
||||
}
|
||||
|
||||
|
||||
@@ -48,6 +48,7 @@ MappedFile *open_file_impl(const std::string &path, std::string &error) {
|
||||
error = path + ": MapViewOfFile failed: " + errno_string();
|
||||
return nullptr;
|
||||
}
|
||||
mf->is_mmapped = true;
|
||||
}
|
||||
|
||||
return mf;
|
||||
|
||||
+846
-367
File diff suppressed because it is too large.
Load diff
+507
-222
File diff suppressed because it is too large.
Load diff
+109
-37
@@ -1,3 +1,4 @@
|
||||
#include "config.h"
|
||||
#include "mold.h"
|
||||
|
||||
#include <fcntl.h>
|
||||
@@ -45,8 +46,7 @@ public:
|
||||
MemoryMappedOutputFile(Context<E> &ctx, std::string path, i64 filesize, int perm)
|
||||
: OutputFile<E>(path, filesize, true) {
|
||||
std::string pid = std::to_string(getpid());
|
||||
std::string tmpfile =
|
||||
path_dirname(path) / ("." + path_filename(path) + "." + pid);
|
||||
std::string tmpfile = path_dirname(path) / ("."s + path_filename(path) + "." + pid);
|
||||
|
||||
this->fd = open_or_create_file(ctx, path, tmpfile, perm);
|
||||
|
||||
@@ -58,18 +58,34 @@ public:
|
||||
|
||||
output_tmpfile = (char *)save_string(ctx, tmpfile).data();
|
||||
|
||||
#ifdef __linux__
|
||||
// Calling falllocate speeds up later linking passes on ext4,
|
||||
// while it just takes time with not benefits on tmpfs.
|
||||
#if HAVE_FALLOCATE
|
||||
// Calling fallocate speeds up later linking passes on ext4 by
|
||||
// taking disk block allocation out of the page-fault handler.
|
||||
// On tmpfs, it instead makes things much slower: the kernel
|
||||
// allocates and zeroes every page of the range inside the
|
||||
// syscall, on one thread, which takes ~1.8 s for a 5 GiB file.
|
||||
if (struct statfs fs;
|
||||
fstatfs(this->fd, &fs) || fs.f_type != TMPFS_MAGIC)
|
||||
fallocate(this->fd, 0, 0, filesize);
|
||||
#endif
|
||||
|
||||
this->buf = (u8 *)mmap(nullptr, filesize, PROT_READ | PROT_WRITE,
|
||||
// We map the file with twice as much address space as its size, so
|
||||
// that extend() can grow the file into the mapping in place.
|
||||
// Touching the mapping beyond the end of the file is not allowed,
|
||||
// but growing the file with ftruncate makes the tail of the
|
||||
// mapping accessible without any further mmap call.
|
||||
vasize = filesize * 2;
|
||||
this->buf = (u8 *)mmap(nullptr, vasize, PROT_READ | PROT_WRITE,
|
||||
MAP_SHARED, this->fd, 0);
|
||||
if (this->buf == MAP_FAILED)
|
||||
Fatal(ctx) << path << ": mmap failed: " << errno_string();
|
||||
|
||||
if (this->buf == MAP_FAILED) {
|
||||
// If the address space is too tight, map just the file.
|
||||
vasize = filesize;
|
||||
this->buf = (u8 *)mmap(nullptr, filesize, PROT_READ | PROT_WRITE,
|
||||
MAP_SHARED, this->fd, 0);
|
||||
if (this->buf == MAP_FAILED)
|
||||
Fatal(ctx) << path << ": mmap failed: " << errno_string();
|
||||
}
|
||||
|
||||
mold::output_buffer_start = this->buf;
|
||||
mold::output_buffer_end = this->buf + filesize;
|
||||
@@ -80,20 +96,51 @@ public:
|
||||
::close(fd2);
|
||||
}
|
||||
|
||||
// Extend the file so that the caller can fill the appended data
|
||||
// through the tail of the mapping. This is called at most once per
|
||||
// output file.
|
||||
u8 *extend(Context<E> &ctx, i64 size) override {
|
||||
i64 mapsize = this->filesize;
|
||||
|
||||
if (ftruncate(this->fd, mapsize + size) == -1)
|
||||
Fatal(ctx) << "ftruncate failed: " << errno_string();
|
||||
|
||||
#if HAVE_FALLOCATE
|
||||
if (struct statfs fs;
|
||||
fstatfs(this->fd, &fs) || fs.f_type != TMPFS_MAGIC)
|
||||
fallocate(this->fd, 0, mapsize, size);
|
||||
#endif
|
||||
|
||||
if (mapsize + size > vasize) {
|
||||
// The appended data does not fit in the mapping. Map the grown
|
||||
// file again, moving the buffer.
|
||||
munmap(this->buf, vasize);
|
||||
vasize = mapsize + size;
|
||||
|
||||
this->buf = (u8 *)mmap(nullptr, vasize, PROT_READ | PROT_WRITE,
|
||||
MAP_SHARED, this->fd, 0);
|
||||
if (this->buf == MAP_FAILED)
|
||||
Fatal(ctx) << this->path << ": mmap failed: " << errno_string();
|
||||
|
||||
ctx.buf = this->buf;
|
||||
mold::output_buffer_start = this->buf;
|
||||
}
|
||||
|
||||
this->filesize += size;
|
||||
mold::output_buffer_end = this->buf + mapsize + size;
|
||||
|
||||
#ifdef MADV_HUGEPAGE
|
||||
madvise(this->buf, mapsize + size, MADV_HUGEPAGE);
|
||||
#endif
|
||||
return this->buf + mapsize;
|
||||
}
|
||||
|
||||
void close(Context<E> &ctx) override {
|
||||
Timer t(ctx, "close_file");
|
||||
|
||||
if (!this->is_unmapped)
|
||||
munmap(this->buf, this->filesize);
|
||||
|
||||
if (!this->buf2) {
|
||||
::close(this->fd);
|
||||
} else {
|
||||
FILE *out = fdopen(this->fd, "w");
|
||||
fseek(out, 0, SEEK_END);
|
||||
fwrite(this->buf2, this->buf2_size, 1, out);
|
||||
fclose(out);
|
||||
}
|
||||
munmap(this->buf, vasize);
|
||||
::close(this->fd);
|
||||
|
||||
// If an output file already exists, open a file and then remove it.
|
||||
// This is the fastest way to unlink a file, as it does not make the
|
||||
@@ -109,6 +156,9 @@ public:
|
||||
|
||||
private:
|
||||
int fd2 = -1;
|
||||
|
||||
// Size of the file mapping, which may extend past the end of the file.
|
||||
i64 vasize = 0;
|
||||
};
|
||||
|
||||
template <typename E>
|
||||
@@ -131,14 +181,7 @@ OutputFile<E>::open(Context<E> &ctx, std::string path, i64 filesize, int perm) {
|
||||
|
||||
#ifdef MADV_HUGEPAGE
|
||||
// Enable transparent huge page for an output memory-mapped file.
|
||||
// On Linux, it has an effect only on tmpfs mounted with `huge=advise`,
|
||||
// but it can make the linker ~10% faster. You can try it by creating
|
||||
// a tmpfs with the following commands
|
||||
//
|
||||
// $ mkdir tmp
|
||||
// $ sudo mount -t tmpfs -o size=2G,huge=advise none tmp
|
||||
//
|
||||
// and then specifying a path under the directory as an output file.
|
||||
// Linking a Chromium debug build is ~20% faster with this madvise call.
|
||||
madvise(file->buf, filesize, MADV_HUGEPAGE);
|
||||
#endif
|
||||
|
||||
@@ -170,10 +213,20 @@ void LockingOutputFile<E>::resize(Context<E> &ctx, i64 filesize) {
|
||||
if (ftruncate(this->fd, filesize) == -1)
|
||||
Fatal(ctx) << "ftruncate failed: " << errno_string();
|
||||
|
||||
this->buf = (u8 *)mmap(nullptr, filesize, PROT_READ | PROT_WRITE,
|
||||
// As in MemoryMappedOutputFile, we map the file with twice as much
|
||||
// address space as its size so that extend() can grow the file into
|
||||
// the mapping in place.
|
||||
vasize = filesize * 2;
|
||||
this->buf = (u8 *)mmap(nullptr, vasize, PROT_READ | PROT_WRITE,
|
||||
MAP_SHARED, this->fd, 0);
|
||||
if (this->buf == MAP_FAILED)
|
||||
Fatal(ctx) << this->path << ": mmap failed: " << errno_string();
|
||||
|
||||
if (this->buf == MAP_FAILED) {
|
||||
vasize = filesize;
|
||||
this->buf = (u8 *)mmap(nullptr, filesize, PROT_READ | PROT_WRITE,
|
||||
MAP_SHARED, this->fd, 0);
|
||||
if (this->buf == MAP_FAILED)
|
||||
Fatal(ctx) << this->path << ": mmap failed: " << errno_string();
|
||||
}
|
||||
|
||||
this->filesize = filesize;
|
||||
mold::output_buffer_start = this->buf;
|
||||
@@ -181,17 +234,36 @@ void LockingOutputFile<E>::resize(Context<E> &ctx, i64 filesize) {
|
||||
}
|
||||
|
||||
template <typename E>
|
||||
void LockingOutputFile<E>::close(Context<E> &ctx) {
|
||||
if (!this->is_unmapped)
|
||||
munmap(this->buf, this->filesize);
|
||||
u8 *LockingOutputFile<E>::extend(Context<E> &ctx, i64 size) {
|
||||
i64 mapsize = this->filesize;
|
||||
|
||||
if (this->buf2) {
|
||||
FILE *out = fdopen(this->fd, "w");
|
||||
fseek(out, 0, SEEK_END);
|
||||
fwrite(this->buf2, this->buf2_size, 1, out);
|
||||
fclose(out);
|
||||
if (ftruncate(this->fd, mapsize + size) == -1)
|
||||
Fatal(ctx) << "ftruncate failed: " << errno_string();
|
||||
|
||||
if (mapsize + size > vasize) {
|
||||
// The appended data does not fit in the mapping. Map the grown
|
||||
// file again, moving the buffer.
|
||||
munmap(this->buf, vasize);
|
||||
vasize = mapsize + size;
|
||||
|
||||
this->buf = (u8 *)mmap(nullptr, vasize, PROT_READ | PROT_WRITE,
|
||||
MAP_SHARED, this->fd, 0);
|
||||
if (this->buf == MAP_FAILED)
|
||||
Fatal(ctx) << this->path << ": mmap failed: " << errno_string();
|
||||
|
||||
ctx.buf = this->buf;
|
||||
mold::output_buffer_start = this->buf;
|
||||
}
|
||||
|
||||
this->filesize += size;
|
||||
mold::output_buffer_end = this->buf + mapsize + size;
|
||||
return this->buf + mapsize;
|
||||
}
|
||||
|
||||
template <typename E>
|
||||
void LockingOutputFile<E>::close(Context<E> &ctx) {
|
||||
if (!this->is_unmapped)
|
||||
munmap(this->buf, vasize);
|
||||
::close(this->fd);
|
||||
}
|
||||
|
||||
|
||||
+31
-12
@@ -39,22 +39,36 @@ public:
|
||||
CloseHandle(handle);
|
||||
}
|
||||
|
||||
u8 *extend(Context<E> &ctx, i64 size) override {
|
||||
UnmapViewOfFile(this->buf);
|
||||
|
||||
HANDLE map = CreateFileMapping(handle, nullptr, PAGE_READWRITE, 0,
|
||||
this->filesize + size, nullptr);
|
||||
if (!map)
|
||||
Fatal(ctx) << this->path << ": CreateFileMapping failed: "
|
||||
<< GetLastError();
|
||||
|
||||
this->buf = (u8 *)MapViewOfFile(map, FILE_MAP_WRITE, 0, 0,
|
||||
this->filesize + size);
|
||||
if (!this->buf)
|
||||
Fatal(ctx) << this->path << ": MapViewOfFile failed: " << GetLastError();
|
||||
|
||||
CloseHandle(map);
|
||||
|
||||
u8 *space = this->buf + this->filesize;
|
||||
memset(space, 0, size);
|
||||
|
||||
this->filesize += size;
|
||||
ctx.buf = this->buf;
|
||||
mold::output_buffer_start = this->buf;
|
||||
mold::output_buffer_end = this->buf + this->filesize;
|
||||
return space;
|
||||
}
|
||||
|
||||
void close(Context<E> &ctx) override {
|
||||
Timer t(ctx, "close_file");
|
||||
|
||||
UnmapViewOfFile(this->buf);
|
||||
|
||||
if (this->buf2) {
|
||||
if (SetFilePointer(handle, 0, nullptr, FILE_END) == INVALID_SET_FILE_POINTER)
|
||||
Fatal(ctx) << this->path << ": SetFilePointer failed: "
|
||||
<< GetLastError();
|
||||
|
||||
DWORD written;
|
||||
if (!WriteFile(handle, this->buf2, this->buf2_size, &written,
|
||||
nullptr))
|
||||
Fatal(ctx) << this->path << ": WriteFile failed: " << GetLastError();
|
||||
}
|
||||
|
||||
CloseHandle(handle);
|
||||
handle = INVALID_HANDLE_VALUE;
|
||||
}
|
||||
@@ -106,6 +120,11 @@ LockingOutputFile<E>::LockingOutputFile(Context<E> &ctx, std::string path,
|
||||
template <typename E>
|
||||
void LockingOutputFile<E>::resize(Context<E> &ctx, i64 filesize) {}
|
||||
|
||||
template <typename E>
|
||||
u8 *LockingOutputFile<E>::extend(Context<E> &ctx, i64 size) {
|
||||
return nullptr;
|
||||
}
|
||||
|
||||
template <typename E>
|
||||
void LockingOutputFile<E>::close(Context<E> &ctx) {}
|
||||
|
||||
|
||||
+698
-346
File diff suppressed because it is too large.
Load diff
+5
-4
@@ -76,16 +76,17 @@ static void create_comdat_group_sections(Context<E> &ctx) {
|
||||
ObjectFile<E> &file = *ctx.objs[i];
|
||||
|
||||
for (ComdatGroupRef<E> &ref : file.comdat_groups) {
|
||||
if (ref.group->owner != file.priority)
|
||||
if (!ref.is_owner)
|
||||
continue;
|
||||
|
||||
Symbol<E> *sym = file.symbols[file.elf_sections[ref.sect_idx].sh_info];
|
||||
assert(sym);
|
||||
|
||||
std::vector<Chunk<E> *> members;
|
||||
for (u32 j : ref.members) {
|
||||
for (u32 j : ref.members(file)) {
|
||||
const ElfShdr<E> &shdr = file.elf_sections[j];
|
||||
if (shdr.sh_type == (E::is_rela ? SHT_RELA : SHT_REL)) {
|
||||
if (shdr.sh_type == (E::is_rela ? SHT_RELA : SHT_REL) ||
|
||||
shdr.sh_type == SHT_CREL) {
|
||||
InputSection<E> &isec = *file.sections[shdr.sh_info];
|
||||
members.push_back(isec.output_section->reloc_sec.get());
|
||||
} else {
|
||||
@@ -127,7 +128,7 @@ static void r_claim_unresolved_symbols(Context<E> &ctx) {
|
||||
continue;
|
||||
|
||||
sym.file = file;
|
||||
sym.origin = 0;
|
||||
sym.origin = nullptr;
|
||||
sym.value = 0;
|
||||
sym.sym_idx = i;
|
||||
}
|
||||
|
||||
@@ -89,8 +89,8 @@ void shrink_sections(Context<E> &ctx) {
|
||||
// only ~0.04% larger than that of GNU ld), so we don't bother to handle
|
||||
// them. We scan relocations only once here.
|
||||
tbb::parallel_for_each(ctx.objs, [&](ObjectFile<E> *file) {
|
||||
for (std::unique_ptr<InputSection<E>> &isec : file->sections)
|
||||
if (isec && isec->is_alive && (isec->shdr().sh_flags & SHF_EXECINSTR))
|
||||
for (InputSection<E> *isec : file->sections)
|
||||
if (isec && isec->is_alive() && (isec->shdr().sh_flags & SHF_EXECINSTR))
|
||||
shrink_section(ctx, *isec);
|
||||
});
|
||||
|
||||
|
||||
+56
-57
@@ -11,14 +11,9 @@
|
||||
//
|
||||
// The function in this file creates thunks.
|
||||
//
|
||||
// Note that although thunks play an important role in an executable, they
|
||||
// don't take up too much space in it. For example, among the clang-16's
|
||||
// text segment whose size is ~300 MiB on ARM64, thunks in total occupy
|
||||
// only ~30 KiB or 0.01%. Of course the number depends on an ISA; we would
|
||||
// need more thunks on ARM32 whose branch range is shorter than ARM64.
|
||||
// That said, the total size of thunks still isn't that much. Therefore,
|
||||
// we don't need to try too hard to reduce thunk size to the absolute
|
||||
// minimum.
|
||||
// Thunk size varies widely across programs. In an ARM64 build of Clang 16,
|
||||
// thunks occupy about 30 KiB (0.01%) of a ~300 MiB text section, compared
|
||||
// with about 12.5 MiB (2.5%) of a ~500 MiB text section in TensorFlow.
|
||||
|
||||
#if MOLD_ARM32LE || MOLD_ARM32BE || MOLD_ARM64LE || MOLD_ARM64BE || \
|
||||
MOLD_PPC32 || MOLD_PPC64V1 || MOLD_PPC64V2
|
||||
@@ -41,10 +36,9 @@ static constexpr i64 batch_size =
|
||||
// for ARM64/ARM32/PPC, respectively.
|
||||
static constexpr i64 max_thunk_size = batch_size / 2;
|
||||
|
||||
// We align thunks to 16 byte boundaries because many processor vendors
|
||||
// recommend we align branch targets to 16 byte boundaries for performance
|
||||
// reasons.
|
||||
static constexpr i64 thunk_align = 16;
|
||||
// Power10 prefixed instructions must not cross a 64-byte boundary.
|
||||
// Aligning each thunk group to a 8-byte boundary guarantees that.
|
||||
static constexpr i64 thunk_align = 8;
|
||||
|
||||
template <typename E>
|
||||
static bool
|
||||
@@ -52,7 +46,7 @@ requires_thunk(Context<E> &ctx, InputSection<E> &isec, const ElfRel<E> &rel,
|
||||
bool first_pass) {
|
||||
if (!is_func_call_rel(rel))
|
||||
return false;
|
||||
Symbol<E> &sym = *isec.file.symbols[rel.r_sym];
|
||||
Symbol<E> &sym = *isec.file->symbols[rel.r_sym];
|
||||
|
||||
if (first_pass) {
|
||||
// On the first pass, we pessimistically assume that all out-of-section
|
||||
@@ -77,10 +71,9 @@ requires_thunk(Context<E> &ctx, InputSection<E> &isec, const ElfRel<E> &rel,
|
||||
// always have to make them jump to a thunk to switch processor mode
|
||||
// even if their destinations are reachable.
|
||||
if constexpr (is_arm32<E>)
|
||||
if (bool is_thumb = sym.get_addr(ctx) & 1;
|
||||
(rel.r_type == R_ARM_JUMP24 && is_thumb) ||
|
||||
(rel.r_type == R_ARM_PLT32 && is_thumb) ||
|
||||
(rel.r_type == R_ARM_THM_JUMP24 && !is_thumb))
|
||||
if ((rel.r_type == R_ARM_JUMP24 && is_thumb_func(ctx, sym)) ||
|
||||
(rel.r_type == R_ARM_PLT32 && is_thumb_func(ctx, sym)) ||
|
||||
(rel.r_type == R_ARM_THM_JUMP24 && is_arm_func(ctx, sym)))
|
||||
return true;
|
||||
|
||||
// On PowerPC, all PLT calls go through range extension thunks.
|
||||
@@ -115,15 +108,16 @@ void Thunk<E>::compute_size() {
|
||||
|
||||
template <>
|
||||
void OutputSection<E>::create_range_extension_thunks(Context<E> &ctx) {
|
||||
std::span<InputSection<E> *> m = members;
|
||||
std::span<ArenaPtr<InputSection<E>>> m = members;
|
||||
if (m.empty())
|
||||
return;
|
||||
|
||||
// Initialize input sections with a dummy offset so that we can
|
||||
// distinguish sections that have got an address with the one who
|
||||
// haven't.
|
||||
for (InputSection<E> *isec : m)
|
||||
// distinguish sections whose addresses have been assigned from those
|
||||
// whose addresses have not.
|
||||
tbb::parallel_for_each(m, [](InputSection<E> *isec) {
|
||||
isec->offset = -1;
|
||||
});
|
||||
thunks.clear();
|
||||
|
||||
// We create thunks from the beginning of the section to the end.
|
||||
@@ -169,17 +163,21 @@ void OutputSection<E>::create_range_extension_thunks(Context<E> &ctx) {
|
||||
d++;
|
||||
}
|
||||
|
||||
// Move C forward so that C is apart from B by BATCH_SIZE. We want
|
||||
// to make sure that there's at least one section between B and C
|
||||
// to ensure progress.
|
||||
c = b + 1;
|
||||
while (c < d && m[c]->offset + m[c]->sh_size < m[b]->offset + batch_size)
|
||||
c++;
|
||||
// Find the end of the current batch. Section end addresses are sorted,
|
||||
// so use binary search. Starting from B + 1 guarantees progress.
|
||||
std::span<ArenaPtr<InputSection<E>>> range = m.subspan(b + 1, d - b - 1);
|
||||
c = ranges::lower_bound(range, m[b]->offset + batch_size, {},
|
||||
[](InputSection<E> *isec) {
|
||||
return isec->offset + isec->sh_size;
|
||||
}) - m.begin();
|
||||
|
||||
// Move A forward so that A is reachable from C.
|
||||
// Find the first section that is within branch range of C.
|
||||
i64 c_offset = (c == d) ? offset : m[c]->offset;
|
||||
while (a < b && m[a]->offset + branch_distance<E> < c_offset)
|
||||
a++;
|
||||
range = m.subspan(a, b - a);
|
||||
a = ranges::lower_bound(range, c_offset - branch_distance<E>, {},
|
||||
[](InputSection<E> *isec) {
|
||||
return isec->offset;
|
||||
}) - m.begin();
|
||||
|
||||
// Erase references to out-of-range thunks.
|
||||
for (; t < thunks.size() && thunks[t]->offset < m[a]->offset; t++)
|
||||
@@ -191,27 +189,22 @@ void OutputSection<E>::create_range_extension_thunks(Context<E> &ctx) {
|
||||
thunks.emplace_back(std::make_unique<Thunk<E>>(*this, offset));
|
||||
|
||||
Thunk<E> &thunk = *thunks.back();
|
||||
std::mutex mu;
|
||||
tbb::enumerable_thread_specific<std::vector<Symbol<E> *>> symbols;
|
||||
|
||||
// Scan relocations between B and C to collect symbols that need
|
||||
// entries in the new thunk.
|
||||
tbb::parallel_for(b, c, [&](i64 i) {
|
||||
InputSection<E> &isec = *m[i];
|
||||
for (const ElfRel<E> &rel : isec.get_rels(ctx)) {
|
||||
if (requires_thunk(ctx, isec, rel, true)) {
|
||||
if (Symbol<E> &sym = *isec.file.symbols[rel.r_sym];
|
||||
!sym.flags.test_and_set()) {
|
||||
std::scoped_lock lock(mu);
|
||||
thunk.symbols.push_back(&sym);
|
||||
}
|
||||
}
|
||||
}
|
||||
for (const ElfRel<E> &rel : isec.get_rels(ctx))
|
||||
if (requires_thunk(ctx, isec, rel, true))
|
||||
if (Symbol<E> &sym = *isec.file->symbols[rel.r_sym];
|
||||
!sym.flags.test_and_set())
|
||||
symbols.local().push_back(&sym);
|
||||
});
|
||||
|
||||
// Sort symbols added to the thunk to make the output deterministic.
|
||||
ranges::sort(thunk.symbols, {}, [](Symbol<E> *x) {
|
||||
return std::tuple{x->file->priority, x->sym_idx};
|
||||
});
|
||||
// Add symbols to the thunk
|
||||
for (std::vector<Symbol<E> *> &vec : symbols)
|
||||
append(thunk.symbols, vec);
|
||||
|
||||
// Now that we know the number of symbols in the thunk, we can compute
|
||||
// the thunk's size.
|
||||
@@ -223,11 +216,18 @@ void OutputSection<E>::create_range_extension_thunks(Context<E> &ctx) {
|
||||
b = c;
|
||||
}
|
||||
|
||||
// Reset flags for future use
|
||||
// Clear marks for thunks that are still reachable from the last batch.
|
||||
for (; t < thunks.size(); t++)
|
||||
for (Symbol<E> *sym : thunks[t]->symbols)
|
||||
sym->flags = 0;
|
||||
|
||||
// Sort symbols for deterministic output.
|
||||
tbb::parallel_for_each(thunks, [](std::unique_ptr<Thunk<E>> &thunk) {
|
||||
ranges::sort(thunk->symbols, {}, [](Symbol<E> *sym) {
|
||||
return std::tuple{sym->file->priority, sym->sym_idx};
|
||||
});
|
||||
});
|
||||
|
||||
this->shdr.sh_size = offset;
|
||||
}
|
||||
|
||||
@@ -259,23 +259,28 @@ void remove_redundant_thunks(Context<E> &ctx) {
|
||||
for (OutputSection<E> *osec : sections) {
|
||||
tbb::parallel_for_each(osec->members, [&](InputSection<E> *isec) {
|
||||
for (const ElfRel<E> &rel : isec->get_rels(ctx))
|
||||
if (requires_thunk(ctx, *isec, rel, false))
|
||||
isec->file.symbols[rel.r_sym]->flags.test_and_set();
|
||||
if (is_func_call_rel(rel))
|
||||
if (Symbol<E> *sym = isec->file->symbols[rel.r_sym];
|
||||
!sym->flags &&
|
||||
requires_thunk(ctx, *isec, rel, false))
|
||||
sym->flags.test_and_set();
|
||||
});
|
||||
}
|
||||
|
||||
// Remove symbols from thunks if they don't actually need range
|
||||
// extension thunks
|
||||
for (OutputSection<E> *osec : sections) {
|
||||
for (std::unique_ptr<Thunk<E>> &thunk : osec->thunks) {
|
||||
std::erase_if(thunk->symbols, [&](Symbol<E> *sym) { return !sym->flags; });
|
||||
tbb::parallel_for_each(osec->thunks,
|
||||
[&](std::unique_ptr<Thunk<E>> &thunk) {
|
||||
std::erase_if(thunk->symbols,
|
||||
[&](Symbol<E> *sym) { return !sym->flags; });
|
||||
thunk->shrink_size(ctx);
|
||||
}
|
||||
});
|
||||
}
|
||||
|
||||
// Recompute section sizes
|
||||
tbb::parallel_for_each(sections, [&](OutputSection<E> *osec) {
|
||||
std::span<InputSection<E> *> m = osec->members;
|
||||
std::span<ArenaPtr<InputSection<E>>> m = osec->members;
|
||||
std::span<std::unique_ptr<Thunk<E>>> t = osec->thunks;
|
||||
i64 offset = 0;
|
||||
|
||||
@@ -294,12 +299,6 @@ void remove_redundant_thunks(Context<E> &ctx) {
|
||||
}
|
||||
osec->shdr.sh_size = offset;
|
||||
});
|
||||
|
||||
// Reset flags for future use
|
||||
for (OutputSection<E> *osec : sections)
|
||||
for (std::unique_ptr<Thunk<E>> &thunk : osec->thunks)
|
||||
for (Symbol<E> *sym : thunk->symbols)
|
||||
sym->flags = 0;
|
||||
}
|
||||
|
||||
// When applying relocations, we want to know the address in a reachable
|
||||
|
||||
+1
-1
@@ -86,7 +86,7 @@ function(add_target ARCH TRIPLE)
|
||||
endif()
|
||||
|
||||
add_test(NAME ${TESTNAME}
|
||||
COMMAND bash -x ${CMAKE_CURRENT_LIST_DIR}/${TEST}
|
||||
COMMAND ${CMAKE_CURRENT_LIST_DIR}/${TEST}
|
||||
WORKING_DIRECTORY ${mold_BINARY_DIR})
|
||||
|
||||
set_property(TEST ${TESTNAME} APPEND PROPERTY ENVIRONMENT
|
||||
|
||||
+1
-1
@@ -1,4 +1,4 @@
|
||||
#!/bin/bash
|
||||
#!/usr/bin/env bash
|
||||
. $(dirname $0)/common.inc
|
||||
|
||||
[ $MACHINE = aarch64 ] && skip
|
||||
|
||||
@@ -1,4 +1,4 @@
|
||||
#!/bin/bash
|
||||
#!/usr/bin/env bash
|
||||
. $(dirname $0)/common.inc
|
||||
|
||||
# This test crashes only on qemu-sparc64 running on GitHub Actions,
|
||||
|
||||
@@ -1,4 +1,4 @@
|
||||
#!/bin/bash
|
||||
#!/usr/bin/env bash
|
||||
. $(dirname $0)/common.inc
|
||||
|
||||
echo 'int main() { return 0; }' | $CC -c -o $t/a.o -xc -
|
||||
|
||||
@@ -1,4 +1,4 @@
|
||||
#!/bin/bash
|
||||
#!/usr/bin/env bash
|
||||
. $(dirname $0)/common.inc
|
||||
|
||||
cat <<EOF | $CC -o $t/a.o -c -xc -
|
||||
|
||||
Executable
+74
@@ -0,0 +1,74 @@
|
||||
#!/usr/bin/env bash
|
||||
. $(dirname $0)/common.inc
|
||||
|
||||
# When mold relaxes an instruction sequence, the relocations attached to the
|
||||
# original instructions no longer match the relaxed code. With --emit-relocs,
|
||||
# mold must rewrite the emitted relocations so that their types describe the
|
||||
# relaxed instructions.
|
||||
|
||||
cat <<'EOF' | $CC -o $t/a.o -c -xassembler -
|
||||
.text
|
||||
.globl _start
|
||||
_start:
|
||||
# GOT-load relaxation: ADRP+LDR => ADRP+ADD
|
||||
# R_AARCH64_ADR_GOT_PAGE => R_AARCH64_ADR_PREL_PG_HI21
|
||||
# R_AARCH64_LD64_GOT_LO12_NC => R_AARCH64_ADD_ABS_LO12_NC
|
||||
adrp x0, :got:gvar
|
||||
ldr x0, [x0, #:got_lo12:gvar]
|
||||
|
||||
# ADRP+ADD => NOP+ADR (gvar is within +-1 MiB)
|
||||
# R_AARCH64_ADR_PREL_PG_HI21 => R_AARCH64_NONE
|
||||
# R_AARCH64_ADD_ABS_LO12_NC => R_AARCH64_ADR_PREL_LO21
|
||||
adrp x1, gvar
|
||||
add x1, x1, #:lo12:gvar
|
||||
|
||||
# Both sequences must materialize the same address.
|
||||
cmp x0, x1
|
||||
bne 1f
|
||||
|
||||
# ... and it must point at gvar, whose value is 42.
|
||||
ldr w2, [x0]
|
||||
cmp w2, #42
|
||||
bne 1f
|
||||
|
||||
mov x0, #0
|
||||
b 2f
|
||||
1:
|
||||
mov x0, #1
|
||||
2:
|
||||
mov x8, #93 // __NR_exit
|
||||
svc #0
|
||||
|
||||
.data
|
||||
.hidden gvar
|
||||
gvar:
|
||||
.word 42
|
||||
EOF
|
||||
|
||||
$CC -B. -o $t/exe $t/a.o --static -nostdlib -Wl,-e,_start,--emit-relocs,--relax
|
||||
$QEMU $t/exe
|
||||
|
||||
$OBJDUMP -dr $t/exe > $t/exe.objdump
|
||||
|
||||
# Relaxation took place.
|
||||
grep -Fw nop $t/exe.objdump
|
||||
grep -Fw adr $t/exe.objdump
|
||||
grep -Fw add $t/exe.objdump
|
||||
|
||||
# The relocations were rewritten to match the relaxed instructions.
|
||||
grep -Fw R_AARCH64_ADR_PREL_PG_HI21 $t/exe.objdump
|
||||
grep -Fw R_AARCH64_ADD_ABS_LO12_NC $t/exe.objdump
|
||||
grep -Fw R_AARCH64_ADR_PREL_LO21 $t/exe.objdump
|
||||
|
||||
# The stale pre-relaxation relocations are gone.
|
||||
not grep -Fw R_AARCH64_ADR_GOT_PAGE $t/exe.objdump
|
||||
not grep -Fw R_AARCH64_LD64_GOT_LO12_NC $t/exe.objdump
|
||||
|
||||
# Each rewritten relocation must sit on the relaxed instruction it describes.
|
||||
awk '
|
||||
$3 == "adrp" || $3 == "add" || $3 == "adr" || $3 == "nop" { insn[$1] = $3 }
|
||||
$2 == "R_AARCH64_ADR_PREL_PG_HI21" { if (insn[$1] != "adrp") { bad=1; print "bad offset: " $0 } }
|
||||
$2 == "R_AARCH64_ADD_ABS_LO12_NC" { if (insn[$1] != "add") { bad=1; print "bad offset: " $0 } }
|
||||
$2 == "R_AARCH64_ADR_PREL_LO21" { if (insn[$1] != "adr") { bad=1; print "bad offset: " $0 } }
|
||||
END { exit bad+0 }
|
||||
' $t/exe.objdump
|
||||
+90
@@ -0,0 +1,90 @@
|
||||
#!/usr/bin/env bash
|
||||
. $(dirname $0)/common.inc
|
||||
|
||||
# Depending on the symbol, mold relaxes a TLSDESC sequence into a local-exec
|
||||
# (LE) or initial-exec (IE) sequence. The four-instruction sequence is rewritten
|
||||
# in place: the ADRP and LDR become NOPs, and the ADD and BLR become the two
|
||||
# instructions that materialize the address. With --emit-relocs, the emitted
|
||||
# relocations must be rewritten to match whichever relaxation was applied.
|
||||
|
||||
cat <<'EOF' | $CC -o $t/a.o -c -xc - -fPIC
|
||||
_Thread_local char foo[4] = "foo";
|
||||
_Thread_local char bar[4] = "bar";
|
||||
EOF
|
||||
|
||||
cat <<'EOF' | $CC -o $t/b.o -c -xc - -fPIC -mtls-dialect=desc -O2
|
||||
extern _Thread_local char foo[4];
|
||||
extern _Thread_local char bar[4];
|
||||
char *get_foo() { return foo; }
|
||||
char *get_bar() { return bar; }
|
||||
EOF
|
||||
|
||||
cat <<EOF | $CC -o $t/c.o -c -xc - -mtls-dialect=desc
|
||||
#include <stdio.h>
|
||||
char *get_foo();
|
||||
char *get_bar();
|
||||
int main() { printf("%s %s\n", get_foo(), get_bar()); }
|
||||
EOF
|
||||
|
||||
#
|
||||
# Local TLS in an executable: TLSDESC => LE
|
||||
#
|
||||
$CC -B. -o $t/exe1 $t/a.o $t/b.o $t/c.o -Wl,--emit-relocs,--relax
|
||||
$QEMU $t/exe1 | grep -F 'foo bar'
|
||||
|
||||
$OBJDUMP -dr $t/exe1 > $t/exe1.objdump
|
||||
|
||||
# The ADD/BLR became MOVZ/MOVK that build the TP-relative offset.
|
||||
grep -Fw R_AARCH64_TLSLE_MOVW_TPREL_G1 $t/exe1.objdump
|
||||
grep -Fw R_AARCH64_TLSLE_MOVW_TPREL_G0_NC $t/exe1.objdump
|
||||
|
||||
# No TLSDESC relocation survives.
|
||||
not grep -Fw R_AARCH64_TLSDESC_ADR_PAGE21 $t/exe1.objdump
|
||||
not grep -Fw R_AARCH64_TLSDESC_LD64_LO12 $t/exe1.objdump
|
||||
not grep -Fw R_AARCH64_TLSDESC_ADD_LO12 $t/exe1.objdump
|
||||
not grep -Fw R_AARCH64_TLSDESC_CALL $t/exe1.objdump
|
||||
|
||||
# The G1 relocation sits on a movz and the G0_NC on a movk, not on the leading
|
||||
# adrp/ldr (which are now nops).
|
||||
awk '
|
||||
$3 == "movz" || $3 == "movk" || $3 == "nop" { insn[$1] = $3 }
|
||||
$2 == "R_AARCH64_TLSLE_MOVW_TPREL_G1" { if (insn[$1] != "movz") { bad=1; print "bad offset: " $0 } }
|
||||
$2 == "R_AARCH64_TLSLE_MOVW_TPREL_G0_NC" { if (insn[$1] != "movk") { bad=1; print "bad offset: " $0 } }
|
||||
END { exit bad+0 }
|
||||
' $t/exe1.objdump
|
||||
|
||||
#
|
||||
# TLS defined in a shared library: TLSDESC => IE
|
||||
#
|
||||
$CC -B. -shared -o $t/d.so $t/a.o -Wl,--relax
|
||||
$CC -B. -o $t/exe2 $t/b.o $t/c.o $t/d.so -Wl,--emit-relocs,--relax -Wl,-rpath=$t
|
||||
$QEMU $t/exe2 | grep -F 'foo bar'
|
||||
|
||||
$OBJDUMP -dr $t/exe2 > $t/exe2.objdump
|
||||
|
||||
# The ADD/BLR became ADRP/LDR that load the address from the GOT.
|
||||
grep -Fw R_AARCH64_TLSIE_ADR_GOTTPREL_PAGE21 $t/exe2.objdump
|
||||
grep -Fw R_AARCH64_TLSIE_LD64_GOTTPREL_LO12_NC $t/exe2.objdump
|
||||
not grep -Fw R_AARCH64_TLSDESC_ADD_LO12 $t/exe2.objdump
|
||||
not grep -Fw R_AARCH64_TLSDESC_CALL $t/exe2.objdump
|
||||
|
||||
awk '
|
||||
$3 == "adrp" || $3 == "ldr" || $3 == "nop" { insn[$1] = $3 }
|
||||
$2 == "R_AARCH64_TLSIE_ADR_GOTTPREL_PAGE21" { if (insn[$1] != "adrp") { bad=1; print "bad offset: " $0 } }
|
||||
$2 == "R_AARCH64_TLSIE_LD64_GOTTPREL_LO12_NC" { if (insn[$1] != "ldr") { bad=1; print "bad offset: " $0 } }
|
||||
END { exit bad+0 }
|
||||
' $t/exe2.objdump
|
||||
|
||||
#
|
||||
# Relocatable output: no relaxation happens and TLSDESC is not downgraded, so
|
||||
# every relocation must be passed through unchanged rather than rewritten as if
|
||||
# it had been relaxed to LE/IE.
|
||||
#
|
||||
$CC -B. -o $t/reloc.o $t/b.o -r
|
||||
$OBJDUMP -r $t/reloc.o > $t/reloc.objdump
|
||||
grep -Fw R_AARCH64_TLSDESC_ADR_PAGE21 $t/reloc.objdump
|
||||
grep -Fw R_AARCH64_TLSDESC_LD64_LO12 $t/reloc.objdump
|
||||
grep -Fw R_AARCH64_TLSDESC_ADD_LO12 $t/reloc.objdump
|
||||
grep -Fw R_AARCH64_TLSDESC_CALL $t/reloc.objdump
|
||||
not grep -Fw R_AARCH64_TLSLE_MOVW_TPREL_G1 $t/reloc.objdump
|
||||
not grep -Fw R_AARCH64_TLSIE_ADR_GOTTPREL_PAGE21 $t/reloc.objdump
|
||||
@@ -1,4 +1,4 @@
|
||||
#!/bin/bash
|
||||
#!/usr/bin/env bash
|
||||
. $(dirname $0)/common.inc
|
||||
|
||||
cat <<EOF > $t/a.c
|
||||
@@ -7,8 +7,8 @@ cat <<EOF > $t/a.c
|
||||
void fn3();
|
||||
void fn4();
|
||||
|
||||
__attribute__((section(".low"))) void fn1() { printf(" fn1"); fn3(); }
|
||||
__attribute__((section(".low"))) void fn2() { printf(" fn2"); fn4(); }
|
||||
__attribute__((section(SEC1))) void fn1() { printf(" fn1"); fn3(); }
|
||||
__attribute__((section(SEC1))) void fn2() { printf(" fn2"); fn4(); }
|
||||
|
||||
int main() {
|
||||
printf(" main");
|
||||
@@ -23,29 +23,36 @@ cat <<EOF > $t/b.c
|
||||
void fn1();
|
||||
void fn2();
|
||||
|
||||
__attribute__((section(".high"))) void fn3() { printf(" fn3"); fn2(); }
|
||||
__attribute__((section(".high"))) void fn4() { printf(" fn4"); }
|
||||
__attribute__((section(SEC2))) void fn3() { printf(" fn3"); fn2(); }
|
||||
__attribute__((section(SEC2))) void fn4() { printf(" fn4"); }
|
||||
EOF
|
||||
|
||||
$CC -c -o $t/c.o $t/a.c
|
||||
$CC -c -o $t/d.o $t/b.c
|
||||
# .high is placed billions of bytes away from the rest of the program.
|
||||
# Functions there cannot have unwind tables because an FDE refers to its
|
||||
# function with a 32-bit PC-relative relocation. We put fn1 and fn2 in
|
||||
# either section to test calls in both directions.
|
||||
flags="-fno-asynchronous-unwind-tables -fno-unwind-tables"
|
||||
starts="-Wl,--section-start=.low=0x10000000,--section-start=.high=0x100000000"
|
||||
|
||||
$CC -B. -o $t/exe1 $t/c.o $t/d.o \
|
||||
-Wl,--section-start=.low=0x10000000,--section-start=.high=0x100000000
|
||||
$CC -c -o $t/c.o $t/a.c $flags -DSEC1='".low"' -DSEC2='".high"'
|
||||
$CC -c -o $t/d.o $t/b.c $flags -DSEC1='".low"' -DSEC2='".high"'
|
||||
$CC -B. -o $t/exe1 $t/c.o $t/d.o $starts
|
||||
$QEMU $t/exe1 | grep 'main fn1 fn3 fn2 fn4'
|
||||
|
||||
$CC -B. -o $t/exe2 $t/c.o $t/d.o \
|
||||
-Wl,--section-start=.high=0x10000000,--section-start=.low=0x100000000
|
||||
$CC -c -o $t/e.o $t/a.c $flags -DSEC1='".high"' -DSEC2='".low"'
|
||||
$CC -c -o $t/f.o $t/b.c $flags -DSEC1='".high"' -DSEC2='".low"'
|
||||
$CC -B. -o $t/exe2 $t/e.o $t/f.o $starts
|
||||
$QEMU $t/exe2 | grep 'main fn1 fn3 fn2 fn4'
|
||||
|
||||
flags="$flags -fno-PIC -mcmodel=large"
|
||||
starts="-Wl,--section-start=.low=0x10000000,--section-start=.high=0x400000000"
|
||||
|
||||
$CC -c -o $t/e.o $t/a.c -fno-PIC -mcmodel=large
|
||||
$CC -c -o $t/f.o $t/b.c -fno-PIC -mcmodel=large
|
||||
|
||||
$CC -B. -o $t/exe3 $t/e.o $t/f.o -pie \
|
||||
-Wl,--section-start=.low=0x10000000,--section-start=.high=0x400000000
|
||||
$CC -c -o $t/g.o $t/a.c $flags -DSEC1='".low"' -DSEC2='".high"'
|
||||
$CC -c -o $t/h.o $t/b.c $flags -DSEC1='".low"' -DSEC2='".high"'
|
||||
$CC -B. -o $t/exe3 $t/g.o $t/h.o -pie $starts
|
||||
$QEMU $t/exe3 | grep 'main fn1 fn3 fn2 fn4'
|
||||
|
||||
$CC -B. -o $t/exe4 $t/e.o $t/f.o -pie \
|
||||
-Wl,--section-start=.high=0x10000000,--section-start=.low=0x400000000
|
||||
$CC -c -o $t/i.o $t/a.c $flags -DSEC1='".high"' -DSEC2='".low"'
|
||||
$CC -c -o $t/j.o $t/b.c $flags -DSEC1='".high"' -DSEC2='".low"'
|
||||
$CC -B. -o $t/exe4 $t/i.o $t/j.o -pie $starts
|
||||
$QEMU $t/exe4 | grep 'main fn1 fn3 fn2 fn4'
|
||||
@@ -1,4 +1,4 @@
|
||||
#!/bin/bash
|
||||
#!/usr/bin/env bash
|
||||
. $(dirname $0)/common.inc
|
||||
|
||||
[ $MACHINE = aarch64 ] || skip
|
||||
|
||||
@@ -1,4 +1,4 @@
|
||||
#!/bin/bash
|
||||
#!/usr/bin/env bash
|
||||
. $(dirname $0)/common.inc
|
||||
|
||||
cat <<EOF | $CC -c -o $t/a.o -fPIC -xc -
|
||||
|
||||
@@ -1,4 +1,4 @@
|
||||
#!/bin/bash
|
||||
#!/usr/bin/env bash
|
||||
. $(dirname $0)/common.inc
|
||||
|
||||
cat <<EOF | $CC -c -o $t/a.o -fPIC -xassembler - 2> /dev/null || skip
|
||||
|
||||
@@ -1,4 +1,4 @@
|
||||
#!/bin/bash
|
||||
#!/usr/bin/env bash
|
||||
. $(dirname $0)/common.inc
|
||||
|
||||
cat <<EOF | $CC -fPIC -c -o $t/a.o -xassembler - -mthumb
|
||||
|
||||
@@ -1,4 +1,4 @@
|
||||
#!/bin/bash
|
||||
#!/usr/bin/env bash
|
||||
. $(dirname $0)/common.inc
|
||||
|
||||
cat <<EOF | $CXX -o $t/a.o -c -xc++ - -fno-PIC
|
||||
|
||||
@@ -1,4 +1,4 @@
|
||||
#!/bin/bash
|
||||
#!/usr/bin/env bash
|
||||
. $(dirname $0)/common.inc
|
||||
|
||||
cat <<EOF | $CC -c -o $t/a.o -fPIC -xc -
|
||||
|
||||
@@ -1,4 +1,4 @@
|
||||
#!/bin/bash
|
||||
#!/usr/bin/env bash
|
||||
. $(dirname $0)/common.inc
|
||||
|
||||
test_cflags -mthumb || skip
|
||||
|
||||
@@ -1,4 +1,4 @@
|
||||
#!/bin/bash
|
||||
#!/usr/bin/env bash
|
||||
. $(dirname $0)/common.inc
|
||||
|
||||
cat <<EOF | $CC -c -o $t/a.o -xassembler -
|
||||
|
||||
@@ -1,4 +1,4 @@
|
||||
#!/bin/bash
|
||||
#!/usr/bin/env bash
|
||||
. $(dirname $0)/common.inc
|
||||
|
||||
cat <<EOF | $CC -o $t/a.o -c -xassembler -
|
||||
|
||||
@@ -1,4 +1,4 @@
|
||||
#!/bin/bash
|
||||
#!/usr/bin/env bash
|
||||
. $(dirname $0)/common.inc
|
||||
|
||||
cat <<EOF | $CC -o $t/a.o -c -xassembler -
|
||||
|
||||
@@ -1,4 +1,4 @@
|
||||
#!/bin/bash
|
||||
#!/usr/bin/env bash
|
||||
. $(dirname $0)/common.inc
|
||||
|
||||
test_cflags -mthumb || skip
|
||||
|
||||
Executable
+34
@@ -0,0 +1,34 @@
|
||||
#!/usr/bin/env bash
|
||||
. $(dirname $0)/common.inc
|
||||
|
||||
test_cflags -mthumb || skip
|
||||
|
||||
# Only function symbols indicate in their value whether they are Thumb or
|
||||
# ARM code. A branch to a symbol of another type, such as a plain label in
|
||||
# hand-written assembly, must not switch the instruction set.
|
||||
|
||||
cat <<EOF | $CC -o $t/a.o -c -xassembler -
|
||||
.syntax unified
|
||||
.thumb
|
||||
.globl foo
|
||||
foo:
|
||||
bx lr
|
||||
EOF
|
||||
|
||||
cat <<EOF | $CC -o $t/b.o -c -xc - -mthumb -O2
|
||||
#include <stdio.h>
|
||||
void foo();
|
||||
__attribute__((noinline)) void bar() { foo(); }
|
||||
int main() {
|
||||
foo();
|
||||
bar();
|
||||
printf("OK\n");
|
||||
}
|
||||
EOF
|
||||
|
||||
$CC -B. -o $t/exe $t/a.o $t/b.o
|
||||
$QEMU $t/exe | grep OK
|
||||
|
||||
$OBJDUMP -d $t/exe > $t/log
|
||||
grep -E '\bbl\b.*<foo>' $t/log
|
||||
grep -E '\bb\.w\b.*<foo>' $t/log
|
||||
@@ -1,4 +1,4 @@
|
||||
#!/bin/bash
|
||||
#!/usr/bin/env bash
|
||||
. $(dirname $0)/common.inc
|
||||
|
||||
is_musl && skip
|
||||
|
||||
@@ -1,4 +1,4 @@
|
||||
#!/bin/bash
|
||||
#!/usr/bin/env bash
|
||||
. $(dirname $0)/common.inc
|
||||
|
||||
cat <<EOF | $CC -o $t/a.o -c -xc -
|
||||
|
||||
@@ -1,4 +1,4 @@
|
||||
#!/bin/bash
|
||||
#!/usr/bin/env bash
|
||||
. $(dirname $0)/common.inc
|
||||
|
||||
# In the REL relocation format, an addend is read from the relocated
|
||||
|
||||
Executable
+32
@@ -0,0 +1,32 @@
|
||||
#!/usr/bin/env bash
|
||||
. $(dirname $0)/common.inc
|
||||
|
||||
# mold relaxes a GOT load of a non-preemptible symbol from
|
||||
# mov foo@GOT(%ebx), %reg => lea foo@GOTOFF(%ebx), %reg
|
||||
# With --emit-relocs the R_386_GOT32X relocation must be rewritten to
|
||||
# R_386_GOTOFF to match the lea (GNU ld does the same).
|
||||
|
||||
cat <<'EOF' | $CC -o $t/a.o -c -xc -
|
||||
int foo = 42;
|
||||
EOF
|
||||
|
||||
cat <<'EOF' | $CC -fPIC -O2 -o $t/b.o -c -xc -
|
||||
extern int foo;
|
||||
int get(void) { return foo; }
|
||||
EOF
|
||||
|
||||
cat <<'EOF' | $CC -o $t/c.o -c -xc -
|
||||
extern int get(void);
|
||||
int main(void) { return get() != 42; } // exits 0 iff foo resolved to 42
|
||||
EOF
|
||||
|
||||
$CC -B. -o $t/exe $t/a.o $t/b.o $t/c.o -no-pie -Wl,--emit-relocs
|
||||
$QEMU $t/exe
|
||||
|
||||
$OBJDUMP -dr $t/exe > $t/exe.objdump
|
||||
|
||||
# The GOT load of foo was relaxed and its relocation rewritten to GOTOFF. The
|
||||
# compiler only emits GOT32X for the extern access, so a GOTOFF naming foo can
|
||||
# only come from the relaxation.
|
||||
grep -E $'R_386_GOTOFF[ \t]+foo' $t/exe.objdump
|
||||
not grep -E $'R_386_GOT32X[ \t]+foo' $t/exe.objdump
|
||||
Executable
+31
@@ -0,0 +1,31 @@
|
||||
#!/usr/bin/env bash
|
||||
. $(dirname $0)/common.inc
|
||||
|
||||
# We once passed arguments to the relocation range checker in the wrong
|
||||
# order in non-alloc sections, so that the relocation index instead of the
|
||||
# relocation value was range-checked. Test both directions: many in-range
|
||||
# relocations must not be reported, and an out-of-range value must be.
|
||||
|
||||
cat <<'EOF' | $CC -c -o $t/a.o -xassembler -
|
||||
.globl main
|
||||
main:
|
||||
ret
|
||||
|
||||
.section .nonalloc
|
||||
.rept 300
|
||||
.byte small
|
||||
.endr
|
||||
EOF
|
||||
|
||||
$CC -B. -o $t/exe1 $t/a.o -no-pie -Wl,-defsym=small=16
|
||||
|
||||
cat <<'EOF' | $CC -c -o $t/b.o -xassembler -
|
||||
.globl main
|
||||
main:
|
||||
ret
|
||||
|
||||
.section .nonalloc
|
||||
.byte main
|
||||
EOF
|
||||
|
||||
not $CC -B. -o $t/exe2 $t/b.o -no-pie |& grep 'out of range'
|
||||
@@ -1,4 +1,4 @@
|
||||
#!/bin/bash
|
||||
#!/usr/bin/env bash
|
||||
. $(dirname $0)/common.inc
|
||||
|
||||
cat <<'EOF' | $CC -fPIC -o $t/a.o -c -xassembler -
|
||||
|
||||
@@ -1,4 +1,4 @@
|
||||
#!/bin/bash
|
||||
#!/usr/bin/env bash
|
||||
. $(dirname $0)/common.inc
|
||||
|
||||
supports_tlsdesc || skip
|
||||
|
||||
@@ -1,4 +1,4 @@
|
||||
#!/bin/bash
|
||||
#!/usr/bin/env bash
|
||||
. $(dirname $0)/common.inc
|
||||
|
||||
# When mold relaxes an instruction sequence, the relocations attached to the
|
||||
|
||||
@@ -1,4 +1,4 @@
|
||||
#!/bin/bash
|
||||
#!/usr/bin/env bash
|
||||
. $(dirname $0)/common.inc
|
||||
|
||||
# Depending on the symbol, mold relaxes a TLSDESC sequence into a local-exec
|
||||
|
||||
@@ -1,4 +1,4 @@
|
||||
#!/bin/bash
|
||||
#!/usr/bin/env bash
|
||||
. $(dirname $0)/common.inc
|
||||
|
||||
cat <<EOF | $CC -o $t/a.o -c -xc - -mcmodel=extreme
|
||||
|
||||
@@ -1,4 +1,4 @@
|
||||
#!/bin/bash
|
||||
#!/usr/bin/env bash
|
||||
. $(dirname $0)/common.inc
|
||||
|
||||
cat <<'EOF' | $CC -o $t/a.o -c -xassembler -
|
||||
|
||||
@@ -1,4 +1,4 @@
|
||||
#!/bin/bash
|
||||
#!/usr/bin/env bash
|
||||
. $(dirname $0)/common.inc
|
||||
|
||||
cat <<EOF | $CC -o $t/a.o -c -xc - -fPIC
|
||||
|
||||
@@ -1,4 +1,4 @@
|
||||
#!/bin/bash
|
||||
#!/usr/bin/env bash
|
||||
. $(dirname $0)/common.inc
|
||||
|
||||
# pcaddi takes a 20-bit immediate that is shifted left by 2 to form
|
||||
|
||||
@@ -1,4 +1,4 @@
|
||||
#!/bin/bash
|
||||
#!/usr/bin/env bash
|
||||
. $(dirname $0)/common.inc
|
||||
|
||||
cat <<'EOF' | $CC -o $t/a.o -c -xassembler -
|
||||
|
||||
@@ -1,4 +1,4 @@
|
||||
#!/bin/bash
|
||||
#!/usr/bin/env bash
|
||||
. $(dirname $0)/common.inc
|
||||
|
||||
cat <<'EOF' | $CC -o $t/a.o -c -xc - -fPIC
|
||||
|
||||
Executable
+17
@@ -0,0 +1,17 @@
|
||||
#!/usr/bin/env bash
|
||||
. $(dirname $0)/common.inc
|
||||
|
||||
# We support ELFv2 only for little-endian PPC64. A big-endian ELFv2 file
|
||||
# must be rejected instead of silently linked as ELFv1.
|
||||
# https://github.com/rui314/mold/issues/1498
|
||||
|
||||
[ $MACHINE = ppc64 ] || skip
|
||||
|
||||
cat <<EOF | $CC -mabi=elfv2 -c -o $t/a.o -xc - 2> /dev/null || skip
|
||||
int main() {}
|
||||
EOF
|
||||
|
||||
readelf -h $t/a.o | grep -q abiv2 || skip
|
||||
|
||||
! ./mold -m elf64ppc -o $t/exe $t/a.o 2> $t/log
|
||||
grep 'unknown machine type' $t/log
|
||||
Executable
+63
@@ -0,0 +1,63 @@
|
||||
#!/usr/bin/env bash
|
||||
. $(dirname $0)/common.inc
|
||||
|
||||
# The linker has to synthesize the _savefpr_N, _restfpr_N, _savevr_N and
|
||||
# _restvr_N routines that GCC calls from function prologues and epilogues
|
||||
# with -Os, just like the _savegpr0_N ones.
|
||||
|
||||
cat <<EOF | $CC -o $t/a.o -c -xassembler -
|
||||
.globl foo
|
||||
foo:
|
||||
bl _savefpr_14
|
||||
bl _restfpr_14
|
||||
bl _savefpr_29
|
||||
bl _restfpr_29
|
||||
bl _savevr_20
|
||||
bl _restvr_20
|
||||
bl _savevr_31
|
||||
bl _restvr_31
|
||||
EOF
|
||||
|
||||
cat <<EOF | $CC -o $t/b.o -c -xc -
|
||||
int main() {}
|
||||
EOF
|
||||
|
||||
$CC -B. -o $t/exe1 $t/a.o $t/b.o
|
||||
$OBJDUMP -d $t/exe1 > $t/log1
|
||||
grep -A1 '<_savefpr_14>:' $t/log1 | grep -F 'stfd f14,-144(r1)'
|
||||
grep -A2 '<_restfpr_29>:' $t/log1 | grep -F 'lfd f29,-24(r1)'
|
||||
grep -A2 '<_savevr_20>:' $t/log1 | grep -F 'stvx v20,r12,r0'
|
||||
grep -A2 '<_restvr_31>:' $t/log1 | grep -F 'lvx v31,r12,r0'
|
||||
|
||||
# A function that keeps many floating-point values live across calls
|
||||
# makes GCC use the routines with -Os.
|
||||
cat <<EOF | $CC -Os -o $t/c.o -c -xc -
|
||||
double g(double);
|
||||
double out[20];
|
||||
|
||||
void f(double a) {
|
||||
double r[20];
|
||||
for (int i = 0; i < 20; i++)
|
||||
r[i] = g(a + i);
|
||||
for (int i = 0; i < 20; i++)
|
||||
out[i] = r[i];
|
||||
}
|
||||
EOF
|
||||
|
||||
cat <<EOF | $CC -Os -o $t/d.o -c -xc -
|
||||
#include <stdio.h>
|
||||
extern double out[20];
|
||||
void f(double);
|
||||
double g(double x) { return x * 2; }
|
||||
|
||||
int main() {
|
||||
f(1);
|
||||
double sum = 0;
|
||||
for (int i = 0; i < 20; i++)
|
||||
sum += out[i];
|
||||
printf("%g\n", sum);
|
||||
}
|
||||
EOF
|
||||
|
||||
$CC -B. -o $t/exe2 $t/c.o $t/d.o
|
||||
$QEMU $t/exe2 | grep '^420$'
|
||||
@@ -1,4 +1,4 @@
|
||||
#!/bin/bash
|
||||
#!/usr/bin/env bash
|
||||
. $(dirname $0)/common.inc
|
||||
|
||||
cat <<EOF | $CC -o $t/a.o -c -xc -
|
||||
|
||||
@@ -1,4 +1,4 @@
|
||||
#!/bin/bash
|
||||
#!/usr/bin/env bash
|
||||
. $(dirname $0)/common.inc
|
||||
|
||||
cat <<EOF | $CC -march=rv64imafd_xtheadba1p5 -o $t/a.o -c -xc -
|
||||
|
||||
@@ -1,4 +1,4 @@
|
||||
#!/bin/bash
|
||||
#!/usr/bin/env bash
|
||||
. $(dirname $0)/common.inc
|
||||
|
||||
cat <<EOF | $CC -o $t/a.o -c -xc -
|
||||
|
||||
@@ -1,4 +1,4 @@
|
||||
#!/bin/bash
|
||||
#!/usr/bin/env bash
|
||||
. $(dirname $0)/common.inc
|
||||
|
||||
# When mold relaxes instructions, the relocations attached to the relaxed code
|
||||
|
||||
@@ -1,4 +1,4 @@
|
||||
#!/bin/bash
|
||||
#!/usr/bin/env bash
|
||||
. $(dirname $0)/common.inc
|
||||
|
||||
cat <<EOF | $CC -o $t/a.o -c -xassembler -
|
||||
|
||||
Loaded 100 of 1773 files, more files were not shown because too many files have changed in this diff.
Show more
Reference in new issue
Block a user