mirror of
https://github.com/neuml/txtai.git
synced 2026-10-12 02:19:52 +00:00
Compare commits
| Author | SHA1 | Date | |
|---|---|---|---|
 Hua.T |
e981d2d8fc | ||
|
PerryLink
|
55fadb4c56 | ||
|
Rızgar Ozan
|
fe5be99bfa | ||
|
David Mezzetti
|
243aaa191d | ||
|
leeshengis
|
93a767f004 | ||
|
davidmezzetti
|
62099b9a34 | ||
|
David Mezzetti
|
c786f1b5ec | ||
|
amengnew
|
738df97d5f | ||
|
Raphael Malikian
|
4605ee001f | ||
|
Rızgar Ozan
|
46516fa4e6 | ||
|
kartsan03
|
fe1fbbc933 | ||
|
Hua.T
|
084a1eca4d | ||
|
Muneeb Ullah
|
ba9d52310a | ||
|
Jasper
|
ca9563daac | ||
|
D41910
|
0e7202caee | ||
|
David Mezzetti
|
c1f1686889 | ||
|
kartsan03
|
04f5bf1998 | ||
|
Gaurav Chintakunta
|
c8e7d813af | ||
|
Yuilona
|
edf61d1d4a | ||
|
Raphael Malikian
|
7e92f5a7d7 | ||
|
Raashish Aggarwal
|
b2ff9bd85c | ||
|
Raashish Aggarwal
|
9c718f7876 | ||
|
Moinuddin Shaik
|
c486f4706e | ||
|
Lukas
|
341184ba46 | ||
|
Lukas
|
647d80f95e | ||
|
Yash Raj Pandey
|
408c25d201 | ||
|
davidmezzetti
|
b0f29a11d1 | ||
|
davidmezzetti
|
49a64943b8 | ||
|
David Mezzetti
|
af33f2e024 | ||
|
davidmezzetti
|
f908b5d88d | ||
|
David Mezzetti
|
2e8493dfca | ||
|
shabeeth2
|
d7e3e29ac3 | ||
|
Mohammad Hijjawi
|
4e2efa2cbc | ||
|
Gaurav Chintakunta
|
ffcbc0b815 | ||
|
tuanzirwar
|
f14c26c4c7 | ||
|
serhiizghama
|
346bb9d282 | ||
|
serhiizghama
|
e3e0413747 | ||
|
David Mezzetti
|
32655393e0 | ||
|
davidmezzetti
|
9118875980 | ||
|
Manobhi Sriram
|
d9b4476187 | ||
|
Grapette.L
|
ff5aec468a | ||
|
davidmezzetti
|
3446a4ef13 | ||
|
HuaTNA
|
84aa1c81c7 | ||
|
Lesereingrape
|
6bc76132d0 | ||
|
Morgan Carr
|
893d0424be | ||
|
Edson
|
98c965cc3b | ||
|
Yash Raj Pandey
|
00622f2cf1 | ||
|
Yash Raj Pandey
|
55d52fda92 | ||
|
Ni0ri
|
20c9b8e0be | ||
|
Mohammad Hijjawi
|
3f33fb2918 | ||
|
davidmezzetti
|
3c7a548923 | ||
|
Pablo Miguel Argudo
|
c78fbd976c | ||
|
David Mezzetti
|
2d535ff215 | ||
|
kartsan03
|
6765330f4a | ||
|
davidmezzetti
|
1d5041b6e7 | ||
|
davidmezzetti
|
d467878064 | ||
|
davidmezzetti
|
3bc07b3f09 | ||
|
Hua.T
|
8ef454d0bf | ||
|
Jin
|
47d3e65756 | ||
|
LimbC-C
|
81f908874b | ||
|
David Mezzetti
|
bed91a0b9f | ||
|
David Mezzetti
|
7df50abb61 | ||
|
David Mezzetti
|
80b8ceff4a | ||
|
David Mezzetti
|
de9e09e9ae | ||
|
Morgan Carr
|
69ede9ec3e | ||
|
Pablo Miguel Argudo
|
f8689ed903 | ||
|
bob
|
0abf3763b4 | ||
|
LimbC-C
|
11b2cfe298 | ||
|
LimbC-C
|
d0cc2bed9c | ||
|
LimbC-C
|
a5ea35d7a7 | ||
|
Yash Raj Pandey
|
6a15ed8490 | ||
|
David Mezzetti
|
76147369fb | ||
|
bob
|
2e89af0845 | ||
|
davidmezzetti
|
d9d6a1cbb1 | ||
|
davidmezzetti
|
f87574de4c | ||
|
Mohammad Hijjawi
|
e313248ff2 | ||
|
davidmezzetti
|
5cba72c88a | ||
|
davidmezzetti
|
45d334f4ce | ||
|
Jin
|
95d4c1c881 | ||
|
LimbC-C
|
ef28da8735 | ||
|
LimbC-C
|
f1304d8403 | ||
|
davidmezzetti
|
97ee7e073a | ||
|
LimbC-C
|
1d3f8e9ebf | ||
|
davidmezzetti
|
f3ceece76a | ||
|
Pablo Miguel Argudo
|
6737ee4e01 | ||
|
davidmezzetti
|
e30e8edbcc | ||
|
davidmezzetti
|
483dbd3b3b | ||
|
davidmezzetti
|
c09a6f24f1 | ||
|
davidmezzetti
|
6e7f0d260e | ||
|
davidmezzetti
|
793ecc8dc2 | ||
|
David Mezzetti
|
37500887ae | ||
|
David Mezzetti
|
4e2eb242b6 | ||
|
Jin
|
83c75ea28a | ||
|
LimbC-C
|
f47d389735 | ||
|
HuaTNA
|
4bb2141954 | ||
|
David Mezzetti
|
5d8c999ae0 | ||
|
HuaTNA
|
48a34e21c3 | ||
|
davidmezzetti
|
262b03027e | ||
|
刘冠杰
|
36c375b86e | ||
|
David Mezzetti
|
b715812e68 | ||
|
hylin
|
dcdded892d | ||
|
LimbC-C
|
e7894cdb00 | ||
|
LimbC-C
|
9f9b32e070 | ||
|
David Mezzetti
|
00167b9f08 | ||
|
dingpuyu
|
3c07766199 | ||
|
Amir Fathi
|
7cb6bd09db | ||
|
Caner Olcay
|
4b7d70e9e8 | ||
|
David Mezzetti
|
2ed4e46ebf | ||
|
LimbC-C
|
47d5f56768 | ||
|
serhiizghama
|
d5db643540 | ||
|
serhiizghama
|
9f7b4ddd42 | ||
|
Morgan Carr
|
19ff237c37 | ||
|
Morgan Carr
|
ad77514b32 | ||
|
davidmezzetti
|
144a957d42 | ||
|
Serhii Zghama
|
2e8a3d7892 | ||
|
Amir Fathi
|
72f9ca7605 | ||
|
Amir Fathi
|
ebe13ae304 | ||
|
Serhii Zghama
|
5d0e995f7f | ||
|
davidmezzetti
|
7965a7f42e | ||
|
Amir Fathi
|
2bae6e4d43 | ||
|
Morgan Carr
|
767272f2d5 | ||
|
Morgan Carr
|
21460347dd | ||
|
Morgan Carr
|
f3945f9120 | ||
|
Paco Cartones
|
3a7b597d78 | ||
|
Morgan Carr
|
20e2dc41e1 | ||
|
Morgan Carr
|
eafe574d92 | ||
|
Morgan Carr
|
7e98746d78 | ||
|
Morgan Carr
|
6ebfbbb716 | ||
|
David Mezzetti
|
8fef6ac454 | ||
|
davidmezzetti
|
0eafc0580f | ||
|
serhiizghama
|
5ade7881c8 | ||
|
serhiizghama
|
948dc42d19 | ||
|
David Mezzetti
|
2e8af221f4 | ||
|
Morgan Carr
|
396b3b8065 | ||
|
Morgan Carr
|
80420ee10a | ||
|
David Mezzetti
|
1d45e88569 | ||
|
Joe Bergin
|
007d61077a | ||
|
David Mezzetti
|
84fcd81039 | ||
|
morgan-coded
|
cfe2227f30 | ||
|
morgan-coded
|
82b5320da3 | ||
|
serhiizghama
|
18b93be702 | ||
|
serhiizghama
|
027c07deb9 | ||
|
Paco Cartones
|
876cd07cf7 | ||
|
davidmezzetti
|
546e7777f1 | ||
|
Yash Raj Pandey
|
27542ca64b | ||
|
David Mezzetti
|
f0ee7d2b2d | ||
|
morgan-coded
|
bba7fd589e | ||
|
David Mezzetti
|
6349ca2eac | ||
|
Evhye38496
|
ba1693480e | ||
|
Sainikhil Juluri
|
e90c67ef06 | ||
|
Amir Fathi
|
57991cb164 | ||
|
David Mezzetti
|
c2b264d297 | ||
|
serhiizghama
|
406e417be0 | ||
|
serhiizghama
|
954b17af4d | ||
|
davidmezzetti
|
2a139449dc | ||
|
davidmezzetti
|
a10667a1c2 | ||
|
davidmezzetti
|
34e6efcdd6 | ||
|
David Mezzetti
|
9b7a96b4d1 | ||
|
morgan-coded
|
b94f770301 | ||
|
Arnaud Thery
|
adbcccda46 | ||
|
David Mezzetti
|
20f818f72c | ||
|
morgan-coded
|
ee0416e87b | ||
|
morgan-coded
|
00ec81a10e | ||
|
davidmezzetti
|
059ecec2ee | ||
|
davidmezzetti
|
21c2c38b98 | ||
|
davidmezzetti
|
47c05994bf | ||
|
Kole Harvey
|
8f3735101b | ||
|
Aryan Pardeshi
|
438ade31b6 | ||
|
davidmezzetti
|
3ea197468d | ||
|
LHMQ878
|
99ebbdfea2 | ||
|
David Mezzetti
|
5570dbc7b6 | ||
|
FU-max-boop
|
01b456900a | ||
|
davidmezzetti
|
a0857e980a | ||
|
davidmezzetti
|
84be3476d8 | ||
|
davidmezzetti
|
f35d932979 | ||
|
Tai An
|
a1c9b94d00 | ||
|
Aryan Pardeshi
|
11ebacdb23 | ||
|
davidmezzetti
|
5986fa6082 | ||
|
davidmezzetti
|
893a333887 | ||
|
David Mezzetti
|
e54255f4e4 | ||
|
latent-9
|
f89835bc77 | ||
|
davidmezzetti
|
ea531b3420 | ||
|
davidmezzetti
|
756917f14b | ||
|
davidmezzetti
|
b1f4845284 | ||
|
David Mezzetti
|
d2b1d3634f | ||
|
morgan-coded
|
193facd144 | ||
|
morgan-coded
|
436662e32b | ||
|
morgan-coded
|
54644a0526 | ||
|
morgan-coded
|
817a2b142a | ||
|
morgan-coded
|
987cff001f | ||
|
David Mezzetti
|
8383e6ce8d | ||
|
morgan-coded
|
0be1231d8d | ||
|
David Mezzetti
|
79e277fb7d | ||
|
morgan-coded
|
f4472312ba | ||
|
morgan-coded
|
90f7cc2078 | ||
|
morgan-coded
|
ce11b08ab1 | ||
|
morgan-coded
|
75b4ce5c7f | ||
|
David Mezzetti
|
2ef401bb78 | ||
|
davidmezzetti
|
8c43c70687 | ||
|
David Mezzetti
|
48e22b593c | ||
|
davidmezzetti
|
3beea7f4bf | ||
|
morgan-coded
|
626cc8fbe0 | ||
|
davidmezzetti
|
21b9049c86 | ||
|
davidmezzetti
|
abf504f70e | ||
|
davidmezzetti
|
d9e9a9e684 | ||
|
Amir Fathi
|
bd199158b6 | ||
|
morgan-coded
|
390cc08b11 | ||
|
morgan-coded
|
feac4c8306 | ||
|
morgan-coded
|
d7f974b3d7 | ||
|
morgan-coded
|
d8fa848f73 | ||
|
morgan-coded
|
bbd23bb12c | ||
|
David Mezzetti
|
8362110c64 | ||
|
morgan-coded
|
83e1835b6d | ||
|
davidmezzetti
|
cf2368269f | ||
|
davidmezzetti
|
a910ddbbea | ||
|
davidmezzetti
|
7b49504dca | ||
|
davidmezzetti
|
86af7ec344 | ||
|
Amir Fathi
|
50ca7b2fde | ||
|
David Mezzetti
|
7c8d001492 | ||
|
weihong.xu
|
dea0a65fd1 | ||
|
davidmezzetti
|
a1224c06f1 | ||
|
davidmezzetti
|
162b65d3d9 | ||
|
davidmezzetti
|
363f8ca7cf | ||
|
davidmezzetti
|
1d084941f4 | ||
|
Andrew Chen
|
597ba8133d | ||
|
Andrew Chen
|
6bbb25872a | ||
|
davidmezzetti
|
f22bf5bbb5 | ||
|
davidmezzetti
|
83871c6fe3 | ||
|
davidmezzetti
|
2c6ec162d0 | ||
|
davidmezzetti
|
d59c88424d | ||
|
David Mezzetti
|
95c7b8df1e | ||
|
Loi Nguyen
|
2389b5946c | ||
|
Andrew Chen
|
b246b642c7 | ||
|
Andrew Chen
|
46467a3453 | ||
|
davidmezzetti
|
fcfd340ff1 | ||
|
Andrew Chen
|
77965f44dd | ||
|
Andrew Chen
|
7435297bac | ||
|
Andrew Chen
|
3bb34eae2e | ||
|
Andrew Chen
|
79a28641b2 | ||
|
Andrew Chen
|
7c77c134e2 | ||
|
Andrew Chen
|
d6f696d795 | ||
|
davidmezzetti
|
d8ae6776f8 | ||
|
davidmezzetti
|
e18e3d1245 | ||
|
Andrew Chen
|
ee0d1a0214 | ||
|
davidmezzetti
|
5ddedf07cd | ||
|
David Mezzetti
|
590c71f593 | ||
|
winklemad
|
c33188a0f8 | ||
|
davidmezzetti
|
638a2e12b1 | ||
|
morgan-coded
|
03da5c96fb | ||
|
morgan-coded
|
99086302ce | ||
|
davidmezzetti
|
2f11f93743 | ||
|
davidmezzetti
|
783d9cf680 | ||
|
David Mezzetti
|
281babeff7 | ||
|
David Mezzetti
|
a71732198a | ||
|
Morgan Carr
|
14cbe51e04 | ||
|
davidmezzetti
|
5d15f7fa66 | ||
|
davidmezzetti
|
ac2dc6a30b | ||
|
chuenchen309andClaude Opus 4.8
|
7791174c1b | ||
|
David Mezzetti
|
b21ba7065e | ||
|
chuenchen309andClaude Opus 4.8
|
10a6b23304 | ||
|
David Mezzetti
|
576f0ddcd7 | ||
|
chuenchen309andClaude Opus 4.8
|
9b8a606a16 | ||
|
davidmezzetti
|
01344b021c | ||
|
davidmezzetti
|
dd00608b9a | ||
|
davidmezzetti
|
702e0b880f | ||
|
davidmezzetti
|
14ac0e4cc5 | ||
|
davidmezzetti
|
1f28e5401d | ||
|
davidmezzetti
|
a84f0a388c | ||
|
davidmezzetti
|
510f9c18ed | ||
|
davidmezzetti
|
ae67f63359 | ||
|
davidmezzetti
|
0e16a22051 | ||
|
davidmezzetti
|
bfd0aa7ff4 | ||
|
davidmezzetti
|
ba2ea2db4e | ||
|
davidmezzetti
|
1daac761aa | ||
|
davidmezzetti
|
e9e65393a0 | ||
|
davidmezzetti
|
24ca4e36ca | ||
|
davidmezzetti
|
8208780b6a | ||
|
davidmezzetti
|
c3735dd5d4 | ||
|
davidmezzetti
|
6544d123f6 | ||
|
davidmezzetti
|
aa0a8cfc32 | ||
|
David Mezzetti
|
fc6f93828b | ||
|
Sanjay Santhanam
|
796c5bb0a8 | ||
|
davidmezzetti
|
7613acd6e5 | ||
|
davidmezzetti
|
9db11953c5 | ||
|
davidmezzetti
|
2ecf4412fc | ||
|
davidmezzetti
|
13b1a0f986 | ||
|
davidmezzetti
|
89d5207b6e | ||
|
davidmezzetti
|
21e6ab8e6a | ||
|
davidmezzetti
|
ae898e6905 | ||
|
davidmezzetti
|
7aee5f91af | ||
|
davidmezzetti
|
7844e2c597 | ||
|
davidmezzetti
|
f9bfc2cb0d | ||
|
David Mezzetti
|
535edaf3ad | ||
|
JSap0914
|
f507c442fd | ||
|
davidmezzetti
|
73e2f6ee51 | ||
|
davidmezzetti
|
bc8847edb0 | ||
|
davidmezzetti
|
d69b72492d | ||
|
davidmezzetti
|
e0ae1450b4 | ||
|
davidmezzetti
|
24c20cc0ff | ||
|
davidmezzetti
|
5f233d4a74 | ||
|
davidmezzetti
|
11b32da720 | ||
|
davidmezzetti
|
039568541b | ||
|
davidmezzetti
|
df53803cf7 | ||
|
davidmezzetti
|
3c4d32f8f7 | ||
|
davidmezzetti
|
68e1c5719e | ||
|
davidmezzetti
|
c3211fbce9 | ||
|
davidmezzetti
|
099b89114e | ||
|
davidmezzetti
|
0428a71243 | ||
|
davidmezzetti
|
4ce690d225 | ||
|
davidmezzetti
|
9bb4917c0e | ||
|
davidmezzetti
|
a3f95a6a26 | ||
|
davidmezzetti
|
e8000315c0 | ||
|
davidmezzetti
|
f9ddb23c10 | ||
|
davidmezzetti
|
1d058cf487 | ||
|
davidmezzetti
|
a5d097197e | ||
|
davidmezzetti
|
32e098af84 | ||
|
davidmezzetti
|
8844ec96b4 | ||
|
davidmezzetti
|
3e8e495bd2 | ||
|
davidmezzetti
|
9d5f82e824 | ||
|
davidmezzetti
|
57de5b3a94 | ||
|
davidmezzetti
|
e240d0bb02 | ||
|
davidmezzetti
|
08e3568d78 | ||
|
davidmezzetti
|
7ff55f32f7 | ||
|
davidmezzetti
|
0ca702cea2 | ||
|
davidmezzetti
|
bb8e9f8a03 | ||
|
davidmezzetti
|
f2ab0087d5 | ||
|
davidmezzetti
|
47620b194a | ||
|
davidmezzetti
|
798ff2e0ed | ||
|
davidmezzetti
|
345aea0544 | ||
|
davidmezzetti
|
65b72bfdfa | ||
|
davidmezzetti
|
b14229c1da | ||
|
davidmezzetti
|
a0e2c9e4ab | ||
|
davidmezzetti
|
d0ddedc048 | ||
|
davidmezzetti
|
6d15bd404a | ||
|
davidmezzetti
|
20fff84a7e | ||
|
davidmezzetti
|
8643baec3e | ||
|
davidmezzetti
|
40c92c15d6 | ||
|
davidmezzetti
|
8745aca849 | ||
|
davidmezzetti
|
109a4d3c66 | ||
|
davidmezzetti
|
676b997f57 | ||
|
davidmezzetti
|
2f8860afde | ||
|
davidmezzetti
|
688734136c | ||
|
davidmezzetti
|
1109094c78 | ||
|
davidmezzetti
|
cfbf235f54 | ||
|
davidmezzetti
|
c10a042cc3 | ||
|
davidmezzetti
|
f0715869a4 | ||
|
davidmezzetti
|
fbce87b9ee | ||
|
davidmezzetti
|
0c6cb615d2 | ||
|
davidmezzetti
|
8e569462f2 | ||
|
davidmezzetti
|
12c8b52b5e | ||
|
davidmezzetti
|
a67870aefd | ||
|
davidmezzetti
|
40da21b2c3 | ||
|
davidmezzetti
|
7b055c5b26 | ||
|
davidmezzetti
|
6971dc422b | ||
|
davidmezzetti
|
511f479251 | ||
|
davidmezzetti
|
c2e2f5d86e | ||
|
davidmezzetti
|
efb0006793 | ||
|
davidmezzetti
|
04153bd737 | ||
|
davidmezzetti
|
f2e02dff4a | ||
|
davidmezzetti
|
b0b181d7e8 | ||
|
davidmezzetti
|
fe916d0049 | ||
|
davidmezzetti
|
a44dbd1809 | ||
|
davidmezzetti
|
ba6d67498b | ||
|
davidmezzetti
|
1e731c3eb7 | ||
|
davidmezzetti
|
354b881318 | ||
|
davidmezzetti
|
8fcfa6363a | ||
|
davidmezzetti
|
d582bf335b | ||
|
davidmezzetti
|
7e3c0e16a4 | ||
|
davidmezzetti
|
d12a6681ea | ||
|
davidmezzetti
|
80b90cdbd6 | ||
|
davidmezzetti
|
6343779678 | ||
|
davidmezzetti
|
2d50a4c202 | ||
|
davidmezzetti
|
d2b3758005 | ||
|
davidmezzetti
|
4c03a8106f | ||
|
davidmezzetti
|
8f583b2446 | ||
|
davidmezzetti
|
e9c34adde3 | ||
|
davidmezzetti
|
6ee6656d40 | ||
|
davidmezzetti
|
f388ecb4a1 | ||
|
davidmezzetti
|
1a0b11654b | ||
|
JiangNan
|
79908eee5a | ||
|
davidmezzetti
|
69cc7538ac | ||
|
davidmezzetti
|
0e3b7ff959 | ||
|
davidmezzetti
|
cd116aaa57 | ||
|
davidmezzetti
|
d1aa381e0e | ||
|
davidmezzetti
|
96234c5754 | ||
|
davidmezzetti
|
312f1653e7 | ||
|
davidmezzetti
|
5cd7d7e407 | ||
|
davidmezzetti
|
1a64d33823 | ||
|
davidmezzetti
|
3073589ad6 | ||
|
davidmezzetti
|
2f2bd50027 | ||
|
davidmezzetti
|
f7380f64da | ||
|
davidmezzetti
|
a53b431492 | ||
|
davidmezzetti
|
2c937db56b | ||
|
Jaepil Jeong
|
ba0d1eaead | ||
|
davidmezzetti
|
89299926bd | ||
|
davidmezzetti
|
00acd243b0 | ||
|
Jaepil Jeong
|
48f0962a44 | ||
|
davidmezzetti
|
1c181e4070 | ||
|
davidmezzetti
|
371d5d8a19 | ||
|
davidmezzetti
|
834e4eb60d | ||
|
davidmezzetti
|
fc579d77aa | ||
|
Sigrid Jin (ง'̀-'́)ง oO
|
90e66075f6 | ||
|
davidmezzetti
|
99339570cb | ||
|
davidmezzetti
|
38170a4ab1 | ||
|
Rin
|
5a66065b34 | ||
|
davidmezzetti
|
090937a396 | ||
|
davidmezzetti
|
d6bd6fc4c6 | ||
|
davidmezzetti
|
90bee00f1d | ||
|
davidmezzetti
|
f013ca7d1d | ||
|
davidmezzetti
|
bfd1f13f2b | ||
|
davidmezzetti
|
f682fd949a | ||
|
davidmezzetti
|
4758907f3b | ||
|
davidmezzetti
|
b9cec19941 | ||
|
davidmezzetti
|
b7c9b156f6 | ||
|
davidmezzetti
|
361b6fe2a5 | ||
|
davidmezzetti
|
45e6080999 | ||
|
davidmezzetti
|
92461fe651 | ||
|
davidmezzetti
|
3a46f51f25 | ||
|
davidmezzetti
|
67543ab31c | ||
|
davidmezzetti
|
14c440ac45 | ||
|
davidmezzetti
|
7672f42743 | ||
|
davidmezzetti
|
f360c2d98e | ||
|
davidmezzetti
|
b4c80cf2e8 | ||
|
davidmezzetti
|
831c3fd7d2 | ||
|
davidmezzetti
|
d3c498f316 | ||
|
davidmezzetti
|
001b97b0bf | ||
|
davidmezzetti
|
c48ecb3062 | ||
|
davidmezzetti
|
f7d5790d07 | ||
|
davidmezzetti
|
5e3492799b | ||
|
davidmezzetti
|
2c3a21490a | ||
|
davidmezzetti
|
846cf2ddc7 | ||
|
davidmezzetti
|
ceb7a4a8f8 | ||
|
davidmezzetti
|
79e2f9bdef | ||
|
davidmezzetti
|
8d8b29e41c | ||
|
davidmezzetti
|
bd2a516eb4 | ||
|
davidmezzetti
|
d4e8ee41f4 | ||
|
davidmezzetti
|
cdf9a40c8e | ||
|
davidmezzetti
|
a6c64a6944 | ||
|
davidmezzetti
|
7132f63c46 | ||
|
davidmezzetti
|
1ff636de4a | ||
|
davidmezzetti
|
2a63caf83e | ||
|
davidmezzetti
|
86e768bccb | ||
|
davidmezzetti
|
995428d96c | ||
|
davidmezzetti
|
7b97ddf9d8 | ||
|
davidmezzetti
|
172f804c1b | ||
|
davidmezzetti
|
17b4660abe | ||
|
davidmezzetti
|
8c22567d10 | ||
|
davidmezzetti
|
1d7b6a98c9 | ||
|
davidmezzetti
|
1545901d27 | ||
|
davidmezzetti
|
c4b2bc4251 | ||
|
davidmezzetti
|
6021194ac9 | ||
|
davidmezzetti
|
9d4772bb65 | ||
|
davidmezzetti
|
a8507d024d | ||
|
davidmezzetti
|
0c2eab7098 | ||
|
davidmezzetti
|
4aa9db69fc | ||
|
davidmezzetti
|
aca56cfe53 | ||
|
davidmezzetti
|
203855a9d7 | ||
|
davidmezzetti
|
861545a1ed | ||
|
davidmezzetti
|
92d02d748d | ||
|
davidmezzetti
|
75c4f54f63 | ||
|
davidmezzetti
|
5d6d3f7a6b | ||
|
davidmezzetti
|
48584abdb4 | ||
|
davidmezzetti
|
1c4f041b91 | ||
|
davidmezzetti
|
4ba611760d | ||
|
davidmezzetti
|
c61e18a216 | ||
|
davidmezzetti
|
fb257a2e5e | ||
|
davidmezzetti
|
c26a61dcb6 | ||
|
davidmezzetti
|
b5b3922464 | ||
|
davidmezzetti
|
441d0eabd7 | ||
|
davidmezzetti
|
4d6c0ecc47 | ||
|
davidmezzetti
|
dd83a40197 | ||
|
davidmezzetti
|
58664444a1 | ||
|
davidmezzetti
|
0a401cb9a2 | ||
|
davidmezzetti
|
d3d26a5ebd | ||
|
davidmezzetti
|
d75be702dd | ||
|
davidmezzetti
|
60755501f5 | ||
|
davidmezzetti
|
e0f8a9404f | ||
|
davidmezzetti
|
26ac43df1c | ||
|
davidmezzetti
|
b8da57eb88 | ||
|
davidmezzetti
|
d3a5217153 | ||
|
davidmezzetti
|
99e3457b1f | ||
|
davidmezzetti
|
b870a3265a | ||
|
davidmezzetti
|
81c152c5ee | ||
|
davidmezzetti
|
90efb5c349 | ||
|
davidmezzetti
|
351702249b | ||
|
davidmezzetti
|
bb37634f8c | ||
|
davidmezzetti
|
594145840f | ||
|
davidmezzetti
|
4447053dd4 | ||
|
davidmezzetti
|
8794d714cc | ||
|
davidmezzetti
|
62a7ade776 | ||
|
davidmezzetti
|
8a01cd2c06 | ||
|
davidmezzetti
|
02bae7ddf1 | ||
|
davidmezzetti
|
1f8e9c5ddb | ||
|
davidmezzetti
|
d64c8d8f27 | ||
|
davidmezzetti
|
fc69c82b94 | ||
|
davidmezzetti
|
75f68c375d | ||
|
davidmezzetti
|
e715b3b4f6 | ||
|
davidmezzetti
|
ce3bdfaee6 | ||
|
davidmezzetti
|
6fa604213b | ||
|
davidmezzetti
|
536a724764 | ||
|
davidmezzetti
|
de3fee46e6 | ||
|
davidmezzetti
|
0a074ae559 | ||
|
davidmezzetti
|
f4f267d449 | ||
|
davidmezzetti
|
cf45a400ce | ||
|
davidmezzetti
|
a07b88f003 | ||
|
davidmezzetti
|
3bc7890360 | ||
|
davidmezzetti
|
e5519d25c3 | ||
|
davidmezzetti
|
e662a631e2 | ||
|
davidmezzetti
|
fb5c3cc468 | ||
|
davidmezzetti
|
1d8c941d1b | ||
|
davidmezzetti
|
13715059dc | ||
|
davidmezzetti
|
e6e1d57ac4 | ||
|
davidmezzetti
|
2c45420a70 | ||
|
davidmezzetti
|
8dcab1addc | ||
|
davidmezzetti
|
7c96fd93d9 | ||
|
davidmezzetti
|
31b6b767fd | ||
|
davidmezzetti
|
612d1ad2f8 | ||
|
davidmezzetti
|
f4d00c75a5 | ||
|
davidmezzetti
|
0d96790a64 | ||
|
davidmezzetti
|
9a1a1e400c | ||
|
davidmezzetti
|
a543b028ef | ||
|
davidmezzetti
|
8ae88a6405 | ||
|
davidmezzetti
|
97e4bdb2b4 | ||
|
davidmezzetti
|
741f39495e | ||
|
davidmezzetti
|
646af6ba87 | ||
|
davidmezzetti
|
fc15901cee | ||
|
davidmezzetti
|
97f3175ddf | ||
|
davidmezzetti
|
3a4457f563 | ||
|
davidmezzetti
|
d523a860fa | ||
|
davidmezzetti
|
e7e44c00e6 | ||
|
davidmezzetti
|
a5eca34c98 | ||
|
davidmezzetti
|
e09c205d70 | ||
|
davidmezzetti
|
6bef6869f5 | ||
|
davidmezzetti
|
a5306ae5d7 | ||
|
davidmezzetti
|
303a257615 | ||
|
davidmezzetti
|
f082bf2a27 | ||
|
davidmezzetti
|
4c698b3638 | ||
|
davidmezzetti
|
4e33678099 | ||
|
davidmezzetti
|
3734404449 | ||
|
davidmezzetti
|
ffa4543b2f | ||
|
davidmezzetti
|
5174079c93 | ||
|
davidmezzetti
|
9ef94c8c79 | ||
|
davidmezzetti
|
ba15148b83 | ||
|
davidmezzetti
|
1f5a352261 | ||
|
davidmezzetti
|
1f5f9cd406 | ||
|
davidmezzetti
|
549632b461 | ||
|
davidmezzetti
|
c4152ff4e1 | ||
|
davidmezzetti
|
b8980bc5be | ||
|
davidmezzetti
|
0e54ad3c3f | ||
|
davidmezzetti
|
34e468e475 | ||
|
davidmezzetti
|
28273d0369 | ||
|
davidmezzetti
|
c68c136b2d | ||
|
davidmezzetti
|
6fcdcb1e38 | ||
|
davidmezzetti
|
2866dd962e | ||
|
davidmezzetti
|
1b1ab4c9ea | ||
|
davidmezzetti
|
ad55344f26 | ||
|
davidmezzetti
|
2956bd8789 | ||
|
davidmezzetti
|
b53c966fa7 | ||
|
davidmezzetti
|
cd784436ef | ||
|
davidmezzetti
|
5cf22c648d | ||
|
davidmezzetti
|
f04a43578b | ||
|
davidmezzetti
|
944ef19276 | ||
|
davidmezzetti
|
da5baa2479 | ||
|
davidmezzetti
|
9b935a24d1 | ||
|
davidmezzetti
|
6cf12b97a0 | ||
|
davidmezzetti
|
1edf3ecc4c | ||
|
davidmezzetti
|
399f584d44 | ||
|
davidmezzetti
|
dc57d6bf0d | ||
|
davidmezzetti
|
e765be3f6c | ||
|
davidmezzetti
|
af264bd0bb | ||
|
davidmezzetti
|
db60bd76e6 | ||
|
davidmezzetti
|
69145bf98e | ||
|
davidmezzetti
|
9c3bf13d39 | ||
|
davidmezzetti
|
a1df111bb8 | ||
|
davidmezzetti
|
e9fa455206 | ||
|
davidmezzetti
|
23e37b4b51 | ||
|
davidmezzetti
|
2549c6598d | ||
|
davidmezzetti
|
5f774b5fd9 | ||
|
davidmezzetti
|
2d0ae9c749 | ||
|
davidmezzetti
|
fdd37c9afa | ||
|
davidmezzetti
|
6ca8a61856 | ||
|
davidmezzetti
|
d9c50c84b7 | ||
|
davidmezzetti
|
397ed4d321 | ||
|
davidmezzetti
|
0aa285848d | ||
|
davidmezzetti
|
10c524c56b | ||
|
davidmezzetti
|
dd8ff3078a | ||
|
davidmezzetti
|
d25209fd89 | ||
|
davidmezzetti
|
255164992a | ||
|
davidmezzetti
|
7fb9c9fd29 | ||
|
davidmezzetti
|
fa924845e8 | ||
|
davidmezzetti
|
fa6a0fdd3c | ||
|
davidmezzetti
|
01b667ad7e | ||
|
davidmezzetti
|
34ba105110 | ||
|
davidmezzetti
|
77eb913d12 | ||
|
davidmezzetti
|
7fffd5e435 | ||
|
davidmezzetti
|
24b0b7ceca | ||
|
davidmezzetti
|
61fa8a3f99 | ||
|
davidmezzetti
|
a55460a9cb | ||
|
davidmezzetti
|
71cf97d104 | ||
|
davidmezzetti
|
484b366608 | ||
|
davidmezzetti
|
1777f6aca7 | ||
|
davidmezzetti
|
203cbecc60 | ||
|
davidmezzetti
|
d34fb4b2e2 | ||
|
davidmezzetti
|
c080f1d4b0 | ||
|
davidmezzetti
|
6ae346e736 | ||
|
davidmezzetti
|
f71fa1fd5e | ||
|
davidmezzetti
|
6d0891b4fa | ||
|
davidmezzetti
|
80a8076c2b | ||
|
davidmezzetti
|
a5468af853 | ||
|
davidmezzetti
|
529dc446f9 | ||
|
davidmezzetti
|
8917c0dab0 | ||
|
davidmezzetti
|
80811ef9f3 | ||
|
davidmezzetti
|
97a5192cdf | ||
|
davidmezzetti
|
9647c7e918 | ||
|
davidmezzetti
|
19a4b7571f | ||
|
davidmezzetti
|
1d1fc36163 | ||
|
davidmezzetti
|
b18854f788 | ||
|
davidmezzetti
|
408a053001 | ||
|
davidmezzetti
|
a6d6231d74 | ||
|
davidmezzetti
|
a3f0896961 | ||
|
davidmezzetti
|
642ef2307a | ||
|
davidmezzetti
|
6368af1591 | ||
|
davidmezzetti
|
6a10aa88d0 | ||
|
davidmezzetti
|
1f65a64dc3 | ||
|
davidmezzetti
|
c50d8fd96d | ||
|
davidmezzetti
|
04795b614b | ||
|
davidmezzetti
|
a78b3b298f | ||
|
davidmezzetti
|
20ac850ec9 | ||
|
davidmezzetti
|
15ee408db8 | ||
|
davidmezzetti
|
e97237ab29 | ||
|
davidmezzetti
|
15bb6346cf | ||
|
davidmezzetti
|
a211f0e1ca | ||
|
davidmezzetti
|
76d39bfe10 | ||
|
davidmezzetti
|
675eea9b92 | ||
|
davidmezzetti
|
1bc1c59786 | ||
|
davidmezzetti
|
d902ee996b | ||
|
davidmezzetti
|
3517704d1a | ||
|
davidmezzetti
|
3ddb3e12ba | ||
|
davidmezzetti
|
fa2f114dee | ||
|
davidmezzetti
|
4a1aa4d0f6 | ||
|
davidmezzetti
|
e7cafe3fd7 | ||
|
davidmezzetti
|
bbf474314b | ||
|
davidmezzetti
|
13ab0c3b9e | ||
|
davidmezzetti
|
186e58a114 | ||
|
davidmezzetti
|
34fa089e68 | ||
|
davidmezzetti
|
679e0cef89 | ||
|
davidmezzetti
|
6301617cd8 | ||
|
davidmezzetti
|
1524b74a6b | ||
|
davidmezzetti
|
437ee1c15b | ||
|
davidmezzetti
|
13ec1e10fa | ||
|
davidmezzetti
|
a9833d0d67 | ||
|
davidmezzetti
|
04d4bc43aa | ||
|
davidmezzetti
|
f880793ae3 | ||
|
davidmezzetti
|
ba552d5a3f | ||
|
davidmezzetti
|
1a9f5eaded | ||
|
davidmezzetti
|
a1a7d34cd8 | ||
|
davidmezzetti
|
8a3ed27bbb | ||
|
davidmezzetti
|
a92bb73c9c | ||
|
davidmezzetti
|
4d92dfc965 | ||
|
davidmezzetti
|
1d077898ca | ||
|
davidmezzetti
|
53f5af52ad | ||
|
davidmezzetti
|
64c1a5c5c7 | ||
|
davidmezzetti
|
b72b04a972 | ||
|
davidmezzetti
|
a68a1338eb | ||
|
davidmezzetti
|
cc5d16df88 | ||
|
davidmezzetti
|
870c7007f6 | ||
|
davidmezzetti
|
7dc1e4bb5f | ||
|
davidmezzetti
|
53fa7ad872 | ||
|
davidmezzetti
|
d7f8210d16 | ||
|
davidmezzetti
|
bd16c6e25c | ||
|
davidmezzetti
|
f52ce51413 | ||
|
davidmezzetti
|
2cd8989183 | ||
|
davidmezzetti
|
61ca27a128 | ||
|
davidmezzetti
|
5049f0447a | ||
|
davidmezzetti
|
ce36fef822 | ||
|
davidmezzetti
|
bf32498a79 | ||
|
davidmezzetti
|
6e55f7a862 | ||
|
davidmezzetti
|
44fb2f9d9f | ||
|
davidmezzetti
|
2b6aa5f363 | ||
|
davidmezzetti
|
13bafb01c6 | ||
|
davidmezzetti
|
ac4c0583e8 | ||
|
davidmezzetti
|
e2e81cd2e3 | ||
|
davidmezzetti
|
fb56af8973 | ||
|
davidmezzetti
|
8fb3aba425 | ||
|
davidmezzetti
|
986da4700a | ||
|
davidmezzetti
|
5887f5f247 | ||
|
davidmezzetti
|
f79d8062ae | ||
|
davidmezzetti
|
12aa955b77 | ||
|
davidmezzetti
|
99df8c0901 | ||
|
davidmezzetti
|
dca693828b | ||
|
davidmezzetti
|
77649d5f30 | ||
|
davidmezzetti
|
8fc52f23ba | ||
|
davidmezzetti
|
39609f3ef9 | ||
|
davidmezzetti
|
ece8e6f8f2 | ||
|
davidmezzetti
|
ac5d04f86b | ||
|
davidmezzetti
|
91cee347f5 | ||
|
davidmezzetti
|
f9b9efa5f6 | ||
|
davidmezzetti
|
d5069b9c39 | ||
|
davidmezzetti
|
351d6f8a80 | ||
|
davidmezzetti
|
0c8a2627ff | ||
|
davidmezzetti
|
532a87049b | ||
|
davidmezzetti
|
6a1664db67 | ||
|
davidmezzetti
|
5178f92767 | ||
|
davidmezzetti
|
05da209b78 | ||
|
davidmezzetti
|
4e5331e641 | ||
|
davidmezzetti
|
80db3a9a85 | ||
|
davidmezzetti
|
c7e0fe3f99 | ||
|
davidmezzetti
|
1352040add | ||
|
davidmezzetti
|
2d8cf5d80d | ||
|
davidmezzetti
|
38520439b9 | ||
|
davidmezzetti
|
dd92c18663 | ||
|
Igor Ribeiro Lima
|
991ea6ac11 | ||
|
davidmezzetti
|
2e0dfb36d9 | ||
|
davidmezzetti
|
fc611ed228 | ||
|
davidmezzetti
|
65a8316de5 | ||
|
davidmezzetti
|
34ffc9723d | ||
|
davidmezzetti
|
522760447d | ||
|
davidmezzetti
|
952a7575b7 | ||
|
davidmezzetti
|
9bd2da7213 | ||
|
davidmezzetti
|
ec5f33b1ea | ||
|
davidmezzetti
|
5d7292048b | ||
|
davidmezzetti
|
bb851a1dc0 | ||
|
davidmezzetti
|
5e56dade9c | ||
|
davidmezzetti
|
d39b85e04b | ||
|
davidmezzetti
|
6cc886aaad | ||
|
davidmezzetti
|
0354e2bef3 | ||
|
davidmezzetti
|
cab131e92a | ||
|
davidmezzetti
|
69aa23c462 | ||
|
davidmezzetti
|
e215ea13bb | ||
|
davidmezzetti
|
e7aa46a1f0 | ||
|
davidmezzetti
|
89410d3661 | ||
|
davidmezzetti
|
26bd35dc02 | ||
|
davidmezzetti
|
3f7bb71a3e | ||
|
davidmezzetti
|
92489ac89a | ||
|
davidmezzetti
|
b05abd20f3 | ||
|
davidmezzetti
|
c6cd565518 | ||
|
davidmezzetti
|
05ae9ebcb2 | ||
|
davidmezzetti
|
4fe7877dd9 | ||
|
davidmezzetti
|
1aa6c506ca | ||
|
davidmezzetti
|
9efc9ba070 | ||
|
davidmezzetti
|
5fdbc90d24 | ||
|
davidmezzetti
|
4b5164beca | ||
|
davidmezzetti
|
cb22635bff | ||
|
davidmezzetti
|
7edc7aa184 | ||
|
davidmezzetti
|
350087ee1d | ||
|
davidmezzetti
|
2e8450d816 | ||
|
davidmezzetti
|
384201d4c8 | ||
|
davidmezzetti
|
51aab3eb26 | ||
|
davidmezzetti
|
0f916d30e2 | ||
|
davidmezzetti
|
ff4d4dac14 | ||
|
David Mezzetti
|
f840ed7625 | ||
|
Ikko Eltociear Ashimine
|
0b584a02c3 | ||
|
davidmezzetti
|
e16d42382b | ||
|
Jeff
|
dceb40c774 | ||
|
davidmezzetti
|
4f370801e8 | ||
|
davidmezzetti
|
29f680fe89 | ||
|
davidmezzetti
|
f0c6c3e0c4 | ||
|
davidmezzetti
|
cdc6eeea6f | ||
|
davidmezzetti
|
94c05fb231 | ||
|
davidmezzetti
|
846fbaf377 | ||
|
davidmezzetti
|
cf340e66c3 | ||
|
davidmezzetti
|
b239c7c131 | ||
|
davidmezzetti
|
9444fcc720 | ||
|
davidmezzetti
|
439b9d7f0c |
+25
-12
@@ -10,54 +10,67 @@ jobs:
|
||||
matrix:
|
||||
os: [ubuntu-latest, macos-latest, windows-latest]
|
||||
|
||||
timeout-minutes: 60
|
||||
timeout-minutes: 75
|
||||
steps:
|
||||
- name: Checkout code
|
||||
uses: actions/checkout@v3
|
||||
uses: actions/checkout@v6
|
||||
|
||||
- name: Install Python
|
||||
uses: actions/setup-python@v4
|
||||
uses: actions/setup-python@v6
|
||||
with:
|
||||
python-version: 3.9
|
||||
python-version: "3.11"
|
||||
|
||||
- name: Install Java
|
||||
uses: actions/setup-java@v3
|
||||
uses: actions/setup-java@v5
|
||||
with:
|
||||
distribution: "zulu"
|
||||
java-version: 17
|
||||
java-version: 21
|
||||
|
||||
- name: Install dependencies - Linux
|
||||
run: sudo apt-get update && sudo apt-get install libportaudio2 libsndfile1
|
||||
run: |
|
||||
sudo apt-get update
|
||||
sudo apt-get install libportaudio2 libsndfile1 libegl1 libgles2
|
||||
sudo rm -rf /usr/share/dotnet /usr/local/lib/android /opt/ghc
|
||||
if: matrix.os == 'ubuntu-latest'
|
||||
|
||||
- name: Install dependencies - macOS
|
||||
run: |
|
||||
echo "OMP_NUM_THREADS=1" >> $GITHUB_ENV
|
||||
echo "PYTORCH_MPS_DISABLE=1" >> $GITHUB_ENV
|
||||
echo "LLAMA_NO_METAL=1" >> $GITHUB_ENV
|
||||
echo "TIKA_STARTUP_SLEEP=30" >> $GITHUB_ENV
|
||||
echo "TIKA_STARTUP_MAX_RETRY=10" >> $GITHUB_ENV
|
||||
brew install portaudio
|
||||
pip install torch==2.12.1 torchvision==0.27.1
|
||||
if: matrix.os == 'macos-latest'
|
||||
|
||||
- name: Install dependencies - Windows
|
||||
run: choco install wget
|
||||
run: |
|
||||
"PYTHONIOENCODING=utf-8" >> $env:GITHUB_ENV
|
||||
choco install wget
|
||||
if: matrix.os == 'windows-latest'
|
||||
|
||||
- name: Build
|
||||
run: |
|
||||
pip install -U wheel
|
||||
pip install .[all,dev] fasttext==0.9.2 pillow==10.4.0
|
||||
pip install .[all,dev]
|
||||
pip cache purge
|
||||
python -c "import nltk; nltk.download(['punkt', 'punkt_tab', 'averaged_perceptron_tagger_eng'])"
|
||||
python --version
|
||||
make data coverage
|
||||
env:
|
||||
HF_HUB_ETAG_TIMEOUT: 100
|
||||
HF_HUB_DOWNLOAD_TIMEOUT: 100
|
||||
HF_XET_CHUNK_CACHE_SIZE_BYTES: 0
|
||||
DOCLING_DEVICE: "cpu"
|
||||
DOCLING_INFERENCE_COMPILE_TORCH_MODELS: false
|
||||
|
||||
- uses: pre-commit/[email protected].0
|
||||
- uses: pre-commit/[email protected].1
|
||||
if: matrix.os == 'ubuntu-latest'
|
||||
|
||||
- name: Test Coverage
|
||||
run: coveralls --service=github
|
||||
run: |
|
||||
coverage report --fail-under=100
|
||||
coveralls --service=github
|
||||
if: matrix.os == 'ubuntu-latest'
|
||||
env:
|
||||
GITHUB_TOKEN: ${{ secrets.GITHUB_TOKEN }}
|
||||
|
||||
@@ -7,12 +7,19 @@ jobs:
|
||||
deploy:
|
||||
runs-on: ubuntu-latest
|
||||
steps:
|
||||
- uses: actions/checkout@v3
|
||||
- uses: actions/setup-python@v4
|
||||
- name: Checkout code
|
||||
uses: actions/checkout@v6
|
||||
|
||||
- name: Install Python
|
||||
uses: actions/setup-python@v6
|
||||
with:
|
||||
python-version: 3.9
|
||||
- run: |
|
||||
python-version: "3.11"
|
||||
|
||||
- name: Install txtai
|
||||
run: |
|
||||
pip install -U pip wheel
|
||||
pip install .[all,dev]
|
||||
- run: mkdocs gh-deploy --force
|
||||
|
||||
- name: Deploy documentation
|
||||
run: mkdocs gh-deploy --force
|
||||
|
||||
@@ -0,0 +1,22 @@
|
||||
# GitHub Actions minimal build
|
||||
name: minimal
|
||||
|
||||
on: ["push", "pull_request"]
|
||||
|
||||
jobs:
|
||||
deploy:
|
||||
runs-on: ubuntu-latest
|
||||
steps:
|
||||
- name: Checkout code
|
||||
uses: actions/checkout@v6
|
||||
|
||||
- name: Install Python
|
||||
uses: actions/setup-python@v6
|
||||
with:
|
||||
python-version: "3.11"
|
||||
|
||||
- name: Minimal install
|
||||
run: |
|
||||
pip install -U pip wheel
|
||||
MINIMAL=1 pip install .
|
||||
python -c "import txtai"
|
||||
@@ -12,6 +12,8 @@ max-locals=40
|
||||
max-returns=10
|
||||
max-attributes=20
|
||||
min-public-methods=0
|
||||
max-public-methods=80
|
||||
|
||||
[FORMAT]
|
||||
max-line-length=150
|
||||
max-module-lines=1500
|
||||
|
||||
+2
-2
@@ -1,8 +1,8 @@
|
||||
cff-version: 1.2.0
|
||||
date-released: 2020-08-11
|
||||
message: "If you use this software, please cite it as below."
|
||||
title: "txtai: the all-in-one embeddings database"
|
||||
abstract: "txtai is an all-in-one open-source embeddings database for semantic search, LLM orchestration and language model workflows"
|
||||
title: "txtai: the all-in-one AI framework"
|
||||
abstract: "txtai is an all-in-one open-source AI framework for semantic search, LLM orchestration and language model workflows"
|
||||
url: "https://github.com/neuml/txtai"
|
||||
authors:
|
||||
- family-names: "Mezzetti"
|
||||
|
||||
@@ -42,6 +42,7 @@ coverage:
|
||||
coverage run -m unittest discover -v -k testdatabase -s ${TEST_DIR}
|
||||
coverage run -m unittest discover -v -k testembeddings -s ${TEST_DIR}
|
||||
coverage run -m unittest discover -v -k testgraph -s ${TEST_DIR}
|
||||
coverage run -m unittest discover -v -k testlibrary -s ${TEST_DIR}
|
||||
coverage run -m unittest discover -v -k testmodels -s ${TEST_DIR}
|
||||
coverage run -m unittest discover -v -k testoptional -s ${TEST_DIR}
|
||||
coverage run -m unittest discover -v -k testpipeline.testaudio -s ${TEST_DIR}
|
||||
|
||||
@@ -3,7 +3,7 @@
|
||||
</p>
|
||||
|
||||
<p align="center">
|
||||
<b>All-in-one embeddings database</b>
|
||||
<b>All-in-one AI framework</b>
|
||||
</p>
|
||||
|
||||
<p align="center">
|
||||
@@ -16,7 +16,7 @@
|
||||
<a href="https://github.com/neuml/txtai/issues">
|
||||
<img src="https://img.shields.io/github/issues/neuml/txtai.svg?style=flat&color=success" alt="GitHub issues"/>
|
||||
</a>
|
||||
<a href="https://join.slack.com/t/txtai/shared_invite/zt-1cagya4yf-DQeuZbd~aMwH5pckBU4vPg">
|
||||
<a href="https://join.slack.com/t/txtai/shared_invite/zt-37c1zfijp-Y57wMty6YOx_hyIHEQvQJA">
|
||||
<img src="https://img.shields.io/badge/slack-join-blue?style=flat&logo=slack&logocolor=white" alt="Join Slack"/>
|
||||
</a>
|
||||
<a href="https://github.com/neuml/txtai/actions?query=workflow%3Abuild">
|
||||
@@ -27,14 +27,16 @@
|
||||
</a>
|
||||
</p>
|
||||
|
||||
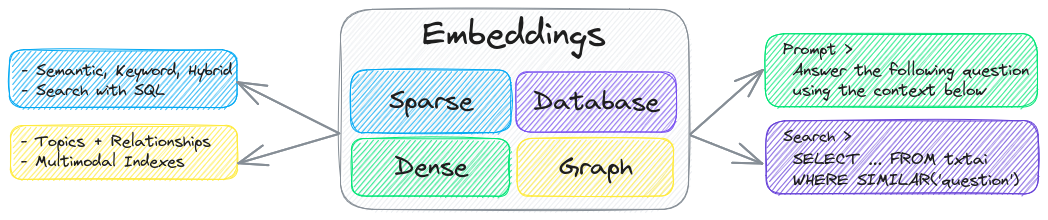
txtai is an all-in-one embeddings database for semantic search, LLM orchestration and language model workflows.
|
||||
txtai is an all-in-one AI framework for semantic search, LLM orchestration and language model workflows.
|
||||
|
||||
|
||||
|
||||
|
||||
Embeddings databases are a union of vector indexes (sparse and dense), graph networks and relational databases. This enables vector search with SQL, topic modeling, graph analysis and more.
|
||||
The key component of txtai is an embeddings database, which is a union of vector indexes (sparse and dense), graph networks and relational databases.
|
||||
|
||||
Embeddings databases can stand on their own and/or serve as a powerful knowledge source for large language model (LLM) prompts. Build autonomous agents, retrieval augmented generation (RAG) processes and multi-model workflows.
|
||||
This foundation enables vector search and/or serves as a powerful knowledge source for large language model (LLM) applications.
|
||||
|
||||
Build autonomous agents, retrieval augmented generation (RAG) processes, multi-model workflows and more.
|
||||
|
||||
Summary of txtai features:
|
||||
|
||||
@@ -43,12 +45,17 @@ Summary of txtai features:
|
||||
- 💡 Pipelines powered by language models that run LLM prompts, question-answering, labeling, transcription, translation, summarization and more
|
||||
- ↪️️ Workflows to join pipelines together and aggregate business logic. txtai processes can be simple microservices or multi-model workflows.
|
||||
- 🤖 Agents that intelligently connect embeddings, pipelines, workflows and other agents together to autonomously solve complex problems
|
||||
- ⚙️ Build with Python or YAML. API bindings available for [JavaScript](https://github.com/neuml/txtai.js), [Java](https://github.com/neuml/txtai.java), [Rust](https://github.com/neuml/txtai.rs) and [Go](https://github.com/neuml/txtai.go).
|
||||
- ⚙️ Web and Model Context Protocol (MCP) APIs. Bindings available for [JavaScript](https://github.com/neuml/txtai.js), [Java](https://github.com/neuml/txtai.java), [Rust](https://github.com/neuml/txtai.rs) and [Go](https://github.com/neuml/txtai.go).
|
||||
- 🔋 Batteries included with defaults to get up and running fast
|
||||
- ☁️ Run local or scale out with container orchestration
|
||||
|
||||
txtai is built with Python 3.9+, [Hugging Face Transformers](https://github.com/huggingface/transformers), [Sentence Transformers](https://github.com/UKPLab/sentence-transformers) and [FastAPI](https://github.com/tiangolo/fastapi). txtai is open-source under an Apache 2.0 license.
|
||||
txtai is built with Python 3.11+, [Hugging Face Transformers](https://github.com/huggingface/transformers), [Sentence Transformers](https://github.com/UKPLab/sentence-transformers) and [FastAPI](https://github.com/tiangolo/fastapi). txtai is open-source under an Apache 2.0 license.
|
||||
|
||||
*Interested in an easy and secure way to run hosted txtai applications? Then join the [txtai.cloud](https://txtai.cloud) preview to learn more.*
|
||||
> [!NOTE]
|
||||
>
|
||||
> [NeuML](https://neuml.com) is the company behind txtai and we provide AI consulting services around our stack. [Schedule a meeting](https://cal.com/neuml/intro) or [send a message](mailto:[email protected]) to learn more.
|
||||
>
|
||||
> We're also building an easy and secure way to run hosted txtai applications with [txtai.cloud](https://txtai.cloud).
|
||||
|
||||
## Why txtai?
|
||||
|
||||
@@ -84,7 +91,7 @@ curl -X GET "http://localhost:8000/search?query=positive"
|
||||
|
||||
## Use Cases
|
||||
|
||||
The following sections introduce common txtai use cases. A comprehensive set of over 60 [example notebooks and applications](https://neuml.github.io/txtai/examples) are also available.
|
||||
The following sections introduce common txtai use cases. A comprehensive set of over 70 [example notebooks and applications](https://neuml.github.io/txtai/examples) are also available.
|
||||
|
||||
### Semantic Search
|
||||
|
||||
@@ -119,6 +126,7 @@ See below to learn more.
|
||||
| [Prompt templates and task chains](https://github.com/neuml/txtai/blob/master/examples/44_Prompt_templates_and_task_chains.ipynb) | Build model prompts and connect tasks together with workflows | [](https://colab.research.google.com/github/neuml/txtai/blob/master/examples/44_Prompt_templates_and_task_chains.ipynb) |
|
||||
| [Integrate LLM frameworks](https://github.com/neuml/txtai/blob/master/examples/53_Integrate_LLM_Frameworks.ipynb) | Integrate llama.cpp, LiteLLM and custom generation frameworks | [](https://colab.research.google.com/github/neuml/txtai/blob/master/examples/53_Integrate_LLM_Frameworks.ipynb) |
|
||||
| [Build knowledge graphs with LLMs](https://github.com/neuml/txtai/blob/master/examples/57_Build_knowledge_graphs_with_LLM_driven_entity_extraction.ipynb) | Build knowledge graphs with LLM-driven entity extraction | [](https://colab.research.google.com/github/neuml/txtai/blob/master/examples/57_Build_knowledge_graphs_with_LLM_driven_entity_extraction.ipynb) |
|
||||
| [Parsing the stars with txtai](https://github.com/neuml/txtai/blob/master/examples/72_Parsing_the_stars_with_txtai.ipynb) | Explore an astronomical knowledge graph of known stars, planets, galaxies | [](https://colab.research.google.com/github/neuml/txtai/blob/master/examples/72_Parsing_the_stars_with_txtai.ipynb) |
|
||||
|
||||
#### Agents
|
||||
|
||||
@@ -126,13 +134,16 @@ Agents connect embeddings, pipelines, workflows and other agents together to aut
|
||||
|
||||
|
||||
|
||||
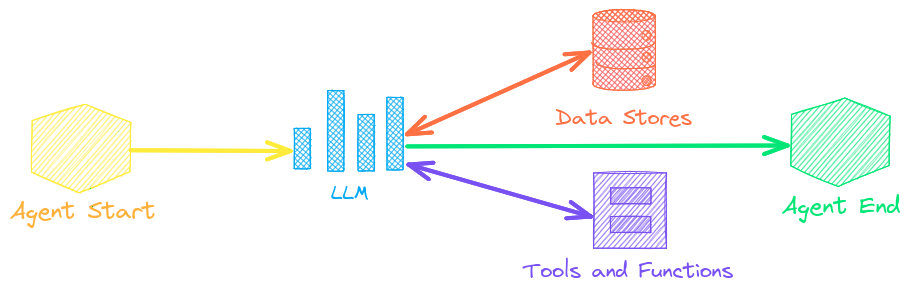
txtai agents are built on top of the Transformers Agent framework. This supports all LLMs txtai supports (Hugging Face, llama.cpp, OpenAI / Claude / AWS Bedrock via LiteLLM).
|
||||
txtai agents are built on top of the [smolagents](https://github.com/huggingface/smolagents) framework. This supports all LLMs txtai supports (Hugging Face, llama.cpp, OpenAI / Claude / AWS Bedrock via LiteLLM). Agent prompting with [`agents.md`](https://github.com/agentsmd/agents.md) and [`skill.md`](https://agentskills.io/specification) are also supported.
|
||||
|
||||
See the link below to learn more.
|
||||
Check out this [Agent Quickstart Example](https://github.com/neuml/txtai/blob/master/examples/agent_quickstart.py). Additional examples are listed below.
|
||||
|
||||
| Notebook | Description | |
|
||||
|:----------|:-------------|------:|
|
||||
| [What's new in txtai 8.0](https://github.com/neuml/txtai/blob/master/examples/67_Whats_new_in_txtai_8_0.ipynb) | Agents with txtai | [](https://colab.research.google.com/github/neuml/txtai/blob/master/examples/67_Whats_new_in_txtai_8_0.ipynb) |
|
||||
| [Granting autonomy to agents](https://github.com/neuml/txtai/blob/master/examples/69_Granting_autonomy_to_agents.ipynb) | Agents that iteratively solve problems as they see fit | [](https://colab.research.google.com/github/neuml/txtai/blob/master/examples/69_Granting_autonomy_to_agents.ipynb) |
|
||||
| [TxtAI got skills](https://github.com/neuml/txtai/blob/master/examples/83_TxtAI_got_skills.ipynb) | Integrate skill.md files with your agent | [](https://colab.research.google.com/github/neuml/txtai/blob/master/examples/83_TxtAI_got_skills.ipynb) |
|
||||
| [Agent Tools](https://github.com/neuml/txtai/blob/master/examples/84_Agent_Tools.ipynb) [▶️](https://www.youtube.com/watch?v=RDNaFXQy3GQ) | Learn about the txtai agent toolkit | [](https://colab.research.google.com/github/neuml/txtai/blob/master/examples/84_Agent_Tools.ipynb) |
|
||||
| [Analyzing LinkedIn Company Posts with Graphs and Agents](https://github.com/neuml/txtai/blob/master/examples/71_Analyzing_LinkedIn_Company_Posts_with_Graphs_and_Agents.ipynb) | Exploring how to improve social media engagement with AI | [](https://colab.research.google.com/github/neuml/txtai/blob/master/examples/71_Analyzing_LinkedIn_Company_Posts_with_Graphs_and_Agents.ipynb) |
|
||||
|
||||
#### Retrieval augmented generation
|
||||
|
||||
@@ -141,13 +152,13 @@ Retrieval augmented generation (RAG) reduces the risk of LLM hallucinations by c
|
||||
|
||||
|
||||
|
||||
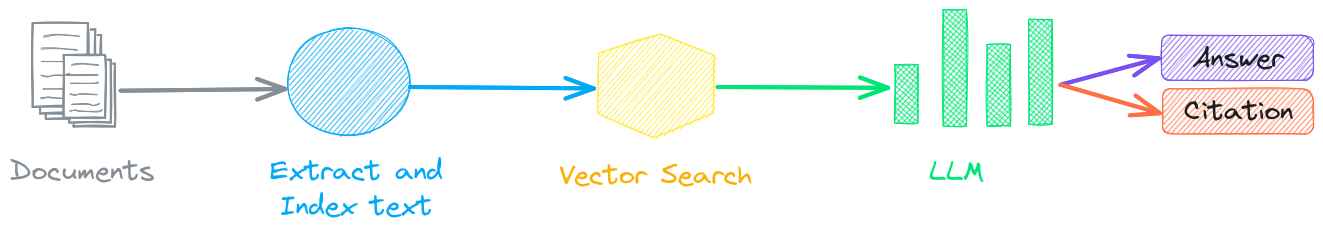
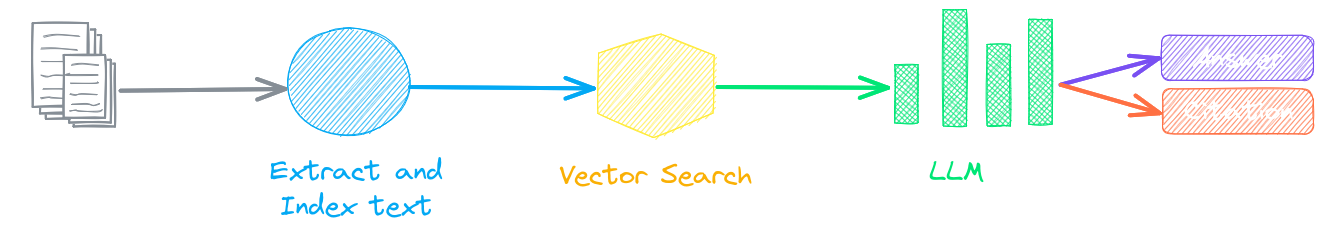
A novel feature of txtai is that it can provide both an answer and source citation.
|
||||
Check out this [RAG Quickstart Example](https://github.com/neuml/txtai/blob/master/examples/rag_quickstart.py). Additional examples are listed below.
|
||||
|
||||
| Notebook | Description | |
|
||||
|:----------|:-------------|------:|
|
||||
| [Build RAG pipelines with txtai](https://github.com/neuml/txtai/blob/master/examples/52_Build_RAG_pipelines_with_txtai.ipynb) | Guide on retrieval augmented generation including how to create citations | [](https://colab.research.google.com/github/neuml/txtai/blob/master/examples/52_Build_RAG_pipelines_with_txtai.ipynb) |
|
||||
| [How RAG with txtai works](https://github.com/neuml/txtai/blob/master/examples/63_How_RAG_with_txtai_works.ipynb) | Create RAG processes, API services and Docker instances | [](https://colab.research.google.com/github/neuml/txtai/blob/master/examples/63_How_RAG_with_txtai_works.ipynb) |
|
||||
| [Advanced RAG with graph path traversal](https://github.com/neuml/txtai/blob/master/examples/58_Advanced_RAG_with_graph_path_traversal.ipynb) | Graph path traversal to collect complex sets of data for advanced RAG | [](https://colab.research.google.com/github/neuml/txtai/blob/master/examples/58_Advanced_RAG_with_graph_path_traversal.ipynb) |
|
||||
| [Build RAG pipelines with txtai](https://github.com/neuml/txtai/blob/master/examples/52_Build_RAG_pipelines_with_txtai.ipynb) [▶️](https://www.youtube.com/watch?v=t_OeAc8NVfQ) | Guide on retrieval augmented generation including how to create citations | [](https://colab.research.google.com/github/neuml/txtai/blob/master/examples/52_Build_RAG_pipelines_with_txtai.ipynb) |
|
||||
| [RAG is more than Vector Search](https://github.com/neuml/txtai/blob/master/examples/79_RAG_is_more_than_Vector_Search.ipynb) | Context retrieval via Web, SQL and other sources | [](https://colab.research.google.com/github/neuml/txtai/blob/master/examples/79_RAG_is_more_than_Vector_Search.ipynb) |
|
||||
| [GraphRAG with Wikipedia and GPT OSS](https://github.com/neuml/txtai/blob/master/examples/77_GraphRAG_with_Wikipedia_and_GPT_OSS.ipynb) | Deep graph search powered RAG | [](https://colab.research.google.com/github/neuml/txtai/blob/master/examples/77_GraphRAG_with_Wikipedia_and_GPT_OSS.ipynb) |
|
||||
| [Speech to Speech RAG](https://github.com/neuml/txtai/blob/master/examples/65_Speech_to_Speech_RAG.ipynb) [▶️](https://www.youtube.com/watch?v=tH8QWwkVMKA) | Full cycle speech to speech workflow with RAG | [](https://colab.research.google.com/github/neuml/txtai/blob/master/examples/65_Speech_to_Speech_RAG.ipynb) |
|
||||
|
||||
### Language Model Workflows
|
||||
@@ -159,6 +170,8 @@ Language model workflows, also known as semantic workflows, connect language mod
|
||||
|
||||
While LLMs are powerful, there are plenty of smaller, more specialized models that work better and faster for specific tasks. This includes models for extractive question-answering, automatic summarization, text-to-speech, transcription and translation.
|
||||
|
||||
Check out this [Workflow Quickstart Example](https://github.com/neuml/txtai/blob/master/examples/workflow_quickstart.py). Additional examples are listed below.
|
||||
|
||||
| Notebook | Description | |
|
||||
|:----------|:-------------|------:|
|
||||
| [Run pipeline workflows](https://github.com/neuml/txtai/blob/master/examples/14_Run_pipeline_workflows.ipynb) [▶️](https://www.youtube.com/watch?v=UBMPDCn1gEU) | Simple yet powerful constructs to efficiently process data | [](https://colab.research.google.com/github/neuml/txtai/blob/master/examples/14_Run_pipeline_workflows.ipynb) |
|
||||
@@ -177,9 +190,9 @@ The easiest way to install is via pip and PyPI
|
||||
pip install txtai
|
||||
```
|
||||
|
||||
Python 3.9+ is supported. Using a Python [virtual environment](https://docs.python.org/3/library/venv.html) is recommended.
|
||||
Python 3.11+ is supported. Using a Python [virtual environment](https://docs.python.org/3/library/venv.html) is recommended.
|
||||
|
||||
See the detailed [install instructions](https://neuml.github.io/txtai/install) for more information covering [optional dependencies](https://neuml.github.io/txtai/install/#optional-dependencies), [environment specific prerequisites](https://neuml.github.io/txtai/install/#environment-specific-prerequisites), [installing from source](https://neuml.github.io/txtai/install/#install-from-source), [conda support](https://neuml.github.io/txtai/install/#conda) and how to [run with containers](https://neuml.github.io/txtai/cloud).
|
||||
See the detailed [install instructions](https://neuml.github.io/txtai/install) for more information covering [optional dependencies](https://neuml.github.io/txtai/install/#optional-dependencies), [environment specific prerequisites](https://neuml.github.io/txtai/install/#environment-specific-prerequisites), [installing from source](https://neuml.github.io/txtai/install/#install-from-source), [conda support](https://neuml.github.io/txtai/install/#conda), [lightweight minimal installation](https://neuml.github.io/txtai/install/#minimal-install) and how to [run with containers](https://neuml.github.io/txtai/cloud).
|
||||
|
||||
## Model guide
|
||||
|
||||
@@ -191,9 +204,9 @@ See the table below for the current recommended models. These models all allow c
|
||||
| ----------------------------------------------------------------------------- | ------------------------------------------------------------------------ |
|
||||
| [Embeddings](https://neuml.github.io/txtai/embeddings) | [all-MiniLM-L6-v2](https://hf.co/sentence-transformers/all-MiniLM-L6-v2) |
|
||||
| [Image Captions](https://neuml.github.io/txtai/pipeline/image/caption) | [BLIP](https://hf.co/Salesforce/blip-image-captioning-base) |
|
||||
| [Labels - Zero Shot](https://neuml.github.io/txtai/pipeline/text/labels) | [BART-Large-MNLI](https://hf.co/facebook/bart-large) |
|
||||
| [Labels - Zero Shot](https://neuml.github.io/txtai/pipeline/text/labels) | [DeBERTa v3 Zeroshot](https://hf.co/MoritzLaurer/deberta-v3-base-zeroshot-v2.0-c) |
|
||||
| [Labels - Fixed](https://neuml.github.io/txtai/pipeline/text/labels) | Fine-tune with [training pipeline](https://neuml.github.io/txtai/pipeline/train/trainer) |
|
||||
| [Large Language Model (LLM)](https://neuml.github.io/txtai/pipeline/text/llm) | [Mistral 7B OpenOrca](https://hf.co/Open-Orca/Mistral-7B-OpenOrca) |
|
||||
| [Large Language Model (LLM)](https://neuml.github.io/txtai/pipeline/text/llm) | [Gemma 4 31B](https://hf.co/google/gemma-4-31B) |
|
||||
| [Summarization](https://neuml.github.io/txtai/pipeline/text/summary) | [DistilBART](https://hf.co/sshleifer/distilbart-cnn-12-6) |
|
||||
| [Text-to-Speech](https://neuml.github.io/txtai/pipeline/audio/texttospeech) | [ESPnet JETS](https://hf.co/NeuML/ljspeech-jets-onnx) |
|
||||
| [Transcription](https://neuml.github.io/txtai/pipeline/audio/transcription) | [Whisper](https://hf.co/openai/whisper-base) |
|
||||
@@ -205,9 +218,8 @@ See the following links to learn more.
|
||||
|
||||
- [Hugging Face Tasks](https://hf.co/tasks)
|
||||
- [Hugging Face Model Hub](https://hf.co/models)
|
||||
- [MTEB Leaderboard](https://hf.co/spaces/mteb/leaderboard)
|
||||
- [LMSYS LLM Leaderboard](https://chat.lmsys.org/?leaderboard)
|
||||
- [Open LLM Leaderboard](https://hf.co/spaces/HuggingFaceH4/open_llm_leaderboard)
|
||||
- [Embeddings Leaderboard](https://hf.co/spaces/mteb/leaderboard)
|
||||
- [LLM Leaderboard](https://hf.co/spaces/lmarena-ai/arena-leaderboard)
|
||||
|
||||
## Powered by txtai
|
||||
|
||||
@@ -217,10 +229,10 @@ The following applications are powered by txtai.
|
||||
|
||||
| Application | Description |
|
||||
|:------------ |:-------------|
|
||||
| [txtchat](https://github.com/neuml/txtchat) | Retrieval Augmented Generation (RAG) powered search |
|
||||
| [paperai](https://github.com/neuml/paperai) | Semantic search and workflows for medical/scientific papers |
|
||||
| [codequestion](https://github.com/neuml/codequestion) | Semantic search for developers |
|
||||
| [tldrstory](https://github.com/neuml/tldrstory) | Semantic search for headlines and story text |
|
||||
| [rag](https://github.com/neuml/rag) | Retrieval Augmented Generation (RAG) application |
|
||||
| [ncoder](https://github.com/neuml/ncoder) | Open-Source AI coding agent |
|
||||
| [paperai](https://github.com/neuml/paperai) | AI for medical and scientific papers |
|
||||
| [annotateai](https://github.com/neuml/annotateai) | Automatically annotate papers with LLMs |
|
||||
|
||||
In addition to this list, there are also many other [open-source projects](https://github.com/neuml/txtai/network/dependents), [published research](https://scholar.google.com/scholar?q=txtai&hl=en&as_ylo=2022) and closed proprietary/commercial projects that have built on txtai in production.
|
||||
|
||||
@@ -229,9 +241,10 @@ In addition to this list, there are also many other [open-source projects](https
|
||||
|
||||
|
||||
|
||||
- [Introducing txtai, the all-in-one embeddings database](https://medium.com/neuml/introducing-txtai-the-all-in-one-embeddings-database-c721f4ff91ad)
|
||||
- [Introducing txtai, the all-in-one AI framework](https://medium.com/neuml/introducing-txtai-the-all-in-one-ai-framework-0660ecfc39d7)
|
||||
- [txtai: An All-in-One AI Framework for Semantic Search and LLM Workflows](https://github.com/neuml/papers/blob/master/txtai/txtai.pdf)
|
||||
- [Tutorial series on Hashnode](https://neuml.hashnode.dev/series/txtai-tutorial) | [dev.to](https://dev.to/neuml/tutorial-series-on-txtai-ibg)
|
||||
- [What's new in txtai 7.0](https://medium.com/neuml/whats-new-in-txtai-7-0-855ad6a55440) | [6.0](https://medium.com/neuml/whats-new-in-txtai-6-0-7d93eeedf804) | [5.0](https://medium.com/neuml/whats-new-in-txtai-5-0-e5c75a13b101) | [4.0](https://medium.com/neuml/whats-new-in-txtai-4-0-bbc3a65c3d1c)
|
||||
- [What's new in txtai 9.0](https://medium.com/neuml/whats-new-in-txtai-9-0-d522bb150afa) | [8.0](https://medium.com/neuml/whats-new-in-txtai-8-0-2d7d0ab4506b) | [7.0](https://medium.com/neuml/whats-new-in-txtai-7-0-855ad6a55440) | [6.0](https://medium.com/neuml/whats-new-in-txtai-6-0-7d93eeedf804) | [5.0](https://medium.com/neuml/whats-new-in-txtai-5-0-e5c75a13b101) | [4.0](https://medium.com/neuml/whats-new-in-txtai-4-0-bbc3a65c3d1c)
|
||||
- [Getting started with semantic search](https://medium.com/neuml/getting-started-with-semantic-search-a9fd9d8a48cf) | [workflows](https://medium.com/neuml/getting-started-with-semantic-workflows-2fefda6165d9) | [rag](https://medium.com/neuml/getting-started-with-rag-9a0cca75f748)
|
||||
- [Running txtai at scale](https://medium.com/neuml/running-at-scale-with-txtai-71196cdd99f9)
|
||||
- [Vector search & RAG Landscape: A review with txtai](https://medium.com/neuml/vector-search-rag-landscape-a-review-with-txtai-a7f37ad0e187)
|
||||
|
||||

Binary file not shown.
|
Before Width: | Height: | Size: 208 KiB After Width: | Height: | Size: 295 KiB |
@@ -1,5 +1,5 @@
|
||||
# Set base image
|
||||
ARG BASE_IMAGE=python:3.9-slim
|
||||
ARG BASE_IMAGE=python:3.11-slim
|
||||
FROM $BASE_IMAGE
|
||||
|
||||
# Install GPU-enabled version of PyTorch if set
|
||||
@@ -8,7 +8,7 @@ ARG GPU
|
||||
# Target CPU architecture
|
||||
ARG TARGETARCH
|
||||
|
||||
# Set Python version (i.e. 3, 3.9)
|
||||
# Set Python version (i.e. 3, 3.11)
|
||||
ARG PYTHON_VERSION=3
|
||||
|
||||
# List of txtai components to install
|
||||
@@ -21,18 +21,18 @@ ENV LANG=C.UTF-8
|
||||
RUN \
|
||||
# Install required packages
|
||||
apt-get update && \
|
||||
apt-get -y --no-install-recommends install libgomp1 libportaudio2 libsndfile1 gcc g++ python${PYTHON_VERSION} python${PYTHON_VERSION}-dev python3-pip && \
|
||||
apt-get -y --no-install-recommends install libgomp1 libportaudio2 libsndfile1 libegl1 libgles2 libvulkan1 git gcc g++ python${PYTHON_VERSION} python${PYTHON_VERSION}-dev python3-pip && \
|
||||
rm -rf /var/lib/apt/lists && \
|
||||
\
|
||||
# Install txtai project and dependencies
|
||||
ln -s /usr/bin/python${PYTHON_VERSION} /usr/bin/python && \
|
||||
python -m pip install --no-cache-dir -U pip wheel setuptools && \
|
||||
if [ -z ${GPU} ] && { [ -z ${TARGETARCH} ] || [ ${TARGETARCH} = "amd64" ] ;}; then pip install --no-cache-dir torch==2.4.1+cpu torchvision==0.19.1+cpu -f https://download.pytorch.org/whl/torch -f https://download.pytorch.org/whl/torchvision; fi && \
|
||||
if [ -z ${GPU} ]; then pip install --no-cache-dir torch==2.14.1+cpu torchvision==0.29.1+cpu -f https://download.pytorch.org/whl/torch -f https://download.pytorch.org/whl/torchvision; fi && \
|
||||
python -m pip install --no-cache-dir txtai${COMPONENTS} && \
|
||||
python -c "import sys, importlib.util as util; 1 if util.find_spec('nltk') else sys.exit(); import nltk; nltk.download(['punkt', 'punkt_tab', 'averaged_perceptron_tagger_eng'])" && \
|
||||
\
|
||||
# Cleanup build packages
|
||||
apt-get -y purge gcc g++ python${PYTHON_VERSION}-dev && apt-get -y autoremove
|
||||
apt-get -y purge git gcc g++ python${PYTHON_VERSION}-dev && apt-get -y autoremove
|
||||
|
||||
# Set default working directory
|
||||
WORKDIR /app
|
||||
|
||||
@@ -0,0 +1,20 @@
|
||||
# Set base image
|
||||
ARG BASE_IMAGE=python:3.11-slim
|
||||
FROM $BASE_IMAGE
|
||||
|
||||
# Target CPU architecture
|
||||
ARG TARGETARCH
|
||||
|
||||
# Set Python version (i.e. 3, 3.11)
|
||||
ARG PYTHON_VERSION=3
|
||||
|
||||
# Locale environment variables
|
||||
ENV LC_ALL=C.UTF-8
|
||||
ENV LANG=C.UTF-8
|
||||
|
||||
RUN \
|
||||
# Install minimal txtai project and dependencies
|
||||
MINIMAL=1 python -m pip install --no-cache-dir txtai_minimal
|
||||
|
||||
# Set default working directory
|
||||
WORKDIR /app
|
||||
+57
-10
@@ -2,7 +2,7 @@
|
||||
|
||||
An agent takes two main arguments, an LLM and a list of tools.
|
||||
|
||||
The txtai agent framework is built with [Transformers Agents](https://huggingface.co/docs/transformers/en/agents) and additional options can be directly passed in the `Agent` constructor.
|
||||
The txtai agent framework is built with [smolagents](https://github.com/huggingface/smolagents). Additional options can be passed in the `Agent` constructor.
|
||||
|
||||
```python
|
||||
from datetime import datetime
|
||||
@@ -34,18 +34,20 @@ def today() -> str:
|
||||
return datetime.today().isoformat()
|
||||
|
||||
agent = Agent(
|
||||
model="Qwen/Qwen3-4B-Instruct-2507",
|
||||
tools=[today, wikipedia, arxiv, "websearch"],
|
||||
llm="hugging-quants/Meta-Llama-3.1-8B-Instruct-AWQ-INT4",
|
||||
)
|
||||
```
|
||||
|
||||
## llm
|
||||
## model
|
||||
|
||||
```yaml
|
||||
llm: string|llm instance
|
||||
model: string|llm instance
|
||||
```
|
||||
|
||||
LLM path or LLM pipeline instance. See the [LLM pipeline](../../pipeline/text/llm) for more information.
|
||||
LLM model path or LLM pipeline instance. The `llm` parameter is also supported for backwards compatibility.
|
||||
|
||||
See the [LLM pipeline](../../pipeline/text/llm) for more information.
|
||||
|
||||
## tools
|
||||
|
||||
@@ -77,18 +79,63 @@ Embeddings indexes have built-in support. Provide the following dictionary confi
|
||||
| description | embeddings index description |
|
||||
| **kwargs | Parameters to pass to [embeddings.load](../../embeddings/methods/#txtai.embeddings.Embeddings.load) |
|
||||
|
||||
### transformers
|
||||
### tool
|
||||
|
||||
A Transformers tool instance can be provided. Additionally, the following strings load tools directly from Transformers.
|
||||
The following shortcut strings load tools directly. Passing a Tool instance is also supported.
|
||||
|
||||
| Tool | Description |
|
||||
|:------------|:----------------------------------------------------------|
|
||||
| websearch | Runs a websearch using built-in Transformers Agent tool |
|
||||
| bash | Runs a shell command through subprocess |
|
||||
| defaults | Loads all of these tools as the default toolkit |
|
||||
| edit | Edits a file in place and returns a diff |
|
||||
| glob | Finds matching file patterns in a directory |
|
||||
| grep | Finds matching file content in a directory |
|
||||
| http.* | HTTP Path to a [Model Context Protocol (MCP)](https://modelcontextprotocol.io/docs/getting-started/intro) server |
|
||||
| python | Runs a Python action |
|
||||
| read | Reads file or url content, supports text extraction |
|
||||
| todowrite | Generates a task list to organize complex tasks |
|
||||
| websearch | Runs a websearch using the built-in websearch tool |
|
||||
| webview | Extracts content from a web page. Alias for `read` tool |
|
||||
| write | Writes content to file |
|
||||
| *.md | Loads a [`skill.md`](https://agentskills.io/specification) file |
|
||||
|
||||
## instructions
|
||||
|
||||
```yaml
|
||||
instructions: string|path
|
||||
```
|
||||
|
||||
Supports loading an `agents.md` file. Can be provided directly as a string or as a path to a file.
|
||||
|
||||
[Read more about agents.md here](https://github.com/agentsmd/agents.md)
|
||||
|
||||
## template
|
||||
|
||||
```yaml
|
||||
template: string
|
||||
```
|
||||
|
||||
Customize the prompt template used by this agent. Supports Jinja templates. Uses a default template when this parameter is not provided.
|
||||
Must include `{{ text }}` and `{{ memory }}` placeholders.
|
||||
|
||||
## memory
|
||||
|
||||
```yaml
|
||||
memory: int
|
||||
```
|
||||
|
||||
Keeps a rolling window of `memory` inputs and outputs. These are added to future prompts and serve as "agent memory".
|
||||
|
||||
Supports storing memory by `session` to enable multiple conversation threads. Defaults to shared memory when not set. See the [method documentation](../methods#txtai.agent.base.Agent.__call__) for more information.
|
||||
|
||||
## method
|
||||
|
||||
```yaml
|
||||
method: reactjson|reactcode|code
|
||||
method: code|tool
|
||||
```
|
||||
|
||||
Sets the agent method. Defaults to `reactjson`. [Read more on this here](https://huggingface.co/docs/transformers/en/agents#types-of-agents).
|
||||
Sets the agent method. Supports either a `code` or `tool` (default) calling agent. A code agent generates Python code and executes that. A tool calling agent generates JSON blocks and calls the agents within those blocks.
|
||||
|
||||
Additional options can be directly passed. See [CodeAgent](https://huggingface.co/docs/smolagents/main/en/reference/agents#smolagents.CodeAgent) or [ToolCallingAgent](https://huggingface.co/docs/smolagents/main/en/reference/agents#smolagents.ToolCallingAgent) for a list of parameters.
|
||||
|
||||
[Read more here](https://huggingface.co/docs/smolagents/main/en/guided_tour).
|
||||
|
||||
+19
-11
@@ -5,6 +5,8 @@
|
||||
An agent automatically creates workflows to answer multi-faceted user requests. Agents iteratively prompt and/or interface with tools to
|
||||
step through a process and ultimately come to an answer for a request.
|
||||
|
||||
Agent prompting with [`agents.md`](https://github.com/agentsmd/agents.md) and [`skill.md`](https://agentskills.io/specification) are also supported. [Read the configuration](./configuration/#tool) for more on how to setup those up.
|
||||
|
||||
Agents excel at complex tasks where multiple tools and/or methods are required. They incorporate a level of randomness similar to different
|
||||
people working on the same task. When the request is simple and/or there is a rule-based process, other methods such as RAG and Workflows
|
||||
should be explored.
|
||||
@@ -41,9 +43,9 @@ def today() -> str:
|
||||
return datetime.today().isoformat()
|
||||
|
||||
agent = Agent(
|
||||
model="Qwen/Qwen3-4B-Instruct-2507",
|
||||
tools=[today, wikipedia, arxiv, "websearch"],
|
||||
llm="hugging-quants/Meta-Llama-3.1-8B-Instruct-AWQ-INT4",
|
||||
max_iterations=10,
|
||||
max_steps=10,
|
||||
)
|
||||
```
|
||||
|
||||
@@ -83,34 +85,35 @@ Agents can also be tools. This enables the concept of building "Agent Teams" to
|
||||
```python
|
||||
from txtai import Agent, LLM
|
||||
|
||||
llm = LLM("hugging-quants/Meta-Llama-3.1-8B-Instruct-AWQ-INT4")
|
||||
llm = LLM("Qwen/Qwen3-4B-Instruct-2507")
|
||||
|
||||
websearcher = Agent(
|
||||
model=llm,
|
||||
tools=["websearch"],
|
||||
llm=llm,
|
||||
)
|
||||
|
||||
wikiman = Agent(
|
||||
model=llm,
|
||||
tools=[{
|
||||
"name": "wikipedia",
|
||||
"description": "Searches a Wikipedia database",
|
||||
"provider": "huggingface-hub",
|
||||
"container": "neuml/txtai-wikipedia"
|
||||
}],
|
||||
llm=llm,
|
||||
)
|
||||
|
||||
researcher = Agent(
|
||||
model=llm,
|
||||
tools=[{
|
||||
"name": "arxiv",
|
||||
"description": "Searches a database of scientific papers",
|
||||
"provider": "huggingface-hub",
|
||||
"container": "neuml/txtai-arxiv"
|
||||
}],
|
||||
llm=llm,
|
||||
)
|
||||
|
||||
agent = Agent(
|
||||
model=llm,
|
||||
tools=[{
|
||||
"name": "websearcher",
|
||||
"description": "I run web searches, there is no answer a web search can't solve!",
|
||||
@@ -124,8 +127,7 @@ agent = Agent(
|
||||
"description": "I'm a science guy. I search arXiv to get all my answers.",
|
||||
"target": researcher
|
||||
}],
|
||||
llm=llm,
|
||||
max_iterations=10
|
||||
max_steps=10
|
||||
)
|
||||
```
|
||||
|
||||
@@ -133,16 +135,22 @@ This provides another level of intelligence to the process. Instead of just a si
|
||||
|
||||
```python
|
||||
agent("""
|
||||
Work with your team and build a comprehensive report on fundamental
|
||||
concepts about Signal Processing.
|
||||
Research fundamental concepts about Signal Processing and build a comprehensive report.
|
||||
Write the output in Markdown.
|
||||
""")
|
||||
```
|
||||
|
||||
# More examples
|
||||
|
||||
See the link below to learn more.
|
||||
Check out this [Agent Quickstart Example](https://github.com/neuml/txtai/blob/master/examples/agent_quickstart.py). Additional examples are listed below.
|
||||
|
||||
| Notebook | Description | |
|
||||
|:----------|:-------------|------:|
|
||||
| [What's new in txtai 8.0](https://github.com/neuml/txtai/blob/master/examples/67_Whats_new_in_txtai_8_0.ipynb) | Agents with txtai | [](https://colab.research.google.com/github/neuml/txtai/blob/master/examples/67_Whats_new_in_txtai_8_0.ipynb) |
|
||||
| [Analyzing Hugging Face Posts with Graphs and Agents](https://github.com/neuml/txtai/blob/master/examples/68_Analyzing_Hugging_Face_Posts_with_Graphs_and_Agents.ipynb) | Explore a rich dataset with Graph Analysis and Agents | [](https://colab.research.google.com/github/neuml/txtai/blob/master/examples/68_Analyzing_Hugging_Face_Posts_with_Graphs_and_Agents.ipynb) |
|
||||
| [Granting autonomy to agents](https://github.com/neuml/txtai/blob/master/examples/69_Granting_autonomy_to_agents.ipynb) | Agents that iteratively solve problems as they see fit | [](https://colab.research.google.com/github/neuml/txtai/blob/master/examples/69_Granting_autonomy_to_agents.ipynb) |
|
||||
| [Analyzing LinkedIn Company Posts with Graphs and Agents](https://github.com/neuml/txtai/blob/master/examples/71_Analyzing_LinkedIn_Company_Posts_with_Graphs_and_Agents.ipynb) | Exploring how to improve social media engagement with AI | [](https://colab.research.google.com/github/neuml/txtai/blob/master/examples/71_Analyzing_LinkedIn_Company_Posts_with_Graphs_and_Agents.ipynb) |
|
||||
| [Parsing the stars with txtai](https://github.com/neuml/txtai/blob/master/examples/72_Parsing_the_stars_with_txtai.ipynb) | Explore an astronomical knowledge graph of known stars, planets, galaxies | [](https://colab.research.google.com/github/neuml/txtai/blob/master/examples/72_Parsing_the_stars_with_txtai.ipynb) |
|
||||
| [Agentic College Search](https://github.com/neuml/txtai/blob/master/examples/82_Agentic_College_Search.ipynb) | Identify list of strong engineering colleges | [](https://colab.research.google.com/github/neuml/txtai/blob/master/examples/82_Agentic_College_Search.ipynb) |
|
||||
| [TxtAI got skills](https://github.com/neuml/txtai/blob/master/examples/83_TxtAI_got_skills.ipynb) | Integrate skill.md files with your agent | [](https://colab.research.google.com/github/neuml/txtai/blob/master/examples/83_TxtAI_got_skills.ipynb) |
|
||||
| [Agent Tools](https://github.com/neuml/txtai/blob/master/examples/84_Agent_Tools.ipynb) [▶️](https://www.youtube.com/watch?v=RDNaFXQy3GQ) | Learn about the txtai agent toolkit | [](https://colab.research.google.com/github/neuml/txtai/blob/master/examples/84_Agent_Tools.ipynb) |
|
||||
|
||||
@@ -1,4 +1,4 @@
|
||||
# Methods
|
||||
|
||||
## ::: txtai.agent.Agent.__init__
|
||||
## ::: txtai.agent.Agent.__call__
|
||||
## ::: txtai.agent.base.Agent.__init__
|
||||
## ::: txtai.agent.base.Agent.__call__
|
||||
|
||||
@@ -33,7 +33,16 @@ Path to save and load the embeddings index. Each API instance can only access a
|
||||
writable: boolean
|
||||
```
|
||||
|
||||
Determines if the input embeddings index is writable (true) or read-only (false). This allows serving a read-only index.
|
||||
Sets this embeddings index as writable (true) or read-only (false). This allows serving a read-only index. Defaults to read-only.
|
||||
|
||||
### reindex
|
||||
```yaml
|
||||
reindex: boolean
|
||||
```
|
||||
|
||||
Enables re-indexing for this embeddings index (defaults to disabled).
|
||||
|
||||
Re-indexing accepts new configuration and should only be enabled when the configuration comes from trusted sources.
|
||||
|
||||
### cloud
|
||||
[Cloud storage settings](../../embeddings/configuration/cloud) can be set under a `cloud` top level configuration group.
|
||||
@@ -51,7 +60,7 @@ agent:
|
||||
- websearch
|
||||
|
||||
llm:
|
||||
path: hugging-quants/Meta-Llama-3.1-8B-Instruct-AWQ-INT4
|
||||
path: Qwen/Qwen3-4B-Instruct-2507
|
||||
```
|
||||
|
||||
## Pipeline
|
||||
|
||||
+8
-1
@@ -120,8 +120,15 @@ The following programming languages have bindings with the txtai API:
|
||||
- [Rust](https://github.com/neuml/txtai.rs)
|
||||
- [Go](https://github.com/neuml/txtai.go)
|
||||
|
||||
See the link below for a detailed example covering how to use the API.
|
||||
The API also supports hosting [OpenAI-compatible](./openai) and [Model Context Protocol (MCP)](./mcp) endpoints.
|
||||
|
||||
See the links below for detailed examples covering the API.
|
||||
|
||||
| Notebook | Description | |
|
||||
|:----------|:-------------|------:|
|
||||
| [API Gallery](https://github.com/neuml/txtai/blob/master/examples/08_API_Gallery.ipynb) | Using txtai in JavaScript, Java, Rust and Go | [](https://colab.research.google.com/github/neuml/txtai/blob/master/examples/08_API_Gallery.ipynb) |
|
||||
| [Distributed embeddings cluster](https://github.com/neuml/txtai/blob/master/examples/15_Distributed_embeddings_cluster.ipynb) | Distribute an embeddings index across multiple data nodes | [](https://colab.research.google.com/github/neuml/txtai/blob/master/examples/15_Distributed_embeddings_cluster.ipynb) |
|
||||
| [Embeddings in the Cloud](https://github.com/neuml/txtai/blob/master/examples/43_Embeddings_in_the_Cloud.ipynb) | Load and use an embeddings index from the Hugging Face Hub | [](https://colab.research.google.com/github/neuml/txtai/blob/master/examples/43_Embeddings_in_the_Cloud.ipynb) |
|
||||
| [Custom API Endpoints](https://github.com/neuml/txtai/blob/master/examples/51_Custom_API_Endpoints.ipynb) | Extend the API with custom endpoints | [](https://colab.research.google.com/github/neuml/txtai/blob/master/examples/51_Custom_API_Endpoints.ipynb) |
|
||||
| [API Authorization and Authentication](https://github.com/neuml/txtai/blob/master/examples/54_API_Authorization_and_Authentication.ipynb) | Add authorization, authentication and middleware dependencies to the API | [](https://colab.research.google.com/github/neuml/txtai/blob/master/examples/54_API_Authorization_and_Authentication.ipynb) |
|
||||
| [OpenAI Compatible API](https://github.com/neuml/txtai/blob/master/examples/74_OpenAI_Compatible_API.ipynb) | Connect to txtai with a standard OpenAI client library | [](https://colab.research.google.com/github/neuml/txtai/blob/master/examples/74_OpenAI_Compatible_API.ipynb) |
|
||||
|
||||
@@ -0,0 +1,34 @@
|
||||
# Model Context Protocol
|
||||
|
||||
The [Model Context Protocol (MCP)](https://modelcontextprotocol.io/introduction) is an open standard that enables developers to build secure, two-way connections between their data sources and AI-powered tools.
|
||||
|
||||
The API can be configured to handle MCP requests. All enabled endpoints set in the API configuration are automatically added as MCP tools.
|
||||
|
||||
```yaml
|
||||
mcp: boolean|dict
|
||||
```
|
||||
|
||||
When `mcp` is a boolean, default arguments are used. When `mcp` is a dictionary it supports the following options.
|
||||
|
||||
```yaml
|
||||
mcp:
|
||||
clientargs: http client options (dict)
|
||||
mcpargs: FastApiMCP options (dict)
|
||||
```
|
||||
|
||||
See the following links for details on the options.
|
||||
|
||||
- [HTTP Client Arguments](https://www.python-httpx.org/api/#asyncclient)
|
||||
- [FastApiMCP Arguments](https://github.com/tadata-org/fastapi_mcp/blob/main/fastapi_mcp/server.py#L22)
|
||||
|
||||
Once this configuration option is added, a new route is added to the application `/mcp`.
|
||||
|
||||
The [Model Context Protocol Inspector tool](https://www.npmjs.com/package/@modelcontextprotocol/inspector) is a quick way to explore how the MCP tools are exported through this interface.
|
||||
|
||||
Run the following and go to the local URL specified.
|
||||
|
||||
```
|
||||
npx @modelcontextprotocol/inspector node build/index.js
|
||||
```
|
||||
|
||||
Enter `http://localhost:8000/mcp` to see the full list of tools available.
|
||||
@@ -0,0 +1,13 @@
|
||||
# OpenAI-compatible API
|
||||
|
||||
The API can be configured to serve an OpenAI-compatible API as shown below.
|
||||
|
||||
```yaml
|
||||
openai: True
|
||||
```
|
||||
|
||||
See the link below for a detailed example.
|
||||
|
||||
| Notebook | Description | |
|
||||
|:----------|:-------------|------:|
|
||||
| [OpenAI Compatible API](https://github.com/neuml/txtai/blob/master/examples/74_OpenAI_Compatible_API.ipynb) | Connect to txtai with a standard OpenAI client library | [](https://colab.research.google.com/github/neuml/txtai/blob/master/examples/74_OpenAI_Compatible_API.ipynb) |
|
||||
+43
-2
@@ -6,9 +6,9 @@ The default implementation of an API service runs via HTTP and is fully open. If
|
||||
|
||||
The default API service command starts a Uvicorn server as a HTTP service on port 8000. To run a HTTPS service, consider the following options.
|
||||
|
||||
- [TLS Proxy Server](https://fastapi.tiangolo.com/deployment/https/). *Recommended choice*. With this configuration, the txtai API service runs as a HTTP service only accessible on the localhost/local network. The proxy server handles all encryption and redirects requests to local services. See this [example configuration](https://www.uvicorn.org/deployment/#running-behind-nginx) for more.
|
||||
- [TLS Proxy Server](https://fastapi.tiangolo.com/deployment/https/). *Recommended choice*. With this configuration, the txtai API service runs as a HTTP service only accessible on the localhost/local network. The proxy server handles all encryption and redirects requests to local services. See this [example configuration](https://www.uvicorn.dev/deployment/#running-behind-nginx) for more.
|
||||
|
||||
- [Uvicorn SSL Certificate](https://www.uvicorn.org/deployment/). Another option is setting the SSL certificate on the Uvicorn service. This works in simple situations but gets complex when hosting multiple txtai or other related services.
|
||||
- [Uvicorn SSL Certificate](https://www.uvicorn.dev/deployment/). Another option is setting the SSL certificate on the Uvicorn service. This works in simple situations but gets complex when hosting multiple txtai or other related services.
|
||||
|
||||
## Authorization
|
||||
|
||||
@@ -31,3 +31,44 @@ curl \
|
||||
It's important to note that HTTPS **must** be enabled using one of the methods mentioned above. Otherwise, tokens will be exchanged as clear text.
|
||||
|
||||
Authentication and Authorization can be fully customized. See the [dependencies](../customization#dependencies) section for more.
|
||||
|
||||
## Safe Open
|
||||
|
||||
Many components in txtai work with local files and have no restrictions on what files and urls can be accessed. The [textractor pipeline](../../pipeline/data/textractor) and [retrieve](../../workflow/task/retrieve) tasks both have a built-in option called `safeopen` which is enabled by default when running the API and applications. It enforces the following rules:
|
||||
|
||||
- Local files must be in the safeopen directory (defaults to temp dir)
|
||||
- URLs must be public URLs (also has checks for redirects and DNS rebind attempts)
|
||||
|
||||
The following workflow only allows accessing files stored in a specific directory along with public urls.
|
||||
|
||||
```yaml
|
||||
workflow:
|
||||
textract:
|
||||
tasks:
|
||||
- action: textractor
|
||||
```
|
||||
|
||||
A number of of pipelines support reading local files. For these it's recommended to wrap those pipelines as workflows with a `retrieve` task. Note that pipelines can be created in-line and don't need to be exposed via the API.
|
||||
|
||||
```yaml
|
||||
workflow:
|
||||
caption:
|
||||
tasks:
|
||||
- task: retrieve
|
||||
action: caption
|
||||
```
|
||||
|
||||
Additionally, internal pipelines can be created but not exposed via the API.
|
||||
|
||||
```yaml
|
||||
routes:
|
||||
caption: False
|
||||
|
||||
caption:
|
||||
|
||||
workflow:
|
||||
caption:
|
||||
tasks:
|
||||
- task: retrieve
|
||||
action: caption
|
||||
```
|
||||
|
||||
+3
-3
@@ -8,7 +8,7 @@ Scalable cloud-native applications can be built with txtai. The following cloud
|
||||
- Container Orchestration Systems (i.e. Kubernetes)
|
||||
- Docker Engine
|
||||
- Serverless Compute
|
||||
- txtai.cloud (coming in 2024)
|
||||
- txtai.cloud (planned for future)
|
||||
|
||||
Images for txtai are available on Docker Hub for [CPU](https://hub.docker.com/r/neuml/txtai-cpu) and [GPU](https://hub.docker.com/r/neuml/txtai-gpu) installs. The CPU install is recommended when GPUs aren't available given the image is significantly smaller.
|
||||
|
||||
@@ -30,8 +30,8 @@ Examples build commands below.
|
||||
# Get Dockerfile
|
||||
wget https://raw.githubusercontent.com/neuml/txtai/master/docker/base/Dockerfile
|
||||
|
||||
# Build Ubuntu 22.04 image running Python 3.10
|
||||
docker build -t txtai --build-arg BASE_IMAGE=ubuntu:22.04 --build-arg PYTHON_VERSION=3.10 .
|
||||
# Build Ubuntu 22.04 image running Python 3.11
|
||||
docker build -t txtai --build-arg BASE_IMAGE=ubuntu:22.04 --build-arg PYTHON_VERSION=3.11 .
|
||||
|
||||
# Build image with GPU support
|
||||
docker build -t txtai --build-arg GPU=1 .
|
||||
|
||||
@@ -4,7 +4,7 @@ Approximate Nearest Neighbor (ANN) index configuration for storing vector embedd
|
||||
|
||||
## backend
|
||||
```yaml
|
||||
backend: faiss|hnsw|annoy|numpy|torch|pgvector|sqlite|custom
|
||||
backend: faiss|hnsw|annoy|ggml|milvus|numpy|rabitq|torch|turbovec|zvec|pgvector|sqlite|custom
|
||||
```
|
||||
|
||||
Sets the ANN backend. Defaults to `faiss`. Additional backends are available via the [ann](../../../install/#ann) extras package. Set custom backends via setting this parameter to the fully resolvable class string.
|
||||
@@ -40,6 +40,8 @@ See the following Faiss documentation links for more information.
|
||||
- [Binary Indexes](https://github.com/facebookresearch/faiss/wiki/Binary-indexes)
|
||||
- [Search Tuning](https://github.com/facebookresearch/faiss/wiki/Faster-search)
|
||||
|
||||
Note: For macOS users, an existing bug in an upstream package restricts the number of processing threads to 1. This limitation is managed internally to prevent system crashes.
|
||||
|
||||
### hnsw
|
||||
```yaml
|
||||
hnsw:
|
||||
@@ -60,18 +62,99 @@ annoy:
|
||||
|
||||
See [Annoy documentation](https://github.com/spotify/annoy#full-python-api) for more information on these parameters. Note that annoy indexes can not be modified after creation, upserts/deletes and other modifications are not supported.
|
||||
|
||||
### ggml
|
||||
```yaml
|
||||
ggml:
|
||||
gpu: enable GPU - defaults to True
|
||||
quantize: sets the tensor quantization - defaults to F32
|
||||
querysize: query buffer size - defaults to 64
|
||||
```
|
||||
|
||||
The [GGML](https://github.com/ggml-org/ggml) backend is a k-nearest neighbors backend. It stores tensors using GGML and [GGUF](https://huggingface.co/docs/hub/en/gguf). It supports GPU-enabled operations and supports quantization. GGML is the framework used by [llama.cpp](https://github.com/ggml-org/llama.cpp).
|
||||
|
||||
[See this](https://github.com/ggml-org/ggml/blob/master/include/ggml.h#L379) for a list of quantization types.
|
||||
|
||||
### milvus
|
||||
|
||||
```yaml
|
||||
milvus:
|
||||
m: number of HNSW links per element (int) - defaults to 50
|
||||
```
|
||||
|
||||
### numpy
|
||||
|
||||
The NumPy backend is a k-nearest neighbors backend. It's designed for simplicity and works well with smaller datasets.
|
||||
```yaml
|
||||
numpy:
|
||||
safetensors: stores vectors using the safetensors format
|
||||
defaults to NumPy array storage
|
||||
```
|
||||
|
||||
The `torch` backend supports the same options. The only difference is that the vectors can be search using GPUs.
|
||||
The NumPy backend is a k-nearest neighbors backend. It's designed for simplicity and works well with smaller datasets that fit into memory.
|
||||
|
||||
### rabitq
|
||||
|
||||
```yaml
|
||||
rabitq:
|
||||
mode: index mode (ivf or hnsw) - defaults to "ivf"
|
||||
nbits: number of quantization bits per dimension (int) - defaults to 1,
|
||||
supports 1 to 9 in both modes, ivf mode also supports 32 which
|
||||
keeps raw vectors for reranking
|
||||
clusters: number of IVF clusters (int) - defaults to
|
||||
max(1, min(round(4 * sqrt(embeddings count)), embeddings count))
|
||||
nprobe: search probe setting for ivf mode (int) - defaults to
|
||||
max(1, round(num_clusters/16))
|
||||
m: M param for hnsw mode (int) - defaults to 16
|
||||
efconstruction: ef_construction param for hnsw mode (int) - defaults to 200
|
||||
efsearch: ef search param for hnsw mode (int) - defaults to None and not set
|
||||
randomseed: random-seed param for hnsw mode (int) - defaults to 100
|
||||
```
|
||||
|
||||
The [rabitq](https://github.com/VectorDB-NTU/RaBitQ-Library) backend is a quantized index powered by the [RaBitQ algorithm](https://doi.org/10.1145/3725413). It supports ivf and hnsw search modes. Vectors are stored with 1-bit quantization by default. More bits increase accuracy at the cost of memory. The index is stored as a single file and no vectors are kept outside of it. With nbits set to 32, the vectors are stored in the index for reranking. The ivf mode supports upserts and deletes. Deleted rows keep their storage. Rows added after the first index are assigned to the clusters trained when the index was built, so recall can drop if the new data differs from the original data. Rebuild the index to train new clusters. Note that hnsw indexes can not be modified after creation, upserts/deletes and other modifications are not supported.
|
||||
|
||||
### torch
|
||||
|
||||
```yaml
|
||||
torch:
|
||||
safetensors: stores vectors using the safetensors format - defaults
|
||||
to NumPy array storage if quantization is disabled
|
||||
quantize:
|
||||
type: quantization type (fp4, nf4, int8)
|
||||
blocksize: quantization block size parameter
|
||||
```
|
||||
|
||||
The Torch backend is a k-nearest neighbors backend like NumPy. It supports GPU-enabled operations. It also has support for quantization which enables fitting larger arrays into GPU memory.
|
||||
|
||||
When quantization is enabled, vectors are _always_ stored in safetensors. _Note that macOS support for quantization is limited._
|
||||
|
||||
### turbovec
|
||||
|
||||
```yaml
|
||||
turbovec:
|
||||
bitwidth: number of bits to store each vector dimension as. Supports 2, 3 or 4.
|
||||
```
|
||||
|
||||
The [turbovec](https://github.com/RyanCodrai/turbovec) backend is a k-nearest neighbors backend powered by the [TurboQuant algorithm](https://arxiv.org/abs/2504.19874).
|
||||
|
||||
### zvec
|
||||
|
||||
```yaml
|
||||
zvec:
|
||||
efconstruction: ef_construction param for HnswIndexParam (int) - defaults to 200
|
||||
m: number of HNSW links per element (int) - defaults to 50
|
||||
efsearch: ef search param for HnswQueryParam (int) - defaults to 300
|
||||
```
|
||||
|
||||
The [zvec](https://github.com/alibaba/zvec) backend is an embedded, path-based vector index.
|
||||
|
||||
### pgvector
|
||||
```yaml
|
||||
pgvector:
|
||||
url: database url connection string, alternatively can be set via
|
||||
ANN_URL environment variable
|
||||
schema: database schema to store vectors - defaults to being
|
||||
determined by the database
|
||||
table: database table to store vectors - defaults to `vectors`
|
||||
precision: vector float precision (half or full) - defaults to `full`
|
||||
efconstruction: ef_construction param (int) - defaults to 200
|
||||
m: M param for init_index (int) - defaults to 16
|
||||
```
|
||||
|
||||
@@ -11,7 +11,7 @@ provider: string
|
||||
|
||||
Cloud provider. Can be one of the following:
|
||||
|
||||
- Cloud object storage. Set to one of these [providers](https://libcloud.readthedocs.io/en/stable/storage/supported_providers.html).
|
||||
- Cloud object storage. Set to one of these [providers](https://libcloud.readthedocs.io/en/stable/storage/supported_providers.html). Use the text shown in the `Provider Constant` column as lower case.
|
||||
|
||||
- Hugging Face Hub. Set to `huggingface-hub`.
|
||||
|
||||
@@ -44,6 +44,18 @@ secret: string
|
||||
|
||||
Provider-specific access secret. Can also be set via `ACCESS_SECRET` environment variable. Ensure the configuration file is secured if added to the file. When using implicit authentication, this option is not required.
|
||||
|
||||
### prefix
|
||||
```yaml
|
||||
prefix: string
|
||||
```
|
||||
|
||||
Optional object prefix. Object storage doesn't have the concept of a directory but a prefix is similar. For example, a prefix could be `base/dir`. This helps with organizing data in an object storage bucket.
|
||||
|
||||
More can be found at the following links.
|
||||
|
||||
- [Organizing objects using prefixes](https://docs.aws.amazon.com/AmazonS3/latest/userguide/using-prefixes.html)
|
||||
- [libcloud container method documentation](https://libcloud.readthedocs.io/en/stable/storage/api.html#libcloud.storage.base.StorageDriver.iterate_container_objects)
|
||||
|
||||
### host
|
||||
```yaml
|
||||
host: string
|
||||
|
||||
@@ -15,6 +15,14 @@ Add custom storage engines via setting this parameter to the fully resolvable cl
|
||||
|
||||
Content storage specific settings are set with a corresponding configuration object having the same name as the content storage engine (i.e. duckdb or sqlite). These are optional and set to defaults if omitted.
|
||||
|
||||
### client
|
||||
```yaml
|
||||
schema: default database schema for the session - defaults to being
|
||||
determined by the database
|
||||
```
|
||||
|
||||
Additional settings for client-server databases. Also supported when the `content=url`.
|
||||
|
||||
### sqlite
|
||||
```yaml
|
||||
sqlite:
|
||||
@@ -22,6 +30,8 @@ sqlite:
|
||||
defaults to false
|
||||
```
|
||||
|
||||
Additional settings for SQLite.
|
||||
|
||||
## objects
|
||||
```yaml
|
||||
objects: boolean|image|pickle
|
||||
@@ -40,14 +50,27 @@ Object encoding options are:
|
||||
functions: list
|
||||
```
|
||||
|
||||
List of functions with user-defined SQL functions, only used when [content](#content) is enabled. Each list element must be one of the following:
|
||||
List of functions with user-defined SQL functions. Each list element must be one of the following:
|
||||
|
||||
- function
|
||||
- callable object
|
||||
- dict with fields for name, argcount and function
|
||||
- dict with fields for name, argcount, function and deterministic
|
||||
|
||||
[An example can be found here](../../query#custom-sql-functions).
|
||||
|
||||
## expressions
|
||||
```yaml
|
||||
expressions: list
|
||||
```
|
||||
|
||||
List of expression shortcuts. Each list element must be a dict with the following fields.
|
||||
|
||||
- `name`: name of the expression
|
||||
- `expression`: SQL expression, defaults to `name` when empty
|
||||
- `index`: if this expression should have a database index, defaults to False when not provided
|
||||
|
||||
The expression can be a json data column, sql function or anything that can be run as a SQL snippet.
|
||||
|
||||
## query
|
||||
```yaml
|
||||
query:
|
||||
|
||||
@@ -1,15 +1,35 @@
|
||||
# General
|
||||
|
||||
General configuration options that don't fit elsewhere.
|
||||
General configuration options.
|
||||
|
||||
## keyword
|
||||
```yaml
|
||||
keyword: boolean
|
||||
keyword: boolean|string
|
||||
```
|
||||
|
||||
Enables sparse keyword indexing for this embeddings.
|
||||
|
||||
When enabled, this parameter creates a BM25 index for full text search. It also implicitly disables the [defaults](../vectors/#defaults) setting for vector search.
|
||||
When set to a boolean, this parameter creates a BM25 index for full text search. When set to a string, it expects a [keyword method](../scoring#method).
|
||||
|
||||
It also implicitly disables the [defaults](#defaults) setting for vector search.
|
||||
|
||||
## sparse
|
||||
```yaml
|
||||
sparse: boolean|path
|
||||
```
|
||||
|
||||
Enables sparse vector indexing for this embeddings.
|
||||
|
||||
When set to `True`, this parameter creates a sparse vector index using the [default sparse index model](https://huggingface.co/prithivida/Splade_PP_en_v2). When set to a string, it expects a local or Hugging Face model path.
|
||||
|
||||
It also implicitly disables the [defaults](#defaults) setting for vector search.
|
||||
|
||||
## dense
|
||||
```yaml
|
||||
dense: boolean|string
|
||||
```
|
||||
|
||||
Alias for the [vector model path](../vectors/#path). When set to `True`, the [default transformers vector model](https://huggingface.co/sentence-transformers/all-MiniLM-L6-v2) is used.
|
||||
|
||||
## hybrid
|
||||
```yaml
|
||||
@@ -18,7 +38,14 @@ hybrid: boolean
|
||||
|
||||
Enables hybrid (sparse + dense) indexing for this embeddings.
|
||||
|
||||
When enabled, this parameter creates a BM25 index for full text search. It has no effect on the [defaults](../vectors/#defaults) or [path](../vectors/#path) settings.
|
||||
When enabled, this parameter creates a BM25 index for full text search. It has no effect on the [defaults](#defaults) or [path](../vectors/#path) settings.
|
||||
|
||||
## defaults
|
||||
```yaml
|
||||
defaults: boolean
|
||||
```
|
||||
|
||||
Uses default vector model path when enabled (default setting is True) and `path` is not provided. See [this link](../) for an example.
|
||||
|
||||
## indexes
|
||||
```yaml
|
||||
@@ -39,13 +66,18 @@ Sets the auto id generation method. When this is not set, an autogenerated numer
|
||||
columns:
|
||||
text: name of the text column
|
||||
object: name of the object column
|
||||
store: limit json data fields to this list of columns
|
||||
```
|
||||
|
||||
Sets the `text` and `object` column names. Defaults to `text` and `object` if not provided.
|
||||
|
||||
`store` sets a list of columns to store in the JSON data field. When this isn't provided, all columns are stored (default). When `store` is set to `None`, no JSON columns are stored. This is useful is a field is only needed at indexing time but not search time.
|
||||
|
||||
## format
|
||||
```yaml
|
||||
format: json|pickle
|
||||
```
|
||||
|
||||
Sets the configuration storage format. Defaults to `json`.
|
||||
|
||||
Note that `pickle` configuration is deprecated and will raise an error with the default settings. Its only kept for reading legacy indexes and requires setting the `ALLOW_PICKLE` environment variable. Only enable for local and/or trusted sources.
|
||||
|
||||
@@ -19,6 +19,8 @@ The `rdbms` backend has the following additional settings.
|
||||
```yaml
|
||||
url: database url connection string, alternatively can be set via the
|
||||
GRAPH_URL environment variable
|
||||
schema: database schema to store graph - defaults to being
|
||||
determined by the database
|
||||
nodes: table to store node data, defaults to `nodes`
|
||||
edges: table to store edge data, defaults to `edges`
|
||||
```
|
||||
@@ -68,3 +70,11 @@ topics:
|
||||
```
|
||||
|
||||
Enables topic modeling. Defaults are tuned so that in most cases these values don't need to be changed (except for categories). These parameters are available for advanced use cases where one wants full control over the community detection process.
|
||||
|
||||
## copyattributes
|
||||
```yaml
|
||||
copyattributes: boolean|list
|
||||
```
|
||||
|
||||
Copy these attributes from input dictionaries in the `insert` method. If this is set to `True`, all attributes are copied. Otherwise, only the
|
||||
attributes specified in this list are copied to the graph as attributes.
|
||||
|
||||
@@ -12,11 +12,70 @@ The following covers the available options.
|
||||
|
||||
## method
|
||||
```yaml
|
||||
method: bm25|tfidf|sif|custom
|
||||
method: bm25|tfidf|sif|pgtext|sparse|custom
|
||||
```
|
||||
|
||||
Sets the scoring method. Add custom scoring via setting this parameter to the fully resolvable class string.
|
||||
|
||||
### pgtext
|
||||
```yaml
|
||||
schema: database schema to store keyword index - defaults to being
|
||||
determined by the database
|
||||
```
|
||||
|
||||
Additional settings for Postgres full-text keyword indexes.
|
||||
|
||||
### sparse
|
||||
```yaml
|
||||
path: sparse vector model path
|
||||
vectormethod: vector embeddings method
|
||||
vectornormalize: enable vector embeddings normalization (boolean)
|
||||
gpu: boolean|int|string|device
|
||||
normalize: enable score normalization (boolean|float|string|dict)
|
||||
batch: Sets the transform batch size
|
||||
encodebatch: Sets the encode batch size
|
||||
vectors: additional model init args
|
||||
encodeargs: additional encode() args
|
||||
backend: ivfsparse|pgsparse|zvecsparse
|
||||
```
|
||||
|
||||
Sparse vector scoring options. The sparse scoring instance combines a sparse vector model with a sparse approximate nearest neighbor index (ANN). This method supports both vector normalization and score normalization.
|
||||
|
||||
Vector normalization normalizes all vectors to have a magnitude of 1. By extension, all generated scores will be 0 to 1.
|
||||
|
||||
Score normalization scales the output between 0 and 1. This setting supports:
|
||||
|
||||
- `True` for default scale normalization
|
||||
- `float` normalize using this as the scale factor
|
||||
- `"bayes"` for Bayesian normalization using dynamic candidate score statistics
|
||||
- `{method: "bayes", alpha: 1.0, beta: null}` for Bayesian normalization with optional custom parameters
|
||||
|
||||
#### ivfsparse
|
||||
```yaml
|
||||
ivfsparse:
|
||||
sample: percent of data to use for model training (0.0 - 1.0)
|
||||
nfeatures: top n features to use for model training, defaults to all features (int)
|
||||
nlist: desired number of clusters (int)
|
||||
nprobe: search probe setting (int)
|
||||
minpoints: minimum number of points for a cluster (int)
|
||||
```
|
||||
|
||||
Inverted file (IVF) index with flat vector file storage and sparse array support.
|
||||
|
||||
#### pgsparse
|
||||
|
||||
Sparse ANN backed by Postgres. Supports same options as the [pgvector](../ann/#pgvector) ANN.
|
||||
|
||||
#### zvecsparse
|
||||
```yaml
|
||||
zvecsparse:
|
||||
efconstruction: ef_construction param for HnswIndexParam (int) - defaults to 200
|
||||
m: number of HNSW links per element (int) - defaults to 50
|
||||
efsearch: ef search param for HnswQueryParam (int) - defaults to 300
|
||||
```
|
||||
|
||||
Sparse ANN backed by [zvec](https://github.com/alibaba/zvec). Stores sparse vectors in an embedded, path-based vector index. Requires the [ann](../../../install/#ann) extras package.
|
||||
|
||||
## terms
|
||||
```yaml
|
||||
terms: boolean|dict
|
||||
@@ -32,9 +91,38 @@ Supports a `dict` with the parameters `cachelimit` and `cutoff`.
|
||||
|
||||
When `terms` is set to `True`, default parameters are used for the `cachelimit` and `cutoff`. Normally, these defaults are sufficient.
|
||||
|
||||
### Wildcard queries
|
||||
|
||||
Keyword queries containing `*` expand matching terms using SQL `LIKE`. Within these
|
||||
expressions, `%` matches any sequence and `_` matches one character. To match a literal
|
||||
percent sign, underscore or backslash, use `\%`, `\_` or `\\`, respectively.
|
||||
For example, `report\_*` matches `report_2026`, while `report_*` also matches `reportX2026`.
|
||||
Use a tokenizer that preserves these characters, such as `tokenizer: {whitespace: true}`,
|
||||
or pass pre-tokenized query terms. Queries without `*` retain exact-term matching.
|
||||
|
||||
## normalize
|
||||
```yaml
|
||||
normalize: boolean
|
||||
normalize: boolean|str|dict
|
||||
```
|
||||
|
||||
Enables normalized scoring (ranging from 0 to 1). When enabled, statistics from the index will be used to calculate normalized scores.
|
||||
Enables normalized scoring (ranging from 0 to 1). This setting supports:
|
||||
|
||||
- `True` for standard score normalization
|
||||
- `"bayes"` | `"bb25"` for Bayesian normalization using dynamic candidate score statistics
|
||||
- `{method: "bayes", alpha: 1.0, beta: null}` for Bayesian normalization with optional custom parameters
|
||||
|
||||
When standard normalization is enabled, statistics from the index are used to calculate normalized scores.
|
||||
When Bayesian/BB25 normalization is enabled, it uses positive-score candidates, dynamic `beta=median(scores)`, adaptive
|
||||
`alpha_eff=alpha/std(scores)` and a sigmoid transform (likelihood-only variant with flat prior) to map scores to `[0, 1]`.
|
||||
|
||||
Bayesian normalization references:
|
||||
|
||||
- [https://github.com/instructkr/bb25](https://github.com/instructkr/bb25)
|
||||
- [https://github.com/cognica-io/bayesian-bm25](https://github.com/cognica-io/bayesian-bm25)
|
||||
|
||||
## tokenizer
|
||||
```yaml
|
||||
tokenizer: dict
|
||||
```
|
||||
|
||||
Set tokenization rules. Passes these arguments to the underlying [Tokenization pipeline](../../../pipeline/data/tokenizer#txtai.pipeline.Tokenizer.__init__).
|
||||
|
||||
@@ -10,16 +10,10 @@ path: string
|
||||
Sets the path for a vectors model. When using a transformers/sentence-transformers model, this can be any model on the
|
||||
[Hugging Face Hub](https://huggingface.co/models) or a local file path. Otherwise, it must be a local file path to a word embeddings model.
|
||||
|
||||
## defaults
|
||||
```yaml
|
||||
defaults: boolean
|
||||
```
|
||||
|
||||
Uses default vector model path when enabled (default setting is True) and `path` is not provided. See [this link](../) for an example.
|
||||
|
||||
## method
|
||||
```yaml
|
||||
method: transformers|sentence-transformers|llama.cpp|litellm|model2vec|external|words
|
||||
method: transformers|sentence-transformers|llama.cpp|litellm|model2vec|external|
|
||||
words
|
||||
```
|
||||
|
||||
Embeddings method to use. If the method is not provided, it is inferred using the `path`.
|
||||
@@ -31,11 +25,12 @@ Embeddings method to use. If the method is not provided, it is inferred using th
|
||||
Builds embeddings using a transformers model. While this can be any transformers model, it works best with
|
||||
[models trained](https://huggingface.co/models?pipeline_tag=sentence-similarity) to build embeddings.
|
||||
|
||||
Both `mean` and `cls` pooling are supported and automatically inferred from the model. The pooling method can be overwritten by changing the method
|
||||
from `transformers` to `meanpooling` or `clspooling` respectively.
|
||||
`mean`, `cls`, `last`, `late` and `max` pooling are supported and automatically inferred from the model. The pooling method can be overwritten by changing the method from `transformers` to `meanpooling`, `clspooling`, `lastpooling`, `latepooling` or `maxpooling` respectively.
|
||||
|
||||
Setting `maxlength` to `True` enables truncating inputs to the `max_seq_length`. Setting `maxlength` to an integer will truncate inputs to that value. When omitted (default), the `maxlength` will be set to either the model or tokenizer maxlength.
|
||||
|
||||
Supports loading ONNX models directly. [See this section for more](../../../examples/#model-training).
|
||||
|
||||
### sentence-transformers
|
||||
|
||||
Same as transformers but loads models with the [sentence-transformers](https://github.com/UKPLab/sentence-transformers) library.
|
||||
@@ -50,18 +45,11 @@ Builds embeddings using a LiteLLM model. See the [LiteLLM documentation](https:/
|
||||
|
||||
### model2vec
|
||||
|
||||
Builds embeddings using a [Model2Vec](https://github.com/MinishLab/model2vec) model.
|
||||
Builds embeddings using a [Model2Vec](https://github.com/MinishLab/model2vec) model. Model2Vec is a knowledge-distilled version of a transformers model with static vectors.
|
||||
|
||||
### words
|
||||
|
||||
Builds embeddings using a word embeddings model. Transformers models are the preferred vector backend in most cases. Word embeddings models may be deprecated in the future.
|
||||
|
||||
#### storevectors
|
||||
```yaml
|
||||
storevectors: boolean
|
||||
```
|
||||
|
||||
Enables copying of a vectors model set in path into the embeddings models output directory on save. This option enables a fully encapsulated index with no external file dependencies.
|
||||
Builds embeddings using a word embeddings model and static vectors. While Transformers models are preferred in most cases, this method can be useful for low resource and historical languages where there isn't much linguistic data available.
|
||||
|
||||
#### pca
|
||||
```yaml
|
||||
@@ -79,7 +67,9 @@ Embeddings are created via an external model or API. Requires setting the [trans
|
||||
transform: function
|
||||
```
|
||||
|
||||
When method is `external`, this function transforms input content into embeddings. The input to this function is a list of data. This method must return either a numpy array or list of numpy arrays.
|
||||
When method is `external`, this function transforms input content into embeddings. The input to this function is a list of data. This method must return either a numpy array, list of numpy arrays or list of float arrays.
|
||||
|
||||
Note that this method is deprecated and will raise an error with the default settings. Adding a custom `Vectors` implementation is a cleaner approach. The `ALLOW_RESOLVE_TRANSFORM` environment variable must be set to enable. Only enable for trusted and/or reviewed code.
|
||||
|
||||
## gpu
|
||||
```yaml
|
||||
@@ -88,6 +78,8 @@ gpu: boolean|int|string|device
|
||||
|
||||
Set the target device. Supports true/false, device id, device string and torch device instance. This is automatically derived if omitted.
|
||||
|
||||
The `sentence-transformers` method supports encoding with multiple GPUs. This can be enabled by setting the gpu parameter to `all`.
|
||||
|
||||
## batch
|
||||
```yaml
|
||||
batch: int
|
||||
@@ -114,9 +106,9 @@ Enables truncation of vectors to this dimensionality. This is only useful for mo
|
||||
quantize: int|boolean
|
||||
```
|
||||
|
||||
Enables scalar vector quantization at the specified precision. Supports 1-bit through 8-bit quantization. Scalar quantization transforms continuous floating point values to discrete unsigned integers. Only the `faiss`, `numpy` and `torch` ANN backends support storing these vectors.
|
||||
Enables scalar vector quantization at the specified precision. Supports 1-bit through 8-bit quantization. Scalar quantization transforms continuous floating point values to discrete unsigned integers. The `faiss`, `pgvector`, `numpy` and `torch` ANN backends support storing these vectors.
|
||||
|
||||
This parameter supports booleans for backwards compatability. When set to true/false, this flag sets [faiss.quantize](../ann/#faiss).
|
||||
This parameter supports booleans for backwards compatibility. When set to true/false, this flag sets [faiss.quantize](../ann/#faiss).
|
||||
|
||||
In addition to vector-level quantization, some ANN backends have the ability to quantize vectors at the storage layer. See the [ANN](../ann) configuration options for more.
|
||||
|
||||
@@ -129,7 +121,7 @@ instructions:
|
||||
|
||||
Instruction-based models use prefixes to modify how embeddings are computed. This is especially useful with asymmetric search, which is when the query and indexed data are of vastly different lengths. In other words, short queries with long documents.
|
||||
|
||||
[E5-base](https://huggingface.co/intfloat/e5-base) is an example of a model that accepts instructions. It takes `query: ` and `passage: ` prefixes and uses those to generate embeddings that work well for asymmetric search.
|
||||
`txtai` automatically loads prompts stored in `config_sentence_transformers.json` except if this parameter is set. For some older models such as [E5-base](https://huggingface.co/intfloat/e5-base), instructions still need to be provided via this parameter.
|
||||
|
||||
## models
|
||||
```yaml
|
||||
@@ -151,3 +143,58 @@ vectors: dict
|
||||
```
|
||||
|
||||
Passes these additional parameters to the underlying vector model.
|
||||
|
||||
### center
|
||||
```yaml
|
||||
center: boolean | dict
|
||||
```
|
||||
|
||||
Centers normalized late-interaction token vectors and normalizes them again before MUVERA or LEMUR encoding. Centering is applied to
|
||||
both query and document vectors. `true` uses batch scope and `false` disables centering. An explicit setting always takes precedence.
|
||||
When omitted, a LEMUR artifact with a stored collection mean uses collection scope. Other LEMUR artifacts and late-interaction models
|
||||
default to batch scope only when they load more than one `torch.nn.Linear` layer; models with zero or one loaded linear layer keep their
|
||||
previous output.
|
||||
|
||||
Dictionary configuration supports the following scopes:
|
||||
|
||||
```yaml
|
||||
center:
|
||||
scope: document | batch | collection
|
||||
```
|
||||
|
||||
`document` subtracts the mean of each document or query independently. `batch` subtracts the mean of all real token rows in the current
|
||||
model batch. Explicit `collection` scope requires a caller-provided, one-dimensional mean vector through either `mean` (an array-like
|
||||
value) or `path` (a safetensors file containing a `center.mean` tensor), but not both. LEMUR artifacts can provide this mean
|
||||
automatically. Zero-padding rows are never centered and remain zero.
|
||||
|
||||
### muvera
|
||||
```yaml
|
||||
muvera:
|
||||
repetitions: defaults 20
|
||||
hashes: defaults to 5
|
||||
projection: defaults 16
|
||||
```
|
||||
|
||||
Settings to control the size of MUVERA fixed dimensional outputs. Default is 20 * 2^5 * 16 = 10,240 dimensions.
|
||||
Set `muvera` to `false` to disable it or `true` to use the default settings. `false` only makes sense when the multi-vector output
|
||||
is consumed directly, for example through `PoolingFactory`. Embeddings vectors require `muvera` or `lemur`.
|
||||
|
||||
### lemur
|
||||
```yaml
|
||||
lemur:
|
||||
path: local artifact directory or Hugging Face Hub path
|
||||
```
|
||||
|
||||
Loads a trained [LEMUR](../../../pipeline/train/lemur) fixed dimensional encoder. LEMUR artifacts are corpus-specific and must be
|
||||
created with `LemurTrainer` before configuring an embeddings index. A bare string is treated as the artifact path. Query vectors are
|
||||
summed learned features and document vectors are ordinary least squares weights over the artifact's stored token sample. Each artifact
|
||||
contains `config.json` and `model.safetensors`; newly trained artifacts also store the collection token mean as `lemur.center`. Loading that mean automatically
|
||||
selects collection centering unless `center` is explicitly configured. Artifacts without `lemur.center` retain the previous default.
|
||||
The Safetensors file contains inference state only. See the trainer page for score filtering and Faiss exact/IVF search behavior.
|
||||
|
||||
### trust_remote_code
|
||||
```yaml
|
||||
trust_remote_code: boolean
|
||||
```
|
||||
|
||||
Parameter for trusting the code from Hugging Face models with custom implementations.
|
||||
|
||||
@@ -100,6 +100,23 @@ The search method takes two parameters, the query and query limit. The results f
|
||||
|
||||
Both natural language and SQL queries are supported. More information can be found in the [query guide](query).
|
||||
|
||||
## Resource management
|
||||
|
||||
Embeddings databases are context managers. The following blocks automatically [close](methods/#txtai.embeddings.base.Embeddings.close) and free resources upon completion.
|
||||
|
||||
```python
|
||||
# Create a new Embeddings database, index data and save
|
||||
with Embeddings() as embeddings:
|
||||
embeddings.index(rows)
|
||||
embeddings.save(path)
|
||||
|
||||
# Search a saved Embeddings database
|
||||
with Embeddings().load(path) as embeddings:
|
||||
embeddings.search(query)
|
||||
```
|
||||
|
||||
While calling `close` isn't always necessary (resources will be garbage collected), it's best to free shared resources like database connections as soon as they aren't needed.
|
||||
|
||||
## More examples
|
||||
|
||||
See [this link](../examples/#semantic-search) for a full list of embeddings examples.
|
||||
@@ -23,6 +23,8 @@ As mentioned above, computed vectors are stored in an ANN. There are various ind
|
||||
|
||||
Embeddings indexes can optionally [store content](../configuration/database#content). When this is enabled, the input content is saved in a database alongside the computed vectors. This enables filtering on additional fields and content retrieval.
|
||||
|
||||
The columns used for text, object and JSON data storage are set via [column configuration](../configuration/general#columns).
|
||||
|
||||
## Index vs Upsert
|
||||
|
||||
Data is loaded into an index with either an [index](../methods#txtai.embeddings.base.Embeddings.index) or [upsert](../methods#txtai.embeddings.base.Embeddings.upsert) call.
|
||||
@@ -112,7 +114,7 @@ Graphs are persisted alongside an embeddings index. Each save and load will also
|
||||
|
||||
## Sparse vectors
|
||||
|
||||
Scoring instances can create a standalone [keyword](../configuration/general#keyword) or sparse index (BM25, TF-IDF). This enables [hybrid](../configuration/general/#hybrid) search when there is an available dense vector index.
|
||||
Scoring instances can create a standalone [sparse keyword indexes](../configuration/general#keyword) (BM25, TF-IDF) and [sparse vector indexes](../configuration/general#sparse) (SPLADE). This enables [hybrid](../configuration/general/#hybrid) search when there is an available dense vector index.
|
||||
|
||||
The terms `sparse vector index`, `keyword index`, `terms index` and `scoring index` are used interchangeably throughout txtai's documentation.
|
||||
|
||||
|
||||
@@ -54,6 +54,8 @@ The number of candidates should be larger than the desired number of results whe
|
||||
- For a single query filter clause, the default is the query limit
|
||||
- With multiple filtering clauses, the default is 10x the query limit
|
||||
|
||||
When a query orders results by score, its `offset` adds to the query limit.
|
||||
|
||||
The index name is only applicable when [subindexes](../configuration/general/#indexes) are enabled. This specifies the index to use for the query.
|
||||
|
||||
Weights sets the hybrid score weights when an index has both a sparse and dense index.
|
||||
@@ -132,8 +134,11 @@ embeddings = Embeddings(content=True, objects=True)
|
||||
request = open("demo.gif", "rb")
|
||||
|
||||
# Insert record
|
||||
embeddings.index([("txtai", {"text": "txtai executes machine-learning workflows.",
|
||||
"object": request.read()})])
|
||||
embeddings.index([(
|
||||
"txtai",
|
||||
{"text": "txtai executes machine-learning workflows.",
|
||||
"object": request.read()}
|
||||
)])
|
||||
|
||||
# Query txtai and get associated object
|
||||
query = "SELECT object FROM txtai WHERE similar('machine learning') LIMIT 1"
|
||||
@@ -169,6 +174,26 @@ LIMIT 1
|
||||
""")
|
||||
```
|
||||
|
||||
## Expressions
|
||||
|
||||
Expression shortcuts expand into more complex SQL snippets. This is useful for making SQL queries more concise. Indexing is also available on expressions as a performance improvement.
|
||||
|
||||
The following example indexes a json extraction field (`filepath`) and the length of each field.
|
||||
|
||||
```python
|
||||
# Create embeddings index
|
||||
embeddings = Embeddings(
|
||||
path="sentence-transformers/nli-mpnet-base-v2",
|
||||
content=True,
|
||||
expressions=[
|
||||
{"name": "filepath", "index": True},
|
||||
{"name": "textlength", "expression": "length(text)", "index": True}
|
||||
]
|
||||
)
|
||||
|
||||
embeddings.search("SELECT textlength, filepath FROM txtai LIMIT 1")
|
||||
```
|
||||
|
||||
## Query translation
|
||||
|
||||
Natural language queries with filters can be converted to txtai-compatible SQL statements with query translation. For example:
|
||||
@@ -192,7 +217,9 @@ When an embeddings database has both a sparse and dense index, both indexes will
|
||||
|
||||
```python
|
||||
embeddings.search("query", weights=0.5)
|
||||
embeddings.search("SELECT id, text, score FROM txtai WHERE similar('query', 0.5)")
|
||||
embeddings.search(
|
||||
"SELECT id, text, score FROM txtai WHERE similar('query', 0.5)"
|
||||
)
|
||||
```
|
||||
|
||||
## Graph search
|
||||
@@ -203,11 +230,20 @@ Additionally, standard embeddings searches can be returned as graphs.
|
||||
|
||||
```python
|
||||
# Find all paths between id: 0 and id: 5 between 1 and 3 hops away
|
||||
embeddings.graph.search("""
|
||||
embeddings.search("""
|
||||
MATCH P=({id: 0})-[*1..3]->({id: 5})
|
||||
RETURN P
|
||||
""")
|
||||
|
||||
# Find related nodes for query matches
|
||||
embeddings.search("""
|
||||
MATCH P=(A)-[]->(B)
|
||||
WHERE SIMILAR(A, "query")
|
||||
RETURN B
|
||||
ORDER BY A.score DESC
|
||||
LIMIT 10
|
||||
""")
|
||||
|
||||
# Standard embeddings search as graph
|
||||
embeddings.search("query", graph=True)
|
||||
```
|
||||
@@ -217,13 +253,28 @@ embeddings.search("query", graph=True)
|
||||
Subindexes can be queried as follows:
|
||||
|
||||
```python
|
||||
# Build index with subindexes
|
||||
embeddings = Embeddings(
|
||||
content=True,
|
||||
defaults=False,
|
||||
indexes={
|
||||
"keyword": {
|
||||
"keyword": True
|
||||
},
|
||||
"dense":{
|
||||
"dense": True
|
||||
}
|
||||
}
|
||||
)
|
||||
embeddings.index(stream())
|
||||
|
||||
# Query with index parameter
|
||||
embeddings.search("query", index="subindex1")
|
||||
embeddings.search("query", index="keyword")
|
||||
|
||||
# Specify with SQL
|
||||
embeddings.search("""
|
||||
SELECT id, text, score FROM txtai
|
||||
WHERE similar('query', 'subindex1')
|
||||
WHERE similar('query', 'keyword')
|
||||
""")
|
||||
```
|
||||
|
||||
|
||||
+21
-3
@@ -31,7 +31,7 @@ Autonomous agents, retrieval augmented generation (RAG), chat with your data, pi
|
||||
|:----------|:-------------|------:|
|
||||
| [Prompt-driven search with LLMs](https://github.com/neuml/txtai/blob/master/examples/42_Prompt_driven_search_with_LLMs.ipynb) | Embeddings-guided and Prompt-driven search with Large Language Models (LLMs) | [](https://colab.research.google.com/github/neuml/txtai/blob/master/examples/42_Prompt_driven_search_with_LLMs.ipynb) |
|
||||
| [Prompt templates and task chains](https://github.com/neuml/txtai/blob/master/examples/44_Prompt_templates_and_task_chains.ipynb) | Build model prompts and connect tasks together with workflows | [](https://colab.research.google.com/github/neuml/txtai/blob/master/examples/44_Prompt_templates_and_task_chains.ipynb) |
|
||||
| [Build RAG pipelines with txtai](https://github.com/neuml/txtai/blob/master/examples/52_Build_RAG_pipelines_with_txtai.ipynb) | Guide on retrieval augmented generation including how to create citations | [](https://colab.research.google.com/github/neuml/txtai/blob/master/examples/52_Build_RAG_pipelines_with_txtai.ipynb) |
|
||||
| [Build RAG pipelines with txtai](https://github.com/neuml/txtai/blob/master/examples/52_Build_RAG_pipelines_with_txtai.ipynb) [▶️](https://www.youtube.com/watch?v=t_OeAc8NVfQ) | Guide on retrieval augmented generation including how to create citations | [](https://colab.research.google.com/github/neuml/txtai/blob/master/examples/52_Build_RAG_pipelines_with_txtai.ipynb) |
|
||||
| [Integrate LLM frameworks](https://github.com/neuml/txtai/blob/master/examples/53_Integrate_LLM_Frameworks.ipynb) | Integrate llama.cpp, LiteLLM and custom generation frameworks | [](https://colab.research.google.com/github/neuml/txtai/blob/master/examples/53_Integrate_LLM_Frameworks.ipynb) |
|
||||
| [Generate knowledge with Semantic Graphs and RAG](https://github.com/neuml/txtai/blob/master/examples/55_Generate_knowledge_with_Semantic_Graphs_and_RAG.ipynb) | Knowledge exploration and discovery with Semantic Graphs and RAG | [](https://colab.research.google.com/github/neuml/txtai/blob/master/examples/55_Generate_knowledge_with_Semantic_Graphs_and_RAG.ipynb) |
|
||||
| [Build knowledge graphs with LLMs](https://github.com/neuml/txtai/blob/master/examples/57_Build_knowledge_graphs_with_LLM_driven_entity_extraction.ipynb) | Build knowledge graphs with LLM-driven entity extraction | [](https://colab.research.google.com/github/neuml/txtai/blob/master/examples/57_Build_knowledge_graphs_with_LLM_driven_entity_extraction.ipynb) |
|
||||
@@ -40,6 +40,19 @@ Autonomous agents, retrieval augmented generation (RAG), chat with your data, pi
|
||||
| [RAG with llama.cpp and external API services](https://github.com/neuml/txtai/blob/master/examples/62_RAG_with_llama_cpp_and_external_API_services.ipynb) | RAG with additional vector and LLM frameworks | [](https://colab.research.google.com/github/neuml/txtai/blob/master/examples/62_RAG_with_llama_cpp_and_external_API_services.ipynb) |
|
||||
| [How RAG with txtai works](https://github.com/neuml/txtai/blob/master/examples/63_How_RAG_with_txtai_works.ipynb) | Create RAG processes, API services and Docker instances | [](https://colab.research.google.com/github/neuml/txtai/blob/master/examples/63_How_RAG_with_txtai_works.ipynb) |
|
||||
| [Speech to Speech RAG](https://github.com/neuml/txtai/blob/master/examples/65_Speech_to_Speech_RAG.ipynb) [▶️](https://www.youtube.com/watch?v=tH8QWwkVMKA) | Full cycle speech to speech workflow with RAG | [](https://colab.research.google.com/github/neuml/txtai/blob/master/examples/65_Speech_to_Speech_RAG.ipynb) |
|
||||
| [Analyzing Hugging Face Posts with Graphs and Agents](https://github.com/neuml/txtai/blob/master/examples/68_Analyzing_Hugging_Face_Posts_with_Graphs_and_Agents.ipynb) | Explore a rich dataset with Graph Analysis and Agents | [](https://colab.research.google.com/github/neuml/txtai/blob/master/examples/68_Analyzing_Hugging_Face_Posts_with_Graphs_and_Agents.ipynb) |
|
||||
| [Granting autonomy to agents](https://github.com/neuml/txtai/blob/master/examples/69_Granting_autonomy_to_agents.ipynb) | Agents that iteratively solve problems as they see fit | [](https://colab.research.google.com/github/neuml/txtai/blob/master/examples/69_Granting_autonomy_to_agents.ipynb) |
|
||||
| [Getting started with LLM APIs](https://github.com/neuml/txtai/blob/master/examples/70_Getting_started_with_LLM_APIs.ipynb) | Generate embeddings and run LLMs with OpenAI, Claude, Gemini, Bedrock and more | [](https://colab.research.google.com/github/neuml/txtai/blob/master/examples/70_Getting_started_with_LLM_APIs.ipynb) |
|
||||
| [Analyzing LinkedIn Company Posts with Graphs and Agents](https://github.com/neuml/txtai/blob/master/examples/71_Analyzing_LinkedIn_Company_Posts_with_Graphs_and_Agents.ipynb) | Exploring how to improve social media engagement with AI | [](https://colab.research.google.com/github/neuml/txtai/blob/master/examples/71_Analyzing_LinkedIn_Company_Posts_with_Graphs_and_Agents.ipynb) |
|
||||
| [Parsing the stars with txtai](https://github.com/neuml/txtai/blob/master/examples/72_Parsing_the_stars_with_txtai.ipynb) | Explore an astronomical knowledge graph of known stars, planets, galaxies | [](https://colab.research.google.com/github/neuml/txtai/blob/master/examples/72_Parsing_the_stars_with_txtai.ipynb) |
|
||||
| [Chunking your data for RAG](https://github.com/neuml/txtai/blob/master/examples/73_Chunking_your_data_for_RAG.ipynb) | Extract, chunk and index content for effective retrieval | [](https://colab.research.google.com/github/neuml/txtai/blob/master/examples/73_Chunking_your_data_for_RAG.ipynb) |
|
||||
| [Medical RAG Research with txtai](https://github.com/neuml/txtai/blob/master/examples/75_Medical_RAG_Research_with_txtai.ipynb) | Analyze PubMed article metadata with RAG | [](https://colab.research.google.com/github/neuml/txtai/blob/master/examples/75_Medical_RAG_Research_with_txtai.ipynb) |
|
||||
| [GraphRAG with Wikipedia and GPT OSS](https://github.com/neuml/txtai/blob/master/examples/77_GraphRAG_with_Wikipedia_and_GPT_OSS.ipynb) | Deep graph search powered RAG | [](https://colab.research.google.com/github/neuml/txtai/blob/master/examples/77_GraphRAG_with_Wikipedia_and_GPT_OSS.ipynb) |
|
||||
| [RAG is more than Vector Search](https://github.com/neuml/txtai/blob/master/examples/79_RAG_is_more_than_Vector_Search.ipynb) | Context retrieval via Web, SQL and other sources | [](https://colab.research.google.com/github/neuml/txtai/blob/master/examples/79_RAG_is_more_than_Vector_Search.ipynb) |
|
||||
| [OpenCode as a txtai LLM](https://github.com/neuml/txtai/blob/master/examples/81_OpenCode_as_a_txtai_LLM.ipynb) | Integrate OpenCode with the txtai ecosystem | [](https://colab.research.google.com/github/neuml/txtai/blob/master/examples/81_OpenCode_as_a_txtai_LLM.ipynb) |
|
||||
| [Agentic College Search](https://github.com/neuml/txtai/blob/master/examples/82_Agentic_College_Search.ipynb) | Identify a list of strong engineering colleges | [](https://colab.research.google.com/github/neuml/txtai/blob/master/examples/82_Agentic_College_Search.ipynb) |
|
||||
| [TxtAI got skills](https://github.com/neuml/txtai/blob/master/examples/83_TxtAI_got_skills.ipynb) | Integrate skill.md files with your agent | [](https://colab.research.google.com/github/neuml/txtai/blob/master/examples/83_TxtAI_got_skills.ipynb) |
|
||||
| [Agent Tools](https://github.com/neuml/txtai/blob/master/examples/84_Agent_Tools.ipynb) [▶️](https://www.youtube.com/watch?v=RDNaFXQy3GQ) | Learn about the txtai agent toolkit | [](https://colab.research.google.com/github/neuml/txtai/blob/master/examples/84_Agent_Tools.ipynb) |
|
||||
|
||||
## Pipelines
|
||||
|
||||
@@ -77,7 +90,7 @@ Efficiently process data at scale.
|
||||
|
||||
## Model Training
|
||||
|
||||
Train NLP models.
|
||||
Train, distill, fine-tune and export models.
|
||||
|
||||
| Notebook | Description | |
|
||||
|:----------|:-------------|------:|
|
||||
@@ -85,6 +98,8 @@ Train NLP models.
|
||||
| [Train without labels](https://github.com/neuml/txtai/blob/master/examples/17_Train_without_labels.ipynb) | Use zero-shot classifiers to train new models | [](https://colab.research.google.com/github/neuml/txtai/blob/master/examples/17_Train_without_labels.ipynb) |
|
||||
| [Train a QA model](https://github.com/neuml/txtai/blob/master/examples/19_Train_a_QA_model.ipynb) | Build and fine-tune question-answering models | [](https://colab.research.google.com/github/neuml/txtai/blob/master/examples/19_Train_a_QA_model.ipynb) |
|
||||
| [Train a language model from scratch](https://github.com/neuml/txtai/blob/master/examples/41_Train_a_language_model_from_scratch.ipynb) | Build new language models | [](https://colab.research.google.com/github/neuml/txtai/blob/master/examples/41_Train_a_language_model_from_scratch.ipynb) |
|
||||
| [Distilling Knowledge into Tiny LLMs](https://github.com/neuml/txtai/blob/master/examples/80_Distilling_Knowledge_into_Tiny_LLMs.ipynb) [▶️](https://www.youtube.com/watch?v=Ol560ktgkf0) | Finetune tiny LLMs to enable inference using less resources | [](https://colab.research.google.com/github/neuml/txtai/blob/master/examples/80_Distilling_Knowledge_into_Tiny_LLMs.ipynb) |
|
||||
| [Progressive Distillation](https://github.com/neuml/txtai/blob/master/examples/85_Progressive_Distillation.ipynb) | Incrementally compress knowledge from a series of teachers | [](https://colab.research.google.com/github/neuml/txtai/blob/master/examples/85_Progressive_Distillation.ipynb) |
|
||||
| [Export and run models with ONNX](https://github.com/neuml/txtai/blob/master/examples/18_Export_and_run_models_with_ONNX.ipynb) | Export models with ONNX, run natively in JavaScript, Java and Rust | [](https://colab.research.google.com/github/neuml/txtai/blob/master/examples/18_Export_and_run_models_with_ONNX.ipynb) |
|
||||
| [Export and run other machine learning models](https://github.com/neuml/txtai/blob/master/examples/21_Export_and_run_other_machine_learning_models.ipynb) | Export and run models from scikit-learn, PyTorch and more | [](https://colab.research.google.com/github/neuml/txtai/blob/master/examples/21_Export_and_run_other_machine_learning_models.ipynb) |
|
||||
|
||||
@@ -99,6 +114,7 @@ Run distributed txtai, integrate with the API and cloud endpoints.
|
||||
| [Embeddings in the Cloud](https://github.com/neuml/txtai/blob/master/examples/43_Embeddings_in_the_Cloud.ipynb) | Load and use an embeddings index from the Hugging Face Hub | [](https://colab.research.google.com/github/neuml/txtai/blob/master/examples/43_Embeddings_in_the_Cloud.ipynb) |
|
||||
| [Custom API Endpoints](https://github.com/neuml/txtai/blob/master/examples/51_Custom_API_Endpoints.ipynb) | Extend the API with custom endpoints | [](https://colab.research.google.com/github/neuml/txtai/blob/master/examples/51_Custom_API_Endpoints.ipynb) |
|
||||
| [API Authorization and Authentication](https://github.com/neuml/txtai/blob/master/examples/54_API_Authorization_and_Authentication.ipynb) | Add authorization, authentication and middleware dependencies to the API | [](https://colab.research.google.com/github/neuml/txtai/blob/master/examples/54_API_Authorization_and_Authentication.ipynb) |
|
||||
| [OpenAI Compatible API](https://github.com/neuml/txtai/blob/master/examples/74_OpenAI_Compatible_API.ipynb) | Connect to txtai with a standard OpenAI client library | [](https://colab.research.google.com/github/neuml/txtai/blob/master/examples/74_OpenAI_Compatible_API.ipynb) |
|
||||
|
||||
## Architecture
|
||||
|
||||
@@ -109,13 +125,14 @@ Project architecture, data formats, external integrations, scale to production,
|
||||
| [Anatomy of a txtai index](https://github.com/neuml/txtai/blob/master/examples/29_Anatomy_of_a_txtai_index.ipynb) | Deep dive into the file formats behind a txtai embeddings index | [](https://colab.research.google.com/github/neuml/txtai/blob/master/examples/29_Anatomy_of_a_txtai_index.ipynb) |
|
||||
| [Embeddings components](https://github.com/neuml/txtai/blob/master/examples/37_Embeddings_index_components.ipynb) | Composable search with vector, SQL and scoring components | [](https://colab.research.google.com/github/neuml/txtai/blob/master/examples/37_Embeddings_index_components.ipynb) |
|
||||
| [Customize your own embeddings database](https://github.com/neuml/txtai/blob/master/examples/45_Customize_your_own_embeddings_database.ipynb) | Ways to combine vector indexes with relational databases | [](https://colab.research.google.com/github/neuml/txtai/blob/master/examples/45_Customize_your_own_embeddings_database.ipynb) |
|
||||
| [Building an efficient sparse keyword index in Python](https://github.com/neuml/txtai/blob/master/examples/47_Building_an_efficient_sparse_keyword_index_in_Python.ipynb) | Fast and accurate sparse keyword indexing | [](https://colab.research.google.com/github/neuml/txtai/blob/master/examples/48_Benefits_of_hybrid_search.ipynb) |
|
||||
| [Building an efficient sparse keyword index in Python](https://github.com/neuml/txtai/blob/master/examples/47_Building_an_efficient_sparse_keyword_index_in_Python.ipynb) | Fast and accurate sparse keyword indexing | [](https://colab.research.google.com/github/neuml/txtai/blob/master/examples/47_Building_an_efficient_sparse_keyword_index_in_Python.ipynb) |
|
||||
| [Benefits of hybrid search](https://github.com/neuml/txtai/blob/master/examples/48_Benefits_of_hybrid_search.ipynb) | Improve accuracy with a combination of semantic and keyword search | [](https://colab.research.google.com/github/neuml/txtai/blob/master/examples/48_Benefits_of_hybrid_search.ipynb) |
|
||||
| [External database integration](https://github.com/neuml/txtai/blob/master/examples/49_External_database_integration.ipynb) | Store metadata in PostgreSQL, MariaDB, MySQL and more | [](https://colab.research.google.com/github/neuml/txtai/blob/master/examples/49_External_database_integration.ipynb) |
|
||||
| [All about vector quantization](https://github.com/neuml/txtai/blob/master/examples/50_All_about_vector_quantization.ipynb) | Benchmarking scalar and product quantization methods | [](https://colab.research.google.com/github/neuml/txtai/blob/master/examples/50_All_about_vector_quantization.ipynb) |
|
||||
| [External vectorization](https://github.com/neuml/txtai/blob/master/examples/56_External_vectorization.ipynb) | Vectorization with precomputed embeddings datasets and APIs | [](https://colab.research.google.com/github/neuml/txtai/blob/master/examples/56_External_vectorization.ipynb) |
|
||||
| [Integrate txtai with Postgres](https://github.com/neuml/txtai/blob/master/examples/61_Integrate_txtai_with_Postgres.ipynb) | Persist content, vectors and graph data in Postgres | [](https://colab.research.google.com/github/neuml/txtai/blob/master/examples/61_Integrate_txtai_with_Postgres.ipynb) |
|
||||
| [Embeddings index format for open data access](https://github.com/neuml/txtai/blob/master/examples/64_Embeddings_index_format_for_open_data_access.ipynb) | Platform and programming language independent data storage with txtai | [](https://colab.research.google.com/github/neuml/txtai/blob/master/examples/64_Embeddings_index_format_for_open_data_access.ipynb) |
|
||||
| [Accessing Low Level Vector APIs](https://github.com/neuml/txtai/blob/master/examples/78_Accessing_Low_Level_Vector_APIs.ipynb) | Build a vector database using txtai's low-level APIs | [](https://colab.research.google.com/github/neuml/txtai/blob/master/examples/78_Accessing_Low_Level_Vector_APIs.ipynb) |
|
||||
|
||||
## Releases
|
||||
|
||||
@@ -127,6 +144,7 @@ New functionality added in major releases.
|
||||
| [What's new in txtai 6.0](https://github.com/neuml/txtai/blob/master/examples/46_Whats_new_in_txtai_6_0.ipynb) | Sparse, hybrid and subindexes for embeddings, LLM improvements | [](https://colab.research.google.com/github/neuml/txtai/blob/master/examples/46_Whats_new_in_txtai_6_0.ipynb) |
|
||||
| [What's new in txtai 7.0](https://github.com/neuml/txtai/blob/master/examples/59_Whats_new_in_txtai_7_0.ipynb) | Semantic graph 2.0, LoRA/QLoRA training and binary API support | [](https://colab.research.google.com/github/neuml/txtai/blob/master/examples/59_Whats_new_in_txtai_7_0.ipynb) |
|
||||
| [What's new in txtai 8.0](https://github.com/neuml/txtai/blob/master/examples/67_Whats_new_in_txtai_8_0.ipynb) | Agents with txtai | [](https://colab.research.google.com/github/neuml/txtai/blob/master/examples/67_Whats_new_in_txtai_8_0.ipynb) |
|
||||
| [What's new in txtai 9.0](https://github.com/neuml/txtai/blob/master/examples/76_Whats_new_in_txtai_9_0.ipynb) | Learned sparse vectors, late interaction models and rerankers | [](https://colab.research.google.com/github/neuml/txtai/blob/master/examples/76_Whats_new_in_txtai_9_0.ipynb) |
|
||||
|
||||
## Applications
|
||||
|
||||
|
||||
+11
-6
@@ -30,11 +30,13 @@ Wrap the list or generator passed to the index call with tqdm. See [#478](https:
|
||||
|
||||
__Question__
|
||||
|
||||
What is the best way to analyze the content of a txtai index?
|
||||
What is the best way to analyze and debug a txtai process?
|
||||
|
||||
__Answer__
|
||||
|
||||
txtai has a console application that makes this easy. Read [this article](https://medium.com/neuml/insights-from-the-txtai-console-d307c28e149e) to learn more.
|
||||
See the [observability](../observability) section for more on how this can be enabled in txtai processes.
|
||||
|
||||
txtai also has a console application. [This article](https://medium.com/neuml/insights-from-the-txtai-console-d307c28e149e) has more details.
|
||||
|
||||
----------
|
||||
|
||||
@@ -66,11 +68,11 @@ import torch
|
||||
from transformers import AutoModelForCausalLM, AutoTokenizer
|
||||
from txtai import LLM
|
||||
|
||||
# Load Mistral-7B-OpenOrca
|
||||
path = "Open-Orca/Mistral-7B-OpenOrca"
|
||||
# Load Qwen3 0.6B
|
||||
path = "Qwen/Qwen3-0.6B"
|
||||
model = AutoModelForCausalLM.from_pretrained(
|
||||
path,
|
||||
torch_dtype=torch.bfloat16,
|
||||
dtype=torch.bfloat16,
|
||||
)
|
||||
tokenizer = AutoTokenizer.from_pretrained(path)
|
||||
|
||||
@@ -103,10 +105,13 @@ __Solution__
|
||||
|
||||
Set the following environment parameters.
|
||||
|
||||
- Disable OpenMP threading via the environment variable `export OMP_NUM_THREADS=1`
|
||||
- Disable OpenMP multithreading via `export OMP_NUM_THREADS=1`
|
||||
- Workaround `OMP: Error #15` errors via `export KMP_DUPLICATE_LIB_OK=TRUE`
|
||||
- Disable PyTorch MPS device via `export PYTORCH_MPS_DISABLE=1`
|
||||
- Disable llama.cpp metal via `export LLAMA_NO_METAL=1`
|
||||
|
||||
For more details, refer to [this issue on GitHub](https://github.com/kyamagu/faiss-wheels/issues/73).
|
||||
|
||||
----------
|
||||
|
||||
__Issue__
|
||||
|
||||
+3
-2
@@ -3,9 +3,10 @@
|
||||

|
||||

|
||||
|
||||
- [Introducing txtai, the all-in-one embeddings database](https://medium.com/neuml/introducing-txtai-the-all-in-one-embeddings-database-c721f4ff91ad)
|
||||
- [Introducing txtai, the all-in-one AI framework](https://medium.com/neuml/introducing-txtai-the-all-in-one-ai-framework-0660ecfc39d7)
|
||||
- [txtai: An All-in-One AI Framework for Semantic Search and LLM Workflows](https://github.com/neuml/papers/blob/master/txtai/txtai.pdf)
|
||||
- [Tutorial series on Hashnode](https://neuml.hashnode.dev/series/txtai-tutorial) | [dev.to](https://dev.to/neuml/tutorial-series-on-txtai-ibg)
|
||||
- [What's new in txtai 7.0](https://medium.com/neuml/whats-new-in-txtai-7-0-855ad6a55440) | [6.0](https://medium.com/neuml/whats-new-in-txtai-6-0-7d93eeedf804) | [5.0](https://medium.com/neuml/whats-new-in-txtai-5-0-e5c75a13b101) | [4.0](https://medium.com/neuml/whats-new-in-txtai-4-0-bbc3a65c3d1c)
|
||||
- [What's new in txtai 9.0](https://medium.com/neuml/whats-new-in-txtai-9-0-d522bb150afa) | [8.0](https://medium.com/neuml/whats-new-in-txtai-8-0-2d7d0ab4506b) | [7.0](https://medium.com/neuml/whats-new-in-txtai-7-0-855ad6a55440) | [6.0](https://medium.com/neuml/whats-new-in-txtai-6-0-7d93eeedf804) | [5.0](https://medium.com/neuml/whats-new-in-txtai-5-0-e5c75a13b101) | [4.0](https://medium.com/neuml/whats-new-in-txtai-4-0-bbc3a65c3d1c)
|
||||
- [Getting started with semantic search](https://medium.com/neuml/getting-started-with-semantic-search-a9fd9d8a48cf) | [workflows](https://medium.com/neuml/getting-started-with-semantic-workflows-2fefda6165d9) | [rag](https://medium.com/neuml/getting-started-with-rag-9a0cca75f748)
|
||||
- [Running txtai at scale](https://medium.com/neuml/running-at-scale-with-txtai-71196cdd99f9)
|
||||
- [Vector search & RAG Landscape: A review with txtai](https://medium.com/neuml/vector-search-rag-landscape-a-review-with-txtai-a7f37ad0e187)
|
||||
|
||||
+15
-8
@@ -5,7 +5,7 @@
|
||||
</p>
|
||||
|
||||
<p align="center">
|
||||
<b>All-in-one embeddings database</b>
|
||||
<b>All-in-one AI framework</b>
|
||||
</p>
|
||||
|
||||
<p align="center">
|
||||
@@ -18,7 +18,7 @@
|
||||
<a href="https://github.com/neuml/txtai/issues">
|
||||
<img src="https://img.shields.io/github/issues/neuml/txtai.svg?style=flat&color=success" alt="GitHub issues"/>
|
||||
</a>
|
||||
<a href="https://join.slack.com/t/txtai/shared_invite/zt-1cagya4yf-DQeuZbd~aMwH5pckBU4vPg">
|
||||
<a href="https://join.slack.com/t/txtai/shared_invite/zt-37c1zfijp-Y57wMty6YOx_hyIHEQvQJA">
|
||||
<img src="https://img.shields.io/badge/slack-join-blue?style=flat&logo=slack&logocolor=white" alt="Join Slack"/>
|
||||
</a>
|
||||
<a href="https://github.com/neuml/txtai/actions?query=workflow%3Abuild">
|
||||
@@ -29,14 +29,16 @@
|
||||
</a>
|
||||
</p>
|
||||
|
||||
txtai is an all-in-one embeddings database for semantic search, LLM orchestration and language model workflows.
|
||||
txtai is an all-in-one AI framework for semantic search, LLM orchestration and language model workflows.
|
||||
|
||||

|
||||

|
||||
|
||||
Embeddings databases are a union of vector indexes (sparse and dense), graph networks and relational databases. This enables vector search with SQL, topic modeling, graph analysis and more.
|
||||
The key component of txtai is an embeddings database, which is a union of vector indexes (sparse and dense), graph networks and relational databases.
|
||||
|
||||
Embeddings databases can stand on their own and/or serve as a powerful knowledge source for large language model (LLM) prompts. Build autonomous agents, retrieval augmented generation (RAG) processes and multi-model workflows.
|
||||
This foundation enables vector search and/or serves as a powerful knowledge source for large language model (LLM) applications.
|
||||
|
||||
Build autonomous agents, retrieval augmented generation (RAG) processes, multi-model workflows and more.
|
||||
|
||||
Summary of txtai features:
|
||||
|
||||
@@ -45,9 +47,14 @@ Summary of txtai features:
|
||||
- 💡 Pipelines powered by language models that run LLM prompts, question-answering, labeling, transcription, translation, summarization and more
|
||||
- ↪️️ Workflows to join pipelines together and aggregate business logic. txtai processes can be simple microservices or multi-model workflows.
|
||||
- 🤖 Agents that intelligently connect embeddings, pipelines, workflows and other agents together to autonomously solve complex problems
|
||||
- ⚙️ Build with Python or YAML. API bindings available for [JavaScript](https://github.com/neuml/txtai.js), [Java](https://github.com/neuml/txtai.java), [Rust](https://github.com/neuml/txtai.rs) and [Go](https://github.com/neuml/txtai.go).
|
||||
- ⚙️ Web and Model Context Protocol (MCP) APIs. Bindings available for [JavaScript](https://github.com/neuml/txtai.js), [Java](https://github.com/neuml/txtai.java), [Rust](https://github.com/neuml/txtai.rs) and [Go](https://github.com/neuml/txtai.go).
|
||||
- 🔋 Batteries included with defaults to get up and running fast
|
||||
- ☁️ Run local or scale out with container orchestration
|
||||
|
||||
txtai is built with Python 3.9+, [Hugging Face Transformers](https://github.com/huggingface/transformers), [Sentence Transformers](https://github.com/UKPLab/sentence-transformers) and [FastAPI](https://github.com/tiangolo/fastapi). txtai is open-source under an Apache 2.0 license.
|
||||
txtai is built with Python 3.11+, [Hugging Face Transformers](https://github.com/huggingface/transformers), [Sentence Transformers](https://github.com/UKPLab/sentence-transformers) and [FastAPI](https://github.com/tiangolo/fastapi). txtai is open-source under an Apache 2.0 license.
|
||||
|
||||
*Interested in an easy and secure way to run hosted txtai applications? Then join the [txtai.cloud](https://txtai.cloud) preview to learn more.*
|
||||
!!! note
|
||||
|
||||
[NeuML](https://neuml.com) is the company behind txtai and we provide AI consulting services around our stack. [Schedule a meeting](https://cal.com/neuml/intro) or [send a message](mailto:[email protected]) to learn more.
|
||||
|
||||
We're also building an easy and secure way to run hosted txtai applications with [txtai.cloud](https://txtai.cloud).
|
||||
|
||||
+23
-3
@@ -9,7 +9,7 @@ The easiest way to install is via pip and PyPI
|
||||
pip install txtai
|
||||
```
|
||||
|
||||
Python 3.9+ is supported. Using a Python [virtual environment](https://docs.python.org/3/library/venv.html) is recommended.
|
||||
Python 3.11+ is supported. Using a Python [virtual environment](https://docs.python.org/3/library/venv.html) is recommended.
|
||||
|
||||
## Optional dependencies
|
||||
|
||||
@@ -130,7 +130,11 @@ Additional environment specific prerequisites are below.
|
||||
|
||||
### Linux
|
||||
|
||||
The AudioStream and Microphone pipelines require the [PortAudio](https://python-sounddevice.readthedocs.io/en/0.5.0/installation.html) system library. The Transcription pipeline requires the [SoundFile](https://github.com/bastibe/python-soundfile#installation) system library.
|
||||
The AudioStream and Microphone pipelines require the [PortAudio](https://python-sounddevice.readthedocs.io/en/0.5.0/installation.html) system library.
|
||||
|
||||
The Transcription pipeline requires the [SoundFile](https://github.com/bastibe/python-soundfile#installation) system library.
|
||||
|
||||
The LiteRT LLM pipeline requires libegl1, libgles2 and libvulkan1.
|
||||
|
||||
### macOS
|
||||
|
||||
@@ -146,7 +150,7 @@ The [txtai build workflow](https://github.com/neuml/txtai/blob/master/.github/wo
|
||||
|
||||
## CPU-only
|
||||
|
||||
The default install adds PyTorch with GPU support. There are a number of dependencies that come with that. When running in a CPU-only environment or using Embeddings/LLM models without PyTorch (i.e. llama.cpp or API services), the CPU-only PyTorch package can be installed with txtai as follows.
|
||||
The default install adds PyTorch with GPU support. There are a number of dependencies that come with that. When running in a CPU-only environment, the CPU-only PyTorch package can be installed with txtai as follows.
|
||||
|
||||
```
|
||||
pip install txtai torch==[version]+cpu \
|
||||
@@ -173,6 +177,22 @@ A [community-supported txtai package](https://anaconda.org/conda-forge/txtai) is
|
||||
conda install -c conda-forge txtai
|
||||
```
|
||||
|
||||
## Minimal install
|
||||
|
||||
A lightweight zero dependency minimal install package is available. This is helpful if the default libraries are too heavy or there are no plans to use them.
|
||||
|
||||
All the same extras mentioned above are available in this version of the package.
|
||||
|
||||
```
|
||||
# Lightweight minimal install
|
||||
pip install txtai_minimal
|
||||
|
||||
# Same as standard `txtai` install
|
||||
pip install txtai_minimal[default]
|
||||
```
|
||||
|
||||
Note that in order to use the `Embeddings` or `LLM` interface without `torch` requires either `llama.cpp`, `litellm` or `litert`.
|
||||
|
||||
## Run with containers
|
||||
|
||||
Docker images are available for txtai. [See this section](../cloud) for more information on container-based installs.
|
||||
|
||||
+4
-5
@@ -8,9 +8,9 @@ See the table below for the current recommended models. These models all allow c
|
||||
| ---------------------------------------------------- | ------------------------------------------------------------------------ |
|
||||
| [Embeddings](../embeddings) | [all-MiniLM-L6-v2](https://hf.co/sentence-transformers/all-MiniLM-L6-v2) |
|
||||
| [Image Captions](./pipeline/image/caption.md) | [BLIP](https://hf.co/Salesforce/blip-image-captioning-base) |
|
||||
| [Labels - Zero Shot](./pipeline/text/labels.md) | [BART-Large-MNLI](https://hf.co/facebook/bart-large) |
|
||||
| [Labels - Zero Shot](./pipeline/text/labels.md) | [DeBERTa v3 Zeroshot](https://hf.co/MoritzLaurer/deberta-v3-base-zeroshot-v2.0-c) |
|
||||
| [Labels - Fixed](./pipeline/text/labels.md) | Fine-tune with [training pipeline](./pipeline/train/trainer.md) |
|
||||
| [Large Language Model (LLM)](./pipeline/text/llm.md) | [Mistral 7B OpenOrca](https://hf.co/Open-Orca/Mistral-7B-OpenOrca) |
|
||||
| [Large Language Model (LLM)](./pipeline/text/llm.md) | [Gemma 4 31B](https://hf.co/google/gemma-4-31B) |
|
||||
| [Summarization](./pipeline/text/summary.md) | [DistilBART](https://hf.co/sshleifer/distilbart-cnn-12-6) |
|
||||
| [Text-to-Speech](./pipeline/audio/texttospeech.md) | [ESPnet JETS](https://hf.co/NeuML/ljspeech-jets-onnx) |
|
||||
| [Transcription](./pipeline/audio/transcription.md) | [Whisper](https://hf.co/openai/whisper-base) |
|
||||
@@ -22,6 +22,5 @@ See the following links to learn more.
|
||||
|
||||
- [Hugging Face Tasks](https://hf.co/tasks)
|
||||
- [Hugging Face Model Hub](https://hf.co/models)
|
||||
- [MTEB Leaderboard](https://hf.co/spaces/mteb/leaderboard)
|
||||
- [LMSYS LLM Leaderboard](https://chat.lmsys.org/?leaderboard)
|
||||
- [Open LLM Leaderboard](https://hf.co/spaces/HuggingFaceH4/open_llm_leaderboard)
|
||||
- [Embeddings Leaderboard](https://hf.co/spaces/mteb/leaderboard)
|
||||
- [LLM Leaderboard](https://hf.co/spaces/lmarena-ai/arena-leaderboard)
|
||||
|
||||
@@ -0,0 +1,182 @@
|
||||
# Observability
|
||||
|
||||
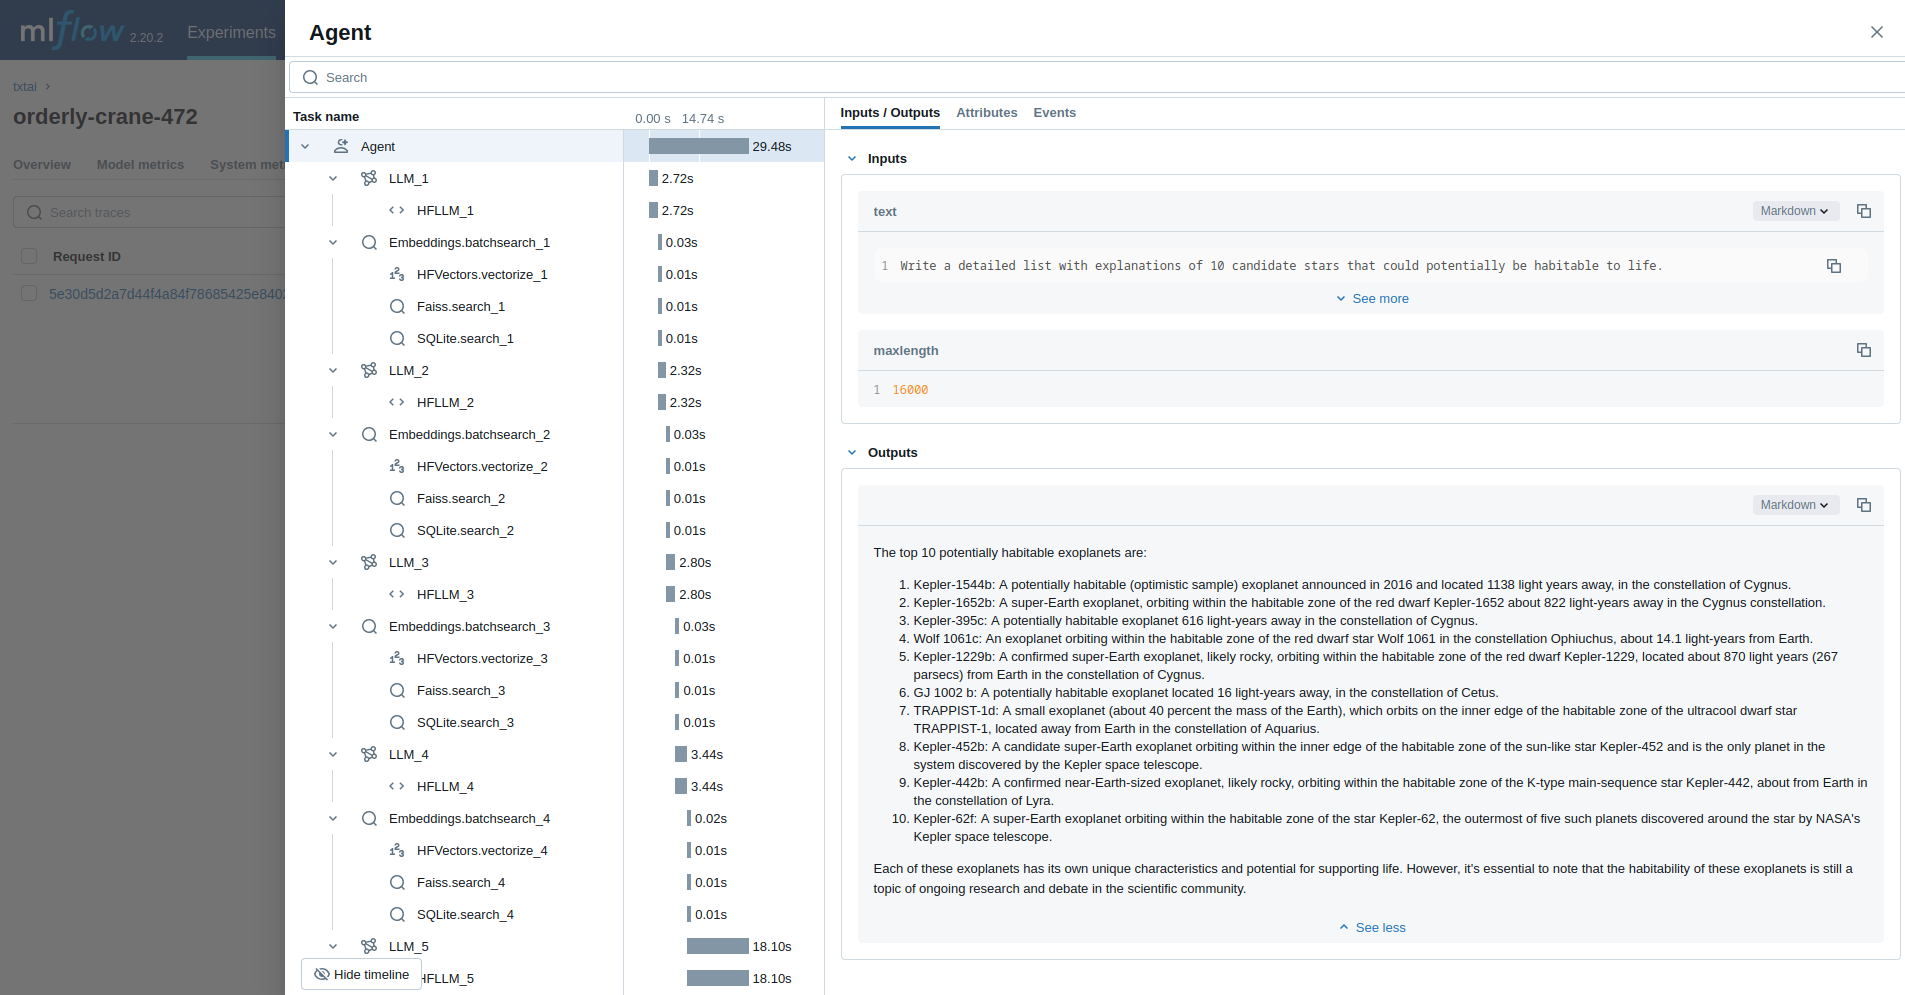
|
||||
|
||||
Observability enables tracking the inner workings of a system without having to change the system. This makes it much easier to debug and evaluate overall performance.
|
||||
|
||||
`txtai` has an integration with [MLflow](https://mlflow.org) and it's [tracing module](https://mlflow.org/docs/latest/llms/tracing/index.html) to provide insights into each of the components in `txtai`.
|
||||
|
||||
## Examples
|
||||
|
||||
The following shows a number of examples on how to introduce observability into a `txtai` process.
|
||||
|
||||
### Initialization
|
||||
|
||||
Run the following sections first to initialize tracing.
|
||||
|
||||
```
|
||||
# Install MLflow plugin for txtai
|
||||
pip install mlflow-txtai
|
||||
|
||||
# Start a local MLflow service
|
||||
mlflow server --host 127.0.0.1 --port 8000
|
||||
```
|
||||
|
||||
```python
|
||||
import mlflow
|
||||
|
||||
mlflow.set_tracking_uri(uri="http://localhost:8000")
|
||||
mlflow.set_experiment("txtai")
|
||||
|
||||
# Enable txtai automatic tracing
|
||||
mlflow.txtai.autolog()
|
||||
```
|
||||
|
||||
### Textractor
|
||||
|
||||
The first example traces a [Textractor pipeline](../pipeline/data/textractor).
|
||||
|
||||
```python
|
||||
from txtai.pipeline import Textractor
|
||||
|
||||
with mlflow.start_run():
|
||||
textractor = Textractor()
|
||||
textractor("https://github.com/neuml/txtai")
|
||||
```
|
||||
|
||||
|
||||
|
||||
### Embeddings
|
||||
|
||||
Next, we'll trace an [Embeddings](../embeddings) query.
|
||||
|
||||
```python
|
||||
from txtai import Embeddings
|
||||
|
||||
with mlflow.start_run():
|
||||
wiki = Embeddings()
|
||||
wiki.load(provider="huggingface-hub", container="neuml/txtai-wikipedia-slim")
|
||||
|
||||
embeddings = Embeddings(content=True, graph=True)
|
||||
embeddings.index(wiki.search("SELECT id, text FROM txtai LIMIT 25"))
|
||||
|
||||
embeddings.search("MATCH (A)-[]->(B) RETURN A")
|
||||
```
|
||||
|
||||
|
||||
|
||||
|
||||
### Retrieval Augmented Generation (RAG)
|
||||
|
||||
The next example traces a [RAG pipeline](../pipeline/text/rag).
|
||||
|
||||
```python
|
||||
from txtai import Embeddings, RAG
|
||||
|
||||
with mlflow.start_run():
|
||||
wiki = Embeddings()
|
||||
wiki.load(provider="huggingface-hub", container="neuml/txtai-wikipedia-slim")
|
||||
|
||||
# Define prompt template
|
||||
template = """
|
||||
Answer the following question using only the context below. Only include information
|
||||
specifically discussed.
|
||||
|
||||
question: {question}
|
||||
context: {context} """
|
||||
|
||||
# Create RAG pipeline
|
||||
rag = RAG(
|
||||
wiki,
|
||||
"openai/gpt-oss-20b",
|
||||
system="You are a friendly assistant. You answer questions from users.",
|
||||
template=template,
|
||||
context=10
|
||||
)
|
||||
|
||||
rag("Tell me about the Roman Empire", maxlength=2048)
|
||||
```
|
||||
|
||||
|
||||
|
||||
### Workflow
|
||||
|
||||
This example runs a [workflow](../workflow). This workflow runs an embeddings query and then translates each result to French.
|
||||
|
||||
```python
|
||||
from txtai import Embeddings, Workflow
|
||||
from txtai.pipeline import Translation
|
||||
from txtai.workflow import Task
|
||||
|
||||
with mlflow.start_run():
|
||||
wiki = Embeddings()
|
||||
wiki.load(provider="huggingface-hub", container="neuml/txtai-wikipedia-slim")
|
||||
|
||||
# Translation instance
|
||||
translate = Translation()
|
||||
|
||||
workflow = Workflow([
|
||||
Task(lambda x: [y[0]["text"] for y in wiki.batchsearch(x, 1)]),
|
||||
Task(lambda x: translate(x, "fr"))
|
||||
])
|
||||
|
||||
print(list(workflow(["Roman Empire", "Greek Empire", "Industrial Revolution"])))
|
||||
```
|
||||
|
||||
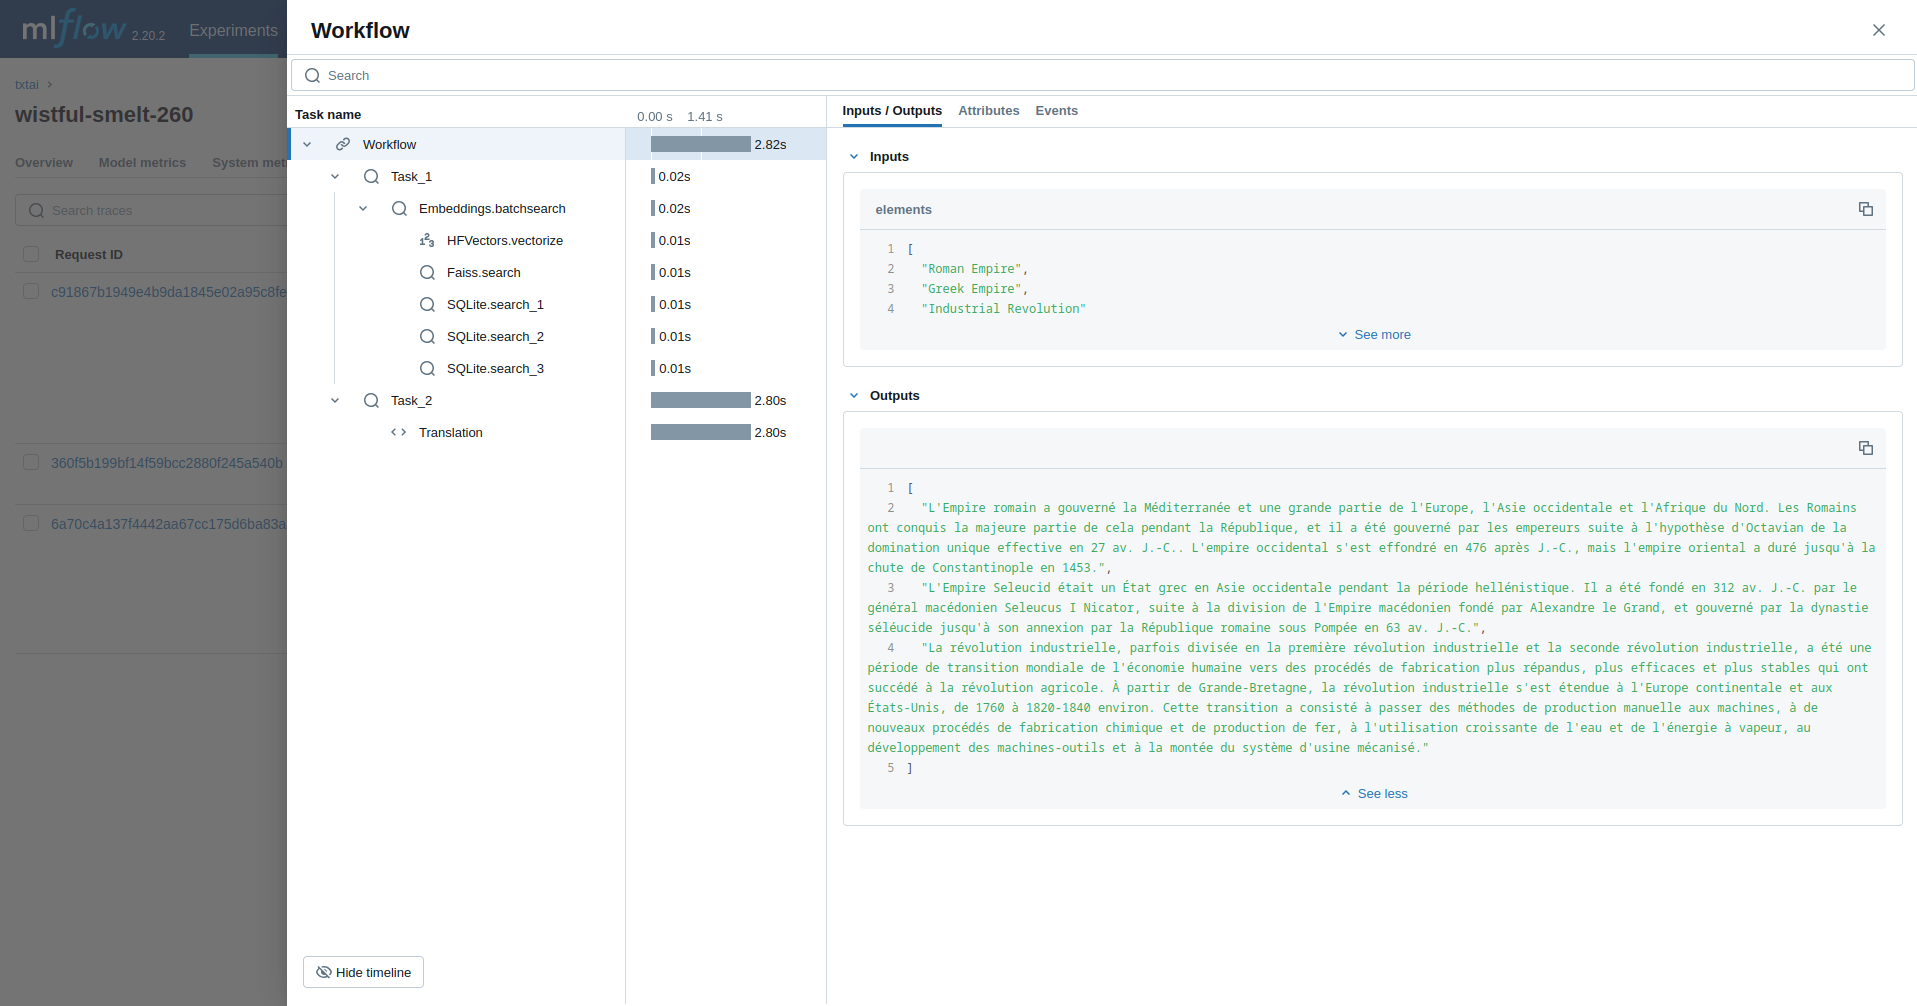
|
||||
|
||||
### Agent
|
||||
|
||||
The last example runs a [txtai agent](../agent) designed to research questions on astronomy.
|
||||
|
||||
```python
|
||||
from txtai import Agent, Embeddings
|
||||
|
||||
def search(query):
|
||||
"""
|
||||
Searches a database of astronomy data.
|
||||
|
||||
Make sure to call this tool only with a string input, never use JSON.
|
||||
|
||||
Args:
|
||||
query: concepts to search for using similarity search
|
||||
|
||||
Returns:
|
||||
list of search results with for each match
|
||||
"""
|
||||
|
||||
return embeddings.search(
|
||||
"SELECT id, text, distance FROM txtai WHERE similar(:query)",
|
||||
10, parameters={"query": query}
|
||||
)
|
||||
|
||||
embeddings = Embeddings()
|
||||
embeddings.load(provider="huggingface-hub", container="neuml/txtai-astronomy")
|
||||
|
||||
agent = Agent(
|
||||
tools=[search],
|
||||
llm="Qwen/Qwen3-4B-Instruct-2507",
|
||||
max_steps=10,
|
||||
)
|
||||
|
||||
researcher = """
|
||||
{command}
|
||||
|
||||
Do the following.
|
||||
- Search for results related to the topic.
|
||||
- Analyze the results
|
||||
- Continue querying until conclusive answers are found
|
||||
- Write a Markdown report
|
||||
"""
|
||||
|
||||
with mlflow.start_run():
|
||||
agent(researcher.format(command="""
|
||||
Write a detailed list with explanations of 10 candidate stars that could potentially be habitable to life.
|
||||
"""), maxlength=16000)
|
||||
```
|
||||
|
||||

|
||||
|
||||
## Read more
|
||||
|
||||
Check out the [mlflow-txtai](https://github.com/neuml/mlflow-txtai) project to see more examples.
|
||||
@@ -12,7 +12,7 @@ The following shows a simple example using this pipeline.
|
||||
```python
|
||||
from txtai.pipeline import TextToSpeech
|
||||
|
||||
# Create and run pipeline
|
||||
# Create and run pipeline with default model
|
||||
tts = TextToSpeech()
|
||||
tts("Say something here")
|
||||
|
||||
@@ -41,6 +41,7 @@ See the links below for a more detailed example.
|
||||
|
||||
This pipeline is backed by ONNX models from the Hugging Face Hub. The following models are currently available.
|
||||
|
||||
- [kokoro-base-onnx](https://huggingface.co/NeuML/kokoro-base-onnx) | [fp16](https://huggingface.co/NeuML/kokoro-fp16-onnx) | [int8](https://huggingface.co/NeuML/kokoro-int8-onnx)
|
||||
- [ljspeech-jets-onnx](https://huggingface.co/NeuML/ljspeech-jets-onnx)
|
||||
- [ljspeech-vits-onnx](https://huggingface.co/NeuML/ljspeech-vits-onnx)
|
||||
- [vctk-vits-onnx](https://huggingface.co/NeuML/vctk-vits-onnx)
|
||||
|
||||
@@ -0,0 +1,80 @@
|
||||
# File To HTML
|
||||
|
||||

|
||||

|
||||
|
||||
The File To HTML pipeline transforms files to HTML. It supports the following text extraction backends.
|
||||
|
||||
## Apache Tika
|
||||
|
||||
[Apache Tika](https://tika.apache.org/) detects and extracts metadata and text from over a thousand different file types. See [this link](https://tika.apache.org/2.9.2/formats.html) for a list of supported document formats.
|
||||
|
||||
Apache Tika requires [Java](https://en.wikipedia.org/wiki/Java_(programming_language)) to be installed. An alternative to that is starting a separate Apache Tika service via [this Docker Image](https://hub.docker.com/r/apache/tika) and setting these [environment variables](https://github.com/chrismattmann/tika-python?tab=readme-ov-file#environment-variables).
|
||||
|
||||
## Docling
|
||||
|
||||
[Docling](https://github.com/DS4SD/docling) parses documents and exports them to the desired format with ease and speed. This is a library that has rapidly gained popularity starting in late 2024. Docling excels in parsing formatting elements from PDFs (tables, sections etc).
|
||||
|
||||
See [this link](https://github.com/DS4SD/docling?tab=readme-ov-file#features) for a list of supported document formats.
|
||||
|
||||
## LiteParse
|
||||
|
||||
[LiteParse](https://github.com/run-llama/liteparse) is a fast, helpful, and open-source document parser. It supports PDF out of the box with additional format support via third-party packages.
|
||||
|
||||
See [this link](https://github.com/run-llama/liteparse#multi-format-input-support) for more.
|
||||
|
||||
## Example
|
||||
|
||||
The following shows a simple example using this pipeline.
|
||||
|
||||
```python
|
||||
from txtai.pipeline import FileToHTML
|
||||
|
||||
# Create and run pipeline
|
||||
html = FileToHTML()
|
||||
html("/path/to/file")
|
||||
```
|
||||
|
||||
## Configuration-driven example
|
||||
|
||||
Pipelines are run with Python or configuration. Pipelines can be instantiated in [configuration](../../../api/configuration/#pipeline) using the lower case name of the pipeline. Configuration-driven pipelines are run with [workflows](../../../workflow/#configuration-driven-example) or the [API](../../../api#local-instance).
|
||||
|
||||
### config.yml
|
||||
```yaml
|
||||
# Create pipeline using lower case class name
|
||||
filetohtml:
|
||||
|
||||
# Run pipeline with workflow
|
||||
workflow:
|
||||
html:
|
||||
tasks:
|
||||
- action: filetohtml
|
||||
```
|
||||
|
||||
### Run with Workflows
|
||||
|
||||
```python
|
||||
from txtai import Application
|
||||
|
||||
# Create and run pipeline with workflow
|
||||
app = Application("config.yml")
|
||||
list(app.workflow("html", ["/path/to/file"]))
|
||||
```
|
||||
|
||||
### Run with API
|
||||
|
||||
```bash
|
||||
CONFIG=config.yml uvicorn "txtai.api:app" &
|
||||
|
||||
curl \
|
||||
-X POST "http://localhost:8000/workflow" \
|
||||
-H "Content-Type: application/json" \
|
||||
-d '{"name":"html", "elements":["/path/to/file"]}'
|
||||
```
|
||||
|
||||
## Methods
|
||||
|
||||
Python documentation for the pipeline.
|
||||
|
||||
### ::: txtai.pipeline.FileToHTML.__init__
|
||||
### ::: txtai.pipeline.FileToHTML.__call__
|
||||
@@ -0,0 +1,68 @@
|
||||
# HTML To Markdown
|
||||
|
||||

|
||||

|
||||
|
||||
The HTML To Markdown pipeline transforms HTML to Markdown.
|
||||
|
||||
Markdown formatting is applied for headings, blockquotes, lists, code, tables and text. Visual formatting is also included (bold, italic etc).
|
||||
|
||||
This pipeline searches for the best node that has relevant text, often found with an `article`, `main` or `body` tag.
|
||||
|
||||
The HTML to Markdown pipeline requires the [BeautifulSoup4](https://pypi.org/project/beautifulsoup4/) library to be installed.
|
||||
|
||||
## Example
|
||||
|
||||
The following shows a simple example using this pipeline.
|
||||
|
||||
```python
|
||||
from txtai.pipeline import HTMLToMarkdown
|
||||
|
||||
# Create and run pipeline
|
||||
md = HTMLToMarkdown()
|
||||
md("<html><body>This is a test</body></html>")
|
||||
```
|
||||
|
||||
## Configuration-driven example
|
||||
|
||||
Pipelines are run with Python or configuration. Pipelines can be instantiated in [configuration](../../../api/configuration/#pipeline) using the lower case name of the pipeline. Configuration-driven pipelines are run with [workflows](../../../workflow/#configuration-driven-example) or the [API](../../../api#local-instance).
|
||||
|
||||
### config.yml
|
||||
```yaml
|
||||
# Create pipeline using lower case class name
|
||||
htmltomarkdown:
|
||||
|
||||
# Run pipeline with workflow
|
||||
workflow:
|
||||
markdown:
|
||||
tasks:
|
||||
- action: htmltomarkdown
|
||||
```
|
||||
|
||||
### Run with Workflows
|
||||
|
||||
```python
|
||||
from txtai import Application
|
||||
|
||||
# Create and run pipeline with workflow
|
||||
app = Application("config.yml")
|
||||
list(app.workflow("markdown", ["<html><body>This is a test</body></html>"]))
|
||||
```
|
||||
|
||||
### Run with API
|
||||
|
||||
```bash
|
||||
CONFIG=config.yml uvicorn "txtai.api:app" &
|
||||
|
||||
curl \
|
||||
-X POST "http://localhost:8000/workflow" \
|
||||
-H "Content-Type: application/json" \
|
||||
-d '{"name":"markdown", "elements":["<html><body>This is a test</body></html>"]}'
|
||||
```
|
||||
|
||||
## Methods
|
||||
|
||||
Python documentation for the pipeline.
|
||||
|
||||
### ::: txtai.pipeline.HTMLToMarkdown.__init__
|
||||
### ::: txtai.pipeline.HTMLToMarkdown.__call__
|
||||
@@ -15,8 +15,14 @@ from txtai.pipeline import Segmentation
|
||||
# Create and run pipeline
|
||||
segment = Segmentation(sentences=True)
|
||||
segment("This is a test. And another test.")
|
||||
|
||||
# Load third-party chunkers
|
||||
segment = Segmentation(chunker="semantic")
|
||||
segment("This is a test. And another test.")
|
||||
```
|
||||
|
||||
The Segmentation pipeline supports segmenting `sentences`, `lines`, `paragraphs` and `sections` using a rules-based approach. Each of these modes can be set when creating the pipeline. Third-party chunkers are also supported via the `chunker` parameter.
|
||||
|
||||
## Configuration-driven example
|
||||
|
||||
Pipelines are run with Python or configuration. Pipelines can be instantiated in [configuration](../../../api/configuration/#pipeline) using the lower case name of the pipeline. Configuration-driven pipelines are run with [workflows](../../../workflow/#configuration-driven-example) or the [API](../../../api#local-instance).
|
||||
|
||||
@@ -3,15 +3,20 @@
|
||||

|
||||

|
||||
|
||||
The Textractor pipeline extracts and splits text from documents. This pipeline uses [Apache Tika](https://github.com/chrismattmann/tika-python) (if Java is available) and [BeautifulSoup4](https://pypi.org/project/beautifulsoup4/). See [this link](https://tika.apache.org/2.9.2/formats.html) for a list of supported document formats.
|
||||
The Textractor pipeline extracts and splits text from documents. This pipeline extends the [Segmentation](../segmentation) pipeline.
|
||||
|
||||
Each document goes through the following process.
|
||||
|
||||
- Content is retrieved if it's not local
|
||||
- If the document `mime-type` isn't plain text or HTML, it's run through Tika and converted to XHTML
|
||||
- XHTML is converted to Markdown and returned
|
||||
- If the document `mime-type` isn't plain text or HTML, it's converted to HTML via the [FiletoHTML](../filetohtml) pipeline
|
||||
- HTML is converted to Markdown via the [HTMLToMarkdown](../htmltomd) pipeline
|
||||
- Content is split/chunked based on the [segmentation parameters](../segmentation/#txtai.pipeline.Segmentation.__init__) and returned
|
||||
|
||||
Without Apache Tika, this pipeline only supports plain text and HTML. Other document types require Tika and Java to be installed. Another option is to start Apache Tika via [this Docker Image](https://hub.docker.com/r/apache/tika).
|
||||
The [backend](../filetohtml/#txtai.pipeline.FileToHTML.__init__) parameter sets the FileToHTML pipeline backend. If a backend isn't available, this pipeline assumes input is HTML content and only converts it to Markdown.
|
||||
|
||||
See the [FiletoHTML](../filetohtml) and [HTMLToMarkdown](../htmltomd) pipelines to learn more on the dependencies necessary for each of those pipelines.
|
||||
|
||||
Note that the default parameters enable access to all local files and all URLs. The `safeopen` parameter limits this to only files in a specified directory (defaults to temp directory) and public URLs. When running the textractor pipeline through an Application or via the API, `safeopen` defaults to True. It can be disabled if desired via configuration.
|
||||
|
||||
## Example
|
||||
|
||||
@@ -30,6 +35,7 @@ See the link below for a more detailed example.
|
||||
| Notebook | Description | |
|
||||
|:----------|:-------------|------:|
|
||||
| [Extract text from documents](https://github.com/neuml/txtai/blob/master/examples/10_Extract_text_from_documents.ipynb) | Extract text from PDF, Office, HTML and more | [](https://colab.research.google.com/github/neuml/txtai/blob/master/examples/10_Extract_text_from_documents.ipynb) |
|
||||
| [Chunking your data for RAG](https://github.com/neuml/txtai/blob/master/examples/73_Chunking_your_data_for_RAG.ipynb) | Extract, chunk and index content for effective retrieval | [](https://colab.research.google.com/github/neuml/txtai/blob/master/examples/73_Chunking_your_data_for_RAG.ipynb) |
|
||||
|
||||
## Configuration-driven example
|
||||
|
||||
|
||||
@@ -0,0 +1,82 @@
|
||||
# Tokenizer
|
||||
|
||||

|
||||

|
||||
|
||||
The Tokenizer pipeline splits text into tokens. This is primarily used for keyword / term indexing.
|
||||
|
||||
_Note: Transformers-based models have their own tokenizers and this pipeline isn't designed for working with Transformers models._
|
||||
|
||||
## Example
|
||||
|
||||
The following shows a simple example using this pipeline.
|
||||
|
||||
```python
|
||||
from txtai.pipeline import Tokenizer
|
||||
|
||||
# Create and run pipeline
|
||||
tokenizer = Tokenizer()
|
||||
tokenizer("text to tokenize")
|
||||
|
||||
# Whitespace tokenization
|
||||
tokenizer = Tokenizer(whitespace=True)
|
||||
tokenizer("text to tokenize")
|
||||
|
||||
# Tokenize using a regular expression
|
||||
tokenizer = Tokenizer(regexp=r"\w{5,}")
|
||||
tokenizer("text to tokenize")
|
||||
|
||||
# Tokenize into trigrams like pg_trgm
|
||||
tokenizer = Tokenizer(ngrams={
|
||||
"ngrams": 3, "lpad": " ", "rpad": " ", "unique": True
|
||||
})
|
||||
tokenize("text to tokenize")
|
||||
|
||||
# Tokenize into edge ngrams
|
||||
tokenizer = Tokenizer(ngrams={"nmin": 2, "nmax": 5, "edge": True})
|
||||
tokenizer("text to tokenize")
|
||||
```
|
||||
|
||||
## Configuration-driven example
|
||||
|
||||
Pipelines are run with Python or configuration. Pipelines can be instantiated in [configuration](../../../api/configuration/#pipeline) using the lower case name of the pipeline. Configuration-driven pipelines are run with [workflows](../../../workflow/#configuration-driven-example) or the [API](../../../api#local-instance).
|
||||
|
||||
### config.yml
|
||||
```yaml
|
||||
# Create pipeline using lower case class name
|
||||
tokenizer:
|
||||
|
||||
# Run pipeline with workflow
|
||||
workflow:
|
||||
tokenizer:
|
||||
tasks:
|
||||
- action: tokenizer
|
||||
```
|
||||
|
||||
### Run with Workflows
|
||||
|
||||
```python
|
||||
from txtai import Application
|
||||
|
||||
# Create and run pipeline with workflow
|
||||
app = Application("config.yml")
|
||||
list(app.workflow("tokenizer", ["text to tokenize"]))
|
||||
```
|
||||
|
||||
### Run with API
|
||||
|
||||
```bash
|
||||
CONFIG=config.yml uvicorn "txtai.api:app" &
|
||||
|
||||
curl \
|
||||
-X POST "http://localhost:8000/workflow" \
|
||||
-H "Content-Type: application/json" \
|
||||
-d '{"name":"tokenizer", "elements":["text"]}'
|
||||
```
|
||||
|
||||
## Methods
|
||||
|
||||
Python documentation for the pipeline.
|
||||
|
||||
### ::: txtai.pipeline.Tokenizer.__init__
|
||||
### ::: txtai.pipeline.Tokenizer.__call__
|
||||
@@ -0,0 +1,62 @@
|
||||
# URL Retrieve
|
||||
|
||||

|
||||

|
||||
|
||||
The URL Retrieve pipeline retrieves content from a HTTP(s) URL.
|
||||
|
||||
## Example
|
||||
|
||||
The following shows a simple example using this pipeline.
|
||||
|
||||
```python
|
||||
from txtai.pipeline import URLRetrieve
|
||||
|
||||
# Create and run pipeline
|
||||
urlretrieve = URLRetrieve()
|
||||
urlretrieve("https://github.com/neuml/txtai")
|
||||
```
|
||||
|
||||
## Configuration-driven example
|
||||
|
||||
Pipelines are run with Python or configuration. Pipelines can be instantiated in [configuration](../../../api/configuration/#pipeline) using the lower case name of the pipeline. Configuration-driven pipelines are run with [workflows](../../../workflow/#configuration-driven-example) or the [API](../../../api#local-instance).
|
||||
|
||||
### config.yml
|
||||
```yaml
|
||||
# Create pipeline using lower case class name
|
||||
urlretrieve:
|
||||
|
||||
# Run pipeline with workflow
|
||||
workflow:
|
||||
retrieve:
|
||||
tasks:
|
||||
- action: urlretrieve
|
||||
```
|
||||
|
||||
### Run with Workflows
|
||||
|
||||
```python
|
||||
from txtai import Application
|
||||
|
||||
# Create and run pipeline with workflow
|
||||
app = Application("config.yml")
|
||||
list(app.workflow("urlretrieve", ["https://github.com/neuml/txtai"]))
|
||||
```
|
||||
|
||||
### Run with API
|
||||
|
||||
```bash
|
||||
CONFIG=config.yml uvicorn "txtai.api:app" &
|
||||
|
||||
curl \
|
||||
-X POST "http://localhost:8000/workflow" \
|
||||
-H "Content-Type: application/json" \
|
||||
-d '{"name":"retrieve", "elements":["http://github.com/neuml/txtai"]}'
|
||||
```
|
||||
|
||||
## Methods
|
||||
|
||||
Python documentation for the pipeline.
|
||||
|
||||
### ::: txtai.pipeline.URLRetrieve.__init__
|
||||
### ::: txtai.pipeline.URLRetrieve.__call__
|
||||
@@ -21,9 +21,13 @@ The `LLM` and `RAG` pipelines also have integrations for [llama.cpp](https://git
|
||||
- [TextToSpeech](audio/texttospeech)
|
||||
- [Transcription](audio/transcription)
|
||||
- Data Processing
|
||||
- [FileToHTML](data/filetohtml)
|
||||
- [HTMLToMarkdown](data/htmltomd)
|
||||
- [Segmentation](data/segmentation)
|
||||
- [Tabular](data/tabular)
|
||||
- [Text extraction](data/textractor)
|
||||
- [Tokenizer](data/tokenizer)
|
||||
- [URLRetrieve](data/urlretrieve)
|
||||
- Image
|
||||
- [Caption](image/caption)
|
||||
- [Image Hash](image/imagehash)
|
||||
@@ -33,6 +37,7 @@ The `LLM` and `RAG` pipelines also have integrations for [llama.cpp](https://git
|
||||
- [Labeling](text/labels)
|
||||
- [LLM](text/llm)
|
||||
- [RAG](text/rag)
|
||||
- [Reranker](text/reranker)
|
||||
- [Similarity](text/similarity)
|
||||
- [Summary](text/summary)
|
||||
- [Translation](text/translation)
|
||||
|
||||
@@ -0,0 +1,225 @@
|
||||
# LLM
|
||||
|
||||

|
||||

|
||||
|
||||
The LLM pipeline runs prompts through a large language model (LLM). This pipeline autodetects the LLM framework based on the model path.
|
||||
|
||||
## Example
|
||||
|
||||
The following shows a simple example using this pipeline.
|
||||
|
||||
```python
|
||||
from txtai import LLM
|
||||
|
||||
# Create LLM pipeline
|
||||
llm = LLM()
|
||||
|
||||
# Run prompt
|
||||
llm(
|
||||
"""
|
||||
Answer the following question using the provided context.
|
||||
|
||||
Question:
|
||||
What are the applications of txtai?
|
||||
|
||||
Context:
|
||||
txtai is an open-source platform for semantic search and
|
||||
workflows powered by language models.
|
||||
"""
|
||||
)
|
||||
|
||||
# Prompts with chat templating can be directly passed
|
||||
# The template format varies by model
|
||||
llm(
|
||||
"""
|
||||
<|im_start|>system
|
||||
You are a friendly assistant.<|im_end|>
|
||||
<|im_start|>user
|
||||
Answer the following question...<|im_end|>
|
||||
<|im_start|>assistant
|
||||
"""
|
||||
)
|
||||
|
||||
# Chat messages automatically handle templating
|
||||
llm([
|
||||
{"role": "system", "content": "You are a friendly assistant."},
|
||||
{"role": "user", "content": "Answer the following question..."}
|
||||
])
|
||||
|
||||
# When there is no system prompt passed to instruction tuned models
|
||||
# the default role is inferred `defaultrole="auto"`
|
||||
llm("Answer the following question...")
|
||||
|
||||
# To always generate chat messages for string inputs
|
||||
llm("Answer the following question...", defaultrole="user")
|
||||
|
||||
# To never generate chat messages for string inputs
|
||||
llm("Answer the following question...", defaultrole="prompt")
|
||||
```
|
||||
|
||||
The LLM pipeline automatically detects the underlying LLM framework. This can also be manually set. The following methods are supported.
|
||||
|
||||
- [Hugging Face Transformers](https://github.com/huggingface/transformers)
|
||||
- [llama.cpp](https://github.com/abetlen/llama-cpp-python)
|
||||
- [LLM APIs via LiteLLM](https://github.com/BerriAI/litellm)
|
||||
- [LiteRT-LM](https://ai.google.dev/edge/litert-lm)
|
||||
- [OpenCode server](https://github.com/anomalyco/opencode)
|
||||
|
||||
`llama.cpp` and `LiteRT-LM` support both local and remote file paths on the HF Hub.
|
||||
|
||||
See the [LiteLLM documentation](https://litellm.vercel.app/docs/providers) for the options available with LiteLLM models.
|
||||
|
||||
See the [OpenCode documentation](https://opencode.ai/docs/server/) for more on how to integrate the LLM pipeline with a running OpenCode instance.
|
||||
|
||||
```python
|
||||
from txtai import LLM
|
||||
|
||||
# Transformers
|
||||
llm = LLM("openai/gpt-oss-20b")
|
||||
llm = LLM("openai/gpt-oss-20b", method="transformers")
|
||||
|
||||
# llama.cpp
|
||||
llm = LLM("unsloth/gpt-oss-20b-GGUF/gpt-oss-20b-Q4_K_M.gguf")
|
||||
llm = LLM("unsloth/gpt-oss-20b-GGUF/gpt-oss-20b-Q4_K_M.gguf",
|
||||
method="llama.cpp")
|
||||
|
||||
# LiteLLM
|
||||
llm = LLM("ollama/gpt-oss")
|
||||
llm = LLM("ollama/gpt-oss", method="litellm")
|
||||
|
||||
# LiteRT-LM
|
||||
llm = LLM(
|
||||
"litert-community/gemma-4-E2B-it-litert-lm/gemma-4-E2B-it.litertlm"
|
||||
)
|
||||
llm = LLM(
|
||||
"litert-community/gemma-4-E2B-it-litert-lm/gemma-4-E2B-it.litertlm",
|
||||
method="litert"
|
||||
)
|
||||
|
||||
# Custom Ollama endpoint
|
||||
llm = LLM("ollama/gpt-oss", api_base="http://localhost:11434")
|
||||
|
||||
# Custom OpenAI-compatible endpoint
|
||||
llm = LLM("openai/gpt-oss", api_base="http://localhost:4000")
|
||||
|
||||
# LLM APIs - must also set API key via environment variable
|
||||
llm = LLM("gpt-5.2")
|
||||
llm = LLM("claude-opus-4-5-20251101")
|
||||
llm = LLM("gemini/gemini-3-pro-preview")
|
||||
|
||||
# Local OpenCode server started via `opencode serve`
|
||||
llm = LLM("opencode")
|
||||
llm = LLM("opencode/big-pickle", url="http://localhost:4000")
|
||||
```
|
||||
|
||||
Models can be externally loaded and passed to pipelines. This is useful for models that are not yet supported by Transformers and/or need special initialization.
|
||||
|
||||
```python
|
||||
import torch
|
||||
|
||||
from transformers import AutoModelForCausalLM, AutoTokenizer
|
||||
from txtai import LLM
|
||||
|
||||
# Load Qwen3 0.6B
|
||||
path = "Qwen/Qwen3-0.6B"
|
||||
model = AutoModelForCausalLM.from_pretrained(
|
||||
path,
|
||||
dtype=torch.bfloat16,
|
||||
)
|
||||
tokenizer = AutoTokenizer.from_pretrained(path)
|
||||
|
||||
llm = LLM((model, tokenizer))
|
||||
```
|
||||
|
||||
See the links below for more detailed examples.
|
||||
|
||||
| Notebook | Description | |
|
||||
|:----------|:-------------|------:|
|
||||
| [Prompt-driven search with LLMs](https://github.com/neuml/txtai/blob/master/examples/42_Prompt_driven_search_with_LLMs.ipynb) | Embeddings-guided and Prompt-driven search with Large Language Models (LLMs) | [](https://colab.research.google.com/github/neuml/txtai/blob/master/examples/42_Prompt_driven_search_with_LLMs.ipynb) |
|
||||
| [Prompt templates and task chains](https://github.com/neuml/txtai/blob/master/examples/44_Prompt_templates_and_task_chains.ipynb) | Build model prompts and connect tasks together with workflows | [](https://colab.research.google.com/github/neuml/txtai/blob/master/examples/44_Prompt_templates_and_task_chains.ipynb) |
|
||||
| [Build RAG pipelines with txtai](https://github.com/neuml/txtai/blob/master/examples/52_Build_RAG_pipelines_with_txtai.ipynb) [▶️](https://www.youtube.com/watch?v=t_OeAc8NVfQ) | Guide on retrieval augmented generation including how to create citations | [](https://colab.research.google.com/github/neuml/txtai/blob/master/examples/52_Build_RAG_pipelines_with_txtai.ipynb) |
|
||||
| [Integrate LLM frameworks](https://github.com/neuml/txtai/blob/master/examples/53_Integrate_LLM_Frameworks.ipynb) | Integrate llama.cpp, LiteLLM and custom generation frameworks | [](https://colab.research.google.com/github/neuml/txtai/blob/master/examples/53_Integrate_LLM_Frameworks.ipynb) |
|
||||
| [Generate knowledge with Semantic Graphs and RAG](https://github.com/neuml/txtai/blob/master/examples/55_Generate_knowledge_with_Semantic_Graphs_and_RAG.ipynb) | Knowledge exploration and discovery with Semantic Graphs and RAG | [](https://colab.research.google.com/github/neuml/txtai/blob/master/examples/55_Generate_knowledge_with_Semantic_Graphs_and_RAG.ipynb) |
|
||||
| [Build knowledge graphs with LLMs](https://github.com/neuml/txtai/blob/master/examples/57_Build_knowledge_graphs_with_LLM_driven_entity_extraction.ipynb) | Build knowledge graphs with LLM-driven entity extraction | [](https://colab.research.google.com/github/neuml/txtai/blob/master/examples/57_Build_knowledge_graphs_with_LLM_driven_entity_extraction.ipynb) |
|
||||
| [Advanced RAG with graph path traversal](https://github.com/neuml/txtai/blob/master/examples/58_Advanced_RAG_with_graph_path_traversal.ipynb) | Graph path traversal to collect complex sets of data for advanced RAG | [](https://colab.research.google.com/github/neuml/txtai/blob/master/examples/58_Advanced_RAG_with_graph_path_traversal.ipynb) |
|
||||
| [Advanced RAG with guided generation](https://github.com/neuml/txtai/blob/master/examples/60_Advanced_RAG_with_guided_generation.ipynb) | Retrieval Augmented and Guided Generation | [](https://colab.research.google.com/github/neuml/txtai/blob/master/examples/60_Advanced_RAG_with_guided_generation.ipynb) |
|
||||
| [RAG with llama.cpp and external API services](https://github.com/neuml/txtai/blob/master/examples/62_RAG_with_llama_cpp_and_external_API_services.ipynb) | RAG with additional vector and LLM frameworks | [](https://colab.research.google.com/github/neuml/txtai/blob/master/examples/62_RAG_with_llama_cpp_and_external_API_services.ipynb) |
|
||||
| [How RAG with txtai works](https://github.com/neuml/txtai/blob/master/examples/63_How_RAG_with_txtai_works.ipynb) | Create RAG processes, API services and Docker instances | [](https://colab.research.google.com/github/neuml/txtai/blob/master/examples/63_How_RAG_with_txtai_works.ipynb) |
|
||||
| [Speech to Speech RAG](https://github.com/neuml/txtai/blob/master/examples/65_Speech_to_Speech_RAG.ipynb) [▶️](https://www.youtube.com/watch?v=tH8QWwkVMKA) | Full cycle speech to speech workflow with RAG | [](https://colab.research.google.com/github/neuml/txtai/blob/master/examples/65_Speech_to_Speech_RAG.ipynb) |
|
||||
| [Analyzing Hugging Face Posts with Graphs and Agents](https://github.com/neuml/txtai/blob/master/examples/68_Analyzing_Hugging_Face_Posts_with_Graphs_and_Agents.ipynb) | Explore a rich dataset with Graph Analysis and Agents | [](https://colab.research.google.com/github/neuml/txtai/blob/master/examples/68_Analyzing_Hugging_Face_Posts_with_Graphs_and_Agents.ipynb) |
|
||||
| [Granting autonomy to agents](https://github.com/neuml/txtai/blob/master/examples/69_Granting_autonomy_to_agents.ipynb) | Agents that iteratively solve problems as they see fit | [](https://colab.research.google.com/github/neuml/txtai/blob/master/examples/69_Granting_autonomy_to_agents.ipynb) |
|
||||
| [Getting started with LLM APIs](https://github.com/neuml/txtai/blob/master/examples/70_Getting_started_with_LLM_APIs.ipynb) | Generate embeddings and run LLMs with OpenAI, Claude, Gemini, Bedrock and more | [](https://colab.research.google.com/github/neuml/txtai/blob/master/examples/70_Getting_started_with_LLM_APIs.ipynb) |
|
||||
| [Analyzing LinkedIn Company Posts with Graphs and Agents](https://github.com/neuml/txtai/blob/master/examples/71_Analyzing_LinkedIn_Company_Posts_with_Graphs_and_Agents.ipynb) | Exploring how to improve social media engagement with AI | [](https://colab.research.google.com/github/neuml/txtai/blob/master/examples/71_Analyzing_LinkedIn_Company_Posts_with_Graphs_and_Agents.ipynb) |
|
||||
| [Parsing the stars with txtai](https://github.com/neuml/txtai/blob/master/examples/72_Parsing_the_stars_with_txtai.ipynb) | Explore an astronomical knowledge graph of known stars, planets, galaxies | [](https://colab.research.google.com/github/neuml/txtai/blob/master/examples/72_Parsing_the_stars_with_txtai.ipynb) |
|
||||
| [Chunking your data for RAG](https://github.com/neuml/txtai/blob/master/examples/73_Chunking_your_data_for_RAG.ipynb) | Extract, chunk and index content for effective retrieval | [](https://colab.research.google.com/github/neuml/txtai/blob/master/examples/73_Chunking_your_data_for_RAG.ipynb) |
|
||||
| [Medical RAG Research with txtai](https://github.com/neuml/txtai/blob/master/examples/75_Medical_RAG_Research_with_txtai.ipynb) | Analyze PubMed article metadata with RAG | [](https://colab.research.google.com/github/neuml/txtai/blob/master/examples/75_Medical_RAG_Research_with_txtai.ipynb) |
|
||||
| [GraphRAG with Wikipedia and GPT OSS](https://github.com/neuml/txtai/blob/master/examples/77_GraphRAG_with_Wikipedia_and_GPT_OSS.ipynb) | Deep graph search powered RAG | [](https://colab.research.google.com/github/neuml/txtai/blob/master/examples/77_GraphRAG_with_Wikipedia_and_GPT_OSS.ipynb) |
|
||||
| [RAG is more than Vector Search](https://github.com/neuml/txtai/blob/master/examples/79_RAG_is_more_than_Vector_Search.ipynb) | Context retrieval via Web, SQL and other sources | [](https://colab.research.google.com/github/neuml/txtai/blob/master/examples/79_RAG_is_more_than_Vector_Search.ipynb) |
|
||||
| [OpenCode as a txtai LLM](https://github.com/neuml/txtai/blob/master/examples/81_OpenCode_as_a_txtai_LLM.ipynb) | Integrate OpenCode with the txtai ecosystem | [](https://colab.research.google.com/github/neuml/txtai/blob/master/examples/81_OpenCode_as_a_txtai_LLM.ipynb) |
|
||||
| [Agentic College Search](https://github.com/neuml/txtai/blob/master/examples/82_Agentic_College_Search.ipynb) | Identify a list of strong engineering colleges | [](https://colab.research.google.com/github/neuml/txtai/blob/master/examples/82_Agentic_College_Search.ipynb) |
|
||||
| [TxtAI got skills](https://github.com/neuml/txtai/blob/master/examples/83_TxtAI_got_skills.ipynb) | Integrate skill.md files with your agent | [](https://colab.research.google.com/github/neuml/txtai/blob/master/examples/83_TxtAI_got_skills.ipynb) |
|
||||
| [Agent Tools](https://github.com/neuml/txtai/blob/master/examples/84_Agent_Tools.ipynb) [▶️](https://www.youtube.com/watch?v=RDNaFXQy3GQ) | Learn about the txtai agent toolkit | [](https://colab.research.google.com/github/neuml/txtai/blob/master/examples/84_Agent_Tools.ipynb) |
|
||||
|
||||
## Configuration-driven example
|
||||
|
||||
Pipelines are run with Python or configuration. Pipelines can be instantiated in [configuration](../../../api/configuration/#pipeline) using the lower case name of the pipeline. Configuration-driven pipelines are run with [workflows](../../../workflow/#configuration-driven-example) or the [API](../../../api#local-instance).
|
||||
|
||||
### config.yml
|
||||
```yaml
|
||||
# Create pipeline using lower case class name
|
||||
llm:
|
||||
|
||||
# Run pipeline with workflow
|
||||
workflow:
|
||||
llm:
|
||||
tasks:
|
||||
- action: llm
|
||||
```
|
||||
|
||||
Similar to the Python example above, the underlying [Hugging Face pipeline parameters](https://huggingface.co/docs/transformers/main/main_classes/pipelines#transformers.pipeline.model) and [model parameters](https://huggingface.co/docs/transformers/model_doc/auto#transformers.AutoModel.from_pretrained) can be set in pipeline configuration.
|
||||
|
||||
```yaml
|
||||
llm:
|
||||
path: Qwen/Qwen3-0.6B
|
||||
dtype: torch.bfloat16
|
||||
```
|
||||
|
||||
### Run with Workflows
|
||||
|
||||
```python
|
||||
from txtai import Application
|
||||
|
||||
# Create and run pipeline with workflow
|
||||
app = Application("config.yml")
|
||||
list(app.workflow("llm", [
|
||||
"""
|
||||
Answer the following question using the provided context.
|
||||
|
||||
Question:
|
||||
What are the applications of txtai?
|
||||
|
||||
Context:
|
||||
txtai is an open-source platform for semantic search and
|
||||
workflows powered by language models.
|
||||
"""
|
||||
]))
|
||||
```
|
||||
|
||||
### Run with API
|
||||
|
||||
```bash
|
||||
CONFIG=config.yml uvicorn "txtai.api:app" &
|
||||
|
||||
curl \
|
||||
-X POST "http://localhost:8000/workflow" \
|
||||
-H "Content-Type: application/json" \
|
||||
-d '{"name":"llm", "elements": ["Answer the following question..."]}'
|
||||
```
|
||||
|
||||
## Methods
|
||||
|
||||
Python documentation for the pipeline.
|
||||
|
||||
### ::: txtai.pipeline.LLM.__init__
|
||||
### ::: txtai.pipeline.LLM.__call__
|
||||
@@ -3,9 +3,9 @@
|
||||

|
||||

|
||||
|
||||
The RAG pipeline (aka Extractor) joins a prompt, context data store and generative model together to extract knowledge.
|
||||
The Retrieval Augmented Generation (RAG) pipeline joins a prompt, context data store and generative model together to extract knowledge.
|
||||
|
||||
The data store can be an embeddings database or a similarity instance with associated input text. The generative model can be a prompt-driven large language model (LLM), an extractive question-answering model or a custom pipeline. This is known as retrieval augmented generation (RAG).
|
||||
The data store can be an embeddings database or a similarity instance with associated input text. The generative model can be a prompt-driven large language model (LLM), an extractive question-answering model or a custom pipeline.
|
||||
|
||||
## Example
|
||||
|
||||
@@ -30,8 +30,8 @@ data = [
|
||||
embeddings = Embeddings(content=True)
|
||||
embeddings.index(data)
|
||||
|
||||
# Create and run pipeline
|
||||
rag = RAG(embeddings, "google/flan-t5-base", template="""
|
||||
# Create the RAG pipeline
|
||||
rag = RAG(embeddings, "Qwen/Qwen3-0.6B", template="""
|
||||
Answer the following question using the provided context.
|
||||
|
||||
Question:
|
||||
@@ -41,30 +41,71 @@ rag = RAG(embeddings, "google/flan-t5-base", template="""
|
||||
{context}
|
||||
""")
|
||||
|
||||
# Run RAG pipeline
|
||||
rag("What was won?")
|
||||
|
||||
# Prompts with chat templating can be directly passed
|
||||
# The template format varies by model
|
||||
rag = RAG(embeddings, "Qwen/Qwen3-0.6B", template="""
|
||||
<|im_start|>system
|
||||
You are a friendly assistant.<|im_end|>
|
||||
<|im_start|>user
|
||||
Answer the following question using the provided context.
|
||||
|
||||
Question:
|
||||
{question}
|
||||
|
||||
Context:
|
||||
{context}
|
||||
<|im_start|>assistant
|
||||
"""
|
||||
)
|
||||
rag("What was won?")
|
||||
|
||||
# Inputs are automatically converted to chat messages when a
|
||||
# system prompt is provided
|
||||
rag = RAG(
|
||||
embeddings,
|
||||
"openai/gpt-oss-20b",
|
||||
system="You are a friendly assistant",
|
||||
template="""
|
||||
Answer the following question using the provided context.
|
||||
|
||||
Question:
|
||||
{question}
|
||||
|
||||
Context:
|
||||
{context}
|
||||
""")
|
||||
rag("What was won?")
|
||||
|
||||
# LLM options can be passed as additional arguments
|
||||
# - Streaming RAG response with `stream=True`
|
||||
# - String inputs are always converted to user messages with `defaultrole="user"`
|
||||
# - Thinking text is removed with `stripthink=True`
|
||||
rag("What was won?", stream=True, defaultrole="user", stripThink=True)
|
||||
```
|
||||
|
||||
See the [Embeddings](../../../embeddings) and [LLM](../llm) pages for additional configuration options.
|
||||
|
||||
See the links below for more detailed examples.
|
||||
Check out this [RAG Quickstart Example](https://github.com/neuml/txtai/blob/master/examples/rag_quickstart.py). Additional examples are listed below.
|
||||
|
||||
| Notebook | Description | |
|
||||
|:----------|:-------------|------:|
|
||||
| [Prompt-driven search with LLMs](https://github.com/neuml/txtai/blob/master/examples/42_Prompt_driven_search_with_LLMs.ipynb) | Embeddings-guided and Prompt-driven search with Large Language Models (LLMs) | [](https://colab.research.google.com/github/neuml/txtai/blob/master/examples/42_Prompt_driven_search_with_LLMs.ipynb) |
|
||||
| [Prompt templates and task chains](https://github.com/neuml/txtai/blob/master/examples/44_Prompt_templates_and_task_chains.ipynb) | Build model prompts and connect tasks together with workflows | [](https://colab.research.google.com/github/neuml/txtai/blob/master/examples/44_Prompt_templates_and_task_chains.ipynb) |
|
||||
| [Build RAG pipelines with txtai](https://github.com/neuml/txtai/blob/master/examples/52_Build_RAG_pipelines_with_txtai.ipynb) | Guide on retrieval augmented generation including how to create citations | [](https://colab.research.google.com/github/neuml/txtai/blob/master/examples/52_Build_RAG_pipelines_with_txtai.ipynb) |
|
||||
| [Build RAG pipelines with txtai](https://github.com/neuml/txtai/blob/master/examples/52_Build_RAG_pipelines_with_txtai.ipynb) [▶️](https://www.youtube.com/watch?v=t_OeAc8NVfQ) | Guide on retrieval augmented generation including how to create citations | [](https://colab.research.google.com/github/neuml/txtai/blob/master/examples/52_Build_RAG_pipelines_with_txtai.ipynb) |
|
||||
| [Integrate LLM frameworks](https://github.com/neuml/txtai/blob/master/examples/53_Integrate_LLM_Frameworks.ipynb) | Integrate llama.cpp, LiteLLM and custom generation frameworks | [](https://colab.research.google.com/github/neuml/txtai/blob/master/examples/53_Integrate_LLM_Frameworks.ipynb) |
|
||||
| [Generate knowledge with Semantic Graphs and RAG](https://github.com/neuml/txtai/blob/master/examples/55_Generate_knowledge_with_Semantic_Graphs_and_RAG.ipynb) | Knowledge exploration and discovery with Semantic Graphs and RAG | [](https://colab.research.google.com/github/neuml/txtai/blob/master/examples/55_Generate_knowledge_with_Semantic_Graphs_and_RAG.ipynb) |
|
||||
| [Build knowledge graphs with LLMs](https://github.com/neuml/txtai/blob/master/examples/57_Build_knowledge_graphs_with_LLM_driven_entity_extraction.ipynb) | Build knowledge graphs with LLM-driven entity extraction | [](https://colab.research.google.com/github/neuml/txtai/blob/master/examples/57_Build_knowledge_graphs_with_LLM_driven_entity_extraction.ipynb) |
|
||||
| [Advanced RAG with graph path traversal](https://github.com/neuml/txtai/blob/master/examples/58_Advanced_RAG_with_graph_path_traversal.ipynb) | Graph path traversal to collect complex sets of data for advanced RAG | [](https://colab.research.google.com/github/neuml/txtai/blob/master/examples/58_Advanced_RAG_with_graph_path_traversal.ipynb) |
|
||||
| [Advanced RAG with guided generation](https://github.com/neuml/txtai/blob/master/examples/60_Advanced_RAG_with_guided_generation.ipynb) | Retrieval Augmented and Guided Generation | [](https://colab.research.google.com/github/neuml/txtai/blob/master/examples/60_Advanced_RAG_with_guided_generation.ipynb) |
|
||||
| [RAG with llama.cpp and external API services](https://github.com/neuml/txtai/blob/master/examples/62_RAG_with_llama_cpp_and_external_API_services.ipynb) | RAG with additional vector and LLM frameworks | [](https://colab.research.google.com/github/neuml/txtai/blob/master/examples/62_RAG_with_llama_cpp_and_external_API_services.ipynb) |
|
||||
| [How RAG with txtai works](https://github.com/neuml/txtai/blob/master/examples/63_How_RAG_with_txtai_works.ipynb) | Create RAG processes, API services and Docker instances | [](https://colab.research.google.com/github/neuml/txtai/blob/master/examples/63_How_RAG_with_txtai_works.ipynb) |
|
||||
| [Speech to Speech RAG](https://github.com/neuml/txtai/blob/master/examples/65_Speech_to_Speech_RAG.ipynb) [▶️](https://www.youtube.com/watch?v=tH8QWwkVMKA) | Full cycle speech to speech workflow with RAG | [](https://colab.research.google.com/github/neuml/txtai/blob/master/examples/65_Speech_to_Speech_RAG.ipynb) |
|
||||
| [Generative Audio](https://github.com/neuml/txtai/blob/master/examples/66_Generative_Audio.ipynb) | Storytelling with generative audio workflows | [](https://colab.research.google.com/github/neuml/txtai/blob/master/examples/66_Generative_Audio.ipynb) |
|
||||
| [Extractive QA with txtai](https://github.com/neuml/txtai/blob/master/examples/05_Extractive_QA_with_txtai.ipynb) | Introduction to extractive question-answering with txtai | [](https://colab.research.google.com/github/neuml/txtai/blob/master/examples/05_Extractive_QA_with_txtai.ipynb) |
|
||||
| [Extractive QA with Elasticsearch](https://github.com/neuml/txtai/blob/master/examples/06_Extractive_QA_with_Elasticsearch.ipynb) | Run extractive question-answering queries with Elasticsearch | [](https://colab.research.google.com/github/neuml/txtai/blob/master/examples/06_Extractive_QA_with_Elasticsearch.ipynb) |
|
||||
| [Extractive QA to build structured data](https://github.com/neuml/txtai/blob/master/examples/20_Extractive_QA_to_build_structured_data.ipynb) | Build structured datasets using extractive question-answering | [](https://colab.research.google.com/github/neuml/txtai/blob/master/examples/20_Extractive_QA_to_build_structured_data.ipynb) |
|
||||
| [Parsing the stars with txtai](https://github.com/neuml/txtai/blob/master/examples/72_Parsing_the_stars_with_txtai.ipynb) | Explore an astronomical knowledge graph of known stars, planets, galaxies | [](https://colab.research.google.com/github/neuml/txtai/blob/master/examples/72_Parsing_the_stars_with_txtai.ipynb) |
|
||||
| [Chunking your data for RAG](https://github.com/neuml/txtai/blob/master/examples/73_Chunking_your_data_for_RAG.ipynb) | Extract, chunk and index content for effective retrieval | [](https://colab.research.google.com/github/neuml/txtai/blob/master/examples/73_Chunking_your_data_for_RAG.ipynb) |
|
||||
| [Medical RAG Research with txtai](https://github.com/neuml/txtai/blob/master/examples/75_Medical_RAG_Research_with_txtai.ipynb) | Analyze PubMed article metadata with RAG | [](https://colab.research.google.com/github/neuml/txtai/blob/master/examples/75_Medical_RAG_Research_with_txtai.ipynb) |
|
||||
| [GraphRAG with Wikipedia and GPT OSS](https://github.com/neuml/txtai/blob/master/examples/77_GraphRAG_with_Wikipedia_and_GPT_OSS.ipynb) | Deep graph search powered RAG | [](https://colab.research.google.com/github/neuml/txtai/blob/master/examples/77_GraphRAG_with_Wikipedia_and_GPT_OSS.ipynb) |
|
||||
| [RAG is more than Vector Search](https://github.com/neuml/txtai/blob/master/examples/79_RAG_is_more_than_Vector_Search.ipynb) | Context retrieval via Web, SQL and other sources | [](https://colab.research.google.com/github/neuml/txtai/blob/master/examples/79_RAG_is_more_than_Vector_Search.ipynb) |
|
||||
|
||||
## Configuration-driven example
|
||||
|
||||
@@ -80,7 +121,7 @@ embeddings:
|
||||
content: True
|
||||
|
||||
rag:
|
||||
path: google/flan-t5-base
|
||||
path: Qwen/Qwen3-0.6B
|
||||
template: |
|
||||
Answer the following question using the provided context.
|
||||
|
||||
@@ -16,6 +16,11 @@ from txtai.pipeline import Entity
|
||||
entity = Entity()
|
||||
entity("Canada's last fully intact ice shelf has suddenly collapsed, " \
|
||||
"forming a Manhattan-sized iceberg")
|
||||
|
||||
# Extract entities using a GLiNER model which supports dynamic labels
|
||||
entity = Entity("gliner-community/gliner_medium-v2.5")
|
||||
entity("Canada's last fully intact ice shelf has suddenly collapsed, " \
|
||||
"forming a Manhattan-sized iceberg", labels=["country", "city"])
|
||||
```
|
||||
|
||||
See the link below for a more detailed example.
|
||||
@@ -23,6 +28,7 @@ See the link below for a more detailed example.
|
||||
| Notebook | Description | |
|
||||
|:----------|:-------------|------:|
|
||||
| [Entity extraction workflows](https://github.com/neuml/txtai/blob/master/examples/26_Entity_extraction_workflows.ipynb) | Identify entity/label combinations | [](https://colab.research.google.com/github/neuml/txtai/blob/master/examples/26_Entity_extraction_workflows.ipynb) |
|
||||
| [Parsing the stars with txtai](https://github.com/neuml/txtai/blob/master/examples/72_Parsing_the_stars_with_txtai.ipynb) | Explore an astronomical knowledge graph of known stars, planets, galaxies | [](https://colab.research.google.com/github/neuml/txtai/blob/master/examples/72_Parsing_the_stars_with_txtai.ipynb) |
|
||||
|
||||
## Configuration-driven example
|
||||
|
||||
|
||||
@@ -1,168 +0,0 @@
|
||||
# LLM
|
||||
|
||||

|
||||

|
||||
|
||||
The LLM pipeline runs prompts through a large language model (LLM). This pipeline autodetects the LLM framework based on the model path.
|
||||
|
||||
## Example
|
||||
|
||||
The following shows a simple example using this pipeline.
|
||||
|
||||
```python
|
||||
from txtai import LLM
|
||||
|
||||
# Create LLM pipeline
|
||||
llm = LLM()
|
||||
|
||||
# Run prompt
|
||||
llm(
|
||||
"""
|
||||
Answer the following question using the provided context.
|
||||
|
||||
Question:
|
||||
What are the applications of txtai?
|
||||
|
||||
Context:
|
||||
txtai is an open-source platform for semantic search and
|
||||
workflows powered by language models.
|
||||
"""
|
||||
)
|
||||
|
||||
# Chat messages are also supported
|
||||
llm([
|
||||
{"role": "system", "content": "You are a friendly assistant."},
|
||||
{"role": "user", "content": "Answer the following question..."}
|
||||
])
|
||||
|
||||
```
|
||||
|
||||
The LLM pipeline automatically detects the underlying LLM framework. This can also be manually set.
|
||||
|
||||
See the [LiteLLM documentation](https://litellm.vercel.app/docs/providers) for the options available with LiteLLM models. llama.cpp models support both local and remote GGUF paths on the HF Hub.
|
||||
|
||||
```python
|
||||
from txtai import LLM
|
||||
|
||||
# Transformers
|
||||
llm = LLM("meta-llama/Meta-Llama-3.1-8B-Instruct")
|
||||
llm = LLM("meta-llama/Meta-Llama-3.1-8B-Instruct", method="transformers")
|
||||
|
||||
# llama.cpp
|
||||
llm = LLM("microsoft/Phi-3-mini-4k-instruct-gguf/Phi-3-mini-4k-instruct-gguf")
|
||||
llm = LLM("microsoft/Phi-3-mini-4k-instruct-gguf/Phi-3-mini-4k-instruct-gguf",
|
||||
method="llama.cpp")
|
||||
|
||||
# LiteLLM
|
||||
llm = LLM("ollama/llama3.1")
|
||||
llm = LLM("ollama/llama3.1", method="litellm")
|
||||
|
||||
# Custom Ollama endpoint
|
||||
llm = LLM("ollama/llama3.1", api_base="http://localhost:11434")
|
||||
|
||||
# Custom OpenAI-compatible endpoint
|
||||
llm = LLM("openai/llama3.1", api_base="http://localhost:4000")
|
||||
|
||||
# LLM APIs - must also set API key via environment variable
|
||||
llm = LLM("gpt-4o")
|
||||
llm = LLM("claude-3-5-sonnet-20240620")
|
||||
```
|
||||
|
||||
Models can be externally loaded and passed to pipelines. This is useful for models that are not yet supported by Transformers and/or need special initialization.
|
||||
|
||||
```python
|
||||
import torch
|
||||
|
||||
from transformers import AutoModelForCausalLM, AutoTokenizer
|
||||
from txtai import LLM
|
||||
|
||||
# Load Phi 3.5-mini
|
||||
path = "microsoft/Phi-3.5-mini-instruct"
|
||||
model = AutoModelForCausalLM.from_pretrained(
|
||||
path,
|
||||
torch_dtype=torch.bfloat16,
|
||||
)
|
||||
tokenizer = AutoTokenizer.from_pretrained(path)
|
||||
|
||||
llm = LLM((model, tokenizer))
|
||||
```
|
||||
|
||||
See the links below for more detailed examples.
|
||||
|
||||
| Notebook | Description | |
|
||||
|:----------|:-------------|------:|
|
||||
| [Prompt-driven search with LLMs](https://github.com/neuml/txtai/blob/master/examples/42_Prompt_driven_search_with_LLMs.ipynb) | Embeddings-guided and Prompt-driven search with Large Language Models (LLMs) | [](https://colab.research.google.com/github/neuml/txtai/blob/master/examples/42_Prompt_driven_search_with_LLMs.ipynb) |
|
||||
| [Prompt templates and task chains](https://github.com/neuml/txtai/blob/master/examples/44_Prompt_templates_and_task_chains.ipynb) | Build model prompts and connect tasks together with workflows | [](https://colab.research.google.com/github/neuml/txtai/blob/master/examples/44_Prompt_templates_and_task_chains.ipynb) |
|
||||
| [Build RAG pipelines with txtai](https://github.com/neuml/txtai/blob/master/examples/52_Build_RAG_pipelines_with_txtai.ipynb) | Guide on retrieval augmented generation including how to create citations | [](https://colab.research.google.com/github/neuml/txtai/blob/master/examples/52_Build_RAG_pipelines_with_txtai.ipynb) |
|
||||
| [Integrate LLM frameworks](https://github.com/neuml/txtai/blob/master/examples/53_Integrate_LLM_Frameworks.ipynb) | Integrate llama.cpp, LiteLLM and custom generation frameworks | [](https://colab.research.google.com/github/neuml/txtai/blob/master/examples/53_Integrate_LLM_Frameworks.ipynb) |
|
||||
| [Generate knowledge with Semantic Graphs and RAG](https://github.com/neuml/txtai/blob/master/examples/55_Generate_knowledge_with_Semantic_Graphs_and_RAG.ipynb) | Knowledge exploration and discovery with Semantic Graphs and RAG | [](https://colab.research.google.com/github/neuml/txtai/blob/master/examples/55_Generate_knowledge_with_Semantic_Graphs_and_RAG.ipynb) |
|
||||
| [Build knowledge graphs with LLMs](https://github.com/neuml/txtai/blob/master/examples/57_Build_knowledge_graphs_with_LLM_driven_entity_extraction.ipynb) | Build knowledge graphs with LLM-driven entity extraction | [](https://colab.research.google.com/github/neuml/txtai/blob/master/examples/57_Build_knowledge_graphs_with_LLM_driven_entity_extraction.ipynb) |
|
||||
| [Advanced RAG with graph path traversal](https://github.com/neuml/txtai/blob/master/examples/58_Advanced_RAG_with_graph_path_traversal.ipynb) | Graph path traversal to collect complex sets of data for advanced RAG | [](https://colab.research.google.com/github/neuml/txtai/blob/master/examples/58_Advanced_RAG_with_graph_path_traversal.ipynb) |
|
||||
| [Advanced RAG with guided generation](https://github.com/neuml/txtai/blob/master/examples/60_Advanced_RAG_with_guided_generation.ipynb) | Retrieval Augmented and Guided Generation | [](https://colab.research.google.com/github/neuml/txtai/blob/master/examples/60_Advanced_RAG_with_guided_generation.ipynb) |
|
||||
| [RAG with llama.cpp and external API services](https://github.com/neuml/txtai/blob/master/examples/62_RAG_with_llama_cpp_and_external_API_services.ipynb) | RAG with additional vector and LLM frameworks | [](https://colab.research.google.com/github/neuml/txtai/blob/master/examples/62_RAG_with_llama_cpp_and_external_API_services.ipynb) |
|
||||
| [How RAG with txtai works](https://github.com/neuml/txtai/blob/master/examples/63_How_RAG_with_txtai_works.ipynb) | Create RAG processes, API services and Docker instances | [](https://colab.research.google.com/github/neuml/txtai/blob/master/examples/63_How_RAG_with_txtai_works.ipynb) |
|
||||
| [Speech to Speech RAG](https://github.com/neuml/txtai/blob/master/examples/65_Speech_to_Speech_RAG.ipynb) [▶️](https://www.youtube.com/watch?v=tH8QWwkVMKA) | Full cycle speech to speech workflow with RAG | [](https://colab.research.google.com/github/neuml/txtai/blob/master/examples/65_Speech_to_Speech_RAG.ipynb) |
|
||||
| [Generative Audio](https://github.com/neuml/txtai/blob/master/examples/66_Generative_Audio.ipynb) | Storytelling with generative audio workflows | [](https://colab.research.google.com/github/neuml/txtai/blob/master/examples/66_Generative_Audio.ipynb) |
|
||||
|
||||
## Configuration-driven example
|
||||
|
||||
Pipelines are run with Python or configuration. Pipelines can be instantiated in [configuration](../../../api/configuration/#pipeline) using the lower case name of the pipeline. Configuration-driven pipelines are run with [workflows](../../../workflow/#configuration-driven-example) or the [API](../../../api#local-instance).
|
||||
|
||||
### config.yml
|
||||
```yaml
|
||||
# Create pipeline using lower case class name
|
||||
llm:
|
||||
|
||||
# Run pipeline with workflow
|
||||
workflow:
|
||||
llm:
|
||||
tasks:
|
||||
- action: llm
|
||||
```
|
||||
|
||||
Similar to the Python example above, the underlying [Hugging Face pipeline parameters](https://huggingface.co/docs/transformers/main/main_classes/pipelines#transformers.pipeline.model) and [model parameters](https://huggingface.co/docs/transformers/model_doc/auto#transformers.AutoModel.from_pretrained) can be set in pipeline configuration.
|
||||
|
||||
```yaml
|
||||
llm:
|
||||
path: microsoft/Phi-3.5-mini-instruct
|
||||
torch_dtype: torch.bfloat16
|
||||
```
|
||||
|
||||
### Run with Workflows
|
||||
|
||||
```python
|
||||
from txtai import Application
|
||||
|
||||
# Create and run pipeline with workflow
|
||||
app = Application("config.yml")
|
||||
list(app.workflow("llm", [
|
||||
"""
|
||||
Answer the following question using the provided context.
|
||||
|
||||
Question:
|
||||
What are the applications of txtai?
|
||||
|
||||
Context:
|
||||
txtai is an open-source platform for semantic search and
|
||||
workflows powered by language models.
|
||||
"""
|
||||
]))
|
||||
```
|
||||
|
||||
### Run with API
|
||||
|
||||
```bash
|
||||
CONFIG=config.yml uvicorn "txtai.api:app" &
|
||||
|
||||
curl \
|
||||
-X POST "http://localhost:8000/workflow" \
|
||||
-H "Content-Type: application/json" \
|
||||
-d '{"name":"llm", "elements": ["Answer the following question..."]}'
|
||||
```
|
||||
|
||||
## Methods
|
||||
|
||||
Python documentation for the pipeline.
|
||||
|
||||
### ::: txtai.pipeline.LLM.__init__
|
||||
### ::: txtai.pipeline.LLM.__call__
|
||||
@@ -0,0 +1,82 @@
|
||||
# Reranker
|
||||
|
||||

|
||||

|
||||
|
||||
The Reranker pipeline runs embeddings queries and re-ranks them using a similarity pipeline.
|
||||
|
||||
## Example
|
||||
|
||||
The following shows a simple example using this pipeline.
|
||||
|
||||
```python
|
||||
from txtai import Embeddings
|
||||
from txtai.pipeline import Reranker, Similarity
|
||||
|
||||
# Embeddings instance
|
||||
embeddings = Embeddings()
|
||||
embeddings.load(provider="huggingface-hub", container="neuml/txtai-wikipedia")
|
||||
|
||||
# Similarity instance
|
||||
similarity = Similarity(path="colbert-ir/colbertv2.0", lateencode=True)
|
||||
|
||||
# Reranking pipeline
|
||||
reranker = Reranker(embeddings, similarity)
|
||||
reranker("Tell me about AI")
|
||||
```
|
||||
|
||||
_Note: Content must be enabled with the embeddings instance for this to work properly._
|
||||
|
||||
See the link below for a more detailed example.
|
||||
|
||||
| Notebook | Description | |
|
||||
|:----------|:-------------|------:|
|
||||
| [What's new in txtai 9.0](https://github.com/neuml/txtai/blob/master/examples/76_Whats_new_in_txtai_9_0.ipynb) | Learned sparse vectors, late interaction models and rerankers | [](https://colab.research.google.com/github/neuml/txtai/blob/master/examples/76_Whats_new_in_txtai_9_0.ipynb) |
|
||||
|
||||
## Configuration-driven example
|
||||
|
||||
Pipelines are run with Python or configuration. Pipelines can be instantiated in [configuration](../../../api/configuration/#pipeline) using the lower case name of the pipeline. Configuration-driven pipelines are run with [workflows](../../../workflow/#configuration-driven-example) or the [API](../../../api#local-instance).
|
||||
|
||||
### config.yml
|
||||
```yaml
|
||||
embeddings:
|
||||
|
||||
similarity:
|
||||
|
||||
# Create pipeline using lower case class name
|
||||
reranker:
|
||||
|
||||
# Run pipeline with workflow
|
||||
workflow:
|
||||
translate:
|
||||
tasks:
|
||||
- reranker
|
||||
```
|
||||
|
||||
### Run with Workflows
|
||||
|
||||
```python
|
||||
from txtai import Application
|
||||
|
||||
# Create and run pipeline with workflow
|
||||
app = Application("config.yml")
|
||||
list(app.workflow("reranker", ["Tell me about AI"]))
|
||||
```
|
||||
|
||||
### Run with API
|
||||
|
||||
```bash
|
||||
CONFIG=config.yml uvicorn "txtai.api:app" &
|
||||
|
||||
curl \
|
||||
-X POST "http://localhost:8000/workflow" \
|
||||
-H "Content-Type: application/json" \
|
||||
-d '{"name":"rerank", "elements":["Tell me about AI"]}'
|
||||
```
|
||||
|
||||
## Methods
|
||||
|
||||
Python documentation for the pipeline.
|
||||
|
||||
### ::: txtai.pipeline.Reranker.__init__
|
||||
### ::: txtai.pipeline.Reranker.__call__
|
||||
@@ -7,7 +7,7 @@ The Similarity pipeline computes similarity between queries and list of text usi
|
||||
|
||||
This pipeline supports both standard text classification models and zero-shot classification models. The pipeline uses the queries as labels for the input text. The results are transposed to get scores per query/label vs scores per input text.
|
||||
|
||||
Cross-encoder models are supported via the `crossencode=True` constructor parameter. These models are loaded with a CrossEncoder pipeline that can also be instantiated directly. The CrossEncoder pipeline has the same methods and functionality as described below.
|
||||
Cross-encoder models are supported via the `crossencode=True` constructor parameter. Late interaction (i.e. ColBERT) models are also supported via the `lateencode=True` constructor parameter. CrossEncoder and LateEncoder pipelines back each of these models and can be instantiated directly as well.
|
||||
|
||||
## Example
|
||||
|
||||
|
||||
@@ -0,0 +1,98 @@
|
||||
# LemurTrainer
|
||||
|
||||

|
||||

|
||||
|
||||
Trains a LEMUR fixed dimensional encoder for a late interaction model and corpus. Training is a separate pipeline step; the saved
|
||||
artifact is then loaded through the embeddings `vectors.lemur` configuration.
|
||||
|
||||
`LemurTrainer` owns training-data construction, feature-model setup, epoch training and validation-based selection. The loaded LEMUR
|
||||
pooler remains responsible for query-feature and document-weight encoding.
|
||||
|
||||
## Example
|
||||
|
||||
```python
|
||||
from txtai.pipeline import LemurTrainer
|
||||
|
||||
corpus = [
|
||||
"First document",
|
||||
"Second document",
|
||||
"Third document",
|
||||
]
|
||||
|
||||
trainer = LemurTrainer()
|
||||
trainer(
|
||||
"colbert-ir/colbertv2.0",
|
||||
corpus,
|
||||
"lemur-model",
|
||||
epochs=100,
|
||||
validationsplit=0.1,
|
||||
)
|
||||
```
|
||||
|
||||
`epochs` is required so the training mode is explicit. Use `epochs=100` for the quality-oriented MLP setting. This can take hours on
|
||||
a CPU. Use `epochs=0` to select deterministic random ELM features as a lower-cost fallback.
|
||||
|
||||
The learn distribution defaults to `learncategory="query"`. Target documents are always encoded with the data encoder, so the
|
||||
default encodes selected corpus texts once as data and once as queries. Set `learncategory="data"` to reuse the data encodings, or
|
||||
pass a separate iterable of texts with `learn`.
|
||||
|
||||
When `vectors.center` is omitted, the trainer encodes the corpus without centering, computes one mean over all corpus token rows and
|
||||
uses that mean to center both data and learn vectors before fitting. The collection mean is stored in the LEMUR artifact. An explicit
|
||||
`vectors.center` setting keeps its configured behavior and does not store an automatic collection mean.
|
||||
|
||||
Set `corpussubsetsize` to a positive integer to sample that many raw corpus texts under `seed` before either encoding pass. The
|
||||
default is `None`, which uses every corpus text. `trainsubsetsize` and `learnsubsetsize` apply later, after token vectors have already
|
||||
been created. `corpussubsetsize` applies to `data`; a separate `learn` iterable remains caller-sized.
|
||||
|
||||
For trained MLP features, set `validationsplit` to a fraction greater than zero and less than one to retain the epoch with the lowest
|
||||
held-out loss. The default is `0.0`, which preserves training-loss selection. The selected one-based epoch, loss and metric are
|
||||
available as `selectedepoch`, `selectedloss` and `selectionmetric` on the fitted or reloaded encoder.
|
||||
|
||||
MLP training displays a `tqdm` progress bar on an interactive terminal, including percent complete and the current validation loss
|
||||
when `validationsplit` is enabled (or training loss otherwise). Progress output is disabled for non-interactive runs.
|
||||
|
||||
The artifact contains `config.json` and `model.safetensors`. It stores the inference feature model, output-normalization statistics,
|
||||
token sample needed to encode documents added after training and, by default, the collection token mean. The training-only output
|
||||
readout is not saved.
|
||||
|
||||
Load the artifact in an embeddings configuration.
|
||||
|
||||
```yaml
|
||||
embeddings:
|
||||
path: colbert-ir/colbertv2.0
|
||||
vectors:
|
||||
lemur:
|
||||
path: lemur-model
|
||||
```
|
||||
|
||||
## Search behavior
|
||||
|
||||
Loading a LEMUR artifact with a stored collection mean automatically centers both query and document token vectors with that mean.
|
||||
This keeps training and search on the same representation and makes fixed vectors independent of indexing or query batch size. An
|
||||
explicit `vectors.center` setting takes precedence. Older artifacts without a stored mean use the standard late-pooling fallback:
|
||||
batch centering for models with multiple linear layers and no centering for models with zero or one linear layer.
|
||||
|
||||
LEMUR approximates standardized MaxSim targets, so useful ranking scores can be negative. txtai's dense vector path L2-normalizes the
|
||||
fixed vectors and removes results with scores less than or equal to zero. This can change ordering and return fewer than the requested
|
||||
number of candidates compared with raw maximum inner-product search.
|
||||
|
||||
The Faiss backend uses exact `IDMap,Flat` search through 5,000 rows and switches to an IVF index above that threshold. In the measured
|
||||
scifact run, default IVF reduced LEMUR NDCG@10 by 43% relative to exact search, compared with 25% for MUVERA. For LEMUR corpora above
|
||||
5,000 rows, either pin `faiss.components` to an exact index or tune the IVF settings for the corpus. The exact configuration is:
|
||||
|
||||
```yaml
|
||||
embeddings:
|
||||
path: colbert-ir/colbertv2.0
|
||||
vectors:
|
||||
lemur:
|
||||
path: lemur-model
|
||||
faiss:
|
||||
components: IDMap,Flat
|
||||
```
|
||||
|
||||
## Methods
|
||||
|
||||
Python documentation for the pipeline.
|
||||
|
||||
### ::: txtai.pipeline.LemurTrainer.__call__
|
||||
@@ -98,6 +98,20 @@ See the following PEFT documentation links for more information.
|
||||
- [Quantization](https://huggingface.co/docs/peft/developer_guides/quantization)
|
||||
- [LoRA](https://huggingface.co/docs/peft/developer_guides/lora)
|
||||
|
||||
## Merge
|
||||
|
||||
An important parameter for `language-generation` and `language-modeling` tasks is `merge` or the packing of data into chunks.
|
||||
|
||||
It supports the following options.
|
||||
|
||||
- `concat` (default) - text is split into chunks up to maxlength, data can be split across multiple chunks
|
||||
- `pack` - text is split into chunks up to maxlength, data guaranteed to be in same chunk, chunks can be smaller than maxlength
|
||||
- `None` - disables merging
|
||||
|
||||
Merging helps reduce training time as data can be processed efficiently without padding. `concat` maximizes this as it guarantees each chunk will be up to maxlength size. `pack` is a middle ground where data is combined but records are preserved.
|
||||
|
||||
For general language modeling tasks like masked language modeling, `concat` is the best choice. For instruction/prompt fine-tuning, `pack` or None are the better choices as it guarantees complex logic is not split across chunks.
|
||||
|
||||
## Methods
|
||||
|
||||
Python documentation for the pipeline.
|
||||
|
||||
+4
-4
@@ -6,9 +6,9 @@ The following applications are powered by txtai.
|
||||
|
||||
| Application | Description |
|
||||
|:------------ |:-------------|
|
||||
| [txtchat](https://github.com/neuml/txtchat) | Retrieval Augmented Generation (RAG) powered search |
|
||||
| [paperai](https://github.com/neuml/paperai) | Semantic search and workflows for medical/scientific papers |
|
||||
| [codequestion](https://github.com/neuml/codequestion) | Semantic search for developers |
|
||||
| [tldrstory](https://github.com/neuml/tldrstory) | Semantic search for headlines and story text |
|
||||
| [rag](https://github.com/neuml/rag) | Retrieval Augmented Generation (RAG) application |
|
||||
| [ncoder](https://github.com/neuml/ncoder) | Open-Source AI coding agent |
|
||||
| [paperai](https://github.com/neuml/paperai) | AI for medical and scientific papers |
|
||||
| [annotateai](https://github.com/neuml/annotateai) | Automatically annotate papers with LLMs |
|
||||
|
||||
In addition to this list, there are also many other [open-source projects](https://github.com/neuml/txtai/network/dependents), [published research](https://scholar.google.com/scholar?q=txtai&hl=en&as_ylo=2022) and closed proprietary/commercial projects that have built on txtai in production.
|
||||
|
||||
+13
-8
@@ -1,6 +1,6 @@
|
||||
# Use Cases
|
||||
|
||||
The following sections introduce common txtai use cases. A comprehensive set of over 60 [example notebooks and applications](../examples) are also available.
|
||||
The following sections introduce common txtai use cases. A comprehensive set of over 70 [example notebooks and applications](../examples) are also available.
|
||||
|
||||
## Semantic Search
|
||||
|
||||
@@ -42,13 +42,16 @@ Agents connect embeddings, pipelines, workflows and other agents together to aut
|
||||
|
||||

|
||||
|
||||
txtai agents are built on top of the Transformers Agent framework. This supports all LLMs txtai supports (Hugging Face, llama.cpp, OpenAI / Claude / AWS Bedrock via LiteLLM).
|
||||
txtai agents are built on top of the [smolagents](https://github.com/huggingface/smolagents) framework. This supports all LLMs txtai supports (Hugging Face, llama.cpp, OpenAI / Claude / AWS Bedrock via LiteLLM). Agent prompting with [`agents.md`](https://github.com/agentsmd/agents.md) and [`skill.md`](https://agentskills.io/specification) are also supported.
|
||||
|
||||
See the link below to learn more.
|
||||
Check out this [Agent Quickstart Example](https://github.com/neuml/txtai/blob/master/examples/agent_quickstart.py). Additional examples are listed below.
|
||||
|
||||
| Notebook | Description | |
|
||||
|:----------|:-------------|------:|
|
||||
| [What's new in txtai 8.0](https://github.com/neuml/txtai/blob/master/examples/67_Whats_new_in_txtai_8_0.ipynb) | Agents with txtai | [](https://colab.research.google.com/github/neuml/txtai/blob/master/examples/67_Whats_new_in_txtai_8_0.ipynb) |
|
||||
| [Granting autonomy to agents](https://github.com/neuml/txtai/blob/master/examples/69_Granting_autonomy_to_agents.ipynb) | Agents that iteratively solve problems as they see fit | [](https://colab.research.google.com/github/neuml/txtai/blob/master/examples/69_Granting_autonomy_to_agents.ipynb) |
|
||||
| [TxtAI got skills](https://github.com/neuml/txtai/blob/master/examples/83_TxtAI_got_skills.ipynb) | Integrate skill.md files with your agent | [](https://colab.research.google.com/github/neuml/txtai/blob/master/examples/83_TxtAI_got_skills.ipynb) |
|
||||
| [Agent Tools](https://github.com/neuml/txtai/blob/master/examples/84_Agent_Tools.ipynb) [▶️](https://www.youtube.com/watch?v=RDNaFXQy3GQ) | Learn about the txtai agent toolkit | [](https://colab.research.google.com/github/neuml/txtai/blob/master/examples/84_Agent_Tools.ipynb) |
|
||||
| [Analyzing LinkedIn Company Posts with Graphs and Agents](https://github.com/neuml/txtai/blob/master/examples/71_Analyzing_LinkedIn_Company_Posts_with_Graphs_and_Agents.ipynb) | Exploring how to improve social media engagement with AI | [](https://colab.research.google.com/github/neuml/txtai/blob/master/examples/71_Analyzing_LinkedIn_Company_Posts_with_Graphs_and_Agents.ipynb) |
|
||||
|
||||
### Retrieval augmented generation
|
||||
|
||||
@@ -57,13 +60,13 @@ Retrieval augmented generation (RAG) reduces the risk of LLM hallucinations by c
|
||||

|
||||

|
||||
|
||||
A novel feature of txtai is that it can provide both an answer and source citation.
|
||||
Check out this [RAG Quickstart Example](https://github.com/neuml/txtai/blob/master/examples/rag_quickstart.py). Additional examples are listed below.
|
||||
|
||||
| Notebook | Description | |
|
||||
|:----------|:-------------|------:|
|
||||
| [Build RAG pipelines with txtai](https://github.com/neuml/txtai/blob/master/examples/52_Build_RAG_pipelines_with_txtai.ipynb) | Guide on retrieval augmented generation including how to create citations | [](https://colab.research.google.com/github/neuml/txtai/blob/master/examples/52_Build_RAG_pipelines_with_txtai.ipynb) |
|
||||
| [How RAG with txtai works](https://github.com/neuml/txtai/blob/master/examples/63_How_RAG_with_txtai_works.ipynb) | Create RAG processes, API services and Docker instances | [](https://colab.research.google.com/github/neuml/txtai/blob/master/examples/63_How_RAG_with_txtai_works.ipynb) |
|
||||
| [Advanced RAG with graph path traversal](https://github.com/neuml/txtai/blob/master/examples/58_Advanced_RAG_with_graph_path_traversal.ipynb) | Graph path traversal to collect complex sets of data for advanced RAG | [](https://colab.research.google.com/github/neuml/txtai/blob/master/examples/58_Advanced_RAG_with_graph_path_traversal.ipynb) |
|
||||
| [Build RAG pipelines with txtai](https://github.com/neuml/txtai/blob/master/examples/52_Build_RAG_pipelines_with_txtai.ipynb) [▶️](https://www.youtube.com/watch?v=t_OeAc8NVfQ) | Guide on retrieval augmented generation including how to create citations | [](https://colab.research.google.com/github/neuml/txtai/blob/master/examples/52_Build_RAG_pipelines_with_txtai.ipynb) |
|
||||
| [RAG is more than Vector Search](https://github.com/neuml/txtai/blob/master/examples/79_RAG_is_more_than_Vector_Search.ipynb) | Context retrieval via Web, SQL and other sources | [](https://colab.research.google.com/github/neuml/txtai/blob/master/examples/79_RAG_is_more_than_Vector_Search.ipynb) |
|
||||
| [GraphRAG with Wikipedia and GPT OSS](https://github.com/neuml/txtai/blob/master/examples/77_GraphRAG_with_Wikipedia_and_GPT_OSS.ipynb) | Deep graph search powered RAG | [](https://colab.research.google.com/github/neuml/txtai/blob/master/examples/77_GraphRAG_with_Wikipedia_and_GPT_OSS.ipynb) |
|
||||
| [Speech to Speech RAG](https://github.com/neuml/txtai/blob/master/examples/65_Speech_to_Speech_RAG.ipynb) [▶️](https://www.youtube.com/watch?v=tH8QWwkVMKA) | Full cycle speech to speech workflow with RAG | [](https://colab.research.google.com/github/neuml/txtai/blob/master/examples/65_Speech_to_Speech_RAG.ipynb) |
|
||||
|
||||
## Language Model Workflows
|
||||
@@ -75,6 +78,8 @@ Language model workflows, also known as semantic workflows, connect language mod
|
||||
|
||||
While LLMs are powerful, there are plenty of smaller, more specialized models that work better and faster for specific tasks. This includes models for extractive question-answering, automatic summarization, text-to-speech, transcription and translation.
|
||||
|
||||
Check out this [Workflow Quickstart Example](https://github.com/neuml/txtai/blob/master/examples/workflow_quickstart.py). Additional examples are listed below.
|
||||
|
||||
| Notebook | Description | |
|
||||
|:----------|:-------------|------:|
|
||||
| [Run pipeline workflows](https://github.com/neuml/txtai/blob/master/examples/14_Run_pipeline_workflows.ipynb) [▶️](https://www.youtube.com/watch?v=UBMPDCn1gEU) | Simple yet powerful constructs to efficiently process data | [](https://colab.research.google.com/github/neuml/txtai/blob/master/examples/14_Run_pipeline_workflows.ipynb) |
|
||||
|
||||
@@ -133,7 +133,7 @@ Workflows can connect multiple LLM prompting tasks together.
|
||||
|
||||
```yaml
|
||||
llm:
|
||||
path: google/flan-t5-xl
|
||||
path: openai/gpt-oss-20b
|
||||
|
||||
workflow:
|
||||
llm:
|
||||
@@ -168,7 +168,7 @@ Any txtai pipeline/workflow task can be connected in workflows with LLMs.
|
||||
|
||||
```yaml
|
||||
llm:
|
||||
path: google/flan-t5-xl
|
||||
path: openai/gpt-oss-20b
|
||||
|
||||
translation:
|
||||
|
||||
@@ -202,4 +202,4 @@ Workflows are callable objects. Workflows take an input of iterable data element
|
||||
|
||||
## More examples
|
||||
|
||||
See [this link](../examples/#workflows) for a full list of workflow examples.
|
||||
Check out this [Workflow Quickstart Example](https://github.com/neuml/txtai/blob/master/examples/workflow_quickstart.py). See [this link](../examples/#workflows) for a full list of workflow examples.
|
||||
|
||||
@@ -22,8 +22,9 @@ This task can also be created with workflow configuration.
|
||||
|
||||
```yaml
|
||||
workflow:
|
||||
tasks:
|
||||
- task: console
|
||||
name:
|
||||
tasks:
|
||||
- task: console
|
||||
```
|
||||
|
||||
## Methods
|
||||
|
||||
@@ -22,8 +22,9 @@ This task can also be created with workflow configuration.
|
||||
|
||||
```yaml
|
||||
workflow:
|
||||
tasks:
|
||||
- task: export
|
||||
name:
|
||||
tasks:
|
||||
- task: export
|
||||
```
|
||||
|
||||
## Methods
|
||||
|
||||
@@ -22,8 +22,9 @@ This task can also be created with workflow configuration.
|
||||
|
||||
```yaml
|
||||
workflow:
|
||||
tasks:
|
||||
- task: file
|
||||
name:
|
||||
tasks:
|
||||
- task: file
|
||||
```
|
||||
|
||||
## Methods
|
||||
|
||||
@@ -22,8 +22,9 @@ This task can also be created with workflow configuration.
|
||||
|
||||
```yaml
|
||||
workflow:
|
||||
tasks:
|
||||
- task: image
|
||||
name:
|
||||
tasks:
|
||||
- task: image
|
||||
```
|
||||
|
||||
## Methods
|
||||
|
||||
@@ -35,12 +35,26 @@ Tasks can also be created with configuration as part of a workflow.
|
||||
|
||||
```yaml
|
||||
workflow:
|
||||
tasks:
|
||||
- action: summary
|
||||
name:
|
||||
tasks:
|
||||
- action: summary
|
||||
```
|
||||
|
||||
::: txtai.workflow.Task.__init__
|
||||
|
||||
## Multi-action task inputs
|
||||
|
||||
A multi-action `Task` requires reusable inputs. Passing a single-pass iterator, such as a generator or the output of a `StreamTask`, raises a `ValueError` before consuming inputs or running any actions. Automatically buffering an iterator could exhaust memory, so tasks do not convert these inputs to a list.
|
||||
|
||||
Iterators passed to a `Workflow` remain supported: the workflow collects bounded batches before passing them to its tasks. For example:
|
||||
|
||||
```python
|
||||
workflow = Workflow([Task([list, list])], batch=2)
|
||||
list(workflow(iter([1, 2, 3]))) # [(1, 1), (2, 2), (3, 3)]
|
||||
```
|
||||
|
||||
This batching occurs at the workflow input; it does not batch iterator outputs produced by tasks inside that workflow. Single-action tasks continue to accept iterator inputs.
|
||||
|
||||
## Multi-action task concurrency
|
||||
|
||||
The default processing mode is to run actions sequentially. Multiprocessing support is already built in at a number of levels. Any of the GPU models will maximize GPU utilization for example and even in CPU mode, concurrency is utilized. But there are still use cases for task action concurrency. For example, if the system has multiple GPUs, the task runs external sequential code, or the task has a large number of I/O tasks.
|
||||
@@ -72,7 +86,7 @@ workflow = Workflow([Task(lambda x: [y * 3 for y in x], unpack=False, column=0)]
|
||||
list(workflow([(2, 8)]))
|
||||
```
|
||||
|
||||
For the example input tuple of (2, 2), the workflow will only select the first element (2) and run the task against that element.
|
||||
For the example input tuple of (2, 8), the workflow will only select the first element (2) and run the task against that element.
|
||||
|
||||
```python
|
||||
workflow = Workflow([Task([lambda x: [y * 3 for y in x],
|
||||
|
||||
@@ -22,9 +22,10 @@ This task can also be created with workflow configuration.
|
||||
|
||||
```yaml
|
||||
workflow:
|
||||
tasks:
|
||||
- task: retrieve
|
||||
directory: /tmp
|
||||
name:
|
||||
tasks:
|
||||
- task: retrieve
|
||||
directory: /tmp
|
||||
```
|
||||
|
||||
## Methods
|
||||
|
||||
@@ -22,9 +22,10 @@ This task can also be created with workflow configuration.
|
||||
|
||||
```yaml
|
||||
workflow:
|
||||
tasks:
|
||||
- task: service
|
||||
url: https://service.url/action
|
||||
name:
|
||||
tasks:
|
||||
- task: service
|
||||
url: https://service.url/action
|
||||
```
|
||||
|
||||
## Methods
|
||||
|
||||
@@ -22,8 +22,9 @@ This task can also be created with workflow configuration.
|
||||
|
||||
```yaml
|
||||
workflow:
|
||||
tasks:
|
||||
- task: storage
|
||||
name:
|
||||
tasks:
|
||||
- task: storage
|
||||
```
|
||||
|
||||
## Methods
|
||||
|
||||
@@ -23,9 +23,10 @@ This task can also be created with workflow configuration.
|
||||
|
||||
```yaml
|
||||
workflow:
|
||||
tasks:
|
||||
- task: template
|
||||
template: This is a {text} task
|
||||
name:
|
||||
tasks:
|
||||
- task: template
|
||||
template: This is a {text} task
|
||||
```
|
||||
|
||||
## Methods
|
||||
|
||||
@@ -22,8 +22,9 @@ This task can also be created with workflow configuration.
|
||||
|
||||
```yaml
|
||||
workflow:
|
||||
tasks:
|
||||
- task: url
|
||||
name:
|
||||
tasks:
|
||||
- task: url
|
||||
```
|
||||
|
||||
## Methods
|
||||
|
||||
+464
-454
File diff suppressed because one or more lines are too long
@@ -1,15 +1,4 @@
|
||||
{
|
||||
"nbformat": 4,
|
||||
"nbformat_minor": 0,
|
||||
"metadata": {
|
||||
"colab": {
|
||||
"provenance": []
|
||||
},
|
||||
"kernelspec": {
|
||||
"name": "python3",
|
||||
"display_name": "Python 3"
|
||||
}
|
||||
},
|
||||
"cells": [
|
||||
{
|
||||
"cell_type": "markdown",
|
||||
@@ -21,7 +10,7 @@
|
||||
"\n",
|
||||
"In Part 1, we gave a general overview of txtai, the backing technology and examples of how to use it for similarity searches. Part 2 covered an embedding index with a larger dataset.\n",
|
||||
"\n",
|
||||
"For real world large-scale use cases, data is often stored in a database (Elasticsearch, SQL, MongoDB, files, etc). Here we'll show how to read from SQLite, build a Embedding index backed by word embeddings and run queries against the generated Embeddings index.\n",
|
||||
"For real world large-scale use cases, data is often stored in a database (Elasticsearch, SQL, MongoDB, files, etc). Here we'll show how to read from SQLite, build an Embedding index and run queries against the generated Embeddings index.\n",
|
||||
"\n",
|
||||
"This example covers functionality found in the [paperai](https://github.com/neuml/paperai) library. See that library for a full solution that can be used with the dataset discussed below."
|
||||
]
|
||||
@@ -34,20 +23,20 @@
|
||||
"source": [
|
||||
"# Install dependencies\n",
|
||||
"\n",
|
||||
"Install `txtai` and all dependencies. Since this notebook is building word vectors, we need to install the similarity extras package."
|
||||
"Install `txtai` and all dependencies."
|
||||
]
|
||||
},
|
||||
{
|
||||
"cell_type": "code",
|
||||
"execution_count": null,
|
||||
"metadata": {
|
||||
"id": "czPYSA2Q9ZHO"
|
||||
},
|
||||
"outputs": [],
|
||||
"source": [
|
||||
"%%capture\n",
|
||||
"!pip install git+https://github.com/neuml/txtai#egg=txtai[similarity]"
|
||||
],
|
||||
"execution_count": null,
|
||||
"outputs": []
|
||||
"!pip install git+https://github.com/neuml/txtai"
|
||||
]
|
||||
},
|
||||
{
|
||||
"cell_type": "markdown",
|
||||
@@ -64,93 +53,16 @@
|
||||
},
|
||||
{
|
||||
"cell_type": "code",
|
||||
"execution_count": null,
|
||||
"metadata": {
|
||||
"id": "TONQ4_Kv9dtd"
|
||||
},
|
||||
"outputs": [],
|
||||
"source": [
|
||||
"%%capture\n",
|
||||
"!wget https://github.com/neuml/txtai/releases/download/v1.1.0/tests.gz\n",
|
||||
"!gunzip tests.gz\n",
|
||||
"!mv tests articles.sqlite"
|
||||
],
|
||||
"execution_count": null,
|
||||
"outputs": []
|
||||
},
|
||||
{
|
||||
"cell_type": "markdown",
|
||||
"metadata": {
|
||||
"id": "bzdaJiZYBIHE"
|
||||
},
|
||||
"source": [
|
||||
"# Build Word Vectors\n",
|
||||
"\n",
|
||||
"This example will build a search system backed by word embeddings. Word embeddings provide a good tradeoff of performance to functionality for a similarity search system. With that being said, transformer models are making great progress in scaling performance down to smaller models and are the preferred vector backend for txtai in most cases.\n",
|
||||
"\n",
|
||||
"For this notebook, we'll build our own custom embeddings for demo purposes. A number of pre-trained word embedding models are available:\n",
|
||||
"\n",
|
||||
" - [General language models from pymagnitude](https://github.com/plasticityai/magnitude)\n",
|
||||
" - [CORD-19 fastText](https://www.kaggle.com/davidmezzetti/cord19-fasttext-vectors)"
|
||||
]
|
||||
},
|
||||
{
|
||||
"cell_type": "code",
|
||||
"metadata": {
|
||||
"id": "fJcn-CAH-u3K",
|
||||
"colab": {
|
||||
"base_uri": "https://localhost:8080/"
|
||||
},
|
||||
"outputId": "ab5a4340-13fc-4b47-b881-9388e2534ece"
|
||||
},
|
||||
"source": [
|
||||
"import os\n",
|
||||
"import sqlite3\n",
|
||||
"import tempfile\n",
|
||||
"\n",
|
||||
"from txtai.pipeline import Tokenizer\n",
|
||||
"from txtai.vectors import WordVectors\n",
|
||||
"\n",
|
||||
"print(\"Streaming tokens to temporary file\")\n",
|
||||
"\n",
|
||||
"# Stream tokens to temp working file\n",
|
||||
"with tempfile.NamedTemporaryFile(mode=\"w\", suffix=\".txt\", delete=False) as output:\n",
|
||||
" # Save file path\n",
|
||||
" tokens = output.name\n",
|
||||
"\n",
|
||||
" db = sqlite3.connect(\"articles.sqlite\")\n",
|
||||
" cur = db.cursor()\n",
|
||||
" cur.execute(\"SELECT Text from sections\")\n",
|
||||
"\n",
|
||||
" for row in cur:\n",
|
||||
" output.write(\" \".join(Tokenizer.tokenize(row[0])) + \"\\n\")\n",
|
||||
"\n",
|
||||
" # Free database resources\n",
|
||||
" db.close()\n",
|
||||
"\n",
|
||||
"# Build word vectors model - 300 dimensions, 3 min occurrences\n",
|
||||
"WordVectors.build(tokens, 300, 3, \"cord19-300d\")\n",
|
||||
"\n",
|
||||
"# Remove temporary tokens file\n",
|
||||
"os.remove(tokens)\n",
|
||||
"\n",
|
||||
"# Show files\n",
|
||||
"!ls -l"
|
||||
],
|
||||
"execution_count": null,
|
||||
"outputs": [
|
||||
{
|
||||
"output_type": "stream",
|
||||
"name": "stdout",
|
||||
"text": [
|
||||
"Streaming tokens to temporary file\n",
|
||||
"Building 300 dimension model\n",
|
||||
"Converting vectors to magnitude format\n",
|
||||
"total 78948\n",
|
||||
"-rw-r--r-- 1 root root 8065024 Dec 7 15:48 articles.sqlite\n",
|
||||
"-rw-r--r-- 1 root root 24145920 Dec 27 17:42 cord19-300d.magnitude\n",
|
||||
"-rw-r--r-- 1 root root 48625387 Dec 27 17:41 cord19-300d.txt\n",
|
||||
"drwxr-xr-x 1 root root 4096 Dec 3 14:33 sample_data\n"
|
||||
]
|
||||
}
|
||||
]
|
||||
},
|
||||
{
|
||||
@@ -161,25 +73,34 @@
|
||||
"source": [
|
||||
"# Build an embeddings index\n",
|
||||
"\n",
|
||||
"The following steps build an embeddings index using the word vector model just created. This model builds a BM25 + fastText index. BM25 is used to build a weighted average of the word embeddings for a section. More information on this method can be found in this [Medium article](https://towardsdatascience.com/building-a-sentence-embedding-index-with-fasttext-and-bm25-f07e7148d240?gi=79da927aa10)."
|
||||
"The following steps build an embeddings index using a vector model designed for medical papers, [PubMedBERT Embeddings](https://huggingface.co/NeuML/pubmedbert-base-embeddings)."
|
||||
]
|
||||
},
|
||||
{
|
||||
"cell_type": "code",
|
||||
"execution_count": 2,
|
||||
"metadata": {
|
||||
"id": "5PrrxGRPGHqX",
|
||||
"colab": {
|
||||
"base_uri": "https://localhost:8080/"
|
||||
},
|
||||
"id": "5PrrxGRPGHqX",
|
||||
"outputId": "61bf7211-6757-4147-8f2f-e4d1ebe58e11"
|
||||
},
|
||||
"outputs": [
|
||||
{
|
||||
"name": "stdout",
|
||||
"output_type": "stream",
|
||||
"text": [
|
||||
"Iterated over 21499 total rows\n"
|
||||
]
|
||||
}
|
||||
],
|
||||
"source": [
|
||||
"import sqlite3\n",
|
||||
"\n",
|
||||
"import regex as re\n",
|
||||
"\n",
|
||||
"from txtai.embeddings import Embeddings\n",
|
||||
"from txtai.pipeline import Tokenizer\n",
|
||||
"from txtai import Embeddings\n",
|
||||
"\n",
|
||||
"def stream():\n",
|
||||
" # Connection to database file\n",
|
||||
@@ -196,46 +117,24 @@
|
||||
"\n",
|
||||
" # Only process certain document sections\n",
|
||||
" if not name or not re.search(r\"background|(?<!.*?results.*?)discussion|introduction|reference\", name.lower()):\n",
|
||||
" # Tokenize text\n",
|
||||
" tokens = Tokenizer.tokenize(text)\n",
|
||||
"\n",
|
||||
" document = (uid, tokens, None)\n",
|
||||
" document = (uid, text, None)\n",
|
||||
"\n",
|
||||
" count += 1\n",
|
||||
" if count % 1000 == 0:\n",
|
||||
" print(\"Streamed %d documents\" % (count), end=\"\\r\")\n",
|
||||
"\n",
|
||||
" # Skip documents with no tokens parsed\n",
|
||||
" if tokens:\n",
|
||||
" yield document\n",
|
||||
" yield document\n",
|
||||
"\n",
|
||||
" print(\"Iterated over %d total rows\" % (count))\n",
|
||||
"\n",
|
||||
" # Free database resources\n",
|
||||
" db.close()\n",
|
||||
"\n",
|
||||
"# BM25 + fastText vectors\n",
|
||||
"embeddings = Embeddings({\"path\": \"cord19-300d.magnitude\",\n",
|
||||
" \"scoring\": \"bm25\",\n",
|
||||
" \"pca\": 3})\n",
|
||||
"\n",
|
||||
"# Build scoring index if scoring method provided\n",
|
||||
"if embeddings.config.get(\"scoring\"):\n",
|
||||
" embeddings.score(stream())\n",
|
||||
"# Create embeddings index \n",
|
||||
"embeddings = Embeddings(path=\"neuml/pubmedbert-base-embeddings\")\n",
|
||||
"\n",
|
||||
"# Build embeddings index\n",
|
||||
"embeddings.index(stream())\n"
|
||||
],
|
||||
"execution_count": null,
|
||||
"outputs": [
|
||||
{
|
||||
"output_type": "stream",
|
||||
"name": "stdout",
|
||||
"text": [
|
||||
"Iterated over 21499 total rows\n",
|
||||
"Iterated over 21499 total rows\n"
|
||||
]
|
||||
}
|
||||
]
|
||||
},
|
||||
{
|
||||
@@ -251,14 +150,70 @@
|
||||
},
|
||||
{
|
||||
"cell_type": "code",
|
||||
"execution_count": 7,
|
||||
"metadata": {
|
||||
"id": "CRbDhvvDKEl-",
|
||||
"colab": {
|
||||
"base_uri": "https://localhost:8080/",
|
||||
"height": 293
|
||||
},
|
||||
"id": "CRbDhvvDKEl-",
|
||||
"outputId": "774f8085-01db-49e2-f025-4fe68afca594"
|
||||
},
|
||||
"outputs": [
|
||||
{
|
||||
"data": {
|
||||
"text/html": [
|
||||
"<table border=\"1\" class=\"dataframe\">\n",
|
||||
" <thead>\n",
|
||||
" <tr style=\"text-align: right;\">\n",
|
||||
" <th>Title</th>\n",
|
||||
" <th>Published</th>\n",
|
||||
" <th>Reference</th>\n",
|
||||
" <th>Match</th>\n",
|
||||
" </tr>\n",
|
||||
" </thead>\n",
|
||||
" <tbody>\n",
|
||||
" <tr>\n",
|
||||
" <td>Management of osteoarthritis during COVID‐19 pandemic</td>\n",
|
||||
" <td>2020-05-21 00:00:00</td>\n",
|
||||
" <td>https://doi.org/10.1002/cpt.1910</td>\n",
|
||||
" <td>Indeed, risk factors are sex, obesity, genetic factors and mechanical factors (3) .</td>\n",
|
||||
" </tr>\n",
|
||||
" <tr>\n",
|
||||
" <td>Does apolipoprotein E genotype predict COVID-19 severity?</td>\n",
|
||||
" <td>2020-04-27 00:00:00</td>\n",
|
||||
" <td>https://doi.org/10.1093/qjmed/hcaa142</td>\n",
|
||||
" <td>Risk factors associated with subsequent death include older age, hypertension, diabetes, ischemic heart disease, obesity and chronic lung disease; however, sometimes there are no obvious risk factors .</td>\n",
|
||||
" </tr>\n",
|
||||
" <tr>\n",
|
||||
" <td>Prevalence and Impact of Myocardial Injury in Patients Hospitalized with COVID-19 Infection</td>\n",
|
||||
" <td>2020-04-24 00:00:00</td>\n",
|
||||
" <td>http://medrxiv.org/cgi/content/short/2020.04.20.20072702v1?rss=1</td>\n",
|
||||
" <td>This risk was consistent across patients stratified by history of CVD, risk factors but no CVD, and neither CVD nor risk factors.</td>\n",
|
||||
" </tr>\n",
|
||||
" <tr>\n",
|
||||
" <td>COVID-19 and associations with frailty and multimorbidity: a prospective analysis of UK Biobank participants</td>\n",
|
||||
" <td>2020-07-23 00:00:00</td>\n",
|
||||
" <td>https://www.ncbi.nlm.nih.gov/pubmed/32705587/</td>\n",
|
||||
" <td>BACKGROUND: Frailty and multimorbidity have been suggested as risk factors for severe COVID-19 disease.</td>\n",
|
||||
" </tr>\n",
|
||||
" <tr>\n",
|
||||
" <td>Risk Stratification for Healthcare workers during the CoViD-19 Pandemic; using demographics, co-morbid disease and clinical domain in order to assign clinical duties</td>\n",
|
||||
" <td>2020-05-09 00:00:00</td>\n",
|
||||
" <td>http://medrxiv.org/cgi/content/short/2020.05.05.20091967v1?rss=1</td>\n",
|
||||
" <td>Vascular disease, diabetes and chronic pulmonary disease further increased risk.</td>\n",
|
||||
" </tr>\n",
|
||||
" </tbody>\n",
|
||||
"</table>"
|
||||
],
|
||||
"text/plain": [
|
||||
"<IPython.core.display.HTML object>"
|
||||
]
|
||||
},
|
||||
"metadata": {},
|
||||
"output_type": "display_data"
|
||||
}
|
||||
],
|
||||
"source": [
|
||||
"import pandas as pd\n",
|
||||
"\n",
|
||||
@@ -291,62 +246,6 @@
|
||||
"# file.write(htmlData)\n",
|
||||
"\n",
|
||||
"display(HTML(df.to_html(index=False)))"
|
||||
],
|
||||
"execution_count": null,
|
||||
"outputs": [
|
||||
{
|
||||
"output_type": "display_data",
|
||||
"data": {
|
||||
"text/html": [
|
||||
"<table border=\"1\" class=\"dataframe\">\n",
|
||||
" <thead>\n",
|
||||
" <tr style=\"text-align: right;\">\n",
|
||||
" <th>Title</th>\n",
|
||||
" <th>Published</th>\n",
|
||||
" <th>Reference</th>\n",
|
||||
" <th>Match</th>\n",
|
||||
" </tr>\n",
|
||||
" </thead>\n",
|
||||
" <tbody>\n",
|
||||
" <tr>\n",
|
||||
" <td>Management of osteoarthritis during COVID‐19 pandemic</td>\n",
|
||||
" <td>2020-05-21 00:00:00</td>\n",
|
||||
" <td>https://doi.org/10.1002/cpt.1910</td>\n",
|
||||
" <td>Indeed, risk factors are sex, obesity, genetic factors and mechanical factors (3) .</td>\n",
|
||||
" </tr>\n",
|
||||
" <tr>\n",
|
||||
" <td>Work-related and Personal Factors Associated with Mental Well-being during COVID-19 Response: A Survey of Health Care and Other Workers</td>\n",
|
||||
" <td>2020-06-11 00:00:00</td>\n",
|
||||
" <td>http://medrxiv.org/cgi/content/short/2020.06.09.20126722v1?rss=1</td>\n",
|
||||
" <td>Poor family supportive behaviors by supervisors were also associated with these outcomes [1.40 (1.21 - 1.62), 1.69 (1.48 - 1.92), 1.54 (1.44 - 1.64)].</td>\n",
|
||||
" </tr>\n",
|
||||
" <tr>\n",
|
||||
" <td>No evidence that androgen regulation of pulmonary TMPRSS2 explains sex-discordant COVID-19 outcomes</td>\n",
|
||||
" <td>2020-04-21 00:00:00</td>\n",
|
||||
" <td>https://doi.org/10.1101/2020.04.21.051201</td>\n",
|
||||
" <td>In addition to male sex, smoking is a risk factor for COVID-19 susceptibility and poor clinical outcomes .</td>\n",
|
||||
" </tr>\n",
|
||||
" <tr>\n",
|
||||
" <td>Current status of potential therapeutic candidates for the COVID-19 crisis</td>\n",
|
||||
" <td>2020-04-22 00:00:00</td>\n",
|
||||
" <td>https://doi.org/10.1016/j.bbi.2020.04.046</td>\n",
|
||||
" <td>There was no difference on 28-day mortality between heparin users and nonusers.</td>\n",
|
||||
" </tr>\n",
|
||||
" <tr>\n",
|
||||
" <td>COVID-19: what has been learned and to be learned about the novel coronavirus disease</td>\n",
|
||||
" <td>2020-03-15 00:00:00</td>\n",
|
||||
" <td>https://doi.org/10.7150/ijbs.45134</td>\n",
|
||||
" <td>• Three major risk factors for COVID-19 were sex (male), age (≥60), and severe pneumonia.</td>\n",
|
||||
" </tr>\n",
|
||||
" </tbody>\n",
|
||||
"</table>"
|
||||
],
|
||||
"text/plain": [
|
||||
"<IPython.core.display.HTML object>"
|
||||
]
|
||||
},
|
||||
"metadata": {}
|
||||
}
|
||||
]
|
||||
},
|
||||
{
|
||||
@@ -362,29 +261,98 @@
|
||||
},
|
||||
{
|
||||
"cell_type": "code",
|
||||
"execution_count": null,
|
||||
"metadata": {
|
||||
"id": "TLVOTQJchvTi"
|
||||
},
|
||||
"outputs": [],
|
||||
"source": [
|
||||
"%%capture\n",
|
||||
"from txtai.pipeline import Extractor\n",
|
||||
"\n",
|
||||
"# Create extractor instance using qa model designed for the CORD-19 dataset\n",
|
||||
"# Note: That extractive QA was a predecessor to Large Language Models (LLMs). LLMs likely will get better results.\n",
|
||||
"extractor = Extractor(embeddings, \"NeuML/bert-small-cord19qa\")"
|
||||
],
|
||||
"execution_count": null,
|
||||
"outputs": []
|
||||
]
|
||||
},
|
||||
{
|
||||
"cell_type": "code",
|
||||
"execution_count": 9,
|
||||
"metadata": {
|
||||
"id": "19fmKawThs6d",
|
||||
"colab": {
|
||||
"base_uri": "https://localhost:8080/",
|
||||
"height": 293
|
||||
},
|
||||
"id": "19fmKawThs6d",
|
||||
"outputId": "b7cd40e3-a87c-419d-f520-b7795607cebc"
|
||||
},
|
||||
"outputs": [
|
||||
{
|
||||
"data": {
|
||||
"text/html": [
|
||||
"<table border=\"1\" class=\"dataframe\">\n",
|
||||
" <thead>\n",
|
||||
" <tr style=\"text-align: right;\">\n",
|
||||
" <th>Title</th>\n",
|
||||
" <th>Published</th>\n",
|
||||
" <th>Reference</th>\n",
|
||||
" <th>Match</th>\n",
|
||||
" <th>Risk Factors</th>\n",
|
||||
" <th>Locations</th>\n",
|
||||
" </tr>\n",
|
||||
" </thead>\n",
|
||||
" <tbody>\n",
|
||||
" <tr>\n",
|
||||
" <td>Management of osteoarthritis during COVID‐19 pandemic</td>\n",
|
||||
" <td>2020-05-21 00:00:00</td>\n",
|
||||
" <td>https://doi.org/10.1002/cpt.1910</td>\n",
|
||||
" <td>Indeed, risk factors are sex, obesity, genetic factors and mechanical factors (3) .</td>\n",
|
||||
" <td>sex, obesity, genetic factors and mechanical factors</td>\n",
|
||||
" <td>hospitals and clinics</td>\n",
|
||||
" </tr>\n",
|
||||
" <tr>\n",
|
||||
" <td>Does apolipoprotein E genotype predict COVID-19 severity?</td>\n",
|
||||
" <td>2020-04-27 00:00:00</td>\n",
|
||||
" <td>https://doi.org/10.1093/qjmed/hcaa142</td>\n",
|
||||
" <td>Risk factors associated with subsequent death include older age, hypertension, diabetes, ischemic heart disease, obesity and chronic lung disease; however, sometimes there are no obvious risk factors .</td>\n",
|
||||
" <td>None</td>\n",
|
||||
" <td>None</td>\n",
|
||||
" </tr>\n",
|
||||
" <tr>\n",
|
||||
" <td>Prevalence and Impact of Myocardial Injury in Patients Hospitalized with COVID-19 Infection</td>\n",
|
||||
" <td>2020-04-24 00:00:00</td>\n",
|
||||
" <td>http://medrxiv.org/cgi/content/short/2020.04.20.20072702v1?rss=1</td>\n",
|
||||
" <td>This risk was consistent across patients stratified by history of CVD, risk factors but no CVD, and neither CVD nor risk factors.</td>\n",
|
||||
" <td>neither CVD nor risk factors</td>\n",
|
||||
" <td>Mount Sinai Health System</td>\n",
|
||||
" </tr>\n",
|
||||
" <tr>\n",
|
||||
" <td>COVID-19 and associations with frailty and multimorbidity: a prospective analysis of UK Biobank participants</td>\n",
|
||||
" <td>2020-07-23 00:00:00</td>\n",
|
||||
" <td>https://www.ncbi.nlm.nih.gov/pubmed/32705587/</td>\n",
|
||||
" <td>BACKGROUND: Frailty and multimorbidity have been suggested as risk factors for severe COVID-19 disease.</td>\n",
|
||||
" <td>Frailty and multimorbidity</td>\n",
|
||||
" <td>213 countries and territories</td>\n",
|
||||
" </tr>\n",
|
||||
" <tr>\n",
|
||||
" <td>Risk Stratification for Healthcare workers during the CoViD-19 Pandemic; using demographics, co-morbid disease and clinical domain in order to assign clinical duties</td>\n",
|
||||
" <td>2020-05-09 00:00:00</td>\n",
|
||||
" <td>http://medrxiv.org/cgi/content/short/2020.05.05.20091967v1?rss=1</td>\n",
|
||||
" <td>Vascular disease, diabetes and chronic pulmonary disease further increased risk.</td>\n",
|
||||
" <td>Vascular disease, diabetes and chronic pulmonary disease</td>\n",
|
||||
" <td>None</td>\n",
|
||||
" </tr>\n",
|
||||
" </tbody>\n",
|
||||
"</table>"
|
||||
],
|
||||
"text/plain": [
|
||||
"<IPython.core.display.HTML object>"
|
||||
]
|
||||
},
|
||||
"metadata": {},
|
||||
"output_type": "display_data"
|
||||
}
|
||||
],
|
||||
"source": [
|
||||
"db = sqlite3.connect(\"articles.sqlite\")\n",
|
||||
"cur = db.cursor()\n",
|
||||
@@ -415,74 +383,6 @@
|
||||
"\n",
|
||||
"df = pd.DataFrame(results, columns=[\"Title\", \"Published\", \"Reference\", \"Match\", \"Risk Factors\", \"Locations\"])\n",
|
||||
"display(HTML(df.to_html(index=False)))"
|
||||
],
|
||||
"execution_count": null,
|
||||
"outputs": [
|
||||
{
|
||||
"output_type": "display_data",
|
||||
"data": {
|
||||
"text/html": [
|
||||
"<table border=\"1\" class=\"dataframe\">\n",
|
||||
" <thead>\n",
|
||||
" <tr style=\"text-align: right;\">\n",
|
||||
" <th>Title</th>\n",
|
||||
" <th>Published</th>\n",
|
||||
" <th>Reference</th>\n",
|
||||
" <th>Match</th>\n",
|
||||
" <th>Risk Factors</th>\n",
|
||||
" <th>Locations</th>\n",
|
||||
" </tr>\n",
|
||||
" </thead>\n",
|
||||
" <tbody>\n",
|
||||
" <tr>\n",
|
||||
" <td>Management of osteoarthritis during COVID‐19 pandemic</td>\n",
|
||||
" <td>2020-05-21 00:00:00</td>\n",
|
||||
" <td>https://doi.org/10.1002/cpt.1910</td>\n",
|
||||
" <td>Indeed, risk factors are sex, obesity, genetic factors and mechanical factors (3) .</td>\n",
|
||||
" <td>sex, obesity, genetic factors and mechanical factors</td>\n",
|
||||
" <td>None</td>\n",
|
||||
" </tr>\n",
|
||||
" <tr>\n",
|
||||
" <td>Work-related and Personal Factors Associated with Mental Well-being during COVID-19 Response: A Survey of Health Care and Other Workers</td>\n",
|
||||
" <td>2020-06-11 00:00:00</td>\n",
|
||||
" <td>http://medrxiv.org/cgi/content/short/2020.06.09.20126722v1?rss=1</td>\n",
|
||||
" <td>Poor family supportive behaviors by supervisors were also associated with these outcomes [1.40 (1.21 - 1.62), 1.69 (1.48 - 1.92), 1.54 (1.44 - 1.64)].</td>\n",
|
||||
" <td>Poor family supportive behaviors</td>\n",
|
||||
" <td>None</td>\n",
|
||||
" </tr>\n",
|
||||
" <tr>\n",
|
||||
" <td>No evidence that androgen regulation of pulmonary TMPRSS2 explains sex-discordant COVID-19 outcomes</td>\n",
|
||||
" <td>2020-04-21 00:00:00</td>\n",
|
||||
" <td>https://doi.org/10.1101/2020.04.21.051201</td>\n",
|
||||
" <td>In addition to male sex, smoking is a risk factor for COVID-19 susceptibility and poor clinical outcomes .</td>\n",
|
||||
" <td>Higher morbidity and mortality</td>\n",
|
||||
" <td>None</td>\n",
|
||||
" </tr>\n",
|
||||
" <tr>\n",
|
||||
" <td>Current status of potential therapeutic candidates for the COVID-19 crisis</td>\n",
|
||||
" <td>2020-04-22 00:00:00</td>\n",
|
||||
" <td>https://doi.org/10.1016/j.bbi.2020.04.046</td>\n",
|
||||
" <td>There was no difference on 28-day mortality between heparin users and nonusers.</td>\n",
|
||||
" <td>elicited strong inflammatory responses are favorable or detrimental</td>\n",
|
||||
" <td>None</td>\n",
|
||||
" </tr>\n",
|
||||
" <tr>\n",
|
||||
" <td>COVID-19: what has been learned and to be learned about the novel coronavirus disease</td>\n",
|
||||
" <td>2020-03-15 00:00:00</td>\n",
|
||||
" <td>https://doi.org/10.7150/ijbs.45134</td>\n",
|
||||
" <td>• Three major risk factors for COVID-19 were sex (male), age (≥60), and severe pneumonia.</td>\n",
|
||||
" <td>sex (male), age (≥60), and severe pneumonia</td>\n",
|
||||
" <td>None</td>\n",
|
||||
" </tr>\n",
|
||||
" </tbody>\n",
|
||||
"</table>"
|
||||
],
|
||||
"text/plain": [
|
||||
"<IPython.core.display.HTML object>"
|
||||
]
|
||||
},
|
||||
"metadata": {}
|
||||
}
|
||||
]
|
||||
},
|
||||
{
|
||||
@@ -494,5 +394,29 @@
|
||||
"In the example above, the Embeddings index is used to find the top N results for a given query. On top of that, a question-answer extractor is used to derive additional columns based on a list of questions. In this case, the \"Risk Factors\" and \"Location\" columns were pulled from the document text."
|
||||
]
|
||||
}
|
||||
]
|
||||
}
|
||||
],
|
||||
"metadata": {
|
||||
"colab": {
|
||||
"provenance": []
|
||||
},
|
||||
"kernelspec": {
|
||||
"display_name": "local",
|
||||
"language": "python",
|
||||
"name": "python3"
|
||||
},
|
||||
"language_info": {
|
||||
"codemirror_mode": {
|
||||
"name": "ipython",
|
||||
"version": 3
|
||||
},
|
||||
"file_extension": ".py",
|
||||
"mimetype": "text/x-python",
|
||||
"name": "python",
|
||||
"nbconvert_exporter": "python",
|
||||
"pygments_lexer": "ipython3",
|
||||
"version": "3.9.21"
|
||||
}
|
||||
},
|
||||
"nbformat": 4,
|
||||
"nbformat_minor": 0
|
||||
}
|
||||
|
||||
@@ -429,7 +429,7 @@
|
||||
"source": [
|
||||
"# External vector models\n",
|
||||
"\n",
|
||||
"txtai supports generating vectors with [Hugging Face Transformers](https://github.com/huggingface/transformers), [PyTorch](https://github.com/pytorch/pytorch), [ONNX](https://github.com/microsoft/onnxruntime) and [Word Vector](https://github.com/neuml/magnitude) models.\n",
|
||||
"txtai supports generating vectors with [Hugging Face Transformers](https://github.com/huggingface/transformers), [PyTorch](https://github.com/pytorch/pytorch), [ONNX](https://github.com/microsoft/onnxruntime) and [Word Vector](https://github.com/neuml/staticvectors) models.\n",
|
||||
"\n",
|
||||
"This release adds support for pre-computed vectors using external models. External models may be an API, custom library and/or another way to vectorize data. This adds flexibility given the high computation cost in building embeddings vectors. Embeddings generation could be outsourced or consolidated to a group of servers with GPUs, leaving index servers to run on lower resourced machines. \n",
|
||||
"\n",
|
||||
|
||||
+197
-198
@@ -1,28 +1,4 @@
|
||||
{
|
||||
"nbformat": 4,
|
||||
"nbformat_minor": 0,
|
||||
"metadata": {
|
||||
"kernelspec": {
|
||||
"name": "python3",
|
||||
"display_name": "Python 3",
|
||||
"language": "python"
|
||||
},
|
||||
"language_info": {
|
||||
"name": "python",
|
||||
"version": "3.7.6",
|
||||
"mimetype": "text/x-python",
|
||||
"codemirror_mode": {
|
||||
"name": "ipython",
|
||||
"version": 3
|
||||
},
|
||||
"pygments_lexer": "ipython3",
|
||||
"nbconvert_exporter": "python",
|
||||
"file_extension": ".py"
|
||||
},
|
||||
"colab": {
|
||||
"provenance": []
|
||||
}
|
||||
},
|
||||
"cells": [
|
||||
{
|
||||
"cell_type": "markdown",
|
||||
@@ -61,44 +37,59 @@
|
||||
},
|
||||
{
|
||||
"cell_type": "code",
|
||||
"execution_count": null,
|
||||
"metadata": {
|
||||
"_uuid": "8f2839f25d086af736a60e9eeb907d3b93b6e0e5",
|
||||
"_cell_guid": "b1076dfc-b9ad-4769-8c92-a6c4dae69d19",
|
||||
"trusted": true,
|
||||
"_kg_hide-output": true,
|
||||
"id": "24q-1n5i6XzQ"
|
||||
"_uuid": "8f2839f25d086af736a60e9eeb907d3b93b6e0e5",
|
||||
"id": "24q-1n5i6XzQ",
|
||||
"trusted": true
|
||||
},
|
||||
"outputs": [],
|
||||
"source": [
|
||||
"%%capture\n",
|
||||
"!pip install git+https://github.com/neuml/txtai#egg=txtai[pipeline]"
|
||||
],
|
||||
"execution_count": null,
|
||||
"outputs": []
|
||||
]
|
||||
},
|
||||
{
|
||||
"cell_type": "markdown",
|
||||
"metadata": {
|
||||
"id": "0p3WCDniUths"
|
||||
},
|
||||
"source": [
|
||||
"# Create index\n",
|
||||
"Let's first recap how to create an index. We'll use the classic txtai example.\n"
|
||||
],
|
||||
"metadata": {
|
||||
"id": "0p3WCDniUths"
|
||||
}
|
||||
]
|
||||
},
|
||||
{
|
||||
"cell_type": "code",
|
||||
"execution_count": 1,
|
||||
"metadata": {
|
||||
"_uuid": "d629ff2d2480ee46fbb7e2d37f6b5fab8052498a",
|
||||
"_cell_guid": "79c7e3d0-c299-4dcb-8224-4455121ee9b0",
|
||||
"trusted": true,
|
||||
"id": "2j_CFGDR6Xzp",
|
||||
"_uuid": "d629ff2d2480ee46fbb7e2d37f6b5fab8052498a",
|
||||
"colab": {
|
||||
"base_uri": "https://localhost:8080/"
|
||||
},
|
||||
"outputId": "e65238c5-d67f-4fe4-9cbf-c88b0ff3a8bb"
|
||||
"id": "2j_CFGDR6Xzp",
|
||||
"outputId": "e65238c5-d67f-4fe4-9cbf-c88b0ff3a8bb",
|
||||
"trusted": true
|
||||
},
|
||||
"outputs": [
|
||||
{
|
||||
"data": {
|
||||
"text/plain": [
|
||||
"[{'id': '4',\n",
|
||||
" 'text': 'Maine man wins $1M from $25 lottery ticket',\n",
|
||||
" 'score': 0.08329025655984879}]"
|
||||
]
|
||||
},
|
||||
"execution_count": 1,
|
||||
"metadata": {},
|
||||
"output_type": "execute_result"
|
||||
}
|
||||
],
|
||||
"source": [
|
||||
"from txtai.embeddings import Embeddings\n",
|
||||
"from txtai import Embeddings\n",
|
||||
"\n",
|
||||
"data = [\"US tops 5 million confirmed virus cases\",\n",
|
||||
" \"Canada's last fully intact ice shelf has suddenly collapsed, forming a Manhattan-sized iceberg\",\n",
|
||||
@@ -108,65 +99,29 @@
|
||||
" \"Make huge profits without work, earn up to $100,000 a day\"]\n",
|
||||
"\n",
|
||||
"# Create embeddings index with content enabled. The default behavior is to only store indexed vectors.\n",
|
||||
"embeddings = Embeddings({\"path\": \"sentence-transformers/nli-mpnet-base-v2\", \"content\": True})\n",
|
||||
"embeddings = Embeddings(path=\"sentence-transformers/nli-mpnet-base-v2\", content=True)\n",
|
||||
"\n",
|
||||
"# Create an index for the list of text\n",
|
||||
"embeddings.index([(uid, text, None) for uid, text in enumerate(data)])\n",
|
||||
"embeddings.index(data)\n",
|
||||
"\n",
|
||||
"# Run a search\n",
|
||||
"embeddings.search(\"feel good story\", 1)"
|
||||
],
|
||||
"execution_count": null,
|
||||
"outputs": [
|
||||
{
|
||||
"output_type": "execute_result",
|
||||
"data": {
|
||||
"text/plain": [
|
||||
"[{'id': '4',\n",
|
||||
" 'score': 0.08329011499881744,\n",
|
||||
" 'text': 'Maine man wins $1M from $25 lottery ticket'}]"
|
||||
]
|
||||
},
|
||||
"metadata": {},
|
||||
"execution_count": 30
|
||||
}
|
||||
]
|
||||
},
|
||||
{
|
||||
"cell_type": "markdown",
|
||||
"metadata": {
|
||||
"id": "QTee7YMNDD4R"
|
||||
},
|
||||
"source": [
|
||||
"# Query translation models\n",
|
||||
"\n",
|
||||
"Next we'll explore how query translation models work with examples. "
|
||||
],
|
||||
"metadata": {
|
||||
"id": "QTee7YMNDD4R"
|
||||
}
|
||||
]
|
||||
},
|
||||
{
|
||||
"cell_type": "code",
|
||||
"source": [
|
||||
"from txtai.pipeline import Sequences\n",
|
||||
"\n",
|
||||
"sequences = Sequences(\"NeuML/t5-small-txtsql\")\n",
|
||||
"\n",
|
||||
"queries = [\n",
|
||||
" \"feel good story\",\n",
|
||||
" \"feel good story since yesterday\",\n",
|
||||
" \"feel good story with lottery in text\",\n",
|
||||
" \"how many feel good story\",\n",
|
||||
" \"feel good story translated to fr\",\n",
|
||||
" \"feel good story summarized\"\n",
|
||||
"]\n",
|
||||
"\n",
|
||||
"# Prefix to pass to T5 model\n",
|
||||
"prefix = \"translate English to SQL: \"\n",
|
||||
"\n",
|
||||
"for query in queries:\n",
|
||||
" print(f\"Input: {query}\")\n",
|
||||
" print(f\"SQL: {sequences(query, prefix)}\")\n",
|
||||
" print()\n"
|
||||
],
|
||||
"execution_count": 2,
|
||||
"metadata": {
|
||||
"colab": {
|
||||
"base_uri": "https://localhost:8080/"
|
||||
@@ -174,11 +129,10 @@
|
||||
"id": "04iOgP_ojSfK",
|
||||
"outputId": "41e73130-75e6-4ae9-b690-685972a13565"
|
||||
},
|
||||
"execution_count": null,
|
||||
"outputs": [
|
||||
{
|
||||
"output_type": "stream",
|
||||
"name": "stdout",
|
||||
"output_type": "stream",
|
||||
"text": [
|
||||
"Input: feel good story\n",
|
||||
"SQL: select id, text, score from txtai where similar('feel good story')\n",
|
||||
@@ -186,8 +140,8 @@
|
||||
"Input: feel good story since yesterday\n",
|
||||
"SQL: select id, text, score from txtai where similar('feel good story') and entry >= date('now', '-1 day')\n",
|
||||
"\n",
|
||||
"Input: feel good story with lottery in text\n",
|
||||
"SQL: select id, text, score from txtai where similar('feel good story') and text like '% lottery%'\n",
|
||||
"Input: feel good story with 'lottery' in text\n",
|
||||
"SQL: select id, text, score from txtai where similar('feel good story') and text like '%lottery%'\n",
|
||||
"\n",
|
||||
"Input: how many feel good story\n",
|
||||
"SQL: select count(*) from txtai where similar('feel good story')\n",
|
||||
@@ -200,32 +154,73 @@
|
||||
"\n"
|
||||
]
|
||||
}
|
||||
],
|
||||
"source": [
|
||||
"from txtai import LLM\n",
|
||||
"\n",
|
||||
"llm = LLM(\"NeuML/t5-small-txtsql\", template=\"translate English to SQL: {text}\")\n",
|
||||
"\n",
|
||||
"queries = [\n",
|
||||
" \"feel good story\",\n",
|
||||
" \"feel good story since yesterday\",\n",
|
||||
" \"feel good story with 'lottery' in text\",\n",
|
||||
" \"how many feel good story\",\n",
|
||||
" \"feel good story translated to fr\",\n",
|
||||
" \"feel good story summarized\"\n",
|
||||
"]\n",
|
||||
"\n",
|
||||
"for query in queries:\n",
|
||||
" print(f\"Input: {query}\")\n",
|
||||
" print(f\"SQL: {llm(query)}\")\n",
|
||||
" print()\n"
|
||||
]
|
||||
},
|
||||
{
|
||||
"cell_type": "markdown",
|
||||
"metadata": {
|
||||
"id": "rAnEMaiWlOXm"
|
||||
},
|
||||
"source": [
|
||||
"Looking at the query translations above gives an idea on how this model works.\n",
|
||||
"\n",
|
||||
"[t5-small-txtsql](https://huggingface.co/NeuML/t5-small-txtsql) is the default model. Custom domain query syntax languages can be created using this same methodology, including for other languages. Natural language can be translated to functions, query clauses, column selection and more!"
|
||||
],
|
||||
"metadata": {
|
||||
"id": "rAnEMaiWlOXm"
|
||||
}
|
||||
]
|
||||
},
|
||||
{
|
||||
"cell_type": "markdown",
|
||||
"metadata": {
|
||||
"id": "P9hOcgNfjSyL"
|
||||
},
|
||||
"source": [
|
||||
"# Natural language filtering\n",
|
||||
"\n",
|
||||
"Now it's time for this in action! Let's first initialize the embeddings index with the appropriate settings."
|
||||
],
|
||||
"metadata": {
|
||||
"id": "P9hOcgNfjSyL"
|
||||
}
|
||||
]
|
||||
},
|
||||
{
|
||||
"cell_type": "code",
|
||||
"execution_count": 2,
|
||||
"metadata": {
|
||||
"colab": {
|
||||
"base_uri": "https://localhost:8080/"
|
||||
},
|
||||
"id": "L2DDJrd0RAaN",
|
||||
"outputId": "c60bfc29-187b-4926-8656-04063b2ca85c"
|
||||
},
|
||||
"outputs": [
|
||||
{
|
||||
"data": {
|
||||
"text/plain": [
|
||||
"{'id': '4',\n",
|
||||
" 'score': 0.08329025655984879,\n",
|
||||
" 'text': 'Maine Mann gewinnt $1M von $25 Lotterie-Ticket'}"
|
||||
]
|
||||
},
|
||||
"execution_count": 2,
|
||||
"metadata": {},
|
||||
"output_type": "execute_result"
|
||||
}
|
||||
],
|
||||
"source": [
|
||||
"from txtai.pipeline import Translation\n",
|
||||
"\n",
|
||||
@@ -235,56 +230,34 @@
|
||||
"translation = Translation()\n",
|
||||
"\n",
|
||||
"# Create embeddings index with content enabled. The default behavior is to only store indexed vectors.\n",
|
||||
"embeddings = Embeddings({\"path\": \"sentence-transformers/nli-mpnet-base-v2\",\n",
|
||||
" \"content\": True,\n",
|
||||
" \"query\": {\"path\": \"NeuML/t5-small-txtsql\"},\n",
|
||||
" \"functions\": [translate]})\n",
|
||||
"embeddings = Embeddings(\n",
|
||||
" path=\"sentence-transformers/nli-mpnet-base-v2\",\n",
|
||||
" content=True,\n",
|
||||
" query={\"path\": \"NeuML/t5-small-txtsql\"},\n",
|
||||
" functions=[translate]\n",
|
||||
")\n",
|
||||
"\n",
|
||||
"# Create an index for the list of text\n",
|
||||
"embeddings.index([(uid, text, None) for uid, text in enumerate(data)])\n",
|
||||
"embeddings.index(data)\n",
|
||||
"\n",
|
||||
"query = \"select id, score, translate(text, 'de') 'text' from txtai where similar('feel good story')\"\n",
|
||||
"\n",
|
||||
"# Run a search using a custom SQL function\n",
|
||||
"embeddings.search(query)[0]"
|
||||
],
|
||||
"metadata": {
|
||||
"colab": {
|
||||
"base_uri": "https://localhost:8080/"
|
||||
},
|
||||
"id": "L2DDJrd0RAaN",
|
||||
"outputId": "c60bfc29-187b-4926-8656-04063b2ca85c"
|
||||
},
|
||||
"execution_count": null,
|
||||
"outputs": [
|
||||
{
|
||||
"output_type": "execute_result",
|
||||
"data": {
|
||||
"text/plain": [
|
||||
"{'id': '4',\n",
|
||||
" 'score': 0.08329011499881744,\n",
|
||||
" 'text': 'Maine Mann gewinnt $1M von $25 Lotterie-Ticket'}"
|
||||
]
|
||||
},
|
||||
"metadata": {},
|
||||
"execution_count": 32
|
||||
}
|
||||
]
|
||||
},
|
||||
{
|
||||
"cell_type": "markdown",
|
||||
"source": [
|
||||
"Note how the query model was provided as a embeddings index configuration parameter. Custom SQL functions were also added in. Let's now see if the same SQL statement can be run with a natural language query."
|
||||
],
|
||||
"metadata": {
|
||||
"id": "MNd7QmFmnh-f"
|
||||
}
|
||||
},
|
||||
"source": [
|
||||
"Note how the query model was provided as a embeddings index configuration parameter. Custom SQL functions were also added in. Let's now see if the same SQL statement can be run with a natural language query."
|
||||
]
|
||||
},
|
||||
{
|
||||
"cell_type": "code",
|
||||
"source": [
|
||||
"embeddings.search(\"feel good story translated to de\")[0]"
|
||||
],
|
||||
"execution_count": 4,
|
||||
"metadata": {
|
||||
"colab": {
|
||||
"base_uri": "https://localhost:8080/"
|
||||
@@ -292,36 +265,36 @@
|
||||
"id": "mnGSBNMonur2",
|
||||
"outputId": "dc14d898-b46f-42e6-88e0-434863cc15d6"
|
||||
},
|
||||
"execution_count": null,
|
||||
"outputs": [
|
||||
{
|
||||
"output_type": "execute_result",
|
||||
"data": {
|
||||
"text/plain": [
|
||||
"{'id': '4',\n",
|
||||
" 'score': 0.08329011499881744,\n",
|
||||
" 'text': 'Maine Mann gewinnt $1M von $25 Lotterie-Ticket'}"
|
||||
" 'text': 'Maine Mann gewinnt $1M von $25 Lotterie-Ticket',\n",
|
||||
" 'score': 0.08329025655984879}"
|
||||
]
|
||||
},
|
||||
"execution_count": 4,
|
||||
"metadata": {},
|
||||
"execution_count": 33
|
||||
"output_type": "execute_result"
|
||||
}
|
||||
],
|
||||
"source": [
|
||||
"embeddings.search(\"feel good story translated to de\")[0]"
|
||||
]
|
||||
},
|
||||
{
|
||||
"cell_type": "markdown",
|
||||
"source": [
|
||||
"Same result. Let's try a few more."
|
||||
],
|
||||
"metadata": {
|
||||
"id": "OnmVUK2DoZkh"
|
||||
}
|
||||
},
|
||||
"source": [
|
||||
"Same result. Let's try a few more."
|
||||
]
|
||||
},
|
||||
{
|
||||
"cell_type": "code",
|
||||
"source": [
|
||||
"embeddings.search(\"feel good story since yesterday\")[0]"
|
||||
],
|
||||
"execution_count": 5,
|
||||
"metadata": {
|
||||
"colab": {
|
||||
"base_uri": "https://localhost:8080/"
|
||||
@@ -329,27 +302,27 @@
|
||||
"id": "Js2b_M61oitg",
|
||||
"outputId": "fab080cb-d082-4cf3-8314-12d23acc3c02"
|
||||
},
|
||||
"execution_count": null,
|
||||
"outputs": [
|
||||
{
|
||||
"output_type": "execute_result",
|
||||
"data": {
|
||||
"text/plain": [
|
||||
"{'id': '4',\n",
|
||||
" 'score': 0.08329011499881744,\n",
|
||||
" 'text': 'Maine man wins $1M from $25 lottery ticket'}"
|
||||
" 'text': 'Maine man wins $1M from $25 lottery ticket',\n",
|
||||
" 'score': 0.08329025655984879}"
|
||||
]
|
||||
},
|
||||
"execution_count": 5,
|
||||
"metadata": {},
|
||||
"execution_count": 34
|
||||
"output_type": "execute_result"
|
||||
}
|
||||
],
|
||||
"source": [
|
||||
"embeddings.search(\"feel good story since yesterday\")[0]"
|
||||
]
|
||||
},
|
||||
{
|
||||
"cell_type": "code",
|
||||
"source": [
|
||||
"embeddings.search(\"feel good story with lottery in text\")[0]"
|
||||
],
|
||||
"execution_count": 6,
|
||||
"metadata": {
|
||||
"colab": {
|
||||
"base_uri": "https://localhost:8080/"
|
||||
@@ -357,36 +330,36 @@
|
||||
"id": "pcxPgriwomWv",
|
||||
"outputId": "7e71dd09-7c4f-4147-ba9e-47a45c1cf90f"
|
||||
},
|
||||
"execution_count": null,
|
||||
"outputs": [
|
||||
{
|
||||
"output_type": "execute_result",
|
||||
"data": {
|
||||
"text/plain": [
|
||||
"{'id': '4',\n",
|
||||
" 'score': 0.08329011499881744,\n",
|
||||
" 'text': 'Maine man wins $1M from $25 lottery ticket'}"
|
||||
"[{'id': '4',\n",
|
||||
" 'text': 'Maine man wins $1M from $25 lottery ticket',\n",
|
||||
" 'score': 0.08329025655984879}]"
|
||||
]
|
||||
},
|
||||
"execution_count": 6,
|
||||
"metadata": {},
|
||||
"execution_count": 35
|
||||
"output_type": "execute_result"
|
||||
}
|
||||
],
|
||||
"source": [
|
||||
"embeddings.search(\"feel good story with 'lottery' in text\")"
|
||||
]
|
||||
},
|
||||
{
|
||||
"cell_type": "markdown",
|
||||
"source": [
|
||||
"For good measure, a couple queries with filters that return no results."
|
||||
],
|
||||
"metadata": {
|
||||
"id": "1ob4Q_CLpGBm"
|
||||
}
|
||||
},
|
||||
"source": [
|
||||
"For good measure, a couple queries with filters that return no results."
|
||||
]
|
||||
},
|
||||
{
|
||||
"cell_type": "code",
|
||||
"source": [
|
||||
"embeddings.search(\"feel good story with missing in text\")"
|
||||
],
|
||||
"execution_count": 7,
|
||||
"metadata": {
|
||||
"colab": {
|
||||
"base_uri": "https://localhost:8080/"
|
||||
@@ -394,25 +367,25 @@
|
||||
"id": "LMaf7JJzonAC",
|
||||
"outputId": "71080bd1-2d9e-41ba-9501-2cdedaf26d6d"
|
||||
},
|
||||
"execution_count": null,
|
||||
"outputs": [
|
||||
{
|
||||
"output_type": "execute_result",
|
||||
"data": {
|
||||
"text/plain": [
|
||||
"[]"
|
||||
]
|
||||
},
|
||||
"execution_count": 7,
|
||||
"metadata": {},
|
||||
"execution_count": 36
|
||||
"output_type": "execute_result"
|
||||
}
|
||||
],
|
||||
"source": [
|
||||
"embeddings.search(\"feel good story with missing in text\")"
|
||||
]
|
||||
},
|
||||
{
|
||||
"cell_type": "code",
|
||||
"source": [
|
||||
"embeddings.search(\"feel good story with field equal 14\")"
|
||||
],
|
||||
"execution_count": 8,
|
||||
"metadata": {
|
||||
"colab": {
|
||||
"base_uri": "https://localhost:8080/"
|
||||
@@ -420,33 +393,57 @@
|
||||
"id": "ADFNLhvto_0J",
|
||||
"outputId": "12e08ea8-7203-4fb0-cb84-1133b5db9dc0"
|
||||
},
|
||||
"execution_count": null,
|
||||
"outputs": [
|
||||
{
|
||||
"output_type": "execute_result",
|
||||
"data": {
|
||||
"text/plain": [
|
||||
"[]"
|
||||
]
|
||||
},
|
||||
"execution_count": 8,
|
||||
"metadata": {},
|
||||
"execution_count": 37
|
||||
"output_type": "execute_result"
|
||||
}
|
||||
],
|
||||
"source": [
|
||||
"embeddings.search(\"feel good story with field equal 14\")"
|
||||
]
|
||||
},
|
||||
{
|
||||
"cell_type": "markdown",
|
||||
"metadata": {
|
||||
"id": "mTT8nopiRdVH"
|
||||
},
|
||||
"source": [
|
||||
"# Query translation with applications\n",
|
||||
"\n",
|
||||
"Of course this is all available with YAML-configured applications."
|
||||
],
|
||||
"metadata": {
|
||||
"id": "mTT8nopiRdVH"
|
||||
}
|
||||
]
|
||||
},
|
||||
{
|
||||
"cell_type": "code",
|
||||
"execution_count": 9,
|
||||
"metadata": {
|
||||
"colab": {
|
||||
"base_uri": "https://localhost:8080/"
|
||||
},
|
||||
"id": "FZ_7G6M4RUbz",
|
||||
"outputId": "b00ce1c2-8df2-4289-8d03-991174a0e74f"
|
||||
},
|
||||
"outputs": [
|
||||
{
|
||||
"data": {
|
||||
"text/plain": [
|
||||
"{'id': '4',\n",
|
||||
" 'text': 'Maine Mann gewinnt $1M von $25 Lotterie-Ticket',\n",
|
||||
" 'score': 0.08329025655984879}"
|
||||
]
|
||||
},
|
||||
"execution_count": 9,
|
||||
"metadata": {},
|
||||
"output_type": "execute_result"
|
||||
}
|
||||
],
|
||||
"source": [
|
||||
"config = \"\"\"\n",
|
||||
"translation:\n",
|
||||
@@ -470,28 +467,6 @@
|
||||
"\n",
|
||||
"# Run search query\n",
|
||||
"app.search(\"feel good story translated to de\")[0]"
|
||||
],
|
||||
"metadata": {
|
||||
"colab": {
|
||||
"base_uri": "https://localhost:8080/"
|
||||
},
|
||||
"id": "FZ_7G6M4RUbz",
|
||||
"outputId": "b00ce1c2-8df2-4289-8d03-991174a0e74f"
|
||||
},
|
||||
"execution_count": null,
|
||||
"outputs": [
|
||||
{
|
||||
"output_type": "execute_result",
|
||||
"data": {
|
||||
"text/plain": [
|
||||
"{'id': '4',\n",
|
||||
" 'score': 0.08329011499881744,\n",
|
||||
" 'text': 'Maine Mann gewinnt $1M von $25 Lotterie-Ticket'}"
|
||||
]
|
||||
},
|
||||
"metadata": {},
|
||||
"execution_count": 38
|
||||
}
|
||||
]
|
||||
},
|
||||
{
|
||||
@@ -505,5 +480,29 @@
|
||||
"This notebook introduced natural language filtering with query translation models. This powerful feature adds filtering and pipelines to natural language statements. Custom domain-specific query languages can be created to enable rich queries natively in txtai."
|
||||
]
|
||||
}
|
||||
]
|
||||
}
|
||||
],
|
||||
"metadata": {
|
||||
"colab": {
|
||||
"provenance": []
|
||||
},
|
||||
"kernelspec": {
|
||||
"display_name": "local",
|
||||
"language": "python",
|
||||
"name": "python3"
|
||||
},
|
||||
"language_info": {
|
||||
"codemirror_mode": {
|
||||
"name": "ipython",
|
||||
"version": 3
|
||||
},
|
||||
"file_extension": ".py",
|
||||
"mimetype": "text/x-python",
|
||||
"name": "python",
|
||||
"nbconvert_exporter": "python",
|
||||
"pygments_lexer": "ipython3",
|
||||
"version": "3.10.19"
|
||||
}
|
||||
},
|
||||
"nbformat": 4,
|
||||
"nbformat_minor": 0
|
||||
}
|
||||
|
||||
@@ -30,6 +30,7 @@
|
||||
"- Changing the vocabulary size\n",
|
||||
"- Changing the number of hidden dimensions\n",
|
||||
"- Changing the number of attention heads or layers\n",
|
||||
"- Create a custom model architecture\n",
|
||||
"\n",
|
||||
"This notebook will show how to build a new tokenizer and train a small language model (known as a micromodel) from scratch.\n"
|
||||
],
|
||||
|
||||
@@ -1,17 +1,4 @@
|
||||
{
|
||||
"nbformat": 4,
|
||||
"nbformat_minor": 0,
|
||||
"metadata": {
|
||||
"colab": {
|
||||
"provenance": []
|
||||
},
|
||||
"kernelspec": {
|
||||
"name": "python3",
|
||||
"display_name": "Python 3"
|
||||
},
|
||||
"accelerator": "GPU",
|
||||
"gpuClass": "standard"
|
||||
},
|
||||
"cells": [
|
||||
{
|
||||
"cell_type": "markdown",
|
||||
@@ -44,15 +31,15 @@
|
||||
},
|
||||
{
|
||||
"cell_type": "code",
|
||||
"execution_count": null,
|
||||
"metadata": {
|
||||
"id": "LPQTb25tASIG"
|
||||
},
|
||||
"outputs": [],
|
||||
"source": [
|
||||
"%%capture\n",
|
||||
"!pip install git+https://github.com/neuml/txtai datasets"
|
||||
],
|
||||
"execution_count": null,
|
||||
"outputs": []
|
||||
]
|
||||
},
|
||||
{
|
||||
"cell_type": "markdown",
|
||||
@@ -71,32 +58,65 @@
|
||||
},
|
||||
{
|
||||
"cell_type": "code",
|
||||
"execution_count": 1,
|
||||
"metadata": {
|
||||
"id": "OUc9gqTyAYnm"
|
||||
},
|
||||
"outputs": [],
|
||||
"source": [
|
||||
"%%capture\n",
|
||||
"\n",
|
||||
"from txtai import Embeddings, RAG\n",
|
||||
"\n",
|
||||
"# Create embeddings model with content support\n",
|
||||
"embeddings = Embeddings({\"path\": \"sentence-transformers/all-MiniLM-L6-v2\", \"content\": True})\n",
|
||||
"embeddings = Embeddings(path=\"sentence-transformers/all-MiniLM-L6-v2\", content=True)\n",
|
||||
"\n",
|
||||
"# Create RAG instance\n",
|
||||
"rag = RAG(embeddings, \"google/flan-t5-base\")"
|
||||
],
|
||||
"execution_count": null,
|
||||
"outputs": []
|
||||
"# Create the RAG pipeline\n",
|
||||
"rag = RAG(embeddings, \"Qwen/Qwen3-4B-Instruct-2507\", template=\"\"\"\n",
|
||||
" Answer the following question using the provided context.\n",
|
||||
"\n",
|
||||
" Question:\n",
|
||||
" {question}\n",
|
||||
"\n",
|
||||
" Context:\n",
|
||||
" {context}\n",
|
||||
"\"\"\")"
|
||||
]
|
||||
},
|
||||
{
|
||||
"cell_type": "code",
|
||||
"execution_count": 2,
|
||||
"metadata": {
|
||||
"id": "4X5z3UjnAGe7",
|
||||
"colab": {
|
||||
"base_uri": "https://localhost:8080/"
|
||||
},
|
||||
"id": "4X5z3UjnAGe7",
|
||||
"outputId": "cacb7e9d-471a-437d-c68d-a8b51f876413"
|
||||
},
|
||||
"outputs": [
|
||||
{
|
||||
"name": "stdout",
|
||||
"output_type": "stream",
|
||||
"text": [
|
||||
"---- Red Sox - Blue Jays ----\n",
|
||||
"{'answer': 'The Blue Jays won the game.'}\n",
|
||||
"{'answer': 'The score was 2-1 in favor of the Blue Jays.'}\n",
|
||||
"\n",
|
||||
"---- Phillies - Braves ----\n",
|
||||
"{'answer': 'The Phillies won the game.'}\n",
|
||||
"{'answer': 'The score was 5-0 in favor of the Phillies.'}\n",
|
||||
"\n",
|
||||
"---- Dodgers - Giants ----\n",
|
||||
"{'answer': 'The Giants won the game.'}\n",
|
||||
"{'answer': 'The score was Giants 5, Dodgers 4.'}\n",
|
||||
"\n",
|
||||
"---- Flyers - Lightning ----\n",
|
||||
"{'answer': 'The Flyers won the game.'}\n",
|
||||
"{'answer': 'The score was Flyers 4, Lightning 1.'}\n",
|
||||
"\n"
|
||||
]
|
||||
}
|
||||
],
|
||||
"source": [
|
||||
"data = [\"Giants hit 3 HRs to down Dodgers\",\n",
|
||||
" \"Giants 5 Dodgers 4 final\",\n",
|
||||
@@ -111,88 +131,40 @@
|
||||
" \"Flyers 4 Lightning 1 final\",\n",
|
||||
" \"Flyers win 4-1\"]\n",
|
||||
"\n",
|
||||
"def prompt(question):\n",
|
||||
" return f\"\"\"\n",
|
||||
" Answer the following question using the context below.\n",
|
||||
" Question: {question}\n",
|
||||
" Context:\n",
|
||||
" \"\"\"\n",
|
||||
"\n",
|
||||
"questions = [\"What team won the game?\", \"What was score?\"]\n",
|
||||
"\n",
|
||||
"execute = lambda query: rag([(question, query, prompt(question), False) for question in questions], data)\n",
|
||||
"\n",
|
||||
"for query in [\"Red Sox - Blue Jays\", \"Phillies - Braves\", \"Dodgers - Giants\", \"Flyers - Lightning\"]:\n",
|
||||
" print(\"----\", query, \"----\")\n",
|
||||
" for answer in execute(query):\n",
|
||||
" for answer in rag([f\"{query} {x}\" for x in questions], data):\n",
|
||||
" print(answer)\n",
|
||||
" print()"
|
||||
],
|
||||
"execution_count": null,
|
||||
"outputs": [
|
||||
{
|
||||
"output_type": "stream",
|
||||
"name": "stdout",
|
||||
"text": [
|
||||
"---- Red Sox - Blue Jays ----\n",
|
||||
"('What team won the game?', 'Blue Jays')\n",
|
||||
"('What was score?', '2-1')\n",
|
||||
"\n",
|
||||
"---- Phillies - Braves ----\n",
|
||||
"('What team won the game?', 'Phillies')\n",
|
||||
"('What was score?', '5-0')\n",
|
||||
"\n",
|
||||
"---- Dodgers - Giants ----\n",
|
||||
"('What team won the game?', 'Giants')\n",
|
||||
"('What was score?', '5-4')\n",
|
||||
"\n",
|
||||
"---- Flyers - Lightning ----\n",
|
||||
"('What team won the game?', 'Flyers')\n",
|
||||
"('What was score?', '4-1')\n",
|
||||
"\n"
|
||||
]
|
||||
}
|
||||
]
|
||||
},
|
||||
{
|
||||
"cell_type": "markdown",
|
||||
"metadata": {
|
||||
"id": "7AnPvSeM3N1Z"
|
||||
},
|
||||
"source": [
|
||||
"This code runs a series of questions. First it runs an embeddings filtering query to find the most relevant text. For example, `Red Sox - Blue Jays` finds text related to those teams. Then `What team won the game?` and `What was the score?` are asked.\n",
|
||||
"\n",
|
||||
"This logic is the same logic found in Notebook 5 - Extractive QA with txtai but uses prompt-based QA vs extractive QA. "
|
||||
],
|
||||
"metadata": {
|
||||
"id": "7AnPvSeM3N1Z"
|
||||
}
|
||||
]
|
||||
},
|
||||
{
|
||||
"cell_type": "markdown",
|
||||
"metadata": {
|
||||
"id": "Aj8GoDk331cS"
|
||||
},
|
||||
"source": [
|
||||
"# Embeddings-guided and Prompt-driven Search\n",
|
||||
"\n",
|
||||
"Now for the fun stuff. Let's build an embeddings index for the `ag_news` dataset (a set of news stories from the mid 2000s). Then we'll use prompts to ask questions with embeddings results as the context."
|
||||
],
|
||||
"metadata": {
|
||||
"id": "Aj8GoDk331cS"
|
||||
}
|
||||
]
|
||||
},
|
||||
{
|
||||
"cell_type": "code",
|
||||
"source": [
|
||||
"from datasets import load_dataset\n",
|
||||
"\n",
|
||||
"dataset = load_dataset(\"ag_news\", split=\"train\")\n",
|
||||
"\n",
|
||||
"# List of all text elements\n",
|
||||
"texts = dataset[\"text\"]\n",
|
||||
"\n",
|
||||
"# Create an embeddings index over the dataset\n",
|
||||
"embeddings = Embeddings({\"path\": \"sentence-transformers/all-MiniLM-L6-v2\", \"content\": True})\n",
|
||||
"embeddings.index((x, text, None) for x, text in enumerate(texts))\n",
|
||||
"\n",
|
||||
"# Create RAG instance\n",
|
||||
"rag = RAG(embeddings, \"google/flan-t5-large\")"
|
||||
],
|
||||
"execution_count": null,
|
||||
"metadata": {
|
||||
"colab": {
|
||||
"base_uri": "https://localhost:8080/"
|
||||
@@ -200,40 +172,41 @@
|
||||
"id": "yL716oEZ43t-",
|
||||
"outputId": "23f4b0e7-a60a-4e89-fb57-06966e6612f8"
|
||||
},
|
||||
"execution_count": null,
|
||||
"outputs": []
|
||||
"outputs": [
|
||||
],
|
||||
"source": [
|
||||
"from datasets import load_dataset\n",
|
||||
"\n",
|
||||
"dataset = load_dataset(\"ag_news\", split=\"train\")\n",
|
||||
"\n",
|
||||
"# Create an embeddings index over the dataset\n",
|
||||
"embeddings = Embeddings(path=\"sentence-transformers/all-MiniLM-L6-v2\", content=True)\n",
|
||||
"embeddings.index(dataset[\"text\"])\n",
|
||||
"\n",
|
||||
"# Create RAG instance\n",
|
||||
"rag = RAG(embeddings, \"Qwen/Qwen3-4B-Instruct-2507\", template=\"\"\"\n",
|
||||
" Answer the following question using the provided context.\n",
|
||||
"\n",
|
||||
" Question:\n",
|
||||
" {question}\n",
|
||||
"\n",
|
||||
" Context:\n",
|
||||
" {context}\n",
|
||||
"\"\"\", output=\"flatten\")"
|
||||
]
|
||||
},
|
||||
{
|
||||
"cell_type": "markdown",
|
||||
"source": [
|
||||
"Now let's run a prompt-driven search!"
|
||||
],
|
||||
"metadata": {
|
||||
"id": "Ifl8JwLDBL7k"
|
||||
}
|
||||
},
|
||||
"source": [
|
||||
"Now let's run a prompt-driven search!"
|
||||
]
|
||||
},
|
||||
{
|
||||
"cell_type": "code",
|
||||
"source": [
|
||||
"def prompt(question):\n",
|
||||
" return f\"\"\"Answer the following question using only the context below. Say 'no answer' when the question can't be answered.\n",
|
||||
"Question: {question}\n",
|
||||
"Context: \"\"\"\n",
|
||||
"\n",
|
||||
"def search(query, question=None):\n",
|
||||
" # Default question to query if empty\n",
|
||||
" if not question:\n",
|
||||
" question = query\n",
|
||||
"\n",
|
||||
" return rag([(\"answer\", query, prompt(question), False)])[0][1]\n",
|
||||
"\n",
|
||||
"question = \"Who won the 2004 presidential election?\"\n",
|
||||
"answer = search(question)\n",
|
||||
"print(question, answer)\n",
|
||||
"\n",
|
||||
"nquestion = \"Who did the candidate beat?\"\n",
|
||||
"print(nquestion, search(f\"{question} {answer}. {nquestion}\"))"
|
||||
],
|
||||
"execution_count": 22,
|
||||
"metadata": {
|
||||
"colab": {
|
||||
"base_uri": "https://localhost:8080/"
|
||||
@@ -241,91 +214,52 @@
|
||||
"id": "5O1WBJ8153Mo",
|
||||
"outputId": "ddf09da2-7d4c-4fd3-b0da-df5631bacd13"
|
||||
},
|
||||
"execution_count": null,
|
||||
"outputs": [
|
||||
{
|
||||
"output_type": "stream",
|
||||
"name": "stdout",
|
||||
"output_type": "stream",
|
||||
"text": [
|
||||
"Who won the 2004 presidential election? George W. Bush\n",
|
||||
"Who did the candidate beat? John F. Kerry\n"
|
||||
"Who won the 2004 presidential election? George W. Bush won the 2004 presidential election.\n",
|
||||
"Who did the candidate beat? George W. Bush beat John F. Kerry in the 2004 presidential election.\n"
|
||||
]
|
||||
}
|
||||
],
|
||||
"source": [
|
||||
"question = \"Who won the 2004 presidential election?\"\n",
|
||||
"answer = rag(question)\n",
|
||||
"print(question, answer)\n",
|
||||
"\n",
|
||||
"nquestion = \"Who did the candidate beat?\"\n",
|
||||
"print(nquestion, rag(f\"{question} {answer}. {nquestion}\"))"
|
||||
]
|
||||
},
|
||||
{
|
||||
"cell_type": "markdown",
|
||||
"metadata": {
|
||||
"id": "AhViFXH_BZSo"
|
||||
},
|
||||
"source": [
|
||||
"And there are the answers. Let's unpack how this works.\n",
|
||||
"\n",
|
||||
"The first thing the RAG pipeline does is run an embeddings search to find the most relevant text within the index. A context string is then built using those search results.\n",
|
||||
"\n",
|
||||
"After that, a prompt is generated, run and the answer printed. Let's see what a full prompt looks like."
|
||||
],
|
||||
"metadata": {
|
||||
"id": "AhViFXH_BZSo"
|
||||
}
|
||||
},
|
||||
{
|
||||
"cell_type": "code",
|
||||
"source": [
|
||||
"text = prompt(question)\n",
|
||||
"text += \"\\n\" + \"\\n\".join(x[\"text\"]for x in embeddings.search(question))\n",
|
||||
"print(text)"
|
||||
],
|
||||
"metadata": {
|
||||
"colab": {
|
||||
"base_uri": "https://localhost:8080/"
|
||||
},
|
||||
"id": "h7BsoJC3CFOq",
|
||||
"outputId": "44ae0dec-4f79-4d44-88f5-585e5eae9cb2"
|
||||
},
|
||||
"execution_count": null,
|
||||
"outputs": [
|
||||
{
|
||||
"output_type": "stream",
|
||||
"name": "stdout",
|
||||
"text": [
|
||||
"Answer the following question using only the context below. Say 'no answer' when the question can't be answered.\n",
|
||||
"Question: Who won the 2004 presidential election?\n",
|
||||
"Context: \n",
|
||||
"Right- and left-click politics The 2004 presidential race ended last week in a stunning defeat for Massachusetts Senator John F. Kerry, as incumbent President George W. Bush cruised to an easy victory.\n",
|
||||
"2004 Presidential Endorsements (AP) AP - Newspaper endorsements in the 2004 presidential campaign between President Bush, a Republican, and Sen. John Kerry, a Democrat.\n",
|
||||
"Presidential Campaign to Nov. 2, 2004 (Reuters) Reuters - The following diary of events\\leading up to the presidential election on Nov. 2.\n"
|
||||
]
|
||||
}
|
||||
"After that, a prompt is generated, run and the answer printed."
|
||||
]
|
||||
},
|
||||
{
|
||||
"cell_type": "markdown",
|
||||
"source": [
|
||||
"The prompt has the information needed to determine the answers to the questions."
|
||||
],
|
||||
"metadata": {
|
||||
"id": "4m9XketCty3m"
|
||||
}
|
||||
},
|
||||
{
|
||||
"cell_type": "markdown",
|
||||
"id": "JtDcVPdOB0Rv"
|
||||
},
|
||||
"source": [
|
||||
"# Additional examples\n",
|
||||
"\n",
|
||||
"Before moving on, a couple more example questions."
|
||||
],
|
||||
"metadata": {
|
||||
"id": "JtDcVPdOB0Rv"
|
||||
}
|
||||
]
|
||||
},
|
||||
{
|
||||
"cell_type": "code",
|
||||
"source": [
|
||||
"question = \"Who won the World Series in 2004?\"\n",
|
||||
"answer = search(question)\n",
|
||||
"print(question, answer)\n",
|
||||
"\n",
|
||||
"nquestion = \"Who did they beat?\"\n",
|
||||
"print(nquestion, search(f\"{question} {answer}. {nquestion}\"))"
|
||||
],
|
||||
"execution_count": 23,
|
||||
"metadata": {
|
||||
"colab": {
|
||||
"base_uri": "https://localhost:8080/"
|
||||
@@ -333,23 +267,28 @@
|
||||
"id": "0NNLBwC-83MM",
|
||||
"outputId": "4b9fabd7-baf9-4f7d-bb8b-c9c60c5101e4"
|
||||
},
|
||||
"execution_count": null,
|
||||
"outputs": [
|
||||
{
|
||||
"output_type": "stream",
|
||||
"name": "stdout",
|
||||
"output_type": "stream",
|
||||
"text": [
|
||||
"Who won the World Series in 2004? Boston\n",
|
||||
"Who did they beat? St Louis\n"
|
||||
"Who won the World Series in 2004? The Boston Red Sox won the World Series in 2004.\n",
|
||||
"What team did the Red Sox beat in the World Series? The Boston Red Sox beat the St. Louis Cardinals in the World Series.\n"
|
||||
]
|
||||
}
|
||||
],
|
||||
"source": [
|
||||
"question = \"Who won the World Series in 2004?\"\n",
|
||||
"answer = rag(question)\n",
|
||||
"print(question, answer)\n",
|
||||
"\n",
|
||||
"nquestion = \"What team did the Red Sox beat in the World Series?\"\n",
|
||||
"print(nquestion, rag(f\"{question} {answer}. {nquestion}\"))"
|
||||
]
|
||||
},
|
||||
{
|
||||
"cell_type": "code",
|
||||
"source": [
|
||||
"search(\"Tell me something interesting?\")"
|
||||
],
|
||||
"execution_count": 29,
|
||||
"metadata": {
|
||||
"colab": {
|
||||
"base_uri": "https://localhost:8080/",
|
||||
@@ -358,43 +297,36 @@
|
||||
"id": "1P0zqkTW9cZW",
|
||||
"outputId": "4f2232db-761b-464f-b47d-6695c84ffb80"
|
||||
},
|
||||
"execution_count": null,
|
||||
"outputs": [
|
||||
{
|
||||
"output_type": "execute_result",
|
||||
"data": {
|
||||
"text/plain": [
|
||||
"'herrings communicate by farting'"
|
||||
],
|
||||
"application/vnd.google.colaboratory.intrinsic+json": {
|
||||
"type": "string"
|
||||
}
|
||||
"'An interesting fact is that herrings communicate by farting—a quirky and unusual discovery that was honored with an Ig Nobel Prize for its oddball research.'"
|
||||
]
|
||||
},
|
||||
"execution_count": 29,
|
||||
"metadata": {},
|
||||
"execution_count": 8
|
||||
"output_type": "execute_result"
|
||||
}
|
||||
],
|
||||
"source": [
|
||||
"rag(\"Tell me something interesting\")"
|
||||
]
|
||||
},
|
||||
{
|
||||
"cell_type": "markdown",
|
||||
"metadata": {
|
||||
"id": "ygFFcwWPGI9p"
|
||||
},
|
||||
"source": [
|
||||
"Whhaaaattt??? Is this a model hallucination?\n",
|
||||
"\n",
|
||||
"Let's run an embeddings query and see if that text is in the results."
|
||||
],
|
||||
"metadata": {
|
||||
"id": "ygFFcwWPGI9p"
|
||||
}
|
||||
]
|
||||
},
|
||||
{
|
||||
"cell_type": "code",
|
||||
"source": [
|
||||
"answer = \"herrings communicate by farting\"\n",
|
||||
"for x in embeddings.search(\"Tell me something interesting?\"):\n",
|
||||
" if answer in x[\"text\"]:\n",
|
||||
" start = x[\"text\"].find(answer)\n",
|
||||
" print(x[\"text\"][start:start + len(answer)])"
|
||||
],
|
||||
"execution_count": 28,
|
||||
"metadata": {
|
||||
"colab": {
|
||||
"base_uri": "https://localhost:8080/"
|
||||
@@ -402,143 +334,68 @@
|
||||
"id": "qZPhLqSxGMbK",
|
||||
"outputId": "e3b2909a-1ee8-480f-afa3-201a8e27cb08"
|
||||
},
|
||||
"execution_count": null,
|
||||
"outputs": [
|
||||
{
|
||||
"output_type": "stream",
|
||||
"name": "stdout",
|
||||
"output_type": "stream",
|
||||
"text": [
|
||||
"herrings communicate by farting\n"
|
||||
]
|
||||
}
|
||||
],
|
||||
"source": [
|
||||
"answer = \"herrings communicate by farting\"\n",
|
||||
"for x in embeddings.search(\"Tell me something interesting\"):\n",
|
||||
" if answer in x[\"text\"]:\n",
|
||||
" start = x[\"text\"].find(answer)\n",
|
||||
" print(x[\"text\"][start:start + len(answer)])"
|
||||
]
|
||||
},
|
||||
{
|
||||
"cell_type": "markdown",
|
||||
"source": [
|
||||
"Sure enough it is. It appears that the FLAN-T5 model has a bit of an immature sense of humor 😃"
|
||||
],
|
||||
"metadata": {
|
||||
"id": "IpgxMc1DZcds"
|
||||
}
|
||||
},
|
||||
{
|
||||
"cell_type": "markdown",
|
||||
"source": [
|
||||
"# External API Integration\n",
|
||||
"\n",
|
||||
"In addition to support for Hugging Face models, the RAG pipeline also supports custom question-answer models. This could be a call to the OpenAI API (GPT-3), Cohere API, Hugging Face API or using langchain to manage that. All that is needed is a Callable object or a function!\n",
|
||||
"\n",
|
||||
"Let's see an example that uses the Hugging Face API to answer questions. We'll use the original sports dataset to demonstrate."
|
||||
],
|
||||
"metadata": {
|
||||
"id": "7bitjzeyYOqh"
|
||||
}
|
||||
},
|
||||
{
|
||||
"cell_type": "code",
|
||||
"source": [
|
||||
"import requests\n",
|
||||
"\n",
|
||||
"data = [\"Giants hit 3 HRs to down Dodgers\",\n",
|
||||
" \"Giants 5 Dodgers 4 final\",\n",
|
||||
" \"Dodgers drop Game 2 against the Giants, 5-4\",\n",
|
||||
" \"Blue Jays beat Red Sox final score 2-1\",\n",
|
||||
" \"Red Sox lost to the Blue Jays, 2-1\",\n",
|
||||
" \"Blue Jays at Red Sox is over. Score: 2-1\",\n",
|
||||
" \"Phillies win over the Braves, 5-0\",\n",
|
||||
" \"Phillies 5 Braves 0 final\",\n",
|
||||
" \"Final: Braves lose to the Phillies in the series opener, 5-0\",\n",
|
||||
" \"Lightning goaltender pulled, lose to Flyers 4-1\",\n",
|
||||
" \"Flyers 4 Lightning 1 final\",\n",
|
||||
" \"Flyers win 4-1\"]\n",
|
||||
"\n",
|
||||
"def prompt(question):\n",
|
||||
" return f\"\"\"\n",
|
||||
" Answer the following question using the context below.\n",
|
||||
" Question: {question}\n",
|
||||
" Context:\n",
|
||||
" \"\"\"\n",
|
||||
"\n",
|
||||
"# Submits a series of prompts to the Hugging Face API.\n",
|
||||
"# This call can easily be switched to use the OpenAI API (GPT-3), Cohere API or a library like langchain.\n",
|
||||
"def api(prompts):\n",
|
||||
" response = requests.post(\"https://api-inference.huggingface.co/models/google/flan-t5-base\",\n",
|
||||
" json={\"inputs\": prompts})\n",
|
||||
"\n",
|
||||
" return [x[\"generated_text\"] for x in response.json()]\n",
|
||||
"\n",
|
||||
"# Create embeddings model with content support\n",
|
||||
"embeddings = Embeddings({\"path\": \"sentence-transformers/all-MiniLM-L6-v2\", \"content\": True})\n",
|
||||
"\n",
|
||||
"# Create RAG instance, submit prompts to the Hugging Face inference API\n",
|
||||
"rag = RAG(embeddings, api)\n",
|
||||
"\n",
|
||||
"questions = [\"What team won the game?\", \"What was score?\"]\n",
|
||||
"\n",
|
||||
"execute = lambda query: rag([(question, query, prompt(question), False) for question in questions], data)\n",
|
||||
"\n",
|
||||
"for query in [\"Red Sox - Blue Jays\", \"Phillies - Braves\", \"Dodgers - Giants\", \"Flyers - Lightning\"]:\n",
|
||||
" print(\"----\", query, \"----\")\n",
|
||||
" for answer in execute(query):\n",
|
||||
" print(answer)\n",
|
||||
" print()\n"
|
||||
],
|
||||
"metadata": {
|
||||
"colab": {
|
||||
"base_uri": "https://localhost:8080/"
|
||||
},
|
||||
"id": "yYAa9N7EYm7E",
|
||||
"outputId": "72208327-bfb7-466f-c664-3630f207b6dd"
|
||||
},
|
||||
"execution_count": null,
|
||||
"outputs": [
|
||||
{
|
||||
"output_type": "stream",
|
||||
"name": "stdout",
|
||||
"text": [
|
||||
"---- Red Sox - Blue Jays ----\n",
|
||||
"('What team won the game?', 'Blue Jays')\n",
|
||||
"('What was score?', '2-1')\n",
|
||||
"\n",
|
||||
"---- Phillies - Braves ----\n",
|
||||
"('What team won the game?', 'Phillies')\n",
|
||||
"('What was score?', '5-0')\n",
|
||||
"\n",
|
||||
"---- Dodgers - Giants ----\n",
|
||||
"('What team won the game?', 'Giants')\n",
|
||||
"('What was score?', '5-4')\n",
|
||||
"\n",
|
||||
"---- Flyers - Lightning ----\n",
|
||||
"('What team won the game?', 'Flyers')\n",
|
||||
"('What was score?', '4-1')\n",
|
||||
"\n"
|
||||
]
|
||||
}
|
||||
"source": [
|
||||
"Sure enough it is 😃"
|
||||
]
|
||||
},
|
||||
{
|
||||
"cell_type": "markdown",
|
||||
"source": [
|
||||
"Everything matches with first example above in [Create Embeddings and RAG instances](#Create-Embeddings-and-RAG-instances) except the prompts are run as an external API call.\n",
|
||||
"\n",
|
||||
"The Embeddings instance can also swap out the vectorization, database and vector store components with external API services. Check out the [txtai documentation](https://neuml.github.io/txtai/embeddings/configuration/) documentation for more information.\n",
|
||||
"\n"
|
||||
],
|
||||
"metadata": {
|
||||
"id": "Xh8UhC3NdsGf"
|
||||
}
|
||||
},
|
||||
{
|
||||
"cell_type": "markdown",
|
||||
"id": "KqfvCXp2B3li"
|
||||
},
|
||||
"source": [
|
||||
"# Wrapping up\n",
|
||||
"\n",
|
||||
"This notebook covered how to run embeddings-guided and prompt-driven search with LLMs. This functionality is a major step forward towards `Generative Semantic Search` for txtai. More to come, stay tuned!"
|
||||
],
|
||||
"metadata": {
|
||||
"id": "KqfvCXp2B3li"
|
||||
}
|
||||
]
|
||||
}
|
||||
]
|
||||
}
|
||||
],
|
||||
"metadata": {
|
||||
"accelerator": "GPU",
|
||||
"colab": {
|
||||
"provenance": []
|
||||
},
|
||||
"gpuClass": "standard",
|
||||
"kernelspec": {
|
||||
"display_name": "local",
|
||||
"language": "python",
|
||||
"name": "python3"
|
||||
},
|
||||
"language_info": {
|
||||
"codemirror_mode": {
|
||||
"name": "ipython",
|
||||
"version": 3
|
||||
},
|
||||
"file_extension": ".py",
|
||||
"mimetype": "text/x-python",
|
||||
"name": "python",
|
||||
"nbconvert_exporter": "python",
|
||||
"pygments_lexer": "ipython3",
|
||||
"version": "3.10.19"
|
||||
}
|
||||
},
|
||||
"nbformat": 4,
|
||||
"nbformat_minor": 0
|
||||
}
|
||||
|
||||
@@ -1,17 +1,4 @@
|
||||
{
|
||||
"nbformat": 4,
|
||||
"nbformat_minor": 0,
|
||||
"metadata": {
|
||||
"colab": {
|
||||
"provenance": []
|
||||
},
|
||||
"kernelspec": {
|
||||
"name": "python3",
|
||||
"display_name": "Python 3"
|
||||
},
|
||||
"accelerator": "GPU",
|
||||
"gpuClass": "standard"
|
||||
},
|
||||
"cells": [
|
||||
{
|
||||
"cell_type": "markdown",
|
||||
@@ -41,15 +28,15 @@
|
||||
},
|
||||
{
|
||||
"cell_type": "code",
|
||||
"execution_count": null,
|
||||
"metadata": {
|
||||
"id": "LPQTb25tASIG"
|
||||
},
|
||||
"outputs": [],
|
||||
"source": [
|
||||
"%%capture\n",
|
||||
"!pip install git+https://github.com/neuml/txtai#egg=txtai[api]"
|
||||
],
|
||||
"execution_count": null,
|
||||
"outputs": []
|
||||
]
|
||||
},
|
||||
{
|
||||
"cell_type": "markdown",
|
||||
@@ -61,36 +48,46 @@
|
||||
"\n",
|
||||
"First, we'll look at building a workflow with a series of model prompts. This workflow creates a conditional translation using a statement and target language. Another task reads that output text and detects the language.\n",
|
||||
"\n",
|
||||
"This workflow uses a sequences pipeline. The sequences pipeline loads a Hugging Face sequence to sequence model for inference, in this case [FLAN-T5](https://huggingface.co/google/flan-t5-base). The sequences pipeline takes a prompt as input and outputs the model inference result.\n",
|
||||
"This workflow uses a LLM pipeline. The LLM pipeline loads a local model for inference, in this case [Qwen3-4B-Instruct-2507](https://huggingface.co/Qwen/Qwen3-4B-Instruct-2507). The [LLM pipeline](https://neuml.github.io/txtai/pipeline/llm/llm) supports local transformers models, llama.cpp models and LLM APIs such as Ollama, vLLM, OpenAI, Claude etc. \n",
|
||||
"\n",
|
||||
"It's important to note that a pipeline is simply a callable function. It can easily be replaced with a call to an external API."
|
||||
]
|
||||
},
|
||||
{
|
||||
"cell_type": "code",
|
||||
"execution_count": null,
|
||||
"metadata": {
|
||||
"id": "OUc9gqTyAYnm",
|
||||
"colab": {
|
||||
"base_uri": "https://localhost:8080/"
|
||||
},
|
||||
"id": "OUc9gqTyAYnm",
|
||||
"outputId": "83300311-736c-47c8-bc16-ec0303274054"
|
||||
},
|
||||
"outputs": [
|
||||
{
|
||||
"name": "stdout",
|
||||
"output_type": "stream",
|
||||
"text": [
|
||||
"['French', 'German']\n"
|
||||
]
|
||||
}
|
||||
],
|
||||
"source": [
|
||||
"from txtai.pipeline import Sequences\n",
|
||||
"from txtai.workflow import Workflow, TemplateTask\n",
|
||||
"from txtai import LLM, Workflow\n",
|
||||
"from txtai.workflow import TemplateTask\n",
|
||||
"\n",
|
||||
"# Create sequences pipeline\n",
|
||||
"sequences = Sequences(\"google/flan-t5-large\")\n",
|
||||
"# Create LLM\n",
|
||||
"llm = LLM(\"Qwen/Qwen3-4B-Instruct-2507\")\n",
|
||||
"\n",
|
||||
"# Define workflow or chaining of tasks together.\n",
|
||||
"workflow = Workflow([\n",
|
||||
" TemplateTask(\n",
|
||||
" template=\"Translate '{statement}' to {language} if it's English\",\n",
|
||||
" action=sequences\n",
|
||||
" template=\"Translate text '{statement}' to {language} if the text is English, otherwise keep the original text\",\n",
|
||||
" action=llm\n",
|
||||
" ),\n",
|
||||
" TemplateTask(\n",
|
||||
" template=\"What language is the following text? {text}\",\n",
|
||||
" action=sequences\n",
|
||||
" template=\"What language is the following text. Only print the answer? {text}\",\n",
|
||||
" action=llm\n",
|
||||
" )\n",
|
||||
"])\n",
|
||||
"\n",
|
||||
@@ -100,20 +97,13 @@
|
||||
"]\n",
|
||||
"\n",
|
||||
"print(list(workflow(inputs)))"
|
||||
],
|
||||
"execution_count": null,
|
||||
"outputs": [
|
||||
{
|
||||
"output_type": "stream",
|
||||
"name": "stdout",
|
||||
"text": [
|
||||
"['French', 'German']\n"
|
||||
]
|
||||
}
|
||||
]
|
||||
},
|
||||
{
|
||||
"cell_type": "markdown",
|
||||
"metadata": {
|
||||
"id": "_zz4Do8BV-Lk"
|
||||
},
|
||||
"source": [
|
||||
"Let's recap what happened here. The first workflow task conditionally translates text to a language if it's English.\n",
|
||||
"\n",
|
||||
@@ -122,40 +112,22 @@
|
||||
"The second statement is German, so it's not converted to French.\n",
|
||||
"\n",
|
||||
"The next step asks the model what the language is and it correctly prints `French` and `German`."
|
||||
],
|
||||
"metadata": {
|
||||
"id": "_zz4Do8BV-Lk"
|
||||
}
|
||||
]
|
||||
},
|
||||
{
|
||||
"cell_type": "markdown",
|
||||
"metadata": {
|
||||
"id": "iXDAKP4CX0W9"
|
||||
},
|
||||
"source": [
|
||||
"# Prompt Workflow as YAML\n",
|
||||
"\n",
|
||||
"The same workflow above can be created with YAML configuration."
|
||||
],
|
||||
"metadata": {
|
||||
"id": "iXDAKP4CX0W9"
|
||||
}
|
||||
]
|
||||
},
|
||||
{
|
||||
"cell_type": "code",
|
||||
"source": [
|
||||
"%%writefile workflow.yml\n",
|
||||
"\n",
|
||||
"sequences:\n",
|
||||
" path: google/flan-t5-large\n",
|
||||
"\n",
|
||||
"workflow:\n",
|
||||
" chain:\n",
|
||||
" tasks:\n",
|
||||
" - task: template\n",
|
||||
" template: Translate '{statement}' to {language} if it's English\n",
|
||||
" action: sequences\n",
|
||||
" - task: template\n",
|
||||
" template: What language is the following text? {text}\n",
|
||||
" action: sequences"
|
||||
],
|
||||
"execution_count": 2,
|
||||
"metadata": {
|
||||
"colab": {
|
||||
"base_uri": "https://localhost:8080/"
|
||||
@@ -163,25 +135,35 @@
|
||||
"id": "GwV5A9xRYtYs",
|
||||
"outputId": "ffe6ee65-95a7-46c6-e6b9-5324eab26ca8"
|
||||
},
|
||||
"execution_count": null,
|
||||
"outputs": [
|
||||
{
|
||||
"output_type": "stream",
|
||||
"name": "stdout",
|
||||
"output_type": "stream",
|
||||
"text": [
|
||||
"Writing workflow.yml\n"
|
||||
]
|
||||
}
|
||||
],
|
||||
"source": [
|
||||
"%%writefile workflow.yml\n",
|
||||
"\n",
|
||||
"llm:\n",
|
||||
" path: Qwen/Qwen3-4B-Instruct-2507\n",
|
||||
"\n",
|
||||
"workflow:\n",
|
||||
" chain:\n",
|
||||
" tasks:\n",
|
||||
" - task: template\n",
|
||||
" template: Translate text '{statement}' to {language} if the text is English, otherwise keep the original text\n",
|
||||
" action: llm\n",
|
||||
" - task: template\n",
|
||||
" template: What language is the following text. Only print the answer? {text}\n",
|
||||
" action: llm"
|
||||
]
|
||||
},
|
||||
{
|
||||
"cell_type": "code",
|
||||
"source": [
|
||||
"from txtai import Application\n",
|
||||
"\n",
|
||||
"app = Application(\"workflow.yml\")\n",
|
||||
"print(list(app.workflow(\"chain\", inputs)))"
|
||||
],
|
||||
"execution_count": 2,
|
||||
"metadata": {
|
||||
"colab": {
|
||||
"base_uri": "https://localhost:8080/"
|
||||
@@ -189,58 +171,58 @@
|
||||
"id": "dr7Lv5S5X98e",
|
||||
"outputId": "d6ac0427-671d-4525-aa21-664430109af3"
|
||||
},
|
||||
"execution_count": null,
|
||||
"outputs": [
|
||||
{
|
||||
"output_type": "stream",
|
||||
"name": "stdout",
|
||||
"output_type": "stream",
|
||||
"text": [
|
||||
"['French', 'German']\n"
|
||||
]
|
||||
}
|
||||
],
|
||||
"source": [
|
||||
"from txtai import Application\n",
|
||||
"\n",
|
||||
"app = Application(\"workflow.yml\")\n",
|
||||
"print(list(app.workflow(\"chain\", inputs)))"
|
||||
]
|
||||
},
|
||||
{
|
||||
"cell_type": "markdown",
|
||||
"source": [
|
||||
"As expected, the same result! This is a matter of preference on how you want to create a workflow. One advantage of YAML workflows is that an API can easily be created from the workflow file."
|
||||
],
|
||||
"metadata": {
|
||||
"id": "EGqiV45fYVse"
|
||||
}
|
||||
},
|
||||
"source": [
|
||||
"As expected, the same result! This is a matter of preference on how you want to create a workflow. One advantage of YAML workflows is that an API can easily be created from the workflow file."
|
||||
]
|
||||
},
|
||||
{
|
||||
"cell_type": "markdown",
|
||||
"metadata": {
|
||||
"id": "9PqMU0bNYinf"
|
||||
},
|
||||
"source": [
|
||||
"# Prompt Workflow via an API call\n",
|
||||
"\n",
|
||||
"Let's say you want the workflow to be available via an API call. Well good news, txtai has a built in API mechanism using FastAPI. "
|
||||
],
|
||||
"metadata": {
|
||||
"id": "9PqMU0bNYinf"
|
||||
}
|
||||
]
|
||||
},
|
||||
{
|
||||
"cell_type": "code",
|
||||
"execution_count": null,
|
||||
"metadata": {
|
||||
"id": "vDxQj1ZIYsz3"
|
||||
},
|
||||
"outputs": [],
|
||||
"source": [
|
||||
"# Start an API service\n",
|
||||
"!CONFIG=workflow.yml nohup uvicorn \"txtai.api:app\" &> api.log &\n",
|
||||
"!sleep 60"
|
||||
],
|
||||
"metadata": {
|
||||
"id": "vDxQj1ZIYsz3"
|
||||
},
|
||||
"execution_count": null,
|
||||
"outputs": []
|
||||
]
|
||||
},
|
||||
{
|
||||
"cell_type": "code",
|
||||
"source": [
|
||||
"import requests\n",
|
||||
"\n",
|
||||
"# Run API request\n",
|
||||
"requests.post(\"http://localhost:8000/workflow\", json={\"name\": \"chain\", \"elements\": inputs}).json()"
|
||||
],
|
||||
"execution_count": 3,
|
||||
"metadata": {
|
||||
"colab": {
|
||||
"base_uri": "https://localhost:8080/"
|
||||
@@ -248,31 +230,53 @@
|
||||
"id": "R1o08SVtZW7h",
|
||||
"outputId": "99875acd-18a8-4c2c-ead3-cb6975a4b2d2"
|
||||
},
|
||||
"execution_count": null,
|
||||
"outputs": [
|
||||
{
|
||||
"output_type": "execute_result",
|
||||
"data": {
|
||||
"text/plain": [
|
||||
"['French', 'German']"
|
||||
]
|
||||
},
|
||||
"execution_count": 3,
|
||||
"metadata": {},
|
||||
"execution_count": 5
|
||||
"output_type": "execute_result"
|
||||
}
|
||||
],
|
||||
"source": [
|
||||
"import requests\n",
|
||||
"\n",
|
||||
"# Run API request\n",
|
||||
"requests.post(\"http://localhost:8000/workflow\", json={\"name\": \"chain\", \"elements\": inputs}).json()"
|
||||
]
|
||||
},
|
||||
{
|
||||
"cell_type": "markdown",
|
||||
"source": [
|
||||
"Just like the previous steps, except through an API call. Let's run via cURL for good measure."
|
||||
],
|
||||
"metadata": {
|
||||
"id": "B88mCrGFl5W-"
|
||||
}
|
||||
},
|
||||
"source": [
|
||||
"Just like the previous steps, except through an API call. Let's run via cURL for good measure."
|
||||
]
|
||||
},
|
||||
{
|
||||
"cell_type": "code",
|
||||
"execution_count": 4,
|
||||
"metadata": {
|
||||
"colab": {
|
||||
"base_uri": "https://localhost:8080/"
|
||||
},
|
||||
"id": "hRUyh0cQl_P2",
|
||||
"outputId": "9db8481d-0b6e-4a31-bdf6-5443df5f768a"
|
||||
},
|
||||
"outputs": [
|
||||
{
|
||||
"name": "stdout",
|
||||
"output_type": "stream",
|
||||
"text": [
|
||||
"[\"French\",\"German\"]"
|
||||
]
|
||||
}
|
||||
],
|
||||
"source": [
|
||||
"%%bash\n",
|
||||
"\n",
|
||||
@@ -287,51 +291,51 @@
|
||||
" ]\n",
|
||||
"}\n",
|
||||
"EOF"
|
||||
],
|
||||
"metadata": {
|
||||
"colab": {
|
||||
"base_uri": "https://localhost:8080/"
|
||||
},
|
||||
"id": "hRUyh0cQl_P2",
|
||||
"outputId": "9db8481d-0b6e-4a31-bdf6-5443df5f768a"
|
||||
},
|
||||
"execution_count": null,
|
||||
"outputs": [
|
||||
{
|
||||
"output_type": "stream",
|
||||
"name": "stdout",
|
||||
"text": [
|
||||
"[\"French\",\"German\"]"
|
||||
]
|
||||
}
|
||||
]
|
||||
},
|
||||
{
|
||||
"cell_type": "markdown",
|
||||
"metadata": {
|
||||
"id": "W0zL93WPoaCo"
|
||||
},
|
||||
"source": [
|
||||
"One last time, the same output is shown.\n",
|
||||
"\n",
|
||||
"If your primary development environment isn't Python, txtai does have API bindings for [JavaScript](https://github.com/neuml/txtai.js), [Rust](https://github.com/neuml/txtai.rs), [Go](https://github.com/neuml/txtai.go) and [Java](https://github.com/neuml/txtai.java).\n",
|
||||
"\n",
|
||||
"More information on the API is available [here](https://neuml.github.io/txtai/api/)."
|
||||
],
|
||||
"metadata": {
|
||||
"id": "W0zL93WPoaCo"
|
||||
}
|
||||
]
|
||||
},
|
||||
{
|
||||
"cell_type": "markdown",
|
||||
"source": [
|
||||
"# Conversational chain\n",
|
||||
"\n",
|
||||
"Conversational search is another big area of focus in 2023. [txtchat](https://github.com/neuml/txtchat) is a framework for building conversational search applications. It relies heavily on txtai. Let's see a conversational example."
|
||||
],
|
||||
"metadata": {
|
||||
"id": "q9WiFG6fpzw5"
|
||||
}
|
||||
},
|
||||
"source": [
|
||||
"# Chat with your data\n",
|
||||
"\n",
|
||||
"\"Chat with your data\" is a popular entry point into the AI space. Let's run an example."
|
||||
]
|
||||
},
|
||||
{
|
||||
"cell_type": "code",
|
||||
"execution_count": 10,
|
||||
"metadata": {
|
||||
"colab": {
|
||||
"base_uri": "https://localhost:8080/"
|
||||
},
|
||||
"id": "rM3Y551LqF-J",
|
||||
"outputId": "85623785-c15f-4996-9460-0644f69cf5bf"
|
||||
},
|
||||
"outputs": [
|
||||
{
|
||||
"name": "stdout",
|
||||
"output_type": "stream",
|
||||
"text": [
|
||||
"Writing search.yml\n"
|
||||
]
|
||||
}
|
||||
],
|
||||
"source": [
|
||||
"%%writefile search.yml\n",
|
||||
"\n",
|
||||
@@ -341,48 +345,27 @@
|
||||
" container: neuml/txtai-intro\n",
|
||||
"\n",
|
||||
"rag:\n",
|
||||
" path: google/flan-t5-large\n",
|
||||
" path: Qwen/Qwen3-4B-Instruct-2507\n",
|
||||
" output: reference\n",
|
||||
" template: |\n",
|
||||
" Answer the following question using only the context below.\n",
|
||||
"\n",
|
||||
" Question: {question}\n",
|
||||
" Context: {context}\n",
|
||||
"\n",
|
||||
"workflow:\n",
|
||||
" search:\n",
|
||||
" tasks:\n",
|
||||
" - task: rag\n",
|
||||
" template: |\n",
|
||||
" Answer the following question using only the context below. Give a detailed answer.\n",
|
||||
" Say 'I don't have data on that' when the question can't be answered.\n",
|
||||
" Question: {text}\n",
|
||||
" Context: \n",
|
||||
" action: rag\n",
|
||||
" - action: rag\n",
|
||||
" - task: template\n",
|
||||
" template: \"{answer}\\n\\nReference: {reference}\"\n",
|
||||
" rules:\n",
|
||||
" answer: I don't have data on that"
|
||||
],
|
||||
"metadata": {
|
||||
"colab": {
|
||||
"base_uri": "https://localhost:8080/"
|
||||
},
|
||||
"id": "rM3Y551LqF-J",
|
||||
"outputId": "85623785-c15f-4996-9460-0644f69cf5bf"
|
||||
},
|
||||
"execution_count": null,
|
||||
"outputs": [
|
||||
{
|
||||
"output_type": "stream",
|
||||
"name": "stdout",
|
||||
"text": [
|
||||
"Overwriting search.yml\n"
|
||||
]
|
||||
}
|
||||
]
|
||||
},
|
||||
{
|
||||
"cell_type": "code",
|
||||
"source": [
|
||||
"app = Application(\"search.yml\")\n",
|
||||
"print(list(app.workflow(\"search\", [\"Tell me something about North America\"])))"
|
||||
],
|
||||
"execution_count": null,
|
||||
"metadata": {
|
||||
"colab": {
|
||||
"base_uri": "https://localhost:8080/"
|
||||
@@ -390,40 +373,67 @@
|
||||
"id": "1Elb8JANqpwX",
|
||||
"outputId": "b1f1ffa1-6c47-4d90-b6f1-8098d4dc45f8"
|
||||
},
|
||||
"execution_count": null,
|
||||
"outputs": [
|
||||
{
|
||||
"output_type": "stream",
|
||||
"name": "stdout",
|
||||
"output_type": "stream",
|
||||
"text": [
|
||||
"[\"Canada's last fully intact ice shelf has suddenly collapsed, forming a Manhattan-sized iceberg\\n\\nReference: 1\"]\n"
|
||||
"[\"Canada's last fully intact ice shelf has suddenly collapsed, forming a Manhattan-sized iceberg.\\n\\nReference: 1\"]\n"
|
||||
]
|
||||
}
|
||||
],
|
||||
"source": [
|
||||
"app = Application(\"search.yml\")\n",
|
||||
"print(list(app.workflow(\"search\", [\"Find something about North America\"])))"
|
||||
]
|
||||
},
|
||||
{
|
||||
"cell_type": "markdown",
|
||||
"metadata": {
|
||||
"id": "4r49V4c9s5nf"
|
||||
},
|
||||
"source": [
|
||||
"The first thing the code above does is run an embeddings search to build a conversational context. That context is then used to build a prompt and inference is run against the LLM. \n",
|
||||
"\n",
|
||||
"The next task formats the outputs with a reference to the best matching record. In this case, it's only an id of 1. But this can be much more useful if the id is a URL or there is logic to format the id back to a unique reference string.\n",
|
||||
"\n",
|
||||
"The [txtchat](https://github.com/neuml/txtchat) project has much more on this, check it out!"
|
||||
],
|
||||
"metadata": {
|
||||
"id": "4r49V4c9s5nf"
|
||||
}
|
||||
"The next task formats the outputs with a reference to the best matching record. In this case, it's only an id of 1. But this can be much more useful if the id is a URL or there is logic to format the id back to a unique reference string."
|
||||
]
|
||||
},
|
||||
{
|
||||
"cell_type": "markdown",
|
||||
"metadata": {
|
||||
"id": "KqfvCXp2B3li"
|
||||
},
|
||||
"source": [
|
||||
"# Wrapping up\n",
|
||||
"\n",
|
||||
"This notebook covered how to build prompt templates and task chains through a series of results. txtai has long had a robust and efficient workflow framework for connecting models together. This can be small and simple models and/or prompting with large models. Go ahead and give it a try!"
|
||||
],
|
||||
"metadata": {
|
||||
"id": "KqfvCXp2B3li"
|
||||
}
|
||||
]
|
||||
}
|
||||
]
|
||||
}
|
||||
],
|
||||
"metadata": {
|
||||
"accelerator": "GPU",
|
||||
"colab": {
|
||||
"provenance": []
|
||||
},
|
||||
"gpuClass": "standard",
|
||||
"kernelspec": {
|
||||
"display_name": "local",
|
||||
"language": "python",
|
||||
"name": "python3"
|
||||
},
|
||||
"language_info": {
|
||||
"codemirror_mode": {
|
||||
"name": "ipython",
|
||||
"version": 3
|
||||
},
|
||||
"file_extension": ".py",
|
||||
"mimetype": "text/x-python",
|
||||
"name": "python",
|
||||
"nbconvert_exporter": "python",
|
||||
"pygments_lexer": "ipython3",
|
||||
"version": "3.10.19"
|
||||
}
|
||||
},
|
||||
"nbformat": 4,
|
||||
"nbformat_minor": 0
|
||||
}
|
||||
|
||||
@@ -428,7 +428,7 @@
|
||||
"source": [
|
||||
"import txtai\n",
|
||||
"\n",
|
||||
"# Creat embeddings\n",
|
||||
"# Create embeddings\n",
|
||||
"embeddings = txtai.Embeddings(\n",
|
||||
" keyword=True,\n",
|
||||
" content=\"postgresql+psycopg2://postgres:postgres@localhost/postgres\",\n",
|
||||
@@ -799,4 +799,4 @@
|
||||
},
|
||||
"nbformat": 4,
|
||||
"nbformat_minor": 0
|
||||
}
|
||||
}
|
||||
|
||||
@@ -78,8 +78,7 @@
|
||||
"\n",
|
||||
"# LLM pipeline\n",
|
||||
"llm:\n",
|
||||
" path: google/flan-t5-large\n",
|
||||
" torch_dtype: torch.bfloat16"
|
||||
" path: Qwen/Qwen3-4B-Instruct-2507"
|
||||
],
|
||||
"metadata": {
|
||||
"colab": {
|
||||
|
||||
@@ -1,61 +1,45 @@
|
||||
{
|
||||
"nbformat": 4,
|
||||
"nbformat_minor": 0,
|
||||
"metadata": {
|
||||
"colab": {
|
||||
"provenance": [],
|
||||
"gpuType": "T4"
|
||||
},
|
||||
"kernelspec": {
|
||||
"name": "python3",
|
||||
"display_name": "Python 3"
|
||||
},
|
||||
"language_info": {
|
||||
"name": "python"
|
||||
},
|
||||
"accelerator": "GPU"
|
||||
},
|
||||
"cells": [
|
||||
{
|
||||
"cell_type": "markdown",
|
||||
"metadata": {
|
||||
"id": "VGeVB8M41jqW"
|
||||
},
|
||||
"source": [
|
||||
"# Build RAG pipelines with txtai\n",
|
||||
"\n",
|
||||
"Large Language Models (LLMs) have completely dominated the AI and machine learning space in 2023. The results have been amazing and the public imagination is almost endless.\n",
|
||||
"Large Language Models (LLMs) have completely dominated the tech space in recent years. The results have been amazing and the public imagination is almost endless.\n",
|
||||
"\n",
|
||||
"While LLMs have been impressive, they are not problem free. The biggest challenge is with hallucinations. Hallucinations is the term for when a LLM generates output that is factually incorrect. The alarming part of this is that on a cursory glance, it actually sounds like good content. The default behavior of LLMs is to produce plausible answers even when no plausible answer exists. LLMs are not great at saying I don't know.\n",
|
||||
"\n",
|
||||
"Retrieval augmented generation (RAG) helps reduce the risk of hallucinations by limiting the context in which a LLM can generate answers. This is typically done with a vector search query that hydrates a prompt with a relevant context. RAG is one of the most practical and production-ready use cases for *Generative AI*. It's so popular now, that some are creating their entire companies around it.\n",
|
||||
"\n",
|
||||
"[txtai](https://github.com/neuml/txtai) has long had question-answering pipelines, which employ the same process of retrieving a relevant context. LLMs are now the preferred approach for analyzing that context and RAG pipelines are one of the main features of txtai. One of the other main features of txtai is that it's a vector database! You can build your prompts and limit your context all with one library. Hence the phrase *all-in-one embeddings database*.\n",
|
||||
"[txtai](https://github.com/neuml/txtai) has long had question-answering pipelines, which employ the same process of retrieving a relevant context. LLMs are now the preferred approach for analyzing that context and RAG pipelines are one of the main features of txtai. One of the other main features of txtai is that it's a vector database! You can build your prompts and limit your context all with one library. Hence the phrase *all-in-one AI framework*.\n",
|
||||
"\n",
|
||||
"This notebook shows how to build RAG pipelines with txtai."
|
||||
],
|
||||
"metadata": {
|
||||
"id": "VGeVB8M41jqW"
|
||||
}
|
||||
]
|
||||
},
|
||||
{
|
||||
"cell_type": "markdown",
|
||||
"metadata": {
|
||||
"id": "ZQrHIw351lwE"
|
||||
},
|
||||
"source": [
|
||||
"# Install dependencies\n",
|
||||
"\n",
|
||||
"Install `txtai` and all dependencies. Since this notebook is using optional pipelines, we need to install the pipeline extras package."
|
||||
],
|
||||
"metadata": {
|
||||
"id": "ZQrHIw351lwE"
|
||||
}
|
||||
]
|
||||
},
|
||||
{
|
||||
"cell_type": "code",
|
||||
"execution_count": 1,
|
||||
"execution_count": null,
|
||||
"metadata": {
|
||||
"id": "R0AqRP7v1hdr"
|
||||
},
|
||||
"outputs": [],
|
||||
"source": [
|
||||
"%%capture\n",
|
||||
"!pip install git+https://github.com/neuml/txtai#egg=txtai[pipeline] autoawq\n",
|
||||
"!pip install git+https://github.com/neuml/txtai#egg=txtai[pipeline]\n",
|
||||
"\n",
|
||||
"# Get test data\n",
|
||||
"!wget -N https://github.com/neuml/txtai/releases/download/v6.2.0/tests.tar.gz\n",
|
||||
@@ -68,50 +52,43 @@
|
||||
},
|
||||
{
|
||||
"cell_type": "markdown",
|
||||
"metadata": {
|
||||
"id": "xmPN8RDF1pXd"
|
||||
},
|
||||
"source": [
|
||||
"# Start with the basics\n",
|
||||
"\n",
|
||||
"Let's jump right in and start with a simple LLM pipeline. The [LLM pipeline](https://neuml.github.io/txtai/pipeline/text/llm/) supports loading local LLM models from the [Hugging Face Hub](https://huggingface.co/models).\n",
|
||||
"Let's jump right in and start with a simple LLM pipeline. The [LLM pipeline](https://neuml.github.io/txtai/pipeline/text/llm/) supports local LLM models via [Hugging Face Transformers](https://github.com/huggingface/transformers) and [llama.cpp](https://github.com/abetlen/llama-cpp-python).\n",
|
||||
"\n",
|
||||
"For those using LLM API services (OpenAI, Cohere, etc), this call can easily be replaced with an API call."
|
||||
],
|
||||
"metadata": {
|
||||
"id": "xmPN8RDF1pXd"
|
||||
}
|
||||
"The LLM pipeline also supports [API services (i.e. OpenAI, Claude, Bedrock etc) via LiteLLM](https://github.com/BerriAI/litellm). The LLM pipeline automatically detects the underlying LLM framework from the `path` parameter.\n"
|
||||
]
|
||||
},
|
||||
{
|
||||
"cell_type": "code",
|
||||
"execution_count": 1,
|
||||
"metadata": {
|
||||
"id": "XZ7vPBIs1rGZ"
|
||||
},
|
||||
"outputs": [],
|
||||
"source": [
|
||||
"from txtai import LLM\n",
|
||||
"\n",
|
||||
"# Create LLM\n",
|
||||
"llm = LLM(\"TheBloke/Mistral-7B-OpenOrca-AWQ\")"
|
||||
],
|
||||
"metadata": {
|
||||
"id": "XZ7vPBIs1rGZ"
|
||||
},
|
||||
"execution_count": 21,
|
||||
"outputs": []
|
||||
"llm = LLM(\"Qwen/Qwen3-4B-Instruct-2507\")"
|
||||
]
|
||||
},
|
||||
{
|
||||
"cell_type": "markdown",
|
||||
"source": [
|
||||
"Next, we'll load a document to query. The [Textractor pipeline](https://neuml.github.io/txtai/pipeline/data/textractor/) has support for extracting text from common document formats (docx, pdf, xlsx)."
|
||||
],
|
||||
"metadata": {
|
||||
"id": "9rmTWMxAH3Vx"
|
||||
}
|
||||
},
|
||||
"source": [
|
||||
"Next, we'll load a document to query. The [Textractor pipeline](https://neuml.github.io/txtai/pipeline/data/textractor/) has support for extracting text from common document formats (docx, pdf, xlsx, web)."
|
||||
]
|
||||
},
|
||||
{
|
||||
"cell_type": "code",
|
||||
"source": [
|
||||
"from txtai.pipeline import Textractor\n",
|
||||
"\n",
|
||||
"# Create Textractor\n",
|
||||
"textractor = Textractor()\n",
|
||||
"text = textractor(\"txtai/document.docx\")\n",
|
||||
"print(text)"
|
||||
],
|
||||
"execution_count": null,
|
||||
"metadata": {
|
||||
"colab": {
|
||||
"base_uri": "https://localhost:8080/"
|
||||
@@ -119,24 +96,24 @@
|
||||
"id": "nifStGtOHuyc",
|
||||
"outputId": "5a4010e0-75f9-4095-a24c-cd4c859847d0"
|
||||
},
|
||||
"execution_count": 22,
|
||||
"outputs": [
|
||||
{
|
||||
"output_type": "stream",
|
||||
"name": "stdout",
|
||||
"output_type": "stream",
|
||||
"text": [
|
||||
"txtai – the all-in-one embeddings database\n",
|
||||
"# txtai – the all-in-one embeddings database\n",
|
||||
"txtai is an all-in-one embeddings database for semantic search, LLM orchestration and language model workflows.\n",
|
||||
"\n",
|
||||
"Summary of txtai features:\n",
|
||||
"· Vector search with SQL, object storage, topic modeling\n",
|
||||
"· Create embeddings for text, documents, audio, images and video\n",
|
||||
"· Pipelines powered by language models that run LLM prompts\n",
|
||||
"· Workflows to join pipelines together and aggregate business logic\n",
|
||||
"· Build with Python or YAML. API bindings available for JavaScript, Java, Rust and Go.\n",
|
||||
"· Run local or scale out with container orchestration\n",
|
||||
"· *Vector search* with SQL, object storage, topic modeling\n",
|
||||
"· Create *embeddings* for text, documents, audio, images and video\n",
|
||||
"· *Pipelines* powered by language models that run LLM prompts\n",
|
||||
"· *Workflows* to join pipelines together and aggregate business logic\n",
|
||||
"· Build with *Python* or *YAML* . API bindings available for JavaScript, Java, Rust and Go.\n",
|
||||
"· *Run local or scale out with container orchestration* \n",
|
||||
"\n",
|
||||
"Examples\n",
|
||||
"\n",
|
||||
"## Examples\n",
|
||||
"List of example notebooks.\n",
|
||||
"|Notebook|Description|\n",
|
||||
"|---|---|\n",
|
||||
@@ -145,16 +122,17 @@
|
||||
"|Build a QA database|Question matching with semantic search|\n",
|
||||
"|Semantic Graphs|Explore topics, data connectivity and run network analysis|\n",
|
||||
"\n",
|
||||
"Install\n",
|
||||
"## Install\n",
|
||||
"The easiest way to install is via pip and PyPI\n",
|
||||
"pip install txtai\n",
|
||||
"Python 3.9+ is supported. Using a Python virtual environment is recommended.\n",
|
||||
"Python 3.11+ is supported. Using a Python virtual environment is **recommended** .\n",
|
||||
"See the detailed install instructions for more information covering optional dependencies, environment specific prerequisites, installing from source, conda support and how to run with containers.\n",
|
||||
"\n",
|
||||
"\n",
|
||||
"\n",
|
||||
"\n",
|
||||
"Model guide\n",
|
||||
"\n",
|
||||
"## Model guide\n",
|
||||
"The following shows a list of suggested models.\n",
|
||||
"|Component|Model(s)|\n",
|
||||
"|---|---|\n",
|
||||
@@ -171,35 +149,28 @@
|
||||
"|Translation|OPUS Model Series|\n"
|
||||
]
|
||||
}
|
||||
],
|
||||
"source": [
|
||||
"from txtai import Textractor\n",
|
||||
"\n",
|
||||
"# Create Textractor\n",
|
||||
"textractor = Textractor()\n",
|
||||
"text = textractor(\"txtai/document.docx\")\n",
|
||||
"print(text)"
|
||||
]
|
||||
},
|
||||
{
|
||||
"cell_type": "markdown",
|
||||
"source": [
|
||||
"Now we'll define a simple LLM pipeline. It takes a question and context (which in this case is the whole file), creates a prompt and runs it with the LLM."
|
||||
],
|
||||
"metadata": {
|
||||
"id": "2jkamwgdIgEp"
|
||||
}
|
||||
},
|
||||
"source": [
|
||||
"Now we'll define a simple LLM pipeline. It takes a question and context (which in this case is the whole file), creates a prompt and runs it with the LLM."
|
||||
]
|
||||
},
|
||||
{
|
||||
"cell_type": "code",
|
||||
"source": [
|
||||
"def execute(question, text):\n",
|
||||
" prompt = f\"\"\"<|im_start|>system\n",
|
||||
" You are a friendly assistant. You answer questions from users.<|im_end|>\n",
|
||||
" <|im_start|>user\n",
|
||||
" Answer the following question using only the context below. Only include information specifically discussed.\n",
|
||||
"\n",
|
||||
" question: {question}\n",
|
||||
" context: {text} <|im_end|>\n",
|
||||
" <|im_start|>assistant\n",
|
||||
" \"\"\"\n",
|
||||
"\n",
|
||||
" return llm(prompt, maxlength=4096, pad_token_id=32000)\n",
|
||||
"\n",
|
||||
"execute(\"Tell me about txtai in one sentence\", text)"
|
||||
],
|
||||
"execution_count": 18,
|
||||
"metadata": {
|
||||
"colab": {
|
||||
"base_uri": "https://localhost:8080/",
|
||||
@@ -208,28 +179,36 @@
|
||||
"id": "9HU6C0OIIAKn",
|
||||
"outputId": "f9d556c4-cd7a-4774-ef62-1f3fff90aa47"
|
||||
},
|
||||
"execution_count": 23,
|
||||
"outputs": [
|
||||
{
|
||||
"output_type": "execute_result",
|
||||
"data": {
|
||||
"text/plain": [
|
||||
"'Txtai is an all-in-one embeddings database for semantic search, LLM orchestration, and language model workflows, offering features such as vector search, pipeline creation, workflow management, and API bindings for various programming languages.'"
|
||||
],
|
||||
"application/vnd.google.colaboratory.intrinsic+json": {
|
||||
"type": "string"
|
||||
}
|
||||
"'txtai is an all-in-one embeddings database that supports semantic search, LLM orchestration, and language model workflows with features like vector search, embeddings for text, audio, images, and video, pipelines powered by language models, and scalable workflows available via Python or YAML with API bindings for multiple languages.'"
|
||||
]
|
||||
},
|
||||
"execution_count": 18,
|
||||
"metadata": {},
|
||||
"execution_count": 23
|
||||
"output_type": "execute_result"
|
||||
}
|
||||
],
|
||||
"source": [
|
||||
"def execute(question, text):\n",
|
||||
" return llm([\n",
|
||||
" {\"role\": \"system\", \"content\": \"You are a friendly assistant. You answer questions from users.\"},\n",
|
||||
" {\"role\": \"user\", \"content\": f\"\"\"\n",
|
||||
" Answer the following question using only the context below. Only include information specifically discussed.\n",
|
||||
"\n",
|
||||
" question: {question}\n",
|
||||
" context: {text} \n",
|
||||
" \"\"\"}\n",
|
||||
" ], maxlength=4096)\n",
|
||||
"\n",
|
||||
"execute(\"Tell me about txtai in one sentence\", text)"
|
||||
]
|
||||
},
|
||||
{
|
||||
"cell_type": "code",
|
||||
"source": [
|
||||
"execute(\"What model does txtai recommend for transcription?\", text)"
|
||||
],
|
||||
"execution_count": 19,
|
||||
"metadata": {
|
||||
"colab": {
|
||||
"base_uri": "https://localhost:8080/",
|
||||
@@ -238,28 +217,25 @@
|
||||
"id": "xxF7ajCPJP5_",
|
||||
"outputId": "0e6f6dbb-c784-4841-fe3f-82754ef478eb"
|
||||
},
|
||||
"execution_count": 24,
|
||||
"outputs": [
|
||||
{
|
||||
"output_type": "execute_result",
|
||||
"data": {
|
||||
"text/plain": [
|
||||
"'The model that txtai recommends for transcription is Whisper.'"
|
||||
],
|
||||
"application/vnd.google.colaboratory.intrinsic+json": {
|
||||
"type": "string"
|
||||
}
|
||||
"'txtai recommends using Whisper for transcription.'"
|
||||
]
|
||||
},
|
||||
"execution_count": 19,
|
||||
"metadata": {},
|
||||
"execution_count": 24
|
||||
"output_type": "execute_result"
|
||||
}
|
||||
],
|
||||
"source": [
|
||||
"execute(\"What model does txtai recommend for transcription?\", text)"
|
||||
]
|
||||
},
|
||||
{
|
||||
"cell_type": "code",
|
||||
"source": [
|
||||
"execute(\"I don't know anything about txtai, what would be the best thing to read?\", text)"
|
||||
],
|
||||
"execution_count": 20,
|
||||
"metadata": {
|
||||
"colab": {
|
||||
"base_uri": "https://localhost:8080/",
|
||||
@@ -268,36 +244,38 @@
|
||||
"id": "AKmmTqsnJa5X",
|
||||
"outputId": "834bf3ee-b7ed-4e38-e2ef-d5950f99ed9a"
|
||||
},
|
||||
"execution_count": 25,
|
||||
"outputs": [
|
||||
{
|
||||
"output_type": "execute_result",
|
||||
"data": {
|
||||
"text/plain": [
|
||||
"'The best thing to read to learn about txtai is the \"Introducing txtai\" notebook, which provides an overview of the functionality provided by txtai. This notebook covers various features such as vector search with SQL, object storage, topic modeling, creating embeddings for text, documents, audio, images, and video, and running language model workflows. Additionally, you can explore other example notebooks like \"Similarity search with images,\" \"Build a QA database,\" and \"Semantic Graphs\" to learn more about specific use cases and features. To install txtai, use pip and PyPI with Python 3.9+, and follow the detailed install instructions for more information on optional dependencies and environment-specific prerequisites.'"
|
||||
],
|
||||
"application/vnd.google.colaboratory.intrinsic+json": {
|
||||
"type": "string"
|
||||
}
|
||||
"'The best thing to read if you don\\'t know anything about txtai would be the \"Introducing txtai\" notebook, as it provides an overview of the functionality offered by txtai.'"
|
||||
]
|
||||
},
|
||||
"execution_count": 20,
|
||||
"metadata": {},
|
||||
"execution_count": 25
|
||||
"output_type": "execute_result"
|
||||
}
|
||||
],
|
||||
"source": [
|
||||
"execute(\"I don't know anything about txtai, what would be the best thing to read?\", text)"
|
||||
]
|
||||
},
|
||||
{
|
||||
"cell_type": "markdown",
|
||||
"metadata": {
|
||||
"id": "WaVeEHrIMpFr"
|
||||
},
|
||||
"source": [
|
||||
"If this is the first time you've seen *Generative AI*, then these statements are 🤯. Even if you've been in the space a while, it's still amazing how much a language model can understand and the high level of quality in it's answers.\n",
|
||||
"\n",
|
||||
"While this use case is fun, lets try to scale it to a larger set of documents."
|
||||
],
|
||||
"metadata": {
|
||||
"id": "WaVeEHrIMpFr"
|
||||
}
|
||||
]
|
||||
},
|
||||
{
|
||||
"cell_type": "markdown",
|
||||
"metadata": {
|
||||
"id": "viVVft59NbKv"
|
||||
},
|
||||
"source": [
|
||||
"# Build a RAG pipeline with vector search\n",
|
||||
"\n",
|
||||
@@ -308,13 +286,30 @@
|
||||
"Typically, this candidate query uses vector search but it can be anything that runs a search and returns results. In fact, many complex production systems have customized retrieval pipelines that feed a context into LLM prompts.\n",
|
||||
"\n",
|
||||
"The first step in building our RAG pipeline is creating the knowledge store. In this case, it's a vector database of file content. The files will be split into paragraphs with each paragraph stored as a separate row."
|
||||
],
|
||||
"metadata": {
|
||||
"id": "viVVft59NbKv"
|
||||
}
|
||||
]
|
||||
},
|
||||
{
|
||||
"cell_type": "code",
|
||||
"execution_count": null,
|
||||
"metadata": {
|
||||
"colab": {
|
||||
"base_uri": "https://localhost:8080/"
|
||||
},
|
||||
"id": "ipmsmtN1NahT",
|
||||
"outputId": "64733e1f-fb7b-4a2d-bf02-8930478a8ee8"
|
||||
},
|
||||
"outputs": [
|
||||
{
|
||||
"name": "stdout",
|
||||
"output_type": "stream",
|
||||
"text": [
|
||||
"Indexing txtai/article.pdf\n",
|
||||
"Indexing txtai/document.docx\n",
|
||||
"Indexing txtai/document.pdf\n",
|
||||
"Indexing txtai/spreadsheet.xlsx\n"
|
||||
]
|
||||
}
|
||||
],
|
||||
"source": [
|
||||
"import os\n",
|
||||
"\n",
|
||||
@@ -336,39 +331,40 @@
|
||||
"# Vector Database\n",
|
||||
"embeddings = Embeddings(content=True)\n",
|
||||
"embeddings.index(stream(\"txtai\"))"
|
||||
],
|
||||
"metadata": {
|
||||
"colab": {
|
||||
"base_uri": "https://localhost:8080/"
|
||||
},
|
||||
"id": "ipmsmtN1NahT",
|
||||
"outputId": "64733e1f-fb7b-4a2d-bf02-8930478a8ee8"
|
||||
},
|
||||
"execution_count": 26,
|
||||
"outputs": [
|
||||
{
|
||||
"output_type": "stream",
|
||||
"name": "stdout",
|
||||
"text": [
|
||||
"Indexing txtai/article.pdf\n",
|
||||
"Indexing txtai/document.docx\n",
|
||||
"Indexing txtai/document.pdf\n",
|
||||
"Indexing txtai/spreadsheet.xlsx\n"
|
||||
]
|
||||
}
|
||||
]
|
||||
},
|
||||
{
|
||||
"cell_type": "markdown",
|
||||
"source": [
|
||||
"The next step is defining the RAG pipeline. This pipeline takes the input question, runs a vector search and builds a context using the search results. The context is then inserted into a prompt template and run with the LLM."
|
||||
],
|
||||
"metadata": {
|
||||
"id": "ASlmAaR3nBPN"
|
||||
}
|
||||
},
|
||||
"source": [
|
||||
"The next step is defining the RAG pipeline. This pipeline takes the input question, runs a vector search and builds a context using the search results. The context is then inserted into a prompt template and run with the LLM."
|
||||
]
|
||||
},
|
||||
{
|
||||
"cell_type": "code",
|
||||
"execution_count": 23,
|
||||
"metadata": {
|
||||
"colab": {
|
||||
"base_uri": "https://localhost:8080/",
|
||||
"height": 39
|
||||
},
|
||||
"id": "_-9SW6r4P5ha",
|
||||
"outputId": "6a7bcd69-bcd0-4f6e-81c1-e32c323b3ffb"
|
||||
},
|
||||
"outputs": [
|
||||
{
|
||||
"data": {
|
||||
"text/plain": [
|
||||
"'txtai recommends using BLIP for image captioning.'"
|
||||
]
|
||||
},
|
||||
"execution_count": 23,
|
||||
"metadata": {},
|
||||
"output_type": "execute_result"
|
||||
}
|
||||
],
|
||||
"source": [
|
||||
"def context(question):\n",
|
||||
" context = \"\\n\".join(x[\"text\"] for x in embeddings.search(question))\n",
|
||||
@@ -378,38 +374,11 @@
|
||||
" return execute(question, context(question))\n",
|
||||
"\n",
|
||||
"rag(\"What model does txtai recommend for image captioning?\")"
|
||||
],
|
||||
"metadata": {
|
||||
"colab": {
|
||||
"base_uri": "https://localhost:8080/",
|
||||
"height": 39
|
||||
},
|
||||
"id": "_-9SW6r4P5ha",
|
||||
"outputId": "6a7bcd69-bcd0-4f6e-81c1-e32c323b3ffb"
|
||||
},
|
||||
"execution_count": 27,
|
||||
"outputs": [
|
||||
{
|
||||
"output_type": "execute_result",
|
||||
"data": {
|
||||
"text/plain": [
|
||||
"'Based on the provided context, txtai recommends the model \"BLIP\" for image captioning.'"
|
||||
],
|
||||
"application/vnd.google.colaboratory.intrinsic+json": {
|
||||
"type": "string"
|
||||
}
|
||||
},
|
||||
"metadata": {},
|
||||
"execution_count": 27
|
||||
}
|
||||
]
|
||||
},
|
||||
{
|
||||
"cell_type": "code",
|
||||
"source": [
|
||||
"result = rag(\"When was the BLIP model added for image captioning?\")\n",
|
||||
"print(result)"
|
||||
],
|
||||
"execution_count": 24,
|
||||
"metadata": {
|
||||
"colab": {
|
||||
"base_uri": "https://localhost:8080/"
|
||||
@@ -417,47 +386,47 @@
|
||||
"id": "NbQhSunPQtB0",
|
||||
"outputId": "de0caf04-4cdb-48e8-aadf-37283be9909a"
|
||||
},
|
||||
"execution_count": 28,
|
||||
"outputs": [
|
||||
{
|
||||
"output_type": "stream",
|
||||
"name": "stdout",
|
||||
"output_type": "stream",
|
||||
"text": [
|
||||
"The BLIP model was added for image captioning on 2022-03-17.\n"
|
||||
]
|
||||
}
|
||||
],
|
||||
"source": [
|
||||
"result = rag(\"When was the BLIP model added for image captioning?\")\n",
|
||||
"print(result)"
|
||||
]
|
||||
},
|
||||
{
|
||||
"cell_type": "markdown",
|
||||
"metadata": {
|
||||
"id": "D6HW-3GtnTFl"
|
||||
},
|
||||
"source": [
|
||||
"As we can see, the result is similar to what we had before without vector search. The difference is that we only used a relevant portion of the documents to generate the answer.\n",
|
||||
"\n",
|
||||
"As we discussed before, this is important when dealing with large volumes of data. Not all of the data can be added to a LLM prompt. Additionally, having only the most relevant context helps the LLM generate higher quality answers."
|
||||
],
|
||||
"metadata": {
|
||||
"id": "D6HW-3GtnTFl"
|
||||
}
|
||||
]
|
||||
},
|
||||
{
|
||||
"cell_type": "markdown",
|
||||
"metadata": {
|
||||
"id": "FZ-yPC-xiUqa"
|
||||
},
|
||||
"source": [
|
||||
"# Citations for LLMs\n",
|
||||
"\n",
|
||||
"A healthy level of skepticism should be applied to answers generated by AI. We're far from the day where we can blindly trust answers from an AI model.\n",
|
||||
"\n",
|
||||
"txtai has a couple approaches for generating citations. The basic approach is to take the answer and search the vector database for the closest match."
|
||||
],
|
||||
"metadata": {
|
||||
"id": "FZ-yPC-xiUqa"
|
||||
}
|
||||
]
|
||||
},
|
||||
{
|
||||
"cell_type": "code",
|
||||
"source": [
|
||||
"for x in embeddings.search(result):\n",
|
||||
" print(x[\"text\"])"
|
||||
],
|
||||
"execution_count": 25,
|
||||
"metadata": {
|
||||
"colab": {
|
||||
"base_uri": "https://localhost:8080/"
|
||||
@@ -465,16 +434,15 @@
|
||||
"id": "obttSg_dSFT5",
|
||||
"outputId": "c7ae7675-6959-4bcb-ad06-065ea8609c31"
|
||||
},
|
||||
"execution_count": 29,
|
||||
"outputs": [
|
||||
{
|
||||
"output_type": "stream",
|
||||
"name": "stdout",
|
||||
"output_type": "stream",
|
||||
"text": [
|
||||
"E5-base-v2\n",
|
||||
"Image Captions BLIP\n",
|
||||
"Labels - Zero Shot BART-Large-MNLI\n",
|
||||
"Model Guide\n",
|
||||
"# Model Guide\n",
|
||||
"|Component |Model(s)|Date Added|\n",
|
||||
"|---|---|---|\n",
|
||||
"|Embeddings |all-MiniLM-L6-v2|2022-04-15|\n",
|
||||
@@ -486,66 +454,65 @@
|
||||
"|Transcription |Whisper|2022-08-01|\n",
|
||||
"|Translation |OPUS Model Series|2021-04-06|\n",
|
||||
"&\"Times New Roman,Regular\"&12&A\n",
|
||||
"Notebook Description\n",
|
||||
"Introducing txtai Overview of the functionality provided by txtai\n",
|
||||
"Similarity search with \n",
|
||||
"images Embed images and text into the same space for search\n"
|
||||
"## Model guide\n",
|
||||
"The following shows a list of suggested models.\n",
|
||||
"|Component|Model(s)|\n",
|
||||
"|---|---|\n",
|
||||
"|Embeddings|all-MiniLM-L6-v2|\n",
|
||||
"||E5-base-v2|\n",
|
||||
"|Image Captions|BLIP|\n",
|
||||
"|Labels - Zero Shot|BART-Large-MNLI|\n",
|
||||
"|Labels - Fixed|Fine-tune with training pipeline|\n",
|
||||
"|Large Language Model (LLM)|Flan T5 XL|\n",
|
||||
"||Mistral 7B OpenOrca|\n",
|
||||
"|Summarization|DistilBART|\n",
|
||||
"|Text-to-Speech|ESPnet JETS|\n",
|
||||
"|Transcription|Whisper|\n",
|
||||
"|Translation|OPUS Model Series|\n"
|
||||
]
|
||||
}
|
||||
],
|
||||
"source": [
|
||||
"for x in embeddings.search(result):\n",
|
||||
" print(x[\"text\"])"
|
||||
]
|
||||
},
|
||||
{
|
||||
"cell_type": "markdown",
|
||||
"metadata": {
|
||||
"id": "MDcB7GCWY6TO"
|
||||
},
|
||||
"source": [
|
||||
"While the basic approach above works in this case, txtai has a more robust pipeline to handle citations and references.\n",
|
||||
"\n",
|
||||
"The RAG pipeline is defined below. A RAG pipeline works in the same way as a LLM + Vector Search pipeline, except it has special logic for generating citations. This pipeline takes the answers and compares it to the context passed to the LLM to determine the most likely reference."
|
||||
],
|
||||
"metadata": {
|
||||
"id": "MDcB7GCWY6TO"
|
||||
}
|
||||
]
|
||||
},
|
||||
{
|
||||
"cell_type": "code",
|
||||
"source": [
|
||||
"from txtai import RAG\n",
|
||||
"\n",
|
||||
"# RAG prompt\n",
|
||||
"def prompt(question):\n",
|
||||
" return [{\n",
|
||||
" \"query\": question,\n",
|
||||
" \"question\": f\"\"\"\n",
|
||||
"Answer the following question using only the context below. Only include information specifically discussed.\n",
|
||||
"\n",
|
||||
"question: {question}\n",
|
||||
"context:\n",
|
||||
"\"\"\"\n",
|
||||
"}]\n",
|
||||
"\n",
|
||||
"# Create LLM with system prompt template\n",
|
||||
"llm = LLM(\"TheBloke/Mistral-7B-OpenOrca-AWQ\", template=\"\"\"<|im_start|>system\n",
|
||||
"You are a friendly assistant. You answer questions from users.<|im_end|>\n",
|
||||
"<|im_start|>user\n",
|
||||
"{text} <|im_end|>\n",
|
||||
"<|im_start|>assistant\n",
|
||||
"\"\"\")\n",
|
||||
"\n",
|
||||
"# Create RAG instance\n",
|
||||
"rag = RAG(embeddings, llm, output=\"reference\")"
|
||||
],
|
||||
"execution_count": 26,
|
||||
"metadata": {
|
||||
"id": "Lm6gg85_Y7ot"
|
||||
},
|
||||
"execution_count": null,
|
||||
"outputs": []
|
||||
"outputs": [],
|
||||
"source": [
|
||||
"from txtai import RAG\n",
|
||||
"\n",
|
||||
"# Create the RAG pipeline\n",
|
||||
"rag = RAG(embeddings, \"Qwen/Qwen3-4B-Instruct-2507\", template=\"\"\"\n",
|
||||
" Answer the following question using the provided context.\n",
|
||||
"\n",
|
||||
" Question:\n",
|
||||
" {question}\n",
|
||||
"\n",
|
||||
" Context:\n",
|
||||
" {context}\n",
|
||||
"\"\"\", output=\"reference\")"
|
||||
]
|
||||
},
|
||||
{
|
||||
"cell_type": "code",
|
||||
"source": [
|
||||
"result = rag(prompt(\"What version of Python is supported?\"), maxlength=4096, pad_token_id=32000)[0]\n",
|
||||
"print(\"ANSWER:\", result[\"answer\"])\n",
|
||||
"print(\"CITATION:\", embeddings.search(\"select id, text from txtai where id = :id\", limit=1, parameters={\"id\": result[\"reference\"]}))"
|
||||
],
|
||||
"execution_count": 27,
|
||||
"metadata": {
|
||||
"colab": {
|
||||
"base_uri": "https://localhost:8080/"
|
||||
@@ -553,29 +520,36 @@
|
||||
"id": "4pOfE5paZatH",
|
||||
"outputId": "2bed2de5-22ff-4f7b-dba5-41b8e4cc6c75"
|
||||
},
|
||||
"execution_count": 31,
|
||||
"outputs": [
|
||||
{
|
||||
"output_type": "stream",
|
||||
"name": "stdout",
|
||||
"output_type": "stream",
|
||||
"text": [
|
||||
"ANSWER: Python 3.9+ is supported. Using a Python virtual environment is recommended. The easiest way to install is via pip and PyPI.\n",
|
||||
"CITATION: [{'id': '24', 'text': 'Python 3.9+ is supported. Using a Python virtual environment is recommended.'}]\n"
|
||||
"ANSWER: Python 3.11 and later versions (Python 3.11+) are supported.\n",
|
||||
"CITATION: [{'id': '24', 'text': 'Python 3.11+ is supported. Using a Python virtual environment is recommended.'}]\n"
|
||||
]
|
||||
}
|
||||
],
|
||||
"source": [
|
||||
"result = rag(\"What version of Python is supported?\", maxlength=4096)\n",
|
||||
"print(\"ANSWER:\", result[\"answer\"])\n",
|
||||
"print(\"CITATION:\", embeddings.search(\"select id, text from txtai where id = :id\", limit=1, parameters={\"id\": result[\"reference\"]}))"
|
||||
]
|
||||
},
|
||||
{
|
||||
"cell_type": "markdown",
|
||||
"source": [
|
||||
"And as we can see, not only is the answer to the statement shown, the RAG pipeline also provides a citation. This step is crucial in any line of work where answers must be verified (which is most lines of work)."
|
||||
],
|
||||
"metadata": {
|
||||
"id": "vHdE2Q59jNnF"
|
||||
}
|
||||
},
|
||||
"source": [
|
||||
"And as we can see, not only is the answer to the statement shown, the RAG pipeline also provides a citation. This step is crucial in any line of work where answers must be verified (which is most lines of work)."
|
||||
]
|
||||
},
|
||||
{
|
||||
"cell_type": "markdown",
|
||||
"metadata": {
|
||||
"id": "oPwgCgBc2Er2"
|
||||
},
|
||||
"source": [
|
||||
"# Wrapping up\n",
|
||||
"\n",
|
||||
@@ -583,13 +557,36 @@
|
||||
"\n",
|
||||
"The advantages of building RAG pipelines with txtai are:\n",
|
||||
"\n",
|
||||
"- **All-in-one database** - one library can handle LLM inference and vector search retrieval\n",
|
||||
"- **All-in-one AI framework** - one library can handle LLM inference and vector search retrieval\n",
|
||||
"- **Generating citations** - generating answers is useful but referencing where those answers came from is crucial in gaining the trust of users\n",
|
||||
"- **Simple yet powerful** - building pipelines can be done in a small amount of Python. Options are available to build pipelines in YAML and/or run through the API"
|
||||
],
|
||||
"metadata": {
|
||||
"id": "oPwgCgBc2Er2"
|
||||
}
|
||||
]
|
||||
}
|
||||
]
|
||||
],
|
||||
"metadata": {
|
||||
"accelerator": "GPU",
|
||||
"colab": {
|
||||
"gpuType": "T4",
|
||||
"provenance": []
|
||||
},
|
||||
"kernelspec": {
|
||||
"display_name": "local",
|
||||
"language": "python",
|
||||
"name": "python3"
|
||||
},
|
||||
"language_info": {
|
||||
"codemirror_mode": {
|
||||
"name": "ipython",
|
||||
"version": 3
|
||||
},
|
||||
"file_extension": ".py",
|
||||
"mimetype": "text/x-python",
|
||||
"name": "python",
|
||||
"nbconvert_exporter": "python",
|
||||
"pygments_lexer": "ipython3",
|
||||
"version": "3.10.19"
|
||||
}
|
||||
},
|
||||
"nbformat": 4,
|
||||
"nbformat_minor": 0
|
||||
}
|
||||
|
||||
@@ -90,7 +90,7 @@
|
||||
"embeddings.index(data)\n",
|
||||
"\n",
|
||||
"# Create LLM with llama.cpp - GGUF file is automatically downloaded\n",
|
||||
"llm = LLM(\"TheBloke/Mistral-7B-OpenOrca-GGUF/mistral-7b-openorca.Q4_K_M.gguf\", verbose=True)\n",
|
||||
"llm = LLM(\"unsloth/Qwen3-4B-Instruct-2507-GGUF/Qwen3-4B-Instruct-2507-Q4_K_M.gguf\", verbose=True)\n",
|
||||
"\n",
|
||||
"template = \"\"\"<|im_start|>system\n",
|
||||
"You are a friendly assistant. You answer questions from users.<|im_end|>\n",
|
||||
|
||||
@@ -19,7 +19,7 @@
|
||||
"source": [
|
||||
"# API Authorization and Authentication\n",
|
||||
"\n",
|
||||
"[txtai](https://github.com/neuml/txtai) is an all-in-one embeddings database for semantic search, LLM orchestration and language model workflows. txtai can run in Python, with YAML configuration and through an API service.\n",
|
||||
"txtai can run in Python, with YAML configuration and through an API service.\n",
|
||||
"\n",
|
||||
"The default API service implementation runs without any security. This may be OK for a local prototype or if it's run on a small internal network. But in most cases, additional security measures should be taken.\n",
|
||||
"\n",
|
||||
|
||||
@@ -8,8 +8,6 @@
|
||||
"source": [
|
||||
"# Generate knowledge with Semantic Graphs and RAG\n",
|
||||
"\n",
|
||||
"[txtai](https://github.com/neuml/txtai) is an all-in-one embeddings database for semantic search, LLM orchestration and language model workflows.\n",
|
||||
"\n",
|
||||
"Embeddings databases are a union of vector indexes (sparse and dense), graph networks and relational databases. This enables vector search with SQL, topic modeling, retrieval augmented generation and more.\n",
|
||||
"\n",
|
||||
"Semantic graphs were introduced in late 2022 with txtai 5.0, right before the start of the LLM era. This notebook picks back up where that work left off, opening a new frontier in semantic graph integration."
|
||||
@@ -35,7 +33,7 @@
|
||||
"outputs": [],
|
||||
"source": [
|
||||
"%%capture\n",
|
||||
"!pip install git+https://github.com/neuml/txtai#egg=txtai[graph] autoawq"
|
||||
"!pip install git+https://github.com/neuml/txtai#egg=txtai[graph]"
|
||||
]
|
||||
},
|
||||
{
|
||||
@@ -296,7 +294,7 @@
|
||||
"outputs": [],
|
||||
"source": [
|
||||
"from txtai import LLM\n",
|
||||
"llm = LLM(\"TheBloke/Mistral-7B-OpenOrca-AWQ\")"
|
||||
"llm = LLM(\"Qwen/Qwen3-4B-Instruct-2507\")"
|
||||
]
|
||||
},
|
||||
{
|
||||
|
||||
@@ -21,8 +21,6 @@
|
||||
"source": [
|
||||
"# External vectorization\n",
|
||||
"\n",
|
||||
"[txtai](https://github.com/neuml/txtai) is an all-in-one embeddings database for semantic search, LLM orchestration and language model workflows.\n",
|
||||
"\n",
|
||||
"Vectorization is the process of transforming data into numbers using machine learning models. Input data is run through a model and fixed dimension vectors are returned. These vectors can then be loaded into a vector database for similarity search.\n",
|
||||
"\n",
|
||||
"txtai is an open-source first system. Given it's own open-source roots, like-minded projects such as [sentence-transformers](https://github.com/UKPLab/sentence-transformers) are prioritized during development. But that doesn't mean txtai can't work with Embeddings API services.\n",
|
||||
|
||||
@@ -8,8 +8,6 @@
|
||||
"source": [
|
||||
"# Build knowledge graphs with LLM-driven entity extraction\n",
|
||||
"\n",
|
||||
"[txtai](https://github.com/neuml/txtai) is an all-in-one embeddings database for semantic search, LLM orchestration and language model workflows.\n",
|
||||
"\n",
|
||||
"Embeddings databases are a union of vector indexes (sparse and dense), graph networks and relational databases. This enables vector search with SQL, topic modeling, retrieval augmented generation and more.\n",
|
||||
"\n",
|
||||
"Up until txtai 7.0, semantic graphs only supported automatic relationship detection. Now relationships can be loaded directly into a txtai database. This notebook will demonstrate how to work with this new feature."
|
||||
@@ -35,7 +33,7 @@
|
||||
"outputs": [],
|
||||
"source": [
|
||||
"%%capture\n",
|
||||
"!pip install git+https://github.com/neuml/txtai#egg=txtai[graph] autoawq"
|
||||
"!pip install git+https://github.com/neuml/txtai#egg=txtai[graph]"
|
||||
]
|
||||
},
|
||||
{
|
||||
@@ -99,7 +97,7 @@
|
||||
"from txtai import LLM\n",
|
||||
"\n",
|
||||
"# Load LLM\n",
|
||||
"llm = LLM(\"TheBloke/Mistral-7B-OpenOrca-AWQ\")\n",
|
||||
"llm = LLM(\"Qwen/Qwen3-4B-Instruct-2507\")\n",
|
||||
"\n",
|
||||
"data = []\n",
|
||||
"for result in results:\n",
|
||||
|
||||
@@ -8,8 +8,6 @@
|
||||
"source": [
|
||||
"# Advanced RAG with graph path traversal\n",
|
||||
"\n",
|
||||
"[txtai](https://github.com/neuml/txtai) is an all-in-one embeddings database for semantic search, LLM orchestration and language model workflows.\n",
|
||||
"\n",
|
||||
"Embeddings databases are a union of vector indexes (sparse and dense), graph networks and relational databases. This enables vector search with SQL, topic modeling, retrieval augmented generation (RAG) and more.\n",
|
||||
"\n",
|
||||
"A standard RAG process typically runs a single vector search query and returns the closest matches. Those matches are then passed into a LLM prompt and used to limit the context and help ensure more factually correct answers are generated. This works well with most simple cases. More complex use cases, require a more advanced approach.\n",
|
||||
@@ -37,7 +35,7 @@
|
||||
"outputs": [],
|
||||
"source": [
|
||||
"%%capture\n",
|
||||
"!pip install git+https://github.com/neuml/txtai#egg=txtai[graph] autoawq"
|
||||
"!pip install git+https://github.com/neuml/txtai#egg=txtai[graph]"
|
||||
]
|
||||
},
|
||||
{
|
||||
@@ -215,7 +213,7 @@
|
||||
"source": [
|
||||
"from txtai import LLM\n",
|
||||
"\n",
|
||||
"llm = LLM(\"TheBloke/Mistral-7B-OpenOrca-AWQ\")"
|
||||
"llm = LLM(\"Qwen/Qwen3-4B-Instruct-2507\")"
|
||||
]
|
||||
},
|
||||
{
|
||||
@@ -280,6 +278,27 @@
|
||||
"print(rag(\"Write a book covering the end of Roman Britain, Saxons, Vikings and Norman conquest of England\", context))\n"
|
||||
]
|
||||
},
|
||||
{
|
||||
"cell_type": "markdown",
|
||||
"metadata": {},
|
||||
"source": [
|
||||
"_It's important to note that txtai has multiple ways to run LLM inference. In the past, prior to \"Chat Templates\", it was expected that the submitted text had all the required chat tokens embedded. The same prompt above can also be written with chat messages. This is especially important when working with LLM APIs (i.e. OpenAI, Claude, Bedrock etc)._\n",
|
||||
"\n",
|
||||
"```python\n",
|
||||
"llm([\n",
|
||||
" {\"role\": \"system\": \"You are a friendly assistant. You answer questions from users.\"}\n",
|
||||
" {\"role\": \"user\", \"content\": f\"\"\"\n",
|
||||
" Answer the following question using only the context below. Only include information specifically discussed.\n",
|
||||
"\n",
|
||||
" question: {question}\n",
|
||||
" context: {text} \n",
|
||||
" \"\"\"}\n",
|
||||
"])\n",
|
||||
"```\n",
|
||||
"\n",
|
||||
"_See the [LLM pipeline documentation](https://neuml.github.io/txtai/pipeline/text/llm/) for more information._"
|
||||
]
|
||||
},
|
||||
{
|
||||
"cell_type": "markdown",
|
||||
"metadata": {
|
||||
|
||||
@@ -54,7 +54,7 @@
|
||||
"outputs": [],
|
||||
"source": [
|
||||
"%%capture\n",
|
||||
"!pip install git+https://github.com/neuml/txtai#egg=txtai[api,graph,pipeline-train] datasets autoawq"
|
||||
"!pip install git+https://github.com/neuml/txtai#egg=txtai[api,graph,pipeline-train] datasets"
|
||||
]
|
||||
},
|
||||
{
|
||||
@@ -244,7 +244,7 @@
|
||||
"source": [
|
||||
"from txtai import LLM\n",
|
||||
"\n",
|
||||
"llm = LLM(\"TheBloke/Mistral-7B-OpenOrca-AWQ\")\n",
|
||||
"llm = LLM(\"Qwen/Qwen3-4B-Instruct-2507\")\n",
|
||||
"\n",
|
||||
"def rag(question, text):\n",
|
||||
" prompt = f\"\"\"<|im_start|>system\n",
|
||||
|
||||
@@ -8,8 +8,6 @@
|
||||
"source": [
|
||||
"# Advanced RAG with guided generation\n",
|
||||
"\n",
|
||||
"[txtai](https://github.com/neuml/txtai) is an all-in-one embeddings database for semantic search, LLM orchestration and language model workflows.\n",
|
||||
"\n",
|
||||
"A standard RAG process typically runs a single vector search query and returns the closest matches. Those matches are then passed into a LLM prompt and used to limit the context and help ensure more factually correct answers are generated. This works well with most simple cases. More complex use cases, require a more advanced approach.\n",
|
||||
"\n",
|
||||
"This notebook will demonstrate how constrained or guided generation can be applied to better control LLM output."
|
||||
@@ -35,7 +33,7 @@
|
||||
"outputs": [],
|
||||
"source": [
|
||||
"%%capture\n",
|
||||
"!pip install git+https://github.com/neuml/txtai#egg=txtai autoawq outlines"
|
||||
"!pip install git+https://github.com/neuml/txtai#egg=txtai outlines"
|
||||
]
|
||||
},
|
||||
{
|
||||
@@ -59,7 +57,7 @@
|
||||
"source": [
|
||||
"from txtai import LLM\n",
|
||||
"\n",
|
||||
"llm = LLM(\"TheBloke/Mistral-7B-OpenOrca-AWQ\")\n",
|
||||
"llm = LLM(\"Qwen/Qwen3-4B-Instruct-2507\")\n",
|
||||
"\n",
|
||||
"def rag(question, text):\n",
|
||||
" prompt = f\"\"\"<|im_start|>system\n",
|
||||
|
||||
@@ -21,8 +21,6 @@
|
||||
"source": [
|
||||
"# Integrate txtai with Postgres\n",
|
||||
"\n",
|
||||
"[txtai](https://github.com/neuml/txtai) is an all-in-one embeddings database for semantic search, LLM orchestration and language model workflows.\n",
|
||||
"\n",
|
||||
"The default persistence methods for txtai are local and file-based. `SQLite` for content, `Faiss` for vectors and `NetworkX` for graph data. The main value add of txtai is getting up and running quickly with a minimal amount of external dependencies.\n",
|
||||
"\n",
|
||||
"Another key feature of txtai is being able to quickly move from prototyping to production. This notebook will demonstrate how txtai can integrate with [Postgres](https://www.postgresql.org/), a powerful, production-ready and open source object-relational database system. After txtai persists content to Postgres, we'll show it can be directly queried with SQL from any Postgres client 🔥"
|
||||
|
||||
@@ -8,8 +8,6 @@
|
||||
"source": [
|
||||
"# RAG with llama.cpp and external API services\n",
|
||||
"\n",
|
||||
"[txtai](https://github.com/neuml/txtai) is an all-in-one embeddings database for semantic search, LLM orchestration and language model workflows.\n",
|
||||
"\n",
|
||||
"txtai has been and always will be a local-first framework. It was originally designed to run models on local hardware using Hugging Face Transformers. As the AI space has evolved over the last year, so has txtai. Additional LLM inference frameworks have been available for a while using llama.cpp and external API services (via LiteLLM). Recent changes have added the ability to use these frameworks for vectorization and made it easier to use for LLM inference.\n",
|
||||
"\n",
|
||||
"This notebook will demonstrate how to run retrieval-augmented-generation (RAG) processes (vectorization and LLM inference) with llama.cpp and external API services."
|
||||
@@ -182,7 +180,7 @@
|
||||
"from txtai import LLM\n",
|
||||
"\n",
|
||||
"# LLM instance\n",
|
||||
"llm = LLM(path=\"TheBloke/Mistral-7B-OpenOrca-GGUF/mistral-7b-openorca.Q4_K_M.gguf\")\n",
|
||||
"llm = LLM(path=\"unsloth/Qwen3-4B-Instruct-2507-GGUF/Qwen3-4B-Instruct-2507-Q4_K_M.gguf\")\n",
|
||||
"\n",
|
||||
"# Question and context\n",
|
||||
"question = \"Write a list of invented electric-powered devices\"\n",
|
||||
@@ -237,11 +235,11 @@
|
||||
"\n",
|
||||
"# Download models\n",
|
||||
"!wget https://huggingface.co/second-state/All-MiniLM-L6-v2-Embedding-GGUF/resolve/main/all-MiniLM-L6-v2-Q4_K_M.gguf\n",
|
||||
"!wget https://huggingface.co/TheBloke/Mistral-7B-OpenOrca-GGUF/resolve/main/mistral-7b-openorca.Q4_K_M.gguf\n",
|
||||
"!wget https://huggingface.co/unsloth/Qwen3-4B-Instruct-2507-GGUF/blob/main/Qwen3-4B-Instruct-2507-Q4_K_M.gguf\n",
|
||||
"\n",
|
||||
"# Start local API services\n",
|
||||
"!nohup python -m llama_cpp.server --n_gpu_layers -1 --model all-MiniLM-L6-v2-Q4_K_M.gguf --host 127.0.0.1 --port 8000 &> vector.log &\n",
|
||||
"!nohup python -m llama_cpp.server --n_gpu_layers -1 --model mistral-7b-openorca.Q4_K_M.gguf --chat_format chatml --host 127.0.0.1 --port 8001 &> llm.log &\n",
|
||||
"!nohup python -m llama_cpp.server --n_gpu_layers -1 --model Qwen3-4B-Instruct-2507-Q4_K_M.gguf --chat_format chatml --host 127.0.0.1 --port 8001 &> llm.log &\n",
|
||||
"!sleep 30"
|
||||
]
|
||||
},
|
||||
|
||||
@@ -8,8 +8,6 @@
|
||||
"source": [
|
||||
"# How RAG with txtai works\n",
|
||||
"\n",
|
||||
"[txtai](https://github.com/neuml/txtai) is an all-in-one embeddings database for semantic search, LLM orchestration and language model workflows.\n",
|
||||
"\n",
|
||||
"Large Language Models (LLMs) have captured the public's attention with their impressive capabilities. The Generative AI era has reached a fever pitch with some predicting the coming rise of superintelligence.\n",
|
||||
"\n",
|
||||
"LLMs are far from perfect though and we're still a ways away from true AI. The biggest challenge is with hallucinations. Hallucinations is the term for when a LLM generates output that is factually incorrect. The alarming part of this is that on a cursory glance, it actually sounds like factual content. The default behavior of LLMs is to produce plausible answers even when no plausible answer exists. LLMs are not great at saying I don't know.\n",
|
||||
@@ -45,7 +43,7 @@
|
||||
"outputs": [],
|
||||
"source": [
|
||||
"%%capture\n",
|
||||
"!pip install git+https://github.com/neuml/txtai#egg=txtai[api,pipeline] autoawq"
|
||||
"!pip install git+https://github.com/neuml/txtai#egg=txtai[api,pipeline]"
|
||||
]
|
||||
},
|
||||
{
|
||||
@@ -74,7 +72,7 @@
|
||||
"embeddings.load(provider=\"huggingface-hub\", container=\"neuml/txtai-wikipedia\")\n",
|
||||
"\n",
|
||||
"# Create LLM\n",
|
||||
"llm = LLM(\"TheBloke/Mistral-7B-OpenOrca-AWQ\")"
|
||||
"llm = LLM(\"Qwen/Qwen3-4B-Instruct-2507\")"
|
||||
]
|
||||
},
|
||||
{
|
||||
@@ -186,6 +184,27 @@
|
||||
"id": "CSNbxxIMN_26"
|
||||
}
|
||||
},
|
||||
{
|
||||
"cell_type": "markdown",
|
||||
"metadata": {},
|
||||
"source": [
|
||||
"_Before continuing, it's important to note that txtai has multiple ways to run LLM inference. In the past, prior to \"Chat Templates\", it was expected that the submitted text had all the required chat tokens embedded. The same prompt above can also be written with chat messages. This is especially important when working with LLM APIs (i.e. OpenAI, Claude, Bedrock etc)._\n",
|
||||
"\n",
|
||||
"```python\n",
|
||||
"llm([\n",
|
||||
" {\"role\": \"system\": \"You are a friendly assistant. You answer questions from users.\"}\n",
|
||||
" {\"role\": \"user\", \"content\": f\"\"\"\n",
|
||||
" Answer the following question using only the context below. Only include information specifically discussed.\n",
|
||||
"\n",
|
||||
" question: {question}\n",
|
||||
" context: {text} \n",
|
||||
" \"\"\"}\n",
|
||||
"])\n",
|
||||
"```\n",
|
||||
"\n",
|
||||
"_See the [LLM pipeline documentation](https://neuml.github.io/txtai/pipeline/text/llm/) for more information._"
|
||||
]
|
||||
},
|
||||
{
|
||||
"cell_type": "markdown",
|
||||
"source": [
|
||||
@@ -259,6 +278,13 @@
|
||||
}
|
||||
]
|
||||
},
|
||||
{
|
||||
"cell_type": "markdown",
|
||||
"metadata": {},
|
||||
"source": [
|
||||
"_As with the LLM pipeline, the RAG pipeline also supports chat messages. See the [RAG pipeline documentation](https://neuml.github.io/txtai/pipeline/text/rag/) for more._"
|
||||
]
|
||||
},
|
||||
{
|
||||
"cell_type": "markdown",
|
||||
"source": [
|
||||
@@ -282,7 +308,7 @@
|
||||
"\n",
|
||||
"# RAG pipeline configuration\n",
|
||||
"rag:\n",
|
||||
" path: TheBloke/Mistral-7B-OpenOrca-AWQ\n",
|
||||
" path: Qwen/Qwen3-4B-Instruct-2507\n",
|
||||
" output: flatten\n",
|
||||
" template: |\n",
|
||||
" <|im_start|>system\n",
|
||||
|
||||
@@ -21,8 +21,6 @@
|
||||
"source": [
|
||||
"# Embeddings index format for open data access\n",
|
||||
"\n",
|
||||
"[txtai](https://github.com/neuml/txtai) is an all-in-one embeddings database for semantic search, LLM orchestration and language model workflows.\n",
|
||||
"\n",
|
||||
"The main programming language with txtai is Python. A key tenet is that the underlying data in an embeddings index is accessible without txtai.\n",
|
||||
"\n",
|
||||
"This notebook will demonstrate this through a series of examples.\n"
|
||||
|
||||
@@ -6,8 +6,6 @@
|
||||
"source": [
|
||||
"# Speech to Speech RAG\n",
|
||||
"\n",
|
||||
"[txtai](https://github.com/neuml/txtai) is an all-in-one embeddings database for semantic search, LLM orchestration and language model workflows.\n",
|
||||
"\n",
|
||||
"There are many articles, notebooks and examples covering how to perform vector search and/or retrieval augmented generation (RAG) with txtai. A lesser known component of txtai is it's built-in workflow component.\n",
|
||||
"\n",
|
||||
"Workflows are a simple yet powerful construct that takes a callable and returns elements. Workflows enable efficient processing of pipeline data. Workflows are streaming by nature and work on data in batches. This allows large volumes of data to be processed efficiently.\n",
|
||||
@@ -33,7 +31,7 @@
|
||||
"outputs": [],
|
||||
"source": [
|
||||
"%%capture\n",
|
||||
"!pip install git+https://github.com/neuml/txtai#egg=txtai[pipeline-audio] autoawq"
|
||||
"!pip install git+https://github.com/neuml/txtai#egg=txtai[pipeline-audio]"
|
||||
]
|
||||
},
|
||||
{
|
||||
@@ -86,7 +84,7 @@
|
||||
"# Create RAG pipeline\n",
|
||||
"rag = RAG(\n",
|
||||
" embeddings,\n",
|
||||
" \"hugging-quants/Meta-Llama-3.1-8B-Instruct-AWQ-INT4\",\n",
|
||||
" \"Qwen/Qwen3-4B-Instruct-2507\",\n",
|
||||
" system=\"You are a friendly assistant. You answer questions from users.\",\n",
|
||||
" template=template,\n",
|
||||
" context=10\n",
|
||||
@@ -160,7 +158,7 @@
|
||||
"\n",
|
||||
"# RAG\n",
|
||||
"rag:\n",
|
||||
" path: \"hugging-quants/Meta-Llama-3.1-8B-Instruct-AWQ-INT4\"\n",
|
||||
" path: \"Qwen/Qwen3-4B-Instruct-2507\"\n",
|
||||
" system: You are a friendly assistant. You answer questions from users.\n",
|
||||
" template: |\n",
|
||||
" Answer the following question using only the context below. Only include information\n",
|
||||
|
||||
@@ -6,8 +6,6 @@
|
||||
"source": [
|
||||
"# Generative Audio\n",
|
||||
"\n",
|
||||
"[txtai](https://github.com/neuml/txtai) is an all-in-one embeddings database for semantic search, LLM orchestration and language model workflows.\n",
|
||||
"\n",
|
||||
"txtai works with much more than just text! It has rich multimedia and multimodal capabilities.\n",
|
||||
"\n",
|
||||
"This notebook will demonstrate how to build generative audio workflows. These workflows will generate a combined audio stream with text and relevant audio for a series of poems."
|
||||
@@ -29,7 +27,7 @@
|
||||
"outputs": [],
|
||||
"source": [
|
||||
"%%capture\n",
|
||||
"!pip install git+https://github.com/neuml/txtai#egg=txtai[pipeline-audio] autoawq"
|
||||
"!pip install git+https://github.com/neuml/txtai#egg=txtai[pipeline-audio]"
|
||||
]
|
||||
},
|
||||
{
|
||||
@@ -41,7 +39,7 @@
|
||||
"The next section defines a generative audio workflow. This workflow consists of a set of pipelines as follows:\n",
|
||||
"\n",
|
||||
"- LLM\n",
|
||||
" - Llama 3 model used to describe the emotions of a given story or poem\n",
|
||||
" - Model used to describe the emotions of a given story or poem\n",
|
||||
"- Text To Audio\n",
|
||||
" - Builds audio given a text prompt\n",
|
||||
"- Text To Speech\n",
|
||||
@@ -81,7 +79,7 @@
|
||||
" return audio\n",
|
||||
"\n",
|
||||
"# LLM\n",
|
||||
"llm = LLM(\"hugging-quants/Meta-Llama-3.1-8B-Instruct-AWQ-INT4\")\n",
|
||||
"llm = LLM(\"Qwen/Qwen3-4B-Instruct-2507\")\n",
|
||||
"\n",
|
||||
"# Text to Audio\n",
|
||||
"# Important: The code for musicgen is licensed as MIT but model weights are CC-BY-NC\n",
|
||||
|
||||
@@ -8,13 +8,13 @@
|
||||
"source": [
|
||||
"# 💡 What's new in txtai 8.0\n",
|
||||
"\n",
|
||||
"[txtai](https://github.com/neuml/txtai) is an all-in-one embeddings database for semantic search, LLM orchestration and language model workflows.\n",
|
||||
"\n",
|
||||
"The 8.0 release brings a major new feature: Agents 🚀\n",
|
||||
"\n",
|
||||
"Agents automatically create workflows to answer multi-faceted user requests. Agents iteratively prompt and/or interface with tools to\n",
|
||||
"step through a process and ultimately come to an answer for a request.\n",
|
||||
"\n",
|
||||
"This release also adds support for Model2Vec vectorization.\n",
|
||||
"\n",
|
||||
"**Standard upgrade disclaimer below**\n",
|
||||
"\n",
|
||||
"While everything is backwards compatible, it's prudent to backup production indexes before upgrading and test before deploying."
|
||||
@@ -40,7 +40,7 @@
|
||||
"outputs": [],
|
||||
"source": [
|
||||
"%%capture\n",
|
||||
"!pip install git+https://github.com/neuml/txtai autoawq"
|
||||
"!pip install git+https://github.com/neuml/txtai#egg=txtai[agent] model2vec"
|
||||
]
|
||||
},
|
||||
{
|
||||
@@ -92,7 +92,7 @@
|
||||
"\n",
|
||||
"agent = Agent(\n",
|
||||
" tools=[today, wikipedia, arxiv, \"websearch\"],\n",
|
||||
" llm=\"hugging-quants/Meta-Llama-3.1-8B-Instruct-AWQ-INT4\",\n",
|
||||
" llm=\"Qwen/Qwen3-4B-Instruct-2507\",\n",
|
||||
" max_iterations=10,\n",
|
||||
")"
|
||||
]
|
||||
@@ -252,7 +252,7 @@
|
||||
"source": [
|
||||
"Let's unpack what just happened here. The Agent reviewed multiple sources and aggregated the references into a single report. This is quite powerful 💪\n",
|
||||
"\n",
|
||||
"Note that depending on the LLM used, errors can be seen as the Agent tries to get the function parameters right. This example is using Llama 3.1 8B. A more powerful LLM will likely lead to even better results. Remember that txtai supports a number of LLM frameworks (Hugging Face, llama.cpp and LiteLLM APIs)."
|
||||
"Note that depending on the LLM used, errors can be seen as the Agent tries to get the function parameters right. This example is using Qwen3 4B. A more powerful LLM will likely lead to even better results. Remember that txtai supports a number of LLM frameworks (Hugging Face, llama.cpp and LiteLLM APIs)."
|
||||
]
|
||||
},
|
||||
{
|
||||
@@ -275,7 +275,7 @@
|
||||
"from txtai import Agent, LLM\n",
|
||||
"\n",
|
||||
"# Share the LLM instance across multiple agents\n",
|
||||
"llm = LLM(\"hugging-quants/Meta-Llama-3.1-8B-Instruct-AWQ-INT4\")\n",
|
||||
"llm = LLM(\"Qwen/Qwen3-4B-Instruct-2507\")\n",
|
||||
"\n",
|
||||
"websearcher = Agent(\n",
|
||||
" tools=[\"websearch\"],\n",
|
||||
@@ -416,7 +416,7 @@
|
||||
" container: neuml/txtai-arxiv\n",
|
||||
"\n",
|
||||
"llm:\n",
|
||||
" path: hugging-quants/Meta-Llama-3.1-8B-Instruct-AWQ-INT4"
|
||||
" path: Qwen/Qwen3-4B-Instruct-2507"
|
||||
]
|
||||
},
|
||||
{
|
||||
@@ -462,6 +462,54 @@
|
||||
"💥 Look at that! A full API service from a simple configuration file. "
|
||||
]
|
||||
},
|
||||
{
|
||||
"cell_type": "markdown",
|
||||
"metadata": {},
|
||||
"source": [
|
||||
"# Vectorization with Model2Vec\n",
|
||||
"\n",
|
||||
"While the agent framework is the headline change, there is another major update - support for Model2Vec models. \n",
|
||||
"\n",
|
||||
"[Model2Vec](https://github.com/MinishLab/model2vec) is a technique to turn any sentence transformer into a really small static model, reducing model size by 15x and making the models up to 500x faster, with a small drop in performance."
|
||||
]
|
||||
},
|
||||
{
|
||||
"cell_type": "code",
|
||||
"execution_count": 1,
|
||||
"metadata": {},
|
||||
"outputs": [
|
||||
{
|
||||
"data": {
|
||||
"text/plain": [
|
||||
"\"Canada's last fully intact ice shelf has suddenly collapsed, forming a Manhattan-sized iceberg\""
|
||||
]
|
||||
},
|
||||
"execution_count": 1,
|
||||
"metadata": {},
|
||||
"output_type": "execute_result"
|
||||
}
|
||||
],
|
||||
"source": [
|
||||
"from txtai import Embeddings\n",
|
||||
"\n",
|
||||
"# Data to index\n",
|
||||
"data = [\n",
|
||||
" \"US tops 5 million confirmed virus cases\",\n",
|
||||
" \"Canada's last fully intact ice shelf has suddenly collapsed, forming a Manhattan-sized iceberg\",\n",
|
||||
" \"Beijing mobilises invasion craft along coast as Taiwan tensions escalate\",\n",
|
||||
" \"The National Park Service warns against sacrificing slower friends in a bear attack\",\n",
|
||||
" \"Maine man wins $1M from $25 lottery ticket\",\n",
|
||||
" \"Make huge profits without work, earn up to $100,000 a day\"\n",
|
||||
"]\n",
|
||||
"\n",
|
||||
"# Create an embeddings\n",
|
||||
"embeddings = Embeddings(method=\"model2vec\", path=\"minishlab/M2V_base_output\")\n",
|
||||
"embeddings.index(data)\n",
|
||||
"\n",
|
||||
"uid = embeddings.search(\"climate change\")[0][0]\n",
|
||||
"data[uid]"
|
||||
]
|
||||
},
|
||||
{
|
||||
"cell_type": "markdown",
|
||||
"metadata": {
|
||||
|
||||
File diff suppressed because one or more lines are too long
@@ -0,0 +1,501 @@
|
||||
{
|
||||
"cells": [
|
||||
{
|
||||
"cell_type": "markdown",
|
||||
"metadata": {},
|
||||
"source": [
|
||||
"# Granting autonomy to agents\n",
|
||||
"\n",
|
||||
"txtai 8.0 was recently released and added the ability to run agents. Agents automatically create workflows to answer multi-faceted user requests.\n",
|
||||
"\n",
|
||||
"Agents connect a series of tools with a reasoning engine (i.e. LLM). We're giving the agent a degree of latitude to go through it's own internal logic to address a user's request.\n",
|
||||
"\n",
|
||||
"This is a huge paradigm shift. We're talking about handing over control to a program and hoping it makes the right decisions itself. Perhaps there are some parallels to sending your kid to college - we hope we've raised them the right way to be able to make smart decisions 😂. \n",
|
||||
"\n",
|
||||
"This notebook will focus on examples that give agents autonomy to address requests. With this, we can start to the see the path ahead towards more and more automation of tasks."
|
||||
]
|
||||
},
|
||||
{
|
||||
"cell_type": "markdown",
|
||||
"metadata": {},
|
||||
"source": [
|
||||
"# Install dependencies\n",
|
||||
"\n",
|
||||
"Install `txtai` and all dependencies."
|
||||
]
|
||||
},
|
||||
{
|
||||
"cell_type": "code",
|
||||
"execution_count": null,
|
||||
"metadata": {},
|
||||
"outputs": [],
|
||||
"source": [
|
||||
"%%capture\n",
|
||||
"!pip install git+https://github.com/neuml/txtai#egg=txtai[agent,graph]"
|
||||
]
|
||||
},
|
||||
{
|
||||
"cell_type": "markdown",
|
||||
"metadata": {},
|
||||
"source": [
|
||||
"# Let's get creative\n",
|
||||
"\n",
|
||||
"In the first example, we'll define an agent that has access to the [txtai-wikipedia](https://huggingface.co/NeuML/txtai-wikipedia) embeddings database. Standard retrieval augmented generation (RAG) and vector search are typically designed for a single search. Agents enable a much more creative and iterative approach to search.\n",
|
||||
"\n",
|
||||
"This example won't ask the agent exactly what we're looking for. We'll ask the agent to tell us something interesting based on the agent's own ideas and research."
|
||||
]
|
||||
},
|
||||
{
|
||||
"cell_type": "code",
|
||||
"execution_count": null,
|
||||
"metadata": {},
|
||||
"outputs": [],
|
||||
"source": [
|
||||
"from txtai import Agent\n",
|
||||
"\n",
|
||||
"agent = Agent(\n",
|
||||
" tools=[{\n",
|
||||
" \"name\": \"wikipedia\",\n",
|
||||
" \"description\": \"Searches a Wikipedia database\",\n",
|
||||
" \"provider\": \"huggingface-hub\",\n",
|
||||
" \"container\": \"neuml/txtai-wikipedia\"\n",
|
||||
" }],\n",
|
||||
" llm=\"Qwen/Qwen3-4B-Instruct-2507\",\n",
|
||||
" max_iterations=10,\n",
|
||||
")"
|
||||
]
|
||||
},
|
||||
{
|
||||
"cell_type": "code",
|
||||
"execution_count": null,
|
||||
"metadata": {},
|
||||
"outputs": [
|
||||
{
|
||||
"name": "stderr",
|
||||
"output_type": "stream",
|
||||
"text": [
|
||||
"\u001b[32;20;1m======== New task ========\u001b[0m\n",
|
||||
"\u001b[37;1m\n",
|
||||
"I'm bored 🥱. Think about 2-3 disparate topics and use those to search wikipedia to generate something fascinating.\n",
|
||||
"Write a report summarizing each article. Include a section with a list of article hyperlinks.\n",
|
||||
"Write the text as Markdown.\n",
|
||||
"\u001b[0m\n",
|
||||
"\u001b[33;1m=== Agent thoughts:\u001b[0m\n",
|
||||
"\u001b[0mThought: I will use Wikipedia to search for articles related to three disparate topics. The first topic will be the \"Great Barrier Reef\", the second topic will be \"Dark Matter\", and the third topic will be \"The Voynich Manuscript\".\u001b[0m\n",
|
||||
"\u001b[33;1m>>> Calling tool: 'wikipedia' with arguments: {'query': 'Great Barrier Reef'}\u001b[0m\n",
|
||||
"\u001b[33;1m=== Agent thoughts:\u001b[0m\n",
|
||||
"\u001b[0mThought: The results from the Wikipedia search show that the Great Barrier Reef is a vast and diverse ecosystem that supports a wide variety of life. However, it is also facing many threats, including climate change, pollution, and overfishing.\u001b[0m\n",
|
||||
"\u001b[33;1m>>> Calling tool: 'wikipedia' with arguments: {'query': 'Dark Matter'}\u001b[0m\n",
|
||||
"\u001b[33;1m=== Agent thoughts:\u001b[0m\n",
|
||||
"\u001b[0mThought: The results from the Wikipedia search show that Dark Matter is a hypothetical form of matter that does not interact with light or other electromagnetic radiation, and is implied by gravitational effects that cannot be explained by general relativity.\u001b[0m\n",
|
||||
"\u001b[33;1m>>> Calling tool: 'wikipedia' with arguments: {'query': 'The Voynich Manuscript'}\u001b[0m\n",
|
||||
"\u001b[33;1m=== Agent thoughts:\u001b[0m\n",
|
||||
"\u001b[0mThought: The results from the Wikipedia search show that the Voynich Manuscript is an illustrated codex that has been carbon-dated to the early 15th century, and its origins, authorship, and purpose are still debated.\u001b[0m\n",
|
||||
"\u001b[33;1m>>> Calling tool: 'final_answer' with arguments: {'answer': \"### Report on Fascinating Topics\\n\\n#### The Great Barrier Reef\\n\\nThe Great Barrier Reef is the world's largest coral reef system, composed of over 2,900 individual reefs and 900 islands stretching for over 2,300 kilometers off the coast of Queensland, Australia. It is a vast and diverse ecosystem that supports a wide variety of life, including coral and other invertebrate species, bony fish, sharks, rays, marine mammals, marine turtles, sea snakes, and algae. However, it is also facing many threats, including climate change, pollution, and overfishing.\\n\\n#### Dark Matter\\n\\nDark Matter is a hypothetical form of matter that does not interact with light or other electromagnetic radiation. It is implied by gravitational effects that cannot be explained by general relativity, and is a topic of ongoing research in astrophysics and cosmology.\\n\\n#### The Voynich Manuscript\\n\\nThe Voynich Manuscript is an illustrated codex that has been carbon-dated to the early 15th century. Its origins, authorship, and purpose are still debated, and it is considered one of the most mysterious and enigmatic manuscripts in the world.\\n\\n### Article Hyperlinks\\n\\n* [Great Barrier Reef](https://en.wikipedia.org/wiki/Great_Barrier_Reef)\\n* [Dark Matter](https://en.wikipedia.org/wiki/Dark_matter)\\n* [Voynich Manuscript](https://en.wikipedia.org/wiki/Voynich_manuscript)\"}\u001b[0m\n"
|
||||
]
|
||||
},
|
||||
{
|
||||
"data": {
|
||||
"text/markdown": [
|
||||
"### Report on Fascinating Topics\n",
|
||||
"\n",
|
||||
"#### The Great Barrier Reef\n",
|
||||
"\n",
|
||||
"The Great Barrier Reef is the world's largest coral reef system, composed of over 2,900 individual reefs and 900 islands stretching for over 2,300 kilometers off the coast of Queensland, Australia. It is a vast and diverse ecosystem that supports a wide variety of life, including coral and other invertebrate species, bony fish, sharks, rays, marine mammals, marine turtles, sea snakes, and algae. However, it is also facing many threats, including climate change, pollution, and overfishing.\n",
|
||||
"\n",
|
||||
"#### Dark Matter\n",
|
||||
"\n",
|
||||
"Dark Matter is a hypothetical form of matter that does not interact with light or other electromagnetic radiation. It is implied by gravitational effects that cannot be explained by general relativity, and is a topic of ongoing research in astrophysics and cosmology.\n",
|
||||
"\n",
|
||||
"#### The Voynich Manuscript\n",
|
||||
"\n",
|
||||
"The Voynich Manuscript is an illustrated codex that has been carbon-dated to the early 15th century. Its origins, authorship, and purpose are still debated, and it is considered one of the most mysterious and enigmatic manuscripts in the world.\n",
|
||||
"\n",
|
||||
"### Article Hyperlinks\n",
|
||||
"\n",
|
||||
"* [Great Barrier Reef](https://en.wikipedia.org/wiki/Great_Barrier_Reef)\n",
|
||||
"* [Dark Matter](https://en.wikipedia.org/wiki/Dark_matter)\n",
|
||||
"* [Voynich Manuscript](https://en.wikipedia.org/wiki/Voynich_manuscript)"
|
||||
],
|
||||
"text/plain": [
|
||||
"<IPython.core.display.Markdown object>"
|
||||
]
|
||||
},
|
||||
"metadata": {},
|
||||
"output_type": "display_data"
|
||||
}
|
||||
],
|
||||
"source": [
|
||||
"from IPython.display import display, Markdown\n",
|
||||
"\n",
|
||||
"answer = agent(\"\"\"\n",
|
||||
"I'm bored 🥱. Think about 2-3 disparate topics and use those to search wikipedia to generate something fascinating.\n",
|
||||
"Write a report summarizing each article. Include a section with a list of article hyperlinks.\n",
|
||||
"Write the text as Markdown.\n",
|
||||
"\"\"\", maxlength=16000)\n",
|
||||
"\n",
|
||||
"display(Markdown(answer))"
|
||||
]
|
||||
},
|
||||
{
|
||||
"cell_type": "markdown",
|
||||
"metadata": {},
|
||||
"source": [
|
||||
"💥 Interesting indeed. The fundamental concept of search is we need to know what to look for. In this case, we didn't have that (i.e. we're bored 😀).\n",
|
||||
"\n",
|
||||
"Let's go to another example. This time we'll look at the [txtai-hfposts](https://huggingface.co/NeuML/txtai-hfposts) embeddings database. We'll ask the agent to research a specific topic then write a report about what was found.\n"
|
||||
]
|
||||
},
|
||||
{
|
||||
"cell_type": "code",
|
||||
"execution_count": null,
|
||||
"metadata": {},
|
||||
"outputs": [],
|
||||
"source": [
|
||||
"agent = Agent(\n",
|
||||
" tools=[{\n",
|
||||
" \"name\": \"hfposts\",\n",
|
||||
" \"description\": \"Searches a database of technical posts on Hugging Face\",\n",
|
||||
" \"provider\": \"huggingface-hub\",\n",
|
||||
" \"container\": \"neuml/txtai-hfposts\"\n",
|
||||
" }],\n",
|
||||
" llm=\"Qwen/Qwen3-4B-Instruct-2507\",\n",
|
||||
" max_iterations=10,\n",
|
||||
")"
|
||||
]
|
||||
},
|
||||
{
|
||||
"cell_type": "code",
|
||||
"execution_count": null,
|
||||
"metadata": {},
|
||||
"outputs": [
|
||||
{
|
||||
"name": "stderr",
|
||||
"output_type": "stream",
|
||||
"text": [
|
||||
"\u001b[32;20;1m======== New task ========\u001b[0m\n",
|
||||
"\u001b[37;1m\n",
|
||||
"Read posts about medicine and write a report on what you learned.\n",
|
||||
"\n",
|
||||
"The report should be a Markdown table with the following columns.\n",
|
||||
" - Name\n",
|
||||
" - Description\n",
|
||||
" - Link to content\n",
|
||||
"\n",
|
||||
"Only include rows that have a valid web url.\n",
|
||||
"\u001b[0m\n",
|
||||
"\u001b[33;1m=== Agent thoughts:\u001b[0m\n",
|
||||
"\u001b[0mThought: First, I need to search for posts related to medicine using the `hfposts` tool.\u001b[0m\n",
|
||||
"\u001b[33;1m>>> Calling tool: 'hfposts' with arguments: {'query': 'medicine'}\u001b[0m\n",
|
||||
"\u001b[33;1m=== Agent thoughts:\u001b[0m\n",
|
||||
"\u001b[0mThought: Now that I have the posts related to medicine, I need to filter out the ones that have a valid web URL. I will go through each post and check if it contains a URL.\u001b[0m\n",
|
||||
"\u001b[33;1m>>> Calling tool: 'hfposts' with arguments: {'query': 'medicine url'}\u001b[0m\n",
|
||||
"\u001b[33;1m=== Agent thoughts:\u001b[0m\n",
|
||||
"\u001b[0mThought: Now that I have the posts with URLs, I need to extract the relevant information such as the name, description, and link to content. I will create a Markdown table with these details.\u001b[0m\n",
|
||||
"\u001b[33;1m>>> Calling tool: 'hfposts' with arguments: {'query': 'medicine url'}\u001b[0m\n",
|
||||
"\u001b[33;1m=== Agent thoughts:\u001b[0m\n",
|
||||
"\u001b[0mThought: Now that I have the posts with URLs, I can extract the relevant information and create a Markdown table. I will format the data into the required structure.\u001b[0m\n",
|
||||
"\u001b[33;1m>>> Calling tool: 'final_answer' with arguments: {'answer': '| Name | Description | Link to content |\\n| --- | --- | --- |\\n| OpenBioLLM Release | Introducing OpenBioLLM-Llama3-70B & 8B: The most capable openly available Medical-domain LLMs to date! | [https://huggingface.co/blog/aaditya/openbiollm](https://huggingface.co/blog/aaditya/openbiollm) |\\n| Last Week in Medical AI: Top Research Papers/Models (September 1 - September 7, 2024) | Outperforms industry giants like GPT-4, Gemini, Meditron-70B, Med-PaLM-1, and Med-PaLM-2 in the biomedical domain. | [https://x.com/OpenlifesciAI/status/1832476252260712788](https://x.com/OpenlifesciAI/status/1832476252260712788) |\\n| Last Week in Medical AI: Top Research Papers/Models (August 25 - August 31, 2024) | Includes MultiMed, a Multimodal Medical Benchmark, and A Foundation model for generating chest X-ray images. | [https://x.com/OpenlifesciAI/status/1829984701324448051](https://x.com/OpenlifesciAI/status/1829984701324448051) |\\n| Last Week in Medical AI: Top Research Papers/Models (October 5 - October 12, 2024) | Introduces MMedAgent: Learning to Use Medical Tools with Multi-modal Agent. | [https://youtu.be/OD3C5jirszw](https://youtu.be/OD3C5jirszw) |\\n| Last Week in Medical AI: Top Research Papers/Models (October 26 - November 2, 2024) | Google Presents MDAgents: An Adaptive Collaboration of LLMs for Medical Decision-Making. | [https://x.com/OpenlifesciAI/status/1852685220912464066](https://x.com/OpenlifesciAI/status/1852685220912464066) '}\u001b[0m\n"
|
||||
]
|
||||
},
|
||||
{
|
||||
"data": {
|
||||
"text/markdown": [
|
||||
"| Name | Description | Link to content |\n",
|
||||
"| --- | --- | --- |\n",
|
||||
"| OpenBioLLM Release | Introducing OpenBioLLM-Llama3-70B & 8B: The most capable openly available Medical-domain LLMs to date! | [https://huggingface.co/blog/aaditya/openbiollm](https://huggingface.co/blog/aaditya/openbiollm) |\n",
|
||||
"| Last Week in Medical AI: Top Research Papers/Models (September 1 - September 7, 2024) | Outperforms industry giants like GPT-4, Gemini, Meditron-70B, Med-PaLM-1, and Med-PaLM-2 in the biomedical domain. | [https://x.com/OpenlifesciAI/status/1832476252260712788](https://x.com/OpenlifesciAI/status/1832476252260712788) |\n",
|
||||
"| Last Week in Medical AI: Top Research Papers/Models (August 25 - August 31, 2024) | Includes MultiMed, a Multimodal Medical Benchmark, and A Foundation model for generating chest X-ray images. | [https://x.com/OpenlifesciAI/status/1829984701324448051](https://x.com/OpenlifesciAI/status/1829984701324448051) |\n",
|
||||
"| Last Week in Medical AI: Top Research Papers/Models (October 5 - October 12, 2024) | Introduces MMedAgent: Learning to Use Medical Tools with Multi-modal Agent. | [https://youtu.be/OD3C5jirszw](https://youtu.be/OD3C5jirszw) |\n",
|
||||
"| Last Week in Medical AI: Top Research Papers/Models (October 26 - November 2, 2024) | Google Presents MDAgents: An Adaptive Collaboration of LLMs for Medical Decision-Making. | [https://x.com/OpenlifesciAI/status/1852685220912464066](https://x.com/OpenlifesciAI/status/1852685220912464066) "
|
||||
],
|
||||
"text/plain": [
|
||||
"<IPython.core.display.Markdown object>"
|
||||
]
|
||||
},
|
||||
"metadata": {},
|
||||
"output_type": "display_data"
|
||||
}
|
||||
],
|
||||
"source": [
|
||||
"answer = agent(\"\"\"\n",
|
||||
"Read posts about medicine and write a report on what you learned.\n",
|
||||
"\n",
|
||||
"The report should be a Markdown table with the following columns.\n",
|
||||
" - Name\n",
|
||||
" - Description\n",
|
||||
" - Link to content\n",
|
||||
"\n",
|
||||
"Only include rows that have a valid web url.\n",
|
||||
"\"\"\", maxlength=16000)\n",
|
||||
"\n",
|
||||
"display(Markdown(answer))"
|
||||
]
|
||||
},
|
||||
{
|
||||
"cell_type": "markdown",
|
||||
"metadata": {},
|
||||
"source": [
|
||||
"🚀 Once again, very interesting! This time we asked the agent to go read about a topic and report back. The agent did that and left us with links to explore further."
|
||||
]
|
||||
},
|
||||
{
|
||||
"cell_type": "markdown",
|
||||
"metadata": {},
|
||||
"source": [
|
||||
"# Autonomous Embeddings\n",
|
||||
"\n",
|
||||
"For our last example, we're going to give an agent free rein to control an embeddings database.\n",
|
||||
"\n",
|
||||
"First, we will create an empty embeddings database and tell the agent how to add and search for data."
|
||||
]
|
||||
},
|
||||
{
|
||||
"cell_type": "code",
|
||||
"execution_count": null,
|
||||
"metadata": {},
|
||||
"outputs": [],
|
||||
"source": [
|
||||
"from txtai import Agent, Embeddings\n",
|
||||
"from txtai.pipeline import Textractor\n",
|
||||
"from txtai.workflow import Workflow, Task\n",
|
||||
"\n",
|
||||
"# Empty embeddings database\n",
|
||||
"embeddings = Embeddings(\n",
|
||||
" path=\"intfloat/e5-large\",\n",
|
||||
" instructions={\"query\": \"query: \", \"data\": \"passage: \"},\n",
|
||||
" content=True\n",
|
||||
")\n",
|
||||
"\n",
|
||||
"# Textractor instance\n",
|
||||
"textractor = Textractor(sections=True, headers={\"user-agent\": \"Mozilla/5.0\"})\n",
|
||||
"\n",
|
||||
"def insert(elements):\n",
|
||||
" \"\"\"\n",
|
||||
" Inserts elements into the embeddings database.\n",
|
||||
"\n",
|
||||
" Args:\n",
|
||||
" elements: list of strings to insert\n",
|
||||
" \"\"\"\n",
|
||||
"\n",
|
||||
" def upsert(elements):\n",
|
||||
" embeddings.upsert(elements)\n",
|
||||
" return elements\n",
|
||||
"\n",
|
||||
" # Upsert workflow\n",
|
||||
" workflow = Workflow([Task(textractor), Task(upsert)])\n",
|
||||
" list(workflow(elements))\n",
|
||||
" return f\"{elements} inserted successfully\"\n",
|
||||
"\n",
|
||||
"agent = Agent(\n",
|
||||
" tools=[insert, embeddings.search, \"websearch\"],\n",
|
||||
" llm=\"Qwen/Qwen3-4B-Instruct-2507\",\n",
|
||||
" max_iterations=10\n",
|
||||
")"
|
||||
]
|
||||
},
|
||||
{
|
||||
"cell_type": "markdown",
|
||||
"metadata": {},
|
||||
"source": [
|
||||
"Next, we'll define a workflow process. This creates the rules we want the agent to follow. Then we'll run two requests."
|
||||
]
|
||||
},
|
||||
{
|
||||
"cell_type": "code",
|
||||
"execution_count": null,
|
||||
"metadata": {},
|
||||
"outputs": [
|
||||
{
|
||||
"name": "stderr",
|
||||
"output_type": "stream",
|
||||
"text": [
|
||||
"\u001b[32;20;1m======== New task ========\u001b[0m\n",
|
||||
"\u001b[37;1m\n",
|
||||
"Run the following process:\n",
|
||||
" 1. Search your internal knowledge for txtai\n",
|
||||
" 2. If not found, find relevant urls and insert those as a list of strings ONLY. Then rerun the search for txtai.\n",
|
||||
" 3. Write a detailed report about txtai with Markdown sections covering the major topics. Include a section with hyperlink references.\n",
|
||||
"\u001b[0m\n",
|
||||
"\u001b[33;1m=== Agent thoughts:\u001b[0m\n",
|
||||
"\u001b[0mThought: First, I will attempt to search for \"txtai\" in my internal knowledge base.\u001b[0m\n",
|
||||
"\u001b[33;1m>>> Calling tool: 'search' with arguments: {'query': 'txtai'}\u001b[0m\n",
|
||||
"\u001b[33;1m=== Agent thoughts:\u001b[0m\n",
|
||||
"\u001b[0mThought: Since the search for \"txtai\" did not yield any results, I will proceed to find relevant URLs and insert them as a list of strings.\u001b[0m\n",
|
||||
"\u001b[33;1m>>> Calling tool: 'web_search' with arguments: {'query': 'txtai'}\u001b[0m\n",
|
||||
"\u001b[33;1m=== Agent thoughts:\u001b[0m\n",
|
||||
"\u001b[0mThought: Now that I have found relevant URLs, I will insert them into the database as a list of strings.\u001b[0m\n",
|
||||
"\u001b[33;1m>>> Calling tool: 'insert' with arguments: {'elements': ['https://github.com/neuml/txtai', 'https://pypi.org/project/txtai/', 'https://neuml.github.io/txtai/', 'https://neuml.com/', 'https://medium.com/neuml/introducing-txtai-the-all-in-one-embeddings-database-c721f4ff91ad', 'https://neuml.github.io/txtai/embeddings/', 'https://neuml.github.io/txtai/examples/']}\u001b[0m\n",
|
||||
"\u001b[33;1m=== Agent thoughts:\u001b[0m\n",
|
||||
"\u001b[0mThought: Now that the relevant URLs have been inserted, I will rerun the search for \"txtai\".\u001b[0m\n",
|
||||
"\u001b[33;1m>>> Calling tool: 'search' with arguments: {'query': 'txtai'}\u001b[0m\n",
|
||||
"\u001b[33;1m=== Agent thoughts:\u001b[0m\n",
|
||||
"\u001b[33;1m>>> Calling tool: 'final_answer' with arguments: {'answer': '# txtai Overview\\n\\ntxtai is an all-in-one open-source embeddings database designed for semantic search, LLM orchestration, and language model workflows. It combines vector indexes (both sparse and dense), graph networks, and relational databases to offer a comprehensive solution for various tasks.\\n\\n## Semantic Search\\n\\ntxtai supports semantic search, enabling users to find relevant information based on the meaning of the text rather than just keywords. This makes it suitable for applications such as recommendation systems, content retrieval, and more.\\n\\n## LLM Orchestration\\n\\ntxtai includes support for Large Language Models (LLMs) orchestration, which allows users to integrate and manage different LLMs within their workflows. This feature is particularly useful for tasks such as prompt chaining, summarization, transcription, translation, and more.\\n\\n## Embeddings Databases\\n\\ntxtai provides a unified interface for embedding, indexing, searching, and processing text and multimedia data. Users can create, index, and search embeddings using code snippets and examples provided in the documentation.\\n\\n## Hyperlink References\\n\\n- [txtai on GitHub](https://github.com/neuml/txtai)\\n- [PyPI - txtai](https://pypi.org/project/txtai/)\\n- [txtai Documentation](https://neuml.github.io/txtai/)\\n- [txtai Examples](https://neuml.github.io/txtai/examples/)\\n- [txtai Embeddings](https://neuml.github.io/txtai/embeddings/)'}\u001b[0m\n"
|
||||
]
|
||||
},
|
||||
{
|
||||
"data": {
|
||||
"text/markdown": [
|
||||
"# txtai Overview\n",
|
||||
"\n",
|
||||
"txtai is an all-in-one open-source embeddings database designed for semantic search, LLM orchestration, and language model workflows. It combines vector indexes (both sparse and dense), graph networks, and relational databases to offer a comprehensive solution for various tasks.\n",
|
||||
"\n",
|
||||
"## Semantic Search\n",
|
||||
"\n",
|
||||
"txtai supports semantic search, enabling users to find relevant information based on the meaning of the text rather than just keywords. This makes it suitable for applications such as recommendation systems, content retrieval, and more.\n",
|
||||
"\n",
|
||||
"## LLM Orchestration\n",
|
||||
"\n",
|
||||
"txtai includes support for Large Language Models (LLMs) orchestration, which allows users to integrate and manage different LLMs within their workflows. This feature is particularly useful for tasks such as prompt chaining, summarization, transcription, translation, and more.\n",
|
||||
"\n",
|
||||
"## Embeddings Databases\n",
|
||||
"\n",
|
||||
"txtai provides a unified interface for embedding, indexing, searching, and processing text and multimedia data. Users can create, index, and search embeddings using code snippets and examples provided in the documentation.\n",
|
||||
"\n",
|
||||
"## Hyperlink References\n",
|
||||
"\n",
|
||||
"- [txtai on GitHub](https://github.com/neuml/txtai)\n",
|
||||
"- [PyPI - txtai](https://pypi.org/project/txtai/)\n",
|
||||
"- [txtai Documentation](https://neuml.github.io/txtai/)\n",
|
||||
"- [txtai Examples](https://neuml.github.io/txtai/examples/)\n",
|
||||
"- [txtai Embeddings](https://neuml.github.io/txtai/embeddings/)"
|
||||
],
|
||||
"text/plain": [
|
||||
"<IPython.core.display.Markdown object>"
|
||||
]
|
||||
},
|
||||
"metadata": {},
|
||||
"output_type": "display_data"
|
||||
}
|
||||
],
|
||||
"source": [
|
||||
"prompt = \"\"\"\n",
|
||||
"Run the following process:\n",
|
||||
" 1. Search your internal knowledge for {topic}\n",
|
||||
" 2. If not found, find relevant urls and insert those as a list of strings ONLY. Then rerun the search for {topic}.\n",
|
||||
" 3. Write a detailed report about {topic} with Markdown sections covering the major topics. Include a section with hyperlink references.\n",
|
||||
"\"\"\"\n",
|
||||
"\n",
|
||||
"answer = agent(prompt.format(topic=\"txtai\"))\n",
|
||||
"display(Markdown(answer))"
|
||||
]
|
||||
},
|
||||
{
|
||||
"cell_type": "code",
|
||||
"execution_count": null,
|
||||
"metadata": {},
|
||||
"outputs": [
|
||||
{
|
||||
"name": "stderr",
|
||||
"output_type": "stream",
|
||||
"text": [
|
||||
"\u001b[32;20;1m======== New task ========\u001b[0m\n",
|
||||
"\u001b[37;1m\n",
|
||||
"Run the following process:\n",
|
||||
" 1. Search your internal knowledge for openscholar\n",
|
||||
" 2. If not found, find relevant urls and insert those as a list of strings ONLY. Then rerun the search for openscholar.\n",
|
||||
" 3. Write a detailed report about openscholar with Markdown sections covering the major topics. Include a section with hyperlink references.\n",
|
||||
"\u001b[0m\n",
|
||||
"\u001b[33;1m=== Agent thoughts:\u001b[0m\n",
|
||||
"\u001b[0mThought: First, I will search my internal knowledge for \"openscholar\".\u001b[0m\n",
|
||||
"\u001b[33;1m>>> Calling tool: 'search' with arguments: {'query': 'openscholar'}\u001b[0m\n",
|
||||
"\u001b[33;1m=== Agent thoughts:\u001b[0m\n",
|
||||
"\u001b[0mThought: Since the search did not return any relevant information about \"openscholar\", I will find relevant URLs and insert them as a list of strings. Then, I will rerun the search for \"openscholar\".\u001b[0m\n",
|
||||
"\u001b[33;1m>>> Calling tool: 'web_search' with arguments: {'query': 'openscholar'}\u001b[0m\n",
|
||||
"\u001b[33;1m=== Agent thoughts:\u001b[0m\n",
|
||||
"\u001b[0mThought: Now that I have found relevant URLs about \"openscholar\", I will insert these URLs into the database.\u001b[0m\n",
|
||||
"\u001b[33;1m>>> Calling tool: 'insert' with arguments: {'elements': ['https://openscholar.allen.ai/', 'https://allenai.org/blog/openscholar', 'https://arxiv.org/abs/2411.14199', 'https://github.com/AkariAsai/OpenScholar', 'https://www.marktechpost.com/2024/11/22/the-allen-institute-for-ai-ai2-introduces-openscholar-an-open-ecosystem-for-literature-synthesis-featuring-advanced-datastores-and-expert-level-results/', 'https://venturebeat.com/ai/openscholar-the-open-source-a-i-thats-outperforming-gpt-4o-in-scientific-research/']}\u001b[0m\n",
|
||||
"\u001b[33;1m=== Agent thoughts:\u001b[0m\n",
|
||||
"\u001b[0mThought: Now that the relevant URLs have been inserted, I will rerun the search for \"openscholar\" to gather more detailed information.\u001b[0m\n",
|
||||
"\u001b[33;1m>>> Calling tool: 'search' with arguments: {'query': 'openscholar'}\u001b[0m\n",
|
||||
"\u001b[33;1m=== Agent thoughts:\u001b[0m\n",
|
||||
"\u001b[0mThought: The search has returned relevant information about OpenScholar. I will now compile a detailed report about OpenScholar with Markdown sections covering the major topics.\u001b[0m\n",
|
||||
"\u001b[33;1m>>> Calling tool: 'final_answer' with arguments: {'answer': \"# OpenScholar Report\\n\\n## Introduction\\nOpenScholar is an advanced AI system developed by the Allen Institute for AI and the University of Washington. It aims to revolutionize scientific research by processing millions of research papers and providing citation-backed answers to complex research questions.\\n\\n## Key Features\\n- **Data Processing**: Capable of handling 45 million research papers instantly.\\n- **Citation Accuracy**: Achieves high citation accuracy, challenging proprietary AI systems.\\n- **Customizable Tools**: Offers specialized tools and built-in features for creating impactful websites.\\n\\n## Research Impact\\n- **Data Utilization**: Integrates a vast corpus of scientific literature, making it the largest open-access corpus for scientific literature synthesis.\\n- **Expert-Level Results**: Provides answers that match or exceed those of human experts in various scientific domains.\\n\\n## Future Directions\\n- **Continued Development**: Ongoing efforts to improve the system's capabilities and expand its applications.\\n- **Community Engagement**: Plans for expanding the user base and fostering a community around OpenScholar.\\n\\n## References\\n- [OpenScholar](https://openscholar.allen.ai/)\\n- [VentureBeat Article](https://venturebeat.com/ai/openscholar-the-open-source-a-i-thats-outperforming-gpt-4o-in-scientific-research/)\\n- [Allen Institute for AI](https://allenai.org/blog/openscholar)\"}\u001b[0m\n"
|
||||
]
|
||||
},
|
||||
{
|
||||
"data": {
|
||||
"text/markdown": [
|
||||
"# OpenScholar Report\n",
|
||||
"\n",
|
||||
"## Introduction\n",
|
||||
"OpenScholar is an advanced AI system developed by the Allen Institute for AI and the University of Washington. It aims to revolutionize scientific research by processing millions of research papers and providing citation-backed answers to complex research questions.\n",
|
||||
"\n",
|
||||
"## Key Features\n",
|
||||
"- **Data Processing**: Capable of handling 45 million research papers instantly.\n",
|
||||
"- **Citation Accuracy**: Achieves high citation accuracy, challenging proprietary AI systems.\n",
|
||||
"- **Customizable Tools**: Offers specialized tools and built-in features for creating impactful websites.\n",
|
||||
"\n",
|
||||
"## Research Impact\n",
|
||||
"- **Data Utilization**: Integrates a vast corpus of scientific literature, making it the largest open-access corpus for scientific literature synthesis.\n",
|
||||
"- **Expert-Level Results**: Provides answers that match or exceed those of human experts in various scientific domains.\n",
|
||||
"\n",
|
||||
"## Future Directions\n",
|
||||
"- **Continued Development**: Ongoing efforts to improve the system's capabilities and expand its applications.\n",
|
||||
"- **Community Engagement**: Plans for expanding the user base and fostering a community around OpenScholar.\n",
|
||||
"\n",
|
||||
"## References\n",
|
||||
"- [OpenScholar](https://openscholar.allen.ai/)\n",
|
||||
"- [VentureBeat Article](https://venturebeat.com/ai/openscholar-the-open-source-a-i-thats-outperforming-gpt-4o-in-scientific-research/)\n",
|
||||
"- [Allen Institute for AI](https://allenai.org/blog/openscholar)"
|
||||
],
|
||||
"text/plain": [
|
||||
"<IPython.core.display.Markdown object>"
|
||||
]
|
||||
},
|
||||
"metadata": {},
|
||||
"output_type": "display_data"
|
||||
}
|
||||
],
|
||||
"source": [
|
||||
"answer = agent(prompt.format(topic=\"openscholar\"))\n",
|
||||
"display(Markdown(answer))"
|
||||
]
|
||||
},
|
||||
{
|
||||
"cell_type": "markdown",
|
||||
"metadata": {},
|
||||
"source": [
|
||||
"🔥 Amazing.\n",
|
||||
"\n",
|
||||
"Remember, we started with an empty embeddings database. Then we gave basic instructions on how to use the available tools. From there, the agent autonomously operated and answered user requests. The agent also stored what it learned for future requests. This gave the agent it's own internal memory.\n",
|
||||
"\n",
|
||||
"Of course, we could program a process that implements this workflow. But think about the productivity gains we're opening up to so many more people. We're enabling people to control a process simply by pairing a set of tools with a description of what they want, in English.\n",
|
||||
"\n",
|
||||
"Exciting times!"
|
||||
]
|
||||
},
|
||||
{
|
||||
"cell_type": "markdown",
|
||||
"metadata": {},
|
||||
"source": [
|
||||
"# Wrapping up\n",
|
||||
"\n",
|
||||
"This notebook demonstrated ways to run agents in a more autonomous fashion. While the technology isn't perfect, we can certainly see the path ahead where new models will continue to do a better job. With the right agents and targeted tools, much can be done now though. \n",
|
||||
"\n",
|
||||
"Think about the differences between now and 6-12 months ago. Where will we be in another 6-12 months!"
|
||||
]
|
||||
}
|
||||
],
|
||||
"metadata": {
|
||||
"kernelspec": {
|
||||
"display_name": "local",
|
||||
"language": "python",
|
||||
"name": "python3"
|
||||
},
|
||||
"language_info": {
|
||||
"codemirror_mode": {
|
||||
"name": "ipython",
|
||||
"version": 3
|
||||
},
|
||||
"file_extension": ".py",
|
||||
"mimetype": "text/x-python",
|
||||
"name": "python",
|
||||
"nbconvert_exporter": "python",
|
||||
"pygments_lexer": "ipython3",
|
||||
"version": "3.9.20"
|
||||
}
|
||||
},
|
||||
"nbformat": 4,
|
||||
"nbformat_minor": 2
|
||||
}
|
||||
@@ -0,0 +1,792 @@
|
||||
{
|
||||
"cells": [
|
||||
{
|
||||
"cell_type": "markdown",
|
||||
"metadata": {
|
||||
"id": "7btcrgth5z6f"
|
||||
},
|
||||
"source": [
|
||||
"# Getting started with LLM APIs\n",
|
||||
"\n",
|
||||
"_Thank you to [Igor Ribeiro Lima](https://github.com/igorlima) for writing this notebook!_\n",
|
||||
"\n",
|
||||
"This notebook demonstrates how to call different LLM APIs using just one set of common functions.\n",
|
||||
"\n",
|
||||
"While each LLM has its own configuration, here's a cool perk of using [`txtai`](https://neuml.github.io/txtai/) plus [`litellm`](https://docs.litellm.ai/docs/) working behind the scenes. The big win with `txtai` is that it helps standardize inputs and outputs across several LLMs. **This means we can seamlessly call any LLM API**.\n",
|
||||
"\n",
|
||||
"In this notebook, we use one set of common functions to call _**Gemini**_, _**VertexAI**_, _**Mistral**_, _**Cohere**_, _**AWS Bedrock**_, _**OpenAI**_, _**Claude by Anthropic**_, _**Groq**_, _and more_!\n",
|
||||
"\n",
|
||||
"Isn't that amazing? One method for many different LLM APIs - **that's the beauty of these libraries**!"
|
||||
]
|
||||
},
|
||||
{
|
||||
"cell_type": "markdown",
|
||||
"metadata": {
|
||||
"id": "lhrk9y766Lw1"
|
||||
},
|
||||
"source": [
|
||||
"## Install dependencies\n",
|
||||
"\n",
|
||||
"This session guides you through all the essential dependencies you'll need to run the Python script for various LLM APIs.\n",
|
||||
"\n",
|
||||
"You can choose the dependencies based on your specific needs. Each dependency is carefully commented on in the code, so you'll know exactly which API it supports.\n",
|
||||
"\n",
|
||||
"The core dependencies you'll typically need are: `txtai` and `txtai[pipeline]`."
|
||||
]
|
||||
},
|
||||
{
|
||||
"cell_type": "code",
|
||||
"execution_count": null,
|
||||
"metadata": {
|
||||
"id": "czzRItdyN-Zj"
|
||||
},
|
||||
"outputs": [],
|
||||
"source": [
|
||||
"%%capture\n",
|
||||
"# The main point here is to follow the pattern of other notebooks.\n",
|
||||
"# For more information, kindly refer to the note in the bullet right below.\n",
|
||||
"\n",
|
||||
"# !pip install txtai==8.1.0\n",
|
||||
"# !pip install txtai[pipeline]\n",
|
||||
"!pip install git+https://github.com/neuml/txtai#egg=txtai[pipeline]\n",
|
||||
"\n",
|
||||
"# to use Vertex AI\n",
|
||||
"# https://github.com/BerriAI/litellm/issues/5483\n",
|
||||
"# !pip install google-cloud-aiplatform==1.75.0\n",
|
||||
"!pip install google-cloud-aiplatform\n",
|
||||
"\n",
|
||||
"# to use AWS Bedrock\n",
|
||||
"# https://docs.litellm.ai/docs/providers/bedrock\n",
|
||||
"# !pip install boto3==1.35.88\n",
|
||||
"!pip install boto3"
|
||||
]
|
||||
},
|
||||
{
|
||||
"cell_type": "markdown",
|
||||
"metadata": {
|
||||
"id": "evHD8Kw09Aa0"
|
||||
},
|
||||
"source": [
|
||||
"- _**A friendly reminder**: things can change unexpectedly in the ever-evolving world of coding. One day, your code works flawlessly; the next, it might throw a tantrum for no apparent reason. That's why it's essential to specify the dependencies' versions using the latest available versions when writing the code._\n",
|
||||
" - <sup><sub>Even recognizing the importance of version control, each version has one line above as a comment in the code. It serves as a guide to help you track dependencies and ensures the code runs smoothly across different environments, even if something goes awry.</sub></sup>\n",
|
||||
" - <sup><sub>While there is [a trade-off](https://github.com/neuml/txtai/pull/844#issuecomment-2564294186) in limiting code to a specific version, noting today's version as a comment should help you protect against potential issues with future updates.</sub></sup>"
|
||||
]
|
||||
},
|
||||
{
|
||||
"cell_type": "markdown",
|
||||
"metadata": {
|
||||
"id": "wuCvBPCL-VQG"
|
||||
},
|
||||
"source": [
|
||||
"## LLM API Configuration\n",
|
||||
"\n",
|
||||
"This session is like a special Python dictionary that holds all the cool configurations for our LLM AI model. It includes details like environment variables, the model's name, text embedding parameters, and other fancy settings.\n",
|
||||
"\n",
|
||||
"One important key here is `IS_ENABLED`. When it's set to `True`, it's like giving the model a green light to shine! But if you ever feel like taking a break or don't need it for a while, you can easily set this key to `False`, and the model will chill out."
|
||||
]
|
||||
},
|
||||
{
|
||||
"cell_type": "code",
|
||||
"execution_count": null,
|
||||
"metadata": {
|
||||
"colab": {
|
||||
"base_uri": "https://localhost:8080/"
|
||||
},
|
||||
"id": "jyahNyOrO2yp",
|
||||
"outputId": "8143c2b0-a6a9-429b-a66f-93f39e6885e4"
|
||||
},
|
||||
"outputs": [
|
||||
{
|
||||
"name": "stdout",
|
||||
"output_type": "stream",
|
||||
"text": [
|
||||
"config set!\n"
|
||||
]
|
||||
}
|
||||
],
|
||||
"source": [
|
||||
"import os, getpass\n",
|
||||
"from txtai import LLM, Embeddings\n",
|
||||
"\n",
|
||||
"# https://neuml.github.io/txtai/install/\n",
|
||||
"# https://neuml.github.io/txtai/pipeline/text/llm/#example\n",
|
||||
"# https://neuml.github.io/txtai/embeddings/configuration/vectors/#method\n",
|
||||
"# https://docs.litellm.ai/docs/embedding/supported_embedding\n",
|
||||
"LLM_MODEL_CONFIG = {\n",
|
||||
" 'GEMINI': {\n",
|
||||
" 'IS_ENABLED': True,\n",
|
||||
" 'ENV_VAR': ['GEMINI_API_KEY'],\n",
|
||||
" # https://docs.litellm.ai/docs/providers/gemini\n",
|
||||
" # https://ai.google.dev/gemini-api/docs/models/gemini\n",
|
||||
" 'LLM_MODEL_NAME': 'gemini/gemini-pro',\n",
|
||||
" # https://github.com/BerriAI/litellm/tree/12c4e7e695edb07d403dd14fc768a736638bd3d1/litellm/llms/vertex_ai\n",
|
||||
" # https://github.com/BerriAI/litellm/blob/e19bb55e3b4c6a858b6e364302ebbf6633a51de5/model_prices_and_context_window.json#L2625\n",
|
||||
" 'TEXT_EMBEDDING_PATH': 'gemini/text-embedding-004'\n",
|
||||
" },\n",
|
||||
" 'COHERE': {\n",
|
||||
" 'IS_ENABLED': False,\n",
|
||||
" 'ENV_VAR': ['COHERE_API_KEY'],\n",
|
||||
" # https://docs.litellm.ai/docs/providers/cohere\n",
|
||||
" 'LLM_MODEL_NAME': 'command-light',\n",
|
||||
" 'TEXT_EMBEDDING_PATH': 'cohere/embed-english-v3.0'\n",
|
||||
" },\n",
|
||||
" 'AWS_BEDROCK': {\n",
|
||||
" 'IS_ENABLED': False,\n",
|
||||
" 'ENV_VAR': ['AWS_ACCESS_KEY_ID', 'AWS_SECRET_ACCESS_KEY', 'AWS_REGION_NAME'],\n",
|
||||
" # https://docs.litellm.ai/docs/providers/bedrock\n",
|
||||
" 'LLM_MODEL_NAME': 'bedrock/amazon.titan-text-lite-v1',\n",
|
||||
" 'TEXT_EMBEDDING_PATH': 'amazon.titan-embed-text-v1'\n",
|
||||
" },\n",
|
||||
" 'MISTRAL': {\n",
|
||||
" 'IS_ENABLED': False,\n",
|
||||
" 'ENV_VAR': ['MISTRAL_API_KEY'],\n",
|
||||
" # https://docs.litellm.ai/docs/providers/mistral\n",
|
||||
" 'LLM_MODEL_NAME': 'mistral/mistral-tiny',\n",
|
||||
" 'TEXT_EMBEDDING_PATH': 'mistral/mistral-embed'\n",
|
||||
" },\n",
|
||||
" 'VERTEXAI': {\n",
|
||||
" 'IS_ENABLED': False,\n",
|
||||
" 'ENV_VAR': ['GOOGLE_APPLICATION_CREDENTIALS', 'GOOGLE_VERTEX_PROJECT', 'GOOGLE_VERTEX_LOCATION'],\n",
|
||||
" 'ENV_VAR_SETUP': None,\n",
|
||||
" # https://docs.litellm.ai/docs/providers/vertex\n",
|
||||
" 'LLM_MODEL_NAME': 'vertex_ai/gemini-pro',\n",
|
||||
" 'TEXT_EMBEDDING_PATH': 'vertex_ai/text-embedding-004'\n",
|
||||
" },\n",
|
||||
" 'GROQ': {\n",
|
||||
" 'IS_ENABLED': False,\n",
|
||||
" 'ENV_VAR': ['GROQ_API_KEY'],\n",
|
||||
" # https://docs.litellm.ai/docs/providers/groq\n",
|
||||
" # https://console.groq.com/docs/models\n",
|
||||
" 'LLM_MODEL_NAME': 'groq/llama3-8b-8192',\n",
|
||||
" # the line below has been commented out for a reason.\n",
|
||||
" # to understand why, check out the Groq section right below.\n",
|
||||
" # https://groq.com/retrieval-augmented-generation-with-groq-api/\n",
|
||||
" # 'TEXT_EMBEDDING_PATH': 'jinaai/jina-embeddings-v2-base-en',\n",
|
||||
" },\n",
|
||||
" 'OPENAI': {\n",
|
||||
" 'IS_ENABLED': False,\n",
|
||||
" 'ENV_VAR': ['OPENAI_API_KEY'],\n",
|
||||
" # https://docs.litellm.ai/docs/providers/openai\n",
|
||||
" # https://platform.openai.com/docs/models\n",
|
||||
" 'LLM_MODEL_NAME': 'gpt-4o-mini-2024-07-18',\n",
|
||||
" 'TEXT_EMBEDDING_PATH': 'text-embedding-3-small',\n",
|
||||
" },\n",
|
||||
" 'CLAUDE': {\n",
|
||||
" 'IS_ENABLED': False,\n",
|
||||
" # You might need the Voyage API key, depending on the embedding model you choose. Read more below!\n",
|
||||
" # 'ENV_VAR': ['ANTHROPIC_API_KEY', 'VOYAGE_API_KEY'],\n",
|
||||
" 'ENV_VAR': ['ANTHROPIC_API_KEY'],\n",
|
||||
" # https://docs.litellm.ai/docs/providers/anthropic\n",
|
||||
" # https://docs.anthropic.com/en/docs/about-claude/models\n",
|
||||
" 'LLM_MODEL_NAME': 'anthropic/claude-3-5-haiku-20241022',\n",
|
||||
" # the line below has been commented out for a reason.\n",
|
||||
" # to understand why, check out the Claude Anthropic section right below.\n",
|
||||
" # https://docs.anthropic.com/en/docs/build-with-claude/embeddings\n",
|
||||
" # 'TEXT_EMBEDDING_PATH': 'voyage/voyage-01',\n",
|
||||
" },\n",
|
||||
" 'VOYAGE': {\n",
|
||||
" 'IS_ENABLED': False,\n",
|
||||
" # You might need the Anthropic API key, depending on the LLM you choose. Read more below!\n",
|
||||
" # 'ENV_VAR': ['ANTHROPIC_API_KEY', 'VOYAGE_API_KEY'],\n",
|
||||
" 'ENV_VAR': ['VOYAGE_API_KEY'],\n",
|
||||
" # the line below has been commented out for a reason.\n",
|
||||
" # to understand why, check out the Voyage AI section right below.\n",
|
||||
" # https://docs.litellm.ai/docs/providers/voyage\n",
|
||||
" # https://docs.voyageai.com/docs/introduction\n",
|
||||
" # 'LLM_MODEL_NAME': 'anthropic/claude-3-5-haiku-20241022',\n",
|
||||
" #\n",
|
||||
" # https://docs.voyageai.com/docs/embeddings\n",
|
||||
" 'TEXT_EMBEDDING_PATH': 'voyage/voyage-01',\n",
|
||||
" }\n",
|
||||
"}\n",
|
||||
"\n",
|
||||
"import litellm\n",
|
||||
"# # https://github.com/BerriAI/litellm/blob/11932d0576a073d83f38a418cbdf6b2d8d4ff46f/litellm/litellm_core_utils/get_llm_provider_logic.py#L322\n",
|
||||
"litellm.suppress_debug_info = True\n",
|
||||
"# https://docs.litellm.ai/docs/debugging/local_debugging#set-verbose\n",
|
||||
"litellm.set_verbose=False\n",
|
||||
"\n",
|
||||
"def customsetup():\n",
|
||||
" def vertexai():\n",
|
||||
" # https://docs.litellm.ai/docs/embedding/supported_embedding#usage---embedding\n",
|
||||
" # https://docs.litellm.ai/docs/providers/vertex\n",
|
||||
" litellm.vertex_project = os.environ['GOOGLE_VERTEX_PROJECT']\n",
|
||||
" litellm.vertex_location = os.environ['GOOGLE_VERTEX_LOCATION']\n",
|
||||
"\n",
|
||||
" LLM_MODEL_CONFIG['VERTEXAI']['ENV_VAR_SETUP'] = vertexai()\n",
|
||||
"\n",
|
||||
"customsetup()\n",
|
||||
"\n",
|
||||
"LLM_MODELS = {k: v for k, v in LLM_MODEL_CONFIG.items() if v['IS_ENABLED']}\n",
|
||||
"ENV_VARS = [v['ENV_VAR'] for k, v in LLM_MODELS.items()]\n",
|
||||
"ENV_VARS = [x for xs in ENV_VARS for x in xs] # flatten array\n",
|
||||
"\n",
|
||||
"print(\"config set!\")"
|
||||
]
|
||||
},
|
||||
{
|
||||
"cell_type": "markdown",
|
||||
"metadata": {
|
||||
"id": "pgQuDv4fZgHe"
|
||||
},
|
||||
"source": [
|
||||
"### Vertex AI"
|
||||
]
|
||||
},
|
||||
{
|
||||
"cell_type": "markdown",
|
||||
"metadata": {
|
||||
"id": "wG_2u_jKTyYg"
|
||||
},
|
||||
"source": [
|
||||
"When working with VertexAI in a Jupyter notebook, an environment variable called `GOOGLE_APPLICATION_CREDENTIALS` points to a credentials file. This variable is like giving VertexAI a secret map to find the JSON file containing your service account key.\n",
|
||||
"\n",
|
||||
"Imagine you've set `GOOGLE_APPLICATION_CREDENTIALS` to `application_default_credentials.json`. The service account key is stored in a file with that exact name. And guess what? This file must be in the same place you're working _(your current working directory)_.\n",
|
||||
"\n",
|
||||
"Here's how your directory might look:\n",
|
||||
"```\n",
|
||||
".\n",
|
||||
"├── ..\n",
|
||||
"├── sample_data/\n",
|
||||
"└── application_default_credentials.json\n",
|
||||
"```\n",
|
||||
"\n",
|
||||
"If you use Google Colab, your directory structure will differ slightly, but don't worry! It'll look something like this:\n",
|
||||
"\n",
|
||||
"```\n",
|
||||
".\n",
|
||||
"├── bin\n",
|
||||
"├── boot\n",
|
||||
"├── content/\n",
|
||||
"│ ├── sample_data/\n",
|
||||
"│ └── application_default_credentials.json\n",
|
||||
"├── datalab\n",
|
||||
"├── dev\n",
|
||||
"├── etc\n",
|
||||
"├── home\n",
|
||||
"├── lib\n",
|
||||
"├── lib32\n",
|
||||
"└── lib64\n",
|
||||
"```\n"
|
||||
]
|
||||
},
|
||||
{
|
||||
"cell_type": "markdown",
|
||||
"metadata": {
|
||||
"id": "0KsLGZFtrZVT"
|
||||
},
|
||||
"source": [
|
||||
"### Groq"
|
||||
]
|
||||
},
|
||||
{
|
||||
"cell_type": "markdown",
|
||||
"metadata": {
|
||||
"id": "-4RUn2dUrcbZ"
|
||||
},
|
||||
"source": [
|
||||
"It's good to make the most of [free resources](https://github.com/BerriAI/litellm/issues/4922#issuecomment-2374234548) like this one! Of course, free options often come with some limitations, and this is no different. Currently, Groq doesn't offer an API for text embeddings.\n",
|
||||
"\n",
|
||||
"The Groq team highlights a pre-trained model that can be used locally. You can learn more about it on the [Groq Blog](https://groq.com/retrieval-augmented-generation-with-groq-api/), where they discuss the `jinaai/jina-embeddings-v2-base-en`, a model that can be hosted locally.\n",
|
||||
"\n",
|
||||
"This notebook primarily focuses on well-known online API models, so I've commented on the Groq line for text embedding. However, if you're curious, you can explore the model Groq recommends for local use by uncommenting it."
|
||||
]
|
||||
},
|
||||
{
|
||||
"cell_type": "markdown",
|
||||
"metadata": {
|
||||
"id": "I7a3d8EsrdBc"
|
||||
},
|
||||
"source": [
|
||||
"### Claude Anthropic"
|
||||
]
|
||||
},
|
||||
{
|
||||
"cell_type": "markdown",
|
||||
"metadata": {
|
||||
"id": "RHmrKCbZriz_"
|
||||
},
|
||||
"source": [
|
||||
"While Claude Anthropic isn't a free resource, they're well-known for their top-notch LLM outputs. The only tiny hiccup for this Notebook context is that they don't offer an API for text embeddings.\n",
|
||||
"\n",
|
||||
"But don't worry. In their documentation, they recommend checking out the Voyage AI embedding model. You can find all the deets right [here](https://docs.anthropic.com/en/docs/build-with-claude/embeddings).\n",
|
||||
"\n",
|
||||
"The Claude team highlights the Voyage AI embedding model on their documentation page. Voyage is an online resource, though the Claude Anthropic team does not host it.\n",
|
||||
"\n",
|
||||
"This notebook is about well-known online API models. So, I've commented on the Claude config line for text embedding. But if you're curious and want to explore the model Claude recommends, uncomment that line and explore away!"
|
||||
]
|
||||
},
|
||||
{
|
||||
"cell_type": "markdown",
|
||||
"metadata": {
|
||||
"id": "IYpWxGBR2COD"
|
||||
},
|
||||
"source": [
|
||||
"### Voyage AI"
|
||||
]
|
||||
},
|
||||
{
|
||||
"cell_type": "markdown",
|
||||
"metadata": {
|
||||
"id": "j6vIcO0A2FjD"
|
||||
},
|
||||
"source": [
|
||||
"Voyage AI provides only [top-notch embeddings](https://docs.voyageai.com/docs/introduction). While it doesn't offer [its LLM model](https://docs.voyageai.com/docs/embeddings), that doesn't diminish its offerings. The cool thing? Their embeddings are versatile and can be integrated into any model you choose. So, feel free to experiment and have fun with them! That's the beauty of this notebook - it's all about exploration and learning."
|
||||
]
|
||||
},
|
||||
{
|
||||
"cell_type": "markdown",
|
||||
"metadata": {
|
||||
"id": "xZg16h4KHpE5"
|
||||
},
|
||||
"source": [
|
||||
"## Environment Variables\n",
|
||||
"\n",
|
||||
"This session has scripts to reset or set environment variables _(env vars)_. Using env vars is a great way to keep those sensitive API KEY values safe and sound, away from unwanted eyes."
|
||||
]
|
||||
},
|
||||
{
|
||||
"cell_type": "markdown",
|
||||
"metadata": {
|
||||
"id": "Cqh5j0a4JcHg"
|
||||
},
|
||||
"source": [
|
||||
"### Script to Reset Environment Variables\n",
|
||||
"\n",
|
||||
"There are a bunch of reasons to reset the environment variable here. Let's go over a few:\n",
|
||||
"- **Switching API Keys:** Sometimes, we need to change to a different API key.\n",
|
||||
"- **Typos Happen:** We're all human, and typos can sneak in!\n",
|
||||
"- **Skipping Variables:** Sometimes we need to skip one or another, so we set the env var to empty.\n",
|
||||
"- **Fresh Start:** After tweaking a script or setup, it's always good to rerun with a fresh environment.\n"
|
||||
]
|
||||
},
|
||||
{
|
||||
"cell_type": "code",
|
||||
"execution_count": null,
|
||||
"metadata": {
|
||||
"id": "VejHDLF1aKub"
|
||||
},
|
||||
"outputs": [],
|
||||
"source": [
|
||||
"if 'MISTRAL_API_KEY' in os.environ:\n",
|
||||
" del os.environ['MISTRAL_API_KEY']"
|
||||
]
|
||||
},
|
||||
{
|
||||
"cell_type": "code",
|
||||
"execution_count": null,
|
||||
"metadata": {
|
||||
"colab": {
|
||||
"base_uri": "https://localhost:8080/"
|
||||
},
|
||||
"id": "vzrNvU5XJpIm",
|
||||
"outputId": "05181b36-caa8-417d-fcd6-159e15118594"
|
||||
},
|
||||
"outputs": [
|
||||
{
|
||||
"name": "stdout",
|
||||
"output_type": "stream",
|
||||
"text": [
|
||||
"unset env var: GEMINI_API_KEY\n",
|
||||
"unset env var: COHERE_API_KEY\n",
|
||||
"unset env var: AWS_ACCESS_KEY_ID\n",
|
||||
"unset env var: AWS_SECRET_ACCESS_KEY\n",
|
||||
"unset env var: AWS_REGION_NAME\n",
|
||||
"unset env var: MISTRAL_API_KEY\n",
|
||||
"unset env var: GOOGLE_APPLICATION_CREDENTIALS\n",
|
||||
"unset env var: GOOGLE_VERTEX_PROJECT\n",
|
||||
"unset env var: GOOGLE_VERTEX_LOCATION\n"
|
||||
]
|
||||
}
|
||||
],
|
||||
"source": [
|
||||
"for ENV_VARS in [v['ENV_VAR'] for k, v in LLM_MODEL_CONFIG.items()]:\n",
|
||||
" for ENV_VAR in ENV_VARS:\n",
|
||||
" if ENV_VAR in os.environ:\n",
|
||||
" del os.environ[ENV_VAR]\n",
|
||||
" print(f'unset env var: {ENV_VAR}')\n"
|
||||
]
|
||||
},
|
||||
{
|
||||
"cell_type": "markdown",
|
||||
"metadata": {
|
||||
"id": "GqZceA9qJIdq"
|
||||
},
|
||||
"source": [
|
||||
"### Script to Set Environment Variables\n",
|
||||
"\n",
|
||||
"In this session, the script will stroll through the config dictionary to cherry-pick only the enabled LLM models.\n",
|
||||
"\n",
|
||||
"Once your favorites have been gathered, the script will prompt you to set all the necessary environment variables.\n",
|
||||
"\n",
|
||||
"The more LLM models you have enabled, the more prompts you'll see - but don't worry, each environment variable will prompt only once."
|
||||
]
|
||||
},
|
||||
{
|
||||
"cell_type": "code",
|
||||
"execution_count": null,
|
||||
"metadata": {
|
||||
"colab": {
|
||||
"base_uri": "https://localhost:8080/"
|
||||
},
|
||||
"id": "zQmXuvbsHSwR",
|
||||
"outputId": "07e94a99-817b-4fae-e649-c6e0337bb1d1"
|
||||
},
|
||||
"outputs": [
|
||||
{
|
||||
"name": "stdout",
|
||||
"output_type": "stream",
|
||||
"text": [
|
||||
"enter GEMINI_API_KEY: ··········\n",
|
||||
"enter COHERE_API_KEY: ··········\n",
|
||||
"enter AWS_ACCESS_KEY_ID: ··········\n",
|
||||
"enter AWS_SECRET_ACCESS_KEY: ··········\n",
|
||||
"enter AWS_REGION_NAME: ··········\n",
|
||||
"enter MISTRAL_API_KEY: ··········\n",
|
||||
"enter GOOGLE_APPLICATION_CREDENTIALS: ··········\n",
|
||||
"enter GOOGLE_VERTEX_PROJECT: ··········\n",
|
||||
"enter GOOGLE_VERTEX_LOCATION: ··········\n",
|
||||
"enter GROQ_API_KEY: ··········\n",
|
||||
"enter OPENAI_API_KEY: ··········\n",
|
||||
"enter ANTHROPIC_API_KEY: ··········\n",
|
||||
"enter VOYAGE_API_KEY: ··········\n",
|
||||
"running custom env var setup for VERTEXAI...\n",
|
||||
"done setup for VERTEXAI\n",
|
||||
"all env var set!\n"
|
||||
]
|
||||
}
|
||||
],
|
||||
"source": [
|
||||
"for ENV_VAR in ENV_VARS:\n",
|
||||
" os.environ[ENV_VAR] = getpass.getpass(f\"enter {ENV_VAR}: \") if not ENV_VAR in os.environ else os.environ[ENV_VAR]\n",
|
||||
"\n",
|
||||
"LLM_MODELS_WITH_CUSTOM_SETUP = {k: v for k, v in LLM_MODELS.items() if 'ENV_VAR_SETUP' in v}\n",
|
||||
"for LLM_MODEL, LLM_CONFIG in LLM_MODELS_WITH_CUSTOM_SETUP.items():\n",
|
||||
" print(f\"running custom env var setup for {LLM_MODEL}...\")\n",
|
||||
" LLM_CONFIG['ENV_VAR_SETUP']()\n",
|
||||
" print(f\"done setup for {LLM_MODEL}\")\n",
|
||||
"\n",
|
||||
"print(\"all env var set!\")"
|
||||
]
|
||||
},
|
||||
{
|
||||
"cell_type": "markdown",
|
||||
"metadata": {
|
||||
"id": "tnTSFJZcJW5p"
|
||||
},
|
||||
"source": [
|
||||
"# Code Snippet\n",
|
||||
"\n",
|
||||
"You can run the code snippet after installing the necessary dependencies and setting up the required environment variables!\n",
|
||||
"\n",
|
||||
"\n"
|
||||
]
|
||||
},
|
||||
{
|
||||
"cell_type": "markdown",
|
||||
"metadata": {
|
||||
"id": "oPq-sHZifHFZ"
|
||||
},
|
||||
"source": [
|
||||
"## Introduction\n",
|
||||
"\n",
|
||||
"This code snippet is designed to achieve only two tasks: _(i)_ run an LLM Pipeline; _(ii)_ text Embed using the LLM Model."
|
||||
]
|
||||
},
|
||||
{
|
||||
"cell_type": "markdown",
|
||||
"metadata": {
|
||||
"id": "gKd9GB4UfJTt"
|
||||
},
|
||||
"source": [
|
||||
"The code snippet has two tasks:\n",
|
||||
"1. **Running an LLM Pipeline**:\n",
|
||||
" - To kickstart an LLM pipeline, you'll need a prompt and a model name. It's as simple as that!\n",
|
||||
"2. **Text Embedding using the LLM Model**:\n",
|
||||
" - To embed text with the LLM model, you'll need some text and the name of the text embedding model.\n",
|
||||
"\n",
|
||||
"In this script, we'll run an LLM pipeline for every given LLM and embed text using the provided LLM model.\n",
|
||||
"\n",
|
||||
"Here's the heart of the script:\n",
|
||||
"```python\n",
|
||||
"LLM_MODEL_NAME = \"model-name\"\n",
|
||||
"TEXT_EMBEDDING_PATH = \"text-embedding-name\"\n",
|
||||
"# A text prompt to send through the LLM pipeline\n",
|
||||
"LLM_PROMPT_INPUT = \"Where is one place you'd go in Washington, DC?\"\n",
|
||||
"# The embeddings dataset is versatile! It plays with lists, datasets, or even generators.\n",
|
||||
"EMBEDDING_DATA = [\n",
|
||||
" \"US tops 5 million confirmed virus cases\",\n",
|
||||
" \"Canada's last fully intact ice shelf has suddenly collapsed, forming a Manhattan-sized iceberg\",\n",
|
||||
" \"Beijing mobilises invasion craft along coast as Taiwan tensions escalate\"\n",
|
||||
"]\n",
|
||||
"# LLM PIPELINE\n",
|
||||
"llm = LLM(LLM_MODEL_NAME, method=\"litellm\")\n",
|
||||
"print(llm([{\"role\": \"user\", \"content\": LLM_PROMPT_INPUT}]))\n",
|
||||
"# TEXT EMBEDDING\n",
|
||||
"embeddings = Embeddings(path=TEXT_EMBEDDING_PATH, method=\"litellm\")\n",
|
||||
"embeddings.index(EMBEDDING_DATA) # create an index for the text list\n",
|
||||
"for query in (\"feel good story\", \"climate change\"): # now, let's embark on an embeddings search for each query\n",
|
||||
" # extract the uid of the first result\n",
|
||||
" # search result format: (uid, score)\n",
|
||||
" uid = embeddings.search(query, 1)[0][0]\n",
|
||||
" # print the text\n",
|
||||
" print(\"%-20s %s\" % (query, EMBEDDING_DATA[uid]))\n",
|
||||
"```\n",
|
||||
"\n",
|
||||
"- <sup><sub>**friendly reminder**: _the library's author often [points out](https://github.com/neuml/txtai/pull/844#issuecomment-2563561232) that it's [not necessary](https://github.com/neuml/txtai/issues/843#issuecomment-2563244810) to explicitly pass the second argument `method='litellm'`. When you're learning something new, it's okay to avoid relying on shortcuts or \"magic\" until you're more comfortable. Once you understand the library better, you can start using these convenient features to your advantage. In this introduction, I'm intentionally including the second argument `method='litellm'` in the function. However, I'm choosing to leave it out in the Playground section_.</sub></sup>"
|
||||
]
|
||||
},
|
||||
{
|
||||
"cell_type": "markdown",
|
||||
"metadata": {
|
||||
"id": "1I6o5f1ue_KX"
|
||||
},
|
||||
"source": [
|
||||
"## Playground\n",
|
||||
"\n",
|
||||
"Once you've installed the necessary dependencies and configured the environment variables, you can play with and explore the code snippet. Enjoy your coding journey! 😊\n"
|
||||
]
|
||||
},
|
||||
{
|
||||
"cell_type": "code",
|
||||
"execution_count": null,
|
||||
"metadata": {
|
||||
"colab": {
|
||||
"base_uri": "https://localhost:8080/"
|
||||
},
|
||||
"id": "A3NetE3Sh0e0",
|
||||
"outputId": "d9be990a-1f57-4abc-f2be-86f8e8ef7c6c"
|
||||
},
|
||||
"outputs": [
|
||||
{
|
||||
"name": "stdout",
|
||||
"output_type": "stream",
|
||||
"text": [
|
||||
"--------------------------------------------------\n",
|
||||
"GEMINI\n",
|
||||
"The National Mall\n",
|
||||
"..................................................\n",
|
||||
"Query Best Match\n",
|
||||
"..................................................\n",
|
||||
"feel good story Maine man wins $1M from $25 lottery ticket\n",
|
||||
"climate change Canada's last fully intact ice shelf has suddenly collapsed, forming a Manhattan-sized iceberg\n",
|
||||
"public health story US tops 5 million confirmed virus cases\n",
|
||||
"war Beijing mobilises invasion craft along coast as Taiwan tensions escalate\n",
|
||||
"wildlife The National Park Service warns against sacrificing slower friends in a bear attack\n",
|
||||
"asia Beijing mobilises invasion craft along coast as Taiwan tensions escalate\n",
|
||||
"lucky Maine man wins $1M from $25 lottery ticket\n",
|
||||
"dishonest junk Make huge profits without work, earn up to $100,000 a day\n",
|
||||
"--------------------------------------------------\n",
|
||||
"COHERE\n",
|
||||
"As an AI chatbot, I do not have personal preferences or the ability to travel. However, I can suggest popular tourist destinations in Washington, DC, that many people enjoy visiting:\n",
|
||||
"\n",
|
||||
"1. The White House: The official residence and workplace of the President of the United States is a symbol of American democracy. Visitors can take a tour of the White House to learn about its history and see the beautiful architecture.\n",
|
||||
"\n",
|
||||
"2. National Mall: This iconic open park stretches from the United States Capitol to the Lincoln Memorial, featuring various monuments and memorials. Some notable landmarks include the Washington Monument, the Lincoln Memorial Reflecting Pool, the Vietnam Veterans Memorial, and the National World War II Memorial.\n",
|
||||
"\n",
|
||||
"3. Smithsonian Institution: The world's largest museum and research complex offers a wealth of knowledge and cultural experiences. It includes renowned museums such as the National Air and Space Museum, National Museum of Natural History, National Museum of African American History and Culture, and many more, all offering free admission.\n",
|
||||
"\n",
|
||||
"4. United States Capitol: A visit to the Capitol allows you to explore the seat of the United States Congress and learn about the legislative process. The Capitol also features impressive architecture and art, including the iconic Capitol Dome and the National Statuary Hall Collection.\n",
|
||||
"\n",
|
||||
"5. National Gallery of Art: Located on the National Mall, this renowned art museum houses a vast collection of paintings, sculptures, and other artworks from the Middle Ages to the present. It offers a chance to appreciate works by famous artists like Leonardo da Vinci, Rembrandt, and Claude Monet.\n",
|
||||
"\n",
|
||||
"These are just a few highlights, but Washington, DC, offers many more attractions, including historic sites, beautiful parks, vibrant neighborhoods, and cultural institutions, ensuring there's something for everyone to enjoy.\n",
|
||||
"..................................................\n",
|
||||
"Query Best Match\n",
|
||||
"..................................................\n",
|
||||
"feel good story Maine man wins $1M from $25 lottery ticket\n",
|
||||
"climate change Canada's last fully intact ice shelf has suddenly collapsed, forming a Manhattan-sized iceberg\n",
|
||||
"public health story US tops 5 million confirmed virus cases\n",
|
||||
"war Beijing mobilises invasion craft along coast as Taiwan tensions escalate\n",
|
||||
"wildlife The National Park Service warns against sacrificing slower friends in a bear attack\n",
|
||||
"asia Beijing mobilises invasion craft along coast as Taiwan tensions escalate\n",
|
||||
"lucky Maine man wins $1M from $25 lottery ticket\n",
|
||||
"dishonest junk US tops 5 million confirmed virus cases\n",
|
||||
"--------------------------------------------------\n",
|
||||
"AWS_BEDROCK\n",
|
||||
"I'd recommend the Smithsonian National Air and Space Museum. It is located in Washington, DC, and is the world's largest and most visited museum complex.\n",
|
||||
"..................................................\n",
|
||||
"Query Best Match\n",
|
||||
"..................................................\n",
|
||||
"feel good story Maine man wins $1M from $25 lottery ticket\n",
|
||||
"climate change Canada's last fully intact ice shelf has suddenly collapsed, forming a Manhattan-sized iceberg\n",
|
||||
"public health story US tops 5 million confirmed virus cases\n",
|
||||
"war Beijing mobilises invasion craft along coast as Taiwan tensions escalate\n",
|
||||
"wildlife The National Park Service warns against sacrificing slower friends in a bear attack\n",
|
||||
"asia Beijing mobilises invasion craft along coast as Taiwan tensions escalate\n",
|
||||
"lucky Maine man wins $1M from $25 lottery ticket\n",
|
||||
"dishonest junk Make huge profits without work, earn up to $100,000 a day\n",
|
||||
"--------------------------------------------------\n",
|
||||
"MISTRAL\n",
|
||||
"I would love to visit the Smithsonian National Museum of Natural History in Washington, DC. It's one of the most popular and largest museums in the world, with a vast array of exhibits showcasing natural history, including dinosaur fossils, mineral and gemstone collections, and marine life. I find the diversity and depth of knowledge presented in this museum fascinating. Additionally, it's free to the public, which makes it an accessible and enjoyable experience for everyone.\n",
|
||||
"..................................................\n",
|
||||
"Query Best Match\n",
|
||||
"..................................................\n",
|
||||
"feel good story The National Park Service warns against sacrificing slower friends in a bear attack\n",
|
||||
"climate change Canada's last fully intact ice shelf has suddenly collapsed, forming a Manhattan-sized iceberg\n",
|
||||
"public health story The National Park Service warns against sacrificing slower friends in a bear attack\n",
|
||||
"war The National Park Service warns against sacrificing slower friends in a bear attack\n",
|
||||
"wildlife The National Park Service warns against sacrificing slower friends in a bear attack\n",
|
||||
"asia Canada's last fully intact ice shelf has suddenly collapsed, forming a Manhattan-sized iceberg\n",
|
||||
"lucky Maine man wins $1M from $25 lottery ticket\n",
|
||||
"dishonest junk Make huge profits without work, earn up to $100,000 a day\n",
|
||||
"--------------------------------------------------\n",
|
||||
"VERTEXAI\n",
|
||||
"Washington, DC, is a fascinating city with a wealth of historical and cultural attractions. If I had the opportunity to visit, I would definitely make a stop at the Smithsonian National Air and Space Museum. This museum is home to a vast collection of aircraft and spacecraft, from the Wright brothers' first plane to the Apollo 11 command module. I am particularly interested in the history of space exploration, so I would be excited to see these iconic artifacts up close.\n",
|
||||
"\n",
|
||||
"In addition to the Air and Space Museum, there are many other places in Washington, DC, that I would like to visit. The National Mall is a beautiful park that is home to many of the city's most famous monuments, including the Washington Monument, the Lincoln Memorial, and the Vietnam Veterans Memorial. I would also like to visit the White House, the Capitol Building, and the Supreme Court. These buildings are all important symbols of American democracy, and I would be honored to have the opportunity to see them in person.\n",
|
||||
"\n",
|
||||
"Washington, DC, is a city with a rich history and a bright future. I am confident that it will continue to be a major center of culture and government for many years to come.\n",
|
||||
"..................................................\n",
|
||||
"Query Best Match\n",
|
||||
"..................................................\n",
|
||||
"feel good story Maine man wins $1M from $25 lottery ticket\n",
|
||||
"climate change Canada's last fully intact ice shelf has suddenly collapsed, forming a Manhattan-sized iceberg\n",
|
||||
"public health story US tops 5 million confirmed virus cases\n",
|
||||
"war Beijing mobilises invasion craft along coast as Taiwan tensions escalate\n",
|
||||
"wildlife The National Park Service warns against sacrificing slower friends in a bear attack\n",
|
||||
"asia Beijing mobilises invasion craft along coast as Taiwan tensions escalate\n",
|
||||
"lucky Maine man wins $1M from $25 lottery ticket\n",
|
||||
"dishonest junk Make huge profits without work, earn up to $100,000 a day\n",
|
||||
"--------------------------------------------------\n",
|
||||
"GROQ\n",
|
||||
"Washington, D.C. is a city with a plethora of amazing places to visit! But, if I had to pick just one place, I'd recommend the National Mall.\n",
|
||||
"\n",
|
||||
"The National Mall is a beautiful stretch of parkland that stretches from the Lincoln Memorial to the United States Capitol Building. It's home to some of the city's most iconic landmarks, including the Washington Monument, World War II Memorial, and Vietnam Veterans Memorial.\n",
|
||||
"\n",
|
||||
"You can take a leisurely stroll along the Mall, enjoy the scenic views of the city, and stop at one of the many museums or memorials along the way. The National Mall is also a great place to people-watch, with street performers and musicians adding to the lively atmosphere.\n",
|
||||
"\n",
|
||||
"Personally, I'd recommend starting at the Lincoln Memorial, where you can take in the stunning views of the Reflecting Pool and the Washington Monument. From there, you can walk to the World War II Memorial, where you can pay your respects to the millions of Americans who served in the war.\n",
|
||||
"\n",
|
||||
"Overall, the National Mall is a must-see destination in Washington, D.C. – and it's completely free!\n",
|
||||
"--------------------------------------------------\n",
|
||||
"OPENAI\n",
|
||||
"One iconic place to visit in Washington, DC, is the National Mall. It's home to many famous monuments and memorials, including the Lincoln Memorial, the Washington Monument, and the Vietnam Veterans Memorial. The expansive park offers a great opportunity to explore the history and culture of the nation, and it's a beautiful spot for walking, picnicking, and enjoying the iconic views.\n",
|
||||
"..................................................\n",
|
||||
"Query Best Match\n",
|
||||
"..................................................\n",
|
||||
"feel good story Maine man wins $1M from $25 lottery ticket\n",
|
||||
"climate change Canada's last fully intact ice shelf has suddenly collapsed, forming a Manhattan-sized iceberg\n",
|
||||
"public health story US tops 5 million confirmed virus cases\n",
|
||||
"war Beijing mobilises invasion craft along coast as Taiwan tensions escalate\n",
|
||||
"wildlife The National Park Service warns against sacrificing slower friends in a bear attack\n",
|
||||
"asia Beijing mobilises invasion craft along coast as Taiwan tensions escalate\n",
|
||||
"lucky Maine man wins $1M from $25 lottery ticket\n",
|
||||
"dishonest junk Make huge profits without work, earn up to $100,000 a day\n",
|
||||
"--------------------------------------------------\n",
|
||||
"CLAUDE\n",
|
||||
"One great place to visit in Washington, DC is the Smithsonian National Air and Space Museum. It's located on the National Mall and features fascinating exhibits about aviation and space exploration, including famous aircraft and spacecraft like the Wright Brothers' plane and the Apollo 11 command module. The museum is free to enter and is very popular with visitors of all ages.\n",
|
||||
"--------------------------------------------------\n",
|
||||
"VOYAGE\n",
|
||||
"..................................................\n",
|
||||
"Query Best Match\n",
|
||||
"..................................................\n",
|
||||
"feel good story Maine man wins $1M from $25 lottery ticket\n",
|
||||
"climate change Canada's last fully intact ice shelf has suddenly collapsed, forming a Manhattan-sized iceberg\n",
|
||||
"public health story Maine man wins $1M from $25 lottery ticket\n",
|
||||
"war The National Park Service warns against sacrificing slower friends in a bear attack\n",
|
||||
"wildlife The National Park Service warns against sacrificing slower friends in a bear attack\n",
|
||||
"asia Beijing mobilises invasion craft along coast as Taiwan tensions escalate\n",
|
||||
"lucky Maine man wins $1M from $25 lottery ticket\n",
|
||||
"dishonest junk Make huge profits without work, earn up to $100,000 a day\n",
|
||||
"--------------------------------------------------\n"
|
||||
]
|
||||
}
|
||||
],
|
||||
"source": [
|
||||
"# A text prompt to run through the LLM pipeline\n",
|
||||
"# https://neuml.github.io/txtai/pipeline/text/llm/\n",
|
||||
"LLM_PROMPT_INPUT = \"Where is one place you'd go in Washington, DC?\"\n",
|
||||
"\n",
|
||||
"# The embeddings dataset is versatile! It plays with lists, datasets, or even generators.\n",
|
||||
"# https://neuml.github.io/txtai/embeddings/\n",
|
||||
"EMBEDDING_DATA = [\n",
|
||||
" \"US tops 5 million confirmed virus cases\",\n",
|
||||
" \"Canada's last fully intact ice shelf has suddenly collapsed, forming a Manhattan-sized iceberg\",\n",
|
||||
" \"Beijing mobilises invasion craft along coast as Taiwan tensions escalate\",\n",
|
||||
" \"The National Park Service warns against sacrificing slower friends in a bear attack\",\n",
|
||||
" \"Maine man wins $1M from $25 lottery ticket\",\n",
|
||||
" \"Make huge profits without work, earn up to $100,000 a day\"\n",
|
||||
"]\n",
|
||||
"\n",
|
||||
"# https://neuml.github.io/txtai/pipeline/text/llm/\n",
|
||||
"def runllm(prompt=\"\", path=None):\n",
|
||||
" if path:\n",
|
||||
" # A quick note: you can skip specifying the `method` argument.\n",
|
||||
" # There's an autodetection logic designed to recognize it as a `litellm` model.\n",
|
||||
" # \n",
|
||||
" # llm = LLM(LLM_MODEL_NAME, method=\"litellm\")\n",
|
||||
" # \n",
|
||||
" llm = LLM(path)\n",
|
||||
"\n",
|
||||
" # OR: print(llm(LLM_PROMPT_INPUT, defaultrole=\"user\"))\n",
|
||||
" print(llm([{\"role\": \"user\", \"content\": prompt}]))\n",
|
||||
"\n",
|
||||
"# https://neuml.github.io/txtai/embeddings/\n",
|
||||
"def runembeddings(data=None, path=None):\n",
|
||||
" if path:\n",
|
||||
" embeddings = Embeddings(\n",
|
||||
" path=path,\n",
|
||||
" # a quick note: you can skip specifying the `method` argument - there is autodetection logic\n",
|
||||
" # method=\"litellm\"\n",
|
||||
" )\n",
|
||||
" # create an index for the list of text\n",
|
||||
" embeddings.index(data)\n",
|
||||
"\n",
|
||||
" print(\".\" * 50)\n",
|
||||
" print(\"%-20s %s\" % (\"Query\", \"Best Match\"))\n",
|
||||
" print(\".\" * 50)\n",
|
||||
" \n",
|
||||
" # run an embeddings search for each query\n",
|
||||
" for query in (\"feel good story\", \"climate change\",\n",
|
||||
" \"public health story\", \"war\", \"wildlife\", \"asia\",\n",
|
||||
" \"lucky\", \"dishonest junk\"):\n",
|
||||
" # extract uid of first result\n",
|
||||
" # search result format: (uid, score)\n",
|
||||
" uid = embeddings.search(query, 1)[0][0]\n",
|
||||
" # print text\n",
|
||||
" print(\"%-20s %s\" % (query, data[uid]))\n",
|
||||
"\n",
|
||||
"# Let's LOOP THROUGH each enabled LLM and embedding model.\n",
|
||||
"for LLM_MODEL, LLM_CONFIG in LLM_MODELS.items():\n",
|
||||
" LLM_MODEL_NAME = LLM_CONFIG['LLM_MODEL_NAME'] if 'LLM_MODEL_NAME' in LLM_CONFIG else None\n",
|
||||
" TEXT_EMBEDDING_PATH = LLM_CONFIG['TEXT_EMBEDDING_PATH'] if 'TEXT_EMBEDDING_PATH' in LLM_CONFIG else None\n",
|
||||
" print(\"-\" * 50)\n",
|
||||
" print(LLM_MODEL)\n",
|
||||
"\n",
|
||||
" # https://neuml.github.io/txtai/pipeline/text/llm/\n",
|
||||
" runllm(prompt=LLM_PROMPT_INPUT, path=LLM_MODEL_NAME)\n",
|
||||
"\n",
|
||||
" # https://neuml.github.io/txtai/embeddings/\n",
|
||||
" runembeddings(data=EMBEDDING_DATA, path=TEXT_EMBEDDING_PATH)\n",
|
||||
"\n",
|
||||
"print(\"-\" * 50)"
|
||||
]
|
||||
}
|
||||
],
|
||||
"metadata": {
|
||||
"colab": {
|
||||
"collapsed_sections": [
|
||||
"lhrk9y766Lw1",
|
||||
"wuCvBPCL-VQG",
|
||||
"pgQuDv4fZgHe",
|
||||
"0KsLGZFtrZVT",
|
||||
"I7a3d8EsrdBc",
|
||||
"xZg16h4KHpE5",
|
||||
"Cqh5j0a4JcHg",
|
||||
"oPq-sHZifHFZ"
|
||||
],
|
||||
"provenance": [],
|
||||
"toc_visible": true
|
||||
},
|
||||
"kernelspec": {
|
||||
"display_name": "Python 3",
|
||||
"name": "python3"
|
||||
},
|
||||
"language_info": {
|
||||
"name": "python"
|
||||
}
|
||||
},
|
||||
"nbformat": 4,
|
||||
"nbformat_minor": 0
|
||||
}
|
||||
File diff suppressed because one or more lines are too long
File diff suppressed because one or more lines are too long
@@ -0,0 +1,275 @@
|
||||
{
|
||||
"cells": [
|
||||
{
|
||||
"cell_type": "markdown",
|
||||
"metadata": {},
|
||||
"source": [
|
||||
"# Chunking your data for RAG\n",
|
||||
"\n",
|
||||
"One of the major workflows in `txtai` is Retrieval Augmented Generation (RAG). Large Language Models (LLM) are built to generate coherent sounding text. While in many cases it is factually accurate, that is not what they're built to do. RAG steps in to help inject smaller pieces of knowledge into a LLM prompt and increase the overall accuracy of responses. The `R` in RAG is very important.\n",
|
||||
"\n",
|
||||
"This notebook will demonstrate how to extract, chunk and index text to support retrieval operations for RAG."
|
||||
]
|
||||
},
|
||||
{
|
||||
"cell_type": "markdown",
|
||||
"metadata": {},
|
||||
"source": [
|
||||
"# Install dependencies\n",
|
||||
"\n",
|
||||
"Install `txtai` and all dependencies."
|
||||
]
|
||||
},
|
||||
{
|
||||
"cell_type": "code",
|
||||
"execution_count": null,
|
||||
"metadata": {},
|
||||
"outputs": [],
|
||||
"source": [
|
||||
"%%capture\n",
|
||||
"!pip install git+https://github.com/neuml/txtai#egg=txtai[pipeline-data]"
|
||||
]
|
||||
},
|
||||
{
|
||||
"cell_type": "markdown",
|
||||
"metadata": {},
|
||||
"source": [
|
||||
"# Data chunking and indexing\n",
|
||||
"\n",
|
||||
"Let's dive right in and keep this example simple. The next section creates a [Textractor pipeline](https://neuml.github.io/txtai/pipeline/data/textractor/) and an [Embeddings database](https://neuml.github.io/txtai/embeddings/).\n",
|
||||
"\n",
|
||||
"The `Textractor` extracts chunks of text from files and the `Embeddings` takes those chunks and builds an index/database. We'll use a [late chunker](https://docs.chonkie.ai/chunkers/late-chunker) backed by [Chonkie](https://github.com/chonkie-inc/chonkie).\n",
|
||||
"\n",
|
||||
"Then, we'll build an indexing workflow that streams chunks from two files."
|
||||
]
|
||||
},
|
||||
{
|
||||
"cell_type": "code",
|
||||
"execution_count": null,
|
||||
"metadata": {},
|
||||
"outputs": [],
|
||||
"source": [
|
||||
"from txtai import Embeddings\n",
|
||||
"from txtai.pipeline import Textractor\n",
|
||||
"\n",
|
||||
"# Text extraction pipeline with late chunking via Chonkie\n",
|
||||
"textractor = Textractor(chunker=\"late\")\n",
|
||||
"embeddings = Embeddings(content=True)"
|
||||
]
|
||||
},
|
||||
{
|
||||
"cell_type": "code",
|
||||
"execution_count": null,
|
||||
"metadata": {},
|
||||
"outputs": [],
|
||||
"source": [
|
||||
"def stream():\n",
|
||||
" urls = [\"https://github.com/neuml/txtai\", \"https://arxiv.org/pdf/2005.11401\"]\n",
|
||||
" for x, url in enumerate(urls):\n",
|
||||
" chunks = textractor(url)\n",
|
||||
" \n",
|
||||
" # Add all chunks - use the same document id for each chunk\n",
|
||||
" for chunk in chunks:\n",
|
||||
" yield x, chunk\n",
|
||||
"\n",
|
||||
" # Add the document metadata with the same document id\n",
|
||||
" # Can be any metadata. Can also be the entire document.\n",
|
||||
" yield x, {\"url\": url}\n",
|
||||
"\n",
|
||||
"# Index the chunks and metadata\n",
|
||||
"embeddings.index(stream())"
|
||||
]
|
||||
},
|
||||
{
|
||||
"cell_type": "markdown",
|
||||
"metadata": {},
|
||||
"source": [
|
||||
"A key element of `txtai` that is commonly misunderstood is how to best store chunks of data and join them back to the main document. `txtai` allows re-using the same logical id multiple times.\n",
|
||||
"\n",
|
||||
"Behind the scenes, each chunk gets it's own unique index id. The backend database stores chunks in a table called `sections` and data in a table called `documents`. This has been the case as far back as `txtai` 4.0. `txtai` also has the ability to store associated binary data in a table called `objects`. It's important to note that each associated `document` or `object` is only stored once. \n",
|
||||
"\n",
|
||||
"To illustrate, let's look at the first 20 rows in the embeddings database created."
|
||||
]
|
||||
},
|
||||
{
|
||||
"cell_type": "code",
|
||||
"execution_count": 63,
|
||||
"metadata": {},
|
||||
"outputs": [
|
||||
{
|
||||
"name": "stdout",
|
||||
"output_type": "stream",
|
||||
"text": [
|
||||
"{'indexid': 0, 'id': '0', 'url': 'https://github.com/neuml/txtai', 'text': '**GitHub - neuml/txtai: 💡 All-in-one open-source embeddings database for semantic search, LLM orchestration and language model workflows**\\n\\n*💡 All-in-one open-source embeddings database for semantic search, LLM orchestration and language model workflows - neuml/txtai*\\n\\n\\n\\n**All-in-one embeddings database** \\ntxtai is an all-in-one embeddings database for semantic search, LLM orchestration and language model workflows.\\n\\nEmbeddings databases are a union of vector indexes (sparse and dense), graph networks and relational databases.\\n\\nThis foundation enables vector search and/or serves as a powerful knowledge source for large language model (LLM) applications.\\n\\nBuild autonomous agents, retrieval augmented generation (RAG) processes, multi-model workflows and more.\\n\\nSummary of txtai features:\\n\\n- 🔎 Vector search with SQL, object storage, topic modeling, graph analysis and multimodal indexing\\n- 📄 Create embeddings for text, documents, audio, images and video\\n- 💡 Pipelines powered by language models that run LLM prompts, question-answering, labeling, transcription, translation, summarization and more\\n- ↪️️ Workflows to join pipelines together and aggregate business logic. txtai processes can be simple microservices or multi-model workflows.\\n- 🤖 Agents that intelligently connect embeddings, pipelines, workflows and other agents together to autonomously solve complex problems\\n- ⚙️ Build with Python or YAML. API bindings available for [JavaScript](https://github.com/neuml/txtai.js) , [Java](https://github.com/neuml/txtai.java) , [Rust](https://github.com/neuml/txtai.rs) and [Go](https://github.com/neuml/txtai.go) .\\n- 🔋 Batteries included with defaults to get up and running fast\\n- ☁️ Run local or scale out with container orchestration\\ntxtai is built with Python 3.11+, [Hugging Face Transformers](https://github.com/huggingface/transformers) , [Sentence Transformers](https://github.'}\n",
|
||||
"{'indexid': 1, 'id': '0', 'url': 'https://github.com/neuml/txtai', 'text': 'com/UKPLab/sentence-transformers) and [FastAPI](https://github.com/tiangolo/fastapi) . txtai is open-source under an Apache 2.0 license.\\n\\n*Interested in an easy and secure way to run hosted txtai applications? Then join the* [txtai.cloud](https://txtai.cloud) *preview to learn more.* \\n\\n## Why txtai?\\nNew vector databases, LLM frameworks and everything in between are sprouting up daily. Why build with txtai?\\n\\n- Up and running in minutes with [pip](https://neuml.github.io/txtai/install/) or [Docker](https://neuml.github.io/txtai/cloud/) \\n```\\n# Get started in a couple lines\\nimport txtai\\n\\nembeddings = txtai.Embeddings()\\nembeddings.index([\"Correct\", \"Not what we hoped\"])\\nembeddings.search(\"positive\", 1)\\n#[(0, 0.29862046241760254)]\\n```\\n\\n- Built-in API makes it easy to develop applications using your programming language of choice\\n```\\n# app.yml\\nembeddings:\\n path: sentence-transformers/all-MiniLM-L6-v2\\n```\\n\\n```\\nCONFIG=app.yml uvicorn \"txtai.api:app\"\\ncurl -X GET \"http://localhost:8000/search?query=positive\"\\n```\\n\\n- Run local - no need to ship data off to disparate remote services\\n- Work with micromodels all the way up to large language models (LLMs)\\n- Low footprint - install additional dependencies and scale up when needed\\n- [Learn by example](https://neuml.github.io/txtai/examples) - notebooks cover all available functionality\\n\\n## Use Cases\\nThe following sections introduce common txtai use cases. A comprehensive set of over 60 [example notebooks and applications](https://neuml.github.io/txtai/examples) are also available.\\n\\n\\n### Semantic Search\\nBuild semantic/similarity/vector/neural search applications.'}\n",
|
||||
"{'indexid': 2, 'id': '0', 'url': 'https://github.com/neuml/txtai', 'text': 'Traditional search systems use keywords to find data. Semantic search has an understanding of natural language and identifies results that have the same meaning, not necessarily the same keywords.\\n\\nGet started with the following examples.\\n\\n|Notebook|Description||\\n|---|---|---|\\n|[Introducing txtai](https://github.com/neuml/txtai/blob/master/examples/01_Introducing_txtai.ipynb) |Overview of the functionality provided by txtai||\\n|[Similarity search with images](https://github.com/neuml/txtai/blob/master/examples/13_Similarity_search_with_images.ipynb) |Embed images and text into the same space for search||\\n|[Build a QA database](https://github.com/neuml/txtai/blob/master/examples/34_Build_a_QA_database.ipynb) |Question matching with semantic search||\\n|[Semantic Graphs](https://github.com/neuml/txtai/blob/master/examples/38_Introducing_the_Semantic_Graph.ipynb) |Explore topics, data connectivity and run network analysis||\\n\\n### LLM Orchestration\\nAutonomous agents, retrieval augmented generation (RAG), chat with your data, pipelines and workflows that interface with large language models (LLMs).\\n\\nSee below to learn more.\\n\\n|Notebook|Description||\\n|---|---|---|\\n|[Prompt templates and task chains](https://github.com/neuml/txtai/blob/master/examples/44_Prompt_templates_and_task_chains.ipynb) |Build model prompts and connect tasks together with workflows||\\n|[Integrate LLM frameworks](https://github.com/neuml/txtai/blob/master/examples/53_Integrate_LLM_Frameworks.ipynb) |Integrate llama.cpp, LiteLLM and custom generation frameworks||\\n|[Build knowledge graphs with LLMs](https://github.'}\n",
|
||||
"{'indexid': 3, 'id': '0', 'url': 'https://github.com/neuml/txtai', 'text': 'com/neuml/txtai/blob/master/examples/57_Build_knowledge_graphs_with_LLM_driven_entity_extraction.ipynb) |Build knowledge graphs with LLM-driven entity extraction||\\n\\n#### Agents\\nAgents connect embeddings, pipelines, workflows and other agents together to autonomously solve complex problems.\\n\\ntxtai agents are built on top of the Transformers Agent framework. This supports all LLMs txtai supports (Hugging Face, llama.cpp, OpenAI / Claude / AWS Bedrock via LiteLLM).\\n\\nSee the link below to learn more.\\n\\n|Notebook|Description||\\n|---|---|---|\\n|[Analyzing Hugging Face Posts with Graphs and Agents](https://github.com/neuml/txtai/blob/master/examples/68_Analyzing_Hugging_Face_Posts_with_Graphs_and_Agents.ipynb) |Explore a rich dataset with Graph Analysis and Agents||\\n|[Granting autonomy to agents](https://github.com/neuml/txtai/blob/master/examples/69_Granting_autonomy_to_agents.ipynb) |Agents that iteratively solve problems as they see fit||\\n|[Analyzing LinkedIn Company Posts with Graphs and Agents](https://github.com/neuml/txtai/blob/master/examples/71_Analyzing_LinkedIn_Company_Posts_with_Graphs_and_Agents.ipynb) |Exploring how to improve social media engagement with AI||\\n\\n#### Retrieval augmented generation\\nRetrieval augmented generation (RAG) reduces the risk of LLM hallucinations by constraining the output with a knowledge base as context. RAG is commonly used to \"chat with your data\".\\n\\nA novel feature of txtai is that it can provide both an answer and source citation.\\n\\n|Notebook|Description||\\n|---|---|---|\\n|[Build RAG pipelines with txtai](https://github.'}\n",
|
||||
"{'indexid': 4, 'id': '0', 'url': 'https://github.com/neuml/txtai', 'text': 'com/neuml/txtai/blob/master/examples/52_Build_RAG_pipelines_with_txtai.ipynb) |Guide on retrieval augmented generation including how to create citations||\\n|[How RAG with txtai works](https://github.com/neuml/txtai/blob/master/examples/63_How_RAG_with_txtai_works.ipynb) |Create RAG processes, API services and Docker instances||\\n|[Advanced RAG with graph path traversal](https://github.com/neuml/txtai/blob/master/examples/58_Advanced_RAG_with_graph_path_traversal.ipynb) |Graph path traversal to collect complex sets of data for advanced RAG||\\n|[Speech to Speech RAG](https://github.com/neuml/txtai/blob/master/examples/65_Speech_to_Speech_RAG.ipynb) |Full cycle speech to speech workflow with RAG||\\n\\n### Language Model Workflows\\nLanguage model workflows, also known as semantic workflows, connect language models together to build intelligent applications.\\n\\nWhile LLMs are powerful, there are plenty of smaller, more specialized models that work better and faster for specific tasks. This includes models for extractive question-answering, automatic summarization, text-to-speech, transcription and translation.\\n\\n|Notebook|Description||\\n|---|---|---|\\n|[Run pipeline workflows](https://github.com/neuml/txtai/blob/master/examples/14_Run_pipeline_workflows.ipynb) |Simple yet powerful constructs to efficiently process data||\\n|[Building abstractive text summaries](https://github.com/neuml/txtai/blob/master/examples/09_Building_abstractive_text_summaries.ipynb) |Run abstractive text summarization||\\n|[Transcribe audio to text](https://github.com/neuml/txtai/blob/master/examples/11_Transcribe_audio_to_text.'}\n",
|
||||
"{'indexid': 5, 'id': '0', 'url': 'https://github.com/neuml/txtai', 'text': 'ipynb) |Convert audio files to text||\\n|[Translate text between languages](https://github.com/neuml/txtai/blob/master/examples/12_Translate_text_between_languages.ipynb) |Streamline machine translation and language detection||\\n\\n## Installation\\nThe easiest way to install is via pip and PyPI\\n\\n```\\npip install txtai\\n```\\n\\nPython 3.11+ is supported. Using a Python [virtual environment](https://docs.python.org/3/library/venv.html) is recommended.\\n\\nSee the detailed [install instructions](https://neuml.github.io/txtai/install) for more information covering [optional dependencies](https://neuml.github.io/txtai/install/#optional-dependencies) , [environment specific prerequisites](https://neuml.github.io/txtai/install/#environment-specific-prerequisites) , [installing from source](https://neuml.github.io/txtai/install/#install-from-source) , [conda support](https://neuml.github.io/txtai/install/#conda) and how to [run with containers](https://neuml.github.io/txtai/cloud) .\\n\\n\\n## Model guide\\nSee the table below for the current recommended models. These models all allow commercial use and offer a blend of speed and performance.\\n\\n|Component|Model(s)|\\n|---|---|\\n|[Embeddings](https://neuml.github.io/txtai/embeddings) |[all-MiniLM-L6-v2](https://hf.co/sentence-transformers/all-MiniLM-L6-v2) |\\n|[Image Captions](https://neuml.github.io/txtai/pipeline/image/caption) |[BLIP](https://hf.co/Salesforce/blip-image-captioning-base) |'}\n",
|
||||
"{'indexid': 6, 'id': '0', 'url': 'https://github.com/neuml/txtai', 'text': '|[Labels - Zero Shot](https://neuml.github.io/txtai/pipeline/text/labels) |[BART-Large-MNLI](https://hf.co/facebook/bart-large) |\\n|[Labels - Fixed](https://neuml.github.io/txtai/pipeline/text/labels) |Fine-tune with [training pipeline](https://neuml.github.io/txtai/pipeline/train/trainer) |\\n|[Large Language Model (LLM)](https://neuml.github.io/txtai/pipeline/text/llm) |[Llama 3.1 Instruct](https://hf.co/meta-llama/Llama-3.1-8B-Instruct) |\\n|[Summarization](https://neuml.github.io/txtai/pipeline/text/summary) |[DistilBART](https://hf.co/sshleifer/distilbart-cnn-12-6) |\\n|[Text-to-Speech](https://neuml.github.io/txtai/pipeline/audio/texttospeech) |[ESPnet JETS](https://hf.co/NeuML/ljspeech-jets-onnx) |\\n|[Transcription](https://neuml.github.io/txtai/pipeline/audio/transcription) |[Whisper](https://hf.co/openai/whisper-base) |\\n|[Translation](https://neuml.github.io/txtai/pipeline/text/translation) |[OPUS Model Series](https://hf.co/Helsinki-NLP) |\\nModels can be loaded as either a path from the Hugging Face Hub or a local directory. Model paths are optional, defaults are loaded when not specified. For tasks with no recommended model, txtai uses the default models as shown in the Hugging Face Tasks guide.\\n\\nSee the following links to learn more.\\n\\n\\n## Powered by txtai\\nThe following applications are powered by txtai.'}\n",
|
||||
"{'indexid': 7, 'id': '0', 'url': 'https://github.com/neuml/txtai', 'text': \"|Application|Description|\\n|---|---|\\n|[rag](https://github.com/neuml/rag) |Retrieval Augmented Generation (RAG) application|\\n|[ragdata](https://github.com/neuml/ragdata) |Build knowledge bases for RAG|\\n|[paperai](https://github.com/neuml/paperai) |Semantic search and workflows for medical/scientific papers|\\n|[annotateai](https://github.com/neuml/annotateai) |Automatically annotate papers with LLMs|\\nIn addition to this list, there are also many other [open-source projects](https://github.com/neuml/txtai/network/dependents) , [published research](https://scholar.google.com/scholar?q=txtai&hl=en&as_ylo=2022) and closed proprietary/commercial projects that have built on txtai in production.\\n\\n\\n## Further Reading\\n- [Tutorial series on Hashnode](https://neuml.hashnode.dev/series/txtai-tutorial) | [dev.to](https://dev.to/neuml/tutorial-series-on-txtai-ibg) \\n- [What's new in txtai 8.0](https://medium.com/neuml/whats-new-in-txtai-8-0-2d7d0ab4506b) | [7.0](https://medium.com/neuml/whats-new-in-txtai-7-0-855ad6a55440) | [6.0](https://medium.com/neuml/whats-new-in-txtai-6-0-7d93eeedf804) | [5.0](https://medium.com/neuml/whats-new-in-txtai-5-0-e5c75a13b101) | [4.0](https://medium.\"}\n",
|
||||
"{'indexid': 8, 'id': '0', 'url': 'https://github.com/neuml/txtai', 'text': 'com/neuml/whats-new-in-txtai-4-0-bbc3a65c3d1c) \\n- [Getting started with semantic search](https://medium.com/neuml/getting-started-with-semantic-search-a9fd9d8a48cf) | [workflows](https://medium.com/neuml/getting-started-with-semantic-workflows-2fefda6165d9) | [rag](https://medium.com/neuml/getting-started-with-rag-9a0cca75f748) \\n\\n## Documentation\\n[Full documentation on txtai](https://neuml.github.io/txtai) including configuration settings for embeddings, pipelines, workflows, API and a FAQ with common questions/issues is available.\\n\\n\\n## Contributing\\nFor those who would like to contribute to txtai, please see [this guide](https://github.com/neuml/.github/blob/master/CONTRIBUTING.md) .'}\n",
|
||||
"{'indexid': 9, 'id': '1', 'url': 'https://arxiv.org/pdf/2005.11401', 'text': 'Retrieval-Augmented Generation for\\nKnowledge-Intensive NLP Tasks\\n\\nPatrick Lewis†‡, Ethan Perez?,\\n\\nAleksandra Piktus†, Fabio Petroni†, Vladimir Karpukhin†, Naman Goyal†, Heinrich Küttler†,\\n\\nMike Lewis†, Wen-tau Yih†, Tim Rocktäschel†‡, Sebastian Riedel†‡, Douwe Kiela†\\n\\n†Facebook AI Research; ‡University College London; ?New York University;\\[email protected]\\n\\nAbstract\\n\\nLarge pre-trained language models have been shown to store factual knowledge\\nin their parameters, and achieve state-of-the-art results when fine-tuned on down-\\nstream NLP tasks. However, their ability to access and precisely manipulate knowl-\\nedge is still limited, and hence on knowledge-intensive tasks, their performance\\nlags behind task-specific architectures. Additionally, providing provenance for their\\ndecisions and updating their world knowledge remain open research problems. Pre-\\ntrained models with a differentiable access mechanism to explicit non-parametric\\nmemory have so far been only investigated for extractive downstream tasks. We\\nexplore a general-purpose fine-tuning recipe for retrieval-augmented generation\\n(RAG) — models which combine pre-trained parametric and non-parametric mem-\\nory for language generation. We introduce RAG models where the parametric\\nmemory is a pre-trained seq2seq model and the non-parametric memory is a dense\\nvector index of Wikipedia, accessed with a pre-trained neural retriever. We com-\\npare two RAG formulations, one which conditions on the same retrieved passages\\nacross the whole generated sequence, and another which can use different passages\\nper token. We fine-tune and evaluate our models on a wide range of knowledge-\\nintensive NLP tasks and set the state of the art on three open domain QA tasks,\\noutperforming parametric seq2seq models and task-specific retrieve-and-extract\\narchitectures. For language generation tasks, we find that RAG models generate\\nmore specific, diverse and factual language than a state-of-the-art parametric-only\\nseq2seq baseline.\\n\\n1 Introduction\\n\\nPre-trained neural language models have been shown to learn a substantial amount of in-depth knowl-\\nedge from data [47]. They can do so without any access to an external memory, as a parameterized\\nimplicit knowledge base [51, 52].'}\n",
|
||||
"{'indexid': 10, 'id': '1', 'url': 'https://arxiv.org/pdf/2005.11401', 'text': 'While this development is exciting, such models do have down-\\nsides: They cannot easily expand or revise their memory, can’t straightforwardly provide insight into\\ntheir predictions, and may produce “hallucinations” [38]. Hybrid models that combine parametric\\nmemory with non-parametric (i.e., retrieval-based) memories [20, 26, 48] can address some of these\\nissues because knowledge can be directly revised and expanded, and accessed knowledge can be\\ninspected and interpreted. REALM [20] and ORQA [31], two recently introduced models that\\ncombine masked language models [8] with a differentiable retriever, have shown promising results,\\n\\nar\\nX\\n\\niv\\n:2\\n\\n00\\n5.\\n\\n11\\n40\\n\\n1v\\n4 \\n\\n [\\ncs\\n\\n.C\\nL\\n\\n] \\n 1\\n\\n2 \\nA\\n\\npr\\n 2\\n\\n02\\n1\\n\\n\\nThe\\tDivine\\nComedy\\t(x) q\\n\\nQuery\\nEncoder\\n\\nq(x)\\n\\nMIPS pθ\\n\\nGenerator\\xa0pθ\\n(Parametric)\\n\\nMargin-\\nalize\\n\\nThis\\t14th\\tcentury\\twork\\nis\\tdivided\\tinto\\t3\\nsections:\\t\"Inferno\",\\n\"Purgatorio\"\\t&\\n\"Paradiso\"\\t\\t\\t\\t\\t\\t\\t\\t\\t(y)\\n\\nEnd-to-End Backprop through q and\\xa0pθ\\n\\nBarack\\tObama\\twas\\nborn\\tin\\tHawaii.(x)\\n\\nFact Verification: Fact Query\\n\\nsupports\\t(y)\\n\\nQuestion Generation\\n\\nFact Verification:\\nLabel Generation\\n\\nDocument\\nIndex\\n\\nDefine\\t\"middle\\tear\"(x)\\n\\nQuestion Answering:\\nQuestion Query\\n\\nThe\\tmiddle\\tear\\tincludes\\nthe\\ttympanic\\tcavity\\tand\\nthe\\tthree\\tossicles.\\t\\t(y)\\n\\nQuestion Answering:\\nAnswer GenerationRetriever pη\\n\\n(Non-Parametric)\\nz4\\n\\nz3\\nz2\\n\\nz1\\n\\nd(z)\\n\\nJeopardy Question\\nGeneration:\\n\\nAnswer Query\\n\\nFigure 1: Overview of our approach. We combine a pre-trained retriever (Query Encoder + Document\\nIndex) with a pre-trained seq2seq model (Generator) and fine-tune end-to-end. For query x, we use\\nMaximum Inner Product Search (MIPS) to find the top-K documents zi. For final prediction y, we\\ntreat z as a latent variable and marginalize over seq2seq predictions given different documents.\\n\\nbut have only explored open-domain extractive question answering. Here, we bring hybrid parametric\\nand non-parametric memory to the “workhorse of NLP,” i.e. sequence-to-sequence (seq2seq) models.\\n\\nWe endow pre-trained, parametric-memory generation models with a non-parametric memory through'}\n",
|
||||
"{'indexid': 11, 'id': '1', 'url': 'https://arxiv.org/pdf/2005.11401', 'text': 'a general-purpose fine-tuning approach which we refer to as retrieval-augmented generation (RAG).\\nWe build RAG models where the parametric memory is a pre-trained seq2seq transformer, and the\\nnon-parametric memory is a dense vector index of Wikipedia, accessed with a pre-trained neural\\nretriever. We combine these components in a probabilistic model trained end-to-end (Fig. 1). The\\nretriever (Dense Passage Retriever [26], henceforth DPR) provides latent documents conditioned on\\nthe input, and the seq2seq model (BART [32]) then conditions on these latent documents together with\\nthe input to generate the output. We marginalize the latent documents with a top-K approximation,\\neither on a per-output basis (assuming the same document is responsible for all tokens) or a per-token\\nbasis (where different documents are responsible for different tokens). Like T5 [51] or BART, RAG\\ncan be fine-tuned on any seq2seq task, whereby both the generator and retriever are jointly learned.\\n\\nThere has been extensive previous work proposing architectures to enrich systems with non-parametric\\nmemory which are trained from scratch for specific tasks, e.g. memory networks [64, 55], stack-\\naugmented networks [25] and memory layers [30]. In contrast, we explore a setting where both\\nparametric and non-parametric memory components are pre-trained and pre-loaded with extensive\\nknowledge. Crucially, by using pre-trained access mechanisms, the ability to access knowledge is\\npresent without additional training.\\n\\nOur results highlight the benefits of combining parametric and non-parametric memory with genera-\\ntion for knowledge-intensive tasks—tasks that humans could not reasonably be expected to perform\\nwithout access to an external knowledge source. Our RAG models achieve state-of-the-art results\\non open Natural Questions [29], WebQuestions [3] and CuratedTrec [2] and strongly outperform\\nrecent approaches that use specialised pre-training objectives on TriviaQA [24]. Despite these being'}\n",
|
||||
"{'indexid': 12, 'id': '1', 'url': 'https://arxiv.org/pdf/2005.11401', 'text': 'extractive tasks, we find that unconstrained generation outperforms previous extractive approaches.\\nFor knowledge-intensive generation, we experiment with MS-MARCO [1] and Jeopardy question\\ngeneration, and we find that our models generate responses that are more factual, specific, and\\ndiverse than a BART baseline. For FEVER [56] fact verification, we achieve results within 4.3% of\\nstate-of-the-art pipeline models which use strong retrieval supervision. Finally, we demonstrate that\\nthe non-parametric memory can be replaced to update the models’ knowledge as the world changes.1\\n\\n2 Methods\\n\\nWe explore RAG models, which use the input sequence x to retrieve text documents z and use them\\nas additional context when generating the target sequence y. As shown in Figure 1, our models\\nleverage two components: (i) a retriever pη(z|x) with parameters η that returns (top-K truncated)\\ndistributions over text passages given a query x and (ii) a generator pθ(yi|x, z, y1:i−1) parametrized\\n\\n1Code to run experiments with RAG has been open-sourced as part of the HuggingFace Transform-\\ners Library [66] and can be found at https://github.com/huggingface/transformers/blob/master/\\nexamples/rag/. An interactive demo of RAG models can be found at https://huggingface.co/rag/\\n\\n2\\n\\n[https://github.com/huggingface/transformers/blob/master/examples/rag/](https://github.com/huggingface/transformers/blob/master/examples/rag/) \\n[https://github.com/huggingface/transformers/blob/master/examples/rag/](https://github.com/huggingface/transformers/blob/master/examples/rag/) \\n[https://huggingface.co/rag/](https://huggingface.co/rag/) \\n\\nby θ that generates a current token based on a context of the previous i− 1 tokens y1:i−1, the original\\ninput x and a retrieved passage z.\\n\\nTo train the retriever and generator end-to-end, we treat the retrieved document as a latent variable.\\nWe propose two models that marginalize over the latent documents in different ways to produce a'}\n",
|
||||
"{'indexid': 13, 'id': '1', 'url': 'https://arxiv.org/pdf/2005.11401', 'text': 'distribution over generated text. In one approach, RAG-Sequence, the model uses the same document\\nto predict each target token. The second approach, RAG-Token, can predict each target token based\\non a different document. In the following, we formally introduce both models and then describe the\\npη and pθ components, as well as the training and decoding procedure.\\n\\n2.1 Models\\n\\nRAG-Sequence Model The RAG-Sequence model uses the same retrieved document to generate\\nthe complete sequence. Technically, it treats the retrieved document as a single latent variable that\\nis marginalized to get the seq2seq probability p(y|x) via a top-K approximation. Concretely, the\\ntop K documents are retrieved using the retriever, and the generator produces the output sequence\\nprobability for each document, which are then marginalized,\\n\\npRAG-Sequence(y|x) ≈\\n∑\\n\\nz∈top-k(p(·|x))\\n\\npη(z|x)pθ(y|x, z) =\\n∑\\n\\nz∈top-k(p(·|x))\\n\\npη(z|x)\\nN∏\\ni\\n\\npθ(yi|x, z, y1:i−1)\\n\\nRAG-Token Model In the RAG-Token model we can draw a different latent document for each\\ntarget token and marginalize accordingly. This allows the generator to choose content from several\\ndocuments when producing an answer. Concretely, the top K documents are retrieved using the\\nretriever, and then the generator produces a distribution for the next output token for each document,\\nbefore marginalizing, and repeating the process with the following output token, Formally, we define:\\n\\npRAG-Token(y|x) ≈\\nN∏\\ni\\n\\n∑\\nz∈top-k(p(·|x))\\n\\npη(z|x)pθ(yi|x, z, y1:i−1)\\n\\nFinally, we note that RAG can be used for sequence classification tasks by considering the target class\\nas a target sequence of length one, in which case RAG-Sequence and RAG-Token are equivalent.\\n\\n2.2 Retriever: DPR\\n\\nThe retrieval component pη(z|x) is based on DPR [26]. DPR follows a bi-encoder architecture:\\n\\npη(z|x) ∝ exp\\n(\\nd(z)>q(x)\\n\\n)\\nd(z) = BERTd(z), q(x) = BERTq(x)'}\n",
|
||||
"{'indexid': 14, 'id': '1', 'url': 'https://arxiv.org/pdf/2005.11401', 'text': 'where d(z) is a dense representation of a document produced by a BERTBASE document encoder [8],\\nand q(x) a query representation produced by a query encoder, also based on BERTBASE. Calculating\\ntop-k(pη(·|x)), the list of k documents z with highest prior probability pη(z|x), is a Maximum Inner\\nProduct Search (MIPS) problem, which can be approximately solved in sub-linear time [23]. We use\\na pre-trained bi-encoder from DPR to initialize our retriever and to build the document index. This\\nretriever was trained to retrieve documents which contain answers to TriviaQA [24] questions and\\nNatural Questions [29]. We refer to the document index as the non-parametric memory.\\n\\n2.3 Generator: BART\\n\\nThe generator component pθ(yi|x, z, y1:i−1) could be modelled using any encoder-decoder. We use\\nBART-large [32], a pre-trained seq2seq transformer [58] with 400M parameters. To combine the input\\nx with the retrieved content z when generating from BART, we simply concatenate them. BART was\\npre-trained using a denoising objective and a variety of different noising functions. It has obtained\\nstate-of-the-art results on a diverse set of generation tasks and outperforms comparably-sized T5\\nmodels [32]. We refer to the BART generator parameters θ as the parametric memory henceforth.\\n\\n2.4 Training\\n\\nWe jointly train the retriever and generator components without any direct supervision on what\\ndocument should be retrieved. Given a fine-tuning training corpus of input/output pairs (xj , yj), we\\n\\n3\\n\\n\\nminimize the negative marginal log-likelihood of each target,\\n∑\\nj − log p(yj |xj) using stochastic\\n\\ngradient descent with Adam [28]. Updating the document encoder BERTd during training is costly as\\nit requires the document index to be periodically updated as REALM does during pre-training [20].'}\n",
|
||||
"{'indexid': 15, 'id': '1', 'url': 'https://arxiv.org/pdf/2005.11401', 'text': 'We do not find this step necessary for strong performance, and keep the document encoder (and\\nindex) fixed, only fine-tuning the query encoder BERTq and the BART generator.\\n\\n2.5 Decoding\\n\\nAt test time, RAG-Sequence and RAG-Token require different ways to approximate argmaxy p(y|x).\\n\\nRAG-Token The RAG-Token model can be seen as a standard, autoregressive seq2seq genera-\\ntor with transition probability: p′θ(yi|x, y1:i−1) =\\n\\n∑\\nz∈top-k(p(·|x)) pη(zi|x)pθ(yi|x, zi, y1:i−1) To\\n\\ndecode, we can plug p′θ(yi|x, y1:i−1) into a standard beam decoder.\\n\\nRAG-Sequence For RAG-Sequence, the likelihood p(y|x) does not break into a conventional per-\\ntoken likelihood, hence we cannot solve it with a single beam search. Instead, we run beam search for\\neach document z, scoring each hypothesis using pθ(yi|x, z, y1:i−1). This yields a set of hypotheses\\nY , some of which may not have appeared in the beams of all documents. To estimate the probability\\nof an hypothesis y we run an additional forward pass for each document z for which y does not\\nappear in the beam, multiply generator probability with pη(z|x) and then sum the probabilities across\\nbeams for the marginals. We refer to this decoding procedure as “Thorough Decoding.” For longer\\noutput sequences, |Y | can become large, requiring many forward passes. For more efficient decoding,\\nwe can make a further approximation that pθ(y|x, zi) ≈ 0 where y was not generated during beam\\nsearch from x, zi. This avoids the need to run additional forward passes once the candidate set Y has\\nbeen generated. We refer to this decoding procedure as “Fast Decoding.”\\n\\n3 Experiments\\n\\nWe experiment with RAG in a wide range of knowledge-intensive tasks. For all experiments, we use\\na single Wikipedia dump for our non-parametric knowledge source. Following Lee et al. [31] and\\nKarpukhin et al. [26], we use the December 2018 dump. Each Wikipedia article is split into disjoint'}\n",
|
||||
"{'indexid': 16, 'id': '1', 'url': 'https://arxiv.org/pdf/2005.11401', 'text': '100-word chunks, to make a total of 21M documents. We use the document encoder to compute an\\nembedding for each document, and build a single MIPS index using FAISS [23] with a Hierarchical\\nNavigable Small World approximation for fast retrieval [37]. During training, we retrieve the top\\nk documents for each query. We consider k ∈ {5, 10} for training and set k for test time using dev\\ndata. We now discuss experimental details for each task.\\n\\n3.1 Open-domain Question Answering\\n\\nOpen-domain question answering (QA) is an important real-world application and common testbed\\nfor knowledge-intensive tasks [20]. We treat questions and answers as input-output text pairs (x, y)\\nand train RAG by directly minimizing the negative log-likelihood of answers. We compare RAG to\\nthe popular extractive QA paradigm [5, 7, 31, 26], where answers are extracted spans from retrieved\\ndocuments, relying primarily on non-parametric knowledge. We also compare to “Closed-Book\\nQA” approaches [52], which, like RAG, generate answers, but which do not exploit retrieval, instead\\nrelying purely on parametric knowledge. We consider four popular open-domain QA datasets: Natural\\nQuestions (NQ) [29], TriviaQA (TQA) [24]. WebQuestions (WQ) [3] and CuratedTrec (CT) [2]. As\\nCT and WQ are small, we follow DPR [26] by initializing CT and WQ models with our NQ RAG\\nmodel. We use the same train/dev/test splits as prior work [31, 26] and report Exact Match (EM)\\nscores. For TQA, to compare with T5 [52], we also evaluate on the TQA Wiki test set.\\n\\n3.2 Abstractive Question Answering\\n\\nRAG models can go beyond simple extractive QA and answer questions with free-form, abstractive\\ntext generation. To test RAG’s natural language generation (NLG) in a knowledge-intensive setting,\\nwe use the MSMARCO NLG task v2.1 [43]. The task consists of questions, ten gold passages'}\n",
|
||||
"{'indexid': 17, 'id': '1', 'url': 'https://arxiv.org/pdf/2005.11401', 'text': 'retrieved from a search engine for each question, and a full sentence answer annotated from the\\nretrieved passages. We do not use the supplied passages, only the questions and answers, to treat\\n\\n4\\n\\n\\nMSMARCO as an open-domain abstractive QA task. MSMARCO has some questions that cannot be\\nanswered in a way that matches the reference answer without access to the gold passages, such as\\n“What is the weather in Volcano, CA?” so performance will be lower without using gold passages.\\nWe also note that some MSMARCO questions cannot be answered using Wikipedia alone. Here,\\nRAG can rely on parametric knowledge to generate reasonable responses.\\n\\n3.3 Jeopardy Question Generation\\n\\nTo evaluate RAG’s generation abilities in a non-QA setting, we study open-domain question gen-\\neration. Rather than use questions from standard open-domain QA tasks, which typically consist\\nof short, simple questions, we propose the more demanding task of generating Jeopardy questions.\\nJeopardy is an unusual format that consists of trying to guess an entity from a fact about that entity.\\nFor example, “The World Cup” is the answer to the question “In 1986 Mexico scored as the first\\ncountry to host this international sports competition twice.” As Jeopardy questions are precise,\\nfactual statements, generating Jeopardy questions conditioned on their answer entities constitutes a\\nchallenging knowledge-intensive generation task.\\n\\nWe use the splits from SearchQA [10], with 100K train, 14K dev, and 27K test examples. As\\nthis is a new task, we train a BART model for comparison. Following [67], we evaluate using the\\nSQuAD-tuned Q-BLEU-1 metric [42]. Q-BLEU is a variant of BLEU with a higher weight for\\nmatching entities and has higher correlation with human judgment for question generation than\\nstandard metrics. We also perform two human evaluations, one to assess generation factuality, and\\none for specificity. We define factuality as whether a statement can be corroborated by trusted external'}\n",
|
||||
"{'indexid': 18, 'id': '1', 'url': 'https://arxiv.org/pdf/2005.11401', 'text': 'sources, and specificity as high mutual dependence between the input and output [33]. We follow\\nbest practice and use pairwise comparative evaluation [34]. Evaluators are shown an answer and two\\ngenerated questions, one from BART and one from RAG. They are then asked to pick one of four\\noptions—quuestion A is better, question B is better, both are good, or neither is good.\\n\\n3.4 Fact Verification\\n\\nFEVER [56] requires classifying whether a natural language claim is supported or refuted by\\nWikipedia, or whether there is not enough information to decide. The task requires retrieving\\nevidence from Wikipedia relating to the claim and then reasoning over this evidence to classify\\nwhether the claim is true, false, or unverifiable from Wikipedia alone. FEVER is a retrieval problem\\ncoupled with an challenging entailment reasoning task. It also provides an appropriate testbed for\\nexploring the RAG models’ ability to handle classification rather than generation. We map FEVER\\nclass labels (supports, refutes, or not enough info) to single output tokens and directly train with\\nclaim-class pairs. Crucially, unlike most other approaches to FEVER, we do not use supervision on\\nretrieved evidence. In many real-world applications, retrieval supervision signals aren’t available, and\\nmodels that do not require such supervision will be applicable to a wider range of tasks. We explore\\ntwo variants: the standard 3-way classification task (supports/refutes/not enough info) and the 2-way\\n(supports/refutes) task studied in Thorne and Vlachos [57]. In both cases we report label accuracy.\\n\\n4 Results\\n\\n4.1 Open-domain Question Answering\\n\\nTable 1 shows results for RAG along with state-of-the-art models. On all four open-domain QA\\ntasks, RAG sets a new state of the art (only on the T5-comparable split for TQA). RAG combines\\nthe generation flexibility of the “closed-book” (parametric only) approaches and the performance of\\n\"open-book\" retrieval-based approaches. Unlike REALM and T5+SSM, RAG enjoys strong results\\nwithout expensive, specialized “salient span masking” pre-training [20]. It is worth noting that RAG’s\\nretriever is initialized using DPR’s retriever, which uses retrieval supervision on Natural Questions\\nand TriviaQA. RAG compares favourably to the DPR QA system, which uses a BERT-based “cross-'}\n",
|
||||
"{'indexid': 19, 'id': '1', 'url': 'https://arxiv.org/pdf/2005.11401', 'text': 'encoder” to re-rank documents, along with an extractive reader. RAG demonstrates that neither a\\nre-ranker nor extractive reader is necessary for state-of-the-art performance.\\n\\nThere are several advantages to generating answers even when it is possible to extract them. Docu-\\nments with clues about the answer but do not contain the answer verbatim can still contribute towards\\na correct answer being generated, which is not possible with standard extractive approaches, leading\\n\\n5\\n\\n\\nTable 1: Open-Domain QA Test Scores. For TQA,\\nleft column uses the standard test set for Open-\\nDomain QA, right column uses the TQA-Wiki\\ntest set. See Appendix D for further details.\\n\\nModel NQ TQA WQ CT\\n\\nClosed\\nBook\\n\\nT5-11B [52] 34.5 - /50.1 37.4 -\\nT5-11B+SSM[52] 36.6 - /60.5 44.7 -\\n\\nOpen\\nBook\\n\\nREALM [20] 40.4 - / - 40.7 46.8\\nDPR [26] 41.5 57.9/ - 41.1 50.6\\n\\nRAG-Token 44.1 55.2/66.1 45.5 50.0\\nRAG-Seq. 44.5 56.8/68.0 45.2 52.2\\n\\nTable 2: Generation and classification Test Scores.\\nMS-MARCO SotA is [4], FEVER-3 is [68] and\\nFEVER-2 is [57] *Uses gold context/evidence.\\nBest model without gold access underlined.\\n\\nModel Jeopardy MSMARCO FVR3 FVR2\\nB-1 QB-1 R-L B-1 Label Acc.\\n\\nSotA - - 49.8* 49.9* 76.8 92.2*\\n\\nBART 15.1 19.7 38.2 41.6 64.0 81.1\\n\\nRAG-Tok. 17.3 22.2 40.1 41.5 72.5 89.5RAG-Seq. 14.7 21.4 40.8 44.2\\n\\nto more effective marginalization over documents. Furthermore, RAG can generate correct answers\\neven when the correct answer is not in any retrieved document, achieving 11.8% accuracy in such\\ncases for NQ, where an extractive model would score 0%.\\n\\n4.2 Abstractive Question Answering'}\n"
|
||||
]
|
||||
}
|
||||
],
|
||||
"source": [
|
||||
"for x in embeddings.search(\"SELECT indexid, id, url, text from txtai\", 20):\n",
|
||||
" print(x)"
|
||||
]
|
||||
},
|
||||
{
|
||||
"cell_type": "markdown",
|
||||
"metadata": {},
|
||||
"source": [
|
||||
"Note that the id/metadata is the same but the indexid and chunk text change with each row."
|
||||
]
|
||||
},
|
||||
{
|
||||
"cell_type": "markdown",
|
||||
"metadata": {},
|
||||
"source": [
|
||||
"# Retrieval\n",
|
||||
"\n",
|
||||
"Last thing here is to illustrate a couple retrieval operations. LLMs are great at generating answers when we properly bound the context. See the two examples below."
|
||||
]
|
||||
},
|
||||
{
|
||||
"cell_type": "code",
|
||||
"execution_count": 61,
|
||||
"metadata": {},
|
||||
"outputs": [
|
||||
{
|
||||
"name": "stdout",
|
||||
"output_type": "stream",
|
||||
"text": [
|
||||
"including less of emphasis on lightly editing a retrieved item, but on aggregating content from several\n",
|
||||
"pieces of retrieved content, as well as learning latent retrieval, and retrieving evidence documents\n",
|
||||
"rather than related training pairs. This said, RAG techniques may work well in these settings, and\n",
|
||||
"could represent promising future work.\n",
|
||||
"\n",
|
||||
"6 Discussion\n",
|
||||
"\n",
|
||||
"In this work, we presented hybrid generation models with access to parametric and non-parametric\n",
|
||||
"memory. We showed that our RAG models obtain state of the art results on open-domain QA. We\n",
|
||||
"found that people prefer RAG’s generation over purely parametric BART, finding RAG more factual\n",
|
||||
"and specific. We conducted an thorough investigation of the learned retrieval component, validating\n",
|
||||
"its effectiveness, and we illustrated how the retrieval index can be hot-swapped to update the model\n",
|
||||
"without requiring any retraining. In future work, it may be fruitful to investigate if the two components\n",
|
||||
"can be jointly pre-trained from scratch, either with a denoising objective similar to BART or some\n",
|
||||
"another objective. Our work opens up new research directions on how parametric and non-parametric\n",
|
||||
"memories interact and how to most effectively combine them, showing promise in being applied to a\n",
|
||||
"wide variety of NLP tasks.\n",
|
||||
"\n",
|
||||
"9\n",
|
||||
"\n",
|
||||
"\n",
|
||||
"Broader Impact\n",
|
||||
"\n",
|
||||
"This work offers several positive societal benefits over previous work: the fact that it is more\n",
|
||||
"strongly grounded in real factual knowledge (in this case Wikipedia) makes it “hallucinate” less\n",
|
||||
"with generations that are more factual, and offers more control and interpretability. RAG could be\n",
|
||||
"employed in a wide variety of scenarios with direct benefit to society, for example by endowing it\n",
|
||||
"with a medical index and asking it open-domain questions on that topic, or by helping people be more\n",
|
||||
"effective at their jobs.\n",
|
||||
"\n",
|
||||
"With these advantages also come potential downsides: Wikipedia, or any potential external knowledge\n",
|
||||
"source, will probably never be entirely factual and completely devoid of bias. Since RAG can be\n",
|
||||
"employed as a language model, similar concerns as for GPT-2 [50] are valid here, although arguably\n",
|
||||
"to a lesser extent, including that it might be used to generate abuse, faked or misleading content in\n",
|
||||
"the news or on social media; to impersonate others; or to automate the production of spam/phishing\n",
|
||||
"content [54]. Advanced language models may also lead to the automation of various jobs in the\n",
|
||||
"coming decades [16].\n"
|
||||
]
|
||||
}
|
||||
],
|
||||
"source": [
|
||||
"print(embeddings.search(\"What is it called when LLM generation is bounded with factually correct data?\", 1)[0][\"text\"])"
|
||||
]
|
||||
},
|
||||
{
|
||||
"cell_type": "code",
|
||||
"execution_count": 62,
|
||||
"metadata": {},
|
||||
"outputs": [
|
||||
{
|
||||
"name": "stdout",
|
||||
"output_type": "stream",
|
||||
"text": [
|
||||
"Traditional search systems use keywords to find data. Semantic search has an understanding of natural language and identifies results that have the same meaning, not necessarily the same keywords.\n",
|
||||
"\n",
|
||||
"Get started with the following examples.\n",
|
||||
"\n",
|
||||
"|Notebook|Description||\n",
|
||||
"|---|---|---|\n",
|
||||
"|[Introducing txtai](https://github.com/neuml/txtai/blob/master/examples/01_Introducing_txtai.ipynb) |Overview of the functionality provided by txtai||\n",
|
||||
"|[Similarity search with images](https://github.com/neuml/txtai/blob/master/examples/13_Similarity_search_with_images.ipynb) |Embed images and text into the same space for search||\n",
|
||||
"|[Build a QA database](https://github.com/neuml/txtai/blob/master/examples/34_Build_a_QA_database.ipynb) |Question matching with semantic search||\n",
|
||||
"|[Semantic Graphs](https://github.com/neuml/txtai/blob/master/examples/38_Introducing_the_Semantic_Graph.ipynb) |Explore topics, data connectivity and run network analysis||\n",
|
||||
"\n",
|
||||
"### LLM Orchestration\n",
|
||||
"Autonomous agents, retrieval augmented generation (RAG), chat with your data, pipelines and workflows that interface with large language models (LLMs).\n",
|
||||
"\n",
|
||||
"See below to learn more.\n",
|
||||
"\n",
|
||||
"|Notebook|Description||\n",
|
||||
"|---|---|---|\n",
|
||||
"|[Prompt templates and task chains](https://github.com/neuml/txtai/blob/master/examples/44_Prompt_templates_and_task_chains.ipynb) |Build model prompts and connect tasks together with workflows||\n",
|
||||
"|[Integrate LLM frameworks](https://github.com/neuml/txtai/blob/master/examples/53_Integrate_LLM_Frameworks.ipynb) |Integrate llama.cpp, LiteLLM and custom generation frameworks||\n",
|
||||
"|[Build knowledge graphs with LLMs](https://github.\n"
|
||||
]
|
||||
}
|
||||
],
|
||||
"source": [
|
||||
"print(embeddings.search(\"Tell me about semantic search\", 1)[0][\"text\"])"
|
||||
]
|
||||
},
|
||||
{
|
||||
"cell_type": "markdown",
|
||||
"metadata": {},
|
||||
"source": [
|
||||
"Note how both answers give more than enough information for a LLM to answer the question."
|
||||
]
|
||||
},
|
||||
{
|
||||
"cell_type": "markdown",
|
||||
"metadata": {},
|
||||
"source": [
|
||||
"# Wrapping up\n",
|
||||
"\n",
|
||||
"This notebook covered how to build a retrieval system for RAG with txtai. Chunking and retrieval are key pieces of a RAG system, arguably the most important. With the commoditization of LLMs, it's going to be more and more important on how data is presented to LLMs. When given concise information, LLMs can take it from there!\n"
|
||||
]
|
||||
}
|
||||
],
|
||||
"metadata": {
|
||||
"kernelspec": {
|
||||
"display_name": "local",
|
||||
"language": "python",
|
||||
"name": "python3"
|
||||
},
|
||||
"language_info": {
|
||||
"codemirror_mode": {
|
||||
"name": "ipython",
|
||||
"version": 3
|
||||
},
|
||||
"file_extension": ".py",
|
||||
"mimetype": "text/x-python",
|
||||
"name": "python",
|
||||
"nbconvert_exporter": "python",
|
||||
"pygments_lexer": "ipython3",
|
||||
"version": "3.9.21"
|
||||
}
|
||||
},
|
||||
"nbformat": 4,
|
||||
"nbformat_minor": 2
|
||||
}
|
||||
File diff suppressed because one or more lines are too long
@@ -0,0 +1,454 @@
|
||||
{
|
||||
"cells": [
|
||||
{
|
||||
"cell_type": "markdown",
|
||||
"id": "666da745",
|
||||
"metadata": {},
|
||||
"source": [
|
||||
"# Medical RAG Research with txtai\n",
|
||||
"\n",
|
||||
"Large Language Models (LLMs) have captured the public's attention with their impressive capabilities. The Generative AI era has reached a fever pitch with some predicting the coming rise of superintelligence.\n",
|
||||
"\n",
|
||||
"LLMs are far from perfect though and we're still a ways away from true AI. One big challenge is with hallucinations. Hallucinations is the term for when an LLM generates output that is factually incorrect. The alarming part of this is that on a cursory glance, it actually sounds like factual content. The default behavior of LLMs is to produce plausible answers even when no plausible answer exists. LLMs are not great at saying I don't know.\n",
|
||||
"\n",
|
||||
"Retrieval Augmented Generation (RAG) helps reduce the risk of hallucinations by limiting the context in which a LLM can generate answers. This is typically done with a search query that hydrates a prompt with a relevant context. RAG has been one of the most practical use cases of the Generative AI era.\n",
|
||||
"\n",
|
||||
"This notebook will demonstrate how to build a Medical RAG Research process with txtai."
|
||||
]
|
||||
},
|
||||
{
|
||||
"cell_type": "markdown",
|
||||
"id": "a4c7cc15",
|
||||
"metadata": {},
|
||||
"source": [
|
||||
"# Install dependencies\n",
|
||||
"\n",
|
||||
"Install `txtai` and all dependencies."
|
||||
]
|
||||
},
|
||||
{
|
||||
"cell_type": "code",
|
||||
"execution_count": null,
|
||||
"id": "a246bb3a",
|
||||
"metadata": {},
|
||||
"outputs": [],
|
||||
"source": [
|
||||
"%%capture\n",
|
||||
"!pip install git+https://github.com/neuml/txtai"
|
||||
]
|
||||
},
|
||||
{
|
||||
"cell_type": "markdown",
|
||||
"id": "fc5c27ed",
|
||||
"metadata": {},
|
||||
"source": [
|
||||
"# Medical Dataset\n",
|
||||
"\n",
|
||||
"For this example, we'll use a [PubMed subset of article metadata for H5N1](https://huggingface.co/datasets/NeuML/pubmed-h5n1). This dataset was created using [`paperetl`](https://github.com/neuml/paperetl), an open-source library for parsing medical and scientific papers.\n",
|
||||
"\n",
|
||||
"[PubMed](https://pubmed.ncbi.nlm.nih.gov/) has over 38 million article abstracts as of June 2025. `paperetl` supports loading the full dataset with all 38 million articles or just a smaller subset. The dataset link above has more details on how this can be changed for different codes and keywords. This link also has information on how the article abstracts can be loaded in addition to the metadata."
|
||||
]
|
||||
},
|
||||
{
|
||||
"cell_type": "code",
|
||||
"execution_count": 80,
|
||||
"id": "5dd4145d",
|
||||
"metadata": {},
|
||||
"outputs": [],
|
||||
"source": [
|
||||
"from datasets import load_dataset\n",
|
||||
"from txtai import Embeddings\n",
|
||||
"\n",
|
||||
"ds = load_dataset(\"neuml/pubmed-h5n1\", split=\"train\")"
|
||||
]
|
||||
},
|
||||
{
|
||||
"cell_type": "markdown",
|
||||
"id": "2d3b1cd8",
|
||||
"metadata": {},
|
||||
"source": [
|
||||
"Next, we'll build a `txtai` embeddings index with the articles. We'll use a vector embeddings model that specializes in vectorizing medical papers: [PubMedBERT Embeddings](https://huggingface.co/NeuML/pubmedbert-base-embeddings). "
|
||||
]
|
||||
},
|
||||
{
|
||||
"cell_type": "code",
|
||||
"execution_count": 81,
|
||||
"id": "04e69829",
|
||||
"metadata": {},
|
||||
"outputs": [],
|
||||
"source": [
|
||||
"embeddings = Embeddings(path=\"neuml/pubmedbert-base-embeddings\", content=True, columns={\"text\": \"title\"})\n",
|
||||
"embeddings.index(x for x in ds if x[\"title\"])"
|
||||
]
|
||||
},
|
||||
{
|
||||
"cell_type": "code",
|
||||
"execution_count": 82,
|
||||
"id": "a801391e",
|
||||
"metadata": {},
|
||||
"outputs": [
|
||||
{
|
||||
"data": {
|
||||
"text/plain": [
|
||||
"7865"
|
||||
]
|
||||
},
|
||||
"execution_count": 82,
|
||||
"metadata": {},
|
||||
"output_type": "execute_result"
|
||||
}
|
||||
],
|
||||
"source": [
|
||||
"embeddings.count()"
|
||||
]
|
||||
},
|
||||
{
|
||||
"cell_type": "markdown",
|
||||
"id": "907898a4",
|
||||
"metadata": {},
|
||||
"source": [
|
||||
"# RAG Pipeline\n",
|
||||
"\n",
|
||||
"There are a number of [prior examples](https://neuml.github.io/txtai/examples/#llm) on how to run RAG with `txtai`. The [RAG pipeline](https://neuml.github.io/txtai/pipeline/text/rag/) takes two main parameters, an embeddings database and an LLM. The embeddings database is the one just created above. For this example, we'll use a [simple local LLM with 600M parameters](https://huggingface.co/Qwen/Qwen3-0.6B).\n",
|
||||
"\n",
|
||||
"Substitute your own embeddings database to change the knowledge base. `txtai` supports running local LLMs via [transformers](https://github.com/huggingface/transformers) or [llama.cpp](https://github.com/abetlen/llama-cpp-python). It also supports a wide variety of LLMs via [LiteLLM](https://github.com/BerriAI/litellm). For example, setting the 2nd RAG pipeline parameter below to `gpt-4o` along with the appropriate environment variables with access keys switches to a hosted LLM. See [this documentation page](https://neuml.github.io/txtai/pipeline/text/llm/) for more on this."
|
||||
]
|
||||
},
|
||||
{
|
||||
"cell_type": "code",
|
||||
"execution_count": 83,
|
||||
"id": "cd05fc41",
|
||||
"metadata": {},
|
||||
"outputs": [
|
||||
{
|
||||
"name": "stderr",
|
||||
"output_type": "stream",
|
||||
"text": [
|
||||
"Device set to use cuda:0\n"
|
||||
]
|
||||
}
|
||||
],
|
||||
"source": [
|
||||
"from txtai import RAG\n",
|
||||
"\n",
|
||||
"# Prompt templates\n",
|
||||
"system = \"You are a friendly medical assistant that answers questions\"\n",
|
||||
"template = \"\"\"\n",
|
||||
"Answer the following question using the provided context.\n",
|
||||
"\n",
|
||||
"Question:\n",
|
||||
"{question}\n",
|
||||
"\n",
|
||||
"Context:\n",
|
||||
"{context}\n",
|
||||
"\"\"\"\n",
|
||||
"\n",
|
||||
"# Create RAG pipeline\n",
|
||||
"rag = RAG(embeddings, \"Qwen/Qwen3-0.6B\", system=system, template=template, output=\"flatten\")"
|
||||
]
|
||||
},
|
||||
{
|
||||
"cell_type": "markdown",
|
||||
"id": "98800220",
|
||||
"metadata": {},
|
||||
"source": [
|
||||
"# RAG Queries\n",
|
||||
"\n",
|
||||
"Now that the pipeline is setup, let's run a query."
|
||||
]
|
||||
},
|
||||
{
|
||||
"cell_type": "code",
|
||||
"execution_count": 85,
|
||||
"id": "4d93ac4b",
|
||||
"metadata": {},
|
||||
"outputs": [
|
||||
{
|
||||
"name": "stdout",
|
||||
"output_type": "stream",
|
||||
"text": [
|
||||
"<think>\n",
|
||||
"Okay, let's see. The user is asking about H5N1. The context provided starts with \"Why tell me now?\" and then goes into facts about H5N1. The first sentence mentions that people and healthcare providers are weighing in on pandemic messages. Then it says H5N1 is avian influenza, a potential pandemic.\n",
|
||||
"\n",
|
||||
"Wait, but the user's question is about H5N1. The context doesn't go into specifics about what H5N1 is, but it does state that it's avian influenza. So I need to make sure I answer based on that. The answer should be concise, maybe mention that H5N1 is avian flu and it's a potential pandemic. Also, note that people are weighing in on messages. But I need to check if there's any more information. The context ends there. So the answer should be straightforward.\n",
|
||||
"</think>\n",
|
||||
"\n",
|
||||
"H5N1 influenza viruses are a type of avian influenza, a potential pandemic influenza virus that could cause widespread illness and death. While the context highlights the importance of public health and preparedness, it does not provide more specific details about its characteristics or risks.\n"
|
||||
]
|
||||
}
|
||||
],
|
||||
"source": [
|
||||
"print(rag(\"Tell me about H5N1\"))"
|
||||
]
|
||||
},
|
||||
{
|
||||
"cell_type": "markdown",
|
||||
"id": "39ab9946",
|
||||
"metadata": {},
|
||||
"source": [
|
||||
"Notice that this LLM outputs a thinking or reasoning section then the answer.\n",
|
||||
"\n",
|
||||
"Let's review the context to validate this answer is derived from the knowledge base."
|
||||
]
|
||||
},
|
||||
{
|
||||
"cell_type": "code",
|
||||
"execution_count": 79,
|
||||
"id": "53de0f96",
|
||||
"metadata": {},
|
||||
"outputs": [
|
||||
{
|
||||
"data": {
|
||||
"text/plain": [
|
||||
"[{'id': '16775537',\n",
|
||||
" 'text': '\"Why tell me now?\" the public and healthcare providers weigh in on pandemic influenza messages.',\n",
|
||||
" 'score': 0.7156285643577576},\n",
|
||||
" {'id': '22308474',\n",
|
||||
" 'text': 'H5N1 influenza viruses: facts, not fear.',\n",
|
||||
" 'score': 0.658343493938446},\n",
|
||||
" {'id': '16440117',\n",
|
||||
" 'text': 'Avian influenza--a pandemic waiting to happen?',\n",
|
||||
" 'score': 0.5827972888946533},\n",
|
||||
" {'id': '20667302',\n",
|
||||
" 'text': 'The influenza A(H5N1) epidemic at six and a half years: 500 notified human cases and more to come.',\n",
|
||||
" 'score': 0.5593500137329102},\n",
|
||||
" {'id': '18936262',\n",
|
||||
" 'text': 'What Australians know and believe about bird flu: results of a population telephone survey.',\n",
|
||||
" 'score': 0.5568690299987793},\n",
|
||||
" {'id': '30349811',\n",
|
||||
" 'text': 'Back to the Future: Lessons Learned From the 1918 Influenza Pandemic.',\n",
|
||||
" 'score': 0.5540266036987305},\n",
|
||||
" {'id': '17276785',\n",
|
||||
" 'text': 'Pandemic influenza: what infection control professionals should know.',\n",
|
||||
" 'score': 0.5519200563430786},\n",
|
||||
" {'id': '16681227',\n",
|
||||
" 'text': 'A pandemic flu: not if, but when. SARS was the wake-up call we slept through.',\n",
|
||||
" 'score': 0.5518345832824707},\n",
|
||||
" {'id': '22402712',\n",
|
||||
" 'text': 'Ferretting out the facts behind the H5N1 controversy.',\n",
|
||||
" 'score': 0.5508109331130981},\n",
|
||||
" {'id': '25546511',\n",
|
||||
" 'text': \"One-way trip: influenza virus' adaptation to gallinaceous poultry may limit its pandemic potential.\",\n",
|
||||
" 'score': 0.5494509339332581}]"
|
||||
]
|
||||
},
|
||||
"execution_count": 79,
|
||||
"metadata": {},
|
||||
"output_type": "execute_result"
|
||||
}
|
||||
],
|
||||
"source": [
|
||||
"embeddings.search(\"Tell me about H5N1\", limit=10)"
|
||||
]
|
||||
},
|
||||
{
|
||||
"cell_type": "markdown",
|
||||
"id": "025e6092",
|
||||
"metadata": {},
|
||||
"source": [
|
||||
"The answer is doing a good job being based on the context above. Also keep in mind this is a small 600M parameter model, which is even more impressive.\n",
|
||||
"\n",
|
||||
"Let's try another query."
|
||||
]
|
||||
},
|
||||
{
|
||||
"cell_type": "code",
|
||||
"execution_count": 86,
|
||||
"id": "1899047a",
|
||||
"metadata": {},
|
||||
"outputs": [
|
||||
{
|
||||
"name": "stdout",
|
||||
"output_type": "stream",
|
||||
"text": [
|
||||
"<think>\n",
|
||||
"Okay, let's see. The user is asking about the locations that have had H5N1 outbreaks, and the provided context mentions a few places: Indonesia and Bangladesh. The context also has a title about a decade of avian influenza in Bangladesh and mentions \"H5N1.\" \n",
|
||||
"\n",
|
||||
"Wait, the user's question is in English, so I need to make sure I'm interpreting the context correctly. The context includes two sentences: one about a decade in Bangladesh and another about H5N1. The user is probably looking for specific locations where H5N1 has been reported. \n",
|
||||
"\n",
|
||||
"Looking at the context again, it says \"Human avian influenza in Indonesia\" and \"A Decade of Avian Influenza in Bangladesh: Where Are We Now? Are we ready for pandemic influenza H5N1?\" So the outbreaks are in Indonesia and Bangladesh. \n",
|
||||
"\n",
|
||||
"I should confirm that there are no other mentions of other locations. The context doesn't provide more information beyond those two countries. Therefore, the answer should list Indonesia and Bangladesh as the locations with H5N1 outbreaks.\n",
|
||||
"</think>\n",
|
||||
"\n",
|
||||
"The locations with H5N1 outbreaks are Indonesia and Bangladesh.\n"
|
||||
]
|
||||
}
|
||||
],
|
||||
"source": [
|
||||
"print(rag(\"What locations have had H5N1 outbreaks?\"))"
|
||||
]
|
||||
},
|
||||
{
|
||||
"cell_type": "code",
|
||||
"execution_count": 87,
|
||||
"id": "39d4efa6",
|
||||
"metadata": {},
|
||||
"outputs": [
|
||||
{
|
||||
"data": {
|
||||
"text/plain": [
|
||||
"[{'id': '21706937',\n",
|
||||
" 'text': 'Human avian influenza in Indonesia: are they really clustered?',\n",
|
||||
" 'score': 0.6269429326057434},\n",
|
||||
" {'id': '31514405',\n",
|
||||
" 'text': 'A Decade of Avian Influenza in Bangladesh: Where Are We Now?',\n",
|
||||
" 'score': 0.5972536206245422},\n",
|
||||
" {'id': '15889987',\n",
|
||||
" 'text': 'Are we ready for pandemic influenza H5N1?',\n",
|
||||
" 'score': 0.5863772630691528},\n",
|
||||
" {'id': '17717543',\n",
|
||||
" 'text': 'Commentary: From scarcity to abundance: pandemic vaccines and other agents for \"have not\" countries.',\n",
|
||||
" 'score': 0.5844159126281738},\n",
|
||||
" {'id': '22491771',\n",
|
||||
" 'text': 'Two years after pandemic influenza A/2009/H1N1: what have we learned?',\n",
|
||||
" 'score': 0.5812581777572632},\n",
|
||||
" {'id': '39666804',\n",
|
||||
" 'text': \"Why hasn't the bird flu pandemic started?\",\n",
|
||||
" 'score': 0.5738048553466797},\n",
|
||||
" {'id': '23402131',\n",
|
||||
" 'text': 'Where do avian influenza viruses meet in the Americas?',\n",
|
||||
" 'score': 0.5638074278831482},\n",
|
||||
" {'id': '20667302',\n",
|
||||
" 'text': 'The influenza A(H5N1) epidemic at six and a half years: 500 notified human cases and more to come.',\n",
|
||||
" 'score': 0.560465395450592},\n",
|
||||
" {'id': '17338983',\n",
|
||||
" 'text': 'Human avian influenza: how ready are we?',\n",
|
||||
" 'score': 0.555113673210144},\n",
|
||||
" {'id': '24518630',\n",
|
||||
" 'text': 'Recognizing true H5N1 infections in humans during confirmed outbreaks.',\n",
|
||||
" 'score': 0.5501888990402222}]"
|
||||
]
|
||||
},
|
||||
"execution_count": 87,
|
||||
"metadata": {},
|
||||
"output_type": "execute_result"
|
||||
}
|
||||
],
|
||||
"source": [
|
||||
"embeddings.search(\"What locations have had H5N1 outbreaks?\", limit=10)"
|
||||
]
|
||||
},
|
||||
{
|
||||
"cell_type": "markdown",
|
||||
"id": "efa8e59e",
|
||||
"metadata": {},
|
||||
"source": [
|
||||
"Once again the answer is based on the context which mentions the two countries in the answer. The context also discusses the Americas but it doesn't have as strong of language connecting H5N1 outbreaks to the location."
|
||||
]
|
||||
},
|
||||
{
|
||||
"cell_type": "markdown",
|
||||
"id": "18e04661",
|
||||
"metadata": {},
|
||||
"source": [
|
||||
"# Add citations\n",
|
||||
"\n",
|
||||
"The last item we'll cover is citations. One of the most important aspects of a RAG process is being able to ensure the answer is based on reality. There are a number of ways to do this but in this example, we'll ask the LLM to perform this step."
|
||||
]
|
||||
},
|
||||
{
|
||||
"cell_type": "code",
|
||||
"execution_count": 96,
|
||||
"id": "ce10ff39",
|
||||
"metadata": {},
|
||||
"outputs": [
|
||||
{
|
||||
"name": "stderr",
|
||||
"output_type": "stream",
|
||||
"text": [
|
||||
"Device set to use cuda:0\n"
|
||||
]
|
||||
}
|
||||
],
|
||||
"source": [
|
||||
"# Prompt templates\n",
|
||||
"system = \"You are a friendly medical assistant that answers questions\"\n",
|
||||
"template = \"\"\"\n",
|
||||
"Answer the following question using the provided context.\n",
|
||||
"\n",
|
||||
"After the answer, write a citation section with ALL the original article ids used for the answer.\n",
|
||||
"\n",
|
||||
"Question:\n",
|
||||
"{question}\n",
|
||||
"\n",
|
||||
"Context:\n",
|
||||
"{context}\n",
|
||||
"\"\"\"\n",
|
||||
"\n",
|
||||
"def context(question):\n",
|
||||
" context = []\n",
|
||||
" for x in embeddings.search(question, limit=10):\n",
|
||||
" context.append(f\"ARTICLE ID: {x['id']}, TEXT: {x['text']}\")\n",
|
||||
"\n",
|
||||
" return context\n",
|
||||
"\n",
|
||||
"# Create RAG pipeline\n",
|
||||
"rag = RAG(embeddings, \"Qwen/Qwen3-0.6B\", system=system, template=template, output=\"flatten\")"
|
||||
]
|
||||
},
|
||||
{
|
||||
"cell_type": "code",
|
||||
"execution_count": null,
|
||||
"id": "f79bdc9a",
|
||||
"metadata": {},
|
||||
"outputs": [
|
||||
{
|
||||
"name": "stdout",
|
||||
"output_type": "stream",
|
||||
"text": [
|
||||
"H5N1 is a type of avian influenza virus. \n",
|
||||
"\n",
|
||||
"**Citation Section:** \n",
|
||||
"- ARTICLE ID: 22010536, TEXT: Is avian influenza virus A(H5N1) a real threat to human health?\n"
|
||||
]
|
||||
}
|
||||
],
|
||||
"source": [
|
||||
"question = \"What is H5N1?\"\n",
|
||||
"print(rag(question, context(question), maxlength=2048, stripthink=True))"
|
||||
]
|
||||
},
|
||||
{
|
||||
"cell_type": "markdown",
|
||||
"id": "15539c5d",
|
||||
"metadata": {},
|
||||
"source": [
|
||||
"As expected, the answer adds a citation section. Also note that the RAG pipeline stripped the thinking section from the result."
|
||||
]
|
||||
},
|
||||
{
|
||||
"cell_type": "markdown",
|
||||
"id": "3bdf84b5",
|
||||
"metadata": {},
|
||||
"source": [
|
||||
"# Wrapping up\n",
|
||||
"\n",
|
||||
"This notebook covered how to build a Medical RAG Research process with `txtai`. It also covered how to modify this logic to add in your own knowledge base or use a more sophisticated LLM.\n",
|
||||
"\n",
|
||||
"With an important space such as the medical domain, it's vital to ensure that answers are derived from reliable knowledge. This notebook shows how to add that reliability via RAG. But as with anything in an important domain, there should be a human in the loop and answers shouldn't be blindly relied upon. "
|
||||
]
|
||||
}
|
||||
],
|
||||
"metadata": {
|
||||
"kernelspec": {
|
||||
"display_name": "local",
|
||||
"language": "python",
|
||||
"name": "python3"
|
||||
},
|
||||
"language_info": {
|
||||
"codemirror_mode": {
|
||||
"name": "ipython",
|
||||
"version": 3
|
||||
},
|
||||
"file_extension": ".py",
|
||||
"mimetype": "text/x-python",
|
||||
"name": "python",
|
||||
"nbconvert_exporter": "python",
|
||||
"pygments_lexer": "ipython3",
|
||||
"version": "3.10.18"
|
||||
}
|
||||
},
|
||||
"nbformat": 4,
|
||||
"nbformat_minor": 5
|
||||
}
|
||||
@@ -0,0 +1,309 @@
|
||||
{
|
||||
"cells": [
|
||||
{
|
||||
"cell_type": "markdown",
|
||||
"metadata": {
|
||||
"id": "e3wdiK5fGUoZ"
|
||||
},
|
||||
"source": [
|
||||
"# 💡 What's new in txtai 9.0\n",
|
||||
"\n",
|
||||
"The 9.0 release adds first class support for sparse vector models (i.e. [SPLADE](https://en.wikipedia.org/wiki/Learned_sparse_retrieval)), late interaction models (i.e. [ColBERT](https://huggingface.co/colbert-ir/colbertv2.0)), fixed dimensional encoding (i.e. [MUVERA](https://arxiv.org/abs/2405.19504)) and reranking pipelines ✨ \n",
|
||||
"\n",
|
||||
"The embeddings framework was overhauled to seamlessly support both sparse and dense vector models. Previously, sparse vector support was limited to keyword/term indexes. Now learned sparse retrieval models such as SPLADE are supported. These models can help improve the accuracy of retrieval/search operations, which also improves RAG and Agents.\n",
|
||||
"\n",
|
||||
"Support for late interaction models, such as ColBERT, were also added to the embeddings framework. Unlike traditional vector models that pool outputs into single vector outputs, late interaction models produce multiple vectors. These models are paired with the MUVERA algorithm to transform multiple vectors into fixed dimensional single vectors for search.\n",
|
||||
"\n",
|
||||
"LLMs are quickly converging to produce similar outputs for similar inputs and becoming standard commodities. The retrieval or context layer makes or breaks projects. This is known as putting the R in RAG!\n",
|
||||
"\n",
|
||||
"**Standard upgrade disclaimer below**\n",
|
||||
"\n",
|
||||
"While everything is backwards compatible, it's prudent to backup production indexes before upgrading and test before deploying."
|
||||
]
|
||||
},
|
||||
{
|
||||
"cell_type": "markdown",
|
||||
"metadata": {
|
||||
"id": "p8BbfjrhH-V2"
|
||||
},
|
||||
"source": [
|
||||
"# Install dependencies\n",
|
||||
"\n",
|
||||
"Install `txtai` and all dependencies."
|
||||
]
|
||||
},
|
||||
{
|
||||
"cell_type": "code",
|
||||
"execution_count": 1,
|
||||
"metadata": {
|
||||
"id": "-OXsTQgaGQPM"
|
||||
},
|
||||
"outputs": [],
|
||||
"source": [
|
||||
"%%capture\n",
|
||||
"!pip install git+https://github.com/neuml/txtai#egg=txtai[ann,vectors]"
|
||||
]
|
||||
},
|
||||
{
|
||||
"cell_type": "markdown",
|
||||
"metadata": {
|
||||
"id": "n4EXrtcYIIYE"
|
||||
},
|
||||
"source": [
|
||||
"# Sparse vector indexes\n",
|
||||
"\n",
|
||||
"The first major change added with this release is `learned sparse retrieval` (aka sparse vector indexes) models. This effort was multi-faceted in that it required both changes to how vectors were generated as well as how they are stored.\n",
|
||||
"\n",
|
||||
"`txtai` uses approximate nearest neighbor (ANN) search for it's vector search operations. The default library is [Faiss](https://github.com/facebookresearch/faiss). There is support for other libraries but in all cases the existing ANN backends only supported dense (i.e. NumPy) vectors.\n",
|
||||
"\n",
|
||||
"There aren't many options out there for sparse ANN search that supports `txtai` requirements, so IVFSparse was introduced. IVFSparse is an Inverted file (IVF) index with flat vector file storage and sparse array support. There is also support for storing sparse vectors in Postgres via [pgvector](https://github.com/pgvector/pgvector).\n",
|
||||
"\n",
|
||||
"Let's see it in action.\n"
|
||||
]
|
||||
},
|
||||
{
|
||||
"cell_type": "code",
|
||||
"execution_count": 2,
|
||||
"metadata": {
|
||||
"id": "hzPD8_cQJNtN"
|
||||
},
|
||||
"outputs": [
|
||||
{
|
||||
"data": {
|
||||
"text/plain": [
|
||||
"[{'id': '0',\n",
|
||||
" 'text': 'US tops 5 million confirmed virus cases',\n",
|
||||
" 'score': 0.019873601198196412},\n",
|
||||
" {'id': '1',\n",
|
||||
" 'text': \"Canada's last fully intact ice shelf has suddenly collapsed, forming a Manhattan-sized iceberg\",\n",
|
||||
" 'score': 0.018737798929214476}]"
|
||||
]
|
||||
},
|
||||
"execution_count": 2,
|
||||
"metadata": {},
|
||||
"output_type": "execute_result"
|
||||
}
|
||||
],
|
||||
"source": [
|
||||
"from txtai import Embeddings\n",
|
||||
"\n",
|
||||
"# Works with a list, dataset or generator\n",
|
||||
"data = [\n",
|
||||
" \"US tops 5 million confirmed virus cases\",\n",
|
||||
" \"Canada's last fully intact ice shelf has suddenly collapsed, forming a Manhattan-sized iceberg\",\n",
|
||||
" \"Beijing mobilises invasion craft along coast as Taiwan tensions escalate\",\n",
|
||||
" \"The National Park Service warns against sacrificing slower friends in a bear attack\",\n",
|
||||
" \"Maine man wins $1M from $25 lottery ticket\",\n",
|
||||
" \"Make huge profits without work, earn up to $100,000 a day\"\n",
|
||||
"]\n",
|
||||
"\n",
|
||||
"# Create an embeddings\n",
|
||||
"embeddings = Embeddings(sparse=True, content=True)\n",
|
||||
"embeddings.index(data)\n",
|
||||
"embeddings.search(\"North America\", 10)"
|
||||
]
|
||||
},
|
||||
{
|
||||
"cell_type": "markdown",
|
||||
"metadata": {},
|
||||
"source": [
|
||||
"# Late interaction models\n",
|
||||
"\n",
|
||||
"Late interaction models encode data into multi-vector outputs. In other words, multiple input tokens map to multiple output vectors. Then at search time, the maximum similarity algorithm is used to find the best matches between the corpus and a query. This algorithm has achieved excellent results on retrieval benchmarks such as [MTEB](https://github.com/embeddings-benchmark/mteb).\n",
|
||||
"\n",
|
||||
"The downside of this approach is that it produces multiple vectors as opposed a single vector for each input. For example, if a text element tokenizes to many input tokens, there will be many output vectors vs a single one as with standard pooled vector approaches.\n",
|
||||
"\n",
|
||||
"Starting with the 9.0 release, late interaction models are supported with embeddings instances. Late interaction vectors will be transformed into fixed dimensional vectors using the MUVERA algorithm. See below. "
|
||||
]
|
||||
},
|
||||
{
|
||||
"cell_type": "code",
|
||||
"execution_count": 3,
|
||||
"metadata": {},
|
||||
"outputs": [
|
||||
{
|
||||
"data": {
|
||||
"text/plain": [
|
||||
"[{'id': '0',\n",
|
||||
" 'text': 'US tops 5 million confirmed virus cases',\n",
|
||||
" 'score': 0.04216160625219345},\n",
|
||||
" {'id': '1',\n",
|
||||
" 'text': \"Canada's last fully intact ice shelf has suddenly collapsed, forming a Manhattan-sized iceberg\",\n",
|
||||
" 'score': 0.029944246634840965},\n",
|
||||
" {'id': '3',\n",
|
||||
" 'text': 'The National Park Service warns against sacrificing slower friends in a bear attack',\n",
|
||||
" 'score': 0.015931561589241028}]"
|
||||
]
|
||||
},
|
||||
"execution_count": 3,
|
||||
"metadata": {},
|
||||
"output_type": "execute_result"
|
||||
}
|
||||
],
|
||||
"source": [
|
||||
"from txtai import Embeddings\n",
|
||||
"\n",
|
||||
"# Works with a list, dataset or generator\n",
|
||||
"data = [\n",
|
||||
" \"US tops 5 million confirmed virus cases\",\n",
|
||||
" \"Canada's last fully intact ice shelf has suddenly collapsed, forming a Manhattan-sized iceberg\",\n",
|
||||
" \"Beijing mobilises invasion craft along coast as Taiwan tensions escalate\",\n",
|
||||
" \"The National Park Service warns against sacrificing slower friends in a bear attack\",\n",
|
||||
" \"Maine man wins $1M from $25 lottery ticket\",\n",
|
||||
" \"Make huge profits without work, earn up to $100,000 a day\"\n",
|
||||
"]\n",
|
||||
"\n",
|
||||
"# Create an embeddings\n",
|
||||
"embeddings = Embeddings(path=\"colbert-ir/colbertv2.0\", content=True)\n",
|
||||
"embeddings.index(data)\n",
|
||||
"embeddings.search(\"North America\", 10)"
|
||||
]
|
||||
},
|
||||
{
|
||||
"cell_type": "markdown",
|
||||
"metadata": {},
|
||||
"source": [
|
||||
"# Reranking pipeline\n",
|
||||
"\n",
|
||||
"Another major new component in this release is the Reranker pipeline. This pipeline takes an embeddings instance, a similarity instance and uses the similarity instance to rerank outputs. This is a key component of the MUVERA paper - using the standard vector index to retrieve candidates then reranking the outputs using the late interaction model."
|
||||
]
|
||||
},
|
||||
{
|
||||
"cell_type": "code",
|
||||
"execution_count": 4,
|
||||
"metadata": {},
|
||||
"outputs": [
|
||||
{
|
||||
"data": {
|
||||
"text/plain": [
|
||||
"[{'id': '1',\n",
|
||||
" 'text': \"Canada's last fully intact ice shelf has suddenly collapsed, forming a Manhattan-sized iceberg\",\n",
|
||||
" 'score': 0.3324427008628845},\n",
|
||||
" {'id': '0',\n",
|
||||
" 'text': 'US tops 5 million confirmed virus cases',\n",
|
||||
" 'score': 0.24423550069332123},\n",
|
||||
" {'id': '3',\n",
|
||||
" 'text': 'The National Park Service warns against sacrificing slower friends in a bear attack',\n",
|
||||
" 'score': 0.16353240609169006}]"
|
||||
]
|
||||
},
|
||||
"execution_count": 4,
|
||||
"metadata": {},
|
||||
"output_type": "execute_result"
|
||||
}
|
||||
],
|
||||
"source": [
|
||||
"from txtai import Embeddings\n",
|
||||
"from txtai.pipeline import Reranker, Similarity\n",
|
||||
"\n",
|
||||
"# Works with a list, dataset or generator\n",
|
||||
"data = [\n",
|
||||
" \"US tops 5 million confirmed virus cases\",\n",
|
||||
" \"Canada's last fully intact ice shelf has suddenly collapsed, forming a Manhattan-sized iceberg\",\n",
|
||||
" \"Beijing mobilises invasion craft along coast as Taiwan tensions escalate\",\n",
|
||||
" \"The National Park Service warns against sacrificing slower friends in a bear attack\",\n",
|
||||
" \"Maine man wins $1M from $25 lottery ticket\",\n",
|
||||
" \"Make huge profits without work, earn up to $100,000 a day\"\n",
|
||||
"]\n",
|
||||
"\n",
|
||||
"# Create an embeddings\n",
|
||||
"embeddings = Embeddings(path=\"colbert-ir/colbertv2.0\", content=True)\n",
|
||||
"embeddings.index(data)\n",
|
||||
"\n",
|
||||
"similarity = Similarity(path=\"colbert-ir/colbertv2.0\", lateencode=True)\n",
|
||||
"\n",
|
||||
"ranker = Reranker(embeddings, similarity)\n",
|
||||
"ranker(\"North America\")"
|
||||
]
|
||||
},
|
||||
{
|
||||
"cell_type": "markdown",
|
||||
"metadata": {},
|
||||
"source": [
|
||||
"Notice that while the outputs are the same, the scoring and order is different.\n",
|
||||
"\n",
|
||||
"Let's try a more interesting example."
|
||||
]
|
||||
},
|
||||
{
|
||||
"cell_type": "code",
|
||||
"execution_count": 5,
|
||||
"metadata": {},
|
||||
"outputs": [
|
||||
{
|
||||
"data": {
|
||||
"text/plain": [
|
||||
"[{'id': 'ChatGPT',\n",
|
||||
" 'text': 'ChatGPT is a generative artificial intelligence chatbot developed by OpenAI and released on November 30, 2022. It uses large language models (LLMs) such as GPT-4o as well as other multimodal models to create human-like responses in text, speech, and images. It has access to features such as searching the web, using apps, and running programs. It is credited with accelerating the AI boom, an ongoing period of rapid investment in and public attention to the field of artificial intelligence (AI). Some observers have raised concern about the potential of ChatGPT and similar programs to displace human intelligence, enable plagiarism, or fuel misinformation.',\n",
|
||||
" 'score': 0.6639302968978882},\n",
|
||||
" {'id': 'ChatGPT Search',\n",
|
||||
" 'text': 'ChatGPT Search (originally SearchGPT) is a search engine developed by OpenAI. It combines traditional search engine features with generative pretrained transformers (GPT) to generate responses, including citations to external websites.',\n",
|
||||
" 'score': 0.6477508544921875},\n",
|
||||
" {'id': 'ChatGPT in education',\n",
|
||||
" 'text': 'The usage of ChatGPT in education has sparked considerable debate and exploration. ChatGPT is a chatbot based on large language models (LLMs) that was released by OpenAI in November 2022.',\n",
|
||||
" 'score': 0.5918337106704712}]"
|
||||
]
|
||||
},
|
||||
"execution_count": 5,
|
||||
"metadata": {},
|
||||
"output_type": "execute_result"
|
||||
}
|
||||
],
|
||||
"source": [
|
||||
"from txtai import Embeddings\n",
|
||||
"from txtai.pipeline import Reranker, Similarity\n",
|
||||
"\n",
|
||||
"# Create an embeddings\n",
|
||||
"embeddings = Embeddings()\n",
|
||||
"embeddings.load(provider=\"huggingface-hub\", container=\"neuml/txtai-wikipedia\")\n",
|
||||
"\n",
|
||||
"similarity = Similarity(path=\"colbert-ir/colbertv2.0\", lateencode=True)\n",
|
||||
"\n",
|
||||
"ranker = Reranker(embeddings, similarity)\n",
|
||||
"ranker(\"Tell me about ChatGPT\")"
|
||||
]
|
||||
},
|
||||
{
|
||||
"cell_type": "markdown",
|
||||
"metadata": {
|
||||
"id": "tvnMO1Eai6Gy"
|
||||
},
|
||||
"source": [
|
||||
"# Wrapping up\n",
|
||||
"\n",
|
||||
"This notebook gave a quick overview of txtai 9.0. Updated documentation and more examples will be forthcoming. There is much to cover and much to build on!\n",
|
||||
"\n",
|
||||
"See the following links for more information.\n",
|
||||
"\n",
|
||||
"- [9.0 Release on GitHub](https://github.com/neuml/txtai/releases/tag/v9.0.0)\n",
|
||||
"- [Documentation site](https://neuml.github.io/txtai)"
|
||||
]
|
||||
}
|
||||
],
|
||||
"metadata": {
|
||||
"accelerator": "GPU",
|
||||
"colab": {
|
||||
"gpuType": "T4",
|
||||
"provenance": []
|
||||
},
|
||||
"kernelspec": {
|
||||
"display_name": "local",
|
||||
"language": "python",
|
||||
"name": "python3"
|
||||
},
|
||||
"language_info": {
|
||||
"codemirror_mode": {
|
||||
"name": "ipython",
|
||||
"version": 3
|
||||
},
|
||||
"file_extension": ".py",
|
||||
"mimetype": "text/x-python",
|
||||
"name": "python",
|
||||
"nbconvert_exporter": "python",
|
||||
"pygments_lexer": "ipython3",
|
||||
"version": "3.10.18"
|
||||
}
|
||||
},
|
||||
"nbformat": 4,
|
||||
"nbformat_minor": 0
|
||||
}
|
||||
File diff suppressed because one or more lines are too long
Some files were not shown because too many files have changed in this diff Show More
Reference in New Issue
Block a user